



Reference implementation of UCCI from Varun Kotte, UCCI: Calibrated Uncertainty for Cost-Optimal LLM Cascade Routing, arXiv:2605.18796 (2026).
UCCI decides, query by query, whether to keep a small model's answer or pay for a large model. It turns the small model's own token probabilities into a calibrated probability that the answer is wrong, and escalates exactly when that probability exceeds the threshold that meets an accuracy target at the lowest measured cost.
- Python package (
src/ucci): numpy only, fully typed, tested against scikit-learn and against brute force over all routing subsets of small problems. - Serving adapters for OpenAI-compatible APIs, vLLM, Hugging Face transformers and llama.cpp, a cascade runner and a traffic logger.
uccicommand line: fit, route, evaluate with bootstrap intervals, calibration report.- Baselines from the paper (entropy threshold, split conformal, FrugalGPT-style) and its ablations, under the same evaluation protocol.
- Rust crate (
rust/) that reads the same router files and matches the Python results bit for bit on the shared golden vectors. - Public replication on CoNLL-2003 with open models (
benchmarks/conll2003).
Documentation: docs/
pip install ucci-router                    # numpy only
pip install "ucci-router[plot,openai]"     # with extras
The package imports as ucci and installs the ucci command.
Extras: plot (matplotlib), openai (the SDK, for live calls), transformers (torch and
transformers), vllm, sklearn, bench (the CoNLL-2003 replication), docs, dev, and
all (everything except vllm, which needs Linux and a GPU). Python 3.9 or newer.
Run it in the browser with the Colab notebook, or locally:
import numpy as np
from ucci import UCCIRouter

# Logged traffic: u(x) of the small model and whether each model was right.
# Simulated here (raw u is a miscalibrated error probability); use your own logs.
rng = np.random.default_rng(0)
n = 10_000
u = rng.beta(2, 5, n)
small_ok = (rng.random(n) >= 1 / (1 + np.exp(-10 * (u - 0.45)))).astype(float)
large_ok = (rng.random(n) < 0.95).astype(float)
cal, val, test = np.split(rng.permutation(n), [3_000, 5_000])   # 30% / 20% / 50%

router = UCCIRouter()                                   # c_small = 1.0, c_large = 3.02
router.calibrate(u[cal], 1 - small_ok[cal])             # step 1: fit g on calibration
choice = router.choose_threshold(u[val], small_ok[val], large_ok[val], tau=0.90)  # step 2
result = router.evaluate(u[test], small_ok[test], large_ok[test])                  # step 3
print(f"theta* = {choice.theta}, test cost = {result.cost:.2f}, accuracy = {result.accuracy:.3f}")

router.escalate(0.42)       # one live query: True means call the large model
router.save("router.json")  # read by UCCIRouter.load, the ucci CLI and the Rust crate
Getting u(x) from a real response takes one call. With any OpenAI-compatible endpoint:
from openai import OpenAI
from ucci.integrations.openai import u_from_chat_completion

client = OpenAI()   # or OpenAI(base_url=...) for a vLLM, llama.cpp or LiteLLM server
resp = client.chat.completions.create(
    model="gpt-4o-mini",
    messages=[{"role": "user", "content": "Extract the named entities: ..."}],
    temperature=0, logprobs=True, top_logprobs=2,
)
u_query = u_from_chat_completion(resp) # drop_stop_token=True for vLLM and llama.cpp serversUCCI builds the routing policy in three steps (paper Section 4):
- Signal (Section 4.1, Eq. 4). From the small model's greedy generation, take the top-1 and
top-2 next-token probabilities at each of its T content tokens:
u(x) = 1 - (1/T) * sum_t (p_t1 - p_t2). Larger means less decisive. The serving stack already returns these log-probabilities, so the signal costs nothing extra. - Calibration (Section 4.2, Eq. 5). On a held-out calibration split with
e(x) = 1when the small model was wrong, fit a non-decreasing mapgby isotonic regression, so thatp_hat(x) = g(u(x))estimatesP(e(x) = 1 | u(x)). - Threshold (Section 4.3, Eqs. 6 and 7). Keep the small answer if
p_hat(x) <= theta, escalate otherwise. On a validation split where both models ran,theta* = argmin_theta Cost(pi_theta) subject to Acc(pi_theta) >= tau, with costs and accuracies from the actual outputs.
Theorem 1 (Section 5). Assume (i) the large model costs more, c_l > c_s; (ii) its
accuracy alpha_l does not depend on which queries are escalated; and (iii) p_hat is
calibrated. Escalating a query then buys alpha_l - 1 + p_hat(x) expected accuracy (Eq. 8) at the
fixed extra cost c_l - c_s, so the cheapest way to reach tau escalates in decreasing order of
p_hat: among policies that depend only on u(x), a threshold policy on p_hat is cost-optimal,
unique up to tie-breaking on level sets of p_hat. Proposition 2 states that, under standard
regularity conditions and bounded u(x), the expected calibration error of the isotonic fit on
n examples is O(n^(-1/3)).
Because g is non-decreasing, a threshold on p_hat is also a threshold on u. Calibration is
what gives theta its meaning: an error probability that can be set from a budget, compared
across models and monitored over time. The method page
states the results precisely, and paper mapping
maps every element of Sections 4 to 6 and Appendices A and B to the code.
| Stack | Module | Request | Terminating stop token |
|---|---|---|---|
| OpenAI API: Chat Completions, Completions, Responses | ucci.integrations.openai |
Chat: temperature=0, logprobs=True, top_logprobs=2 |
not reported by the API |
| OpenAI-compatible servers (vLLM, llama.cpp, LiteLLM) | ucci.integrations.openai |
as for the OpenAI API | drop_stop_token=True for vLLM and llama.cpp |
vLLM offline (LLM.generate) |
ucci.integrations.vllm |
greedy_sampling_params() |
dropped automatically |
Hugging Face generate |
ucci.integrations.transformers |
generate_with_signals(model, tokenizer, prompts) |
cut at the first EOS |
llama.cpp server /completion |
ucci.integrations.llamacpp |
n_probs=2, top_k=1 |
dropped when stop_type is "eos" |
| Anything else | ucci.uncertainty_from_logprobs, ucci.token_margin_uncertainty |
top-2 per content token | exclude it yourself |
ucci.integrations.cascade.Cascade runs the small model, routes with a fitted router and calls
the large model when needed (sync or async). JsonlLogger writes the traffic records that
ucci fit reads, and shadow_large=True collects the both-models validation data that
threshold selection needs.
Records are JSON Lines, JSON or CSV with id, u, small_correct and large_correct
(optional split, per-query scores and latencies):
ucci fit      --data traffic.jsonl --tau 0.90 --out router.json   # 30/20/50 split by id, seed 0
ucci route    --router router.json --u 0.08 0.35 0.61
ucci evaluate --router router.json --data traffic.jsonl --split test   # bootstrap CIs
ucci report   --router router.json --data traffic.jsonl --split test   # ECE, reliability table
--budget replaces --tau for the matched-budget form, --cost-from-latency sets the cost
ratio from logged latencies, --json prints machine-readable output, and the exit codes are
0 (ok), 2 (usage), 3 (input) and 4 (infeasible target).
[dependencies]
ucci = "0.1"
use ucci::signal::uncertainty_from_top_logprobs;
use ucci::Router;
fn main() -> Result<(), ucci::UcciError> {
let router = Router::load("router.json")?; // written by UCCIRouter.save or `ucci fit`
// Top-2 log-probabilities of each generated content token of the small model.
let u = uncertainty_from_top_logprobs(&[vec![-0.01, -4.7], vec![-0.9, -0.6]])?;
let route = router.route(u)?;
println!("u = {u:.3}, p_hat = {:.3}, escalate = {}", route.p_hat, route.escalate);
Ok(())
}The crate implements the signal, the isotonic fit, threshold selection, the metrics and the
router format. Its only dependencies are serde and serde_json, for router files (none with
default-features = false). See rust/README.md.
ucci.baselines implements every comparator of the paper's Table 2 and the ablations of
Section 6.3 and Appendix B.4, and compare_routers runs them all under the three-step protocol
of Section 6.1: fit on calibration, select on validation, route every test query end to end.
from ucci.baselines import SplitData, compare_routers, format_comparison

def split(idx):   # continuing the quickstart; add "entropy" and "max_prob" signals if logged
    return SplitData({"u": u[idx]}, small_ok[idx], large_ok[idx])

rows = compare_routers(split(cal), split(val), split(test), tau=0.90)
print(format_comparison(rows))benchmarks/conll2003 runs the full pipeline on public data:
CoNLL-2003 (validation and test, 6,703 sentences) with Qwen2.5-1.5B-Instruct as the small model
and Qwen2.5-7B-Instruct as the large one, a 30/20/50 split, and costs set from latency measured
on the machine (c_l / c_s = 2.50 on an Apple M5 Max).
| Policy | Micro-F1 (test) | Cost | Escalated |
|---|---|---|---|
| Small model only | 0.371 | 1.00 | 0% |
| UCCI at the F1 target (0.552) | 0.564 | 1.78 | 52% |
| Large model only | 0.617 | 2.50 | 100% |
UCCI meets the target at 29% lower cost than always calling the 7B model. Isotonic calibration turns the raw margin signal into a usable error probability (test ECE 0.698 to 0.015):
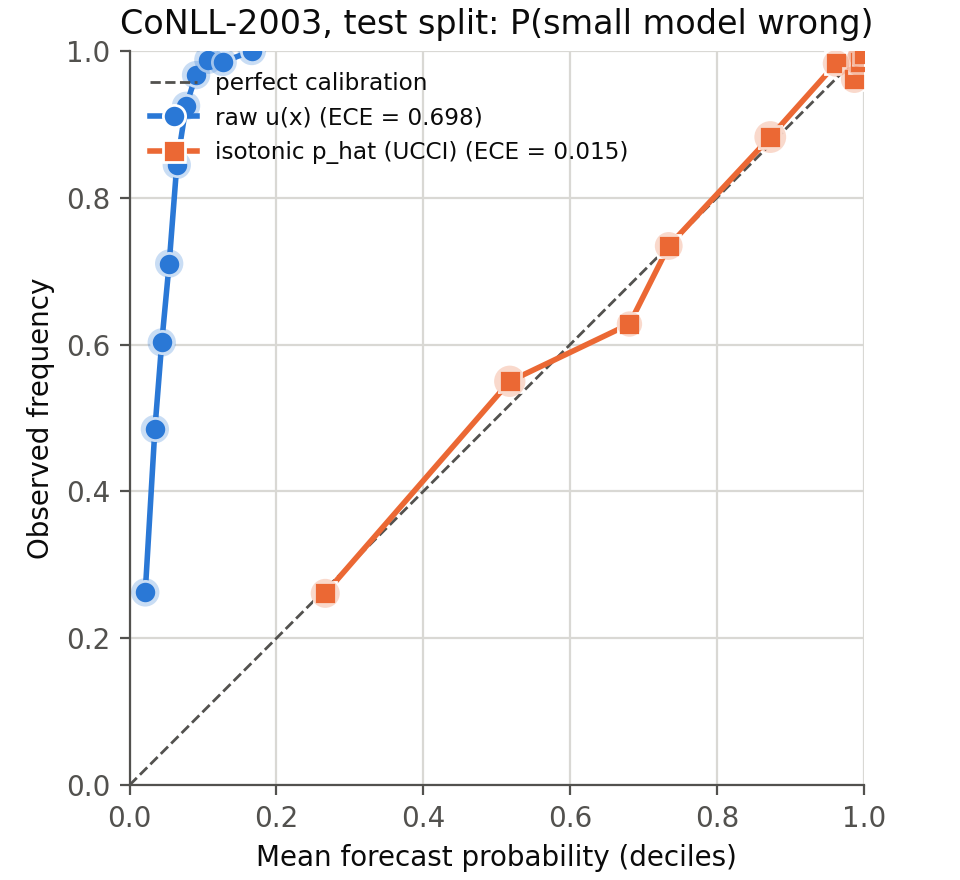
One command reproduces it: bash benchmarks/conll2003/run_full.sh.
Open-source projects whose code cites the paper and implements its calibration step:
- SourceShift/mini-ork:
mini_ork/dispatch/calibration.py(Python, pool-adjacent-violators fit of an error-probability map for escalation). - shizukutanaka/Pasture:
src/calibrate.rs(Rust, isotonic error curve for cascade calibration). - AnOversizedMooseWithSocks/leCore:
holographic/unified/holographic_unified_p22_zoo2.py(NumPy, isotonic map from confidence to error probability).
If you use UCCI or this code, please cite the paper:
@article{kotte2026ucci,
  title         = {{UCCI}: Calibrated Uncertainty for Cost-Optimal {LLM} Cascade Routing},
  author        = {Kotte, Varun},
  journal       = {arXiv preprint arXiv:2605.18796},
  year          = {2026},
  eprint        = {2605.18796},
  archivePrefix = {arXiv},
  primaryClass  = {cs.LG},
  doi           = {10.48550/arXiv.2605.18796},
  url           = {https://arxiv.org/abs/2605.18796}
}
To cite the software itself (all versions): doi:10.5281/zenodo.22957160.
@software{kotte2026ucci_code,
  author    = {Kotte, Varun},
  title     = {ucci: reference implementation of {UCCI}},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.22957160},
  url       = {https://github.com/varunkotte6/ucci}
}
GitHub's "Cite this repository" button reads CITATION.cff.
See CONTRIBUTING.md for the
development setup, the test suites and the golden-vector workflow, and
CHANGELOG.md for releases. MIT
licensed; see LICENSE.