
Agent memory, optimized for what's ahead.
Compress what your agent remembers based on where it's going — not just where it's been.
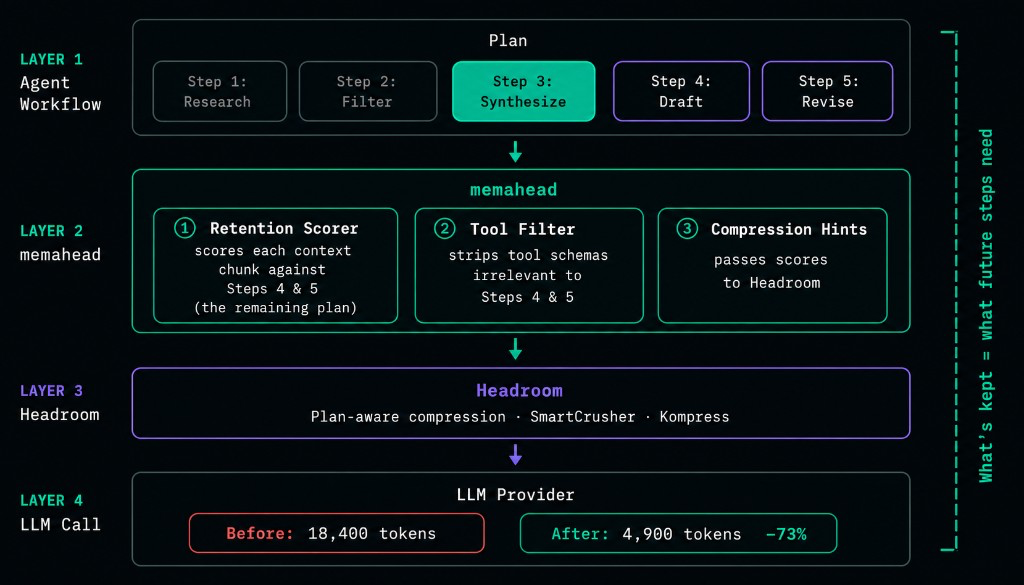


Most agent frameworks compress context based on what already happened.
memahead scores every chunk of memory against the steps still to come — and drops what future steps won't need.
Real numbers — reproduce with python -m benchmarks.run_benchmark:
| Workflow | Before | After | Saved |
|---|---|---|---|
| Research & Synthesis | 6,240 tokens | 4,795 tokens | 23% |
| Code Review | 5,386 tokens | 2,113 tokens | 61% |
| Data Analysis | 4,821 tokens | 494 tokens | 90% |
100% critical fact retention across all workflows.
Plan-aware compression outperforms Headroom-only by up to 87%.
Full methodology → benchmarks/results/README.md
Based on PAACE and ACON — the first production library to implement plan-aware context compression for real agent workflows.
pip install memaheadfrom memahead import Plan, Step, PlanAwareCompressor
plan = Plan([
Step("research", "Search and gather raw facts"),
Step("synthesize", "Identify key themes"),
Step("draft", "Write a structured first draft"),
Step("revise", "Produce the final polished output"),
])
compressor = PlanAwareCompressor(quality=0.85)
compressed = compressor.compress(
history=prior_messages,
tools=all_tool_schemas,
plan=plan,
current_step="synthesize",
)
# TokenReport(before=12400, after=3100, saved=9300, compression_ratio=0.75)
print(compressed.report)| Repo | Description |
|---|---|
| memahead | Core library |
