





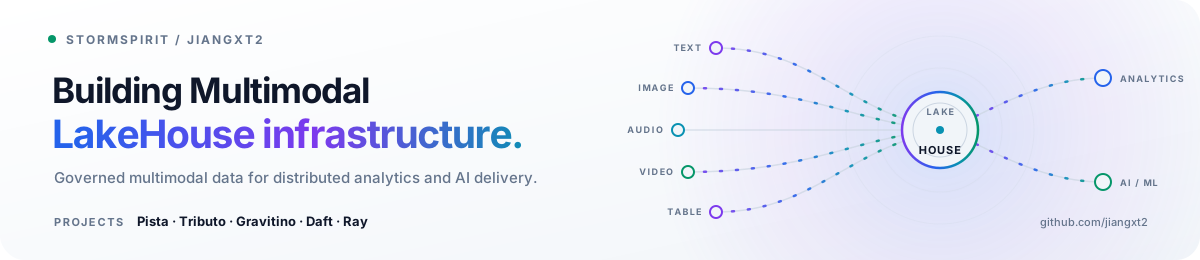
I'm Thunderkeg. I build and contribute to open-source software for distributed data and AI infrastructure.
My work spans SQL analytics, data connectivity, and machine learning workflows—from distributed training to model delivery and inference. I develop tools and contribute improvements across the Spark, Ray, Daft, and Gravitino ecosystems, with a focus on OLAP databases and lakehouse systems.
| Area | What I work on |
|---|---|
| Distributed analytics | Spark SQL, Ray Data, Daft, and reliable OLAP delivery |
| Data connectivity & lakehouse | Doris, ClickHouse, Hive, and governed data access |
| Model delivery & inference | Ray Train, Ray Serve, model bundles, and batch / online inference |
Languages: Python · Scala · Java
I'm interested in how multimodal lakehouse systems bring data governance, distributed analytics, and AI workflows together.
My Spark work focuses on SQL functions and expression correctness, especially bitmap and set operations, type conversion, and consistent behavior across SQL, Scala, PySpark, and Spark Connect.
My Gravitino work centers on Doris, ClickHouse, and Lance catalog integrations, with a focus on type compatibility, metadata consistency, and index and partition support. My ongoing work also covers governed Doris reads and integration testing with processing engines.
My Ray work focuses on Ray Data’s data-source and file-reading APIs, including ORC and Hive reads, Parquet schema inference and source-path metadata, and interoperability with Daft.
My Daft work focuses on data ingestion and scan efficiency, including ORC reading, Iceberg file statistics, SQL expression translation, and Gravitino catalog compatibility.
I welcome conversations about data connectors, distributed analytics, and model delivery.
WeChat Official Account · Scan with WeChat to follow.