



Research on LLM agents at IBM and the Weizmann Institute of Science:
what agents pursue without being asked, and how safely they act.


Ido Levy, Asaf Yehudai, Segev Shlomov, Asaf Adi, Leshem Choshen
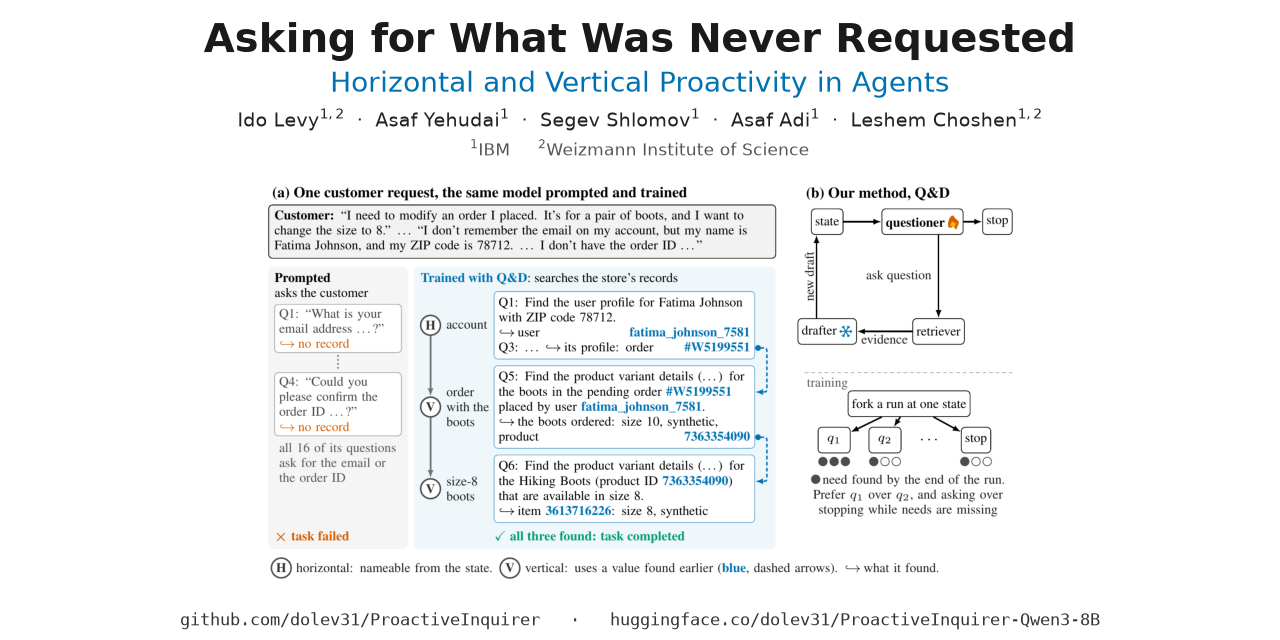
What should an LLM agent pursue that the user never asked for? Need graphs measure it without a model judge, and Q&D trains it from the consequences of its own questions. The trained 8B questioner recovers 90% of the required evidence where the same model, prompted, recovers 78%, and it more than doubles retail task success in a τ²-bench customer-service agent it was never trained on.

Project page · Code · Model 🤗
Ido Levy, Ben Wiesel, Sami Marreed, Alon Oved, Avi Yaeli, Segev Shlomov
A benchmark for evaluating the safety and trustworthiness of web agents in enterprise scenarios.

Paper · Website · Code · Leaderboard · Dataset

An agent harness for complex tasks on the web and APIs, with OpenAPI and MCP integrations, a composable architecture, reasoning modes and policy-aware features.