OpenCode Heads Up is a heads-up display (HUD) with telemetry for both local inference engines and remote models. Get your data straight from the source, with OpenCode's own data layer filling in the gaps.
|
|
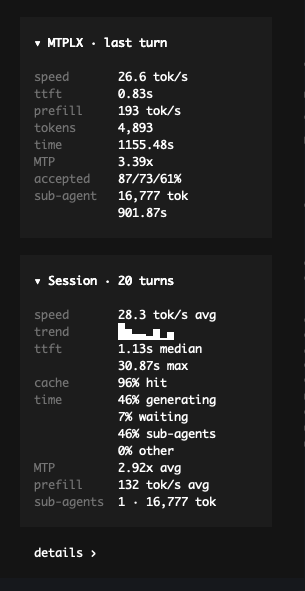
| Sidebar The last turn and the session so far, each collapsible, with details › for the full picture. |
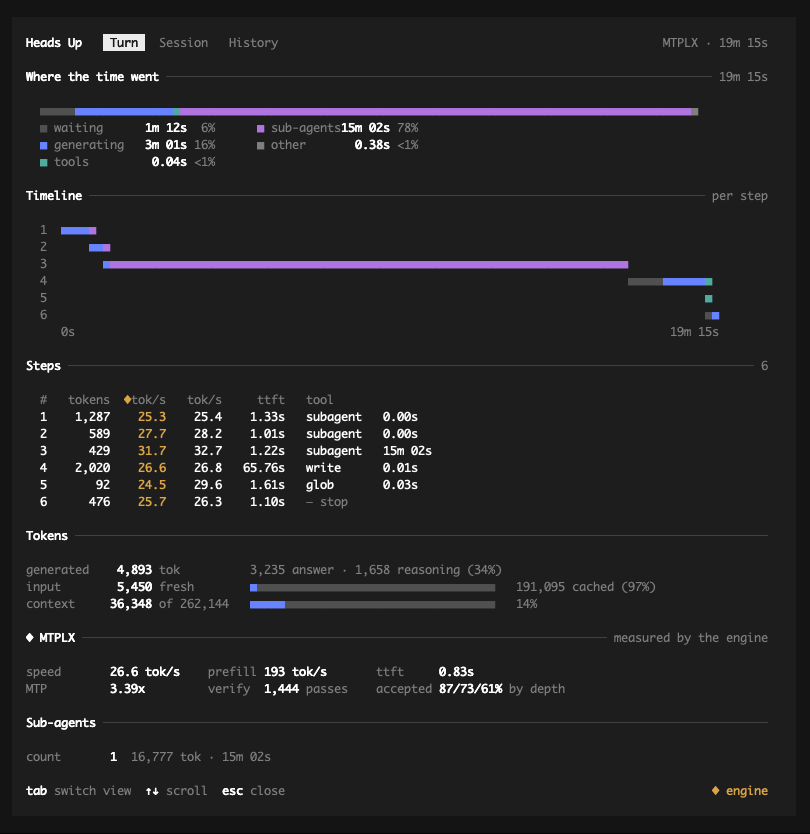
Turn Where the time went, a timeline per step, every tool call, tokens and the engine's own figures. |
|
|
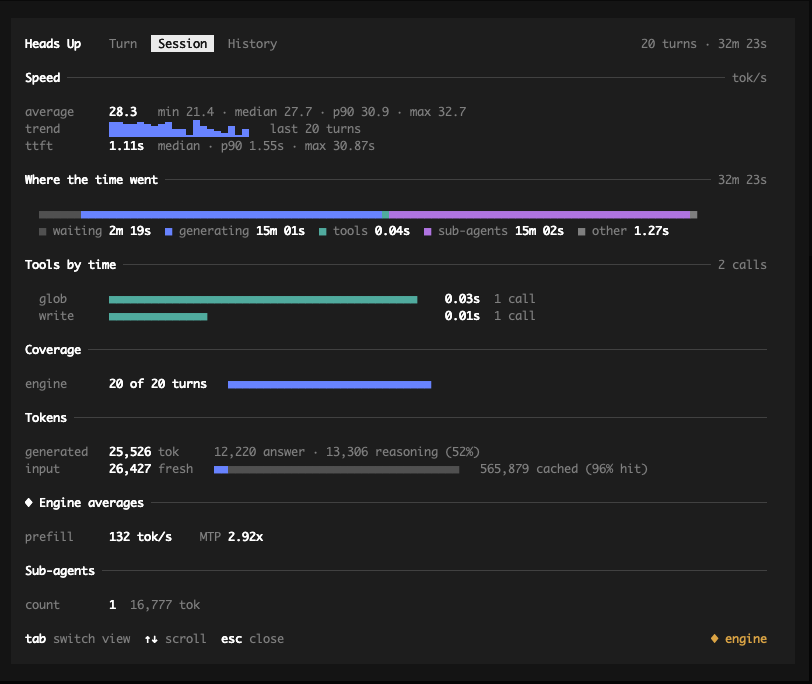
| Session Speed and its spread, where the time went, tools, coverage and engine averages. |
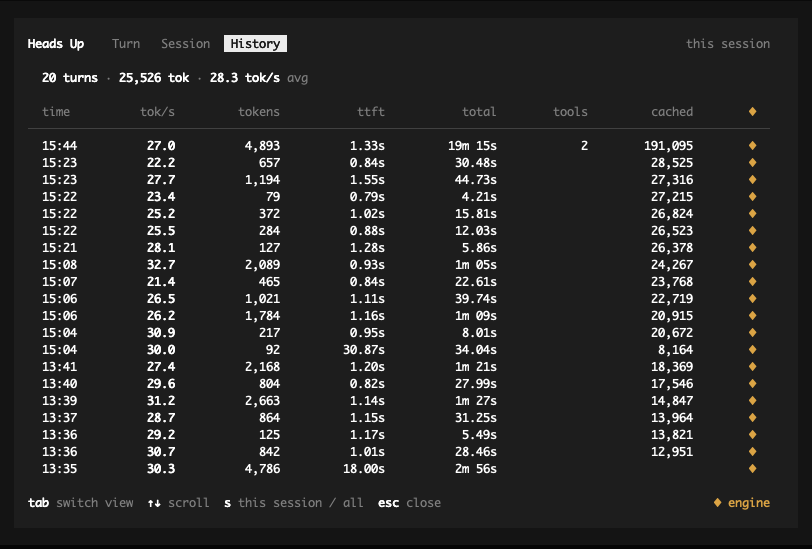
History Every turn in fixed columns, for this session or all of them. |
- Metrics straight from local engines: speed, prefill, cache and speculative-decoding figures read from the engine itself. See the full list.
- Works with any model: remote and hosted models get the same core figures from OpenCode's own data.
- Sidebar and details view
- Turn and session figures
- Where the time went: each turn split into waiting, generating, tools, sub-agents and compaction, step by step.
- Practical numbers: tok/s is generation speed only, time is real elapsed time, bad data is dispensed with.
- Sub-agent aware: sub-agents are counted and shown separately.
- Install
- Keys
- Details
- Configuration
- Supported Engines
- Engine Details
- Adding an Engine
- Important Notes
- Roadmap
Headsup requires OpenCode 2. For the v1 line (OpenCode 1.18.x), see opencode-engine-hud.
opencode plugin add @banburist/opencode-headsupOr place it within the OpenCode cli config file.
| Key | Does |
|---|---|
ctrl+shift+m |
Collapse/expand the last-turn box. Clicking its heading does the same. |
ctrl+shift+d |
Open/close the details dialog on the Turn tab. So do /headsup and clicking details ›. |
ctrl+shift+h |
Open the details dialog on the History tab. |
/headsup session and /headsup history open the dialog on those tabs.
All three are registered with stable command ids (headsup.toggle,
headsup.panel, headsup.details), so they can be remapped from your own
OpenCode keybind config and are reachable from the command palette.
The Session box has no key; click its heading. Collapsed, each box keeps one figure rather than becoming a bare label:
▸ MTPLX · last turn 34.4 tok/s
A dialog with three tabs -- Turn, Session and History --
switched with tab (shift+tab goes back). It is as tall as its content,
up to most of the screen, and scrolls beyond that with the wheel, ↑ ↓
and page up/down; esc closes it.
Turn
- Where the time went, as a bar and in seconds and shares that add up to the turn's total: waiting for the first token, generating, tools, sub-agents, compaction, and the rest. A moment is counted once, so a tool running beside a sub-agent is not counted twice.
- Timeline: each step's wait, generation and tools on one time scale.
- Steps: tokens, tok/s and time to first token per step, each tool call and how long it ran, retries, and a step that waited on a compaction.
- Tokens: output, reasoning, fresh input, cache read and cache write; context used against the model's limit.
- ◆ Engine: only what the engine itself measured -- MTPLX's acceptance at every depth and its verify passes, prefill and decode as tokens and seconds, cache reuse, draft acceptance, and per-step rates where the engine is read per step. When its figures were not used, it says which and why.
- Retry and error reasons in full, and sub-agent totals.
Session (the current model's turns)
- Speed as an average and a spread (min, median, p90, max), a trend, and time to first token (median, p90, max).
- Where the time went, in seconds, across the session.
- Tools by time as bars, retries by reason, tokens in all five kinds.
- Coverage: how many turns had the engine's own figures, and why the rest did not (first turn, compaction, overlapping requests, no engine telemetry, ...).
History
- One row per turn in fixed columns, never wrapped: time, tok/s, tokens,
time to first token, total, tool calls, and
◆where the engine's own figures were used.sswitches between this session and every session, where a model column appears. Cost and cache columns appear when some turn has them.
Everything unmarked is OpenCode's own data; ◆ marks the engine's.
Two keys, because two things are genuinely preferences. Everything else appears exactly when its underlying data exists and stays silent when it does not — there is nothing to choose.
{
  "plugins": [
    {
      "package": "@banburist/opencode-headsup",
      "options": { "showContext": false, "background": true }
    }
  ]
}
showContext (default false)
Adds a 13% prompt/limit line, computed as
tokens.input / ModelInfo.limit.context based on the model's
config in opencode.json. Labeled as prompt/limit rather than
context used.
background (default true)
Puts your theme's offset panel shade behind each box. Turn it off for a theme or terminal with a transparent background, where the shade can disappear.
Engine endpoints use the defaults below, overridable per key or by env var. An engine that is not running just falls back to the universal layer.
| Option | Env | Default |
|---|---|---|
mtplxMetricsUrl |
MTPLX_METRICS_URL |
http://127.0.0.1:8000/metrics |
omlxBaseUrl |
OMLX_BASE_URL |
http://127.0.0.1:8099 |
omlxApiKey |
OMLX_API_KEY |
(none — required to read oMLX) |
llamacppBaseUrl |
LLAMACPP_BASE_URL |
http://127.0.0.1:8080 |
llamafileBaseUrl |
LLAMAFILE_BASE_URL |
http://127.0.0.1:8003 |
vllmBaseUrl |
VLLM_BASE_URL |
http://127.0.0.1:8000 |
sglangBaseUrl |
SGLANG_BASE_URL |
http://127.0.0.1:30000 |
vllmMlxBaseUrl |
VLLM_MLX_BASE_URL |
http://127.0.0.1:8000 |
aphroditeBaseUrl |
APHRODITE_BASE_URL |
http://127.0.0.1:2242 |
lmdeployBaseUrl |
LMDEPLOY_BASE_URL |
http://127.0.0.1:23333 |
splashBaseUrl |
SPLASH_BASE_URL |
http://127.0.0.1:8000 |
koboldcppBaseUrl |
KOBOLDCPP_BASE_URL |
http://127.0.0.1:5001 |
mlxServeBaseUrl |
MLXSERVE_BASE_URL |
http://127.0.0.1:8095 |
mlxServeApiKey |
MLX_API_KEY |
(unset) |
OPENCODE_HUD_DEBUG=1 logs adapter failures to
/tmp/opencode-headsup-debug.log. Adapter throws are swallowed by design so
a broken engine never blanks the panel; this is how you see them.
Providers get the universal line from OpenCode's own per-turn data — rate, TTFT, exact token counts, cost and cache reuse; supported engines provide their own telemetry instead. See Adding an Engine.
For local engines, the provider id in opencode.json must exactly
match the provider ids below, otherwise no data will be passed to the
plugin.
| Provider | tok/s | TTFT | Prefill tok/s | Exact tokens | Cache info | Extras | First turn | Validated |
|---|---|---|---|---|---|---|---|---|
mtplx |
✅ | ✅ | ✅ | ✅ | ❌ | MTP accept % | ✅ | live |
omlx |
✅ | 🟡 | ✅ | ✅ | ✅ | — | ✅ | live |
llamacpp |
✅ | 🟡 | ✅ | ✅ | ❌ | — | 🟡 | live |
llamafile |
✅ | 🟡 | ✅ | ✅ | ❌ | — | 🟡 | live |
mlxserve |
✅ | ✅ | ❌ | ✅ | ❌ | cold-start flag | ✅ | live |
splash |
✅ | 🟡 | ✅ | ✅ | ✅ | draft accept % | 🟡 | live |
koboldcpp |
✅ | 🟡 | ✅ | ✅ | ❌ | draft accept % | ✅ | live |
vllm |
✅ | ✅ | ❌ | ✅ | ✅ | — | 🟡 | live |
sglang |
✅ | ✅ | ❌ | ✅ | ✅ | — | 🟡 | live |
vllmmlx |
✅ | ✅ | ❌ | ✅ | ❌ | — | 🟡 | live |
aphrodite |
✅ | ✅ | ❌ | ✅ | ✅ | — | 🟡 | derived |
lmdeploy |
✅ | ✅ | ✅ | ✅ | ❌ | — | 🟡 | synthetic |
| anything else | 🟡 | 🟡 | ❌ | 🟡 | 🟡 | — | — | live |
-
✅ Provided by the engine
-
🟡 Provided by OpenCode's universal layer, labelled
(host)on the panelOpenCode's telemetry spans queue, network and event delivery as well as prefill, so it is not the same measurement an engine reports.
-
❌ Not available
- live: run against a real server, deltas checked against its own response.
- derived: a real vLLM capture with the metric prefix swapped (Aphrodite is a vLLM fork, identical shape).
- synthetic: values fixed by hand from the engine's source to make
the arithmetic checkable, not measured —
aphroditeandlmdeployare both CUDA-only and unavailable here.
Per-file provenance is located in
fixtures/README.md.
Most engines expose cumulative counters, not per-request figures: total tokens decoded since launch, total milliseconds spent decoding. A single reading says nothing about one turn. The figure for a turn is the difference between a reading taken before it and one taken after, which means the first turn after OpenCode starts has nothing to subtract from.
- ✅ — engine telemetry from the very first turn. These publish a last
request figure (
mtplx,koboldcpp) or an identifiable per-request record (mlxserve), so one reading is enough.omlxis primed like the 🟡 engines below; when it has no reading yet, it still renders, with server-lifetime averages labelled(avg). - 🟡 — primed: when a turn starts on one of these engines and there is no reading yet, that one engine is read before the request reaches it, so the first turn has engine telemetry too. The exception is a brand-new session that has not used or selected a model yet: OpenCode does not tell plugins which model it will use, so that first turn shows the universal line, then engine telemetry from the second turn on. Nothing is broken and nothing is lost; a rate invented from a single counter reading would describe the whole server's history, not your turn.
- — — no adapter, so the universal layer is all there is, on every turn.
The baseline lives in memory for the life of the TUI, so this applies once per OpenCode session rather than once per install. Nothing is read at startup, and an engine you are not using is never read.
Default http://127.0.0.1:8000/metrics. No think/answer split — /metrics
never reports reasoning_tokens.
Default http://127.0.0.1:8099. Requires omlxApiKey. No TTFT: its
counters are atomic at completion, so there is nothing to time a first
token against.
Default port 8080, needs --metrics (off by default). Use the classic
single-model llama-server, not the multi-model router — different
/props shape.
llama-server --hf-repo <user>/<repo> --hf-file <file>.gguf \
  --host 127.0.0.1 --port 8080 --metrics
No cache-hit counter, so prompt tokens read low on a cache hit rather than reporting what was reused.
Default port 8003. Publishes identical llamacpp: metric names, so it
shares that adapter and can run alongside a real llama.cpp instance.
llamafile -m model.gguf --server --host 127.0.0.1 --port 8003 --metricsDefault port 8095. This is
raspoli/mlx-serve, not
mlx_lm.server itself. Set mlxServeApiKey if it runs with MLX_API_KEY.
Matches turns by request id, so multi-request turns are summed rather than
dropped. A streamed request reports no prompt count; a non-streamed one has
no separate decode rate. Cold starts are flagged — a model swap runs ~10x
longer than a warm turn.
Default port 8000, nothing to enable. Apple Silicon only.
splash serve --model <owner/repo>
splash opencode --standalone
--standalone is required on OpenCode 2. splash opencode injects its
provider through OPENCODE_CONFIG_CONTENT, which only the process that
loads config reads — and v2 runs a persistent background server that the TUI
merely connects to. Without a private server the variable never reaches the
process that would act on it, so Splash is not registered as a provider at
all and OpenCode silently opens on whatever model it already had. Reported
upstream.
Port 8000 is also vllm's and vllmmlx's default here. If you run more
than one of them, give Splash its own port with splash serve --port, and
set splashBaseUrl to match — otherwise whichever server is listening
answers for whichever provider you pick, and you get a confusing model not found rather than a connection error.
Both phases are engine-timed, and prefill stays honest on a cache hit — it counts only recomputed tokens, never the whole prompt.
Default port 5001, nothing to enable. Mac arm64 binary is 64MB.
./koboldcpp --model <model.gguf> --port 5001Prefill/decode arrive already timed. A partial cache hit overstates prefill — there is no cached-token counter to correct it with. Streaming emits no usage chunk, so this endpoint is the only source of token counts on a streamed turn.
Default port 8000. On Apple Silicon, vllm-metal runs upstream vLLM unchanged. Decode rate reuses OpenCode's turn timing — there is no per-request duration histogram. TTFT is engine-reported.
Default port 30000, needs --enable-metrics. On Apple Silicon its MLX
backend works despite the docs not saying so:
SGLANG_USE_MLX=1 python -m sglang.launch_server \
  --model-path <mlx-model> --disable-cuda-graph --enable-metrics
(the published docs name an all_mps extra the shipped pyproject lacks;
the real one is srt_mps). cached_tokens_total is registered lazily and
absent until the first cache hit. On a non-streaming turn TTFT is stamped
at completion, collapsing onto total latency.
Default port 8000 — conflicts with vllm. pip install vllm-mlx, then
start with --enable-metrics (not --metrics, despite some docs):
vllm-mlx serve mlx-community/Qwen2.5-0.5B-Instruct-4bit --port 8000 --enable-metricsThe only engine here with a true decode rate excluding prefill, from its own duration histogram. Drops the per-request rate rather than report a blended one when several requests land in one window.
Default port 2242, CUDA host. A vLLM fork publishing vLLM's shape under an
aphrodite: prefix, so it behaves like vllm. Not independently
live-tested.
Default port 23333, needs --enable-metrics, CUDA host. The richest
surface here — prefill and decode are both separately timed histograms, so
neither rate is derived. Not independently live-tested.
Universal layer only, which on v2 still includes exact token counts, cost
and cache reuse. Ollama: baseURL: "http://127.0.0.1:11434/v1"; its own
telemetry is per-caller, not server-wide. MLX-LM has no server-wide
/metrics at all.
Same shape for any OpenAI-compatible server:
// ~/.config/opencode/opencode.json
{
  "provider": {
    "<provider-id>": {
      "name": "Display name",
      "npm": "@ai-sdk/openai-compatible",
      "options": { "baseURL": "http://127.0.0.1:<port>/v1", "apiKey": "anything" },
      "models": {
        "<model id the server reports at /v1/models>": {
          "name": "Display name for the model",
          "limit": { "context": 32768, "output": 8192 },
          "modalities": { "input": ["text"], "output": ["text"] },
          "tool_call": true
        }
      }
    }
  }
}tok/s counts only the time spent generating, after the first token, so
it can be far higher than OpenCode's own figure, which includes the wait
for the first token. That wait shows as TTFT, and the total is the real
time from request to answer, retries included.
Engines that only publish running totals are read before and after each turn, and the difference is used only when it matches OpenCode's count for that turn. When other work shares the engine at the same time (another tab, say), the engine's figures are left out and the reason is shown.
A figure that isn't available is left out, not shown as zero: no $0.00
for a free model, no 0 cached for a cold prompt.
More detail: docs/measurement-notes.md.
- Zen/Go quota (
opencode.ai/zen/go/v1/usage) — opt-in, needs aPRIVACY.md
MIT