
Reinforcement learning training and the environments it learns from, split into two processes and joined by a written protocol: WebSocket and msgpack, with a feedback return channel.
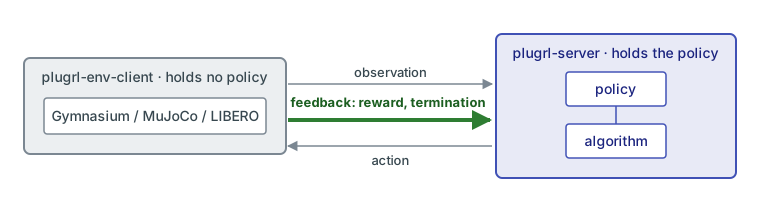
The third arrow is the one that matters. Serving an inference model needs the first two; learning from what happened needs the third, and the protocol specifies it rather than leaving it to a convention.
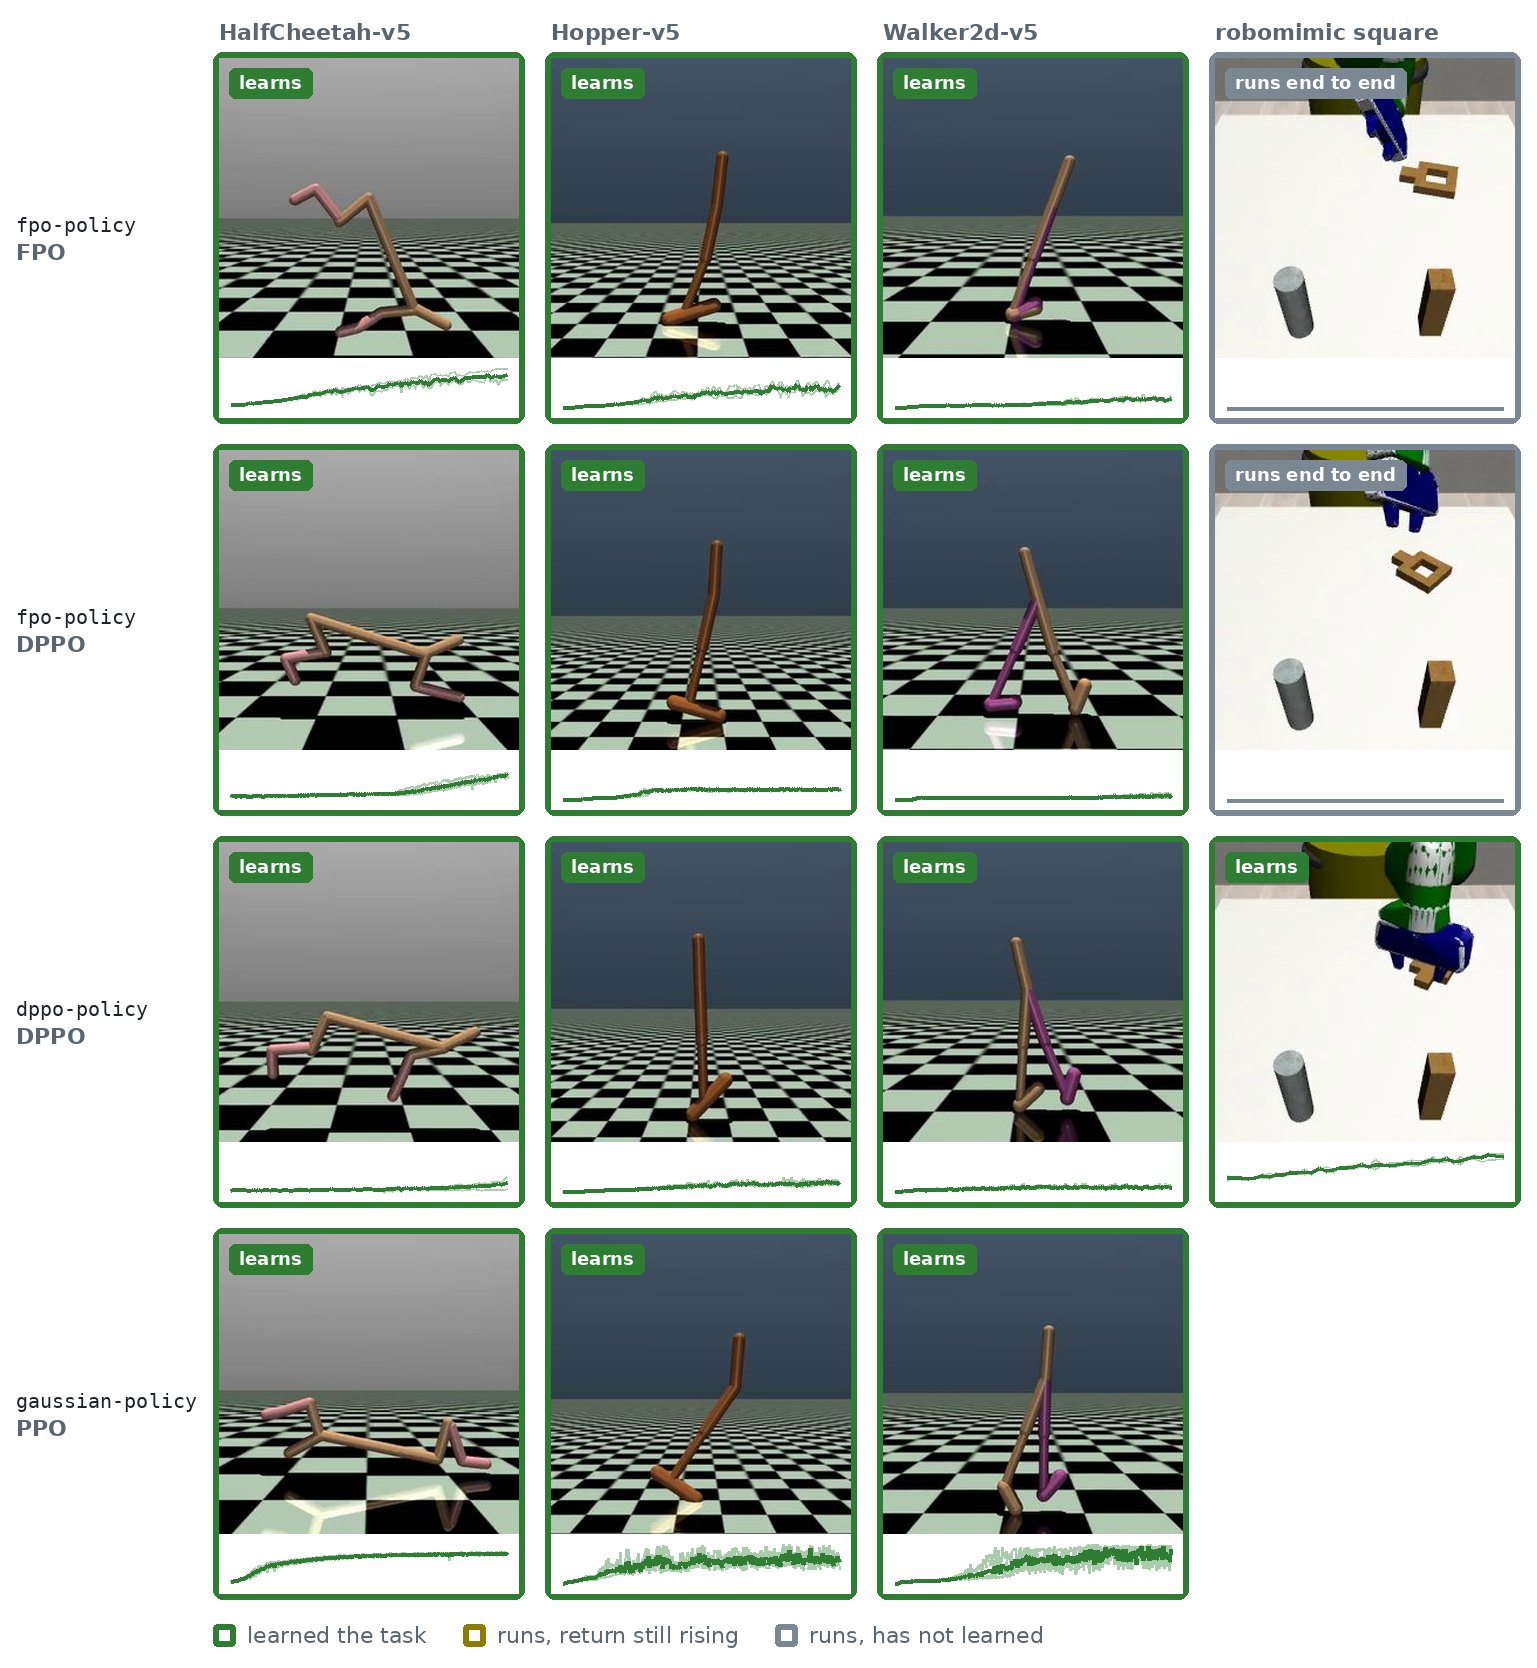
Every combination of the two MLP policies and the two algorithms on four tasks, and the baseline they are measured against, a Gaussian MLP with PPO. All sixteen learn. On the project page each cell plays its clip and shows the two commands that trained it. None of the servers that trained these has MuJoCo, robosuite or gymnasium installed; the env clients carry them, in two separate environments.
The training server is 6.5G and wants a GPU. The environment side needs neither, and need not be Python: it fits on a different class of machine from the trainer. The boundary between them costs a fixed latency plus the observation's bytes over the link, small on a fast link and measurable on a slow one.
| Question | Answer | |
|---|---|---|
| E44 | Does an env client have to be this codebase, or Python? | No - a C++ program with no third-party libraries trains a policy on its own Pendulum as well as the Python env client does (E2 first spoke the protocol from C++) |
| E12 | Does a rollout machine need CUDA? | No - LIBERO's env client goes from 7.8G to 3.4G, with no nvidia wheels |
| E13 | Or a GPU to render on? | No, at 1.91x the wall clock - ten clients rendering on the CPU, 30 of 30 episodes successful |
| E43 | Does training still work with the env clients on another physical machine? | Yes - the quickstart pair learns with its env clients on a Windows laptop over campus Wi-Fi |
| E43 | What does crossing cost? | About 3 ms plus twice the observation's bytes over the link per exchange: 21 ms for 184 KiB at 18 MB/s |
| E10 | Is that cheap beside a VLA forward pass? | On a fast link. Over that Wi-Fi a 184 KiB observation is 21% of pi0.5's 100 ms forward, not E10's 1.3-3.6% |
Every experiment directory carries its data and a FINDINGS.md that states
what the result does not support.
A full-size pi0.5 runs end to end through the boundary on LIBERO. The
unmodified checkpoint scored 99 of 100 on libero_spatial and 185 of 200 on
libero_10, against openpi's published 98.8 and 92.4, and the server's record
of episodes and steps reconciles exactly with the clients'
(E11).
Fine-tuning it with reinforcement learning through PlugRL has not made it
better yet; that record is on its own page.
| plugrl-server | Training side: policy, algorithm, checkpoints, and the experiments |
| plugrl-env-client | Environment side: steps envs, asks for actions, returns feedback |
| plugrl-protocol | The specification, its checkable clauses as tests, and two reference env clients |
| plugrl.github.io | Documentation, in English and 中文 |
Start at the documentation - the quickstart trains FPO on HalfCheetah with no GPU and nothing to download.
PlugRL is built by Chenhao Lu, Zuo Gou and Zilin Kang.
