

Inference and serving for Microsoft Aurora and other geospatial foundation models. A request takes an analysis cube in and writes NetCDF or GeoTIFF out. The tensors keep a lat/lon layout, so the engine uses shape-specialized kernels, named mixed precision (bf16_mixed@fp32 by default), and a job-level GPU scheduler rather than an LLM serving loop.
Walkthrough slides · Tutorial · Benchmark tables
pip install flash-auroraFrom source:
git clone https://github.com/CatManJr/Flash-Aurora.git
cd Flash-Aurora
uv sync
Set CUTE_DSL_ARCH when the CuTe kernels need an explicit GPU architecture (sm_89 on RTX 4090, sm_120a on Blackwell). The published measurements use PyTorch 2.14.0, Triton 3.8.0, and CuTe DSL 4.7.1, which uv.lock pins. If PyPI is slow, point uv at a mirror with UV_DEFAULT_INDEX or a local uv.toml; keep the committed uv.lock on the official index.
from datetime import datetime
from pathlib import Path

from flash_aurora import AuroraEngine, DataDownloader

engine = AuroraEngine.from_preset(
    "era5_pretrained",
    asset_root=Path("/path/to/assets"),
    inference_precision="bf16_mixed@fp32",
)
downloader = DataDownloader.from_preset(
    "era5_pretrained",
    asset_root=engine.config.asset_root,
)
request = downloader.ingest_request(
    datetime(2023, 1, 1, 6),
    time_index=1,
    download=True,
)
batch = engine.prepare(request, rollout_steps=4)
forecasts = list(engine.rollout_stream(batch, steps=4))
engine.release_gpu(move_model_to_cpu=True)
engine.close()
Scheduler loopback, two-GPU placement, and the notebook index: docs/tutorial.md.
Production mixed precision is faster than unfused FP32 and stays closer to that twin than framework autocast. One forward step on RTX PRO 6000 Blackwell, measured with PyTorch 2.14.0 and CuTe DSL 4.7.1, is about bf16_mixed@tf32) and about bf16_mixed@fp32), versus about --isolate-tiers).

Recommended tiers stay within per-variable tolerances versus the unfused FP32 reference (seed 42). The one exception is bf16_mixed@tf32 on aurora_v1p5_ensemble, where scaled_tp_1h is about bf16@* is not a production path because the full BF16 GEMM path corruptted
the prediction in experiments.

Window-attention kernels are short-window CuTe DSL (N = 144 on the default

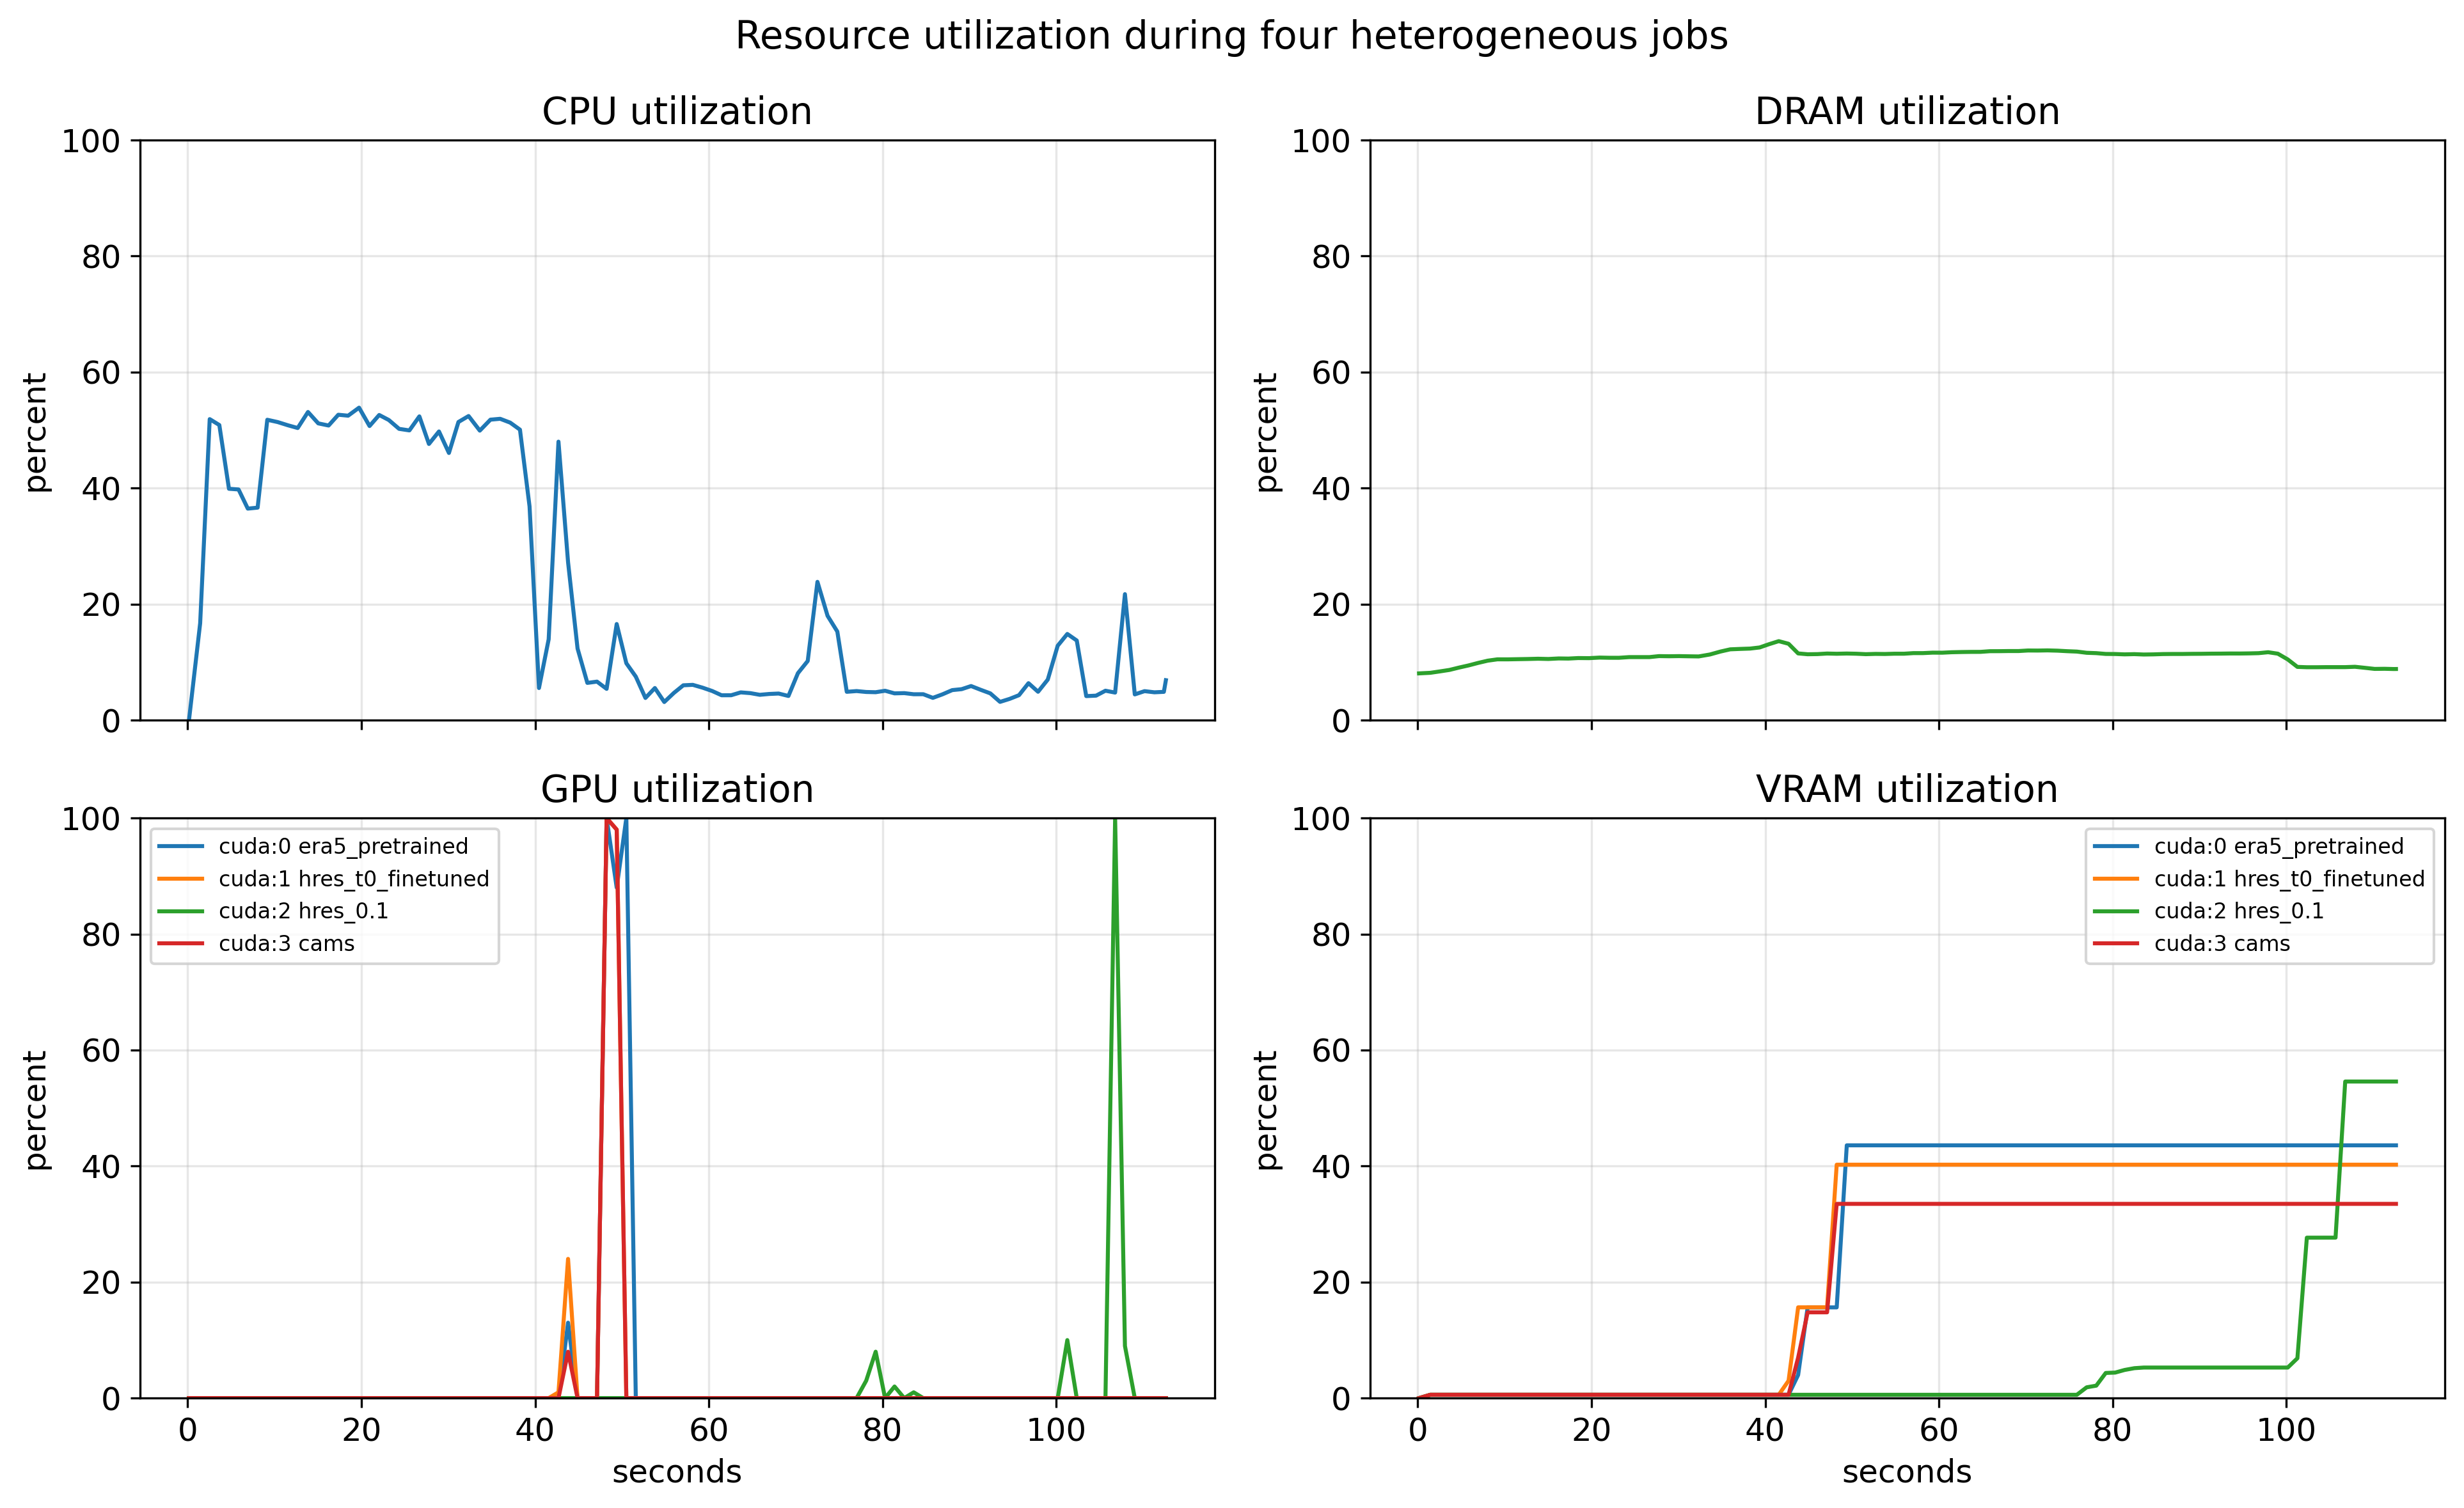
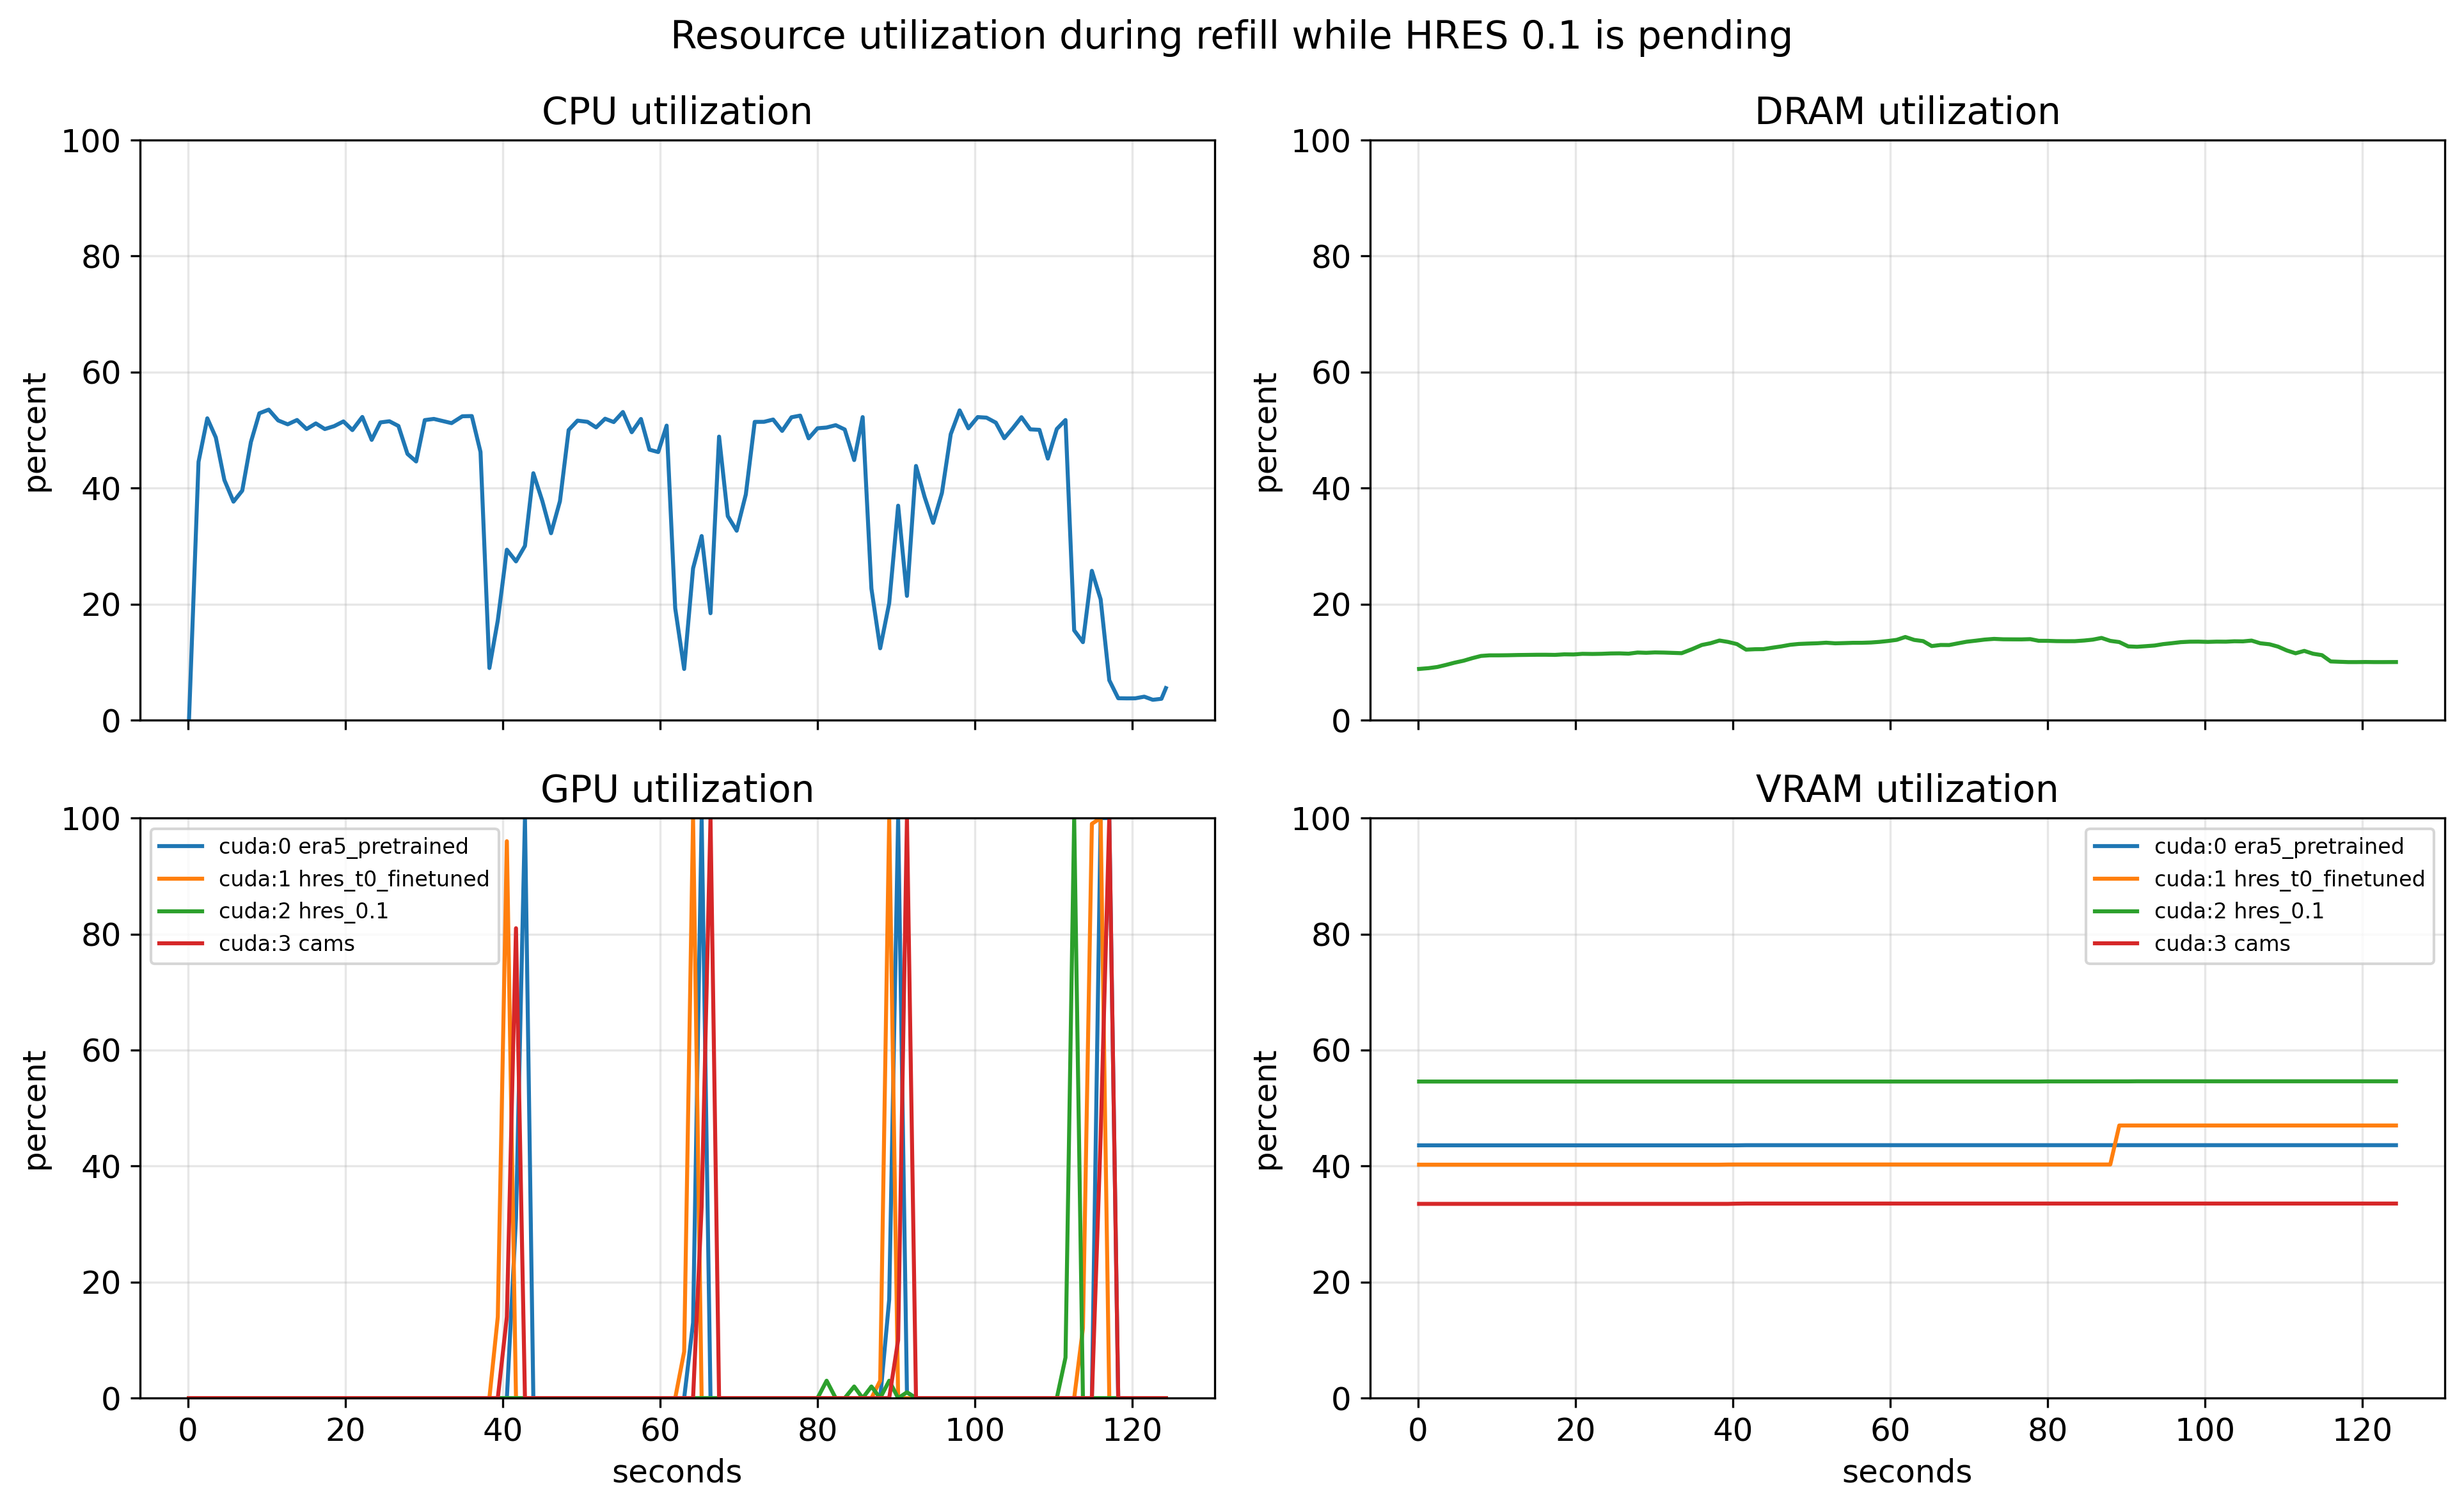
Serving is one GPU per job. A ZeroMQ coordinator fills idle workers; it does not batch tokens inside one forward. Scheduler notebooks.
| One job per worker | Refill while hres_0.1 is pending |
|---|---|
 |
 |
A preset that does not fit one GPU can run encoder / backbone / decoder on two devices in the same process (DistributedConfig). ROI export clips on the egress path so a region of interest does not require a global dump.
| Preset | Grid | Source |
|---|---|---|
era5_pretrained |
CDS ERA5 | |
aurora_v1p5 / aurora_v1p5_ensemble
|
CDS ERA5 (extended) | |
small_pretrained |
CDS ERA5 | |
hres_t0_finetuned / tc_tracking
|
WeatherBench2 HRES | |
hres_0.1 |
IFS analysis | |
cams |
CAMS | |
wave |
WB2 + MARS |
wave usually needs a hand-placed MARS cache; see example_wave.ipynb. Notebooks for every preset are listed in the tutorial.
MIT. Aurora code is derived from Microsoft Aurora (MIT), frozen at v1.8.0, with Aurora 1.5 from tag v2.0.1. Kernel files under flash_aurora.models.ops follow their per-file headers (including NVIDIA BSD-3-Clause where noted).
Bodnar et al., A Foundation Model for the Earth System, Nature (2025). doi:10.1038/s41586-025-09005-y. Upstream docs: microsoft.github.io/aurora.