diff --git a/.dockerignore b/.dockerignore
new file mode 100644
index 00000000..b8c7539e
--- /dev/null
+++ b/.dockerignore
@@ -0,0 +1,9 @@
+# Keep docker build contexts light: images COPY only pyproject.toml,
+# README.md, LICENSE and serviette/ (see benchmarks/*/Dockerfile).
+.git
+.venv*
+benchmarks
+docs
+tests
+results
+**/__pycache__
diff --git a/.github/ISSUE_TEMPLATE/bug_report.yml b/.github/ISSUE_TEMPLATE/bug_report.yml
deleted file mode 100644
index 2b5ab6f3..00000000
--- a/.github/ISSUE_TEMPLATE/bug_report.yml
+++ /dev/null
@@ -1,66 +0,0 @@
-name: Bug Report
-description: File a bug report
-title: "[Bug]: "
-labels: ["bug"]
-body:
- - type: markdown
- attributes:
- value: |
- Thanks for taking the time to fill out this bug report!
- - type: textarea
- id: what-happened
- attributes:
- label: Steps to reproduce
- description: What happened and how to reproduce it?
- placeholder: Tell us what you see!
- validations:
- required: true
- - type: textarea
- id: logs
- attributes:
- label: Relevant log output
- description: Please copy and paste any relevant log output. This will be automatically formatted into code, so no need for backticks.
- placeholder: Tell us what you see! It would be nice if you could leave us the logs.
- render: text
- validations:
- required: true
- - type: textarea
- id: what-did-you-expect
- attributes:
- label: What did you expect to happen?
- description: Also tell us, what did you expect to happen?
- placeholder: Describe your expectations.
- validations:
- required: true
- - type: input
- id: pathway_version
- attributes:
- label: Version
- description: On which version of the Pathway Live Data Framework are you working?
- validations:
- required: true
- - type: input
- id: docker_version
- attributes:
- label: Docker Versions (if used)
- description: On which Docker version are you working?
- validations:
- required: false
- - type: dropdown
- id: os_version
- attributes:
- label: OS
- description: On which OS did you run the Pathway Live Data Framework?
- options:
- - Linux
- - MacOS
- validations:
- required: true
- - type: dropdown
- id: cpu_architecture
- attributes:
- label: On which CPU architecture did you run the Pathway Live Data Framework?
- multiple: false
- options:
- - x86-64
- - ARM64 (AArch64, Apple silicon)
diff --git a/.github/ISSUE_TEMPLATE/config.yml b/.github/ISSUE_TEMPLATE/config.yml
deleted file mode 100644
index 0279986d..00000000
--- a/.github/ISSUE_TEMPLATE/config.yml
+++ /dev/null
@@ -1,8 +0,0 @@
-blank_issues_enabled: false
-contact_links:
- - name: New feature? Tell us about it on GitHub Discussions
- url: https://github.com/pathwaycom/pathway/discussions
- about: We are using Discussions as a place to connect with other members of the Pathway community.
- - name: Discord
- url: https://discord.com/invite/pathway
- about: Ask questions you are wondering about.
diff --git a/.github/assets/banner.png b/.github/assets/banner.png
deleted file mode 100644
index 81a8cf0f..00000000
Binary files a/.github/assets/banner.png and /dev/null differ
diff --git a/.github/assets/streamlit_chat.png b/.github/assets/streamlit_chat.png
deleted file mode 100644
index 5e0f9941..00000000
Binary files a/.github/assets/streamlit_chat.png and /dev/null differ
diff --git a/.github/assets/video-th.png b/.github/assets/video-th.png
deleted file mode 100644
index 092cfdc9..00000000
Binary files a/.github/assets/video-th.png and /dev/null differ
diff --git a/.github/pull_request_template.md b/.github/pull_request_template.md
deleted file mode 100644
index 0a28c945..00000000
--- a/.github/pull_request_template.md
+++ /dev/null
@@ -1,27 +0,0 @@
-### Introduction
-To contribute code to the Pathway Live Data Framework project, start by discussing your proposed changes on Discord or by filing an issue.
-Once approved, follow the fork + pull request model against the main branch, ensuring you've signed the contributor license agreement.
-
-### Context
-
-
-### How has this been tested?
-
-
-### Types of changes
-
-- [ ] Bug fix (non-breaking change which fixes an issue)
-- [ ] New feature or improvement (non-breaking change which adds functionality)
-- [ ] Breaking change (fix or feature that would cause existing functionality to not work as expected)
-
-### Related issue(s):
-1.
-2.
-3.
-
-### Checklist:
-
-
-- [ ] My code follows the code style of this project,
-- [ ] My change requires a change to the documentation,
-- [ ] I described the modification in the CHANGELOG.md file.
\ No newline at end of file
diff --git a/.github/workflows/ci.yml b/.github/workflows/ci.yml
new file mode 100644
index 00000000..e5f8ad4f
--- /dev/null
+++ b/.github/workflows/ci.yml
@@ -0,0 +1,125 @@
+# CI: lint + fast unit tests on every push/PR; the engine-backed suites
+# (slow e2e, per-database integration) run when the PATHWAY_LICENSE_KEY
+# secret is configured and skip gracefully when it is not.
+#
+# All dependencies come from PyPI (pathway >= 0.32.1 ships everything
+# serviette needs); uv is kept for install speed only.
+
+name: CI
+
+on:
+ push:
+ branches: [main]
+ pull_request:
+
+concurrency:
+ group: ${{ github.workflow }}-${{ github.ref }}
+ cancel-in-progress: ${{ github.ref != 'refs/heads/main' }}
+
+jobs:
+ lint-and-fast:
+ name: lint + fast tests (py${{ matrix.python }})
+ runs-on: ubuntu-latest
+ timeout-minutes: 45
+ strategy:
+ fail-fast: false
+ matrix:
+ python: ["3.10", "3.12", "3.14"]
+ steps:
+ - uses: actions/checkout@v4
+ - uses: actions/setup-python@v5
+ with:
+ python-version: ${{ matrix.python }}
+ - uses: actions/cache@v4
+ with:
+ path: ~/.cache/uv
+ key: uv-${{ runner.os }}-py${{ matrix.python }}-${{ hashFiles('pyproject.toml') }}
+ - name: Install
+ run: |
+ pip install -U uv
+ uv venv .venv
+ # pyfilesystem here is a CI-environment choice, not a package
+ # dependency: it keeps the optional-source tests exercised instead
+ # of being skipped (they importorskip when the extra is absent).
+ uv pip install --python .venv/bin/python -e ".[dev,local,pyfilesystem]"
+ .venv/bin/python -c "import pathway; print('pathway', pathway.__version__)"
+ - name: Ruff
+ run: .venv/bin/python -m ruff check serviette tests
+ - name: Fast tests
+ run: .venv/bin/python -m pytest tests/ -m "not slow and not integration" -q
+
+ slow:
+ name: e2e indexer / up / demo smoke
+ runs-on: ubuntu-latest
+ timeout-minutes: 75
+ needs: lint-and-fast
+ steps:
+ - uses: actions/checkout@v4
+ - name: Check license secret
+ id: license
+ run: |
+ if [ -n "${{ secrets.PATHWAY_LICENSE_KEY }}" ]; then
+ echo "present=true" >> "$GITHUB_OUTPUT"
+ else
+ echo "present=false" >> "$GITHUB_OUTPUT"
+ echo "::warning::PATHWAY_LICENSE_KEY secret is not set — skipping the engine-backed suite"
+ fi
+ - uses: actions/setup-python@v5
+ if: steps.license.outputs.present == 'true'
+ with:
+ python-version: "3.12"
+ - uses: actions/cache@v4
+ if: steps.license.outputs.present == 'true'
+ with:
+ path: ~/.cache/uv
+ key: uv-${{ runner.os }}-py3.12-${{ hashFiles('pyproject.toml') }}
+ - name: Install
+ if: steps.license.outputs.present == 'true'
+ run: |
+ pip install -U uv
+ uv venv .venv
+ uv pip install --python .venv/bin/python -e ".[dev,local,pyfilesystem]"
+ - name: Slow tests (multimodal parser tests excluded — they download models)
+ if: steps.license.outputs.present == 'true'
+ env:
+ PATHWAY_LICENSE_KEY: ${{ secrets.PATHWAY_LICENSE_KEY }}
+ run: |
+ .venv/bin/python -m pytest tests/ -m "slow and not integration" -q \
+ --ignore=tests/test_multimodal_parsers.py
+
+ integration:
+ name: vector-DB integration matrix (docker)
+ runs-on: ubuntu-latest
+ timeout-minutes: 90
+ needs: lint-and-fast
+ steps:
+ - uses: actions/checkout@v4
+ - name: Check license secret
+ id: license
+ run: |
+ if [ -n "${{ secrets.PATHWAY_LICENSE_KEY }}" ]; then
+ echo "present=true" >> "$GITHUB_OUTPUT"
+ else
+ echo "present=false" >> "$GITHUB_OUTPUT"
+ echo "::warning::PATHWAY_LICENSE_KEY secret is not set — skipping the integration matrix"
+ fi
+ - uses: actions/setup-python@v5
+ if: steps.license.outputs.present == 'true'
+ with:
+ python-version: "3.12"
+ - uses: actions/cache@v4
+ if: steps.license.outputs.present == 'true'
+ with:
+ path: ~/.cache/uv
+ key: uv-${{ runner.os }}-py3.12-${{ hashFiles('pyproject.toml') }}
+ - name: Install
+ if: steps.license.outputs.present == 'true'
+ run: |
+ pip install -U uv
+ uv venv .venv
+ uv pip install --python .venv/bin/python -e ".[dev,all,local,pyfilesystem,sharepoint]"
+ - name: Integration tests
+ if: steps.license.outputs.present == 'true'
+ env:
+ PATHWAY_LICENSE_KEY: ${{ secrets.PATHWAY_LICENSE_KEY }}
+ run: .venv/bin/python -m pytest tests/ -m integration -q
diff --git a/.github/workflows/python-lint.yml b/.github/workflows/python-lint.yml
deleted file mode 100644
index 31dc2968..00000000
--- a/.github/workflows/python-lint.yml
+++ /dev/null
@@ -1,33 +0,0 @@
-name: lint PR
-on:
- pull_request:
- push:
- branches:
- - main
-concurrency:
- group: ${{ github.workflow }}-${{ github.ref }}
- cancel-in-progress: ${{ github.ref != 'refs/heads/main'}}
-jobs:
- linter:
- runs-on: ubuntu-latest
- strategy:
- fail-fast: false
- steps:
- - name: Git checkout
- uses: actions/checkout@v3
- - name: Set up Python
- uses: actions/setup-python@v5
- with:
- python-version: 3.11
- - name: Install poetry
- uses: abatilo/actions-poetry@v3
- - name: Install linters
- run: poetry install --no-root --only linters
- - name: Run black
- run: poetry run black --check .
- - name: Run Flake8
- run: poetry run flake8 .
- - name: Run mypy
- run: poetry run mypy .
- - name: Run isort
- run: poetry run isort --check .
diff --git a/.gitignore b/.gitignore
index ec5212f2..e68c6beb 100644
--- a/.gitignore
+++ b/.gitignore
@@ -1,6 +1,6 @@
# Byte-compiled / optimized / DLL files
__pycache__/
-*.py[cod]
+*.py[codz]
*$py.class
# C extensions
@@ -27,8 +27,8 @@ share/python-wheels/
MANIFEST
# PyInstaller
-# Usually these files are written by a python script from a template
-# before PyInstaller builds the exe, so as to inject date/other infos into it.
+# Usually these files are written by a python script from a template
+# before PyInstaller builds the exe, so as to inject date/other infos into it.
*.manifest
*.spec
@@ -46,7 +46,7 @@ htmlcov/
nosetests.xml
coverage.xml
*.cover
-*.py,cover
+*.py.cover
.hypothesis/
.pytest_cache/
cover/
@@ -58,8 +58,6 @@ cover/
# Django stuff:
*.log
local_settings.py
-db.sqlite3
-db.sqlite3-journal
# Flask stuff:
instance/
@@ -92,22 +90,37 @@ ipython_config.py
# However, in case of collaboration, if having platform-specific dependencies or dependencies
# having no cross-platform support, pipenv may install dependencies that don't work, or not
# install all needed dependencies.
-#Pipfile.lock
+# Pipfile.lock
+
+# UV
+# Similar to Pipfile.lock, it is generally recommended to include uv.lock in version control.
+# This is especially recommended for binary packages to ensure reproducibility, and is more
+# commonly ignored for libraries.
+# uv.lock
# poetry
# Similar to Pipfile.lock, it is generally recommended to include poetry.lock in version control.
# This is especially recommended for binary packages to ensure reproducibility, and is more
# commonly ignored for libraries.
# https://python-poetry.org/docs/basic-usage/#commit-your-poetrylock-file-to-version-control
-#poetry.lock
+# poetry.lock
+# poetry.toml
# pdm
# Similar to Pipfile.lock, it is generally recommended to include pdm.lock in version control.
-#pdm.lock
-# pdm stores project-wide configurations in .pdm.toml, but it is recommended to not include it
-# in version control.
-# https://pdm.fming.dev/#use-with-ide
-.pdm.toml
+# pdm recommends including project-wide configuration in pdm.toml, but excluding .pdm-python.
+# https://pdm-project.org/en/latest/usage/project/#working-with-version-control
+# pdm.lock
+# pdm.toml
+.pdm-python
+.pdm-build/
+
+# pixi
+# Similar to Pipfile.lock, it is generally recommended to include pixi.lock in version control.
+# pixi.lock
+# Pixi creates a virtual environment in the .pixi directory, just like venv module creates one
+# in the .venv directory. It is recommended not to include this directory in version control.
+.pixi
# PEP 582; used by e.g. github.com/David-OConnor/pyflow and github.com/pdm-project/pdm
__pypackages__/
@@ -116,11 +129,25 @@ __pypackages__/
celerybeat-schedule
celerybeat.pid
+# Redis
+*.rdb
+*.aof
+*.pid
+
+# RabbitMQ
+mnesia/
+rabbitmq/
+rabbitmq-data/
+
+# ActiveMQ
+activemq-data/
+
# SageMath parsed files
*.sage.py
# Environments
-**/.env
+.env
+.envrc
.venv
env/
venv/
@@ -153,13 +180,58 @@ dmypy.json
cython_debug/
# PyCharm
-# JetBrains specific template is maintained in a separate JetBrains.gitignore that can
-# be found at https://github.com/github/gitignore/blob/main/Global/JetBrains.gitignore
-# and can be added to the global gitignore or merged into this file. For a more nuclear
-# option (not recommended) you can uncomment the following to ignore the entire idea folder.
-#.idea/
-
-pw-env/
-
-# llm debug
-examples/ui/data/*
\ No newline at end of file
+# JetBrains specific template is maintained in a separate JetBrains.gitignore that can
+# be found at https://github.com/github/gitignore/blob/main/Global/JetBrains.gitignore
+# and can be added to the global gitignore or merged into this file. For a more nuclear
+# option (not recommended) you can uncomment the following to ignore the entire idea folder.
+# .idea/
+
+# Abstra
+# Abstra is an AI-powered process automation framework.
+# Ignore directories containing user credentials, local state, and settings.
+# Learn more at https://abstra.io/docs
+.abstra/
+
+# Visual Studio Code
+# Visual Studio Code specific template is maintained in a separate VisualStudioCode.gitignore
+# that can be found at https://github.com/github/gitignore/blob/main/Global/VisualStudioCode.gitignore
+# and can be added to the global gitignore or merged into this file. However, if you prefer,
+# you could uncomment the following to ignore the entire vscode folder
+# .vscode/
+# Temporary file for partial code execution
+tempCodeRunnerFile.py
+
+# Ruff stuff:
+.ruff_cache/
+
+# PyPI configuration file
+.pypirc
+
+# Marimo
+marimo/_static/
+marimo/_lsp/
+__marimo__/
+
+# Streamlit
+.streamlit/secrets.toml
+
+# serviette test-run runtime artifacts
+
+# benchmark datasets and results (large, generated)
+benchmarks/*/datasets/
+benchmarks/*/results/
+benchmarks/*/compat/*.so
+
+# Runtime working directory of `serviette demo` (regenerable: corpus copy,
+# generated config, DuckDB store, workdir)
+serviette-demo/
+
+# Default `workdir_path` (persistence state, fingerprint)
+serviette-workdir/
+
+# Internal planning document — kept local, never committed (purged from
+# history on 2026-07-09).
+docs/ROADMAP.md
+scripts/
+ROADMAP.md
+.venv*/
diff --git a/.vscode/settings.json b/.vscode/settings.json
deleted file mode 100644
index 91c0bf95..00000000
--- a/.vscode/settings.json
+++ /dev/null
@@ -1,17 +0,0 @@
-{
- "python.defaultInterpreterPath": "${env:HOME}/pw-env/bin/python",
- "python.formatting.provider": "none",
- "editor.formatOnSave": true,
- "python.linting.enabled": true,
- "python.linting.flake8Enabled": true,
- "python.linting.mypyEnabled": true,
- "[python]": {
- "files.trimTrailingWhitespace": true,
- "editor.rulers": [88],
- "editor.codeActionsOnSave": {
- "source.organizeImports": "explicit"
- },
- "editor.defaultFormatter": "ms-python.black-formatter"
- },
- "git.autofetchPeriod": 315360000
-}
diff --git a/CODE_OF_CONDUCT.md b/CODE_OF_CONDUCT.md
deleted file mode 100644
index 0a7887e5..00000000
--- a/CODE_OF_CONDUCT.md
+++ /dev/null
@@ -1,80 +0,0 @@
-# Pathway Code of Conduct
-
-In the interest of fostering an open and welcoming environment, we as
-contributors and maintainers pledge to make participation in our project and our
-community a harassment-free experience for everyone, regardless of age, body
-size, disability, health condition, ethnicity, gender identity and expression, level of
-experience, nationality, country of origin, personal appearance, race, religion, or sexual identity
-and orientation, and any other criteria falling under discriminatory practices under the Law of France.
-
-## Our Standards
-
-Examples of behavior that contributes to creating a positive environment include:
-
-* Using welcoming and inclusive language.
-* Being respectful of differing viewpoints and experiences.
-* Gracefully accepting constructive criticism.
-* Focusing on what is best for the community.
-* Showing empathy towards other community members.
-
-Examples of unacceptable behavior by participants include:
-
-* The use of sexualized language or imagery and unwelcome sexual attention or
- advances.
-* Trolling, insulting/derogatory comments, and personal or political attacks.
-* Public or private harassment.
-* Publishing others' private information, such as a physical or electronic
- address, without explicit permission.
-* Conduct which could reasonably be considered inappropriate for the forum in
- which it occurs.
-
-All Pathway forums and spaces are meant for professional interactions, and any behavior which could reasonably be considered inappropriate in a professional setting is unacceptable.
-
-
-## Our Responsibilities
-
-Project maintainers are responsible for clarifying the standards of acceptable behavior and are expected to take appropriate and fair corrective action in response to any instances of unacceptable behavior.
-
-Project maintainers have the right and responsibility to remove, edit, or reject comments, commits, code, wiki edits, issues, and other contributions that are not aligned to this Code of Conduct, or to ban temporarily or permanently any contributor for other behaviors that they deem inappropriate, threatening, offensive, or harmful.
-
-
-## Scope
-
-This Code of Conduct applies to all content on pathway.com, Pathway’s GitHub organization, or any other official Pathway web presence allowing for community interactions, as well as at all official Pathway events, whether offline or online.
-
-The Code of Conduct also applies within project spaces and in public spaces whenever an individual is representing Pathway or its community. Examples of representing a project or community include using an official project e-mail address, posting via an official social media account, or acting as an appointed or de facto representative at an online or offline event.
-
-
-## Conflict Resolution
-
-Conflicts in an open source project can take many forms, from someone having a bad day and using harsh and hurtful language in the issue queue, to more serious instances such as sexist/racist statements or threats of violence, and everything in between.
-
-If the behavior is threatening or harassing, or for other reasons requires immediate escalation, please see below.
-
-However, for the vast majority of issues, we aim to empower individuals to first resolve conflicts themselves, asking for help when needed, and only after that fails to escalate further. This approach gives people more control over the outcome of their dispute.
-
-If you are experiencing or witnessing conflict, we ask you to use the following escalation strategy to address the conflict:
-
-1. If you so wish and if you do not feel threatened or at risk of any form of personal abuse, address the perceived conflict directly with those involved, preferably in a real-time medium.
-2. If this fails, get a third party (e.g. a mutual friend, and/or someone with
- background on the issue, but not involved in the conflict) to intercede.
-3. If you are still unable to resolve the conflict, and you believe it rises to
- harassment or another code of conduct violation, report it.
-
-Please note that if you are experiencing or witnessing a discriminatory practice that would be susceptible to be condemned by law, we ask you to directly escalate to 3.
-
-## Reporting Violations
-
-Violations of the Code of Conduct can be reported to Pathway via email to code_of_conduct@pathway.com. Project maintainers will determine whether the Code of Conduct was violated, and will issue an appropriate sanction, possibly including a written warning or expulsion from the project, project sponsored spaces, or project forums. We ask that you make a good-faith effort to resolve your conflict via the conflict resolution policy before submitting a report.
-
-Violations of the Code of Conduct can occur in any setting, even those unrelated to the project. We will only consider complaints about conduct that has occurred within one year of the report.
-
-
-## Enforcement
-
-If the Project maintainers receive a report alleging a violation of the Code of Conduct, the Project maintainers will notify the accused of the report, and provide them an opportunity to discuss the report before a sanction is issued. The Project maintainers will do their utmost to keep the reporter anonymous. If the act is ongoing (such as someone engaging in harassment), or involves a threat to anyone's safety (e.g. threats of violence), the Project maintainers may issue sanctions without notice.
-
-
-## Attribution
-
-This Code of Conduct is adapted from the Tensorflow Code of Conduct, and based on Contributor Covenant, version 1.4, available at https://contributor-covenant.org/version/1/4, and includes some aspects of the Geek Feminism Code of Conduct and the Drupal Code of Conduct.
diff --git a/CONTRIBUTING.md b/CONTRIBUTING.md
deleted file mode 100644
index 088f9e0f..00000000
--- a/CONTRIBUTING.md
+++ /dev/null
@@ -1,33 +0,0 @@
-# Contributing to the Pathway Live Data Framework
-
-Welcome! This guide is intended to help developers that are new to the community
-to make contributions to the Pathway Live Data Framework project. Please be sure to also read our [code of conduct](CODE_OF_CONDUCT.md). We work hard to make this a welcoming community for all, and we're excited to have you on board!
-
-## The basics:
-
-* Use the [Issue Tracker](https://github.com/pathwaycom/llm-app/issues) to
- report bugs, crashes, performance issues, etc... Please include as much detail
-
- as possible.
-
-* [Discussions](https://github.com/pathwaycom/pathway/discussions) is a great
- venue to ask questions, start a design discussion, or post an RFC.
-
-* [Discord](https://discord.com/invite/pathway) is our main gathering place - jump in and ask us anything!
-
-## Contributing Code
-
-We are eager to build the Pathway Live Data Framework together with the community and are excited to have you here!
-
-Important: Before you contribute any changes to our repositories (make a Pull Request) please get in touch with us and explain what you want to work on. You can do so by filing an issue, or asking us on Discord. That way you can get coding advice and speedier reviews. If you start to work on an issue before hearing back from a Pathway core team engineer there is a chance that we will not be able to accept your changes - something we all want to avoid!
-
-We use a standard GitHub fork + pull request model for merging and reviewing
-changes. New pull requests should be made against the main upstream branch.
-After a pull request is opened it will be reviewed, and merged after
-passing continuous integration tests and being accepted by a project or
-sub-system maintainer.
-
-We ask that developers sign our [contributor license
-agreement](https://cla-assistant.io/pathwaycom/llm-app). The
-process of signing the CLA is automated, and you'll be prompted with instructions
-the first time you submit a pull request to the project.
diff --git a/LICENSE b/LICENSE
index 7568843d..1054e849 100644
--- a/LICENSE
+++ b/LICENSE
@@ -1,6 +1,6 @@
MIT License
-Copyright (c) 2022 Pathway
+Copyright (c) 2026 Sergey Kulik
Permission is hereby granted, free of charge, to any person obtaining a copy
of this software and associated documentation files (the "Software"), to deal
diff --git a/README.md b/README.md
index 5f18d70b..f8333c60 100644
--- a/README.md
+++ b/README.md
@@ -1,89 +1,523 @@
-
-
-# Pathway Live Data Framework AI Pipelines
-
-
-
-
-
-[](https://discord.gg/pathway)
-[](https://x.com/intent/follow?screen_name=pathway_com)
-
-
-The Pathway Live Data Framework's **AI Pipelines** allow you to quickly put in production AI applications that offer **high-accuracy RAG and AI enterprise search at scale** using the most **up-to-date knowledge** available in your data sources. It provides you ready-to-deploy **LLM (Large Language Model) App Templates**. You can test them on your own machine and deploy on-cloud (GCP, AWS, Azure, Render,...) or on-premises.
-
-The apps connect and sync (all new data additions, deletions, updates) with data sources on your **file system, Google Drive, Sharepoint, S3, Kafka, PostgreSQL, real-time data APIs**. They come with no infrastructure dependencies that would need a separate setup. They include **built-in data indexing** enabling vector search, hybrid search, and full-text search - all done in-memory, with cache.
-
-
-## Application Templates
-
-The application templates provided in this repo scale up to **millions of pages of documents**. Some of them are optimized for simplicity, some are optimized for amazing accuracy. Pick the one that suits you best. You can use it out of the box, or change some steps of the pipeline - for example, if you would like to add a new data source, or change a Vector Index into a Hybrid Index, it's just a one-line change.
-
-| Application (template) | Description |
-| --------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
-| [`Question-Answering RAG App`](templates/question_answering_rag/) | Basic end-to-end RAG app. A question-answering pipeline that uses the GPT model of choice to provide answers to queries to your documents (PDF, DOCX,...) on a live connected data source (files, Google Drive, Sharepoint,...). You can also try out a [demo REST endpoint](https://pathway.com/solutions/rag-pipelines#try-it-out). |
-| [`Live Document Indexing (Vector Store / Retriever)`](templates/document_indexing/) | A real-time document indexing pipeline for RAG that acts as a vector store service. It performs live indexing on your documents (PDF, DOCX,...) from a connected data source (files, Google Drive, Sharepoint,...). It can be used with any frontend, or integrated as a retriever backend for a [Langchain](https://pathway.com/blog/langchain-integration) or [Llamaindex](https://pathway.com/blog/llamaindex-pathway) application. You can also try out a [demo REST endpoint](https://pathway.com/solutions/ai-contract-management#try-it-out). |
-| [`Multimodal RAG pipeline with GPT4o`](templates/multimodal_rag/) | Multimodal RAG using GPT-4o in the parsing stage to index PDFs and other documents from a connected data source files, Google Drive, Sharepoint,...). It is perfect for extracting information from unstructured financial documents in your folders (including charts and tables), updating results as documents change or new ones arrive.|
-| [`Unstructured-to-SQL pipeline + SQL question-answering`](templates/unstructured_to_sql_on_the_fly/) | A RAG example which connects to unstructured financial data sources (financial report PDFs), structures the data into SQL, and loads it into a PostgreSQL table. It also answers natural language user queries to these financial documents by translating them into SQL using an LLM and executing the query on the PostgreSQL table. |
-| [`Adaptive RAG App`](templates/adaptive_rag/) | A RAG application using Adaptive RAG, a technique developed by Pathway to reduce token cost in RAG up to 4x while maintaining accuracy. |
-| [`Private RAG App with Mistral and Ollama`](templates/private_rag/) | A fully private (local) version of the `question_answering_rag` RAG pipeline using Pathway Live Data Framework, Mistral, and Ollama. |
-| [`Slides AI Search App`](templates/slides_ai_search/) | An indexing pipeline for retrieving slides. It performs multi-modal of PowerPoint and PDF and maintains live index of your slides."|
-| [`Video RAG with TwelveLabs`](templates/video_rag_twelvelabs/) | A RAG pipeline over **video**. It uses [TwelveLabs](https://twelvelabs.io) Pegasus to turn videos into rich text descriptions and Marengo multimodal embeddings to index them, so you can ask questions about your videos on a live connected data source (files, Google Drive,...). |
-
-
-## How do these AI Pipelines work?
-
-The apps can be run as **Docker containers**, and expose an **HTTP API** to connect the frontend. To allow quick testing and demos, some app templates also include an optional Streamlit UI which connects to this API.
-
-The apps rely on the [Pathway Live Data Framework](https://github.com/pathwaycom/pathway) for data source synchronization and for serving API requests (Pathway is a standalone Python library with a Rust engine built into it). They bring you a **simple and unified application logic** for back-end, embedding, retrieval, LLM tech stack. There is no need to integrate and maintain separate modules for your Gen AI app: ~Vector Database (e.g. Pinecone/Weaviate/Qdrant) + Cache (e.g. Redis) + API Framework (e.g. Fast API)~. Pathway's default choice of **built-in vector index** is based on the lightning-fast [usearch](https://github.com/unum-cloud/usearch) library, and **hybrid full-text indexes** make use of [Tantivy](https://github.com/quickwit-oss/tantivy) library. Everything works out of the box.
-
-## Getting started
-
-Each of the [App templates](templates/) in this repo contains a README.md with instructions on how to run it.
-
-You can also find [more ready-to-run code templates](https://pathway.com/developers/templates/) on the Pathway website.
-
-
-## Some visual highlights
-
-Effortlessly extract and organize table and chart data from PDFs, docs, and more with multimodal RAG - in real-time:
-
-
-
-(Check out [`Multimodal RAG pipeline with GPT4o`](templates/multimodal_rag/) to see the whole pipeline in the works. You may also check out the [`Unstructured-to-SQL pipeline`](templates/unstructured_to_sql_on_the_fly/) for a minimal example that works with non-multimodal models as well.)
-
-
-Automated real-time knowledge mining and alerting:
-
-
-
-(Check out the [`Alerting when answers change on Google Drive`](https://github.com/pathwaycom/llm-app/tree/main/templates/drive_alert) app example.)
+# serviette
+
+
+
+
+
+
-### Do-it-Yourself Videos
+**A no-code, always up-to-date RAG server for any vector database — built on
+the [Pathway Live Data Framework](https://github.com/pathwaycom/pathway).**
-▶️ [An introduction to building LLM apps with Pathway Live Data Framework](https://www.youtube.com/watch?v=kcrJSk00duw) - by [Jan Chorowski](https://scholar.google.com/citations?user=Yc94070AAAAJ)
+Point serviette at a folder of documents, pick a vector database and an
+embedder in one YAML file, and run two commands: you get a chat and a REST API
+that answer from those documents and cite their sources. From then on, any
+change to the documents — an edit, a new file, a deletion — is reflected in
+the answers within seconds.
-▶️ [Let's build a real-world LLM app in 11 minutes](https://www.youtube.com/watch?v=k1XGo7ts4tI) - by [Pau Labarta Bajo](https://substack.com/@paulabartabajo)
+serviette runs on Pathway, which needs a **free license key** — one click at
+ (GitHub or LinkedIn sign-in). Every
+command below expects it in `PATHWAY_LICENSE_KEY`.
+Try it in four commands:
-## Troubleshooting
+```bash
+pip install serviette
+export PATHWAY_LICENSE_KEY=... # free: https://pathway.com/framework/get-license
+export OPENAI_API_KEY=sk-...
+serviette demo --embedder openai # → chat at http://localhost:8989
+```
-To provide feedback or report a bug, please [raise an issue on our issue tracker](https://github.com/pathwaycom/pathway/issues).
+**Use pip 23.1 or newer** (`python -m pip install -U pip` first): older pip lacks
+the resolver improvements this dependency tree needs and can take hours.
-## Contributing
+This indexes a [small bundled corpus](https://github.com/pathwaycom/serviette/tree/main/serviette/demo/corpus) (a fictional
+coffee-machine company) into `./serviette-demo/docs` and opens a chat over
+it. Edit or drop files into that folder while it runs — the answers
+follow within seconds.
-Anyone who wishes to contribute to this project, whether documentation, features, bug fixes, code cleanup, testing, or code reviews, is very much encouraged to do so. If this is your first contribution to a GitHub project, here is a [Get Started Guide](https://docs.github.com/en/get-started/quickstart/contributing-to-projects).
+
+
+
+
One command to a live RAG stack — then edit a document and watch the answer change.
+
+## Who is it for
+
+**What you get.** A question-answering assistant over your organisation's
+documents, with sources cited and answers that follow the documents: an edit,
+a new file or a deletion is reflected within seconds, with no re-upload or
+re-indexing step for anyone to run or forget.
+
+**What it costs to run.** Two processes (an indexer and a server) and one YAML
+file. Embeddings can be computed locally for free; the Pathway license is
+free; the only metered component is the optional model API that writes the
+answer text, billed per question rather than per document.
+
+**Where your data goes.** Nowhere by default. With the default local
+embedder, documents, their embeddings and the index stay on the machine or in
+the database you choose; the only thing that leaves is the handful of passages
+retrieved for a question, sent to the model API that writes the answer — and
+only if you configure one. (Choosing an API embedder instead sends the
+document text through that API as well.)
+
+**How mature it is.** serviette is a thin layer over the
+[Pathway Live Data Framework](https://github.com/pathwaycom/pathway) — the
+open-source engine that does the watching, parsing, embedding and writing: in
+development since 2022, 60 000+ GitHub stars, in production use at
+organisations such as
+[DB Schenker](https://pathway.com/success-stories/db-schenker),
+[Intel](https://pathway.com/framework/blog/intel-summit),
+[NATO](https://pathway.com/blog/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024),
+[La Poste](https://pathway.com/success-stories/la-poste),
+[Transdev](https://pathway.com/success-stories/transdev) and
+[CMA CGM](https://pathway.com/success-stories/cma-cgm).
+serviette's own numbers are measured, not estimated: indexing
+up to 50 GB of text (26 million pages, 17 million files) in constant memory,
+retrieval accuracy on a public benchmark (FRAMES), eight vector databases
+under integration tests against real instances — all reproducible from this
+repository.
+
+**Where it stands today.** It answers one question at a time, from the
+current state of the documents. Conversation memory, user accounts and a
+hosted offering are not built in yet — and each is a short step from what is
+here. If your use case needs one of them, or something else, contact us for a
+tailor-made solution:
+[open an issue](https://github.com/pathwaycom/serviette/issues), write on
+[Discord](https://discord.gg/pathway), or email
+[contact@pathway.com](mailto:contact@pathway.com).
+
+The rest of this README is for the person setting it up.
+
+To run it over your own documents, generate a config and start the stack:
+
+```bash
+pip install "serviette[local]" --extra-index-url https://download.pytorch.org/whl/cpu
+ # [local] = free local embeddings, the wizard's default. It brings PyTorch; the
+ # --extra-index-url picks its CPU build (~0.8 GB) instead of the default one
+ # with CUDA libraries (~5 GB) — drop the flag only if you will embed on an
+ # NVIDIA GPU. Plain `pip install serviette` if you will embed with OpenAI instead.
+export PATHWAY_LICENSE_KEY=... # the free Pathway license (see above); the wizard picks it up from here
+export OPENAI_API_KEY=sk-... # powers generated answers; omit to run keyless (answers quote the retrieved snippets)
+
+serviette wizard # interactive config wizard
+serviette up --config config.yaml # indexer + server together → http://localhost:8989
+```
+
+(Production deployments run `serviette indexer` and `serviette server`
+separately — that is what `up` supervises.)
+
+The server hosts both the web chat UI (on `/`) and the versioned REST API
+(under `/api/v1`) on one port:
+
+```bash
+curl -X POST http://localhost:8989/api/v1/retrieve \
+ -H 'Content-Type: application/json' \
+ -d '{"query": "how does persistence work?", "k": 5}'
+```
+
+## Highlights
+
+- **No code.** Configure everything in one YAML file (or generate it with
+ `serviette wizard`).
+- **Any vector DB — 8 backends.** DuckDB (embedded, zero setup — the default),
+ pgvector, Qdrant, Milvus, ChromaDB, Weaviate, Pinecone and MongoDB Atlas
+ Vector Search. Every backend is written through **Pathway's native
+ connectors**, so file edits and deletions become real upserts/deletes in
+ the store.
+- **Zero-setup default.** DuckDB is the default backend: an embedded
+ database in a single local file, no external service to install or run,
+ with built-in vector search.
+- **Live & incremental.** Built on Pathway: additions, edits and deletions
+ are reflected in the vector DB in real time — whatever you change is
+ answerable seconds later. Documents flow through the pipeline instead of
+ accumulating in it, so a large corpus stays small in memory.
+- **Multiple sources.** Local filesystem, Google Drive, S3/MinIO, SharePoint
+ — plus anything the PyFilesystem library opens: FTP, SFTP, WebDAV, even ZIP
+ archives. All watched live, mixed freely in one config.
+- **Multimodal out of the box.** Text, Office documents, PDFs (with tables
+ and layout), scanned images — and, with the corresponding API keys, audio
+ recordings and even video. Every format is on by default and routed to the
+ best parser that needs no API key; drop a file in the folder and it is
+ answerable like any document. See [Multimodality](#multimodality).
+- **Reuses Pathway's LLM xpack.** Parsers, splitters and embedders are used
+ as-is — serviette implements none of its own. Five embedder families (OpenAI,
+ LiteLLM, SentenceTransformers, Gemini, Bedrock) work identically on the
+ indexer and the server side — including a fully local, credential-free
+ stack with local embeddings + DuckDB.
+- **Decoupled & scalable.** Indexer and API server are independent processes
+ sharing only the vector DB. The server is stateless and scales
+ horizontally; the indexer shards across worker processes with one config
+ line. Every part scales on its own.
+- **Web chat UI, same port.** `serviette server` serves a clean
+ ChatGPT/Claude-style chat page on `/` next to the versioned API
+ (`/api/v1/...`) — same origin, no CORS, nothing extra to run. For split
+ deployments (UI on a different host) there is a standalone
+ `serviette frontend` proxy tier.
+- **Free Pathway license.** One click at
+ .
+
+## Architecture
-If you'd like to make a contribution that needs some more work, just raise your hand on the [Pathway Discord server](https://discord.com/invite/pathway) (#get-help) and let us know what you are planning!
+
+
+
-## Supported and maintained by
+**The two halves are fully decoupled.** The indexer (write path) and the
+server (read path) are separate processes — different executables that never
+talk to each other. Their only contract is the vector database itself:
+
+- **Independent scaling.** The server is stateless and read-only — run any
+ number of instances behind a load balancer; each also serves the chat UI at
+ zero cost. The indexer scales separately: Pathway shards it across worker
+ processes (`indexer.workers: 8` is how the benchmarks below run), so every
+ part of the stack scales independently. Bulk re-indexing never slows down
+ query serving, and query spikes never stall indexing.
+- **Failure isolation.** If the indexer is down, serving continues over the
+ last-synced data; if the server is down, indexing keeps the database fresh.
+ Either side can be restarted or upgraded independently (the indexer resumes
+ from its persistence without re-embedding).
+- **The database stays yours.** Vectors live in *your* store in a plain,
+ documented schema — other consumers (BI, other apps, a different retrieval
+ stack) can read the same collection; serviette doesn't hold it hostage. And
+ since the default store is an embedded DuckDB file, trying this out costs
+ nothing to set up.
+- **Optional third tier.** For split deployments (UI on a different host than
+ the API) a standalone `serviette frontend` serves the same chat page and
+ proxies to the API server-side.
+
+The one deliberate exception: the embedded DuckDB backend trades this
+distribution for zero setup — one local file, single-writer, ideal for
+laptops and demos (see [docs](https://github.com/pathwaycom/serviette/blob/main/docs/README.md) for its concurrency note).
+
+## Benchmarks
+
+Two self-contained benchmarks, one per axis: what indexing costs in time
+and memory, and how accurate the retrieval is.
+
+### Indexing resources
+
+Self-contained benchmark (docker-compose: Qdrant + indexer + server, fully
+local embeddings, zero API cost) over a Wikipedia corpus of plain text —
+every byte below is extracted text (a PDF collection with the same text
+content would weigh several times more) —
+see [benchmarks/realtime-data-indexing](https://github.com/pathwaycom/serviette/tree/main/benchmarks/realtime-data-indexing):
+
+| corpus | ≈ pages | files | chunks | indexing time | peak memory (PSS) | in Qdrant |
+|---|---|---|---|---|---|---|
+| 100 MB | 52 000 | 12 969 | 66 136 | 39 s | 6.6 GB | 0.6 GB |
+| 1 GB | 524 000 | 240 516 | 836 595 | 4.8 min | 6.9 GB | 2.2 GB |
+| 3 GB | 1 573 000 | 841 890 | 2 703 850 | 15 min | 7.3 GB | 6.0 GB |
+| 10 GB | 5 243 000 | 3 423 359 | 10 093 514 | 58 min | 7.7 GB | 20.8 GB |
+| 30 GB | 15 729 000 | 9 202 620 | 29 817 294 | 2.9 h | 10.1 GB | 61.3 GB |
+| 50 GB | 26 214 000 | 17 083 603 | 53 913 774 | 5.5 h | 13.1 GB | 107.9 GB |
+
+Documents flow through the pipeline rather than accumulating in it, so
+what stays in memory is short and worth spelling out.
+
+**Grows with the corpus — one thing.** The file-watch index: to detect live
+edits and deletions, the indexer keeps a record (path, mtime, size, owner)
+per watched file. Measured cost: **~318 bytes per file** (paths of typical
+length; ±20% with the hash-table's load factor), verified from 13 thousand
+to 17 million files (right-hand plot: six corpus sizes against one fitted
+line). It scales with the *number of files*, not bytes: the same corpus
+packed into fewer, larger files costs proportionally less.
+
+**Constant, regardless of corpus size.** The embedding stack (PyTorch
+runtime + model, per worker), the engine baseline (~200 MB per process),
+connector machinery (~0.4 GB), and working buffers that reach a plateau in
+the first minutes of a run and stay there — identical on 3 GB and 10 GB.
+
+**On disk, not in memory.** Parsed-text cache, persistence snapshots, and
+the embeddings themselves (in the vector database). That is why the curves
+plateau: a **500× larger corpus costs 2.5× the memory** — and the growth
+that remains is the file-watch index above, i.e. the corpus in fewer files
+would cost less. Indexing time scales linearly with bytes throughout.
-
+
+
Curves from the run before the allocator tuning (peaks 6.6–16.4 GB); the table above has the final numbers from the tuned rerun (6.6–13.1 GB). The shape is the point: each curve reaches its plateau in the first minutes and holds it for the rest of the run — 5.5 hours for 50 GB.
+
+The peak itself is dominated by the embedding stack, not the engine — a
+Pathway worker process is ~200 MB; the rest is the price of running
+embeddings locally (8 × PyTorch runtime + model), i.e. of paying no
+per-token API fees. Fewer workers or an API embedder shrink it accordingly.
+
Same earlier run (8.8 GB peak on the 10 GB corpus; 7.7 GB after tuning). The proportions are what matters here: the embedding stack dominates, the engine and the file-watch index are small.
+
+Memory is measured as PSS (proportional set size) summed over the container:
+shared pages — e.g. the PyTorch libraries mapped by every worker — are
+counted once, not once per process. Setup: 96-core CPU host, streaming mode,
+8 worker processes, local `static-retrieval-mrl-en-v1` embeddings (no API
+calls; Matryoshka-truncated to 256 dims), 512-token chunks, Qdrant, and
+jemalloc's `background_thread` purging enabled in the indexer containers
+(measured free; it keeps idle workers from retaining freed pages). Numbers
+were measured on a nightly Pathway build whose engine matches the released
+wheel (pathway ≥ 0.32.1 — what the benchmark's docker image and the
+Development section install), so they are reproducible as-is.
+
+### Retrieval accuracy (FRAMES)
+
+End-to-end evaluation on [FRAMES](https://arxiv.org/abs/2409.12941)
+(Google, 2024): 824 multi-hop questions whose answers must be assembled
+from 2–15 English Wikipedia articles — see
+[benchmarks/frames](https://github.com/pathwaycom/serviette/tree/main/benchmarks/frames), full technical report in
+[REPORT.md](https://github.com/pathwaycom/serviette/blob/main/benchmarks/frames/REPORT.md):
+
+| measurement | result |
+|---|---|
+| gold-article recall — the paper's metric, on the paper's corpus | **0.50** vs 0.15 published for the paper's BM25 baseline (0.21 for our reproduction of it) |
+| paired gain from adding serviette to gpt-5, paper's protocol | **+5.2 pp** over the same model without retrieval (McNemar z = 4.1, 824 questions) |
+| adaptive retrieval in the grounded (context-only) regime | **41.3% → 52.8%** (z = 7.5) — the largest single effect measured |
+| absolute accuracy (permissive, gpt-5) | **73.7%** — above every number in the paper, including its 5-step agent (66.0%) and oracle (72.9%) |
+
+The setup reproduces the paper wherever technically possible: the identical
+Wikipedia dump (TFDS `wikipedia/20230601.en`, 5.22M articles → 12.07M
+chunks) indexed in full by serviette with the free local `e5-small-v2`
+embedder — so the recall row costs nothing in API fees — plus the paper's
+own retrieval metric and its verbatim autorater prompt. Comparisons are
+paired and internal (identical corpus, generator, judge; only the retrieval
+layer varies — the opt-in strategies described under
+[Retrieval quality](#retrieval-quality) below), because the absolute score
+is dominated by the 2026
+generator — its no-retrieval baseline alone reaches 68.5% — which is why
+the headline is the paired delta, not 73.7%. The grounded rows measure
+serviette as it ships for private corpora: answers strictly from retrieved
+documents, a deliberately stricter regime than the paper's. Methodology,
+statistics, limitations and raw per-question outputs:
+[REPORT.md](https://github.com/pathwaycom/serviette/blob/main/benchmarks/frames/REPORT.md).
+
+## Multimodality
+
+Every file type is enabled by default. serviette routes each file to the best
+parser that works **without an API key**, and turns on key-requiring
+modalities automatically when their key is present:
+
+| format | parsed by default with | notes |
+|---|---|---|
+| text / Markdown | as-is | |
+| PDF | pypdf — **built in**; `serviette[docling]` upgrades to Docling (layout-aware, tables) | local, free |
+| Office (DOCX, PPTX, XLSX, HTML, EML…) | Unstructured — **built in**; `serviette[docling]` widens coverage (EPUB, legacy formats) | local, free |
+| scanned images (PNG, JPG, TIFF…) | PaddleOCR | local, free; install `serviette[ocr]` |
+| audio (MP3, WAV…) | Whisper | when `OPENAI_API_KEY` is set |
+| video (MP4, WebM, MOV…) | TwelveLabs Pegasus — a searchable text description of the video | when `TWELVELABS_API_KEY` is set |
+
+A modality whose only parser needs an absent key is skipped with a clear
+warning — never a crash. Everything stays live: drop a recording of
+yesterday's meeting into the watched folder and ask about it minutes later;
+expensive parses (video) are cached on disk, so restarts cost nothing.
+
+The routing is configurable per file pattern (`parser:` section — pick a
+vision model for images instead of OCR, set a custom video prompt); see
+[docs](https://github.com/pathwaycom/serviette/blob/main/docs/README.md). Embeddings work the same for every modality: parsed
+content is text, so any of the embedder families — including the local
+credential-free default — covers a multimodal corpus.
+
+## Retrieval quality
+
+Retrieval and answering are pure-vector by default; five opt-in strategies
+improve accuracy, each a few lines of config. They compose freely — decompose
+widens *what* is retrieved, hybrid and reranking reorder *which* chunks win,
+MMR *diversifies* them, and adaptive RAG *retries* with more context when the
+answer is not found.
+
+- **Hybrid (BM25 + vector).** Fuses vector similarity with an in-process BM25
+ keyword index (reciprocal-rank fusion). The two signals fail differently —
+ embeddings match paraphrases, BM25's IDF makes rare exact tokens (names,
+ dates, IDs) dominate — so their fusion beats either alone on entity-heavy
+ corpora. Enable with `hybrid: true` on the vector-db section.
+- **Reranker.** A second stage rescoring a shortlist of candidates: a local,
+ keyless cross-encoder (`reranker: {type: cross_encoder}`) or pointwise LLM
+ scoring (`type: llm`). Best for precise, single-hop questions.
+- **Adaptive RAG.** Answers from `k` chunks first, then grows the context and
+ re-asks while the LLM reports the answer is not present (`rag.adaptive`).
+ Your `llm.system_prompt` stays in force; the mode only appends the
+ "reply with this marker when the context is insufficient" instruction it
+ needs to decide when to fetch more.
+- **Query decomposition.** One LLM call splits a multi-hop question into
+ sub-queries, retrieves for each, and fuses — so chunks of different hops
+ stop competing for the same top-k slots (`rag.decompose`).
+- **MMR.** Diversifies the result set, trading relevance against redundancy
+ (`rag.mmr`).
+- **Document questions.** "How many documents do you have?", "What does
+ `journal.pdf` say?", "What changed between `law_2023.txt` and
+ `law_2024.txt`?" are questions about documents, not about a passage, and
+ chunk retrieval cannot answer them. `rag.documents` (on by default) answers
+ them from the document catalog and from whole files: a question naming a
+ file goes straight to that file; any other question is searched as usual,
+ and only if that finds nothing does one short LLM call decide between a
+ wider search and the catalog or the named documents. Two files that share
+ most of their text are compared as a line-level diff computed by the
+ server, so the model reads only what changed — however the files were
+ chunked. Every step has a fixed context budget and the request as a whole
+ a ceiling (`max_request_chars`); when a file cannot be identified the
+ answer says which names were close.
+ Not available on Pinecone, which cannot enumerate documents.
+
+The reranker and the multi-step strategies (adaptive, decompose) are
+backend-independent — they work on every vector DB. Hybrid and MMR read from
+the store, so support depends on the backend:
+
+| Backend | Vector | Reranker · Adaptive · Decompose | MMR | Hybrid (BM25) |
+|----------|:------:|:-------------------------------:|:---:|:-------------:|
+| DuckDB | ✅ | ✅ | ✅ | ✅ in-process |
+| Qdrant | ✅ | ✅ | ✅ | ✅ in-process |
+| pgvector | ✅ | ✅ | ✅ | ✅ in-process |
+| Milvus | ✅ | ✅ | ✅ | ✅ in-process |
+| Weaviate | ✅ | ✅ | ✅ | ✅ in-process |
+| ChromaDB | ✅ | ✅ | ✅ | ✅ in-process |
+| MongoDB | ✅ | ✅ | ✅ | ✅ in-process |
+| Pinecone | ✅ | ✅ | ✅ | ❌ — no scan-all API; native sparse-index hybrid is planned |
+
+The in-process index follows the store: it is rebuilt as soon as the backend
+reports a change (the row count; on DuckDB and pgvector also the newest
+`seen_at`, which catches in-place edits) and refreshed in the background every
+`hybrid_refresh_seconds` (default 30) as a bound on staleness for whatever
+that cheap signal misses. In-process BM25 targets corpora up to a few million
+chunks; above `hybrid_max_chunks` the keyword leg is skipped with a warning and
+retrieval stays pure-vector. **Pinecone** cannot enumerate its vectors, so it has no
+in-process hybrid — `hybrid: true` there fails fast at startup with that
+explanation; native hybrid (a second sparse index) is planned. Native
+server-side BM25 for the client-server backends (replacing the in-process
+leg at larger scale) is planned as well.
+
+## Observability
+
+Three layers, all on by default or one config line away:
+
+**In the chat UI.** The header shows *"indexed N s ago"* — the age of the
+most recent write into the vector store. When you edit a source document,
+you can watch the counter reset as the change lands.
+
+**`GET /api/v1/stats`** on the API server: the backend in use, the number of
+indexed chunks, and index freshness — a JSON one-liner for dashboards and
+health checks, served without touching the indexer (it reads the vector
+store, like every other query).
+
+**Engine metrics (Prometheus).** The Pathway engine ships its own
+observability server; serviette exposes it with one config line:
+
+```yaml
+indexer:
+ monitoring_http_port: 20000
+```
+
+Every worker process then serves `GET /metrics` on
+`127.0.0.1:(20000 + worker index)` — input/output latency gauges (i.e. the
+indexing lag behind the sources) and per-operator row counters, straight
+from the engine's dataflow. Point a Prometheus scrape at the worker ports
+and you get per-stage throughput and freshness graphs with no extra code.
+
+Logs from both processes go to stdout/stderr in plain text; `serviette up`
+interleaves them with per-process prefixes.
+
+## Security
+
+The server listens on **localhost only** by default and ships no built-in
+authentication — exposing it is an explicit decision: set `server.host:
+0.0.0.0` and put an authenticating reverse proxy in front (a five-line
+Caddy example lives in [docs](https://github.com/pathwaycom/serviette/blob/main/docs/README.md#security--exposing-the-server)).
+
+## Requirements
+
+- Python ≥ 3.10 (the minimum supported by Pathway).
+- A free Pathway license key in `PATHWAY_LICENSE_KEY` —
+ .
+
+## Documentation
+
+Full installation, the config wizard, configuration reference, persistence,
+architecture and scaling notes live in **[docs/README.md](https://github.com/pathwaycom/serviette/blob/main/docs/README.md)**.
+
+## Development
+
+serviette runs on the released Pathway from PyPI (≥ 0.32.1 — the first
+release with the vector-database connectors). From-scratch setup on a
+fresh machine:
+
+```bash
+# 0. Prerequisites: Python >= 3.10 (3.12 recommended) and git.
+
+# 1. serviette in its own virtualenv
+git clone https://github.com/pathwaycom/serviette.git && cd serviette
+python3.12 -m venv .venv
+source .venv/bin/activate
+pip install -e ".[dev,local]"
+
+# 2. A (free) Pathway license: https://pathway.com/framework/get-license
+export PATHWAY_LICENSE_KEY=...
+
+# 3. Sanity check: zero-to-chat on the bundled corpus
+serviette demo # -> http://localhost:8989
+```
+
+Notes:
+
+- `serviette demo` materializes everything in a visible working directory:
+ `./serviette-demo/docs` holds the corpus — a **toy example**, a handful of
+ documents about a fictional company (Lumina Coffee Systems). Drop your own
+ files there (PDF, DOCX, scans, …) while it runs and they are answerable
+ within seconds.
+- The demo indexes with one of two embedders — pick your trade-off:
+ - **default, free & local** — needs `serviette[local]`, which pulls the
+ PyTorch stack. Install it with
+ `--extra-index-url https://download.pytorch.org/whl/cpu` to get the CPU
+ build (~0.8 GB); without the flag pip takes PyTorch's default Linux
+ wheel, which ships CUDA libraries whether or not you have an NVIDIA GPU
+ (**~5 GB**, and the install is the slow part of the first run). Free at
+ any corpus size afterwards.
+ - **`--embedder openai`** — nothing to install, starts immediately, but
+ every indexed token is billed to your `OPENAI_API_KEY`. Fine for the toy
+ corpus and small folders; for a large collection, sit out the
+ `serviette[local]` install and use the free embedder instead.
+- Independently of the embedder, export `OPENAI_API_KEY` if you want real
+ generated answers in `/rag` — without it the demo answers by quoting the
+ retrieved snippets.
+
+Running the test suites:
+
+```bash
+pytest -m "not slow" # fast unit tests (no Pathway, no services)
+pytest -m "slow and not integration" # end-to-end indexer tests (spin up Pathway)
+pytest -m integration # real-database tests (see below)
+pytest # everything
+```
+
+Per-backend clients install as extras — pick what you use:
+
+```bash
+pip install "serviette[qdrant]" # also: pgvector, milvus, chroma, weaviate,
+ # pinecone, mongodb, local, gemini, all
+```
+
+### Integration tests (real databases)
+
+**Every claimed backend has an integration test** running the same scenario
+end-to-end against a real instance: index two documents with the real indexer,
+retrieve through the production accessor (exact-text query must rank first
+with cosine ~1.0), delete a file, re-index, and verify its vectors are gone
+(snapshot semantics). The shared driver lives in `tests/integration_common.py`.
+
+| Backend | Test | Real instance |
+|---|---|---|
+| DuckDB | `test_integration_duckdb.py` | embedded — runs everywhere |
+| pgvector | `test_integration_pgvector.py` | `pgvector/pgvector` Docker container |
+| Milvus | `test_integration_milvus.py` | embedded Milvus Lite engine; set `SERVIETTE_TEST_MILVUS_URI=http://host:19530` to run the same tests against a Milvus server (Lite has no growing/sealed segments, so it cannot catch stats-counting bugs) |
+| Qdrant | `test_integration_qdrant.py` | `qdrant/qdrant` Docker container |
+| ChromaDB | `test_integration_chroma.py` | `chromadb/chroma` Docker container |
+| Weaviate | `test_integration_weaviate.py` | `semitechnologies/weaviate` Docker container |
+| Pinecone | `test_integration_pinecone.py` | official `pinecone-local` emulator (Docker) |
+| MongoDB | `test_integration_mongodb.py` | `mongodb-atlas-local` (mongod + mongot, real `$vectorSearch`) |
+
+Containers are throwaway (`tests/dockerutil.py`, Docker CLI via subprocess, no
+extra dependency) and host ports are **allocated dynamically** — tests never
+assume a fixed localhost port is free or that a service is already running.
+Each test skips automatically when Docker or its client library is missing.
+
+## License
+
+See [LICENSE](https://github.com/pathwaycom/serviette/blob/main/LICENSE).
diff --git a/assets/aws-fargate-logo.svg b/assets/aws-fargate-logo.svg
deleted file mode 100644
index b494fc21..00000000
--- a/assets/aws-fargate-logo.svg
+++ /dev/null
@@ -1,20 +0,0 @@
-
-
\ No newline at end of file
diff --git a/assets/azure-logo.svg b/assets/azure-logo.svg
deleted file mode 100644
index ff5dfa5c..00000000
--- a/assets/azure-logo.svg
+++ /dev/null
@@ -1,23 +0,0 @@
-
\ No newline at end of file
diff --git a/assets/gcp-logo.svg b/assets/gcp-logo.svg
deleted file mode 100644
index 8062a3c7..00000000
--- a/assets/gcp-logo.svg
+++ /dev/null
@@ -1 +0,0 @@
-
\ No newline at end of file
diff --git a/assets/render.png b/assets/render.png
deleted file mode 100644
index 37c30478..00000000
Binary files a/assets/render.png and /dev/null differ
diff --git a/benchmarks/frames/README.md b/benchmarks/frames/README.md
new file mode 100644
index 00000000..1989fa02
--- /dev/null
+++ b/benchmarks/frames/README.md
@@ -0,0 +1,105 @@
+# FRAMES benchmark
+
+End-to-end evaluation of serviette's retrieval quality on
+[FRAMES](https://arxiv.org/abs/2409.12941) (Google, 2024): 824 multi-hop
+questions whose answers must be assembled from 2–15 English Wikipedia
+articles.
+
+> **Start with [REPORT.md](REPORT.md)** — the full technical report:
+> methodology, statistics, analysis, limitations. This README is the
+> operational companion (fidelity summary, headline numbers, how to run);
+> [results/RESULTS.md](results/RESULTS.md) holds the raw data tables.
+
+The methodology tracks the paper wherever technically possible and
+documents every deviation below.
+
+## Fidelity to the paper
+
+| Aspect | Paper | This benchmark |
+|---|---|---|
+| Questions | 824, `google/frames-benchmark` | Same dataset, revision pinned in `fetch_dataset.py` |
+| Corpus | Full English Wikipedia, TFDS `wikipedia/20230601.en` | **Same dump, indexed in full**: 5.22M articles → 12.07M chunks — every headline number is measured against it. A small working corpus (the ~2.5k gold articles + a deterministic ~78k distractor sample) exists alongside for fast feature ablations only. Gold articles whose canonical dump title differs from the link (redirects) are fetched via the Wikipedia API **at the snapshot date**; a handful of gold links point at articles created *after* the snapshot — absent here exactly as they were absent in the paper's corpus |
+| Retrieval unit | Whole articles, BM25, n_docs ∈ {2, 4} | 512-token chunks; k=8 chunks ≈ the same context budget as BM25\@4 short articles |
+| Retrieval metric | Gold-article recall in context (0.12–0.15 for their BM25) | Same metric, `run_retrieval_eval.py` — directly comparable, and free of LLM cost |
+| Headline metric | Accuracy via LLM autorater | Same |
+| Judge | Gemini-Pro-1.5, prompt in paper Appendix B (0.96 acc. vs humans) | **Same prompt** (`judge_prompt.txt`), gpt-4o-mini at temperature 0 (validated at 94% agreement with gpt-4o) — Gemini-Pro-1.5 is retired |
+| Generator | Gemini-Pro-1.5-0514 | Configurable (retired model can't be reproduced). Every run reports its generator; the controlled baseline below anchors comparisons |
+| Multi-step baseline | 5 steps × 5 queries × 10 docs → 0.66 | serviette's `rag.adaptive` + `rag.decompose` are the single-shot analogue (documented as *analogous, not identical*) |
+
+**The controlled baseline:** because the paper's generator is unavailable,
+cross-paper numbers are context, not conclusions. The primary comparison is
+internal and fully controlled — serviette with all retrieval features off vs.
+feature configurations, on the identical corpus, generator, judge, and
+prompts. Only the retrieval layer varies.
+
+## Results
+
+Headlines, measured on the paper's full Wikipedia dump under the paper's
+permissive protocol (full analysis and statistics in
+[REPORT.md](REPORT.md)):
+
+- **Adding serviette to gpt-5 yields a paired +5.2 pp over the same model
+ without retrieval** (z = 4.1 on 824 shared questions); under grounding,
+ the adaptive-retrieval flag adds **+11.5 pp** (z = 7.5). For context, the
+ absolute score (73.7%) exceeds every number in the paper, including its
+ 5-step agent (66.0%) and oracle (72.9%) — a comparison dominated by
+ generator strength, which the report isolates.
+- **Retrieval recall on the identical corpus: 0.50 vs 0.15** for the
+ paper's BM25 (0.21 for our reproduction of it) — measured with the
+ paper's own metric, no generator involved.
+- A stricter **grounded** regime (answers only from documents — how
+ serviette ships for private corpora) is reported separately in
+ RESULTS.md and is deliberately not compared against the paper's numbers.
+
+## Layout
+
+```
+fetch_dataset.py questions.jsonl from HF (revision-pinned)
+extract_corpus.py corpora from the TFDS 2023-06-01 dump (run in a TF venv)
+fetch_gold_fallback.py the few redirect-titled gold articles, at snapshot date
+configs/ indexing + evaluation configurations
+run_retrieval_eval.py phase 0: article recall, zero LLM cost
+run_bench.py end-to-end: /rag + Appendix-B judge
+results/ one jsonl per run: summary line + per-question rows
+```
+
+## Runbook
+
+```bash
+export FRAMES_DATA=/path/to/data # big; keep outside the repo
+python fetch_dataset.py --out $FRAMES_DATA
+
+# corpus (TF venv: pip install tensorflow-cpu tensorflow-datasets)
+python extract_corpus.py --questions $FRAMES_DATA/questions.jsonl --out $FRAMES_DATA
+python fetch_gold_fallback.py --missing $FRAMES_DATA/gold-missing.txt \
+ --out $FRAMES_DATA/corpus-gold
+
+# long-lived Qdrant (index survives restarts; re-runs never re-embed)
+docker run -d --name frames-qdrant -p 6343:6333 -p 6344:6334 \
+ -v $FRAMES_DATA/qdrant:/qdrant/storage qdrant/qdrant
+
+serviette indexer --config configs/base-e5small.yaml # working corpus (~1.5 h)
+serviette indexer --config configs/base-e5small-full.yaml # full dump (~75 h)
+serviette server --config # per configuration
+
+python run_retrieval_eval.py --questions $FRAMES_DATA/questions.jsonl \
+ --k 8 --label # free
+OPENAI_API_KEY=... python run_bench.py \
+ --questions $FRAMES_DATA/questions.jsonl --k 8 --label
+```
+
+Re-runs are cheap by construction: corpora and the Qdrant index persist, so
+changing a server-side setting (hybrid, reranker, `rag.*`) and re-evaluating
+takes minutes, not hours. Only changing the embedder or the chunking requires
+re-indexing (into a fresh collection, so the old one stays usable).
+
+## Evaluation protocol
+
+1. **Phase 0 — retrieval ablations, free.** Rank all retrieval
+ configurations by article recall\@k. No generation, no judge.
+2. **Phase 1 — cheap generation sweep.** The shortlist runs end-to-end with
+ an inexpensive generator to rank configurations by accuracy.
+3. **Phase 2 — headline runs.** The best configuration and the
+ features-off baseline run with the strongest generator; the judge stays
+ fixed. Reported: accuracy, article recall, generator, cost.
+```
diff --git a/benchmarks/frames/REPORT.md b/benchmarks/frames/REPORT.md
new file mode 100644
index 00000000..262b4351
--- /dev/null
+++ b/benchmarks/frames/REPORT.md
@@ -0,0 +1,427 @@
+# Single-Shot Retrieval-Augmented Generation on FRAMES: A Controlled Evaluation of serviette
+
+## Abstract
+
+We evaluate serviette — a no-code, single-shot RAG server built on the
+Pathway Live Data Framework — on
+[FRAMES](https://arxiv.org/abs/2409.12941) (Krishna et al., 2024), an
+824-question multi-hop benchmark over English Wikipedia. We reproduce the
+paper's corpus exactly (the TFDS `wikipedia/20230601.en` dump, 5.22M articles,
+12.07M chunks), adopt its autorater prompt, and measure under two explicitly
+separated regimes: *permissive* (the paper's protocol — the generator may
+combine retrieved context with parametric knowledge) and *grounded* (strictly
+context-only — serviette's product default, deliberately stricter than the
+paper). Three system-attributable results. On the identical corpus and
+metric, serviette's retrieval reaches **0.50 gold-article recall versus
+0.15 published / 0.21 reproduced for the paper's BM25 baseline**. Adding
+serviette to gpt-5 under the paper's protocol yields a **paired +5.2 pp
+over the same model without retrieval** (McNemar z = 4.1 on 824 shared
+questions). Under grounding, the refusal-triggered **adaptive-retrieval
+flag lifts accuracy 41.3% → 52.8%** (z = 7.5) — the largest single effect
+we measure, though a fixed-k control separating the escalation policy from
+sheer context size remains future work (§5.4). For context only: the
+absolute permissive score, 73.7%, exceeds every number the paper reports,
+including its five-step agentic pipeline (66.0%) and oracle (72.9%) — but
+most of that gap belongs to the 2026 generator, whose no-retrieval
+baseline alone scores 68.5% on this 2024 benchmark, so we foreground
+paired deltas, not absolute comparisons. Across our three-model ladder the
+paired gain is significant at both ends (+3.8 pp weakest, +5.2 pp
+strongest) with no measurable effect mid-tier; whether this is a genuinely
+non-monotonic pattern is left as a hypothesis pending replication. A
+failure taxonomy attributes 62% of remaining permissive errors to
+retrieval misses and estimates the autorater's false-negative rate at
+≈3 pp (a single-LLM estimate; false positives unaudited). All corpora,
+configurations, raw per-question outputs, and scripts are pinned and
+included.
+
+## 1. Scope and claims
+
+This report makes three claims and explicitly does not make several others.
+
+**Claimed:**
+1. On the paper's own corpus and retrieval metric, serviette's single-shot
+ retrieval stack outperforms the paper's naive BM25 baseline ~2.4–3.3×
+ (0.50 vs 0.15 published / 0.21 reproduced; metric-level uncertainty
+ discussed in §5.1).
+2. serviette's retrieval produces a significant paired gain on a frontier
+ generator under the paper's protocol (+5.2 pp, z = 4.1), and adaptive
+ retrieval under grounding produces the largest effect we measure
+ (+11.5 pp, z = 7.5). The absolute permissive score exceeding every
+ number in the paper is offered as context, not as a claim about the
+ system — that comparison is dominated by generator strength (§5.2).
+3. For gpt-5 under grounding on this corpus, the binding constraint is
+ retrieval recall: 60% of grounded errors are refusals, the ceiling sits
+ ≈27 pp above the fixed-k configuration, and adaptive retrieval recovers
+ roughly two-fifths of that headroom (both figures inherit the ceiling
+ estimate's uncertainty, §5.3; generalization beyond this
+ model-and-corpus pair is untested, §7).
+
+**Observed, not claimed:** paired retrieval gains are significant at both
+ends of the model ladder and absent in the middle. The "non-monotonic in
+generator strength" reading and its proposed mechanism are hypotheses: the
+middle point is a single-run null result, and per-row sub-query generation
+confounds reader strength with retrieval quality (§6.1).
+
+**Not claimed:** superiority over the paper's *system* on matched generators
+(their generator is retired; we bracket its strength instead — §5.2); any
+number under the grounded regime being comparable to the paper (§4.3); that
+FRAMES measures pure retrieval for frontier models (it does not — §6.1);
+that the mid-tier null result establishes harm from retrieval (it is
+statistically indistinguishable from no effect).
+
+## 2. System under test
+
+serviette (this repository) — a two-process RAG stack: a Pathway-based
+indexer (parsing → 512-token chunking, 50 overlap → embedding → vector-DB
+write-through) and a stateless retrieval/answer server. Configuration under
+test:
+
+- **Embedder:** `intfloat/e5-small-v2` (33M parameters, 384-d), local CPU,
+ asymmetric `query:`/`passage:` prefixes. No embedding API calls anywhere.
+- **Vector store:** Qdrant, cosine, HNSW; single named dense slot.
+- **Retrieval features:** multi-hop query decomposition (`rag.decompose`,
+ ≤4 sub-queries, round-robin fusion); adaptive context growth
+ (`rag.adaptive`, k=8→16→32 on refusal; §5.4). In-process BM25 hybrid and
+ MMR exist in the product but are **disabled here**: hybrid by its
+ documented 5M-chunk cap (native sparse-vector hybrid is future work,
+ §8), MMR to keep the tested configuration minimal.
+- **Generation:** `/rag` endpoint, k=8 chunks (~4.1k tokens of context —
+ matching the paper's BM25@4-articles budget).
+
+## 3. Benchmark construction and fidelity
+
+| Aspect | Paper | This evaluation |
+|---|---|---|
+| Questions | 824, `google/frames-benchmark` | identical; HF revision `58d9fb63` pinned |
+| Corpus | full English Wikipedia, TFDS `wikipedia/20230601.en` | same dump: 5,222,443 articles ≥500 chars → 12,068,600 chunks |
+| Gold articles | annotator-linked `wiki_links` | 2,453/2,477 present (99.03%); the 24 absent were created after the snapshot — absent for the paper as well. Redirect-titled links resolved via snapshot-date revisions; recall matching uses an alias map |
+| Retrieval metric | gold-article recall in context | identical (article counted if ≥1 of its chunks retrieved — an optimistic reading vs. the paper's whole-article inclusion; noted in §7) |
+| Judge | LLM autorater, Appendix-B prompt, 0.96 agreement w/ humans | same prompt verbatim; gpt-4o-mini, temperature 0. Validation: 94% agreement with a gpt-4o judge on a 100-question sample drawn from this benchmark's July predecessor run (same prompt and judge configuration, different answer set); noise additionally bounded on *this* run's answers via the failure audit, §6.3 |
+| Generator | Gemini-Pro-1.5-0514 (retired) | three tiers (gpt-4o-mini / gpt-4o / gpt-5) bracketing the paper's generator by the naive anchor (§5.2) |
+
+Corpus preparation is fully scripted (`fetch_dataset.py`,
+`extract_corpus.py`, `fetch_gold_fallback.py`); distractor-free — the full
+dump *is* the distractor set.
+
+**The working corpus.** Alongside the full dump we maintain a small corpus
+cut from the same snapshot: the 2,453 gold articles plus 77,961 distractor
+articles selected by a deterministic title hash — 80,488 articles, 208,010
+chunks, indexable in ~1.5 h versus 75 h for the full dump. It exists purely
+for fast feature-ablation iteration (which retrieval features help, and in
+what order); retrieval there is ~80× easier by gold base-rate, so **no
+headline or cross-paper number is measured on it**. Where its results
+appear (feature ranking in §5.3, the corpus-size check in §5.1, the hybrid
+estimate in §8) they are labeled "working corpus" explicitly.
+
+## 4. Methodology
+
+### 4.1 Metrics
+- **Article recall@k** — the paper's retrieval metric; generator-free.
+- **Accuracy** — Appendix-B autorater verdicts over free-form answers.
+- **Paired significance** — McNemar's test on shared questions for every
+ retrieval-vs-naive comparison (n = 824 pairs); we report b (fixed by
+ retrieval), c (broken by retrieval), z.
+
+### 4.2 Cost/compute accounting
+Embedding and retrieval are local and free. API usage is metered from
+response objects for judge calls and for the direct-call rungs
+(naive/oracle, `run_ladder.py`); generation issued *inside the serviette
+server* was not usage-logged (a known instrumentation gap) and is estimated
+from token arithmetic. Total API spend for every number in this report:
+≈$128 (per-run figures in `results/*.jsonl` summaries). Indexing: 75 h on
+96 CPU cores (8 Pathway workers × 12 threads, ~2,700 chunks/min). One
+operational observation for practitioners: at equal API conditions,
+per-question generation latency roughly doubled from the grounded to the
+permissive regime (≈46 s → ≈96 s), indicating substantially longer
+reasoning traces, billed as output tokens.
+
+### 4.3 Two regimes, never mixed
+**Grounded** (product default): the system prompt forbids outside knowledge;
+insufficient context must produce a refusal. This isolates retrieval quality
+from parametric memory — a reader can attribute grounded accuracy to the
+retrieval stack. It is *stricter than the paper*: the paper's prompt imposed
+no such restriction, which its own numbers prove arithmetically (47.4%
+accuracy at 0.15 recall is unreachable under grounding).
+**Permissive** (the paper's protocol): context plus the model's own
+knowledge; the only regime whose accuracies may be set beside the paper's.
+
+## 5. Results
+
+### 5.1 Retrieval (generator-free, full dump)
+
+Configuration labels: **vector** = plain dense retrieval (embed the
+question, take the k nearest chunks by cosine similarity);
+**vector+decompose** = the same, plus the LLM-generated sub-queries of §2
+retrieving in parallel with the original question, results fused
+round-robin.
+
+| Method | Article recall@context | Full-coverage rate |
+|---|---|---|
+| BM25@4 whole articles (paper, published) | 0.12–0.15 | — |
+| BM25@4 whole articles (our reimplementation) | 0.210 | 0.034 |
+| serviette, vector only, k=8 | 0.284 | 0.078 |
+| serviette, vector+decompose, k=8 (mini sub-queries) | 0.406 | 0.134 |
+| serviette, vector+decompose, k=8 (gpt-5 sub-queries) | 0.497 | — |
+
+**Recall as a function of context size** (mini sub-queries for the
+decompose rows):
+
+| k | 4 | 8 | 16 | 32 | 64 |
+|---|---|---|---|---|---|
+| vector | 0.232 | 0.284 | 0.334 | 0.386 | 0.428 |
+| vector+decompose | 0.328 | 0.407 | 0.468 | 0.529 | 0.577 |
+
+(The k=8 decompose cell, 0.407, is an independent re-run of the 0.406 row
+in the table above; the 0.001 discrepancy is the observed re-run variance —
+ANN search plus mini-generated sub-queries — and doubles as a measure of
+retrieval-pipeline reproducibility.)
+
+Recall grows ≈ logarithmically in k with no saturation by k=64, and
+decomposition's advantage (+10–15 pp) is stable across the whole range —
+the two mechanisms are complementary, not redundant. The curve also
+anticipates the adaptive-retrieval result (§5.4): a refusal-triggered
+escalation to k=32 operates at ≈0.53 recall instead of 0.41.
+
+The BM25 rows involve no index and no part of serviette: they are computed
+by a standalone two-pass streaming scorer (`run_bm25_baseline.py`) directly
+over the corpus text files — Okapi BM25 (k1=1.5, b=0.75), whole articles,
+the raw question as the query, exactly the paper's baseline setup. (BM25
+needs only corpus term statistics; an index buys query speed, which a
+one-shot batch evaluation does not need.)
+
+Two observations. First, this BM25 reproduction validates the evaluation
+pipeline: same method, same corpus, same metric land in the paper's
+ballpark (0.21 vs 0.15; residual gap attributable to tokenizer/stemming
+differences). Note the discrepancy's direction: our reimplementation
+credits the baseline with a *stronger* result than its authors published,
+and the headline multiplier is computed against that stronger 0.21 —
+implementation uncertainty is priced against serviette, not for it.
+Two metric-level biases, however, pull in opposite directions and do not
+cancel: chunk-level coverage (≥1 chunk counts an article) reads *higher*
+than the paper's whole-article inclusion, favoring serviette, while the
+stronger reproduction deflates the multiplier, favoring the baseline. The
+2.4–3.3× range therefore carries more uncertainty than its endpoints
+suggest; the *ordering* — serviette well above BM25 on the same corpus —
+is robust, the exact multiplier is indicative.
+Second,
+decomposition — one cheap LLM call — is worth +12 to +21 recall points on
+multi-hop questions, and the quality of the decomposing model matters
+(mini 0.406 → gpt-5 0.497).
+
+*Corpus-size honesty check:* on an easy 80k-article working corpus the same
+stack reads 0.62–0.74 recall while the same BM25@4 reads 0.508 — i.e., most
+of any "5×" headline against the paper's 0.15 would be haystack size, not
+stack quality. All cross-paper claims in this report therefore use the
+full-dump numbers above.
+
+### 5.2 End-to-end, permissive regime (the paper's protocol)
+
+**Naive** (the paper's term) = no retrieval at all: the model receives the
+bare question and answers from parametric memory alone — the floor against
+which retrieval's contribution is measured. serviette = vector+decompose at
+a fixed k=8 (single-shot; adaptive retrieval applies only to the grounded
+regime, §5.4 — its escalation trigger is the grounded refusal marker, which
+permissive answering rarely emits), full dump. Δ is the paired gain over
+the same generator's naive row. Note an intentional design property:
+each row is the *self-contained system* a user would deploy — decomposition
+sub-queries are produced by the row's own generator, so retrieval quality
+itself varies with the model (context recall column). Δ therefore measures
+"what does adding serviette to this model do", not "same context, different
+reader".
+
+| Generator | Naive | serviette RAG | Context recall | Δ | McNemar |
+|---|---|---|---|---|---|
+| gpt-4o-mini | 32.9% | 36.7% | 0.404 | +3.8 pp | b=104, c=73, z=+2.3 (p<0.02) |
+| gpt-4o | 49.9% | 47.8% | 0.421 | −2.1 pp | b=86, c=103, z=−1.2 (n.s.) |
+| gpt-5 | 68.5% | **73.7%** | 0.497 | +5.2 pp | b=78, c=35, z=+4.1 (p<10⁻⁴) |
+| *Gemini-Pro-1.5 (paper)* | *40.8%* | *BM25@4 47.4 · 5-step agent 66.0 · oracle 72.9* | *0.15 (BM25)* | | |
+
+The paper's generator strength (naive 40.8%) is bracketed by our
+gpt-4o-mini (32.9%) and gpt-4o (49.9%) rows.
+
+### 5.3 Grounded regime (strictly context-only; not paper-comparable)
+
+gpt-5, full dump, k=8: **41.3%** accuracy at 0.482 context recall. 60% of
+errors are explicit refusals — recall, not reading, is the binding
+constraint. The regime's ceiling was estimated two independent ways:
+
+- **Oracle (all gold articles supplied, grounded prompt): 68.2%.**
+- The free proxy — grounded accuracy on the 158 questions whose gold
+ articles were fully retrieved: **68.4%**.
+
+The two estimates are consistent, but the 0.2 pp agreement should not be
+over-read: the proxy subset is biased toward easier questions (fully
+retrievable gold sets), pushing it up; oracle contexts are truncated for
+the longest questions, pushing the oracle down; and at n=158 the proxy's
+CI is ±3.7 pp — the near-exact match is plausibly two opposing biases
+meeting, not a precision result. Reading: perfect retrieval would lift
+grounded accuracy from 41.3% to
+≈68% (+27 pp of retrieval headroom); the residual ≈32% error at recall≈1
+(24 post-snapshot gold articles remain unavailable even to the oracle, §3)
+is the grounded reasoning/reading ceiling of the generator itself (note it
+sits close to the model's permissive naive 68.5% — with complete evidence,
+grounding costs nothing). Downstream figures that use ≈68 as a point — the
++27 pp headroom here and the "recovers ≈42%" of §5.4 — inherit this
+estimate's uncertainty of ±several pp. Working-corpus grounded ablations
+(gpt-4o: features-off 34.6% → full stack 43.8%) established feature
+ranking and are reported in RESULTS.md.
+
+**Does grounding actually ground?** Four observations say the regime works
+as specified, not merely that it scores lower:
+
+1. *Memory suppression.* Only 32/824 grounded answers (3.9%) are correct
+ with zero gold-article coverage — and that is an upper bound on
+ parametric leakage, since on a full-Wikipedia corpus the needed fact
+ often appears in non-gold articles too. The permissive run, same
+ questions, has 78 such answers: the grounded prompt eliminates at least
+ ~60% of memory-sourced correctness.
+2. *Honest failure mode.* 60% of grounded errors are explicit refusals,
+ not fabrications — the system says "the documents don't show this"
+ rather than inventing.
+3. *Reading ability intact.* With complete evidence the grounded score
+ (68.4% on fully-covered questions; 68.2% oracle) matches the model's
+ unrestricted naive 68.5% — grounding costs nothing when retrieval
+ delivers.
+4. *Evidence-tracking.* Correct grounded answers sit at 0.61 mean context
+ recall versus 0.39 for errors — correctness follows what was actually
+ retrieved.
+
+A formal faithfulness audit (are non-refusal answers actually entailed by
+their context?) was not performed and would strengthen this section.
+
+### 5.4 Adaptive retrieval under grounding
+
+`rag.adaptive` converts refusals into re-retrieval at k=16, then k=32 —
+targeting exactly the dominant failure mode of §5.3. Its outcome was
+anticipated by the independently measured recall-vs-k curve (§5.1:
+escalation to k=32 should operate near 0.53–0.58 recall); we note the
+sweep completed before this run did, but make no formal preregistration
+claim.
+
+**Result: 52.8% accuracy at 0.572 context recall** — versus 41.3% / 0.482
+for fixed k=8. Paired on identical questions: adaptivity fixed 128 answers
+and broke 33 (McNemar z = +7.5), the largest single effect measured in
+this evaluation — attributed here to the *configuration flag*, not yet to
+a specific mechanism, for the following reason.
+
+**Missing control.** The comparison is against fixed k=8, but escalation
+changes two things at once: the refusal-triggered policy *and* the amount
+of context. The k-sweep (§5.1) shows fixed k=32 alone lifts recall
+substantially, so part of the +11.5 pp may be "more chunks", not "smarter
+policy". The separating experiment — grounded gpt-5 at a *fixed* k=32 —
+was not run and is the cheapest item in §8. Its two possible outcomes are
+both informative: parity would recast adaptivity as a *cost* result
+(matching large-k accuracy while paying large-k tokens only on the ~36% of
+questions that refuse — still a real product property); superiority would
+establish the policy mechanism. Note the outcome is genuinely open in both
+directions: adaptive serves large contexts only to refusers, while fixed
+k=32 also imposes them on questions already answered correctly at k=8,
+where added context can distract. Adaptive retrieval recovers ≈42% of the
+grounded regime's retrieval headroom (41.3 → 52.8 of a ≈68 ceiling, ±
+per §5.3) — the single-shot analogue of the paper's five-step agentic
+gain (+25.2 pp on its weak generator), realized inside one configuration
+flag.
+
+## 6. Analysis
+
+### 6.1 Retrieval value across generator strength
+
+What the data establish: significant paired gains at both ends of the
+ladder (+3.8 pp weakest, +5.2 pp strongest) and no measurable effect for
+the mid-tier model — a single-run null (z = −1.2), not an established
+"wash-out". A non-monotonic ("U-shaped") pattern is one reading, and a
+mechanistic story fits it — the weakest model substitutes reading for
+memory it lacks, the frontier reasoner arbitrates between context and
+memory (b=78 fixed vs c=35 broken), the mid-tier defers to incomplete
+context — but we present it as a hypothesis, for two reasons. First,
+establishing the shape requires the middle point to be a *replicated*
+null, and generation-run variance is unmeasured (§7.1). Second, a
+confound: each row's sub-queries come from its own generator, so gpt-5
+enjoys both a stronger reader and stronger retrieval (recall 0.497 vs
+0.404); the arbitration story is not separable, on these data, from
+"better decomposition → better context". A cheap disentangling experiment
+— one fixed set of sub-queries served to all three readers — is listed in
+§8. What is not hypothetical: the paper's own +25.2 pp from five-step
+agentic retrieval on a weak generator shows iteration is how weaker models
+exploit retrieval, and the honest product case for RAG is corpora the
+model has *not* memorized (fresh and private data), where the grounded
+regime is the operative one and recall is decisive.
+
+### 6.2 Failure taxonomy (permissive gpt-5, 217 errors, gpt-4o classifier)
+
+| Category | Share | Reading |
+|---|---|---|
+| retrieval_miss | 61.8% | dominant; matches recall 0.497 — headroom lies in retrieval, not generation |
+| reasoning_error | 19.8% | generator ceiling |
+| judge_error | 11.5% | autorater graded an equivalent answer wrong |
+| dataset_issue | 6.0% | consistent with the authors' own 5.5% staleness filtering |
+
+### 6.3 Autorater error: a one-sided estimate
+The failure audit (§6.2) examined only questions the judge marked wrong, so
+by construction it can detect only *false negatives* — correct answers
+misgraded: 25/824 = 3.0%. False positives (wrong answers credited) were
+not audited at all, so no two-sided noise bound exists, and headline
+accuracies cannot be called conservative on this evidence alone. The
+auditor is moreover itself an LLM, whose errors may correlate with the
+judge's. The 94% mini↔gpt-4o agreement (measured on the predecessor
+answer set, §3) is consistent with a low-single-digit error rate; a proper
+bound requires auditing a sample of *passed* verdicts — listed in §8.
+
+## 7. Limitations
+
+1. **Generator non-determinism and run variance:** gpt-5 rejects
+ temperature control; each accuracy is a single run (n=1 per
+ configuration; per-question CI ±3.4 pp). Re-run variance was measured
+ only for the retrieval pipeline (±0.001 recall, §5.1) — never for
+ generation, which weakens every conclusion resting on small deltas,
+ most of all the mid-tier null (§6.1).
+2. **Judge is a small model** (validated, bounded, but not human).
+3. **Dataset contamination:** FRAMES (2024, Wikipedia) is inside 2026
+ models' training data; permissive numbers partly measure memory. The
+ regime split addresses attribution, not contamination itself.
+4. **Chunk-level recall is optimistic** versus the paper's whole-article
+ inclusion (a retrieved chunk may miss the needed fact).
+5. **Hybrid and MMR disabled** in the tested configuration (§2). Grounded
+ weak-model rows on the full dump are left to future work; the grounded
+ regime is therefore characterized on gpt-5 only, plus the working-corpus
+ gpt-4o ablations.
+6. Oracle context truncated at 400k characters for the longest questions.
+
+## 8. Future work
+
+In rough priority order:
+
+1. **The adaptive-retrieval control: grounded gpt-5 at fixed k=32** — one
+ run separating the escalation policy from context size (§5.4); the
+ cheapest and most claim-relevant item on this list.
+2. **Native sparse-vector (BM25) hybrid at full-dump scale.** The upstream
+ connector support has landed in Pathway
+ ([schema-driven named dense+sparse vectors in `pw.io.qdrant.write`](https://github.com/pathwaycom/pathway/commit/972e56cd1b),
+ [sparse records in `pw.io.pinecone.write`](https://github.com/pathwaycom/pathway/commit/fdbedb1c58));
+ the serviette integration and a 75 h re-index are scheduled separately.
+ On the 80k working corpus the BM25 leg was worth +4 recall points; the
+ full-dump gain is an open measurement.
+3. **Replication of the model ladder** — repeated runs per configuration
+ (generation variance) and grounded rows for the weaker models: the
+ grounded regime, the most product-relevant one, is currently
+ characterized on one model in one run.
+4. **Disentangling the ladder confound** — one fixed set of sub-queries
+ (e.g., gpt-5's) served to all three readers, separating reader strength
+ from retrieval quality (§6.1).
+5. **A two-sided autorater bound** — auditing a sample of *passed*
+ verdicts, ideally with a non-LLM (human) spot check (§6.3).
+6. **The reasoning-effort ablation** — the `llm.reasoning_effort` product
+ knob against the latency observation of §4.2.
+
+## 9. Reproducibility
+
+Everything needed to re-run: `benchmarks/frames/` scripts (data fetch with
+pinned revisions, corpus extraction from the public TFDS bucket, sweep
+orchestrators, this report's numbers as raw per-question JSONL in
+`results/`), configs (including ports and worker/thread settings), judge
+prompt verbatim, and the cost model in `run_ladder.py`. Hardware: 96-core
+CPU host, no GPU; peak memory ≈50 GB (Qdrant's 12M-point HNSW plus eight
+indexer workers; estimate — the host is shared, per-process accounting was
+not collected), ~110 GB disk. Version pins:
+pathway 0.31.2-dev915, qdrant-client 1.18/server 1.15.5, e5-small-v2
+revision as fetched 2026-07-24.
diff --git a/benchmarks/frames/configs/README.md b/benchmarks/frames/configs/README.md
new file mode 100644
index 00000000..0fc0afbb
--- /dev/null
+++ b/benchmarks/frames/configs/README.md
@@ -0,0 +1,21 @@
+# Bench configurations
+
+`base-e5small.yaml` indexes both corpora into the long-lived Qdrant container.
+Evaluation configs are the same file plus a **server-side overlay**: retrieval
+features live in the `vector_db` / `reranker` / `rag` sections and need no
+re-indexing — restart only `serviette server` with a different config to
+switch configurations. Overlays used by the sweep (append to the base):
+
+| Label | Overlay |
+|---|---|
+| `vector` | — (base as is) |
+| `hybrid` | `vector_db.hybrid: true` |
+| `hybrid-mmr` | + `rag: {mmr: {candidates: 24, diversity: 0.3}}` |
+| `hybrid-ce-rerank` | + `reranker: {type: cross_encoder, candidates: 30}` |
+| `hybrid-decompose` | + `rag: {decompose: {max_subqueries: 4}}` (needs `llm`) |
+| `best-adaptive` | best of the above + `rag.adaptive` (e2e phases only) |
+
+Generation phases add an `llm` section (e.g. `type: openai`, `model: gpt-4o`,
+`temperature: 0`). The `e5base` variant swaps the embedder model to
+`intfloat/e5-base-v2` and the collection to `frames_e5base` (separate
+collection = both embedders stay indexed side by side).
diff --git a/benchmarks/frames/configs/base-e5small-full.yaml b/benchmarks/frames/configs/base-e5small-full.yaml
new file mode 100644
index 00000000..7f88e913
--- /dev/null
+++ b/benchmarks/frames/configs/base-e5small-full.yaml
@@ -0,0 +1,39 @@
+# FRAMES star-run base: the FULL 2023-06-01 dump (~6.5M articles) with the
+# same embedder/chunking as the working corpus, into a separate collection —
+# both stay queryable side by side. Indexing is a multi-day background job
+# (measured ~2.6k chunks/min on 96 CPU cores); retrieval-feature overlays are
+# applied the same way as for the working corpus (see configs/README.md).
+#
+# spawn_first_port is shifted from the default 10000: other Pathway
+# applications on a shared host (CI agents) occupy the default range, and
+# colliding workers hang retrying "connection refused".
+pathway_license_key: ${PATHWAY_LICENSE_KEY}
+sources:
+ - type: fs
+ path: ${FRAMES_DATA}/corpus-full
+ mode: static
+vector_db:
+ type: qdrant
+ host: 127.0.0.1
+ rest_port: 6343
+ grpc_port: 6344
+ collection: frames_e5small_full
+embedder:
+ type: sentence_transformer
+ model: intfloat/e5-small-v2
+ query_prefix: "query: "
+ document_prefix: "passage: "
+splitter:
+ type: token_count
+ chunk_size: 512
+ chunk_overlap: 50
+indexer:
+ workers: 8
+ spawn_first_port: 12000
+workdir_path: ${FRAMES_DATA}/workdir-e5small-full
+persistence:
+ enabled: true
+ backend: filesystem
+server:
+ port: 8987
+ serve_frontend: false
diff --git a/benchmarks/frames/configs/base-e5small.yaml b/benchmarks/frames/configs/base-e5small.yaml
new file mode 100644
index 00000000..1266e28c
--- /dev/null
+++ b/benchmarks/frames/configs/base-e5small.yaml
@@ -0,0 +1,39 @@
+# FRAMES bench — indexer + retrieval base: local free e5-small-v2 into Qdrant.
+# ${FRAMES_DATA} points at the data dir (questions + corpora); the Qdrant
+# instance is a long-lived container so re-runs never re-embed (persistence
+# below skips unchanged files).
+pathway_license_key: ${PATHWAY_LICENSE_KEY}
+sources:
+ - type: fs
+ path: ${FRAMES_DATA}/corpus-gold
+ mode: static
+ - type: fs
+ path: ${FRAMES_DATA}/corpus-distractors
+ mode: static
+vector_db:
+ type: qdrant
+ host: 127.0.0.1
+ rest_port: 6343
+ grpc_port: 6344
+ collection: frames_e5small
+embedder:
+ type: sentence_transformer
+ model: intfloat/e5-small-v2
+ query_prefix: "query: "
+ document_prefix: "passage: "
+splitter:
+ type: token_count
+ chunk_size: 512
+ chunk_overlap: 50
+# 8 workers — the maximum `pathway spawn` supports; each runs torch intra-op
+# parallelism on its share of the cores (see base-e5small-full.yaml for the
+# thread/port settings of the full-dump run).
+indexer:
+ workers: 8
+workdir_path: ${FRAMES_DATA}/workdir-e5small
+persistence:
+ enabled: true
+ backend: filesystem
+server:
+ port: 8987
+ serve_frontend: false
diff --git a/benchmarks/frames/extract_corpus.py b/benchmarks/frames/extract_corpus.py
new file mode 100644
index 00000000..55ec64ce
--- /dev/null
+++ b/benchmarks/frames/extract_corpus.py
@@ -0,0 +1,146 @@
+"""Extract the benchmark corpus from the paper's exact Wikipedia snapshot.
+
+Reads TFDS ``wikipedia/20230601.en`` — the same June 1, 2023 dump the FRAMES
+paper indexed — and writes two corpora of plain-text files:
+
+- ``corpus-gold/``: the articles referenced by the questions' ``wiki_links``
+ (one file per article, named by a slug of the title so retrieval hits can be
+ mapped back to gold articles for the recall metric);
+- ``corpus-distractors/``: a deterministic ~N-article sample of the remaining
+ dump (hash-based selection on the title, so the sample is independent of
+ read order and reproducible without a stored list), sharded into
+ subdirectories to keep directory sizes sane.
+
+Run inside the TFDS venv (tensorflow-cpu + tensorflow-datasets), not the
+serviette venv:
+
+ python extract_corpus.py --questions data/questions.jsonl --out data \
+ [--distractors 100000] [--min-chars 500]
+
+Gold titles that do not match a dump page (usually redirects) are listed in
+``data/gold-missing.txt``; fetch those few via ``fetch_gold_fallback.py``,
+which asks the live Wikipedia API for the revision as of 2023-06-01 — same
+snapshot date, so no content drift.
+"""
+
+from __future__ import annotations
+
+import argparse
+import hashlib
+import json
+import re
+import urllib.parse
+from pathlib import Path
+
+SNAPSHOT = "wikipedia/20230601.en"
+# Selection threshold denominator: titles are hashed into [0, 1) and kept when
+# below distractors/estimated_pages. The dump has ~6.7M pages; the exact count
+# is discovered at runtime and the threshold adjusted in one pass.
+ESTIMATED_PAGES = 6_700_000
+
+
+def slug(title: str) -> str:
+ return re.sub(r"[^A-Za-z0-9._-]+", "_", title)[:150]
+
+
+def norm(title: str) -> str:
+ return title.replace("_", " ").strip().casefold()
+
+
+def title_of_link(url: str) -> str:
+ # Fragment stripped (section anchors / text-fragments point into an
+ # article, the article itself is the gold unit); double-unquote covers the
+ # occasional double-encoded dataset link.
+ tail = url.rsplit("/wiki/", 1)[-1].split("#", 1)[0]
+ return urllib.parse.unquote(urllib.parse.unquote(tail)).replace("_", " ").strip()
+
+
+def title_hash01(title: str) -> float:
+ digest = hashlib.blake2b(title.encode("utf-8"), digest_size=8).digest()
+ return int.from_bytes(digest, "big") / 2**64
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--out", default="data")
+ ap.add_argument("--distractors", type=int, default=100_000)
+ ap.add_argument("--min-chars", type=int, default=500)
+ ap.add_argument(
+ "--full",
+ action="store_true",
+ help="also write every dump article >= min-chars into corpus-full/ "
+ "(the star-run corpus; ~20 GB)",
+ )
+ ap.add_argument(
+ "--tfds-dir",
+ default=None,
+ help="local TFDS data dir with the prepared shards (downloaded from "
+ "gs://tfds-data); falls back to streaming from GCS when omitted",
+ )
+ args = ap.parse_args()
+
+ import tensorflow_datasets as tfds
+
+ out = Path(args.out)
+ gold_dir = out / "corpus-gold"
+ distractor_dir = out / "corpus-distractors"
+ gold_dir.mkdir(parents=True, exist_ok=True)
+ distractor_dir.mkdir(parents=True, exist_ok=True)
+ full_dir = out / "corpus-full"
+ if args.full:
+ full_dir.mkdir(parents=True, exist_ok=True)
+
+ gold_titles: dict[str, str] = {} # normalized -> display
+ for line in open(args.questions):
+ for link in json.loads(line)["wiki_links"]:
+ title = title_of_link(link)
+ gold_titles[norm(title)] = title
+ print(f"gold titles to find: {len(gold_titles)}", flush=True)
+
+ threshold = args.distractors / ESTIMATED_PAGES
+ if args.tfds_dir:
+ ds = tfds.load(SNAPSHOT, split="train", data_dir=args.tfds_dir)
+ else:
+ ds = tfds.load(SNAPSHOT, split="train", try_gcs=True)
+
+ found: set[str] = set()
+ n_distractors = 0
+ n_full = 0
+ for i, ex in enumerate(ds.as_numpy_iterator()):
+ title = ex["title"].decode("utf-8")
+ text = ex["text"].decode("utf-8")
+ key = norm(title)
+ if key in gold_titles:
+ (gold_dir / (slug(title) + ".txt")).write_text(f"{title}\n\n{text}")
+ found.add(key)
+ elif len(text) >= args.min_chars and title_hash01(title) < threshold:
+ shard = distractor_dir / f"{n_distractors % 256:02x}"
+ shard.mkdir(exist_ok=True)
+ (shard / (slug(title) + ".txt")).write_text(f"{title}\n\n{text}")
+ n_distractors += 1
+ if args.full and len(text) >= args.min_chars:
+ shard = full_dir / f"{n_full % 4096:03x}"
+ shard.mkdir(exist_ok=True)
+ (shard / (slug(title) + ".txt")).write_text(f"{title}\n\n{text}")
+ n_full += 1
+ if (i + 1) % 200_000 == 0:
+ print(
+ f"{i + 1} pages | gold {len(found)}/{len(gold_titles)} "
+ f"| distractors {n_distractors}",
+ flush=True,
+ )
+
+ missing = sorted(gold_titles[k] for k in gold_titles.keys() - found)
+ (out / "gold-missing.txt").write_text("\n".join(missing))
+ print(
+ f"DONE: gold {len(found)}/{len(gold_titles)} "
+ f"(missing {len(missing)} -> gold-missing.txt, likely redirects; "
+ f"run fetch_gold_fallback.py) | distractors {n_distractors}"
+ + (f" | full {n_full}" if args.full else ""),
+ flush=True,
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/extract_slice.py b/benchmarks/frames/extract_slice.py
new file mode 100644
index 00000000..349a0bfb
--- /dev/null
+++ b/benchmarks/frames/extract_slice.py
@@ -0,0 +1,48 @@
+"""Extract a small deterministic slice of the dump for indexing speed tests.
+
+Takes the first N articles (>= min-chars) in dump order and writes them like
+``extract_corpus.py --full`` would — same sharding, same naming — so indexing
+throughput measured on the slice extrapolates to the full corpus.
+
+ python extract_slice.py --out data/corpus-slice --limit 45000 \
+ --tfds-dir
+"""
+
+from __future__ import annotations
+
+import argparse
+from pathlib import Path
+
+from extract_corpus import SNAPSHOT, slug
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--out", required=True)
+ ap.add_argument("--limit", type=int, default=45_000)
+ ap.add_argument("--min-chars", type=int, default=500)
+ ap.add_argument("--tfds-dir", required=True)
+ args = ap.parse_args()
+
+ import tensorflow_datasets as tfds
+
+ out = Path(args.out)
+ out.mkdir(parents=True, exist_ok=True)
+ ds = tfds.load(SNAPSHOT, split="train", data_dir=args.tfds_dir)
+ written = 0
+ for ex in ds.as_numpy_iterator():
+ text = ex["text"].decode("utf-8")
+ if len(text) < args.min_chars:
+ continue
+ title = ex["title"].decode("utf-8")
+ shard = out / f"{written % 256:02x}"
+ shard.mkdir(exist_ok=True)
+ (shard / (slug(title) + ".txt")).write_text(f"{title}\n\n{text}")
+ written += 1
+ if written >= args.limit:
+ break
+ print(f"slice: {written} articles -> {out}")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/fetch_dataset.py b/benchmarks/frames/fetch_dataset.py
new file mode 100644
index 00000000..48a6576f
--- /dev/null
+++ b/benchmarks/frames/fetch_dataset.py
@@ -0,0 +1,81 @@
+"""Fetch the FRAMES questions (google/frames-benchmark) into questions.jsonl.
+
+The dataset revision is pinned (--revision, defaulting to the snapshot this
+benchmark was built against) so re-runs are reproducible even if the upstream
+dataset changes. Every row keeps the fields the harness needs: the prompt, the
+gold answer, the reasoning type, and the gold Wikipedia article links (used
+both to build the corpus and to compute article recall, the paper's retrieval
+metric).
+
+Usage:
+ python fetch_dataset.py [--out DATA_DIR] [--revision SHA]
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+from pathlib import Path
+
+import pandas as pd
+
+PINNED_REVISION = "58d9fb6330f3ab1316d1eca12e5e8ef23dcc22ef"
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--out", default="data", help="data directory")
+ ap.add_argument("--revision", default=PINNED_REVISION)
+ args = ap.parse_args()
+
+ url = (
+ "https://huggingface.co/api/datasets/google/frames-benchmark/parquet"
+ "/default/test/0.parquet"
+ )
+ # The parquet API serves the latest revision; verify it matches the pin so
+ # a silent upstream change fails loudly instead of skewing results.
+ import urllib.request
+
+ with urllib.request.urlopen(
+ "https://huggingface.co/api/datasets/google/frames-benchmark"
+ ) as r:
+ sha = json.load(r)["sha"]
+ if sha != args.revision:
+ raise SystemExit(
+ f"google/frames-benchmark moved to revision {sha}, but this "
+ f"benchmark pins {args.revision}. Review the diff and update "
+ "PINNED_REVISION deliberately."
+ )
+
+ df = pd.read_parquet(url)
+ out_dir = Path(args.out)
+ out_dir.mkdir(parents=True, exist_ok=True)
+ out = out_dir / "questions.jsonl"
+ n_links = 0
+ with out.open("w") as f:
+ for _, row in df.iterrows():
+ links = [
+ row[c]
+ for c in df.columns
+ if c.startswith("wiki")
+ and isinstance(row[c], str)
+ and row[c].startswith("http")
+ ]
+ n_links += len(links)
+ f.write(
+ json.dumps(
+ {
+ "prompt": row["Prompt"],
+ "answer": row["Answer"],
+ "reasoning": row.get("reasoning_types", ""),
+ "wiki_links": links,
+ },
+ ensure_ascii=False,
+ )
+ + "\n"
+ )
+ print(f"questions: {len(df)} | gold links: {n_links} | -> {out}")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/fetch_gold_fallback.py b/benchmarks/frames/fetch_gold_fallback.py
new file mode 100644
index 00000000..7571faa3
--- /dev/null
+++ b/benchmarks/frames/fetch_gold_fallback.py
@@ -0,0 +1,110 @@
+"""Fetch gold articles missing from the dump via the Wikipedia API.
+
+The dump stores articles under their canonical titles; a ``wiki_links`` URL
+pointing at a redirect therefore finds nothing in ``extract_corpus.py``. This
+script resolves each missing title through the live API (following redirects)
+but requests the revision **as of the paper's snapshot date** (2023-06-01), so
+the corpus stays drift-free.
+
+ python fetch_gold_fallback.py --missing data/gold-missing.txt --out data/corpus-gold
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import re
+import time
+import urllib.parse
+import urllib.request
+from pathlib import Path
+
+SNAPSHOT_TS = "2023-06-01T00:00:00Z"
+UA = {"User-Agent": "serviette-frames-bench/1.0 (github.com/pathwaycom/serviette)"}
+
+
+def slug(title: str) -> str:
+ return re.sub(r"[^A-Za-z0-9._-]+", "_", title)[:150]
+
+
+def fetch_at_snapshot(title: str) -> tuple[str, str] | None:
+ """(resolved_title, plaintext) of the last revision before the snapshot."""
+
+ # Step 1: resolve redirects to the canonical title.
+ api = (
+ "https://en.wikipedia.org/w/api.php?action=query&redirects=1&format=json"
+ "&formatversion=2&titles=" + urllib.parse.quote(title)
+ )
+ with urllib.request.urlopen(urllib.request.Request(api, headers=UA), timeout=30) as r:
+ pages = json.load(r).get("query", {}).get("pages", [])
+ if not pages or "missing" in pages[0]:
+ return None
+ resolved = pages[0]["title"]
+
+ # Step 2: the extract of the revision as of the snapshot date. TextExtracts
+ # cannot target old revisions, so pull the wikitext of that revision and
+ # strip markup crudely — good enough for retrieval text.
+ api = (
+ "https://en.wikipedia.org/w/api.php?action=query&prop=revisions"
+ "&rvprop=content&rvslots=main&rvlimit=1&format=json&formatversion=2"
+ f"&rvstart={SNAPSHOT_TS}&titles=" + urllib.parse.quote(resolved)
+ )
+ with urllib.request.urlopen(urllib.request.Request(api, headers=UA), timeout=60) as r:
+ pages = json.load(r).get("query", {}).get("pages", [])
+ revisions = pages[0].get("revisions") if pages else None
+ if not revisions:
+ return None
+ wikitext = revisions[0]["slots"]["main"]["content"]
+ text = strip_wikitext(wikitext)
+ return resolved, text
+
+
+def strip_wikitext(src: str) -> str:
+ """Rough wikitext -> plaintext: drops templates, refs, links markup."""
+
+ text = re.sub(r"(?s)]*>.*?|]*/>", "", src)
+ text = re.sub(r"(?s)\{\{(?:[^{}]|\{\{[^{}]*\}\})*\}\}", "", text)
+ text = re.sub(r"\[\[(?:[^|\]]*\|)?([^\]]+)\]\]", r"\1", text)
+ text = re.sub(r"'{2,}", "", text)
+ text = re.sub(r"(?m)^[=]{2,}.*[=]{2,}$", "", text)
+ text = re.sub(r"(?s)<[^>]+>", "", text)
+ return re.sub(r"\n{3,}", "\n\n", text).strip()
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--missing", required=True)
+ ap.add_argument("--out", required=True)
+ args = ap.parse_args()
+
+ out = Path(args.out)
+ titles = [t for t in Path(args.missing).read_text().splitlines() if t.strip()]
+ print(f"fetching {len(titles)} missing gold articles @ {SNAPSHOT_TS}")
+ failed: list[str] = []
+ for i, title in enumerate(titles):
+ result = None
+ # Wikipedia rate-limits bursts with HTTP 429; back off patiently — this
+ # script handles a few hundred stragglers, not the whole corpus.
+ for attempt in range(5):
+ try:
+ result = fetch_at_snapshot(title)
+ break
+ except Exception:
+ time.sleep(10 * (attempt + 1))
+ if result is None:
+ failed.append(title)
+ else:
+ resolved, text = result
+ # Keep the *link* title in the filename: recall matching walks the
+ # question's wiki_links, which use the pre-redirect names.
+ (out / (slug(title) + ".txt")).write_text(f"{resolved}\n\n{text}")
+ if (i + 1) % 25 == 0:
+ print(f"{i + 1}/{len(titles)}", flush=True)
+ time.sleep(1.5) # be polite to the API
+ if failed:
+ print(f"FAILED ({len(failed)}): " + "; ".join(failed[:10]))
+ print("DONE")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/judge_prompt.txt b/benchmarks/frames/judge_prompt.txt
new file mode 100644
index 00000000..09019868
--- /dev/null
+++ b/benchmarks/frames/judge_prompt.txt
@@ -0,0 +1,20 @@
+===Task===
+I need your help in evaluating an answer provided by an LLM against a ground
+truth answer. Your task is to determine if the ground truth answer is present
+in the LLM's response. Please analyze the provided data and make a decision.
+===Instructions===
+1. Carefully compare the "Predicted Answer" with the "Ground Truth Answer".
+2. Consider the substance of the answers - look for equivalent information or
+ correct answers. Do not focus on exact wording unless the exact wording is
+ crucial to the meaning.
+3. Your final decision should be based on whether the meaning and the vital
+ facts of the "Ground Truth Answer" are present in the "Predicted Answer:"
+===Input Data===
+- Question: {question}
+- Predicted Answer: {predicted}
+- Ground Truth Answer: {gold}
+===Output Format===
+Provide your final evaluation in the following format:
+"Explanation:" (How you made the decision?)
+"Decision:" ("TRUE" or "FALSE")
+Please proceed with the evaluation.
diff --git a/benchmarks/frames/run_bench.py b/benchmarks/frames/run_bench.py
new file mode 100644
index 00000000..16b4cdd2
--- /dev/null
+++ b/benchmarks/frames/run_bench.py
@@ -0,0 +1,143 @@
+"""End-to-end FRAMES run: ask every question via serviette ``/rag``, judge the
+answers with the paper's autorater prompt (Appendix B, judge_prompt.txt).
+
+Reports accuracy (the paper's headline metric) **and** gold-article recall of
+the contexts actually used (the paper's retrieval metric), plus token usage of
+the judge. Generation cost lives inside the serviette server (its ``llm``
+config section); the judge model is set here.
+
+ OPENAI_API_KEY=... python run_bench.py --questions data/questions.jsonl \
+ --port 8987 --k 8 --label e5small-hybrid-gpt4o \
+ [--judge-model gpt-4o-mini] [--limit 0] [--concurrency 6]
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import os
+import statistics
+import time
+import urllib.request
+from concurrent.futures import ThreadPoolExecutor
+from pathlib import Path
+from threading import Lock
+
+from run_retrieval_eval import gold_slugs, hit_slug, post_json
+
+JUDGE_PROMPT = (Path(__file__).parent / "judge_prompt.txt").read_text()
+
+
+def openai_chat(model: str, prompt: str, api_key: str) -> tuple[str, dict]:
+ body = {
+ "model": model,
+ "temperature": 0,
+ "messages": [{"role": "user", "content": prompt}],
+ }
+ req = urllib.request.Request(
+ "https://api.openai.com/v1/chat/completions",
+ data=json.dumps(body).encode(),
+ headers={
+ "Content-Type": "application/json",
+ "Authorization": f"Bearer {api_key}",
+ },
+ )
+ for attempt in range(5):
+ try:
+ with urllib.request.urlopen(req, timeout=180) as r:
+ resp = json.load(r)
+ return resp["choices"][0]["message"]["content"], resp.get("usage", {})
+ except Exception:
+ if attempt == 4:
+ raise
+ time.sleep(3 * (attempt + 1))
+ raise RuntimeError("unreachable")
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--port", type=int, default=8987)
+ ap.add_argument("--k", type=int, default=8)
+ ap.add_argument("--label", required=True)
+ ap.add_argument("--judge-model", default="gpt-4o-mini")
+ ap.add_argument("--limit", type=int, default=0)
+ ap.add_argument("--concurrency", type=int, default=6)
+ ap.add_argument("--out", default=None)
+ args = ap.parse_args()
+
+ api_key = os.environ["OPENAI_API_KEY"]
+ questions = [json.loads(line) for line in open(args.questions)]
+ if args.limit:
+ questions = questions[: args.limit]
+ rag_url = f"http://127.0.0.1:{args.port}/api/v1/rag"
+
+ usage_lock = Lock()
+ judge_usage = {"prompt_tokens": 0, "completion_tokens": 0}
+
+ def ask(item: dict) -> dict:
+ # Reasoning generators can spend minutes per answer; a tight timeout
+ # here is worse than useless — the server keeps generating after the
+ # client gives up, so every retry pays for a duplicate generation.
+ resp = post_json(
+ rag_url, {"query": item["prompt"], "k": args.k}, timeout=900, retries=2
+ )
+ gold = gold_slugs(item["wiki_links"])
+ got = {hit_slug(h) for h in resp.get("sources", [])}
+ return {
+ **item,
+ "predicted": resp.get("answer", ""),
+ "context_recall": len(gold & got) / len(gold) if gold else 1.0,
+ }
+
+ def judge(item: dict) -> dict:
+ verdict, usage = openai_chat(
+ args.judge_model,
+ JUDGE_PROMPT.format(
+ question=item["prompt"],
+ predicted=item["predicted"],
+ gold=item["answer"],
+ ),
+ api_key,
+ )
+ with usage_lock:
+ judge_usage["prompt_tokens"] += usage.get("prompt_tokens", 0)
+ judge_usage["completion_tokens"] += usage.get("completion_tokens", 0)
+ correct = '"TRUE"' in verdict or verdict.rstrip().endswith("TRUE")
+ return {**item, "judge": verdict[-400:], "correct": bool(correct)}
+
+ t0 = time.time()
+ with ThreadPoolExecutor(max_workers=args.concurrency) as ex:
+ answered = list(ex.map(ask, questions))
+ t_answer = time.time() - t0
+ print(f"answered {len(answered)} in {t_answer:.0f}s", flush=True)
+
+ t0 = time.time()
+ with ThreadPoolExecutor(max_workers=args.concurrency) as ex:
+ judged = list(ex.map(judge, answered))
+ print(f"judged in {time.time() - t0:.0f}s", flush=True)
+
+ accuracy = statistics.mean(1.0 if r["correct"] else 0.0 for r in judged)
+ recall = statistics.mean(r["context_recall"] for r in judged)
+ summary = {
+ "label": args.label,
+ "k": args.k,
+ "questions": len(judged),
+ "accuracy": round(accuracy, 4),
+ "context_article_recall": round(recall, 4),
+ "judge_model": args.judge_model,
+ "judge_usage": judge_usage,
+ "answer_seconds": round(t_answer),
+ }
+ print(json.dumps(summary))
+
+ out = Path(args.out or f"results/bench-{args.label}.jsonl")
+ out.parent.mkdir(parents=True, exist_ok=True)
+ with out.open("w") as f:
+ f.write(json.dumps({"summary": summary}) + "\n")
+ for row in judged:
+ f.write(json.dumps(row, ensure_ascii=False) + "\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/run_bm25_baseline.py b/benchmarks/frames/run_bm25_baseline.py
new file mode 100644
index 00000000..91cc04db
--- /dev/null
+++ b/benchmarks/frames/run_bm25_baseline.py
@@ -0,0 +1,132 @@
+"""Reproduce the paper's naive baseline on this corpus: article-level BM25.
+
+The FRAMES paper's BM25-R baseline retrieved whole Wikipedia articles with the
+raw question as the query (n_docs 2 and 4), reaching 0.12-0.15 article recall
+over the full ~6.7M-article dump. This script runs the identical setup over
+*this benchmark's* corpus, which quantifies how much of serviette's recall
+advantage is the retrieval stack and how much is the smaller haystack.
+
+Streaming two-pass BM25 (Okapi, k1=1.5, b=0.75), no index kept in memory:
+pass 1 accumulates document frequencies, pass 2 scores every article against
+all questions at once, keeping a top-n heap per question.
+
+ python run_bm25_baseline.py --questions $FRAMES_DATA/questions.jsonl \
+ --corpus $FRAMES_DATA/corpus-gold $FRAMES_DATA/corpus-distractors \
+ --n-docs 4
+"""
+
+from __future__ import annotations
+
+import argparse
+import heapq
+import json
+import math
+import re
+import statistics
+from pathlib import Path
+
+from run_retrieval_eval import gold_slugs
+
+_TOKEN = re.compile(r"\w+")
+K1, B = 1.5, 0.75
+
+
+def tokenize(text: str) -> list[str]:
+ return _TOKEN.findall(text.lower())
+
+
+def iter_articles(roots: list[Path]):
+ for root in roots:
+ for path in sorted(root.rglob("*.txt")):
+ yield path.stem.casefold(), path.read_text(errors="replace")
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--corpus", nargs="+", required=True)
+ ap.add_argument("--n-docs", type=int, default=4)
+ ap.add_argument("--out", default="results/bm25-baseline.json")
+ args = ap.parse_args()
+
+ questions = [json.loads(line) for line in open(args.questions)]
+ queries = [tokenize(q["prompt"]) for q in questions]
+ roots = [Path(p) for p in args.corpus]
+
+ # Pass 1: document frequencies and lengths. Only the query vocabulary
+ # matters for scoring, so df is tracked for those tokens alone — on the
+ # full ~5M-article dump a whole-vocabulary df dict would not fit the
+ # memory budget, and BM25 never consults it for non-query terms.
+ query_vocab = {t for q in queries for t in q}
+ df: dict[str, int] = {}
+ doc_count = 0
+ total_len = 0
+ for _slug, text in iter_articles(roots):
+ doc_count += 1
+ tokens = tokenize(text)
+ total_len += len(tokens)
+ for token in set(tokens) & query_vocab:
+ df[token] = df.get(token, 0) + 1
+ if doc_count % 100_000 == 0:
+ print(f"pass1: {doc_count} docs", flush=True)
+ avg_len = total_len / doc_count
+ idf = {
+ t: math.log(1.0 + (doc_count - n + 0.5) / (n + 0.5)) for t, n in df.items()
+ }
+ print(
+ f"pass1 done: {doc_count} docs, query vocab {len(query_vocab)}, "
+ f"matched {len(idf)}",
+ flush=True,
+ )
+
+ # Pass 2: score every article against every question; keep top-n heaps.
+ query_terms = [
+ {t: idf[t] for t in q if t in idf} for q in queries
+ ]
+ heaps: list[list[tuple[float, str]]] = [[] for _ in questions]
+ scanned = 0
+ for slug, text in iter_articles(roots):
+ tf: dict[str, int] = {}
+ for token in tokenize(text):
+ tf[token] = tf.get(token, 0) + 1
+ doc_len = sum(tf.values())
+ norm = K1 * (1 - B + B * doc_len / avg_len)
+ for qi, terms in enumerate(query_terms):
+ score = 0.0
+ for token, token_idf in terms.items():
+ f = tf.get(token)
+ if f:
+ score += token_idf * f * (K1 + 1) / (f + norm)
+ if score > 0.0:
+ heap = heaps[qi]
+ if len(heap) < args.n_docs:
+ heapq.heappush(heap, (score, slug))
+ elif score > heap[0][0]:
+ heapq.heapreplace(heap, (score, slug))
+ scanned += 1
+ if scanned % 100_000 == 0:
+ print(f"pass2: {scanned} docs", flush=True)
+
+ recalls = []
+ full = []
+ for q, heap in zip(questions, heaps):
+ gold = gold_slugs(q["wiki_links"])
+ got = {slug for _score, slug in heap}
+ covered = gold & got
+ recalls.append(len(covered) / len(gold) if gold else 1.0)
+ full.append(1.0 if covered == gold else 0.0)
+
+ summary = {
+ "setup": f"article-level BM25@{args.n_docs}, raw question as query",
+ "docs": doc_count,
+ "questions": len(questions),
+ "article_recall": round(statistics.mean(recalls), 4),
+ "full_coverage_rate": round(statistics.mean(full), 4),
+ }
+ print(json.dumps(summary))
+ Path(args.out).parent.mkdir(parents=True, exist_ok=True)
+ Path(args.out).write_text(json.dumps(summary, indent=2))
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/run_ladder.py b/benchmarks/frames/run_ladder.py
new file mode 100644
index 00000000..db36e376
--- /dev/null
+++ b/benchmarks/frames/run_ladder.py
@@ -0,0 +1,200 @@
+"""Corpus-independent ladder rungs: naive (no retrieval) and oracle.
+
+These two mirror the paper's calibration rows and involve no retrieval at
+all, so they run without any index:
+
+- ``--mode naive``: the question alone — measures the generator's parametric
+ knowledge (the paper: 40.8% for Gemini-Pro-1.5);
+- ``--mode oracle``: the question plus the *gold* Wikipedia articles
+ (``wiki_links``) as context — the retrieval-quality ceiling (the paper:
+ 72.9%). Gold articles come from the snapshot corpus; the few post-snapshot
+ ones are absent here exactly as they were for the paper.
+
+Direct OpenAI calls (no serviette server involved), the Appendix-B judge,
+and built-in cost accounting: an estimate is printed *before* anything is
+spent, actual usage is accumulated from every response and reported in the
+summary.
+
+ OPENAI_API_KEY=... python run_ladder.py --mode naive --generator gpt-5 \
+ --questions $FRAMES_DATA/questions.jsonl [--limit 20]
+ OPENAI_API_KEY=... python run_ladder.py --mode oracle --generator gpt-5 \
+ --questions $FRAMES_DATA/questions.jsonl --gold-dir $FRAMES_DATA/corpus-gold
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import os
+import statistics
+import time
+import urllib.request
+from concurrent.futures import ThreadPoolExecutor
+from pathlib import Path
+from threading import Lock
+
+from run_bench import JUDGE_PROMPT
+from run_retrieval_eval import gold_slugs
+
+# $/1M tokens (input, output); used for the pre-run estimate and the actual
+# spend report. Update when prices move.
+PRICES = {
+ "gpt-5": (1.25, 10.0),
+ "gpt-5-mini": (0.25, 2.0),
+ "gpt-4o": (2.50, 10.0),
+ "gpt-4o-mini": (0.15, 0.60),
+}
+
+RAG_SYSTEM = (
+ "You are a helpful assistant. Answer the user's question using only the "
+ "provided context. If the context is insufficient, say so."
+)
+
+
+class Usage:
+ def __init__(self) -> None:
+ self.lock = Lock()
+ self.prompt = 0
+ self.completion = 0
+
+ def add(self, usage: dict) -> None:
+ with self.lock:
+ self.prompt += usage.get("prompt_tokens", 0)
+ self.completion += usage.get("completion_tokens", 0)
+
+ def cost(self, model: str) -> float:
+ p_in, p_out = PRICES.get(model, (0, 0))
+ return (self.prompt * p_in + self.completion * p_out) / 1e6
+
+
+def chat(model: str, messages: list[dict], api_key: str, *, temperature=None) -> tuple[str, dict]:
+ body: dict = {"model": model, "messages": messages}
+ if temperature is not None:
+ body["temperature"] = temperature
+ if model.startswith(("gpt-5", "o")):
+ body["max_completion_tokens"] = 8000 # bound reasoning runaways
+ req = urllib.request.Request(
+ "https://api.openai.com/v1/chat/completions",
+ data=json.dumps(body).encode(),
+ headers={"Content-Type": "application/json", "Authorization": f"Bearer {api_key}"},
+ )
+ for attempt in range(5):
+ try:
+ with urllib.request.urlopen(req, timeout=600) as r:
+ resp = json.load(r)
+ return resp["choices"][0]["message"]["content"] or "", resp.get("usage", {})
+ except Exception:
+ if attempt == 4:
+ raise
+ time.sleep(5 * (attempt + 1))
+ raise RuntimeError("unreachable")
+
+
+def oracle_context(item: dict, gold_dir: Path, max_chars: int) -> str:
+ parts = []
+ for slug in sorted(gold_slugs(item["wiki_links"])):
+ # Files are stored with original-case slugs; resolve case-insensitively.
+ matches = [p for p in gold_dir.glob("*.txt") if p.stem.casefold() == slug]
+ if matches:
+ parts.append(matches[0].read_text(errors="replace"))
+ context = "\n\n====\n\n".join(parts)
+ return context[:max_chars]
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--mode", choices=["naive", "oracle"], required=True)
+ ap.add_argument("--generator", required=True)
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--gold-dir", default=None)
+ ap.add_argument("--judge-model", default="gpt-4o-mini")
+ ap.add_argument("--limit", type=int, default=0)
+ ap.add_argument("--concurrency", type=int, default=6)
+ ap.add_argument("--max-context-chars", type=int, default=400_000)
+ ap.add_argument("--results", default="results")
+ args = ap.parse_args()
+
+ api_key = os.environ["OPENAI_API_KEY"]
+ questions = [json.loads(line) for line in open(args.questions)]
+ if args.limit:
+ questions = questions[: args.limit]
+ gold_dir = Path(args.gold_dir) if args.gold_dir else None
+ if args.mode == "oracle" and gold_dir is None:
+ raise SystemExit("--mode oracle requires --gold-dir")
+
+ # ---- pre-run cost estimate (printed BEFORE any spend) -------------------
+ p_in, p_out = PRICES.get(args.generator, (0, 0))
+ if args.mode == "naive":
+ est_in = len(questions) * 80
+ else:
+ est_in = len(questions) * 22_000
+ est_out = len(questions) * (1200 if args.generator.startswith(("gpt-5", "o")) else 100)
+ est = (est_in * p_in + est_out * p_out) / 1e6
+ judge_est = len(questions) * 450 * 0.15 / 1e6 + len(questions) * 110 * 0.6 / 1e6
+ print(
+ f"ESTIMATE [{args.mode}/{args.generator}/{len(questions)}q]: "
+ f"~{est_in/1e6:.1f}M in + ~{est_out/1e6:.2f}M out ≈ ${est:.2f} "
+ f"(+judge ≈ ${judge_est:.2f})",
+ flush=True,
+ )
+
+ gen_usage, judge_usage = Usage(), Usage()
+
+ def ask(item: dict) -> dict:
+ if args.mode == "naive":
+ messages = [{"role": "user", "content": item["prompt"]}]
+ else:
+ context = oracle_context(item, gold_dir, args.max_context_chars)
+ messages = [
+ {"role": "system", "content": RAG_SYSTEM},
+ {"role": "user", "content": f"Context:\n{context}\n\nQuestion: {item['prompt']}"},
+ ]
+ temperature = None if args.generator.startswith(("gpt-5", "o")) else 0
+ answer, usage = chat(args.generator, messages, api_key, temperature=temperature)
+ gen_usage.add(usage)
+ return {**item, "predicted": answer}
+
+ def judge(item: dict) -> dict:
+ verdict, usage = chat(
+ args.judge_model,
+ [{"role": "user", "content": JUDGE_PROMPT.format(
+ question=item["prompt"], predicted=item["predicted"], gold=item["answer"])}],
+ api_key,
+ temperature=0,
+ )
+ judge_usage.add(usage)
+ correct = '"TRUE"' in verdict or verdict.rstrip().endswith("TRUE")
+ return {**item, "judge": verdict[-400:], "correct": bool(correct)}
+
+ t0 = time.time()
+ with ThreadPoolExecutor(max_workers=args.concurrency) as ex:
+ answered = list(ex.map(ask, questions))
+ print(
+ f"answered {len(answered)} in {time.time()-t0:.0f}s | gen spend so far: "
+ f"${gen_usage.cost(args.generator):.2f}",
+ flush=True,
+ )
+ with ThreadPoolExecutor(max_workers=args.concurrency) as ex:
+ judged = list(ex.map(judge, answered))
+
+ accuracy = statistics.mean(1.0 if r["correct"] else 0.0 for r in judged)
+ label = f"{args.mode}-{args.generator}"
+ summary = {
+ "label": label,
+ "questions": len(judged),
+ "accuracy": round(accuracy, 4),
+ "generator_usage": {"prompt": gen_usage.prompt, "completion": gen_usage.completion},
+ "generator_cost_usd": round(gen_usage.cost(args.generator), 2),
+ "judge_cost_usd": round(judge_usage.cost(args.judge_model), 2),
+ }
+ print(json.dumps(summary), flush=True)
+ out = Path(args.results) / f"ladder-{label}.jsonl"
+ out.parent.mkdir(parents=True, exist_ok=True)
+ with out.open("w") as f:
+ f.write(json.dumps({"summary": summary}) + "\n")
+ for row in judged:
+ f.write(json.dumps(row, ensure_ascii=False) + "\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/run_phase0.py b/benchmarks/frames/run_phase0.py
new file mode 100644
index 00000000..74fef846
--- /dev/null
+++ b/benchmarks/frames/run_phase0.py
@@ -0,0 +1,155 @@
+"""Phase-0 sweep: article recall for every retrieval configuration, LLM-free.
+
+For each configuration overlay, merges it into the base config, starts a
+serviette server, waits for readiness, measures gold-article recall at k via
+``run_retrieval_eval`` machinery, and stops the server. One summary line per
+configuration lands in ``results/phase0-summary.jsonl`` (plus a per-question
+jsonl per configuration).
+
+ python run_phase0.py --base configs/base-e5small.yaml \
+ --questions $FRAMES_DATA/questions.jsonl [--k 8] [--only label,label]
+"""
+
+from __future__ import annotations
+
+import argparse
+import copy
+import json
+import os
+import statistics
+import subprocess
+import sys
+import tempfile
+import time
+import urllib.request
+from concurrent.futures import ThreadPoolExecutor
+from pathlib import Path
+
+import yaml
+
+from run_retrieval_eval import gold_slugs, hit_slug, post_json
+
+# The serviette package resolves from the repo root, not from benchmarks/.
+REPO_ROOT = Path(__file__).resolve().parents[2]
+
+# Retrieval-only overlays (no LLM anywhere). Decompose is deliberately absent:
+# it needs an LLM call per question and belongs to the paid phases.
+OVERLAYS: dict[str, dict] = {
+ "vector": {},
+ "hybrid": {"vector_db": {"hybrid": True}},
+ "mmr": {"rag": {"mmr": {"candidates": 24, "diversity": 0.3}}},
+ "hybrid-mmr": {
+ "vector_db": {"hybrid": True},
+ "rag": {"mmr": {"candidates": 24, "diversity": 0.3}},
+ },
+ "ce-rerank": {"reranker": {"type": "cross_encoder", "candidates": 30}},
+ "hybrid-ce-rerank": {
+ "vector_db": {"hybrid": True},
+ "reranker": {"type": "cross_encoder", "candidates": 30},
+ },
+}
+
+
+def deep_merge(base: dict, patch: dict) -> dict:
+ out = copy.deepcopy(base)
+ for key, value in patch.items():
+ if isinstance(value, dict) and isinstance(out.get(key), dict):
+ out[key] = deep_merge(out[key], value)
+ else:
+ out[key] = value
+ return out
+
+
+def wait_ready(port: int, timeout: float = 600.0) -> None:
+ deadline = time.time() + timeout
+ url = f"http://127.0.0.1:{port}/api/v1/health"
+ while time.time() < deadline:
+ try:
+ with urllib.request.urlopen(url, timeout=5) as r:
+ if r.status == 200:
+ return
+ except Exception:
+ time.sleep(2)
+ raise TimeoutError(f"server on :{port} did not become ready")
+
+
+def evaluate(questions: list[dict], port: int, k: int, concurrency: int) -> list[dict]:
+ url = f"http://127.0.0.1:{port}/api/v1/retrieve"
+
+ def one(item: dict) -> dict:
+ gold = gold_slugs(item["wiki_links"])
+ hits = post_json(url, {"query": item["prompt"], "k": k}, timeout=300)["results"]
+ covered = gold & {hit_slug(h) for h in hits}
+ return {
+ "prompt": item["prompt"],
+ "recall": len(covered) / len(gold) if gold else 1.0,
+ "full_coverage": len(covered) == len(gold),
+ }
+
+ with ThreadPoolExecutor(max_workers=concurrency) as ex:
+ return list(ex.map(one, questions))
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--base", required=True)
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--k", type=int, default=8)
+ ap.add_argument("--concurrency", type=int, default=8)
+ ap.add_argument("--only", default="", help="comma-separated overlay labels")
+ ap.add_argument("--results", default="results")
+ args = ap.parse_args()
+
+ base = yaml.safe_load(Path(args.base).read_text())
+ questions = [json.loads(line) for line in open(args.questions)]
+ labels = [s for s in args.only.split(",") if s] or list(OVERLAYS)
+ port = base.get("server", {}).get("port", 8987)
+ results_dir = Path(args.results)
+ results_dir.mkdir(parents=True, exist_ok=True)
+ summary_path = results_dir / "phase0-summary.jsonl"
+
+ for label in labels:
+ config = deep_merge(base, OVERLAYS[label])
+ config.pop("sources", None) # server needs no sources section
+ with tempfile.NamedTemporaryFile(
+ "w", suffix=f"-{label}.yaml", delete=False
+ ) as f:
+ yaml.safe_dump(config, f)
+ config_path = f.name
+ print(f"=== {label}: starting server", flush=True)
+ server_log = (results_dir / f"phase0-{label}-server.log").open("w")
+ proc = subprocess.Popen(
+ [sys.executable, "-m", "serviette.cli", "server", "--config", config_path],
+ cwd=REPO_ROOT,
+ env=dict(os.environ),
+ stdout=server_log,
+ stderr=subprocess.STDOUT,
+ )
+ try:
+ wait_ready(port)
+ t0 = time.time()
+ rows = evaluate(questions, port, args.k, args.concurrency)
+ elapsed = time.time() - t0
+ finally:
+ proc.terminate()
+ proc.wait(timeout=30)
+ summary = {
+ "label": label,
+ "k": args.k,
+ "questions": len(rows),
+ "article_recall": round(statistics.mean(r["recall"] for r in rows), 4),
+ "full_coverage_rate": round(
+ statistics.mean(1.0 if r["full_coverage"] else 0.0 for r in rows), 4
+ ),
+ "seconds": round(elapsed),
+ }
+ print(json.dumps(summary), flush=True)
+ with summary_path.open("a") as f:
+ f.write(json.dumps(summary) + "\n")
+ with (results_dir / f"phase0-{label}.jsonl").open("w") as f:
+ for row in rows:
+ f.write(json.dumps(row, ensure_ascii=False) + "\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/run_phase1.py b/benchmarks/frames/run_phase1.py
new file mode 100644
index 00000000..756dd70f
--- /dev/null
+++ b/benchmarks/frames/run_phase1.py
@@ -0,0 +1,127 @@
+"""Phase-1/2 sweep: end-to-end accuracy for selected configurations.
+
+Same orchestration as ``run_phase0`` (server per configuration overlay), but
+the server gets an ``llm`` section and every question runs through ``/rag``
+with the Appendix-B judge (``run_bench.py``).
+
+ OPENAI_API_KEY=... python run_phase1.py --base configs/base-e5small.yaml \
+ --questions $FRAMES_DATA/questions.jsonl \
+ --generator gpt-4o-mini [--k 8] [--only label,label] [--limit 0]
+"""
+
+from __future__ import annotations
+
+import argparse
+import os
+import subprocess
+import sys
+import tempfile
+import time
+from pathlib import Path
+
+import yaml
+
+from run_phase0 import REPO_ROOT, deep_merge, wait_ready
+
+# End-to-end overlays: phase-0 winners plus the LLM-dependent strategies
+# (decompose, adaptive) that retrieval-only ranking cannot measure.
+OVERLAYS: dict[str, dict] = {
+ "vector": {},
+ "hybrid": {"vector_db": {"hybrid": True}},
+ "hybrid-mmr": {
+ "vector_db": {"hybrid": True},
+ "rag": {"mmr": {"candidates": 24, "diversity": 0.3}},
+ },
+ "hybrid-decompose": {
+ "vector_db": {"hybrid": True},
+ "rag": {"decompose": {"max_subqueries": 4}},
+ },
+ "hybrid-decompose-adaptive": {
+ "vector_db": {"hybrid": True},
+ "rag": {
+ "decompose": {"max_subqueries": 4},
+ "adaptive": {"factor": 2, "max_iterations": 3},
+ },
+ },
+}
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--base", required=True)
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--generator", required=True)
+ ap.add_argument("--k", type=int, default=8)
+ ap.add_argument("--limit", type=int, default=0)
+ ap.add_argument("--concurrency", type=int, default=6)
+ ap.add_argument("--only", default="", help="comma-separated overlay labels")
+ ap.add_argument("--results", default="results")
+ args = ap.parse_args()
+
+ base = yaml.safe_load(Path(args.base).read_text())
+ labels = [s for s in args.only.split(",") if s] or list(OVERLAYS)
+ port = base.get("server", {}).get("port", 8987)
+ results_dir = Path(args.results)
+ results_dir.mkdir(parents=True, exist_ok=True)
+
+ llm_section = {
+ "llm": {
+ "type": "openai",
+ "model": args.generator,
+ "api_key": "${OPENAI_API_KEY}",
+ }
+ }
+ # Reasoning models (gpt-5*, o*) accept only the default temperature; for
+ # the rest, pin 0 for reproducibility (documented in the README).
+ if not args.generator.startswith(("gpt-5", "o")):
+ llm_section["llm"]["temperature"] = 0
+
+ for label in labels:
+ config = deep_merge(deep_merge(base, OVERLAYS[label]), llm_section)
+ config.pop("sources", None)
+ with tempfile.NamedTemporaryFile(
+ "w", suffix=f"-{label}.yaml", delete=False
+ ) as f:
+ yaml.safe_dump(config, f)
+ config_path = f.name
+ run_label = f"{label}-{args.generator}"
+ print(f"=== {run_label}: starting server", flush=True)
+ server_log = (results_dir / f"bench-{run_label}-server.log").open("w")
+ proc = subprocess.Popen(
+ [sys.executable, "-m", "serviette.cli", "server", "--config", config_path],
+ cwd=REPO_ROOT,
+ env=dict(os.environ),
+ stdout=server_log,
+ stderr=subprocess.STDOUT,
+ )
+ try:
+ wait_ready(port)
+ t0 = time.time()
+ bench = subprocess.run(
+ [
+ sys.executable,
+ str(Path(__file__).parent / "run_bench.py"),
+ "--questions", args.questions,
+ "--port", str(port),
+ "--k", str(args.k),
+ "--label", run_label,
+ "--limit", str(args.limit),
+ "--concurrency", str(args.concurrency),
+ "--out", str(results_dir / f"bench-{run_label}.jsonl"),
+ ],
+ cwd=Path(__file__).parent,
+ env=dict(os.environ),
+ capture_output=True,
+ text=True,
+ )
+ print(bench.stdout.strip(), flush=True)
+ if bench.returncode != 0:
+ print(f"BENCH FAILED for {run_label}:\n{bench.stderr[-2000:]}", flush=True)
+ print(f"({run_label}: {time.time() - t0:.0f}s total)", flush=True)
+ finally:
+ proc.terminate()
+ proc.wait(timeout=30)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/run_retrieval_eval.py b/benchmarks/frames/run_retrieval_eval.py
new file mode 100644
index 00000000..dd5d8ad4
--- /dev/null
+++ b/benchmarks/frames/run_retrieval_eval.py
@@ -0,0 +1,127 @@
+"""Phase-0 evaluation: gold-article recall of the retrieval stack. LLM-free.
+
+For every question, asks a running serviette server (``/api/v1/retrieve``) for
+the top-k chunks and measures **article recall** — the fraction of the
+question's gold Wikipedia articles (``wiki_links``) that have at least one
+chunk in the context. This is the retrieval metric the FRAMES paper reports
+(their BM25 setup reached 0.12–0.15), so retrieval configurations can be
+ranked against the paper and against each other at zero LLM cost.
+
+ python run_retrieval_eval.py --questions data/questions.jsonl \
+ --port 8987 --k 8 --label e5small-hybrid \
+ [--out results/retrieval-e5small-hybrid.jsonl]
+
+The gold mapping relies on corpus file names being ``slug(title).txt`` (see
+extract_corpus.py); a retrieved chunk counts toward an article when its
+``metadata.path`` basename matches the slug of a ``wiki_links`` title.
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import re
+import statistics
+import urllib.parse
+import urllib.request
+from concurrent.futures import ThreadPoolExecutor
+from pathlib import Path
+
+
+def slug(title: str) -> str:
+ return re.sub(r"[^A-Za-z0-9._-]+", "_", title)[:150]
+
+
+def link_title(url: str) -> str:
+ """Article title of a wiki link: fragment stripped, percent-decoding applied
+ (twice — some dataset links are double-encoded), underscores to spaces."""
+
+ tail = url.rsplit("/wiki/", 1)[-1].split("#", 1)[0]
+ return urllib.parse.unquote(urllib.parse.unquote(tail)).replace("_", " ").strip()
+
+
+def gold_slugs(links: list[str]) -> set[str]:
+ # Casefolded: corpus files carry the dump's canonical title, links the
+ # (possibly differently-cased) pre-redirect name.
+ return {slug(link_title(u)).casefold() for u in links}
+
+
+def post_json(url: str, body: dict, timeout: int = 120, retries: int = 4) -> dict:
+ """POST with retries: heavy configurations (decompose × hybrid) can push a
+ transient 408/500 out of the vector store; one lost request must not kill
+ an 824-question run."""
+
+ import time
+
+ req = urllib.request.Request(
+ url,
+ data=json.dumps(body).encode(),
+ headers={"Content-Type": "application/json"},
+ )
+ for attempt in range(retries + 1):
+ try:
+ with urllib.request.urlopen(req, timeout=timeout) as r:
+ return json.load(r)
+ except Exception:
+ if attempt == retries:
+ raise
+ time.sleep(2 * (attempt + 1))
+ raise RuntimeError("unreachable")
+
+
+def hit_slug(hit: dict) -> str:
+ path = (hit.get("metadata") or {}).get("path", "")
+ name = Path(path).name
+ return (name[:-4] if name.endswith(".txt") else name).casefold()
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--questions", required=True)
+ ap.add_argument("--port", type=int, default=8987)
+ ap.add_argument("--k", type=int, default=8)
+ ap.add_argument("--label", required=True)
+ ap.add_argument("--out", default=None)
+ ap.add_argument("--concurrency", type=int, default=8)
+ args = ap.parse_args()
+
+ questions = [json.loads(line) for line in open(args.questions)]
+ url = f"http://127.0.0.1:{args.port}/api/v1/retrieve"
+
+ def evaluate(item: dict) -> dict:
+ gold = gold_slugs(item["wiki_links"])
+ hits = post_json(url, {"query": item["prompt"], "k": args.k})["results"]
+ got = {hit_slug(h) for h in hits}
+ covered = gold & got
+ return {
+ "prompt": item["prompt"],
+ "gold": sorted(gold),
+ "covered": sorted(covered),
+ "recall": len(covered) / len(gold) if gold else 1.0,
+ "full_coverage": covered == gold,
+ }
+
+ with ThreadPoolExecutor(max_workers=args.concurrency) as ex:
+ rows = list(ex.map(evaluate, questions))
+
+ recall = statistics.mean(r["recall"] for r in rows)
+ full = statistics.mean(1.0 if r["full_coverage"] else 0.0 for r in rows)
+ summary = {
+ "label": args.label,
+ "k": args.k,
+ "questions": len(rows),
+ "article_recall": round(recall, 4),
+ "full_coverage_rate": round(full, 4),
+ }
+ print(json.dumps(summary))
+
+ out = Path(args.out or f"results/retrieval-{args.label}.jsonl")
+ out.parent.mkdir(parents=True, exist_ok=True)
+ with out.open("w") as f:
+ f.write(json.dumps({"summary": summary}) + "\n")
+ for row in rows:
+ f.write(json.dumps(row, ensure_ascii=False) + "\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/frames/run_taxonomy.py b/benchmarks/frames/run_taxonomy.py
new file mode 100644
index 00000000..2d2b6b3c
--- /dev/null
+++ b/benchmarks/frames/run_taxonomy.py
@@ -0,0 +1,123 @@
+"""Classify the failures of a bench run into an error taxonomy.
+
+For every question the run got wrong, an LLM classifier (given the question,
+the gold answer, the model's answer, and the retrieval coverage flag) assigns
+exactly one category:
+
+- ``retrieval_miss`` — needed facts absent from the context and the answer
+ shows the model didn't know them either;
+- ``reasoning_error`` — facts were available (context or evidently known)
+ but chained/aggregated incorrectly;
+- ``judge_error`` — the prediction is actually equivalent to the gold
+ answer (the autorater was too strict);
+- ``dataset_issue`` — the question/gold answer is ambiguous, outdated for
+ the 2023-06-01 snapshot, or self-inconsistent.
+
+Judge-error rows double as an estimate of autorater noise, so the taxonomy
+also bounds measurement error of the headline accuracies.
+
+ OPENAI_API_KEY=... python run_taxonomy.py \
+ --run results/bench-serviette-fullwiki-gpt5-permissive.jsonl \
+ [--classifier gpt-4o]
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import os
+import re
+from collections import Counter
+from concurrent.futures import ThreadPoolExecutor
+from pathlib import Path
+
+from run_ladder import Usage, chat
+
+PROMPT = """\
+You are auditing a RAG benchmark. A model answered a multi-hop question \
+incorrectly according to an automatic judge. Classify the failure into \
+exactly one category:
+
+- retrieval_miss: the answer indicates required facts were not available \
+(refusal, "context doesn't say", or a guess unsupported by any fact)
+- reasoning_error: the necessary facts appear known or provided, but they \
+were combined, compared, counted, or converted incorrectly
+- judge_error: the prediction is substantively equivalent to the gold answer \
+(formatting, units, naming variants, added detail) and was misgraded
+- dataset_issue: the question or its gold answer is ambiguous, time-\
+dependent beyond the 2023-06-01 snapshot, or internally inconsistent
+
+Question: {question}
+Gold answer: {gold}
+Model's answer: {predicted}
+Share of gold articles present in the retrieved context: {recall}
+
+Reply with the category name alone on the first line, then one short \
+sentence of justification."""
+
+
+def main() -> None:
+ ap = argparse.ArgumentParser()
+ ap.add_argument("--run", required=True)
+ ap.add_argument("--classifier", default="gpt-4o")
+ ap.add_argument("--concurrency", type=int, default=8)
+ ap.add_argument("--out", default=None)
+ args = ap.parse_args()
+
+ rows = [json.loads(line) for line in open(args.run)]
+ summary_in = rows[0].get("summary", {})
+ failures = [r for r in rows[1:] if not r.get("correct")]
+ print(f"failures to classify: {len(failures)} of {summary_in.get('questions')}")
+
+ api_key = os.environ["OPENAI_API_KEY"]
+ usage = Usage()
+ categories = [
+ "retrieval_miss", "reasoning_error", "judge_error", "dataset_issue"
+ ]
+
+ def classify(item: dict) -> dict:
+ reply, u = chat(
+ args.classifier,
+ [{"role": "user", "content": PROMPT.format(
+ question=item["prompt"],
+ gold=item["answer"],
+ predicted=item["predicted"][:2000],
+ recall=item.get("context_recall", "n/a"),
+ )}],
+ api_key,
+ temperature=0,
+ )
+ usage.add(u)
+ first = reply.strip().splitlines()[0].strip().lower()
+ category = next(
+ (c for c in categories if c in first or c in re.sub(r"\W", "_", first)),
+ "unparsed",
+ )
+ return {**item, "taxonomy": category, "taxonomy_note": reply[:300]}
+
+ with ThreadPoolExecutor(max_workers=args.concurrency) as ex:
+ classified = list(ex.map(classify, failures))
+
+ counts = Counter(r["taxonomy"] for r in classified)
+ total = len(classified)
+ summary = {
+ "run": Path(args.run).name,
+ "classifier": args.classifier,
+ "failures": total,
+ "taxonomy": {
+ c: {"n": counts.get(c, 0), "share": round(counts.get(c, 0) / total, 3)}
+ for c in categories + ["unparsed"]
+ if counts.get(c)
+ },
+ "classifier_cost_usd": round(usage.cost(args.classifier), 2),
+ }
+ print(json.dumps(summary, ensure_ascii=False))
+ out = Path(args.out or args.run.replace(".jsonl", "-taxonomy.jsonl"))
+ with out.open("w") as f:
+ f.write(json.dumps({"summary": summary}) + "\n")
+ for row in classified:
+ f.write(json.dumps(row, ensure_ascii=False) + "\n")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/realtime-data-indexing/Dockerfile b/benchmarks/realtime-data-indexing/Dockerfile
new file mode 100644
index 00000000..3d35aa92
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/Dockerfile
@@ -0,0 +1,11 @@
+# The serviette image for the benchmark, built from the repo checkout with
+# the released Pathway from PyPI. The build context is the repo root — see
+# docker-compose.yml; `docker compose build` (or the first `up`) is all the
+# setup there is.
+FROM python:3.12-slim
+
+COPY pyproject.toml README.md LICENSE /src/
+COPY serviette /src/serviette
+RUN pip install --no-cache-dir "/src[qdrant,local]"
+
+WORKDIR /bench
diff --git a/benchmarks/realtime-data-indexing/README.md b/benchmarks/realtime-data-indexing/README.md
new file mode 100644
index 00000000..70f212a1
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/README.md
@@ -0,0 +1,60 @@
+# Real-time data indexing benchmark
+
+Measures the two claims that matter for the serviette indexer:
+
+1. **Indexing speed** — wall-clock time to index a document collection end to
+ end (parse → chunk → embed → write to the vector DB).
+2. **Flat memory** — the indexer's memory consumption does **not** grow with
+ the size of the input collection (`only_metadata` sources keep paths, not
+ bytes, in the pipeline). The output is a memory-over-time plot and the
+ physical peak memory (PSS: shared pages counted once, not per process).
+
+Everything runs locally and costs nothing: embeddings are computed by a local
+sentence-transformers model (`static-retrieval-mrl-en-v1`,
+Matryoshka-truncated to 256 dims) — **no external API calls**.
+
+## Setup
+
+Three containers via docker-compose:
+
+- **qdrant** — the vector store. Chosen deliberately: HNSW builds
+ incrementally on upsert (fast indexing), it is designed for concurrent
+ search-while-writing, and the Pathway sink keys points internally (no user
+ primary key), so writes parallelize across Pathway workers.
+- **indexer** — `serviette indexer` over the dataset (static mode: the run ends
+ when the collection is fully indexed, so wall-clock = indexing time).
+- **server** — `serviette server`; used after indexing to replay the accuracy
+ questions through `/api/v1/retrieve`.
+
+Memory is sampled from `/proc/1/status` inside the indexer container every
+few seconds: `VmRSS` and `Pss` for the time series (PSS divides pages shared
+between workers — e.g. the PyTorch libraries — proportionally, so its sum is
+the honest physical footprint), `VmHWM` (kernel-tracked high-water
+mark) for the exact peak — no sampling artifacts.
+
+## Dataset
+
+`prepare_dataset.py` downloads Wikipedia parquet shards from Hugging Face
+(public, fast CDN) and writes one `.txt` file per article until the target
+size is reached. It also samples distinctive articles into `questions.json`;
+each question must retrieve its own article (top-k accuracy sanity check).
+
+## Running
+
+The serviette image is built from the repo checkout with the released
+Pathway from PyPI (`docker compose build`, run automatically on first use);
+`run_bench.py` pre-warms the local embedding-model cache, so the containers
+themselves never touch the network.
+
+```bash
+python prepare_dataset.py --size-mb 100 # also: 1000, 3000, 10000
+python run_bench.py --size 100mb
+```
+
+Outputs land in `results/`: `-memory.png` (memory over time),
+`-memory.csv`, `-summary.json` (duration, MB/min, chunk count,
+peak RSS/PSS, retrieval accuracy).
+
+To make the flat-memory point, run the same benchmark at increasing sizes
+(100mb → 1gb → 3gb → 10gb) and compare `peak_rss_mb` across summaries: the
+corpus grows 100×, the peak stays in the same band.
diff --git a/benchmarks/realtime-data-indexing/config.yaml b/benchmarks/realtime-data-indexing/config.yaml
new file mode 100644
index 00000000..7b929add
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/config.yaml
@@ -0,0 +1,55 @@
+# Benchmark config: LOCAL embeddings only (sentence-transformers, no API
+# calls, zero cost), Qdrant as the vector store.
+#
+# Qdrant is chosen deliberately for this scenario: HNSW builds incrementally
+# on upsert (fast indexing), it is built for concurrent search-while-writing,
+# and the Pathway sink keys points internally (no user primary key), so
+# writes parallelize across Pathway workers.
+
+pathway_license_key: ${PATHWAY_LICENSE_KEY}
+
+sources:
+ - type: fs
+ path: /data/docs
+ glob: "**/*.txt"
+ mode: streaming # the product mode: continuous watch, incremental
+ # commits; the bench detects completion by the chunk
+ # counter going stable
+
+vector_db:
+ type: qdrant
+ host: qdrant # docker-compose service name
+ rest_port: 6333
+ grpc_port: 6334
+ collection: bench_embeddings
+
+embedder:
+ type: sentence_transformer # LOCAL — no external API, free
+ # Static token embeddings (no transformer forward pass): ~100x faster on
+ # CPU than MiniLM while staying real semantic vectors — right trade-off for
+ # a throughput benchmark. Matryoshka-truncated to 256 dims.
+ model: sentence-transformers/static-retrieval-mrl-en-v1
+ truncate_dim: 256
+ batch_size: 2048
+
+splitter:
+ type: token_count
+ chunk_size: 512
+
+indexer:
+ workers: 8 # Pathway worker PROCESSES (via `pathway spawn`)
+ # Spill the non-deterministic UDF memo (parsed texts) to disk: in the
+ # container /tmp is overlayfs (real disk), not tmpfs.
+ udf_cache_directory: /tmp/udf-cache
+
+# Product default: persistence on. Lives inside the container (fresh each
+# run, since run_bench recreates containers), so runs stay cold-start honest
+# while exercising the same code path users get — including the disk-backed
+# parse cache under /persistence/runtime_calls.
+workdir_path: /tmp/serviette-workdir
+persistence:
+ enabled: true
+
+server:
+ host: 0.0.0.0
+ port: 8000
diff --git a/benchmarks/realtime-data-indexing/docker-compose.yml b/benchmarks/realtime-data-indexing/docker-compose.yml
new file mode 100644
index 00000000..002d5373
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/docker-compose.yml
@@ -0,0 +1,59 @@
+# Self-contained benchmark: Qdrant + serviette indexer + serviette server.
+#
+# The serviette image is built from the repo checkout (build context ../..)
+# with the released Pathway from PyPI — no external mounts or prebuilt
+# artifacts; `docker compose build` (or the first `up`) is all the setup.
+#
+# Parametrized by env vars:
+# BENCH_SIZE dataset folder under ./datasets (default 100mb)
+# BENCH_SERVER_PORT host port for the serviette server API (default 8300)
+# BENCH_QDRANT_PORT host port for Qdrant REST (readiness probes, default 8301)
+# BENCH_HF_CACHE host Hugging Face cache dir (default ~/.cache/huggingface)
+
+x-serviette: &serviette
+ build:
+ context: ../..
+ dockerfile: benchmarks/realtime-data-indexing/Dockerfile
+ image: serviette-bench
+ environment: &serviette-env
+ PATHWAY_LICENSE_KEY: ${PATHWAY_LICENSE_KEY:-}
+ HF_HOME: /hf-cache
+ # Model cache is pre-warmed by run_bench on the host; containers never
+ # touch the network (8 workers probing HF concurrently hit rate limits).
+ HF_HUB_OFFLINE: "1"
+ # Hard guarantee that nothing can spend OpenAI quota.
+ OPENAI_API_KEY: x
+ # Allocator experiment knobs (empty = library defaults).
+ _RJEM_MALLOC_CONF: ${BENCH_JEMALLOC_CONF:-}
+ MALLOC_ARENA_MAX: ${BENCH_MALLOC_ARENA_MAX:-}
+ volumes:
+ - ${BENCH_HF_CACHE:-~/.cache/huggingface}:/hf-cache:ro
+ - ${BENCH_DATA_ROOT:-./datasets}/${BENCH_SIZE:-100mb}/docs:/data/docs:ro
+ - ./config.yaml:/bench/config.yaml:ro
+
+services:
+ qdrant:
+ image: qdrant/qdrant:latest
+ ports:
+ - "127.0.0.1:${BENCH_QDRANT_PORT:-8301}:6333"
+
+ indexer:
+ <<: *serviette
+ # Worker processes come from `indexer.workers` in config.yaml (the
+ # entrypoint re-executes itself through `pathway spawn --processes N`).
+ command: ["python", "-m", "serviette.cli", "indexer", "--config", "/bench/config.yaml"]
+ environment:
+ <<: *serviette-env
+ # torch threads PER WORKER; without this each worker grabs all cores
+ # and 8 workers thrash (cores / workers is a good default).
+ OMP_NUM_THREADS: ${BENCH_OMP_THREADS:-12}
+ depends_on:
+ - qdrant
+
+ server:
+ <<: *serviette
+ command: ["python", "-m", "serviette.cli", "server", "--config", "/bench/config.yaml"]
+ ports:
+ - "127.0.0.1:${BENCH_SERVER_PORT:-8300}:8000"
+ depends_on:
+ - qdrant
diff --git a/benchmarks/realtime-data-indexing/prepare_dataset.py b/benchmarks/realtime-data-indexing/prepare_dataset.py
new file mode 100644
index 00000000..e85eb3e4
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/prepare_dataset.py
@@ -0,0 +1,114 @@
+#!/usr/bin/env python3
+"""Prepare a plain-text benchmark corpus of a given size.
+
+Downloads Wikipedia parquet shards from Hugging Face (public, no auth, fast
+CDN) and explodes articles into one ``.txt`` file each until the requested
+size is reached — so the same script scales from 100 MB to 10 GB by changing
+``--size-mb``. Also emits ``questions.json``: distinctive articles sampled
+across the corpus with queries that must retrieve exactly that file
+(retrieval-accuracy check for the benchmark).
+
+Usage:
+ python prepare_dataset.py --size-mb 100
+ # -> datasets/100mb/docs/*.txt + datasets/100mb/questions.json
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import re
+from pathlib import Path
+
+HF_REPO = "wikimedia/wikipedia"
+# Language cascade: English alone tops out around 20 GB of plain text, so
+# larger corpora continue into further languages. Accuracy questions are
+# sampled from the head of the corpus, i.e. always from English.
+HF_CONFIGS = ["20231101.en", "20231101.de", "20231101.fr", "20231101.es", "20231101.it"]
+# Shard the docs tree: N files per subdirectory, so multi-million-file
+# corpora don't create a single pathological directory.
+FILES_PER_DIR = 10_000
+# Sample a question article roughly every N articles, up to a cap.
+QUESTION_EVERY = 2000
+MAX_QUESTIONS = 20
+MIN_ARTICLE_CHARS = 2000
+
+
+def _slug(title: str) -> str:
+ return re.sub(r"[^A-Za-z0-9]+", "-", title).strip("-")[:80] or "article"
+
+
+def _first_sentence(text: str) -> str:
+ head = text[:500].replace("\n", " ")
+ match = re.search(r"[.!?]\s", head)
+ return head[: match.end()].strip() if match else head[:200].strip()
+
+
+def main() -> None:
+ parser = argparse.ArgumentParser(description=__doc__)
+ parser.add_argument("--size-mb", type=int, default=100)
+ parser.add_argument("--out", default=None, help="Output dir (default datasets/mb)")
+ args = parser.parse_args()
+
+ from huggingface_hub import HfApi, hf_hub_download
+
+ root = Path(__file__).parent
+ out = Path(args.out) if args.out else root / "datasets" / f"{args.size_mb}mb"
+ docs = out / "docs"
+ docs.mkdir(parents=True, exist_ok=True)
+
+ target_bytes = args.size_mb * 1024 * 1024
+ all_files = HfApi().list_repo_files(HF_REPO, repo_type="dataset")
+ shards = [
+ f
+ for cfg in HF_CONFIGS
+ for f in sorted(x for x in all_files if x.startswith(f"{cfg}/train-"))
+ ]
+
+ import pyarrow.parquet as pq
+
+ written = 0
+ article_index = 0
+ questions: list[dict] = []
+ for shard in shards:
+ if written >= target_bytes:
+ break
+ print(f"downloading {shard} ...", flush=True)
+ local = hf_hub_download(HF_REPO, shard, repo_type="dataset")
+ table = pq.read_table(local, columns=["title", "text"])
+ for title, text in zip(
+ table.column("title").to_pylist(), table.column("text").to_pylist()
+ ):
+ if written >= target_bytes:
+ break
+ if not text or len(text) < 200:
+ continue
+ subdir = docs / f"{article_index // FILES_PER_DIR:04d}"
+ if article_index % FILES_PER_DIR == 0:
+ subdir.mkdir(exist_ok=True)
+ name = f"{subdir.name}/{article_index % FILES_PER_DIR:04d}-{_slug(title)}.txt"
+ payload = f"{title}\n\n{text}"
+ (docs / name).write_text(payload, encoding="utf-8")
+ written += len(payload.encode("utf-8"))
+ if (
+ article_index % QUESTION_EVERY == 0
+ and len(questions) < MAX_QUESTIONS
+ and len(text) >= MIN_ARTICLE_CHARS
+ ):
+ questions.append(
+ {
+ "query": f"{title}: {_first_sentence(text)}",
+ "expected_file": name,
+ }
+ )
+ article_index += 1
+
+ (out / "questions.json").write_text(json.dumps(questions, indent=2))
+ print(
+ f"done: {article_index} files, {written / 1024 / 1024:.1f} MB, "
+ f"{len(questions)} accuracy questions -> {out}"
+ )
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/realtime-data-indexing/run_bench.py b/benchmarks/realtime-data-indexing/run_bench.py
new file mode 100644
index 00000000..e56478d7
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/run_bench.py
@@ -0,0 +1,403 @@
+#!/usr/bin/env python3
+"""Run the real-time indexing benchmark and produce the memory report.
+
+Flow: start Qdrant → start the serviette indexer (static run over the dataset)
+and the serviette server → sample the indexer's memory (VmRSS + kernel-tracked
+peak VmHWM from /proc/1/status inside the container) every few seconds until
+it finishes → replay the accuracy questions through the server's /api/v1
+retrieve endpoint → write a memory-over-time plot, a CSV, and a JSON summary
+into ./results.
+
+Usage:
+ python run_bench.py --size 100mb [--keep-up]
+"""
+
+from __future__ import annotations
+
+import argparse
+import json
+import subprocess
+import time
+from pathlib import Path
+
+import httpx
+
+ROOT = Path(__file__).parent
+SAMPLE_INTERVAL = 3.0
+# Streaming never exits; indexing is "done" when BOTH hold for this long:
+# the chunk counter stopped growing AND the indexer's CPU dropped to idle.
+# (Chunk commits are bursty — the embedding backlog of a large commit can
+# delay the next flush arbitrarily — but during that backlog the CPU burns
+# dozens of cores, so the combination is unambiguous.)
+STABLE_WINDOW = 180.0
+# Below this sustained CPU rate the indexer counts as idle. Must sit between
+# the streaming re-scan hum (the fs connector continuously re-stats every
+# file: ~5 cores per 240k files) and the embedding phase (50-90 cores).
+# A false "idle" is harmless while chunks are still growing — termination
+# requires BOTH conditions — so this errs high.
+IDLE_CORES = 30.0
+
+
+def _compose(*args: str, size: str, capture: bool = False) -> subprocess.CompletedProcess:
+ return subprocess.run(
+ ["docker", "compose", *args],
+ cwd=ROOT,
+ env={
+ **__import__("os").environ,
+ "BENCH_SIZE": size,
+ },
+ capture_output=capture,
+ text=True,
+ check=False,
+ )
+
+
+def _container_id(size: str, service: str) -> str:
+ out = _compose("ps", "-q", service, size=size, capture=True).stdout.strip()
+ if not out:
+ raise RuntimeError(f"container for {service} not found")
+ return out
+
+
+def _proc_status(container: str) -> dict[str, int] | None:
+ """VmRSS/VmHWM (kB) summed over ALL processes in the container.
+
+ With ``indexer.workers`` > 1 the container holds the spawn parent plus N
+ worker processes; the interesting number is their total footprint. The
+ summed VmHWM is an upper bound (individual peaks need not coincide); the
+ headline peak uses the sampled RSS total instead. Returns None once the
+ container has exited.
+ """
+
+ proc = subprocess.run(
+ ["docker", "exec", container, "sh", "-c",
+ "cat /proc/[0-9]*/status /proc/[0-9]*/smaps_rollup 2>/dev/null"],
+ capture_output=True,
+ text=True,
+ )
+ if proc.returncode != 0:
+ return None
+ # Pss divides shared pages (e.g. the torch libraries mapped by every
+ # worker) proportionally, so its sum is the honest physical footprint;
+ # the VmRSS sum counts each shared page once per process.
+ values = {"VmRSS": 0, "VmHWM": 0, "Pss": 0}
+ for line in proc.stdout.splitlines():
+ if line.startswith(("VmRSS:", "VmHWM:", "Pss:")):
+ key, rest = line.split(":", 1)
+ values[key] += int(rest.strip().split()[0])
+ return values
+
+
+def _proc_cpu_seconds(container: str) -> float | None:
+ """Total CPU seconds (utime+stime) over ALL processes in the container."""
+
+ proc = subprocess.run(
+ ["docker", "exec", container, "sh", "-c", "cat /proc/[0-9]*/stat"],
+ capture_output=True,
+ text=True,
+ )
+ if proc.returncode != 0:
+ return None
+ ticks = 0
+ for line in proc.stdout.splitlines():
+ fields = line.rsplit(")", 1)[-1].split()
+ if len(fields) > 12:
+ ticks += int(fields[11]) + int(fields[12]) # utime + stime
+ return ticks / 100.0 # USER_HZ is 100 on Linux
+
+
+def _embedder_description() -> str:
+ import yaml
+
+ embedder = yaml.safe_load((ROOT / "config.yaml").read_text()).get("embedder", {})
+ model = embedder.get("model", "?")
+ dims = embedder.get("truncate_dim")
+ return f"{model} (local{f', {dims} dims' if dims else ''})"
+
+
+def _wait_http(url: str, timeout: float, message: str) -> None:
+ deadline = time.monotonic() + timeout
+ while time.monotonic() < deadline:
+ try:
+ if httpx.get(url, timeout=5).status_code == 200:
+ return
+ except httpx.HTTPError:
+ pass
+ time.sleep(1)
+ raise TimeoutError(message)
+
+
+def _accuracy(
+ base: str, questions: list[dict], k: int
+) -> tuple[int, int, list[dict]]:
+ hits = 0
+ misses: list[dict] = []
+ for q in questions:
+ resp = httpx.post(
+ f"{base}/api/v1/retrieve", json={"query": q["query"], "k": k}, timeout=120
+ )
+ resp.raise_for_status()
+ results = resp.json()["results"]
+ # expected_file may carry a subdir ("0001/0042-Title.txt"); match on
+ # the full path suffix, not the basename, to survive sharded corpora.
+ paths = [r["metadata"].get("path", "") for r in results]
+ if any(p.endswith("/" + q["expected_file"]) for p in paths):
+ hits += 1
+ else:
+ misses.append(
+ {
+ "expected": q["expected_file"],
+ "query": q["query"][:120],
+ "got": [str(Path(p).parent.name + "/" + Path(p).name) for p in paths],
+ }
+ )
+ return hits, len(questions), misses
+
+
+_FREE_EMBEDDERS = {"sentence_transformer", "sentencetransformer", "mock"}
+
+
+def _assert_zero_cost(config_path: Path) -> None:
+ """Refuse to run a benchmark that could spend anyone's API money.
+
+ The guarantee is enforced, not assumed: only local embedders are allowed,
+ no LLM section may be present (the bench never composes answers), and the
+ OPENAI_API_KEY passed to containers must be the literal dummy "x" from
+ docker-compose. Editing any of these fails loudly here, before a single
+ container starts.
+ """
+
+ import yaml
+
+ config = yaml.safe_load(config_path.read_text())
+ embedder = (config.get("embedder") or {}).get("type", "")
+ if embedder not in _FREE_EMBEDDERS:
+ raise SystemExit(
+ f"zero-cost guard: benchmark config uses embedder {embedder!r}; "
+ f"only local embedders {sorted(_FREE_EMBEDDERS)} are allowed"
+ )
+ if config.get("llm"):
+ raise SystemExit(
+ "zero-cost guard: benchmark config must not define an 'llm' "
+ "section (the bench only measures indexing and /retrieve)"
+ )
+ compose = (config_path.parent / "docker-compose.yml").read_text()
+ if "OPENAI_API_KEY: x" not in compose:
+ raise SystemExit(
+ "zero-cost guard: docker-compose must hard-pin OPENAI_API_KEY "
+ "to the dummy value 'x' so no real key can leak into containers"
+ )
+
+
+def main() -> None:
+ parser = argparse.ArgumentParser(description=__doc__)
+ parser.add_argument("--size", default="100mb", help="datasets/ to index")
+ parser.add_argument("--top-k", type=int, default=5)
+ parser.add_argument("--server-port", type=int, default=8300)
+ parser.add_argument("--qdrant-port", type=int, default=8301)
+ parser.add_argument("--keep-up", action="store_true", help="don't docker compose down")
+ args = parser.parse_args()
+
+ import os as _os
+
+ _assert_zero_cost(ROOT / "config.yaml")
+ data_root = Path(_os.environ.get("BENCH_DATA_ROOT", ROOT / "datasets"))
+ dataset = data_root / args.size
+ docs_count = sum(1 for _ in (dataset / "docs").rglob("*.txt"))
+ questions = json.loads((dataset / "questions.json").read_text())
+ results_dir = ROOT / "results"
+ results_dir.mkdir(exist_ok=True)
+
+ import os
+
+ os.environ["BENCH_SERVER_PORT"] = str(args.server_port)
+ os.environ["BENCH_QDRANT_PORT"] = str(args.qdrant_port)
+
+ print(f"== dataset {args.size}: {docs_count} files, {len(questions)} questions")
+ # Always start from a clean slate — leftovers from an interrupted run
+ # (a pre-filled Qdrant, an old indexer) would silently corrupt every
+ # measurement.
+ _compose("down", "-v", size=args.size)
+
+ # Pre-warm the HF model cache on the host: containers run HF_HUB_OFFLINE.
+ import yaml as _yaml
+
+ model = _yaml.safe_load((ROOT / "config.yaml").read_text())["embedder"].get(
+ "model"
+ )
+ if model:
+ # Filesystem check first: lock-free (old runs left root-owned lock
+ # files in the mounted cache), and offline containers only need the
+ # snapshot to exist.
+ snapshots = (
+ Path.home()
+ / ".cache/huggingface/hub"
+ / ("models--" + model.replace("/", "--"))
+ / "snapshots"
+ )
+ if not (snapshots.exists() and any(snapshots.iterdir())):
+ from huggingface_hub import snapshot_download
+
+ print(f"== pre-warming model cache: {model}")
+ snapshot_download(model)
+
+ _compose("up", "-d", "qdrant", size=args.size)
+ _wait_http(
+ f"http://127.0.0.1:{args.qdrant_port}/readyz", 120, "qdrant not ready"
+ )
+
+ started = time.monotonic()
+ _compose("up", "-d", "indexer", "server", size=args.size)
+ indexer = _container_id(args.size, "indexer")
+ base = f"http://127.0.0.1:{args.server_port}"
+ _wait_http(f"{base}/api/v1/health", 180, "server not ready")
+
+ def _chunks() -> int:
+ try:
+ value = httpx.get(f"{base}/api/v1/stats", timeout=10).json().get("chunks")
+ return int(value) if value is not None else 0
+ except (httpx.HTTPError, ValueError):
+ return 0
+
+ # The indexer runs in its product mode — STREAMING — and never exits, so
+ # "indexing finished" is detected by the chunk counter going stable: it
+ # grew at least once and has not changed for STABLE_WINDOW seconds.
+ # Indexing time = the moment of the last observed increase.
+ # The CSV is appended live, so an interrupted run keeps its memory curve.
+ csv_path = results_dir / f"{args.size}-memory.csv"
+ csv_path.write_text("elapsed_s,rss_mb,hwm_mb,pss_mb,chunks\n")
+
+ samples: list[tuple[float, int, int, int, int]] = [] # (s, rss, hwm, pss, chunks)
+ last_count = 0
+ last_change = started
+ last_busy = started
+ prev_cpu: float | None = None
+ prev_time = started
+ cpu_seconds: float | None = None
+ while True:
+ status = _proc_status(indexer)
+ if status is None:
+ _compose("logs", "--tail", "50", "indexer", size=args.size)
+ raise SystemExit("indexer container exited unexpectedly")
+ now = time.monotonic()
+ count = _chunks()
+ if count > last_count:
+ last_count = count
+ last_change = now
+ cpu = _proc_cpu_seconds(indexer)
+ if cpu is not None:
+ if prev_cpu is not None and now > prev_time:
+ if (cpu - prev_cpu) / (now - prev_time) >= IDLE_CORES:
+ last_busy = now
+ prev_cpu, prev_time, cpu_seconds = cpu, now, cpu
+ elapsed = now - started
+ sample = (
+ elapsed,
+ status.get("VmRSS", 0),
+ status.get("VmHWM", 0),
+ status.get("Pss", 0),
+ last_count,
+ )
+ samples.append(sample)
+ with csv_path.open("a") as fh:
+ fh.write(
+ f"{sample[0]:.1f},{sample[1] / 1024:.1f},{sample[2] / 1024:.1f},"
+ f"{sample[3] / 1024:.1f},{sample[4]}\n"
+ )
+ print(
+ f"\r t={elapsed:7.0f}s rss={status.get('VmRSS', 0) / 1024:7.1f} MB "
+ f"peak={status.get('VmHWM', 0) / 1024:7.1f} MB chunks={last_count}",
+ end="",
+ flush=True,
+ )
+ if (
+ # Every document yields at least one chunk, so completion is
+ # impossible before the counter reaches the document count —
+ # this cleanly excludes the low-CPU initial-scan phase.
+ last_count >= docs_count
+ and now - last_change >= STABLE_WINDOW
+ and now - last_busy >= STABLE_WINDOW
+ ):
+ break
+ time.sleep(SAMPLE_INTERVAL)
+ print()
+ duration = last_change - started
+
+ # Vector-DB footprint: on-disk storage inside the qdrant container.
+ qdrant = _container_id(args.size, "qdrant")
+ du = subprocess.run(
+ ["docker", "exec", qdrant, "du", "-sb", "/qdrant/storage"],
+ capture_output=True,
+ text=True,
+ )
+ db_bytes = int(du.stdout.split()[0]) if du.returncode == 0 and du.stdout else None
+
+ stats = httpx.get(f"{base}/api/v1/stats", timeout=60).json()
+ hits, total, misses = _accuracy(base, questions, args.top_k)
+
+ # Peak = highest sampled TOTAL RSS across the container's processes (the
+ # summed VmHWM in the CSV is only an upper bound for multi-process runs).
+ peak_mb = max(s[1] for s in samples) / 1024 if samples else 0.0
+ peak_pss_mb = max(s[3] for s in samples) / 1024 if samples else 0.0
+ size_mb = sum(
+ f.stat().st_size for f in (dataset / "docs").rglob("*.txt")
+ ) / 1024 / 1024
+ summary = {
+ "dataset": args.size,
+ "corpus_mb": round(size_mb, 1),
+ "documents": docs_count,
+ "chunks": stats.get("chunks"),
+ "indexing_seconds": round(duration, 1),
+ "throughput_mb_per_min": round(size_mb / (duration / 60), 2),
+ "peak_rss_mb": round(peak_mb, 1),
+ # Honest physical peak: shared pages divided among processes.
+ "peak_pss_mb": round(peak_pss_mb, 1),
+ "indexer_cpu_seconds": round(cpu_seconds, 1) if cpu_seconds else None,
+ "avg_parallelism": round(cpu_seconds / duration, 1) if cpu_seconds else None,
+ "vector_db_disk_mb": round(db_bytes / 1024 / 1024, 1) if db_bytes else None,
+ "vector_db_mb_per_corpus_mb": (
+ round(db_bytes / 1024 / 1024 / size_mb, 2) if db_bytes else None
+ ),
+ "retrieval_accuracy": f"{hits}/{total}",
+ "embedder": _embedder_description(),
+ # Standard text page ≈ 2000 characters (≈ bytes for English text).
+ "approx_text_pages": int(size_mb * 1024 * 1024 / 2000),
+ # Which questions missed top-k, with what came back instead.
+ "accuracy_misses": misses,
+ }
+ (results_dir / f"{args.size}-summary.json").write_text(json.dumps(summary, indent=2))
+
+ import matplotlib
+
+ matplotlib.use("Agg")
+ import matplotlib.pyplot as plt
+
+ fig, ax = plt.subplots(figsize=(9, 4.5))
+ minutes = [s[0] / 60 for s in samples]
+ ax.plot(minutes, [s[1] / 1024 for s in samples], label="indexer RSS", linewidth=1.8)
+ ax.axhline(peak_mb, linestyle="--", linewidth=1, alpha=0.6, label=f"peak {peak_mb:.0f} MB")
+ ax.set_xlabel("minutes since start")
+ ax.set_ylabel("memory, MB")
+ ax.set_ylim(bottom=0)
+ ax2 = ax.twinx()
+ ax2.plot(minutes, [s[4] for s in samples], color="tab:green", alpha=0.6, linewidth=1.4, label="chunks in DB")
+ ax2.set_ylabel("chunks indexed")
+ ax2.set_ylim(bottom=0)
+ ax.set_title(f"serviette indexer — {args.size} corpus ({docs_count} docs, streaming)")
+ lines, labels = ax.get_legend_handles_labels()
+ lines2, labels2 = ax2.get_legend_handles_labels()
+ ax.legend(lines + lines2, labels + labels2, loc="center right")
+ ax.grid(alpha=0.3)
+ fig.tight_layout()
+ plot_path = results_dir / f"{args.size}-memory.png"
+ fig.savefig(plot_path, dpi=130)
+
+ print(json.dumps(summary, indent=2))
+ print(f"plot: {plot_path}\ncsv: {csv_path}")
+
+ if not args.keep_up:
+ _compose("down", "-v", size=args.size)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/benchmarks/realtime-data-indexing/tests_bench_guard.py b/benchmarks/realtime-data-indexing/tests_bench_guard.py
new file mode 100644
index 00000000..5f0a297f
--- /dev/null
+++ b/benchmarks/realtime-data-indexing/tests_bench_guard.py
@@ -0,0 +1,25 @@
+"""Fast check for the zero-cost guard (run: python tests_bench_guard.py)."""
+import sys
+from pathlib import Path
+
+sys.path.insert(0, str(Path(__file__).parent))
+from run_bench import _assert_zero_cost
+
+root = Path(__file__).parent
+_assert_zero_cost(root / "config.yaml") # the real config must pass
+
+bad = root / "results" / "_guard_check.yaml"
+bad.parent.mkdir(exist_ok=True)
+bad.write_text("embedder:\n type: openai\n")
+try:
+ import shutil
+ shutil.copy(root / "docker-compose.yml", bad.parent / "docker-compose.yml")
+ _assert_zero_cost(bad)
+except SystemExit as exc:
+ assert "zero-cost guard" in str(exc)
+ print("guard OK: real config passes, paid embedder rejected")
+else:
+ raise AssertionError("guard failed to reject a paid embedder")
+finally:
+ bad.unlink(missing_ok=True)
+ (bad.parent / "docker-compose.yml").unlink(missing_ok=True)
diff --git a/cookbooks/self-rag-agents/pathway_deploy_langgraph_agents.ipynb b/cookbooks/self-rag-agents/pathway_deploy_langgraph_agents.ipynb
deleted file mode 100644
index 712b652f..00000000
--- a/cookbooks/self-rag-agents/pathway_deploy_langgraph_agents.ipynb
+++ /dev/null
@@ -1,1054 +0,0 @@
-{
- "cells": [
- {
- "cell_type": "markdown",
- "id": "d58d3552-9168-4f0f-8a79-4dbaa4a01bbf",
- "metadata": {
- "tags": []
- },
- "source": [
- "> The following cookbook is an adaption of the original [LangGraph cookbook](https://github.com/langchain-ai/langgraph/blob/e3ca7bb3e9d34b09633852f4d08d55f6dcd4364b/examples/rag/langgraph_self_rag.ipynb)\n",
- "\n"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "b3e94de1-ca3d-4956-b212-4a558b68062a",
- "metadata": {},
- "source": [
- "# Power and Deploy LangGraph Agents with Pathway: A Complete Guide\n",
- "This notebook demonstrates how to use Pathway to power and deploy LangGraph Agents.\n",
- "\n",
- "In this notebook, you will learn:\n",
- "- How to build a Pathway RAG app that indexes documents from your data sources\n",
- "- How to create a Hybrid Index that is powered by semantic search and BM25 index\n",
- "- How to use the Pathway LangChain Retriever in a LangGraph Agent\n",
- "- How to use Pathway to serve LangGraph Agents"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "d27aa0d3-9b11-4678-8a83-b3865b26f30c",
- "metadata": {},
- "source": [
- "# Setup\n",
- "\n",
- "Install the required packages and set your OpenAI API key. \n",
- "OpenAI is used for embeddings during the indexing stage and to power the LangGraph agent."
- ]
- },
- {
- "cell_type": "markdown",
- "id": "9e055de9-723f-44e3-ad39-70cc5f8932bf",
- "metadata": {},
- "source": [
- "Magic library is used for detecting file types in the `UnstructuredParser` module.\n",
- "\n",
- "If you are running this notebook on **MacOS**, you can install it with:\n",
- "> `brew install libmagic`\n",
- "\n",
- "If you are running the notebook on **colab** or any **linux** environment, you can install it with:\n",
- "> `apt-get install libmagic1`"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "209efe9f-b9d3-4760-8863-0a6052617ebd",
- "metadata": {},
- "outputs": [],
- "source": [
- "!pip install -U \"pathway[all]\""
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "b44f689e-0a62-4bbd-94e8-5bf31ece9cd9",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "!pip install -U langgraph langchain-community langchainhub langchain-openai"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "3ff9da9f-66b8-4675-8c45-afa10e891462",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import os\n",
- "\n",
- "import json\n",
- "from typing import Iterable, Literal, List\n",
- "from pydantic import BaseModel, Field\n",
- "\n",
- "# needed for the OpenAI embedder and the LLM we will use below, you can change the embedding provider, see the documentation:\n",
- "# https://pathway.com/developers/api-docs/pathway-xpacks-llm/embedders\n",
- "os.environ[\"OPENAI_API_KEY\"] = \"sk-...\""
- ]
- },
- {
- "cell_type": "markdown",
- "id": "571d4836-4d08-4ee5-97fa-37132ccc8ef9",
- "metadata": {},
- "source": [
- "Lets define a `DATA_PATH` folder that will store the text files/documents for indexing."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "54979252-13d3-4b94-b2ad-ec7b012aa320",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# folder that we will gather our docs in\n",
- "DATA_PATH = \"./data\"\n",
- "\n",
- "os.makedirs(DATA_PATH, exist_ok=True)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "55c2fb67-c562-47f7-a08e-6a673b4b612b",
- "metadata": {},
- "source": [
- "## Load & save a webpage\n",
- "\n",
- "Define utility functions to read content from a webpage and save it locally into `DATA_PATH`.\n",
- " 1. `load_page_content`: Reads the raw text from a webpage using using a `WebBaseLoader` from `langchain_community.document_loaders`.\n",
- " 2. `ingest_webpage`: Saves the loaded content as a text file into the `DATA_PATH`. "
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "64538684-5b2b-460a-b3a5-1fe737fd8269",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import re\n",
- "from urllib.parse import urlparse\n",
- "from langchain_community.document_loaders import WebBaseLoader\n",
- "\n",
- "\n",
- "def load_page_content(url: str) -> str:\n",
- " \"\"\"Load web page content with Langchain utilities.\"\"\"\n",
- " return WebBaseLoader(url).load()[0].page_content\n",
- "\n",
- "\n",
- "def ingest_webpage(url: str) -> None:\n",
- " \"\"\"Save a webpage to local `DATA_PATH` folder.\"\"\"\n",
- " text_content = load_page_content(url)\n",
- "\n",
- " parsed_url = urlparse(url)\n",
- " file_name = parsed_url.hostname + parsed_url.path.replace(\"/\", \"_\") + \".txt\"\n",
- "\n",
- " with open(os.path.join(DATA_PATH, file_name), \"w\", encoding=\"utf-8\") as f:\n",
- " f.write(text_content)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "5bf15463-7da1-4d04-9f6d-423975e377cb",
- "metadata": {
- "tags": []
- },
- "source": [
- "Download the Self-RAG paper"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "fff7b382-2e25-415b-a3ee-06df976b3dbd",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "ingest_webpage(\"https://arxiv.org/html/2310.11511\")"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "62376b16-e5bc-463d-bf84-bec69a7c2035",
- "metadata": {
- "tags": []
- },
- "source": [
- "# Build the Pathway indexing pipeline\n",
- "\n",
- "Set up Pathway to read and index the documents saved under the `DATA_PATH`.\n",
- "\n",
- "\n",
- "1. [Connectors](https://pathway.com/developers/user-guide/connect/pathway-connectors): Use Pathway’s file reader to ingest all text files under the `DATA_PATH`.\n",
- "2. [Parsers](https://pathway.com/developers/api-docs/pathway-xpacks-llm/parsers): Utilize the UnstructuredParser to parse the documents. This parser supports multiple file types, including PDF, DOCX, and PPTX.\n",
- "3. [Text Splitters](https://pathway.com/developers/api-docs/pathway-xpacks-llm/splitters): Split the document content into chunks.\n",
- "4. [Embedders](https://pathway.com/developers/api-docs/pathway-xpacks-llm/embedders): Use OpenAI API for embeddings."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "27c3d42a-30e1-47f8-bf3c-bd44d4a490f0",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# host and port of the RAG app\n",
- "pathway_host: str = \"0.0.0.0\"\n",
- "pathway_port: int = 8000"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "094ec4e1-e972-441b-9c47-ff0ce3c8d2ff",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import pathway as pw\n",
- "from pathway.stdlib.indexing import BruteForceKnnFactory, HybridIndexFactory\n",
- "from pathway.stdlib.indexing.bm25 import TantivyBM25Factory\n",
- "from pathway.udfs import DiskCache\n",
- "from pathway.xpacks.llm import embedders, llms, parsers, splitters\n",
- "from pathway.xpacks.llm.document_store import DocumentStore\n",
- "from pathway.xpacks.llm.question_answering import BaseRAGQuestionAnswerer, RAGClient\n",
- "\n",
- "\n",
- "# read the text files under the data folder, we can also read from Google Drive, Sharepoint, etc.\n",
- "# See connectors documentation: https://pathway.com/developers/user-guide/connect/pathway-connectors to learn more\n",
- "folder = pw.io.fs.read(\n",
- " path=f\"{DATA_PATH}/*.txt\",\n",
- " format=\"binary\",\n",
- " with_metadata=True,\n",
- ")\n",
- "\n",
- "# list of data sources to be indexed\n",
- "sources = [folder]\n",
- "\n",
- "# define the document processing steps\n",
- "parser = parsers.UnstructuredParser()\n",
- "\n",
- "text_splitter = splitters.TokenCountSplitter(min_tokens=150, max_tokens=450)\n",
- "\n",
- "embedder = embedders.OpenAIEmbedder(cache_strategy=DiskCache())"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "d3426ef8-90ee-4023-8094-5ce007d64b0e",
- "metadata": {},
- "source": [
- "Hybrid index combines semantic search and keyword based BM25 search.\n",
- "\n",
- "[`HybridIndexFactory`](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.HybridIndexFactory) combines different indexes to build an hybrid index:\n",
- " 1. [BM25](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.TantivyBM25) (via TantivyBM25Factory) → Keyword based BM25 search.\n",
- " 2. [BruteForceKnn](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnn) → Vector-based semantic search"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "a3f7c59b-925b-4ef3-88a8-89749479925e",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "index = HybridIndexFactory(\n",
- " [\n",
- " TantivyBM25Factory(),\n",
- " BruteForceKnnFactory(embedder=embedder),\n",
- " ]\n",
- ")"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "8b55a446-cf97-4d47-b1ca-374bcf0e8a7b",
- "metadata": {},
- "source": [
- "[DocumentStore](https://pathway.com/developers/api-docs/pathway-xpacks-llm/document_store#pathway.xpacks.llm.document_store.DocumentStore) manages document ingestion, parsing, splitting, and indexing.\n",
- "\n",
- "[BaseRAGQuestionAnswerer](https://pathway.com/developers/api-docs/pathway-xpacks-llm/question_answering#pathway.xpacks.llm.question_answering.BaseRAGQuestionAnswerer) creates a Pathway “RAG” application that:\n",
- " * Indexes the documents (via `document_store`)\n",
- " * Exposes a standard question-answering interface\n",
- " * Enables us to create endpoint for the agent with Pathway."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "7db0ab59-a641-43cc-901b-cc2713f03a99",
- "metadata": {},
- "outputs": [],
- "source": [
- "llm = llms.OpenAIChat(model=\"gpt-4o-mini\", cache_strategy=DiskCache())\n",
- "\n",
- "document_store = DocumentStore(\n",
- " docs=sources, parser=parser, splitter=text_splitter, retriever_factory=index\n",
- ")\n",
- "\n",
- "# create the RAG app that will power the index, and serve the agent endpoint\n",
- "rag_app = BaseRAGQuestionAnswerer(\n",
- " llm=llm,\n",
- " indexer=document_store,\n",
- ")"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "a027e277-fba8-4198-863b-2168ae6f8505",
- "metadata": {},
- "source": [
- "# Create the LangGraph agent"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "cf15141f-9612-4d0d-a21b-11bd8530686a",
- "metadata": {},
- "source": [
- "### Create the Langchain Retriever\n",
- "\n",
- "You can now query Pathway and access up-to-date documents for your RAG applications from LangChain using [PathwayVectorClient](https://api.python.langchain.com/en/latest/vectorstores/langchain_community.vectorstores.pathway.PathwayVectorClient.html)\n",
- "\n",
- "The Langchain Retriever is a wrapper around the Pathway client, you will use it in `retrieve` part stage of the Agent"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "fefffab6-d5a3-4925-a52d-5a5c574421ea",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langchain_community.vectorstores import PathwayVectorClient"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "51d365aa-5526-4ec8-932d-e65e83ee355d",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "vectorstore_client = PathwayVectorClient(pathway_host, pathway_port)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "59624377-8481-4407-8ee3-0f014bdff30e",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# this will not be able to fetch data until the RAG app is running\n",
- "retriever = vectorstore_client.as_retriever()"
- ]
- },
- {
- "attachments": {
- "76895b7a-fcc5-4758-9fbb-510b17fdeda4.png": {
- "image/png": "iVBORw0KGgoAAAANSUhEUgAABsYAAAKICAIAAABMgdh8AAAAAXNSR0IArs4c6QAAAERlWElmTU0AKgAAAAgAAYdpAAQAAAABAAAAGgAAAAAAA6ABAAMAAAABAAEAAKACAAQAAAABAAAGxqADAAQAAAABAAACiAAAAADBOIDEAABAAElEQVR4Aey9B5xV1bm4DQxTmBlgBhiK9CYgKNJVlKLYwF6iRsUbY9TE/BNjYnI/Y270Jrm5JiYmanI1aoottoi9g2CHoGIBlN57G2aGqcD3DAu3xxkY5kxjYJ79m9/JPnuvvcqz9znxPLzvWo137tzZyE0CEpCABCQgAQlIQAISkIAEJCABCUhAAhKQQOUINKlcMUtJQAISkIAEJCABCUhAAhKQgAQkIAEJSEACEigloFL0OZCABCQgAQlIQAISkIAEJCABCUhAAhKQgATiIKBSjAOWRSUgAQlIQAISkIAEJCABCUhAAhKQgAQkIAGVos+ABCQgAQlIQAISkIAEJCABCUhAAhKQgAQkEAcBlWIcsCwqAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJqBR9BiQgAQlIQAISkIAEJCABCUhAAhKQgAQkIIE4CKgU44BlUQlIQAISkIAEJCABCUhAAhKQgAQkIAEJSECl6DMgAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJxEFApRgHLItKQAISkIAEJCABCUhAAhKQgAQkIAEJSEACKkWfAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJSCAOAirFOGBZVAISkIAEJCABCUhAAhKQgAQkIAEJSEACElAp+gxIQAISkIAEJCABCUhAAhKQgAQkIAEJSEACcRBQKcYBy6ISkIAEJCABCUhAAhKQgAQkIAEJSEACEpCAStFnQAISkIAEJCABCUhAAhKQgAQkIAEJSEACEoiDgEoxDlgWlYAEJCABCUhAAhKQgAQkIAEJSEACEpCABFSKPgMSkIAEJCABCUhAAhKQgAQkIAEJSEACEpBAHARUinHAsqgEJCABCUhAAhKQgAQkIAEJSEACEpCABCSgUvQZkIAEJCABCUhAAhKQgAQkIAEJSEACEpCABOIgoFKMA5ZFJSABCUhAAhKQgAQkIAEJSEACEpCABCQgAZWiz4AEJCABCUhAAhKQgAQkIAEJSEACEpCABCQQBwGVYhywLCoBCUhAAhKQgAQkIAEJSEACEpCABCQgAQmoFH0GJCABCUhAAhKQgAQkIAEJSEACEpCABCQggTgIqBTjgGVRCUhAAhKQgAQkIAEJSEACEpCABCQgAQlIQKXoMyABCUhAAhKQgAQkIAEJSEACEpCABCQgAQnEQUClGAcsi0pAAhKQgAQkIAEJSEACEpCABCQgAQlIQAIqRZ8BCUhAAhKQgAQkIAEJSEACEpCABCQgAQlIIA4CKsU4YFlUAhKQgAQkIAEJSEACEpCABCQgAQlIQAISUCn6DEhAAhKQgAQkIAEJSEACEpCABCQgAQlIQAJxEFApxgHLohKQgAQkIAEJSEACEpCABCQgAQlIQAISkIBK0WdAAhKQgAQkIAEJSEACEpCABCQgAQlIQAISiIOASjEOWBaVgAQkIAEJSEACEpCABCQgAQlIQAISkIAEVIo+AxKQgAQkIAEJSEACEpCABCQgAQlIQAISkEAcBFSKccCyqAQkIAEJSEACEpCABCQgAQlIQAISkIAEJKBS9BmQgAQkIAEJSEACEpCABCQgAQlIQAISkIAE4iCgUowDlkUlIAEJSEACEpCABCQgAQlIQAISkIAEJCABlaLPgAQkIAEJSEACEpCABCQgAQlIQAISkIAEJBAHAZViHLAsKgEJSEACEpCABCQgAQlIQAISkIAEJCABCagUfQYkIAEJSEACEpCABCQgAQlIQAISkIAEJCCBOAioFOOAZVEJSEACEpCABCQgAQlIQAISkIAEJCABCUhApegzIAEJSEACEpCABCQgAQlIQAISkIAEJCABCcRBQKUYByyLSkACEpCABCQgAQlIQAISkIAEJCABCUhAAipFnwEJSEACEpCABCQgAQlIQAISkIAEJCABCUggDgIqxThgWVQCEpCABCQgAQlIQAISkIAEJCABCUhAAhJQKfoMSEACEpCABCQgAQlIQAISkIAEJCABCUhAAnEQUCnGAcuiEpCABCQgAQlIQAISkIAEJCABCUhAAhKQgErRZ0ACEpCABCQgAQlIQAISkIAEJCABCUhAAhKIg4BKMQ5YFpWABCQgAQlIQAISkIAEJCABCUhAAhKQgARUij4DEpCABCQgAQlIQAISkIAEJCABCUhAAhKQQBwEVIpxwLKoBCQgAQlIQAISkIAEJCABCUhAAhKQgAQkoFL0GZCABCQgAQlIQAISkIAEJCABCUhAAhKQgATiIKBSjAOWRSUgAQlIQAISkIAEJCABCUhAAhKQgAQkIAGVos+ABCQgAQlIQAISkIAEJCABCUhAAhKQgAQkEAcBlWIcsCwqAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJqBR9BiQgAQlIQAISkIAEJCABCUhAAhKQgAQkIIE4CKgU44BlUQlIQAISkIAEJCABCUhAAhKQgAQkIAEJSKCpCCQgAQlIQAISkIAEJCABCUhAAhKQgAQkcMAR2LZtW1FRUUpKSnJycuPGjQ+4/h/QHVYpHtC3z85LQAISkIAEJCABCUhAAhKQgAQkIIGGSGDjxo3vvvvu0qVLe/fuPXTo0FatWjVECvtvzCrF/cfeliUgAQlIQAISkIAEJCABCUhAAhKQgASqRODhhx++//77161bl5aW9utf//r0009v0sT5/aqEskoXybpK2LxIAhKQgAQkIAEJSEACEpCABCQgAQlIYD8RKCwsfPPNN/GJtJ+Xl5ednU0G9H7qSwNtVqXYQG+8w5aABCQgAQlIQAISkIAEJCABCUhAAgcogfnz5+fm5kadZzrFxMTE6K07dUDAxOc6gGwTEpCABCQgAQlIQAISkIAEJCABCdQuge3bt5eUlLBGR9OmTcsnwHKWbefOnYin8mdrt2f1tfYdu7aEhIQDcWGTDz74YPPmzQEt/U9KSmIg9ZX0wdkvleLBeV8dlQQkIAEJSEACEpCABCQgAQlIoOEQKC4unjdv3pQpU1BLo0eP7tu3b5mxf/rppzNmzCBbdsKECV26dFE/YVfnzp27du3aI488snnz5kEsHihukdv99ttvszxLuMsZGRlEKZa5476tbQIqxdombP0SkIAEJCABCUhAAhKQgAQkIAEJ1C4BjBgy8a9//WtOTg7xa3fddVesHSM+8Te/+Q1K8ZBDDjnhhBOMUuRmrF69+rHHHmOFEwTrMbu2wYMHZ2VlwS0WXe3etqrW/s4773z++ecI4lBBenp6cnJyVSvzuioSSLjpppuqeKmXSUACEpCABCQgAQlIQAISkIAEJCCBekAAC0ZGM69vvfUWsoxAxXbt2kX9Yh2Phx56CNv4ve99b8SIEUa0QYbIxM6dO7du3Xr9+vVvvPHGU0899fTTTwdP17JlSyRdRK++7ZDejiD+5JNP2Al9a9++/fHHH48brW9dPbj7o1I8uO+vo5OABCQgAQlIQAISkIAEJCABCTQIAkQpohHxYtu2bcMennrqqWHYZPj+13/918KFC3v27HnNNdd06NCh/kfh1c0Ny8zMJDJx/Pjxo0aNatWqFasnk0386quvohfJiQYjCcWYx7rpTOVbeeKJJ+hhNJEiFyITx4wZ07Fjx8pXYsnqEzDxufoMrUECEpCABCQgAQlIQAISkIAEJCCB/UwAUdi2bdsrr7zylltuee2115hasXfv3hx87733mEixqKjo0ksvxTnG+sTFixcT1Thr1ixm5SNeb8iQIccddxyxe7EjIRRu+fLl7777LmFxmzZt2rp1K44S14bGmjhxYqdOnWILH1j7oCC0k23QoEEDBgxgODNnziRikQzxZ5555sUXX8Q5YhvZRo4cSehifRjdypUrSW9fs2ZNbGeaNWvGKGKPVHOftaRx0EuXLuUJIWueu4yyDFnh1az5YLpcpXgw3U3HIgEJSEACEpCABCQgAQlIQAISaLgEUlNTzzjjjAceeIBVR+65557//d//ZY7FMMFi//79UWOx+bwvv/zy3XffTaova32w9DETLL700ktYRaTkscceGyASqffcc8/dfvvtxMThFsMSyZyiMErx4osvPjhYQ4mN+M1TTjmFDGIEK+GKyNZ///vfTz755AsvvEBmMbnkYMEtsqD2/ho1/O+8804MLzuxfYjVxLHH49rHFGdnZ5MjP3nyZOZqZKLG0jXCt2+nEm43Vvrb3/42iOKqc4+FsdsfffTRs88+y/yPP/nJT8rwZGhbtmzJy8tr06YNGfoVDG3JkiX0lqoIL+Uqynfr1o0HmMjTtLS0PTZdswf323NQs8OwNglIQAISkIAEJCABCUhAAhKQgAQaOAH8C2Llm9/85i9+8QtU4FVXXYWdIfIOaUgIHjGMkaAhBg3ziI5B6yDLcDFENRKuSDQiIWldu3YNsYrvv/8+xYiMw0Viavr164e1xD2hF7mQtg4m4MAheZyNMZ599tnoRaZZRFqhF4lbZDLKf/3rXySPs5TL0Ucfjbqq2cDAypBE9k2bNg3dRuFzzjknPz9/+vTphI6i/KI7u8d6uF+LFi0iXpUnoVevXrhRFGooyd1EHPOQTJ06lcDMgoICquW1TD3Lli3jeJmDGzZsWLBgQYsWLXr06FHJCTqpmYZ++tOf0ijBlRdccAH9CdVSP54RA85DiyJEC7IY964g0VGE0JZpmjWIkObcGgQl3pNRMCLs5P33389T+p3vfIfbVDGTMhVW4a1KsQrQvEQCEpCABCQgAQlIQAISkIAEJCCB+kgA0zdhwgTECg4IG0iGLPMqDhw4EIuEwYl6jHD87LPPME3XXXfdmWeeiTFE8bBO9KOPPkpo3lFHHYVSRNMgE5lVkJzfs8466+qrr6Zy7BWVcApfg3qLKoxrh74hwuK6pGqFg2vjlY0a6DM7ZV5j34az0RGcKWIR5UqH8XH4uw8//BBujzzyCN5q+PDhuMXDDjsMLFXrXlxXYYFvvfVWbijwCRH92te+hu7kZlFJ6HaoDTGHaCOokLhU7iNzQXKXibgkvJEauJZVv1nA58ILLwzl0YIIaEaHqSTfeY9dQhei9phuMvbsK6+8wgOGicb9XXbZZeeff/4+nwf0HyrwxhtvpFGqgnO0iBCp+vfeey+CkhDREIPJWfpJHvppp532jW98A+sdtc7o/va3v73++uuxlhNbSgGGgP8lbpGnGo2O7oyuqvEdlWKNI7VCCUhAAhKQgAQkIAEJSEACEpCABPYPAUQMIV2XX375z3/+c5J20UlsuBXsGKeiPhGQiNQj8BAvxrIenMIbDh06FGuGRly1ahUlOYiR4UIEzccff8xciqjJ6k+oh54jk5qGos7U9k7swKP9aCeMNPQhOhjthOMwxLix4a3YmFCSTHBiPB9++GFELcnmF110Ua3GbJKSfPPNNxNpGDKRr7jiCowhDEM/CdALzpTeYuUmTZqEQyRykORl/DKhpn/5y1+44/ScAijmxx9/HBN6xBFHoOQQcKxIg1AOIw2vqFImTyQkE43IAIn+w/3FrlRDVRg9OkATNI13RgVWrBSxmTxXf/zjH4n9pBU0JZN7hgxlOnzbbbdxNvQw9IHydI+NxxgNet5554VYRbpKKjoBm5wKJVG6IaOfoWEt2ZCnf//73+fPn3/99dfX3nSfKsXA31cJSEACEpCABCQgAQlIQAISkIAEDgYCJOSGQEUMFF5m2LBhJIHGRtIRycWGnOIVX0Miahg2k9NhyhBnKDMixVBFSKURI0awvvDs2bNvuukmDCOzCuKbmHAwyleNFxlyioRWhCatswBImZVG4q1tf5VHpbGFWEtydYn6JITw8MMPr43+cC/uuOMOzCCyjPoJMBw7diwSDZNYXiliPwFL7jBsifLDMHKLuTaydRRg0RViDFGK7MM/1idS4c9+9jPqx99h/ZCJUYp07NB4SGgCAhykezwwNBpboPw+zvGxxx4jzJNTZJczKyUZ+uw///zzoENk86zylueKyFBGh68kBpNqqZwdwmyDUpwzZw6Cmw5QGA9OYUJoUZ9cThNkcDM0HlcCIbGlPNuXXHIJJWtjUynWBlXrlIAEJCABCUhAAhKQgAQkIAEJSGD/EMAKYVgwKSS04lkIoONtcE+hQ5ipkFuKdWIhl8gZYZ2I/OJUOEthsk2/9a1vkQSNpmEhFypBUZF2yqR7J598Mqeiays/VOQmxhP7g6nEYFb+wnhL0jeMWJkt9mAskwoqpxiWFr9GvB6dR8DReSI3kVYBFNoLR4aeq6CS6pyCNpMMBomGB+SGErWH8I1uE4OKxkI/6QzN0R+ykrGKrLpTZm5EbCCSjgopTIVIXh6D0EMeGEIveUKYq5GwxCj4sUz/OR61yCmwsJUpE/uW+EGiGkmrx0LSWyIof/jDHxLXSRY5iwhFPpFsZUIXeeq4azxgRNqSkU1nGAjMQ4WIQqxi2MdLkhPNyuaU5wgPMAnprFoepr+EAAOM7UbN7qsUa5antUlAAhKQgAQkIAEJSEACEpCABCSwnwmge/r27RukD2FfQbhEfSIELBxBNZ5wwgnlM0NJiA7X4on69OmDcjrppJOQU+STku2L0+EVszZo0CBiGKNqK7+TmZlJZBnmKOTA7vNCBBZSD1PGa9jCfplxlamHIYQt+C/2o52wX6Z8BW8RbYRwEutH+vCKFSswdKgxDg4YMAACBIFCErFVQQ1VPoXD/cMf/oDBpDkcHAuPcEfCwPG/wWPSGWwaBRgXO+EgxpDsYNpFIPLK84Ckw80hKAlQxYdyNwmrxMERlkgqOqdCJ2mRmQqRyFjF8ePHl/HRoQw5zkFchrc8IWTE0w28M3GCcCaUlX6GszhBHhiSr8MUihkZGczgyVmOs8QKifChGLGrTMiI4uSpoyoeMyIow1hC8jXFGDL+MZhogPP0xj7ePBtEMhK6yKN16qmnMsxazUZXKYYb56sEJCABCUhAAhKQgAQkIAEJSEACBw8B9EoYTHnvhgxi/kSsEDP0sbgz8iVMaRcNHoODnApvqQdbhJrBPTHZImuV4KTIw8UG4o+qphSpmchH6sR/RY1WvENoG6KqzBZ1suJrq3wWSUd4HY6MmD7WwsaIESuHS8WgoRERr6z7TMAgfCLaVW5rjxfS+i233IL7CwGJrJCDqsOUQZ7kZZKIQ+giwo60dGQcC1VzJMQkIuOiyD7u3ZVXXknuMOF7rBnNENB5CDsu4daTxs5q4CQgE0UYriVokY1bzDSLhJRi7hCLwI86yUMVwcff4QeJB2SKQ2YwpFpOkXR/zTXXACr09u6778ZUcjn1YEUJJGQfqqzKEtWJW0Se8kDiHEPKNlG0YeD0H8iUBAgxoeEga9RgFcuTp2+IRbao5lraUSnWElirlYAEJCABCUhAAhKQgAQkIAEJSKCeEsAiEXCHq0ID4Z5QY4ghTCLKBnkXLcRBcByLZqB4CGzE3aCHmNgOW8So0EblbU7lR4ufKuMxK39tHZQkSg44hCXiE0nOhQPTJqJiiaQjNhOfGEwiAXGxoq1mO0Yf/vSnP7GsM9hDzQg4EoG5X2GGQeL1MIOcom9sODsSihG1ZdKc8W5kwY8bN46pMClAuCLLLiNzQ6wf95EbgSxmRLyyrgutUBs6dfny5dx9vB6p01hFnhkUIY9H6AwXhh3UHoYa3worHqrg+9ghPRkPyBop+ETsIcfBReQjGzqbIeAfeZxCJdEomAYRzkQjhrhLjlM5czvyyj4yFCzhEh5XtrC/X15VivsFu41KQAISkIAEJCABCUhAAhKQgAQksN8IMAkdXgmpxMSIxKO9/PLLeEPCu1BUBB4ifRBMmCxMEGuPEICGPcSdcYTARpQiJYOB2m8DqJ2GsXXYQ4L+MGLw2RWrt5aDrI9M6jcxfeyg1VijpvZMYhgZQu2JJ55gaWbkWjTWIOaQfdGRaIf8X6wfTpD8ZbxbdBypR74zgaj4RA5ylzGMDC1EKUbFEIXEjTI0UqEZKeufvPHGG6zxzdjJ+MYtIlh5SHgwEIuYwejCUCepyqhPdGTwiRwkQJLnBA943333sUYKo0BcEuLK4uMEKvIgEZOIHg31MIUiZ6kflUlJtqh+4h/xoThcLCQHsaXBorKP04y0ZlS+LndUinVJ27YkIAEJSEACEpCABCQgAQlIQAISqFMCe5RfzGb49a9/vUOHDmQxz507l2C0qE+4G4LCMIaEg+GSCD2LToUdIhbxSmeccQaBjWVOHbhvCZcjqg6ZyEZOMdm7ZBAT0EeiMa8k3qLb2ILYqu1hYs2YyvDee+8Nkw9GzUXhitw+ohFJTKbbWDycL3NTnnfeeQhEZGjIhuYqTB/9R9hFWcD0Pwr3I/oyqjnsEB7YvXt3buvAgQORzgRpTpkyBb3Ik0CsIhtYaJFUaFqPrkVxIgdZfSWaFZFT9JxVsEnNRjUS+koPiYS94ooryGvmLKYS9UmgYqiEJVZwnaFF4GN16Tm52PhEwkLZGG8oiWmNILDPFo7vl1eV4n7BbqMSkIAEJCABCUhAAhKQgAQkIAEJ1BYBorcQQ6yli+5BDu7RKhLXRrwYUWnkz7KCRwgNI5OU46hGekZkInPecYSot+BuOIKTIt6tZ8+eFKtO4nNtjTz+eomnQ8OxGAgGDRT4LzJ5ifhDIyITQYFJrMscbW4E0xoSHBoSzBkQpg/U3NBwa+gPRo/kdKZ3ZNVsQimxbAg4DhI9SuRplE1M/9F/3KyICgMJSjH4Yu47Lg/BRxDi9OnT+/fvj0ykEtQk26GHHooHDGKRiEUiBPGA//jHPygQ5t8M66jgDbGxzH5IPVFDFOYSrCUPD50HJj6Rhy0UoMPY6qgw6dhEPoIde4iL5BbQBAMkGpTusR+V5DmMlCLmNJKSUYG63PmyW3XZqm1JQAISkIAEJCABCUhAAhKQgAQkIIFaIoBSRAl97Wtfq7h+lOJRRx2FdkQwhXxS7BVbUJCYIPJ88UqcDR6H9FjOcnz/JpxWPKjKn0XGkQKMTOSV+DvkKUqLIZPgzCrY+Ky6NImh29hALOEDDzwQ1l+G86WXXoqPgznSMCg2LBt3IdwCcooZBaKN/mPiuKEovDCXIpKOuD/S2KPZD2mCaEEqIegP84hPJECVMEbKE1FIu+Q+85aAR4ZP/RTjckIFmT4Sfcm0myRBIx9ZxYWngrbgw7PBEtgRc47QXHCa9IqNZwkZevnll1NzpLZ55CIzyLWsNoO75ELaZYtqK79DSCZbOE6WdLT+TPmSdXBEpVgHkG1CAhKQgAQkIAEJSEACEpCABCQggXpKAHmEaWIr3z9OIbPYyp86CI4QXnfnnXcS7IbzIh4TmUigHEoLZ7dfRkfMHQuh/O1vfwvxiSg2fOI3v/lNTF8QiGV6Rc+jwECUItNcovnwocyWyBSZAwYMYO7CKGU4XIvUQyky5SJLORMOSTFMX0hDJm2ZyEHiCoPgI6KQcFSeCpomb5qEZaIFg85DRBKTyBG0NV4v6hXq88QTTyQd+9lnn43iBwmKZDJEoj7RoFFJhkY3ordEPhKoSCt7HGZUjB36H5VBoUbxmLFl6mxfpVhnqG1IAhKQgAQkIAEJSEACEpCABCQgAQnUFwKk1pLni7AbPnw4cwji4/ZjzwjcQ8YFn4g1I8aQuRFJFg5J6HvsGGGGBAmGU0QdhlVZiCtE5zEBIt4Qq1j+QlzeaaedRlYyLYaFVlDGhCJiMzlC3B9CkGRnkqwJOSS1mRpohXxknGMILdwVKbgDdDhEJlgkyJFivL3ggguQmMhNjOHbb79NbcjNMWPGhCzp2J7QIgGhSEku5zjzMKIUWbmF3O3IGMaWp10EIuOiTkQnlxP/iPktI0xjL6mDfZViHUC2CQlIQAISkIAEJCABCUhAAhKQgAQkUL8IYMGIT2S1mWDW9m/nsGYsS8KkhAQDIvhOP/30sNxKBb1ikkQ0KEvrRLnAFMayscQzQZcIQYZW/nIOsoDy//t//w9RSIgiBQhFHD9+PPWwykqY4pB9tvLXhiPDhg0jnJONJXroLZnX7BOfyHEqpwOkObOP/kMUkiJNRnmZqnCOkGeBoF//+tecItzyoYceIuCRnqMpGRQFuBxJSjgkKpM0cHYoxnEcK/3HRZKzT2BpmZrr8m1juliX7dmWBCQgAQlIQAISkIAEJCABCUhAAhKQgARiCaAU58+ff9ttt6EC0XME95U3cbHl2ce4Pfzww0QX4trOOeccVnZmvsUyZfb4FhUWLCSGLhTgLVMivvPOO8wsST44y9RE8Y9RDfSHrHASojGJwR4Sn4iCJECSyEdWAYpdRyW6am879AEXefPNNzNFY1QmTN2IUiQCkdGR10zMI/YQMiGTmg5ff/31zO1Ib1l8BqUYzc8YVVJnOyrFOkNtQxKQgAQkIAEJSEACEpCABCQgAQlIQAJ7JoDFY/ETYgYJ7ttziXJHyVMmhRmlyBSKzFpYTb+G5kMRYhWxeOg8NqZZJMuYvGZmQkTzEVo4ePBg7CEHy/Ul7gN4TMIP7733XiZ2ZCLI2Jg/ctJRiiHPOqoXn0gq93XXXYdvjQ7uxx2V4n6Eb9MSkIAEJCABCUhAAhKQgAQkIAEJSEAC9Y4Ai7cQfsiUhchE4hMRnexUU1nucZCkexNryaLbuFFmh4xN4g7lUZkkO7dr1w6VOXbsWCIZ60OiOn1TKe7xhnpQAhKQgAQkIAEJSEACEpCABCQggf1MgDAxhAsRW/iU/dwVm5dArREgFpK1p9944w2WuuaZJ+iS+EQMJjngPPxkW7PMCwGSLOfC2z2u31JrXauoYpViRXQ8JwEJSEACEpCABCQgAQlIQAISkEDdEyBAbPHixbNmzZo9e/aoUaOYJq/u+2CLEqhLAiQ+89izSAsbkpHQSCZVbN26dWpqam1ER1Z/aK74XH2G1iABCUhAAhKQgAQkIAEJSEACEpBADRAgz5SwRJaeYImMt956K6SCMoXc8OHDyf2sgQasQgL1lQDhhzhEtvrawbL9UimWJeJ7CUhAAhKQgAQkIAEJSEACEpCABOqYQJCJn3/++Xvvvffuu+8uWbIkpH/SDZawIFZRpVjHd8TmJFAxAZVixXw8KwEJSEACEpCABCQgAQlIQAISkEAtEkAmrl+/Hm9IWOLUqVNZ6LaoqIiIraZNmzKjHCtRMJGcPrEWb4BVS6BKBFSKVcLmRRKQgAQkIAEJSEACEpCABCQgAQlUm8Dq1avnz58/bddWUFDQpk2bAQMGrF27ltUqCgsLWaFi5MiRl156af/+/avdlBVIQAI1SUClWJM0rUsCEpCABCQgAQlIQAISkIAEJCCBfRLYsWPHhg0bUIfPPvvslClTsIfEIR5//PH9+vV74YUX5syZw7q3VNK9e/fTTjvtiCOO2GeFFpCABOqYgEqxjoHbnAQkIAEJSEACEpCABCQgAQlIoEETYFnbVatWPf/88y+99BI5zp07dz7llFMmTJiAZ7z99ts5uGXLFgCx4u24ceOOOuqoBg3LwUugvhJQKdbXO2O/JCABCUhAAhKQgAQkIAEJSEACBxeBnJycTZs2IROfe+45ohQ7dep0/vnnn3rqqRkZGXjG++67L/KJjJuIxREjRrRu3frgYuBoJHCQEFApHiQ30mFIQAISkIAEJCABCUhAAhKQgATqLQEWXcnOzn7llVfIdF64cCEO8ZJLLmGSxMzMTPqcm5v7yCOPPPXUU6zT0qRJk507d7I2y5FHHtmrV696OyI7JoEGTkCl2MAfAIcvAQlIQAISkIAEJCABCUhAAhKoLQLIQVKbkYlvv/32pEmT3n///bS0tLPPPnvixInkOyckJNAwq7IQtPjPf/6TbGiOUICpFbt163bMMcd07NixtnpmvRKQQPUIqBSrx8+rJSABCUhAAhKQgAQkIAEJSEACEtgTgZKSEmTizJkzn3766cmTJ6emprLWyrnnnjto0KDExMRwRXFx8RtvvPGXv/xl6dKl+MT27duTHM2FgwcP7tmz555q9ZgEJFAvCKgU68VtsBMSkIAEJCABCUhAAhKQgAQkIIGDiQDBiZ9++ulDDz2ETyTwcPz48WedddZxxx1HXnM0zO3bt3/wwQe33HILqdCNGzcmbpHgxPnz57do0YKSLPcclXRHAhKobwRUivXtjtgfCUhAAhKQgAQkIAEJSEACEpDAAU+A1Vf+8z//c/Xq1azafMEFF4wdO7bMkFjfec6cOZRZtGgRPrFt27ZMrTht2rR169bhHwlR5GCZS3wrAQnUHwIqxfpzL+yJBCQgAQlIQAISkIAEJCABCUjgICFApOHVV19NgvPpp59efkjMsbhkyZLvfve7vHI2PT39+9//flJSEsuzsM8sioYolofmEQnUKwIqxXp1O+yMBCQgAQlIQAISkIAEJCABCUjgYCCAGTznnHP2NhLU4WWXXbZs2TIKkAr9gx/8YMKECXfffffatWuHDh3av3//5OTkvV3rcQlIoD4QUCnWh7tgHyQgAQlIQAISkIAEJCABCUhAAg2FQF5eHrZxxYoVYcA/+tGPmGYRmfjvf/87Nzd3xIgRXbt2bSgsHKcEDlgCX86KesAOwY5LQAISkIAEJCABCUhAAhKQgAQkcGAQYEmWk08+GZ9I7jM9vvbaa88///xWrVqxMDRWcdiwYUOGDGnevPmBMRh7KYEGTECl2IBvvkOXgAQkIAEJSEACEpCABCQgAQnULYETTjhh5cqVwScy2eJFF12UlZXFUi0oRbKh8Yms++zCLHV7T2xNAlUhoFKsCjWvkYAEJCABCUhAAhKQgAQkIAEJSCBeAiQ4M38iApELmUtx4sSJLPSMQMQnzps3r1u3bkcddVTr1q3jrdbyEpBA3RNQKdY9c1uUgAQkIAEJSEACEpCABCQgAQk0LAJoxP/4j//49NNPSXxm5BdccMEVV1zRoUMH1mbh7XvvvUfWMyGKnTp1CkcaFh1HK4EDkIBK8QC8aXZZAhKQgAQkIAEJSEACEpCABCRw4BAoKipiTed33nmnuLiYXp955pnXXHNNZA83bNiAUkxISBg1atQhhxxy4AzLnkqgQRNwxecGffsdvAQkIAEJSEACEpCABCQgAQlIoFYJFBQU/PrXv37llVcKCwtpiLVZWJIl8okcmTFjxurVq4888kgSnxMTE2u1M1YuAQnUFAGVYk2RtB4JSEACEpCABCQgAQlIQAISkIAEvkJg27Ztd91115NPPskOJ4hD/PGPf9y1a1diEqNyRC/m5eUdd9xx5EFHB92RgATqOQGVYj2/QXZPAhKQgAQkIAEJSEACEpCABCRwQBJAIz788MMPPfTQ1q1bWYNl6NChN954Y48ePWJnS5w7d+5HH33Ut2/fgQMHpqenH5DjtNMSaJAEnEuxQd52By0BCUhAAhKQgAQkIAEJSEACEqhNAgQePvXUU/feey9TJeIQDz/88P/+7//u3bt3rE+k/c8++2zTpk0jR47s2LFjmVO12TvrloAEqkug8c6dO6tbh9dLQAISkIAEJCABCUhAAhKQgAQkIIEvCOATmTzxtttuW7p0KaKwT58+v/nNb7CKxCp+UWT3/zKL4rRp04YNG8ZEirHZ0GWK+VYCEqhvBFSK9e2O2B8JSEACEpCABCQgAQlIQAISkMABTIB8ZyzhrbfeumDBAnwimc633HILWc97GxJp0ampqU2bOjPb3gh5XAL1kYCf2Pp4V+yTBCQgAQlIQAISkIAEJCABCUjgQCSQn58/ffr0O+64I/jEzp07k+9cgU9kjC1atDgQR2qfJdDACTiXYgN/ABy+BCQgAQlIQAISkIAEJCABCUigZggUFhZ++OGHf/jDH2bPnk18Iis433zzzcyTWDO1W4sEJFCfCKgU69PdsC8SkIAEJCABCUhAAhKQgAQkIIEDk0BxcfEnn3yCT5w1axZzJmZlZf385z8fO3bsgTkaey0BCeyDgEpxH4A8LQEJSEACEpCABCQgAQlIQAISkEDFBHbs2DF37lx8IlnPlGzbtu2NN9548sknV3yVZyUggQOXgHMpHrj3zp5LQAISkIAEJCABCUhAAhKQgATqBYF58+bhE99880160759++uuu+6MM86oFz2zExKQQO0QMEqxdrhaqwQkIAEJSEACEpCABCQgAQlIoGEQ+Pzzz//4xz9OnjyZ4eITr7nmmnPPPbdhDN1RSqDhElApNtx778glIAEJSEACEpCABCQgAQlIQALVJEB84p/+9KcXX3yRevCJV1xxxfnnn9+0qTmR1eTq5RKo7wRUivX9Dtk/CUhAAhKQgAQkIAEJSEACEpBA/SSAT7z77ruff/75nTt34hMnTpx44YUXNmvWrH721l5JQAI1SEClWIMwrUoCEpCABCQgAQlIQAISkIAEJNBQCMyfP/++++579tlnS0pK8InIxIsuuqh58+YNZfyOUwINm4BKsWHff0cvAQlIQAISkIAEJCABCUhAAhKIn8DChQv//ve/P/PMM4WFhe3atWPyxK9//eutWrWKvyavkIAEDkgCKsUD8rbZaQlIQAISkIAEJCABCUhAAhKQwP4isHjx4vvvv//pp5/etm1bVlYWiztffPHFiMX91R/blYAE6p6ASrHumduiBCQgAQlIQAISkIAEJCABCUjgQCWwZMmSBx544KmnnsrJyWnTps2ECRMuueSSjh07Hqjjsd8SkECVCKgUq4TNiyQgAQlIQAISkIAEJCABCUhAAg2PwMqVKx955BF84pYtW0hzPuWUU/CJ3bp1a3gkHLEEGjoBlWJDfwIcvwQkIAEJSEACEpCABCQgAQlIoDIE1q9f/+STT5LvvHHjxoyMjBNPPBGf2Lt378pcaxkJSOAgI6BSPMhuqMORgAQkIAEJSEACEpCABCQgAQnUPIHs7OwXX3yR+MRVq1a1aNHi+OOPv/TSS/v161fzLVmjBCRwIBBoeiB00j5KQAISkIAEJCABCUhAAhKQgAQk8BUCJSUleXl5BQUFycnJ6enpTZvW4g98lmGZOnXqY489tmDBAtoaPXr0xIkTDz/88K90yDcSkEBDIlCL3zgNCaNjlYAEJCABCUhAAhKQgAQkIAEJ1BGBHTt2bN68Gbs3e/bsDRs2sEbKgAEDSEBu2bJlkyY1n4yIu5w5c+aDDz74ySefpKamHnvssfjEQYMG1dFobUYCEqiXBFSK9fK22CkJSEACEpCABCQgAQlIQAISkMCeCBQVFS1btuyll15iWsOFCxeGIn369DnvvPPGjh3btWvXpKSkPV1X9WNz58695557ZsyY0axZs6OPPvob3/jG8OHDq16dV0pAAgcFgcY7d+48KAbiICQgAQlIQAISkIAEJCABCUhAAgc5ATKd58yZ89e//nXatGlNGzdu3bJlUmJiQWHhpq1btzdqdNxxx1111VXkIycmJtYUCJZ4/vnPf/7qq6+SXo1JvPrqq4lSrKnKrUcCEjhwCRileODeO3suAQlIQAISkIAEJCABCUhAAg2IQH5+PhMa3nfffXPnzGndssUpRx9z7vFjO2ZlzVu2/Olp016bMYOzTK147bXXkgddI1Zx7dq1N9100+TJk6lt4MCBV155pT6xAT1wDlUCFRIwSrFCPJ6UgAQkIAEJSEACEpCABCQgAQnUAwLEJ77++ut/+tOfFi1Y0L9nj2+eeeaoQYMSv1iSZUtu7qvTpz/44ktLV68eNnz49ddfT6xi48aNq9PxTZs2/exnP3vllVe2b9+Oo/zBD35AYnV1KvRaCUjgYCKQwD84HEzjcSwSkIAEJCABCUhAAhKQgAQkIIGDjEBubu6kSZPwiSuXLx8zZMi1F100YsCAhJiVWFKSkg7t0qVTVtbSVas/njt31apVI0aMSEtLq7JVzM7Ovvnmm8l3Li4uPvTQQ3/0ox8df/zxBxlVhyMBCVSHgEqxOvS8VgISkIAEJCABCUhAAhKQgAQkULsEyHe+995777v33m05OReefNKVZ5/dq3On8k1iGLsdckifrl1Xrlv34ezZq9esGTJkCAuqVMEqEhH5i1/8ghVgaLpz58433HDDCSecUL5Fj0hAAg2ZgEqxId99xy4BCUhAAhKQgAQkIAEJSEAC9ZoA6zvfddddDz/8cFF+/rUXXXjRSSdlZWZW0ON2rVr16NhxycqV73/yMbGNJCzHaxULCwv/53/+5/nnn8/JycnKyvrlL385bty4Clr0lAQk0DAJOJdiw7zvjloCEpCABCQgAQlIQAISkIAE6juBkpKSO+6446GHHkpPSrrx8suPOnxA04SEynR67pIlv3/ooQ/mzSe6kHjDli1bVuYqyjBt4m9/+9tHH32UiRRTU1Nvv/32E088sZLXWkwCEmhQBIxSbFC328FKQAISkIAEJCABCUhAAhKQwIFBYOfOnX/4wx8eeOABfOJNV35rxID+lfSJDC8rI6Nvt26LVix/a8a/Fy1aNGrUqOTk5H0Omxb//Oc/YzA3btxIuvTdd99tfOI+oVlAAg2WQJMGO3IHLgEJSEACEpCABCQgAQlIQAISqLcEfv/73z/44IPpycn/fdVVQ/v1q7xPDCPq3bnzTyZOHNKnz5QpU37yk5+QBL3Pkd6/a9uwYQMl8YmjR4/e5yUWkIAEGiwBlWKDvfUOXAISkIAEJCABCUhAAhKQgATqKYHf/e53+MTmKSm/uPqqwX37JDZtGm9HCTPsWWoVLx3at8/rr79+/fXXV2wVn3vuOTTiunXraOjOO+/EJzaNv9F4O2l5CUjgwCWgUjxw7509l4AEJCABCUhAAhKQgAQkIIGDkMCtt976pU/s0ycpMbFqg2yCVezUiVjFYX37Tp06tQKrOGPGjN/85jerV68m95noyLFjx6akpFStUa+SgAQaCAGXZ2kgN9phSkACEpCABCRQfwns3Nnos5VbZy3Onr8qd8nqvI3ZhQkJjdu2SuneIa1vpxZHdmvZNSu1/va+PvVs+46duQUlJdt30qn0lKbJif7zeX26PfZFAhKoHAF8IrMZttgVnzjw0EOTq+oTo9a279ixeOXK3zzwwMzPPmdSRepPT0+PzrLzxhtv/OxnP1u2bNmOHTtY6/m0005r0aIFQY6xZdyXgAQkUIaASrEMEN9KQAISkIAEJCCBOiWwNb/44WnLX/tw7ZacouKSncUlO3agGBs1SmjSOLFpE/7atEw+eWj7C47t1CypUqt81mnv61ljL3yw5sk3V6zbXEC/rj370LFHtPUXcT27RXZHAhKoiACJyf/3f//38MMP4xP/++qrjuzdOzkpqaILKn1ut1W8/4GZn39ORjNrOsdaxfz8/Oeff/5Xv/rVd7/73bPOOqtVq1b6xEqjtaAEGi4BV3xuuPfekUtAAhKQgAQksN8JzF6+9U/PLnztg3Ubs4sKi3cQXrdLJ5b2a8fORrzlYHZe8fJ120p27BzUI2O/d7ied2Dmws3TP9u0dnNhXsH2kYe16d2xuUqxnt8yuycBCUQE8Ik//OEPX3jhhZbNmtWsT6QJMqBbNm9+WI/uS1aufPf99+fNmzdmzJikL3xlYmJit27d2rVrd9JJJ7Vu3bpJE0O8o9vijgQksFcCflPsFY0nJCABCUhAAhKQQK0S2JxX/PDry96dszFnWzGRifze69Wp+dnHdbr2nEO/e1bv4we3a5ORTAeIWiRWMSO9ZgJVanVE+73ySMju957YAQlIQAKVJ8C/JmVnZ+MTp02blpGaynosR5Lv/IXvq3w9FZdMaNKkR8eOP2a1lj59mFfxxz/+cU5OTnRJamrqhAkTsrKy9IkRE3ckIIGKCRilWDEfz0pAAhKQgAQkIIHaIjBp+qops9Zl5xbTQGpKwrmjOn1jXLdjD2tzWOcWfTqmD+6Z2aVt6obcoqSmCece1/HkQe1SEk183se9+GTZ1k+XZOfll1Bu9OFZRinug5enJSCBekAAn7h58+af/vSnaL62mZm/DD6x2vMn7nFkIVaxf4/uTK34zsyZCxcuHDlyZHJyckhzJmjRfOc9cvOgBCSwRwLOpbhHLB6UgAQkIAEJSEACtUtgzZaCXz0y94P5m8luTkpMmHhC1zOOOqRNiySmUIwazivcvmhN3raCkj6dmmeklV3uk4i8vIKSZRu2LV2fT23NU5p2zmrWLSu1bcuU8tm+RSU7Fq3NozyVd22b1io9cc3mgs9W5qzaVDrtYLuM5F4d0ju1akY4ZNR6mR0SsUNzy3Y116JZ085tmnVtm9qu5R6WBF29uWB9dmHx9h1RJe0zU9q2SKb+Zeu30e7a7MLEhMadWqfSbvtdwZhRyS15xZ8szc4pKAEFv36ZQbJ186TubdNSkvbct3VbChl+aOuVWeumzlrHrJTUNnFc1xH9Wn9Js1Ejfiq3bZl8SKtmMYx3N8vslQVF21dszKd7qzYX0HTnNqld2jTr0ia1PMyoq+5IQAISqCYBfOKGDRtuvvnmyZMnZ2Vk/PdVVw6uxvrOlewMa7AsXLnyln/c//7nn48bN+6mm25y8sRKorOYBCQQS6Bp7Bv3JSABCUhAAhKQgATqhsDUT9cvXbstrE08tE/mMYe1xnaVsVdpyQn9OjUnJzqpnOnD7r01Z8NT76zKzS/JKywpKN6BoWuWnJCW3HR4v9ZfH9U5vVnTWJuGp3tw8tJFq/MY3SUndEVWvjV7/aoN+flF2zlC/GPLtMRjDmszfmj7Dq32oAhZRvnN2RueprmCkm1fNJcamjus9cWjuqSlfCWC8rWP1r7x8fq8/NLKwzbmyKyTB7eftSj75fdXM9chuhHBl5qU0Lld6qlDO4zu36Zpwu7+rtyYf+/Li3PyiinAIexeUmITlm9unZF80uB2x/VrU4bSm3M3vDxzTe62Ulu6Oa8od1tp1CfbSzPXvD17AyIxvC19bdzoqL6tzz+uU4fMr4wReh8t3vLItOWbthZCBrdIy6jM9JSE7oekX3VqD2Tol5W4JwEJSKCGCOAT165d++tf//r1KVPaZmTcfNWVQ/r2TWxa6z/SSW3u1anTTyZeesv999N0QkLCDTfcQMrzri/dGhqb1UhAAg2AQK1/WzUAhg5RAhKQgAQkIAEJxE1g3orcnPxS+UXg3jF9W3dvl1bGlIUad4m2GCm26+i67MJH31rxxkfrlq/fVn72wFWb8uetyPn/zu9LcF9UJwtJr9iQv3B1LhVM+XgdIYQLV+ZyMLTC64oNjdZsKkBfXjCqMxGI0XF2iAF87M0VKMIVNBd7Ytf+SppbnnPDBX0z075sbt3WwsVrtjFHZFS8Y9tmTZqsm/H5ptmLtwSRGk6t3pTPTlbLpCO6tgxHiMos07dwPDkpYeHKnDc/3fCjcw5NjnGsG3OLlqzJYxGbUCx6JXqRv+ht2OmSlYoxjD24Obd48kfrJr29YsnavNiOhTKEdiJerzv70J4d0giZjL3QfQlIQALVIUCo4Jo1a1h5mfjEdpmZP/3m5UP79Wua8JV/nqlO/RVfiz3s1bnzjydO/O0DD0yZPBnJyNSKLM+iVayYm2clIIFYAs6lGEvDfQlIQAISkIAEJFBHBCa9s3LZulIh2K5VyqlD2/don1bJhrcVbn/vs40PvLZ07ebSnGV+/jVPS+zQJpXZGLflb0f55RduJ9AvPT2xT8fmUSJzTn7JlI/WbcguVWxbcos3ZBfhE1ukJyUnNsGjBS9JzQQhZmUkx3aGcMh35258aMqy0BxaLZ3mWqcSEbmtYHdzqzYWNE9P7NuxedOE3bnJa7cUbMotTklpWli0PXi69NREnN3iVbn0uEObZs1SEgoKabjR9h07t+YVt0xLGtIrk77Rfwzme59vIjIxMZEfuY137Cg9yLZ9+0703/L1+ckpCYd1asGpXYcbbcwpWr2lkLYympeuYMO4wnBat0yGbUaLZI5Hf307Nx/YPaP5F86Usp8u2fKXFxbRNzK7cYZ0jNGlpzaFBvWUlOwkQ3xjXtHoAW2jOMrQrq8SkIAEqkwAn7hy5crbbrvt1VdfbZ+Z+ZPLLjv68AF15hNDt/m/j9YtW/bu0mXJqpXvvf9Bk4SEAQMGMK9ilQflhRKQQEMj8JV/gm5og3e8EpCABCQgAQlIYL8QQHvlF2zHkdF624wUkpQr3w2CEJ96b9XmXdMFcuGpwzqM6NMKwVe8feeydXn3vbJka04RNT/99sox/dsw12H52Dpyitu1bnbioHaHdy0Vcys35L82a+0ni7PpA5bzs+Vbxw1sG/Vn5caCZ6avDs01T008dVj74Yfuaq5kx5K12/766uKtBDtu3zHprZVjB2R1asM0haWmb2TfNj3bpTOB4+NvrZgxdyN6jlaKine0yUg5eUi7I7q3xDO+8cmGybPW4hOz80rWbMznCM6Oi3u0TyfmkXWuMXq8wio7v+T9BZuZJBH/SAzj49NWjOrXplMbhlbazSE9M9tnpNAW+699tO71L+ZSHD+s/Yg+rctEFrZKTyJ4s/SyXRu6cArRlxu28S41pemwvq1OGdSOYdIQMZuPv71iwYocujF97qZZi7fQkFZxNzj/RwISqAYBfOLy5cvvvPPO13b5xB9efPExde4To+7369bt+xdeePujjz41aRI+8eKLL87IyIjOuiMBCUigAgJx/PdrBbV4SgISkIAEJCABCUig8gQ25xUXfpF03KpFElMKRtdi0ojLK7PhxcKyLSTtkrw8Z+lWChCWeOzhWReN6dyxVbNQHkXItXc+Mx89t3pj/ucrc5gYsfw60Sx6ctKgdueO7Nguo3QhFyITs/OLWQeGhZIJKmQF6sLiHUQvUiczLS5YnTN3aaltTEtpOuqIrItGdzlk12SL2NABXVvS2zueno90C82xBkvSrikcmReSP656e+7GpiQpF25HHdLhEwe3O+vojm2aJ3EJATIL1+R+vHAL7pCG6EZYgiaTWR37tg4j4pWG6A9tsRrM319ZwhH8Iwu8lK6ysmv6RRRhZAnnrc4NPacYK7oM7ZVZRilyPHZDdDLfIp0hnLNP5+bfPLFb70PSgxVlgsWM5ok/+8fsouLtBFS+NXfjEd1a1nEMUWxX3ZeABA4aAhs3bnzwwQdffeWV9q0yv3fBhSMHHtG09udPrIBe/x49vnv++X96/PEnHnuMYl//+tczM0vDxt0kULMEQnDukiVLWrdu3atXL1YYr9n6ra3uCagU6565LUpAAhKQgAQk0NAJkE0cQhQBwbSACV/kCxNpOPnDtTPmbSoDqF1myrED2vTv3ILFQ5ZtyEf8USAzPelrx3WKfCJHWMOE0LyHpi7dsKUQTbZ43baRJTtTyq4U3ahTVurgXpnBJ4ar+nZu0blt6mdLt+LvsHustpycWPof+nkF25fTXHGp42zdIum8kZ2CT+QtAYLESI4f2uGBKUtZYZnmmHbwmH5tkvbyX5fEG/Y6pDnZzfjE0ssbN0J39urYnBztxo0apzVL3J2uzLmvbjSUktjk0EPSWSzln1OXh7HPW5U7un9WNWMGEa+bcopCMnir5kms/UKqeNQ4jQ7v3eqIni1nflZ6O+atzCV0MTrrjgQkIIGqEWB950ceeeT5557r0KrVNeefN2rQkXWwHss+u3p4r17fPu+8u/71ryefeILCF154IdJnn1dVvgBh+R988EFeXukSYdR82GGHsSZM5S+3ZL0lUFxczM2le4S47nMiTpL9n3jiiTfeeKN3794XXHDBkCFDantcBQUF69evX7FiBfOW0tU2bdr06NGjS5cuzKtS2003kPr38h99DWT0DlMCEpCABCQgAQnsDwLkKX9hERuRFExub+gF3u3TpVufn7G6TKe6dUhD+aEU8X1rdy05gpIjZ5lQx493hRDGlicIMbxlikOsWeypsN8pq1lmemJs+F5soB+XkKEcSpY2t2v6xdAc1ZVpDskWzWlIivT27Vy411+JA7q26JK1O6CS+llG+bSh7Qd1L12VBb/JWtWhUV5pF2m4cHVe9rZiYidLSnYkJzdJTW4a9XnFxvy9Kcio3vnC6wAAQABJREFUkn3u0Mqm3FIZysaa2inJCWVGV1Syk/kcQz2EYZaPHt1nExaQgAQkEBEgRGvVqlVPP/30v554IqNZs6vPPWf04MH1wSeGHg7s3fuqc865+8lJTz35JG7oa1/7Gv4l6nx1dghF37p16+9//3v8DvWwCMzvfve7tLTKziBcnaa9trYJsLjQO++8g6G76qqrOnToUHFz2L2PP/4YuZyTkzNixIhaVYo8dYRDMlfphx9+SFzwli1b+I+JFi1adO3addy4caeeeur+DQ2uGNQBdPbL/3Q7gDptVyUgAQlIQAISkMABTYAAw2jhFKwWbqvi4SCzWEiEMiQ+s1gzO4gwIuz+9vKS8hdm5xQHTbYxp3CPgXUtUhOj7OBwOVnVIbH6i9p2i0g6Fpoj/ZhovvLN7Wy0k5kZv2iuqNQo7n0jLTqkNociqckJ/bu04C/2ioLi7Z+vyHn9k/ULV+XiKAnnZLUZRkE+dVpKYuQ6txWWhEZjr413P6+whKVdwlXAfObdVYmR6N11FGu5eE1pTA3b1lL5uAc/G876KgEJSKBiAvjEhQsXku88ZcqUxsXF/3HB18YOGVJ/fGLo/JGHHvqts8687Z+PID2xiuedd15WVlbF46rMWaLY5s+fj3gKhVNSUlavXk2wmJFilaFXz8t88sknTz75JDGnRLbuUynyOA0cOHDz5s1EKXbv3r1Wh/bpp58+/vjjr732GqGRqampbdu2RSnS29mzZxMpfMghh9Sq0KzVodWrylWK9ep22BkJSEACEpCABBoEAZKdiYkjvo+wRFQdS46EYeP1BvXKKE0q3rWxWMonS7KjsxzDKxZ/4e0I35vx2cbdRff0PxgxlF/5M+QLR6GF5c/GHildHWVXc9SSW4nmds18GFvBl/tMUEgqcbQk9JcnYvZYYmX20q33T176wcItRV/VrCUljVhgOqZsDewiaqP4UNzlh/M3V1CpSc8VwPGUBCRQMQF84oIFC/7xj388++yzhIhfdPLJ44YNq28+MQxhcN++l02YcPeTTz7+2GOs00IwV/VXayHhdMaMGTjKnj17EixGyNisWbM6d+7s6tIVPzYH31mc4xlnnHHkkUe2atUKq1irAyQw9vPPP8/Ozh41atQxxxyDQywsLHz99ddfeOEFPozTp09XKdYIf5VijWC0EglIQAISkIAEJBAfgZa7AhWZGXDz1sIVG/KZJDGNbOiExkf1aT2w++7VNqd+up4JCmOVItGFrFkcWkpJSujTpXnTL9Kcyzd/ePcM3GX545U/EtscydqHdq6oOVYviUIvyzeR0LQxyd5fyNLy50uPkNP9yodrp3+2ERWanJTQo0Makxs2b9YUB8osk5u2Fk35eB0rpez54nJH0aAYVSZqLHdm94GUpCZR1GRSYpP2rZtltdjNtvwl6c34+V8tmOXr9IgEIgL4f5YAXrt2LUfat2/fqVOnMCsZv4GZAoyYGqaf69atW1S+Ae6AiBC//Px8tBTxTcyGdqDkLRKjh8K4//778YlFBQXDjzzy7LFjUlNS6u1NHDV4UGFx0d+fex6r2LJlS4xMenp6dXpbVFTE9Hn8P9yYMWN4zgkce/vtt08++eRYpfjZZ5/xqJNqzUZ6LCmrZEkjnvr27YuHio1nhCdekgJ8XrZt28ZnhL4R+UjhwYMHk9nKjI3vvfcelxAQxwdn7ty55JszBM7SB05RAKHJUxQ6QIXUtnTpUlwnnzvq4Rnr2LFj9IDRn3nz5tEWDTVv3pyzNLdo0aLFixcT+ManFUfGkQgR5YlIpbbQPXrCWaLk6A+XR8Uqs4ONBQutUxuLmbCkCT2ncgjQ7qGHHhoqeeutt8BFn/F0odtY7JkzZyLUOMhXB2F6UXNwY7wEioKO/vBRokCZW8zlubm5FAMdo+Bzx5FmzZqRrk7CMogI/UPYgY5XOsn27rvvcnOjVvr3789XWbhxHKeqkPYeCtA01VJhVD7sUCH0eBgYL3US1UieMqOOLbZs2TLgcy2DZSzcBbrKQJigE2+YmLh7Auk+ffqcddZZw4YNO/bYYwcNGsS95mYBh0xtesKXamyd7leZgEqxyui8UAISkIAEJCABCVSdQLd2ae+nbEYpFhbteO+zTQO6tezXqTn2Ky0lgb9Qb4tdNi22DZKFowVSKDb6iLasWxJbIHafhVCYfzD2SLz7rPLcIXP3zyQWYxkzsG3vDnttDh/XLGbp6jJtoRP3IRQbNVq9OX/655tKfWJik/7dWrC6dKlSTG2aiFIs2bF6UyGOtUy1Zd6iUMN6zRxnkkomQ0xJ3KtSZHRhWWoKJycmDOjecvyQ9mUqjN4icImyjN66I4GaJcDPdZzLyy+/jNHgB/C5556LCqEJjMC0adOmTp1KQM0111xTs40ecLURWIRrwB1gQHAEiAZ2MDWR+qmHI0KR4BMfeOABfGLO1q29u3Q594TjO9ZENnHtDTapadMTR4xgJot7Jk1iJRms4tChQ2P1X1xN82yjb8g2xS4RLIbJIvUbr4cGQmMFdU6FeMY333wT68dBJCCiKihFlBBiCD8VSmInyV3lk4Jlw7UFZ8flODueB2QfSpHwtDvuuAMB98Mf/hD5BXlsFx+oW2+9Fd9ErCh9OP/88xFeDAq9iN+kdVKz6WdQiv369cN40nSY8JE7+Le//W3dunU0hNEbP348fXvxxRcRW1gqnNdpp53GYiOcZbDEY7700kuhNrpHSTwm/ouPMPIuLqXItcw8+NRTT0EvKMUBAwaMHDny/fffx6MRQBopxXvvvZdsYo5Eqp2ePPbYY1A66aST+D4JSpGnkaqgR5RorFLEGjO9IEAYAhuDov5nnnmGjxvqMFYp8jDQKFSpASbcDgQfrzT38MMPxyrCa6+9ls9mUIqMguRoXGGon1cIs7B4+JaLDjJespUnTZpEu9wLqmXaTT7jEyZMOP7448EYSqJKWeOFRcnp9r///W8uCUoRY8sEoIcffniwirhpLmTI9Dl0g4FAiUp4NlzTPMJezZ1q/VdmNdv2cglIQAISkIAEJNBgCRzdt9Vbn6zfnFO6NPOsRVve+HQ9Eyy2a8mCiRUhQSl2bLXb8bEQ88r128YPaZeZttfYuorqqsQ5Aicjg8k0jqs25I8f3D6K7KtEBfEVIbV53ebSyfvJCj+sa8tR/b9cGQBRWLxjZ+G+QhRZdiaaJnLpuryNWws7ti4bBBH1iSVZWqYl4goZGspya15xVsvkbllfhnJEJd2RQG0TIASPyCOsIg0REMTv7eOOO459Ynk4jlKMQm9quyf1tn5cD9YGiYPLwHfgEYhgQiHhEXjFpJCfG0mH+jMKxA1K6LnnnkNdtc7IOOmoo0YecUT96d7eeoJVPGn4sHXZW5549bV//etfuKEqp6kihrhZDB+zc8QRRxBbh98h9o1bifSJHmyi2HCF2ED0EGoJM4gAYqFeiqHDCFQM+om3Dz30EDx5HvBNUQ0oLXwWJTnOpwknxdDQYbxionlmcI5UGJwaQXNoSkqGs/fddx8reNA9WuEgjowO4yupkIg8ytBhJBRBc0Qybtq0ib6FOEEuwTbSSWTZ2LFjeSBp8fbbb8dg8iiiGuHGDpcj6Sgc7/NJc0TmPv/886hPRB6jozlkJV6MKEWsOn0L20cffcRB8MIhHGGHkhwndo9bEA5S4aOPPkqFjIWAPhwiUX7oVAQu5ZkMkWFSEnlKMTw43QZy2DgOWLagWQEFH0YEWO4aWp+dWKUYO1j2qZmNy/lEQIl9HonQq/BKByB5zz33IGQ5G+wwSpQhMGpuDQMJZpA+I0bpAMNhH7AMh8FSmA5wF9C+oU7uVNQE/zzDFywimC9Vypj1HJGp5o5KsZoAvVwCEpCABCQgAQlUhUDfjs0H985ctSk/O7c4d1vxy++vRREe179Nt7ZpIdWXvF3m7yszhV9KYkLXtmld2qUuW7uNyQ0nf7A2My1xeN/WPdunpafs/u+6HTt25uSXEK3HkYoF5T77jW6jP6G5nG0lr72/NiM1cVifVj07pKcn744XoLmt+SUEIVa/OX7eoQ63N9pZXLxjw5ZCFocJYY8sz7Jkbd6jbyyLVpshtDOnoAR7WCaXun1GShQp+f6CzV3bpY0a0KZNC4IX+ZHZiLkaS3bsYA0WZCJjp7m2GSkDe2ZMn7sRq/jxwi3/nLrs+IGlgZ8t05JCTCVX5RaWsCwM+ebVhLlP2haQQCDAb2MEx/Dhw6scF3awkkSzsp1wwgkYEJwCoU+s+EGIWbdu3dANBLKxg01AeQRbVB84zJkzh6AwLEZKcvLA3r3OHD0q6YvEzPrQvQr6kJaScvboMYtXrJz+7rtkH2P0iE2roPzeTjH2sCIwUgwDGMwd2o5oPnRwpBTD5Tz8+HQC8Qg5pAzqEHnHvWafDiCkkH0YdtQSSogYNLxYEFUIKawWlVMPdeKM8GJE9uEQEU9cGCLUcE8coQyyj88XGo4mUJlYM2qjTp4ceovVIhSObGKeK+IK6czll1+O28KyUWfQ2RdffDECCz2HMg65yfBhLWMeSOonYBDJSCv0it7SLso7rsg4OowJZbCYRMLxzj77bAQZTz5LjmDlYuVdQLfPVwZOfCiTCSIKyUDncwRSbB1RnHzhcOroo48O4hjahCiClPtO3B+fKXQhDNmwk+Ex4N6xQ5l//vOfSEnGCBDMftQNoEVWEddJYZ4EOAAcSR0Vi3ZQycSukpXMePmYE/jJneVeYJABTmzpr371K45E5bl3ICVilJ7geXGgjAV9TDxjpBSjwsDE8xJWCVLOnnLKKeSqR2fdqQ4BlWJ16HmtBCQgAQlIQAISqCIBXNiJg9t9vjxn1sItJdtL4w2ffHvF/JU5h3Vp0To9CZeHTCyzNgstcRWabMKIQ+57cRGea0te8YNTln28NHtQj0zcIlMxIvhKmHYwp+iQNs3GDWxLPVXs367LaK57+7RTh3X428uLaW5zbtGDk5d+vCR7UM8M3GLU3MatRR3bNjtxYLsQIYjrfO+zjWhN6liwMicsgbJ9+86Z8zezfDMHmSexX+fm3dullekb0zW2bpm0ZmMBOcuzFmx+4q0VrVskMz9jdm7RnOVbX5yxunlaIgtMc9WqDQWT3l7Runny4N4ZXbPSmGwxVHVIZrOsjOQFq5rQ6OLVeZPeWbl8/bbObZqhEVmspqBoR1JSE+Z8JJ86lO+SlXrq0PasLs0iOUQpvjBj9fxVucN6Z7ZtmRLqBOaWbSxRs/MbJ3StYKbIMgPxrQSqTIBf5kTT8BMaDxJlNZavDSlAeA7BPhTmElQFIVH8aK8/Kq18n2vqCGFubKNHj0Y/IZvIfCRy7emnn8ZrYDEI3UKLMH8cYU24iZpqtMr1YKCIiUNytW7RfMyQIZ3btatyVXV/YdsWzceNGD5n4UKsGTPTIXp42OLqBhIqqCLMGpfzfGKFUFdEKZLmfMkll5SZwg/ldPrpp6OxsEXEvhH9h94iBxZ/FNqlAGaK2rjF1IMKLH+XMVmoRj4gXEglXIvq4i4g/tBqbFQVwhv5oCHpCJdjbWvycIMRYylqdCSijWBYdlCKqDc2LqS3HGRE3/nOd5CG9ITWsVQcR1oxWF5DP5Fo5E3zEDLeqn0qeXJIAOcDTrLzZZddxr8xUDPeHBOK3AytxPVKt1GHfGlgTiGMpqRjdBKkBHUCh1c+O4yCkRIoyr2GErnqjKLMbaJd+LOxg0IFOBuSDgW5xy5xO9g4BTEE7h7LcJuwfnyzUS2TPCAK6QkfZ/AyXtTtDTfcwOcoFibJ2t/61rd4BjCbPFHccV6J3yxTP2e50ahJ6iH4kbETo1r+sSlzlW8rSUClWElQFpOABCQgAQlIQAI1TKDPIc1PGdq+cZNGc5duRcPlF2yf8dkm/oiGI1GKpUXQcOWbJO947OFZc5dtnTlvM+GNhNfNmLuJP0rivLgEd8b+Eb0yR/ZrU02lSD2kY5c2tzzng/mbcreVEDlITB9/ZZob2Dtz1GFtglJcm114z0uLiSukTLTh+J59bxV/HMlonvStU3uUV4rtMlOG9M58YdMafkis2Vzw52cXNktJYAibtxYxKPaPG5D1wvTSGtZtyv/bK0vY+cG5h7bPRP/t/m/ajPTEYw5rs2h13or1pb/rFq3K5Y+daOvQplnj47tGSpFEchbDOXlo+1feX7N+SyHadPbibP4oH+IfQ1xkcnLCxaM7qxQjjO7UHgF+w/NLHs1BkNTeUk35tc/P7FdeeYUIOEQAP+b5Ec7veeJ6cGrxSp/aG0ut1oxUIpyNjaAkcOEp0CWEKREmRoQa/gslQYwYPojsTnb2l0EgZJItNyend+f+x8VkqtYqnBqsfHDv3u1bZU57/wN0DJosrjg7uoEhwgmS1AwEpBjf7Rw86qijcJTcMowhHpwHOOow9fPYh3xVXoMxZCoANsqgkwgx4+YymSAhhFzIA4/wQjGHzPdQD88GAosngfpxTBxkPkECDNmnBnwZNfNgcDlHggRE/CHxif6jMNoraMegI0Od0Ss10CuGwBGuQqJdeeWVqC4iZKkQ/cdIcZRM9kfl2MldMu0QznI8VodFFe5tBwOI0OTjzNML+VCMx5gHmwHu7aoKjuMoQ64xuhbvRpRoKJyTk4Om5BUDyxE6ybcQLo8AST5Td911F/+2AWQGwig4VUET1TnFjeAWMDTuJvMhhp7QVbwhzx49524ShRrLkJk3Q1wqlHhseJYQx9y+Mt3gCA8MAY98FeCOL7roovKGtMwlvq08gao8i5Wv3ZISkIAEJCABCUhAAnsjQGrtacM6dMpq9vLMNR8s2LI+uxA/SJghv7mIWwxXoRdxam1aJrVM3b2IIfF4HVs1+9Yp3Una/XjR5iVrthWyHPIu9xjiAcOF67MLojRhjny5asmu5OLdQX1f9IxW+AsbO9EKJxzhcKc2qd86ufszGSmf0NzaPTe3bkthlKNNfnHQml9UX/Z/S4cYlY45ybgAsmZTAaGCW3OZO3FnXn4Jf/yEYIHsEX1bTRjWPijF6KLSMX7Vu54wsC0hh69/tG7lhnx4RiXDTl5BydZtpXGO0dY+M/nckR1JNn9vzsYFa3Lz8oFZWmMsPX5g5hfvSE3Z++rRUXXuSKB6BNAl5BgSwMWPebLzyleGo0GcMV8bv5AxGhgW9AdLuLDxc/qnP/0p4VSxv7rL11CdI8T7RPFi1amnMteGUezxNfYgNgTJwkbUFbFIiCSmVAMO86YhGrA/aEeMDO4J1YgQIWM09vLK9KQ6ZVBd2JkP//3vHp06tt+15E51aqv7a1MSCfIuVX7oLaxTvEoR/c0d4XKeHKJKiSNjnweVr9kwx2K3ry5GHMwgNy6MFFWHY6IwWziC3jrjjDN45tGUrAdCSbrE3SdikQ2jx80N950WkVBMz8e1GEDyc3F81Ma1NMqnjAp5mMM8g+Tb8okLTfDKVbxGKjM6zg5dQl0FDrTFE0XCb1QAw8haKAwZO8Ya3zSN7ie0kFRull0ilJjLo8IV74AOp0l57GfoLeVpkQeet4yi4ss5G0ELJamNOtkn+JFM4cjkYhLRlzTEayiJQCTPGotHSCZulEZxcLCFMEGLBDlGNyiUr5FXbgTSk+80Wo/qZ4e3oX7OEmMY2xaWExrhCBdSmK/H8mQYCDeaUzw8rLqjT4xlWP19lWL1GVqDBCQgAQlIQAISqCIB/N2g7hmd26S+9/nGuctytuQWYdAKivkptDOxaePkpglJiU2I6SMbuk/Mys7k5PZqn37N+B4fLNoy9ZP1ObnFBA9u26Uj+U9/5g0kgzizeVJS0y80IQtJJycMJZ83o/Q/vkk6ZrHj2B7jK0kHbrzrJ9vh3VpyeexZFlxmesFrJvT4YOHmaZ9uQPah6r5sLqEx0xe2apEUZR+j50b0adWjfdm85qjO1JSmHdvsYdUUahjQteV3z+g9eda6JatzGRR5x/y0pLfdO6SffdQhiNbhfVoRP8iW0KRUfZLUTP51VDM7LJN98ZguXdulvj9vM6KTSrbvsoMUJsyQ9aMPafWVpjmOyuSSYb1bvTpr7frNBeRHbyviZ0kpDipndMy9WOpAOfCVpmKbdV8CNUMA7YXvQIrhDZkrsMxPaNogEZIVBkg2RCswGxobMTjMTUZUI2uqjh07FhHJr+ua6c1Xa+GLiTCuPc6D9tWCNfCu9EO+awtyocxrmVO7i+76H6wBw8ccwZBQLCwSfofp21CKzIvH2ZAeHi7BB5H4WQPd3XsV3bt3R8TM+fjj/ILCLbm5Genpey9bH898vGDB+s2bQYq+CRFhcfWS0DOyWbkEPXfjjTeWuZaZ73iAYwNIuXHhXpcpGb0lZA9nx91Eu4dbjBHj48A0fDjB//qv/8JAIctQyQg1NGjQl5g+JCA5v3xqUEvEwQUVRXM8CVRO8i//VxFZNgqwcVWIl4xaZwcUFXBAzDFMdDZSG+mJyUJrMk0hEX/k25LPC8bY2va5z4eujCOjw7RS5mD5ejB0ZZRixJZ7gVskajJcxaeAjXjAqG+Mmq8RBOjrr7/O3AJ856DziIwmsJF/uvjDH/4QMsRjGwUgXY09Eu8+4+LW0+cyQ4veRncnqpny4fZFR/a4w4V8DAlnJk6W52ePZTxYZQJf+a/JKtfihRKQgAQkIAEJSEACVSbQpnnSaUM78Ie2IoaOKQtRaeTksh5xahI50Hv2WEQvHtO3NX9Eb2RvKybIkWhFBBwKjAVJuHDXD6XdnWqRmnjN6b321sMOmSmXjO3aaOzezpcep1oyqfkjeHBXc6Wd/LK55C/FXqfWzX50bp+K6tr7OeTdYZ2as3YNKpAZIVF7AGBGRUQhF9Hiz75+GLKVH534QRQk/rR8ZaA76ch2/DHX5KbcItKZQYQcTEtJyEhL4mz5S2h3QNcW/FEyr7BkXTbTyO+galK5WzVPatGM+ZvKX+QRCdQ8AX4kEw3E5IA4CGYJxGuUaYPf9ggyfiRjGxEopPLxS548QWaCIwqJfFKsItajzFU18hZ3Sa9+97vf1UhtdVkJToTMR7bYRjEs+KzaVorop8P792/brt3bH300oGfP8SOPOVCWZ4FVdm7u82+9tXjVKhQez1gFKi0WbLTPk8njiukLj2tsdBiujYRoFBUPbZC80VX73CFqj4g/4v6ImuSTQlbsCy+8EJQiHxliGGkOR4acIiiSaEHaxScSrIpfJkYVRRVFt+Efg9AkkvTMM89ERMa2jnQrb6D4hFb8+UJWnrhrw2iztgz53azaTLjfpEmTmMKPFitjwegGXUXzoeqohzi7YAAZFDaQg7H9ZJ9e8cpzHnk9xh4CMKOSMAm3gC8NFncmazi2J3wcCHCOCuNeYcJ0CvhH3ChzLPAvGUxXynAQpgRmRtcyXlrnXnCv6Ri6M6okrh1aJKIzzIcYjZebFRbvpiq6HYYZV7UUBiM3l+R3ulqFZW3iba6hlVcpNrQ77nglIAEJSEACEqi/BPBjTJXIX1xdxHZV4aq4mogtTFRAZloSf7EHa3YfDoRVpiV/JZyQJnCIbVvuznKqTItVwAJMlq6Ols+uTCuWkUDNEiACiERdfr0TH8TP/tjKEQr8dOcXPlaF2Dd+Y3OWn9lhvWNivvjlTxBW7CU1tR/0EL2qqQorricIi9hXyvM2HAn70es+T1GADT0R8iKDdkGgRFPUhQK19MqEemPHjPnr3//+6KuvdunQfnCfKv6LSy11b2/VFpeUTP3gg5lz5ialpODCUHJ7K7m348gvfBDptDyu1113HVFvUUk84//8z/9gFdkQSRVLuugqdkIyMuVRYEgoJgrASCKzUIrcXOwbZfhEEO3LhwVfGZYcCXFq5MVjlCiG1wst0iVEG+KPDw6OkiBWtClluJZiNIGEYp8nh2cmCsTjbbB1VMsWdY+SRGVi3rmKa5GApDwzNQHmlExqNBlAKBM9w9GFe9whVDB8wIlzJOYRi0qdqFgUKkjLqDGsGbnMBBLy5dCtWzcKYP8DDbpKu/QZrwpqeoVmpT8kgwfJCC7K8BqFi/KW7xkQ4QdplAcYnoyLjz/9h3Zsh/GwAQK3gO8u3jLAQI8a2OcS3vLKVdTMPjvwZJ+NfZoOuDDXfIkxBGIhuR0cRxkT40kZblmVp3Rg+ChdnjQEMY9xNEyqdas+AZVi9RlagwQkIAEJSEACEpCABCQggZohgI/ARGC7+DnNr/Tgv0LV/BoP853xUx9VEdseHgFzQWJy+MUee6pG9lESpJFSP7/JgxOJzEgFb8uUoSeVKYxKoFjYyu/HHvmiVGnKZJny4Qj0sDxEb+FiMCzsc4RYLTwUhAlcqhE4FVfSrkOHcSee+MH7pUuc/P3Z5zpmZbVr1ariS/b7WRTap4sW/fPllzfm5Jx+xhlE3aGf4u0VEo2wQW4EMojgWQxgVAO1MR8oBUhLZybEIPiis3vbQUsxDyAfCuwYmpJPAbaIKRqJ26UVjoSEXAxX6C33Go3IskWc5fMSRdKh6kKL5MOi6vBNWMV77rmHOFZihJFiQRriK5H1aC8KsIU8az5f+DjmXuRzyuVsUW9pDlXKfAW0jrmLuocQxIQixbCE9CQqX/EOlRAZyoOKYqNvIXCPlYhefvnl8hcOHToUUcj217/+lehCeoub45mnJPsYOvqDTyQsF4DcFEIm+XqhJN8boOCjAZOwojeQGSArLNM0HeYsLpUAT2Y84CPGTUT8xXYgLKdDDc888wyj4y1+kK8pdgCIv+PTxz0Ka79Aj/5wOeVhBRbqxPTxbyc8JEyHSsApJX//+9/zbUM9r776KoNiZ+LEiQCPbbfy+wD8v//7P5bwxqL+5Cc/KfPvNJWvx5J7JKBS3CMWD0pAAhKQgAQkIAEJSEACEtg/BPjRzu9ebAteoIw6DB3iZz9b+c5hMfZ4vHzJeI9QM4Ljt7/9LdYAC8ArG5XwGt7yGrsT7YcCu05+Kf6is9FObDEOxtu9MuVRFUSoIYMwFwR7ghEngk/EkmA6MBfIhTJmpEwNNfv20D59vn7xxctWrpw5Z84/X3r5qnPPaVZVP1KzHdtbbSvWrr0H67Ry1THHHnvJJZcQp7a3khUcxyuhuXFSZJfH+kQuwSIh44h349YwySBBdhXUEx4eCnBDKX/LLbeUKczDiS8jro3J8jjFs0SwIQdxYThHGqIGbCOqkVA7ChBzx9lQkpkZsVeEwjHTImLxscceC5VjLb/73e+iFHmEmKX07rvvDsd5ZYZBNiq5+uqrr7jiiug4vozj9957b3Qk7DB2fCIl9/hZLlM4egs3ZCvxoU8//TQSkIEzCoITeYZRbFGxsMNCxsymiiVk6gM2BCJH4I8c5GuEDeBIwxEjRuDX+HTg9QhjRIxG9ZAazHcOWpZRENp56623RqfCDlQZMhZy9OjR9CQ6SydxkQQwAhBNHB3/5je/SXmUIr364x//yNyX0Sl2QM2cjOxQ1bhx44AGJfKsWRYGm8nZn//85+Eszwaf2fPPPz82IDS2qtj98DUSe4R9HrM1a9awg9zke0ClWIZPNd+WfRarWZ2XS0ACEpCABCQgAQlIQAISkEB1CBCgRLQUCoBf/qQ9RlWhEiJXQvAO9jD8tscC8Ludt5iL4EqiS2pwh5qxijVYYY1XhUJCoxCMRh4rq4LgEch2xHQQ34TNIdSOkDQMSMUCq8Z7RYUpqalHjRx52WWX3fnnP7/47jsD+xw6etAg9EdttFX9OlmP5cEXXvxk4aJ+/ftffvnlCJ0q1EnIHgYQ8kSDIqHK13DqqadyvyhDSCBncYIEwKL/YlN6cVJhZZVwyyhPhCnFeOCDOuf550NBgBvLibBFOa34KWYGwCVRgBpAjVLEDyKVaAu/Flk5YhJ//OMfE+XHXIF8pnCO9JyrqCH0hMeejxWBw2WGgNqje7EHuQolF7oXKqFdRBiRgGPGjKF78T54XIiIpCGEHUIcyci94Bn+5S9/iSqNbRppe/311//lL3/h4adRPqeXXnopfSAVGlZ0jO8NXhk1k67y3ULIHqcoDHyO00nGQp30nyMUYxTsUAOthALQIKoX5RcmZIxa59of/OAHTE+JlgVvuISDUTH8JreVvOzoktgdSjItbDjCN973vvc97hQBj0Rlcou5C9j/b3/720CIruLrkXtK52MflWAeCavkYYhKhh2EONAoz1rV9fwbrEzPD4i3pZntB0RH7aQEJCABCUhAAhKQgAQkIIGDkgA/+3/1q1+RtEhs0fe//31+VKMI77rrrkcffZTx8qsbHRbipEgh5Ac260EzDRzLPiBH+OVPSibRTPyyO/nkk1k+BS9wUFLa26CwGAgXHATQCIsjz5T8UJAig1BaiCSybnEKeI291VA3x1Gc3LIH7r+/T+fOv/rOtzt/dTGQuunDPlvZlJ395yeeePHd93r07v2f//mfBI7x+O3zqjorwEPOvSYEFfeH6uL+8rSjlmrEz+LUkGK8Ui1yimppIt6h8RwS2IgqpUvUQPfwYlWoJ7ZdaqNjKEXMIN6TiEI6SS7wDTfcEFuMrwIsamBC6/SEjwZ+MGxl+sAHBMvGRkk6yRYxBDJ4GQWv7NMuZzGDUYHYRqN9hC/ekBBIilEYgHwAo7Nx7TAQWqdCRGeNPH5UxVjCF0JcPbHwPgkYpbhPRBaQgAQkIAEJSEACEpCABCRQpwRY65nwLnIecQexDRODc/rpp5NgyLSGN9100wUXXECBP//5z/zyRyUQQ4S/iC1/EO8H8YHCIJCTzFAyK0kOxTcRqoZvJQeW4DICoPZLWOIesROEhTImF/XNqVPvevLJ6y+9NCM9fY8l99fBLTk5f3r88Rfefbd7z17oKp7AGhE6NTgcvBi6iq0G64yq4rNT/Y9PbXQPqVcmIjLqc+wON4t/Y4iOVEwJz0hyN1tUPtoBMhx4XKMjldlB2BHyWZmS+yzDQMoHG+7zqgoK0De2Cgp4qsoEVIpVRueFEpCABCQgAQlIQAISkIAEaoUAEoHwOvIZy8xBhgIYP348k6ARiEc6JBvNB8/CXHLMEtgQfjkTtEXMEQFWmMS3336bsESsIhqCwCjSXUkyhUO8QqRW7mK5SkllJQqV7OzJ06enJidfd/HF9WdSxZy8vNsfeeT5t9/p3qsXtppU3/rmE8vh9IAEJLCfCagU9/MNsHkJSEACEpCABCQgAQlIoIETwAky9RiBObxGHgf9xLoHTAtIPBGJhwERJYm8IyzxzjvvfOX/Z+884Nus7/yf2JYtWbYs771X9t4hCWSSBMLeq5TZlh5tr8e19NpyR68tvf+1tFBGOWbZK2wIgSyyyXYSJ473npIsW5Zkefzf8pMoiheOt52v8Ms8evSb7+eRY3/0+X6/X35JYCNnePXqq6++77773JOLjUqkKIk80BBREhFbKbbANpFfSZEGKwKc09LS+m40G1B0RLWjKuIB/GznrtiIyBtXLPceBv4pi83259de+3DbN0kpKaTqI5We6z4cUBoyeC8I8JZXHr3oK12EQP8SkFyK/ctTRhMCQkAICAEhIASEgBAQAkJACAwGAbKh4c4jcxnRjkgMgzHlkM5BUDN1G6gsQXFbJUkcqiuFNfAkUsoWi+KQru48JidVHEV1f/7zn5cVF//77bdfvmiRl9dQ5iu0Nzb+4aWXPti6Tevn9/e//50qFheC1/U8Lthwakq5IWq2EO9P0gPSqg6npclaLkQCIileiFdd9iwEhIAQEAJCQAgIASEgBISAEBhBBMicSD2K3bt3s+YZM2agIVIKdvr06SPUmEm9iAMHDtx7770tDsev7rpr3eJFHkMkCiNMP/r88+u3bNX4+v71r38lcpyknCPoxpClCgEhMIQERFIcQvgytRAQAkJACAgBISAEBoRAK7nVBmTgYT0ou+ZxAW58WF8VWZwQ6CcCSIrvv/8+tU1Wr15N6PcoCMslgnvXrl0/+tGPxra0PP3wL2ePH99PqM5jmFqL5TfPPvvV7j3NLS0vv/wyeiJR5OfRX5oKASFwYRMQSfHCvv6yeyEgBISAEBACQmC0EGhuaT2cX7s9s7rCaK822+ePC75+YYyvz1AG0w0m2kN5tW9vL25obArW+YyL9puXFhwVpPb0EIFxMC+CzCUEBpYAwc5MMJqyyFGtmwI7DzzwQERo6LO/+Pf0+PiBJeg2Op/BUN/57t/9LjM3Dz3x17/+9U033dR9jWC33nIoBISAEHASEElR7gMhIASEgBAQAkJACIxsAnZHy+cHyp/9NNdidSAstraO4W/FxVPDHr4uPcBXNbL31uPVf5tt/H/vniysbCB2kPhBxMSZ6UG3L4ufEqfzEGGxxxiloRAQAoNMgOrPr7/++h/+8Ifw4OBnfvmL9Li4QUiLyb8TNbW1P/zjYxk5OQi16Ik33ngjpYEGee8ynRAQAiOdgCfl4Uf6HmT9QkAICAEhIASEgBC4MAkgHdbUNT7y+vH13xTXWx1Nza0t6IltXzPHBc1NDfL28hiGZBoam1/cmP+bV469vrnwUJ4pRO8TGaju4zrRVbceqaoxN7L9lpZWUJTVWHccr/Hx9kwM16qGJYc+blm6jwgC+fn5KDVUUBkRq5VFDj4BCqFQpZrvmzZv3nrgwOxJE0MCAgZUVURPrDAYHvzfP2dkZ6MnUuuDB3fpgE46+GBlRiEgBAaBgEiKgwBZphACQkAICAEhIASEwIAQqDHb//jeyT3HaxDUXBNEh/nOmxh8+azIyCCNK/J3f67xha8K1u8u3XCwYk+WISzAJzTgnAT8uPxe/NrZILOkTufrRQPXgP1+wGp3Z9Z8m2Ww2pv9fVWTEwLiQnz7OIuPyrN5bGtz65h6W1OjA611DOqqrbH5RHGdn8YrOVLr5SmaTh8ZS/fzJnDPPfc88cQTlGOmMLGU0D1vfBdGB4Q80heOHz++oLDwUEbGjsOHZ4wfH6LXD1C1FozsZdXVD/31b4ezsvhBuWbNmocffphi2aInXhi3m+xSCPQzAa9+Hk+GEwJCQAgIASEgBISAEBgUAg325h2ZNeiJjiannkh47+wJQT+/Ik3t7emj8iCLosrzbCbB0hrroVPGcoNNaZkaoY0N8fXXnP1VsKTGuiezxmhuNNXZpyYETIwd2D3wp6xT9jvzve+Tabw9r5obvXpGBDSQR1/bVJhbWo9j0VjXuPFgRSwya1pQ32eREYRATwjg/NqyZQvFc0+cOEE5XcoTq9V99eH2ZF5pM0IJIOfp9fr/+q//wipICZqfP/7Xx378wKTkZC/Pfk6Gi55YXFHxH08/c+iMnsikAQNsihyhF0WWLQSEQE8InP09sietpY0QEAJCQAgIASEgBITAMCFgqGt8d0dJY5s/kcDeZTPDH1ibHOLvQzLBjg9yLKK1KeIjr+48UTM5MWByfICrZXPz6QaOplYCh13nR8oBu0ZFVcrRLJsSptN4vbgh/3ihGVUxs8B8PL92WmKAWtXPf5+PFDiyzsEhgHp49OjRTZs2bd26tawMK1h1c3PzpZdeGhgYKBawwbkEI3cW7pDQ0NBf/OIXFLP+y1/+8vDfn3r0B/dPSUlRefXnH+zkT3zslVcOnDhBjZs1q1f/9re/DQ4OHrnQZOVCQAgMOYH+/Ak15JuRBQgBISAEhIAQEAJC4AIhYG1sPlZkxojHfr08x05N0aMnhup6Gq18NK+2oKJhQqzOFRk9mrjhWJyTFmRtbHn164Ks4rrGppYDuSYQzUwKHE3blL0MHwJ2u/3w4cPr16/fvn17XV1dQ0MDZxCJgoKC/vVf/1WqXgyfKzXMV4LAR9llch0++cQTj/zjud/cfdc00iz2k6pYYzI98+67Ow4d9lKpbr755nvvvRcRc5gDkeUJASEwzAlITplhfoFkeUJACAgBISAEhIAQ6IQAVVk+2lPa1BbyjIJ27cKYnuuJDEcSwyP5tQQ7dzL0qDiFIXH+uODkSD8lH9mx/NqjeWYHqRblIQT6lQDOxJycnGeeeeahhx769NNPbTabVqttbGwk0hlh6Oqrr46NjfXs7/DVft2BDDa8CBCGTPHlf3vooTq7/fcvvvTxN9vrGxr6vsRKo/GZ9977aNs3Kh+fBx988P7774+IiFCGLS4uJlS/71PICEJACFyABMSleAFedNmyEBACQkAICAEhMLIJkA+LFIFHc2vZBikUQwPVc88/UeDeLMP88UFxoT2ti8Kk5oam/KqGgkoLgma43ichVBsfpvFTq7qhScB1Za09t8JSUNVAQPaEWP/USP9u2rteQvyzO5qLq60F1dZSg5VtxgX7xoVoWHCnkd2ujq4DMkVOTgo4km8qqbI22JpzyuqRUBPCerpf1zhyIAQ6JVBfX48zEVvirl27ysvLMSQuW7bswIEDmZmZ/v7+Vqs1JCQESZHKG512l5NCoCsCRMpfddVVVPV57A9/+Ps77zQ1N106f75Oq+2q/XeeL6+pef7DD9ETPVQqxMQbbriB21XpZTab//jHP15++eXp6ekif38nSWkgBIRAOwIiKbYDIk+FgBAQAkJACAgBITDcCZDusNrcSDljFopF8ZJpYUoOwZ6sW6P2am52JlWsNNqyS+tnJAcG+HanCSpj1jY4vjpc+cW35Q22Jou9mVBidVsFGD+115UXxayYGtZpALXR4nhja+GhHFOtxUExGYYixWFEkHrptPDu/YKUhMZESd+aWjvTsVNkRI23l9bHMyHS777VSeEBnaeMdCeAgjknNZCaM0iKnDfUNxrq7SIpuiOS494RMBqNyIjbtm3bv3+/xWKJj4//4Q9/mJSU9Morr+Tm5uJPnDJlCq8uXbo0ISFBLIq9g3yB98KrePHFF5PX9o+PPfbc+g/ICYuqGODXG1WxtKrqpY8/+XT7Dn1w8M/+9V8vuugil54IZGy2BQUFf/rTn8jh+OMf/5jC0179FGd9gV9B2b4QuEAIiKR4gVxo2aYQEAJCQAgIASEwegig6FWZ7cp+vFUeFGju+d4oBh0TpS2rsaHWHcytnZkaNCNJ3333UoPtta0FO4/WUDa6Y0sciyeL6+5blaT2PiejTpnR9tLG/K0ZVaZ6BxGgSsdK45j8ioaxnmNtbQpjx9E4Y7I4Nh2pfH97SV55fdM50qNzy3kVlnKD9cErUtOi/LAudjqC62RkoCbY3xs5kvnrGppwWbpekgMh0AsClZWVO3bswJl46NAh7F0xMTH4EBcvXuzr6/vPf/5zz549CIi33Xbbhg0bOMNLUui5F5Cli0KAW+iSpUtxuT799NOvfPZZUXnZzatXR4WEnBefksrKlwnI39GmJ/7sZ0uXLWNY9xFw1P7kJz/59a9/zV2NvPjAAw9MmjRJrLXuiORYCAiBbgiIpNgNHHlJCAgBISAEhIAQEALDkUCbpNiorMzLY2xkkKbnq0RfI8ngtycNSIonCp0FXibH61Se56iB7qPVWZv2ZtV8ua/CbHFwnu4+3p56P2+6K/WjCysbPt1TOiNZPy89yH2cz/aVf3O0mgBteqH9hQepg/y9zQ2OKqP9SLbpjMboPpXzmEDp7NK6NzYXMixPmU7t7RmiV3O+wmClLDVZIA9mG5/fmPefN0/8Tm8mhWvUPp5enh4s1Wx1iKTYHrc87zGB0tJSNBf0xIyMDJPJRB66W265ZcmSJXFxcYzx/PPPf/DBB+iJd911F8VYsH1hMUOaEYtijwFLw04IIP8tXrLEX6ejBvSnO3c1t7Tcunp1dFhYJ007O1VUUfHq559v3PttUmrq3ffcgz+xnZ5IJ5VKxfnf//73WBR37txJUsUf/OAH06ZN8/HpabGvzmaWc0JACFwoBERSvFCutOxTCAgBISAEhIAQGDUE3F2KRBxjxDuvrSVH+FWhJxbXWaxNxwrNM9OCErvOMEj+wY/3lCl6IvLcnHFBa2dGcsCZD/eW7jthYOraesermwsmxwfotaelSSyKe0/UmOqdeqK3t8flc6LmTwgmwpqI5uNF5o37y7NLnLWqOz4qTPavj1QVVTn1RI2P56z0oNUzI3S+KjI5Vhhtb28vPlVUhxy594ThUJ5pdmqgu4jZcTTOaNVerBZJsd7aVGd1qqLyEALnRaCoqAiphceRI0fImajT6dauXbt8+XJCRMl2V1NT89prr7377rtYce+55x5e+t3vfocuc91111Gn5bwmksZCoCMBpL1Zs2ZhJHzzzTe3HjzIxyw3r1oVGx7esWW7M4Xl5a9/8YVTT0xLw3s4Y8aMrlRCzuO0/fOf//zb3/529+7dzc3N9913H5OKx7YdUnkqBIRARwIiKXZkImeEgBAQAkJACAgBITCsCSApVtc6o4CJ+8WIRzrF81ouEcozUgKP5NViUTyUa5pXXNeVpGhtbCbfInHNjO/pOTY+XHv3ysT0aGd9FWyDoXqf/PKGapONp8fyzNll9dMS9ayHp7tOGsoMNtpwfNHE0MvnRqVF+yn5FlOi/MiNSC5IxcBIA/dHmcGKtxHR0MvLIyXG/+5Vic4AZ8yKzmotLYH+3g+/eLTR0Uzc9I7MmqmJetV3bd1P44U0WWdxWG3NfLnPJcdCoHsCJSUlxDJ/8803hDmXlZWhsCxYsIAMiQsXLoyOjsbehZ6ImIjW43A47rjjjiuuuCIvL48EizSbPXu2h0eX5t/u55VXhYA7AZIbcjtRs+Wpp57acvAgUcnXL1sWHRrq3sb9GE3wREHBGxs27D56DD2RRJ907z5DIvfqihUr+E5SxX379qGJo4/PmTOno6vRfSI5FgJCQAiIpCj3gBAQAkJACAgBISAERhgBpDprY1tawLF4VsZ+V0bBTnZHnPKWw755ZRasf6dK6+akn67+2a6pxdZUXNPgcLRw3l+jWjw5VNETeYo+iC1x2fSwt7cUogBiA8wut0yM03l5OkW+kyV19TbnCgk6Xjg+ODFC66rfEqhVIWhSs6WjpEjmRE4qGmWgn2rVjPBxbfIl4/AgC+Sc1KApKQH7TxiY8VSppamZhX2Hpujt5aFqUzkJmuZLGUq+C4HuCdTV1aEMkhIReaW4uJhYZmxcc+fORZpJTEwk/RzdDQbDRx99hEWxoaHh1ltvvfHGG7ElfvHFF1SCvvLKK5U23c8irwqBHhJAEBw3bhyy9V9Npg2796BuX7V4ccSZqs3ugzTYbAdPnnz36027MjISU1KIYkYZ7F5PdHWnZDmh+n/729/Q0J955hlSK86fP1/Mti4+ciAEhEBHAiIpdmQiZ4SAEBACQkAICAEhMKwJkD+ReF6WiLLW0tKKF/B8VcUQf59xcTqMirgdjxaYT5V2Hobc0Nhc2WaHZC4/tSdCpDsXPFiLJoa8s6WodYxTqish12GbLZFjV6bFIJ13RKCa8tDuHaMC1RF6tfsZ5djmaK6pb2RTPIho1mq8jhTUujdjfJ8zvkSKtLB391c7Pcbb2NjkbOblNZavTtvISSHQjkB1dTV64pYtW8iZuG7duokTJ06fPp20idThVVriT/z4449fffVVxEfExJtvvjk8PBzxkS5paWnYGNsNKE+FQN8JTJ069e677/7HP/7x2Y6dtkbH1UuWxIefk1exymjaeuDAx998cyw3Ny4hAQkSHbyHeqKyPHKAoir+3//9H5I6E6EqkmkRSb3vi5cRhIAQGJUERFIclZdVNiUEhIAQEAJCQAiMZgIqL48Q3enc+U0trQ32Jr82hbHneyaSeFZq4L4sA5LiqZK6rGKzp9c5qp8ylK2R0tKn68BQWjoy8BwdEItkXMjZ4qFlNVZXgWYyLSrHgTpvyrm0Wxh6aKeVVRrszoBopTF1nz/aVdouVSLp6nLLLYrmWFvf2ANFcQzlZajowpi+THqelNotW55eOASQDufNm4c4mJycHBsbS85Ed68WguMnn3xCiWej0UjOROq0REVFWa1WoqSRGvGFhZxnWd4LB6zstC8EEAeJqefHIJLfFzt3VlRXr1kwf1pams7X197YeDQ3d+PuPdsPHy4oL+fWvfPOO3EdnpeeqKxt0aJFZFdELt+2bdtzzz1HGDVnSCHal5VLXyEgBEYrAZEUR+uVlX0JASEgBISAEBACo5YAwbyhutMlWXDqIcOdr6QImuQIbXKkX0ZebX1DE6VaAvw6qfGCK1Ap60x7EhqiKp7DdOwY5xmcf21mQfRHl2mQWGmneXLMGJbasZo0+RbJzHjOUG1PqMHicMYyOx8NtqaDp4zKcaffFWGx05fcT1ptTfZGp6SIjkleRfeX5FgIdEUgKCho1apVZBXoWNGiqqrq008/RXBBT7zqqqvQE9EcGYd45w8//DAlJeXSSy/talg5LwT6SACJUPHAvv766zsOHMgvKZmckhyk01ltNiTFjFPZjpYWKrHcdNNN6Im9jr4nVlqj0ej1+s8++wz5ktSKFDcXVbGP1066C4FRSUB+rxqVl1U2JQSEgBAQAkJACIxmAuh07i7FcpMtoeuSzV2BUKs8JyUE7DtlPFVcd6zAHNBZ2Wgm8j8jwyEvUjQ52F15bB3jrAR9RkekdopLJ0RqJMUjqiJxx65o6K5W4jpPUDOZFpWnODEjgzUhAZ0InUoDP42K5bn6dnqAUxKhsy3l4hh/Xy9/39ODd9pYTgoBdwKdlrtV9ETyJ5JIkWIspFCMj4+nl91uP3z48LFjx2644Ybg4GD3ceRYCPQvAUVVJBh5/fr1GzduPPL5Fz4qFV5Cu8OBCHjx/PnXX389ORDRBPsy7+TJk3HmMuDbb7/9wgsvULmFdKK91ij7shLpKwSEwHAmIJLicL46sjYhIASEgBAQAkJACHRCACkt9EzgM5rdgRzTvLTO66t00tnt1JSEgORIbU5JfYXBVmvB3XJGHTzTRuPtERpwOsKa6s8EHceHno10xlSYWWI+03ZMVJDaVYNF5+eNFRHbosFsR9RztVEOMBh26jHU+niGBZyOraYYy4QE3WWzI9v1dT1FEv3OUtfFNdYqs12ZC21Ud0YedQ0iB0Kg5wTc9cTLLrsMPZFSLUp3s9lMKDTHhIj2fEBpKQR6RwBVcebMmYTnx8TEbN269eTJk42NjcmpqRgYV69eTcrFXsQ7d1xJUlISNznSJBr6iy++SFlzvIoUnu7YUs4IASFwwRIQSfGCvfSycSEgBISAEBACQmCkElB5jQ3y91b7eNrszUT17jpec9slcf7nnygQXTI9xn//KWOVyW6xtpWQPheJr4+Xq46KuaFpR2b1ogkhaIVKq8amli/2Vyi1WTiD2kh9Z+WlUL0PRsVGR4upzlFc3UAlaPfkiWarQ6kHfe5sY3AmBmhVyr4cza219Q7iuxPCtO2a9fzp/mxjbtnpyjNUpHHpsD0fQVoKAYVAZWUlQaBoK2RLXLt27W233UaaReUlLIr4E/fu3cuZSZMmCTEhMDgEiLKnKBAC4tGjR7kJEbgpIkRaz36cnSyixFCrVKqXX34ZryLFzVesWBEaGtqPU8hQQkAIjGgC3xEtMqL3JosXAkJACAgBISAEhMCoJEBaw2B/7ylJzuKzhBWX1TTszzH1YqcUaZmeHJgW7d9VX3TA+DBffVtMtNXe9O0Jw8ZDFRROYVLKtnz6bdn+kwbFA0ib1Eg/l9o4JT7AX+OMMiboeNPhysN5JltbQkPO0H3vSUNWSV3HSZEqMUVOa6srjVR6NNf02pai3VkGo1slFoyUdbYmQ93pwtAdB3GdqW1wHCuorTDaOEPUc1KkNuyM49LVRg6EQE8IICN++eWXZK/jABcY1q3U1FRXx9ra2i+++AKjolSxcDGRg8EhQCQyMc733HPPAw88gNLdv3qisgVinwnnp9gL9znC4kcffVRWVjY4u5NZhIAQGP4ExKU4/K+RrFAICAEhIASEgBAQAu0J4FJcPSvywClTU1MLkcXrd5akR/m1q8jcvk9nz5PCtanRfgeyjUpZ5HZNiLBOivCbPz74871lSIeVJvuzn+UWVjYgaJYZbZ/sLcOHqHRZNj08KkXC3UAAAEAASURBVFjjCnyekxb4+be+lJOmusu3Jw0UbiZoWq9VtbSMKTNadx6vyS2ztJtLeRoTolk7OzK7tL7aZKdY8xd7yziemxYYGkCgs9MdiZpppJx0S+sdS+MJju50EE7am1p2ZtacLK5TCk+Pi9OROLKb9l2NI+eFAErK5s2b33zzTQKfKb2Cnpienu7CQsBpdnb2jh07CAilGq/rvBwIgVFDAOESVZF0ii+99BKFzm02G4lEibkeNRuUjQgBIdBrAiIp9hqddBQCQkAICAEhIASEwJARII3g5PiA1Bj/zPxaBLYDJw1vbSu6ZmFMbMj5peRHZUNuiw/Xnig8mxXRfVfhep/VsyKyiuuIICbZYlmN9YUNee4NOB4fp7tmQbTGTeAL8vO+eGpYicFaUmWl145j1bsyawiF5pjVUllFq/ak0nT73I1jxrAvMjxeOityw/7yKqON2Orj+bV8MYuiVyrFXnx8PG9YFNOVREjax71ZBmTWvHKncKnx8ZyepE+L8mu3bHkqBL6TAHWct23bRrxzSUnJypUr0RPHjx/v3stkMn311VeojcuXL58wYYL7S3IsBEYNAUq1oCp6enoS/szbgQjo6667LiEhYdRsUDYiBIRA7wh4PvLII73rKb2EgBAQAkJACAgBISAEhpAAiQv5QjtDp0NoO1FktjW34CtEUGNVyG3ER7uWd6Kk7lCOiZLNWrXXkslh7sqjn49XYXVDVkm9EsIcEuAzPVmPe1Hpi5AX4KsK0nmTS7G2oQlB0DUmB1qN16zUwFuXJ0yK03meybGoNIgJ1lDuxVRP2kSKkbYyOIZBNETKLs8dF6z3U5UZbDwPC1TPSAmMCzlb9cVX7Yy2pvpzc3NLvb2pqUlZl7Oiy+kjvIrNrdcuitH6eLltcUyDvbnSbC+sslLG+vUtRZmFZsiwmAkJAatmRbh25L5+ORYC3RCwWq3YDylMkZOTQwq522+/vV2qRO7s3Nzc5557zsfH59577x03blw3o8lLQmBEEyCjIno61Voobr5//37eHRgVg4J6UxlsRHOQxQsBIeBOQFyK7jTkWAgIASEgBISAEBACI4YAiQ4Xjg/aNT4YDyASG4Ldh9tLDmSbSBqYHK69aFJomltyw8ggzfxxwSQlDPDzDtF5u2+S9IVz0oIoz6LIhdGhvuH602WXlWbUSl42NYwyKR/vLas02pAsiXdGskSdDA1S37QoloBrd2nP1euWJXGRQep9J43VzrrPzaiTdIkO1SyZFFpaY/X29EAJTYzQYml0Xw9KKAPevCSWVW044PQqEtnd0Ih641QzES5xMqKcunfhmMDtbUerjhaac8ot2cV1dRaHYoEkHHvFtPAJMbp27eWpEOieABHN+/btI9IzKysLByL1WNrpiXRHVTl+/DgGxmXLlpHSrvsB5VUhMNIJeHt7X3/99XgVn3nmmbfffhsPL2kc3fMAjPQNyvqFgBA4XwJjnR8Zy0MICAEhIASEgBAQAkJgBBJoaW0trrY+/uGpYwVmU12j+w6uuyTu/lWJfudfBtp9kI7HFGJGHyTLIdZFqp10VBI7duGM2dpUa2mkoHOg1luJVkaXtDlaSI9IikRXUZdO+/K7qsXeVFlrt7flbaQ7mRx1GlW7qfMqLL9+5eipktP1nRnKy8sjOlhz1YLolTPC6dLp4HJSCHRKAAH7wIEDTz755MGDB5ELv/e971FXt2NLxMS//e1vu3fv/o//+A9sjB0byBkhMPoItLS0rF+//u9//3thYSFq+49//OO0tDQ8jKNvp7IjISAEvpOAuBS/E5E0EAJCQAgIASEgBITAMCWAoS82xPfhG8a9tb14X6ahuq6xtr7R0dSK1EhpFCXtYP8uHREQC2Fk4PmNqtN48eXeB6chX+5nujpGOkQY/U5tlJotbJxIbw/Psb4+XoF+qphQ3zWzI/BmfmffrqaW8xcsgRMnTjz99NOoikuXLr3jjjs61RNxZlDlOT8/f8qUKUuWLLlgWcnGLzQC1Gm55ppr0BDR0zds2FBXV/fggw9OnjyZmOgLDYXsVwgIgXN+txMcQkAICAEhIASEgBAQAiOLAIpbiL/PDy5NKpwZufNkzdG8WnO9o6m5BeHPVX95ZO2od6vF6pgW408hbLWPZ3SIZlqyfnqinpDqdmbG3g0uvS4oAmROfPzxx/fu3XvJJZfceeed06ZN63T7SIpEgFKShZBnAkI7bSMnhcBoJbBu3TpURd4pu3btolrLAw88MHfuXD8/qYI1Wi+47EsIdE5AAp875yJnhYAQEAJCQAgIASEgBEYWAUKkRUAcWZdsGK62oKDg0Ucf3blzJ3ri3XffPX369GG4SFmSEBgmBDZu3PjnP/+ZfKPEPt933328awICAobJ2mQZQkAIDAIBqfg8CJBlCiEgBISAEBACQkAICIEBJyB64oAjHu0TFBcXP/LII+iJBDJTwVn0xNF+wWV/fSWQnJwcHR2NpMiDUkVarTYuLk4ioPuKVfoLgZFDQCTFkXOtZKVCQAgIASEgBISAEBACQkAIDAyBsrKyhx9+mCjOxYsX33///aInDgxmGXW0EUhMTIyPj0dSJGMAquLYsWNTU1NFVRxtl1n2IwS6ICCSYhdg5LQQEAJCQAgIASEgBISAEBACFwaBysrKn//853v27Fm0aNGPfvQj0RMvjMsuu+wfAjgTk5KSTp06lZeXh6pIasVJkyaJqtg/cGUUITC8CYikOLyvj6xOCAgBISAEhIAQEAJCQAgIgYEkYDAYKC5BPZYFCxZQu1b0xIGELWOPTgIxMTGkU0RVJBspBdMrKipmzZrl4+ODaXF0blh2JQSEQBsBkRTlRhACQkAICAEhIASEgBAQAkLgAiVgNpspw7J///558+ZhVOyqvvMFSke2LQR6TCAyMnLcuHHZ2dmoisRBZ2Zmzpw5kxrQHh4ePR5DGgoBITDCCIikOMIumCxXCAgBISAEhIAQEAJCQAgIgX4hQITmbbfddujQodmzZz/00ENTp04VU1W/gJVBLkwC4eHhhDzn5uaiKvLYvXv3lClTQkJCRFW8MO8H2fWFQEAkxQvhKssehYAQEAJCQAgIASEgBISAEDiHQGNj47XXXnvkyJEZM2b88pe/xJ8owsc5gOSJEDh/AqGhoUjz6In5+fmEP3/99ddYF2NjY+XNdf4spYcQGAEERFIcARdJligEhIAQEAJCQAgIASEgBIRAPxJobW1du3YtpSSQP37zm9/w3dPTsx/Hl6GEwAVLICgoiISkRUVF2BUtFsvmzZsjIiLGjx9/wQKRjQuBUUxAJMVRfHFla0JACAgBISAEhIAQEAJCQAh0QmDVqlWkeyNI89e//jX+RC8vr04aySkhIAR6RSAgIADzL4XUeZfZbLadO3fyFiO1Yq8Gk05CQAgMXwIiKQ7fayMrEwJCQAgIASEgBISAEBACQqDfCaxcuZLStMRj4k/ETuXt7d3vU8iAQuBCJkBOUp1Oh/nXZDJRp8XhcBw4cMBoNC5atEjSlV7IN4bsffQREElx9F1T2ZEQEAJCQAgIASEgBISAEBACnRNYsWIFRWlTUlLwJ2KbUqvVnbeTs0JACPSBANIh5Z5RFSmClJGRQepStEWkfEzBnO9GWKRc0quvvsobkxLSfZhfugoBITAYBERSHAzKMocQEAJCQAgIASEgBISAEBACQ05A0RMTExPRE6nyrNFohnxJsgAhMFoJoBtqtdrJkyc3NzcjFDY1NVGzBXkRQZ8qLl0VbCFK+p133qG0C+/T4ODg0QpH9iUERgcBkRRHx3WUXQgBISAEhIAQEAJCQAgIASHQHQFFT4yLi/vVr341b948X1/fbqxS3Q0krwkBIdAzArzFeKNNnDiR9ALffvst2mJ5eTkHOBApA91pTSTeoaiKlIomISPiI917NpW0EgJCYAgIiKQ4BNBlSiEgBISAEBACQkAICAEhIAQGjQD1nanHQrxzdHT0ww8/vHDhQsxToicOGn+Z6EImoKiK6enper1+x44dLS0tJFjcvXs3yRZRDFUqVTs4iI9Wq/XEiRPHjh2LiYlJSkrqVHls10ueCgEhMCQERFIcEuwyqRAQAkJACAgBISAEhIAQEAKDQYAkbmvXrqXyLMYo9MTFixd3n8ptMNYkcwiBC4mAoioiIPIe3LZtG6qixWI5cuQIB+PHj/fx8WkHIyQk5ODBgzSgWnRCQkJUVFS7BvJUCAiBYUJAJMVhciFkGUJACAgBISAEhIAQEAJCQAj0MwFKQ1x77bXHjx8PDw//xS9+sXTpUtET+xmxDCcEekAAVZGKK1gOiWveunUrYiLvTYT+2tpaVMV2WQhIclpfX5+Tk3Py5ElipePj4yWpYg8YSxMhMAQERFIcAugypRAQAkJACAgBISAEhIAQEAIDTQC14vbbb8frhOnp3//938ml6O/vL/HOA41dxhcCnRJQVEVch9gVURWp1oKqmJeXR3ZFREPCol0FWzhAZOSdS4Xo4uJi0hSkpqZKUsVOqcpJITC0BERSHFr+MrsQEAJCQAgIASEgBISAEBAC/U/AYDDcf//9+/btCwwM/PnPf75mzRrRE/ufsowoBM6TAGHOCIhIhNu3b7fb7Yj+HOAjJrqZMtBeXl7KeLiJjUZjbm5uZWUllkbsjfQ6z6mkuRAQAgNOQCTFAUcsEwgBISAEhIAQEAJCQAgIASEwmASqqqp++tOf7tq1Kygo6MEHH1y3bh3VY8WfOJiXQOYSAl0RoCQL4c/EOyMm8la97rrrKPG8f/9+optJtkh5FjpSkgVVkdjn/Px8Ph4gFBpvI+/irsaU80JACAwJAZEUhwS7TCoEhIAQEAJCQAgIASEgBC4UAmRDKy0tfffddzdv3ozziCquHcu89iML4ih/9atfUQWCUMof/vCHV199NQf9OL4MJQSEQB8J4EbEdYiq+Nlnn1VUVPAmxVC8Z88eykBTlp2si4yPpEhkNEZFGlCnBRUyLS1NPhjoI3npLgT6l4BIiv3LU0YTAkJACAgBISAEhIAQEAJC4CwBtIDdu3c/8cQTGzZsoIprRkbGqZMnU2JiAoKCBkIdQLt89NFHv/76a8Kc77nnHgxQGBXPrkaOhIAQGB4ESJhIXkUioPnJgFdx4cKFR48ePXToEJHRfOpA5kRkR2yJJSUlqIp8FMHnEIQ/S52W4XH1ZBVC4DQBkRTlVhACQkAICAEhIASEgBAQAkJgQAhgMtqyZcuTTz6J/6jJ4UiOilSNad136FDmyROqltbE1FTCG/txYio5/OlPf0KhoJ7DnXfeeeONN5KdrR/Hl6GEgBDoRwJ8qICqyAP/MqrixIkTiXQ+duwYaiNeRT4V4I3c2NiYnZ1dVlZmNpv5eCA9PV2JjO7HZchQQkAI9JqASIq9RicdhYAQEAJCQAgIASEgBISAEOiSQE1NzVtvvfXaa69lHj8+NS3t7ivWrV6wYO6kSaGB+g3fbM88kTm2pTV9/HgvlarLIc7nhaKioscff5w4StKu3XbbbTfffHN4ePj5DCBthYAQGAICSIoENeNlrq6ujo2N5YOBzMxMSrKgKlJbCRmR86iKGBWRIDEqUshlCFYpUwoBIdAZAZEUO6Mi54SAEBACQkAICAEhIASEgBDoAwFUgHfeeefVV18tLS5ePnfunesuXzpzZmx4eHRoaEpsbFhQ4I5DhzOOHrVbrckpKYiAfQyCLiwsfOqppz755BOysN1000233nordR76sHzpKgSEQP8TQCh85JFH8Czz84HReeMTzsx7n7yKCIUEPnN+xYoV1GMhSYLD4SACmvP0QlJEaqyrqyMUetKkSQRH9//iZEQhIATOn4BIiufPTHoIASEgBISAEBACQkAICAEh0DWByspKirHgTzQbjeuWLL51zerpaWmeHh70QD7Q+PikxcXp/Pz2kjrt8GGr1ZqalkaEY69VRfTE55577oMPPkBPJHni7bffjr+p69XJK0JACAwNgdbW1ldeeYX6zkeOHCHAGd2QNy8CItHNEyZMwKKYlZVlt9uxItbW1qIwWiwWJEU8jCaTCVWRlkQ9U6RFPjAYmusnswqBDgREUuyARE4IASEgBISAEBACQkAICAEh0FsC6Invvffem2+80WS13nTpquuWLU+NjW03GCkUqdCi1fgeyso6eOQIauO4ceOwLLVr1pOnBQUFL7744vr169EarrrqKvREBIiedJQ2QkAIDD4BdEPeoWRZPXXq1I4dO463PVAYMSFS7hlbIlHPxDiTBRWdkWO0xZSUlLCwMIq08GbHusjx5MmTKd4y+IuXGYWAEGhHQCTFdkDkqRAQAkJACAgBISAEhIAQEAK9JFBRUYG69/Zbb411OG5YueLGFSsiQoI7HQtVEanRV+1TWFZ28PARtUaD1nC+EdBIDJie3n//ffSFK664Aj2RvGydTicnhYAQGHICOJFxHVKGJTk5GbMh5Zubm5vz8/PRFTEtYlHElsh7GesixVj8/Pyo04I5kWhoCkMT7IwKSRUXzMhYGkNCQoZ8O7IAISAERFKUe0AICAEhIASEgBAQAkJACAiBfiBQXl5O9PG777xDZsTb1qy5bNFFgf7+3YzrVBXj4kL0+pyiQspA22w2UqqhI/QwAhrdgdhqHJHoDmvXrr3jjjuIl+xmOnlJCAiB4UCANz5OQ4zJaItohXwMgD9RqeyckZGBmIjOyA8TDjjv6+ubl5eHqkizpqYmFEa+o0uSUbGHPyiGw5ZlDUJgtBIQSXG0XlnZlxAQAkJACAgBISAEBopA65gx9sbm7HJLfmVDfqU1p7w+q7S+3GSvqXPYGpttjpbm1lYVsaxjxw7UCmTc4UfAXU+8/bK1l1200K8Hgcxenp7JMTFBOt3uw0e+3b+fVIs9VBXRE19//XUyNkJi9erV6IlERw4/KrIiISAEuiTA5wcEQU+ZMiU9PZ3PAzAtIiAS6YzZGYWR4GjqsdCGR05ODhkV/P396+vreZUz06ZN43uXQ8sLQkAIDAqBsWRIHZSJZBIhIASEgBC4QAnYm1p2Ha+pMdvZf1y4Nj3GX6eR9DcX6M0g2x4FBOyOlsLqhpIaa3655URJncmChthidzSjJAb4qvx8vUP8Vb4+nv4aVWiAd6C/t17rrdPynZNeaq+xns76HPIYhQQUPfGtN98k3vmOyy+7askSb5XqvPb5yqefvfDRR44xY26++eYbbrgBFxLew65GcOmJuJkuvfTS733ve0gSXTWW80JACIwIAlRfIbSZIOhDhw5xwNscSZE4aD5mICVCSUkJGqJiWuT9/pOf/GT58uUjYl+ySCEwignIH3Wj+OLK1oTAgBAwNzi8vTx8VJ5iPRkQvt0OWm9rqjDZjPWOWoujwdbER0JqH0+dr0rvpwrV+QT7e3fbe8hetNqb39hamJFXywpWzooI1nmLpDhkF0MmFgK9JdDS0mpqcOSUWQoqLYdya0+W1BWWW9wH0wdomlpbDBZbYZWN84iMLc3N/r5eoQE+oQHq8EBNCN/1PhF6p+aI+Oij6lItch9WjkcEAUVPfPPNN1tstmuXLVs5d+756ols86pLLq4yGddv3oL3kKfXX389VZs7VRXJn/jGG2+88847LS0tq1atIn+i6Ikj4j6RRQqB7gkEBQXNnTt3zpw5iImkVty3bx/lWYh65qleryeXIqoiCiNx0zgWSbwokmL3POVVITAIBERSHATIMoUQGCUEGuzNh3JNWSV1Gm/PCfG65Ag/fCijZG/DfhtNza3FNda9WYajBbWYgyqMdmNdY2tLq5/WK1yvjgrWJEdopyXrpyfqVV7D7q90pM/mlla+wNzYjC4x7HHLAoWAEDiXAM7EvArL7pOG7cery432Okujzd7sauLrqwoN1KYnhflqvFyZrRqsjto6m7nOZmxoLDGYbScMBLTq/bzjQ9XxoZqYYE2Y3icxQhsd1JsKv66p5WA4EFD0RDS+BrP5mqVLr1u+rPv8iV2t2d/X9/a1a831ls937iRDIvfSjTfeiFexXXumI3kieiL+xJUrV952223jx49v10aeCgEhMHIJ8N7HlsjjoosuInMiwuLOnTsPHz6Mh5HPGAiIZmu8/bExEiIdEBAwcncqKxcCo4CA5FIcBRdRtjBkBIqqradK6/mOxOP+VW60GTGR2Zvx8Q1EJimkGUdza3MzglIraaoGzS14KK/2iY+yvzpYsSvTUFPXmBrtF6LzGTL6F9LEFlvTsSLz+ztL3t1ekllgrjTasSiizCHV2RtbasyNhB/iATxVZuFP9Pgw7XBjQ1DkxoMVlSZn4HNSlN/05MAgv2FqqBxu6GQ9QmDICfCTprah6UCOaf2uki0Z1R6eqoRovYenh7nezk8hLy+PIL3vpLTwmZOiU+KDwoK0IYG+yldkqH9iTGB8VGBkmH9okB8eRv5BRGcsKLcczDbuOWng3xRCoVMi/YbhByFDjn0ELcClJ9YZjavmz792+bKoPpRh1arV4cFBNbXmXDxKmZlYlhLaAh5dQMit9vnnn6MnOhyOSy65BH8iJRpcr8qBEBACo4kAtsTIyMiZM2dSHpqSLNR6pmCLqu1ht9v5Ewgjs2RQHU1XXPYyEgmIS3EkXjVZ83Ah8HVG5cb9FXg32i1I5TU2yN+bUC98fBPjdMmRWkJT+zFB/cFcE6olkqKv2nN2ahAJqtotYICe7soyVJpsisdsX5Zx3VxbWrR/P+5rgJY90ofFn3g4v/afXxfwR7iS/Fbj4xkc4OOvJvBjrLmhqdpst1ibaJZfVv/ZvorFE0NH+pZl/UJACAwTAvwDp/ijNx6srDI7EmKCYsP9W8d61tY7NGoil73CQ/2S44MnJId29W+BRu2lUfsjL7KjBpujorq+uAK1yFBZU19Wbd2eUU3Shhkper4Pky3LMs6LAEUSqO9MnHKdybR6/vxbVl+aHB19XiN0bDwhMfGuK9ZxfuuBA2++8YZGrSZVYmBQkNISSRFZISQkZM2aNcuWLZs8eXLHEeSMEBACo4wA73Qqt0RERFCOidLPpFOkOnxeXt6mTZv4+TDKNivbEQIji4BIiiPreslqhxeBMoOtqLKBkpcdl5Xbdgr/4IT4gMvnRS2eGNKPee5e3lRwMMvoaGoJD9b88Q7NoEmKvt6enh6n/2wk5Bk9q+PG5Uy/EygxWDceqDhwysjIFE9Fqp6eEjg9VU/YIBHo1Fo9mGPam+ksfkII4SVTRE/s9ysgAwqBC5RAY1MLCRPX7y7NKKjT+qrTkvRBAZqTBcaCUqPKyzM2Up+SEJwcE6j26ekvk75qFb5FviJC/A5llpVV1h3OM1WZ7WvmRC6fFhahV0t2xZF1q5HL7P333yfe2aknLlhw6+pLk/qsJyoEzqqK+/e/8MILePJXr1kTGBjIq4iJFHeeN2/euHHjJOBxZN0wsloh0BcC5EC47rrrtFrtW2+9ZbFYJkyYgFsR92JfxpS+QkAI9J1AT38L7PtMMoIQGMUEEHoC/VTobeyRX3yJSqYeRSP/ax1zLL+WShpeHmNXTg/vrz+WEBMVt9ogI106OZSAtRPFZpWHx+xxQXFhvqIpDvQl4E968id+26YnEt8RGay+ckH0FfOiA85UTJ4Yq1s4LviTcN+9mYa18yJXTQt33oRjxlBFR8ld6FohxRBQhLl1KM9qsTVzE3l7jfVXq7Tqs0qx0rjO2sQXgjjXd6zHWCrxoF2qe1aQhzuzwd5EGRkC/xGdCXDW9FhuYMX0sjjfOy0sFdla6+Op9pZ8na5rKAdCYPAI8C9YTrll/a7SHZmG9KTQ+Ch9Zm5VRlYFPxYiQvw5kxITqNH00iOfGh8cqNMcz6nKKaypNFnf2lqUX2FZPTNickKA/5kfboO3VZmpVwRqamrWr1+PP7HeZFqzcCH+xP7SE5XluKuKL77wAiexJerbVMW0tLReLVk6CQEhMLIJhIaGXnHFFf7+/pgTiYa+8847R/Z+ZPVCYFQQEElxVFxG2cRQE0D1WDM3ijq2LAQdx2xtKq5sOFVSX26wIo4UVzXsPF6dFu2XHu2M/Bq5j6QI7YNXph7Jr/VTe46L1ul85QfIgF9MQg4P55iqjM7yqTqt16qZETcvjmvnD8WmesNFsSumhlNKVVkQQfGf7ytH2nNf37q50Yh0OWX1e08ZKbPQ0Ngc5KdKifCbkhiQGK5FNDzdt6X1QK5px/FqhHIydRLFj3wZGaiJDFIHaFWUgummJo8dT1NxXW55PUpEcbVVq/aamazntgn+rpBGorYram255ZbCyobCamtNnZ0Ma7HBmvgw35QoP/yYFBl334scCwEhMKAE+MihsKrh4z1l247WhARpm5tbvtqZ3dTUQpLE8SlhyTFBftq+pkNlqHlTY6LDdUdPVRSWmL46UJFbWn/1RTHzxwVFScGWAb26/TF4fX39p59+Sn1n8ieuveiiW1avTopuX0Sl7/MoqiL/EhEB/dKLLyJnr167lqqvfR9ZRhACQmCEEuAnwLp16yj0PHi55EcoKVm2EBgsAqIIDBZpmWdUE6DG5dpZEegyrl0iLH59pOqfX+efKq7Dt4UMd7KkvqOkiJsMMcXW2GxtbMaihYtM7e1BBvuOuepxb1GPw2k/a+vSZkSjbwt2MPxornmVAyROlwSDzY1kWM5CHmceXp4eqEI8x+2IGU3JBcm8Wh+vdj5KKvNSGMS9r7fn2FnJzt/mUbXYoysO+szY7f/P36UEhlsbW1iGh8cYnG5IV+1moQ9DWdC/2tbI3rsyxKGC8Tdt2+weDNJxdqYDJsVAup+u/SqH8fNjhWYKs7BAPIPj43SLJoW00xOVteMgdOmJnOHGePazXEq4uO9sfFwAIuMzn+YUVVrdr+nMtMDvr0yclqTHS0t7bsXDOcYPd5S49+XYx9tzYkLAlfOiusp6xi26J8vw2DsnTJSiPnO7bdxXHqjz/sFlKWjr7QZ0PWXG7DLL+p0lVP5pl0bAW+UxKVF/54qEKfE6sSu6iMmBEBhQArx/y4z2T/ZVfHmw0lvlSf7cY1kVwYHaCalhqXFBAf7q/pqdwZNjA0P0msyg6oyscj7wePKj7CN5oXevSowNkTLQ/YW5/8ch5HDLli3UXDZUVl6+eDH+xMQORZn7a1ZUxfuvuUbnp92wa7cSAb328ssl3rm/8Mo4QmAkEvDy8tLpdCNx5bJmITAqCYikOCovq2xq6Amgdi2bEnqsoLaoqsFqayb22WxpL/yhITpr9VY25FdaCiobqKFM9HR8qC8Z8ZLC/UiZdyZvoXM73xyvJlmeotRUUyOlTbIx1zu2Hq2i6nS7Dc9KDXTJl4x/KNeEeuhqExWsXjA+BL0ps6ju22xjucnpgIsL8aWSzKR4nXspXsK3Nxwo71h/hvYRQerpiXqq0LiGbXeASkiALT4XwtnyqxoqTHZUy/gQX4TX5Ei/iECnbKh0YSt1tqbPvi1TdocbbsG44I76kc3RQoXQ0horvUL1PlPiAxjENSnTUWUbjxsw2XJlLdN5JoT6JoT5tpvO1WVEHJjqHZRBYKk+Kk/qomIO7dGyx4719/VSdEObvVnR9/LKLZ/sLS2ptiJKIiuj8QGN0fZnGXECRgdrItt4ogxyxRF2uRz859Sx2y4MYt+BLENOad3auVH3rExs51VkqB2Z1Y/88zhqJmMigMLf03Mss6AwbjxYzhXpdOWo3RkFtS9tzGcZSkdPDw9FsGYouh/MMnDD//TqNO6KTkeQk0JACPQvAVODY3NGFT+THY5mfhRYGuyT0iMmpoZFtZVY6d+5GA2Ncuq4cH5o7DlchH1644Fys6XxlzeMDwuQgi39DrsfBqQ6Cnris88+m5+Tc8WSJbeuXp0QFdkP43Y9RHJM9A+uuUbjo16/efOLL76o8vK6/Ior1BoRnbtGJq8IASEgBISAEBgsAiIpDhZpmefCI4CqGBPiG+jnY7U1OBxOcQQBx10lRGR5c2vRu9uK22VGpI7zqtmRD16e4opFBd4LG/MLyyztWiIU0r0jWvQXVy3m/aeMT32cjWvP1Wx2elBShN/+bONf3s9iVa7z1BH+/urE2y+Od50xWx3PfZaLMug64zqYkhwYHqDuRlLE//jpt2UvbsxvsJ7jlcN3NjUl8OEbxkXpzwqCbOTvH2Vj2GT8sCD1pAcDOkqKqJNvbS08mG2iTUqM//1rktwlRYLNP95T+srXBR2nm5EW9Ivr0iPdpnPtYvgfWG1NCLusU6dVhZyrMnezeLJ6zpsYkl9uoc3RHJMiHRLOXGFwFgoPDVFHhmhyi+sUsZI2vDR/fLAiKSIg4rrlKnDPcF2Y3d62AGU6unyTUTUvPWhu2unim8p5pnjxqwKiI5WnSJbpyNP+3rlllpLKhv0nqVWtCJvK62e/I1/uPWE4eMp5WXk405LqvEMD1XUNjtKqBlZLtzKj7d0dxSIpKojkuxAYaAIHc2v5cWqqdX7a5KvxnjM1dlJKmNdAJh+geHRaYojBbD10rJR3Pb5+qpD921WSL2+gL3Vvxs/IyEDXO3LkyGWLFl2/YvlA64nKEkP0emq/GM3mj7Zt+3LDhnHp6ZOnT+/N6qWPEBACQkAICAEh0K8EJDtVv+KUwYTAuQScBS5OW/HOfWHMGJQUYz1VMs6R25RGiChUz6g02RUrYvuefX7O+Dj+zA1N7TQeztc1NLn7GXs9FXn9ncZMpnAqQuc8OGF3NFfX2t1VToQkV6w34hTaYvtuEGtCsDp9mqhnRCvXuPg9u5mOUOhqc2O/7Ms14+AcsFsXB1LGQKmH83LfBWpVoTqfEB1e19O9wA4/na8K70+Ivw9ZEV26LX/D40ZUHkjhOo0zZyKKLV8kNcM3Sp5Q98Z11vYqM/ezizAzon6G6LxxvBKOHehPFP7Yszs5dw+sigvkNES2RdOTFzI8UB2q8w53juBz+q5odQbp2xydlFY/dzB5JgSEQF8J8NObt2RTUys/OVQqT61GRdIDZ6mmAX7w883H24sZmYcfR3yYwedSAzynDH/eBGw2m8lkstvtWo1Gp9ViGDzvIXrbAd874c9atZo11BgMmCV7O5L0EwJCQAgIASEgBPqNwOD9KtBvS5aBhMDIIUD8ppvwdXbdSDv7c4zPfp57oqAtTV6bOYs/qDAhIu7wpxQZ6CgV/fSPZrgS5KlVHsgrikuRgFCX5MYUHfMTc841GWqOt7czcyImSUWSQ8ek+MbrmwvJS4gwR1tFDOLPyHe3FmFAm5kceLr72DE4U9zFu2ZGcalcrjnOPaDBqdK6l78q2HK4UnmFrTGPsjvmOpJt+tWLGf9x8wTF6cZag7Tek5L0+08aGL7GZC+ssoQGkGXrrGjIOIdyayuMzuBZFjw5PoCiH8rgTJdVUv/SV/nbjlR1Ot3hU8Zfv5Tx8E3j56SeY6xTGg/n73hIuShOd+uYMQQyo825r7bT66BceO6KH1yapDReeaKm1uLUCw+dMnIV7lqdtGZWpE7jRV7FR147vv1YNbdcpdHuCsxHyLvtkji+XHOR6zCzuO6D3aVbD1WynnKD7c0tRUunhLnESiTgg7mmwjZTJL0igtX/c/eUxDAt0/F0x4maJz88lV/e0FFf5tU9WcZ9OSYuIqMlR/ndsjR++dQwOnKvEpj/zBc5+04YuGcKyht2nqhZOjnMtSo5EAJCYCAIZJfVbzlSWVbdoPX1To4PnjUpOizobJrggZhRGTPAz2dKerjN5jiaVUFejp3HqoP9vb+/IsHdrT9ws8vIPSHQ2Ni4bdu2J554Ijc7+6pLLr5tzZqEyIENeXZfVahe//116zw9PN/btOm/f//773//+1defbVGwp/dGcmxEBACQkAICIFBJyCS4qAjlwkvGALoLEVVVmOd08+FKuftRf3c05svM9i2ZVQpeiLqCWpRWJAGIxi2vqJyS72VKiOt+Phe3lzw8ytTFeFm2fTwjMBaRV1CG2qrmuKskTIhIYCQ2HZQSXR4ZqoxiVHaS6aHGesaCXqlVgwtq8x2khISIBzo7xMf6Sz1m5FtVPwgOAff3F7skhTRMVH6qADjGv9Efi3Lcz3t9ACtigrXisCHmEjSvVC9mkBaYniLKhowuEGGxJHPfJ47I0l/2oY2dsxlcyPR/hrb5LOtx6rHxej02rOSolNgKjDDhBmxzKAnutJsUddl+9Gq7RnVvHR6ukB1WKCaP0qZrr5tuqpa+3Mb8kj+6PJCdrry4XaytsHhoq318XQvsY0rkFfbLZgbzE+tImdlu/PKUwTK1fMikQLREzlDSeX0ON3xojoDjlFHsyIrd9qRO4QrRXJP7uGPd5ZyczbYmg31jVgdlfbYHz/5tkw5RvD9lytSSZqp6ImcXDgu+ECOqaauxBVn7ZoFJTG7uC6/zJkMVK/zXjkzYtX0cOVVuk+I87/9kvjMfDMQyPB4JN8skqILnRwIgYEgwD8BB3NMvGED9RrExJkT+7+GbzfLDtH7zpgY1WBzZOfX8G/Whn3lpM29el40/9J100teGhwCDoeDFIqPP/54aVHR7WvXEvIcFRIyOFO7ZkFV/PEN10eFhrzw4UfPv/ACHzBefc01Pj7DK+cmH57ByrVm5cDb+5xPBJWTTXyu6woQaDtF0QkPKtkN4kNZLctQ4RD2dHqEh9VDWV5zczNXeZDJDCsOshghIASEwHAmIJLicL46sraRQ6DVGavLl7JipajFvhzjQaS6Nt0nhPBP3elfKJFRqJfydZuDD7kwLcb/vrXJ89OdBjqkmUN5tf/9ZmZZtZVqGF/uLbvt4jglw93tF591jd3/1IGMnFq8isF69U+vSJ0Q113JjlnJgXwxOLmxfv/mCfQgg7mRAOekKL+fXJXKS6h1J0vq7v/bAUJQSYWXW3K22Eug1vuxOya5X4Z7/7b/SJ7TU9bN41B+7fbMGiZCXYoO0dx4cdyVc6P4mxA9NKfc8vjHp/ZlGnDGFVc2bD1WtXyqU0Li78VLJoT+r7enEg29/Wj1rUviiIF1zULFFfRExWVJ4ePYMF/Xn5jkAdyBvbFtuphQ35suiV03+/R0WaX1f/ske/8Jg1PerWjYdrx62ZSRZHNjU3wpEPjfmUNnlfAtR6p+88+jLj7KgZ/G6/ZVCXe4ZcN0b8DlWD45zJ1qapQfRZzLjTbSdwafWwmBi4WwzXcmVVbgr/aaHBeApMiY3Cr5lVaXpIgOXGJwpl3j4av24qZqJ90uGBe082h1R0mx3t5koXpM2wST4nSzUwNdbyJlNLIxTk0N3HGkihsDIV45Kd+FgBAYCAL8gN14uPL9XSV+WvWCGXFp8UNQECkixG/OlBhjrbXaYKkw2t7eUpQQpp2TesY4PxDbHuox+SGL+w9NBzkJTWd46iaKnvjnP/8ZPfFH11935cUXB2gHw7va8eL4qFTXLF3qMdbjH+vX/9///R//elx33XXIYR1bntcZNsiFaKfocQYxi0vDdeHRwwGJCt+4caO7qsiwl156aUdV8dtvvy0vL3f+K9v24NJPnTo1MTGxhxP1SzPC2Hfs2FFWVjZ79uxJkyax1H4ZtvtB2HLH8JpOu5jN5q+//rqwsHDt2rWpqamdthmqk+yCe0N5sAZ21O7+GaqFybxCQAgIgUEmMBj/cgzylmQ6ITD4BLBQUZH5RJsHEAXGYHEcKzAT3muqb2QxSDnTkgLGx54W/mrq7Dll9RRr5qWYMM01i2MUPZGnhPpSyPhnV6Y99PxhfslE0yFLvSIp9uOm0In0fqrL5kUqUiN2MJLuTUwOOHjSgGylLKwv0+WXWU4WOO2Qfr6qi6eGXbsgWhkNCyE1i3+0JvlHeWYshJjmvs2uVSRFGvh4e8yZFLxlfyVSaaXBRkWOMP3ZqtDEibtKBk9L0lPH2bXC3NL6U4Wnp1s2PQxLi2s6yl4T//sv+c7piNjdn20aWZKiv8ZLqz79UxpfqrmDLdEFQTlA2iMLZ7uTrqcUXUFyJa+h68ziCSF8uZ4qB9x46HfHi82bjlRlldS1xUQ38mcusrjLK0S2NUOd894+3aWltcp4Wu9LiPSj0POZV07/P0ynxvHa7iRPeYO4NkUtoP25pmNFzkvpeuCopUQ1TzFzVLcVi3C9JAdCQAj0L4GDeabP9pYZzI650yKGRE9UthOo06QlhNQYLfwsojgYpeRnpwTyz+hofVRWViKN5eTkrFixYu7cuXFxcWgTqEs91FwGAQuy2nvvvffUU09Z6+p+dsstaxYuIIviIMzb1RSoioRdw+fp99577rnnaHbjjTf2RYolLeMnn3zChVi0aNG4ceNctseKioq9e/eWlJRwXWbMmNHVetqdRwX7xS9+oaR6RG/iVV9fX0buKCk+//zzGD/BizjFg3l/+9vfDrKkuGHDhqeffjo/P//yyy9/8MEHB1q2AwhkyIbJZgla717BpNmuXbt++tOfIhnv3r37zTffbId6CJ9yvVBjT506RbWizMxMbr/Y2NjFixenp6er1WdrDw7hCmVqISAEhMCgERBJcdBQy0SjmQBBxM9+ktPVDuPCtYsnhyaGn/4VvLahqaZNaqR9UrjfijabnqsvhUeSI7VUvEVWQ/srqnHqKf3+oFjzkgmhrmEJJZ6erMe9yO/oofpOwnNcLb/zAHWVQGnFW5ce7bd0ytlZ6MufhfjO5k0M3rS/gkYl5+5u3azInYermto0sW3HqpMjtIF+pxdzOMekRD1r1J7oidT9UFZC1LNrugmx/hdPaj9dsM5n7oTgzQcqsL+VjjSbm9bHy5fCCG0PJEVK0CjHynf3P7FPmxzcX+5wrPfzdgUjd3jx7ImjhbXkwSSRmeIJdb1Qe+amdZ1xHTB7/Zm1BfqpOv7xj32yo85Id6PF4arAcCjbxJdrzHYH3FF2u/NvM3kIASEwQARySi3ZpfXREbrEmKF0BfprvcclhZRUmguKnTb/XUerr5gblXTmH9AB2vvQDksA7PHjxzdt2oR0gllswYIFa9asQVoaJqoiYuLLL7+s9vT83Q/uXzBlymCWZOnqujhVxYuXaHy8n3rn3WeffRah6tZbb+2q8Xeet1qtr7766uHDh1G4EIbcJUW0VFS/n/zkJ9OnT+/h5aD70qVLa2pqWBV1sS0WS1cLYEwuPR7VgoIC7IpdNRvQ88h2LIApOOAxoHMxeF1d3X//93+/9dZbq1ev/vGPfzxx4sRuZkRsra93xs1woPDsi3DczUS9eAmH6W9+85usrCzW5upOmtF/+Zd/4VbU6/Wuk3IgBISAEBj1BERSHPWXWDY4xAQWTAq5c3nCpPgAlwCEhkKtZ5aFCQFtkUCzdks01jeiH3ES01lxm0WrXYM+PiWxY1CAN/kWXeOQXO/uZQnfX5rAmY56kKtZTw4wnSneTBoT05pRaM6pOKcso8nSSIpJXm2hKojhHMF0VkqQVuNFMRDMKd8crcbeqEiKOBarTHYl2d+UJH1MqMa1ErJPuoS2elvz4YLaU2eKhChtgFlU5VwAAlml8ZzpXIMM5wO1jydfNnsz21REVVaLPDdvfPBzP52trLzMYH3q01zKKXS/kQAtLljXbdh52+NFZvREAs/5BL7zFv161seLokPfsSRlQmpYuzyS/boEGUwICAEngZzy+sO5Rsqqx0bqQwelHks33PU6zfik0JLyWuzJtdYmPmEaxZJiWFjYr371q/vvv59o2S+//JL6JxiynnzySTSX22+/fcqUKT0Pue0Gaa9f2vTVV8hq6Im/ufuueZMnDwc9UdmLt0p12aJFIXr9E2+9rXgV+6Iq9ppPx44BAQFknOTfUMSmxx577KWXXurYRjnzgx/84L777uP4gw8+eOaZZwjv7arlwJ1fuXIlkdrZ2dkc4LAbuIl6MTLuTnx/P/zhD4uKim655Zbhoyd+/PHHf/zjH7GvcpV5/44fPx6La15eHprsO++8k5yczJu3F/uVLkJACAiBEUpAJMUReuFk2cOOgLeK33ZOiyOE9GIwZIkB/qoV08InxevOvOJcNvVJ0Lk4wHhFWeeTRc6iz+4PxByCfznDLyuuOrzuDfp4TJ47f42qnZDD4jsJTD3/mczWJlPD6fotJ4vqcsjMeO5M7I4oH+fuxrSilLnPQIXni6eHf7SjhDySZJOsNNmjgrC3jSUrZXWdszALjxnJ+rjQsyFXlCjB9am8lFlodtaf6Wq61vbTKb2G+XetRoXMCiirrTm3zJJX0ZAY7swjSamWiXH+yuKp3IJ58zs3Qgz1uTW02/fg0uzMrNmXZVD0xPRY/8vnR01N0Af4OtNUUY+FmkIvbMhr3w0ZmiB3rVdtWyUi5PKeq5HB/j567WnDKc7cKcn6mOCzSrf7RIih0cFno93dX5JjISAE+k7gaKGZ3B3Bel/qO5/7Q7TvY5/3CBjn46L0aYmhx09V1Dc4dh6vueGiWE0XhafOe/Rh1gHvG+Y4hAmid6+88krsil+0PT766KPPP/8c0+JNN920bNkyl3VuMJd/ZP/+Pz72WEV5+f978F/mTprkPSiJ9nq+QT6XnTFu3A0rV/z1jTedeRVbW2+77baedx+4looKzJXtXgXjVaXBEKrGkZGR1M7md1ZuwiFcRqfXAoChoaEEPnNluw+R7rT7wJ3EXIlwbDAY/u3f/g1DMZ5EAP7P//zPu+++iy5MYkrU5OEGc+BoyMhCQAgIAZEU5R4QAv1AIFjv88fvTY4PPS15PLsh78t95URskZcwt7zeUBcYojtbkRBdx1W8AuVRqXHcxSLGeg/AH1EqlbPGdBcz9vU0CqDqTCq979qds2J1u/nWzoigKA2SIr9B7jxZkxSpJcb5wCljjdkpwgb4qWJDfKkT4urFXD2eDptbv6imrskH4yA+zDcu1LfG5FRUSdC55WhVYng8x4BzBWE5k271x1pIW1ZhtFvbdN5pKYF3rIgn26aXM6OXc3gqdxO03uk81DIP1WsUSbGg3NKuxApdqGrZqc5IlLRSfpo2lJOenhRw+ezITqdgu+66fBdt5LQQEAK9IWCocxzPM1cY7NMmBCMp9maI/u4TqFNPGxdRUmGuNVtJ1YqJkgpO/T3JMBqPH7OIJn5+fjNnzqRKxt13342uiGlxz549+/fvDwoKWrduHeJFWlpax5R8A7SN7IyM//yv/8rNzX34+3fOnjCBWOMBmqgvw6q9vS+aOrWsuvof76//+9//XlVV9bOf/awvA3bfF+WIYiZvv/02ghEiL4IX6hI1VaKiorrv2JdXka5IKXjw4MGUlJSrr75auQGIIMbQykm0LSKI243/zTffcNuQoLO2tpZe3FFz5syJiIhQhDl+v8IXeezYMfdeRGFjCfT3P/1RJS8Bk3G4ASZMmIARj7uR2HAitXHOXn/99Yjgru6c/OUvf0kANVgYAZseo5GW0T2r4GeffUZ3wsBZMx2Rzv/xj38AUBmEA+L9J0+ezFOj0bh9+3Yau8Zn2SzgiiuucJ1xHXBFNm/eTBjyyZMnSc7I1NgteZu4JHjowerAgQPsd/78+QS2b926lQSIOAp5r9E4MTHRNRoH7AVTJBtnhWRLpDubCgwMRDdkjwqfhISE//3f/wUjo/GeVX5H4lin05FJkyXxkvuYcjxMCCD1EnSPLRcpn+ShXFbl2mE45Rbi/MKFC2NiYobJamUZQmAEETj7l/kIWrQsVQgMNwL8m0QlDQJLlYVdNjsiq8ickVfLLxWbj1RNiAtwTymI5yvkjDQTHaqZPzGEFHed7oj41snd/hFFJcJe/NqCnxJ5qNMZ+36SgsKuRIeB/t4TEwNQxDod1sNjTFhAe0saNYhDAn2IDWdnO47XIDDBtrSt/jWDTE0OJOrZXT/D44YspYwfpGM6fWzI2bBo93mZLkLf+UvuzYbb8ZQE3bREfUauCZ3OVNf41cGK8ED1qmlh3xnC3IuNNNidRWyUjmpvp5XVvZYLlVKwi3Y6LGJfbJgmu81va7E6dmfVkNTSvW9uuUWJ5W/XnV3otE4bpsXaVF5j23G0moo6VChq10yeCgEhMKAETpaacyst+gBNVLhOox4WyhGflOj81SR2RFK0OZqzR7uk6Lq+6BfEeyKOYE686qqr0F9QjlBzyGb4xhtvzJo1izx9S5YsCQ8Pp6WrV78f1JWX/eUvfzl+8iTllZdMn+Hv2/m/4/0+by8GDAoIWLNgQZXB+MaXXxKRiiKA4NWLcXrSBdGB9HmUNKExv5wgTJD+EqMfMdc8FHmiJ+OcVxskNhQuRECuO8qyIimS/3Hfvn3cEtHR0e6SIhri73//+6+++ooGqGPIW1SYYZFobcTXo/QhzyF4odl9+umn7sugRDWyo7ukyLzkkaQlkiL3Gxq3knURURUC2EI5qYyA9EYmUJQ7nsKEKZgRtY6Y5fh454egPBD+qIHD1MogxcXFpI9UTJq8igjIRhRJEdmRNRNB3NbP+Q1pklDijpIilV4ILWdhCHmsH/7MQkfmVQQj+pKEsbS0FBmRZlgItVot7yYasxI2snPnTpyGSK7KXEzNq48++iiLpA30ePAS60Q6fOihh5RmPGXBynnloiO/8lble0hISHBwsCLdKo3l+/AhgKRITgneIyyJO4Gbiu8cc2O88sorpDTldhJJcfhcL1nJCCIgkuIIuliy1BFDIC3KPyXaP6fMQqFhAngz8msnJ+ioqqxsIEDr5TItUn+DWpYzk7vMhe+uy7j2T7ELBLIxzWNwQSoZBl0v9eiAvHTuslyP+vS0kc5XRTlppTVmTIK+r13Q5Sd+HXUxfItLp4a9Xl2IAlVUYamqtWeV1dfUNSqf+M4kMDboHFkQGTfA97R1jukQ4K46U/G544o7TtexzXA7Q9HrWemBGQW1+04a+OA7v6z+mU+yD+eaLp8TiSsWIRtNmTSRHY2BvdgIwdTaMwHUp0rqD2Sb0qP8uAPRrfMrLa9vLdp1rEYZ1tHcUmq0Er8foPVGT6TNVXOjNu+v4FWu1OPvZWm8PeemBXGep9R7efHL/K6ygl40MYRwy82HKtnF/lNGCkkvnxG+bGpYhF6tXC+bowU1E4nZ5QLuxdakixAQAt0QqDY3YlIODfQNDfIdsH8cupm/85d81ar4SP3xrAp7Y8vJknNqwXfeYRSd5d9oVEUeF110EV4qMu4h4uDzwrSI2kJ6PtQfDDVUIsZo0+/7brFan3/mmZ379qXHx924cmVESPDA/c7Q98XjpI8JD790wYLM/LzDp7L/+c9/Igpgeev7yJ2OgOnvhhtuQFskfR5GNqpCU0KE6i4Ii8uXL++0Sx9PomqhcCER8t1lf+MAzYuT7jVVaIlignKHNIawhesQ8Qt3HnZFfHm8hKqIFsbVpAI1DVgYLjykyby8PEVlc1+qMi8NuOUQ9XBikmyRxgT2MuDrr79OSLKr/TXXXAMHND6YMBryIpH7OBlRWhXl8eKLL+YpDRDycBQiNaKPu6yOKHFJSUnKaIh38+bN4+bnKeoPtz3bZHmuuVwHH374IckBuBCsDQciuyYPKUolcieV05XtswuEJAUgAiKCLLcHjkKKNVPnGi8nnlNFUqQlOSX/8z//Ey0VkyO3ENcayQlcLJuOLucjC3AX9AFC1DNqJrOg+OPidK1QDoYVAd413CRKzR/eJtwziqTIHcIl5jwq/LBasCxGCIwUAiIpjpQrJescSQTQxVZMC8sqriNVIkLJtqNVE+N1y6eeDhIJ1HqHBZxWwQoqLBv2ladH+Ue6FUv5zq1GBGootEHGRvTE7DJLSpSfn1ss8Hd2H9AGxMn6+6q0vl4WClub7d+eNExL0k9PPI/idyunh3+wvQRJsbm5FVsc2QORmVhzWKA6NtTX1+ecn1pMp9N6KTa3mlrndFMT9VMTRpXNbWKsbsH4YDQ+ai4jHVYa7V9+W7b7WDWCHSoqVtZ6axPaq+uycld8sr/8ja8LlDOuksoZOaYfPnlA0enmTAi5aXFM9Ln6LMkWUYQJDyeVp7Gu8bU1BwMuAABAAElEQVSv878+WK7z825sbGbS2gbnVQjRq6tNttp6B+N/vKMkVO/zP3dP8VerJsbpxicGnMh3OnORgB9764RyG+CTYHkkWFTSg7oW6TpICNMunBCSXVZfVNHALU3B2TKDjRuArfE+Qs2kI9/TY/x/f8dpH4GrrxwIASHQLwRKqq2GOntCXCi5FPtlwH4ZxFvlGRHqFxTkW2uyniwcQEkR2QJxAV+V4q7iu/JQznDMgbuC0C+76+EgCBk8CKjEooVJDXEH4xhhsO+//z6uK3QTAm/xduFBw9vIH8YsFZmmjwVnd2/a9N6GLz09PH547bVJMdEc9HC1Q9WMFU5MSrx++YrcklJchC+++CLilyKZndeSXnvtNfC6lCMMbhiX3EdAWUPMBTjyE+oD8gQqFZU6cDmhoA2QpOi+gG6OWRJ7J64TZYQwYax2yHZIiiySEGMkRTJ1onsyAhrZihUruJ04RhxENEQE7GpkVBhuP4yf5Ppk+0xx1113oaiibru6oGtTaoYF8OAluFEN+ejRo6g2l1xyiSIpcoAIjp2Q6ZAUCTdGhRw3bpwyCO8vF3amo7EiCmNm5J7HZuiay3WAzvj8889jDGR8Nqs4HNevX4/gTi+ES8TTdgHpvJWUjaBXMiylzDMzM7nEIEJaYuVcR/RErJrf+973EENZEgCZkX0Bje27ZncdsCMKPWMLBfull16KudhlzHS1kYNhSAD1mR/7/LTkZ+YwXJ4sSQiMLALn/HE+spYuqxUCw5kAJZ6To/zQR5yVRmqsBEFPSQgIC3AaFTFwTUwIoBLFkRzKGLfszqyhbPHKWeEXTQgJ0nrjEMF3Ri+Kk/DLTHiH0GBGiA3VILhwgHzz6qYCgsJw9oUH+KAWNTa1UlKZA8KrO2YqHBxi05P07AWpFE3waL75rx+cWjotbOmUsMjA074zR3MrvjP0o4SwTv58ReeKi9AaLQ5CdjYdqjTVOahMwsqnJeujgtQdHTQzUwJR3DYeqEBuO5Jb+7gy3eTQiDPTwYTqLghtI9Tmxg2zdnYkUeTv7Sg+motm19pgb+YLJm00xnLG/coiwBXXWAsqG9xPckxQs8sqGB9lczSd04sGeD0WTw49VVq/81g1Mh41pusampAscUdyKUlkyZUlc+WWgzaEclM9pb0d9qaWprZQaULpf3x5yn+8nGE0Oy2lSJzVZrLVjGUcno6L12HXpdZQ+ynHOPNpYlTkHn5ve3FemYWJaKZUJVKuNd1J5ein9iS/pmfHy99uk/JUCAiB8yRQbrSVVDe0tI7V+Hx3UfjzHLtPzXm7U58qPjLwoKHBUNtYVG3tKq9FX6YhZhMxCFsTkkH3jzNKY3vBUXmOJkL3ditBiUB4avfAb4X2x0nloF2Xrp4qP+ex0iBhYAFjBCQMRZ1BW0T7YAG0YQ1E891xxx0kzutqqO7PW8zmvzz3XGll5c9uuXlKaurwTKHYcQu+avXcyZOuXbbs+Q8/RD7jmt55550dm3V/BikKx5nrOnL54OzehZec3tE2Ax2vcgUxOq1atQqFF20Ow2CnqpP7CAN3zHpQ8bg9mOLee+9FYlMWg7RKZDR3DuqJ4smiAQfKMfodQlv3q2IEzHfo1zTjHsM5S5gz6edcvbj3XG5ZnHokRkQuxC2oKHQwpAGSNw8AKtIhk6Lcdap9o+IpjRmfW533l2si9wOuFNolu0bIY7PsjlcJDEfdQ4JEKEQcbCcpsgWskUh+LEPR4vFUIk3yQwAaSEskLWUQtEXci7RkWNe+3Kd2PybOmtQEYEespDoQWnZXC3bvJcdDS4C3Bu9WPj9Ad3Yl9Oy4JO4xbLlHjhzhXuJOwH9Kvaxe/2jtOL6cEQKjhkDnP6ZHzfZkI0JgqAj4qDwWTwrBqHii0IxKQiFdjIr471gPf3RMJLvi1DB8Z1ZbE9oQcayFlZZ3thbhO/Py8kBKowviy5wJwQ+sSe64hUXjQ97bVlxrcWo35Qbr65sKPttTxoy0RMBBWZs/IfiKedH89ZVTbvloTynaJS8hAPEqB5jdPthevCOjimOsZCtnRVw2q5O/PWj802cPmxvOCTbJr7C0jTEmu9j86OvHXTkZx8fr1s2LGhftTOyN4olIdLK4Lr/cgjZKFeYKg+2LveWsEP2I7kiKJPiJCNL8712dhIeghy6ZHJpdXFfb1EIWRUWTYtgZyYGohBy0eyAULmS60vrCcguqGVksYfL5/2fvPOCjqtL+H9ImM5lkkknvISH0JkiR3sSCncVVWQvqru11m/ruu+uu+3fVffVd111dV7Gsil1ABQERqYoivRNKCAnpvU6SmTT+38mF6zBpkz5JnvuJeObeU3/n3Dtzfvf3PE8DIBeaq6+tPxcZpHvuLqvn79544KES74RMKK45vz1WQLACJVh2w1xY55RFpfNyZxZGxRj4DOXX6jCbzDE4XH/73Bii93x/rJBAq6yB+gbmET5x9tjg2aODtxzOa7Jm6Ej8fj5/95hXvzpzMKkYApe+sYzhKAZF6pfMi/3om7SDySWcaVzcT+dxxbhQ3AVsOZS3+VAealMmnWzKSrMmXFwgQFE7KrGnG9cgZwQBQaDdCKTmV+YUW5AEenp2oW++9nVP5+WZEGM8cCwThXZmUWVXUIpYWcIKYfCIs8KWOwkNYXfAfXBAkbBB5V81Ae2i0IhQThyQLGqCNAwLGdSj5UZbvkorcC4cajY4FHa8CjOinmxTAneEJ5KTJwwfNm/CBF8ndqFoNyimJsTff8YlYzft3pWRl489LKo6hfuzy9nCRwzJYZrUUpBiaPHgxdQizB1cFYQaEidMnplEKC0IKRLwUIjdepBSpA/QmkpXocNYjUoaZFgSXCWhDqRNCbg/VU6oyGAZte2qY+w4K9y8eTPWxKxwGlJ4OtYnmPAvlGKbWnQkM5wm3SAnkkyFHiWNYhEClE5iDQ3nblcPJs+oIxUcmCki25ABZBTimE6SAZNw3EfiGPFPf/oTA8dEGjCJjMSd1SSAkI+0haU2nk9BSSRvdpg750ckuuhYUdGi/sbovslOQibiRYGwLSwk1jAzi/tRFgPvKvBJ2mQROSkI9FsEhFLst1MvA+9yBMbF+WGSnJyFzaeVGjucUooJsCJU9Na4wZqVVdV+8UMWZqRkQJPIH32CmuH3DRwKdJj3BaeEdn0N8dMsnB6x7OtU4iCTlX/546eiytZgI1xcUc3uC8UiSsnENOtba/WAc0REppjK+vl4jk1o2hMTP9UoaEcpqpXAhEIvqh+1RNgwn3dBgtBlQoLRZK5d+V1GcqaJ5rBcVoyXG36QNQzPxaWiyrqvalJ3NnNk0Mdb01DJqQxURJAOphLHgmqLagLB5qQhxgqLVeZ2JquhubLqooYI0bbNIQhtrjm1KmdOwN4Oi/QN89deOS4UTR/mzMwg0ZmJo0KAGkKpQN7ptW647CR08s1TImcPb/pHkjJGgqIgGm08XkhtTJhD/TS4pERmiHs1yD18LIb4eWGbj1k0pN6EQUbmgVnmT6txUwNwU3ZYtO9jNw5GY5hbZuFfXD0GGTSUUsrie5E88MJ2Zv5sc4j7TLuoUK8cH1plqaXdgvLq6tp6QoJDlQb4eAb6aHA82rjDckYQ6BEEkPywe+dAZQMHYSdzgD9ia42FIHvUuXPnorjpkU462GhKbgVCRU8Pd5TtDhbptmwo//x8vQIDvGstNYXlF73f6qw+ICmCZcBsk3gO7aiTbxkOhVtkupUE9UB2WL/KGw41rST4lw0qi4R/1cPuI+c5A9OhUJBKNts8pDnQzkBnoNWCwaFaesKOF3ajVd1ZCyP9Yu1alrfVhWJAAMNpIaezXQL/6NCwmePGL1u7FntYqEAkY23qJOhBMajSObwQwlvZUorIALGqxtgZGhEejcob5v88VccUtKm5jmRmZSlEmFoJZxSJImcaP3Pop5qzrQnuEZWzo6yyKmwHi8gXnSYMLAQi3VDyKAmyKYm2NtpqftpS+sBg1YVKgo+sBNYwN4hdJVxSB6LctrYZOINhODFYCEeD1JHHO1f5F3oRp4233XYb0kuVqFUKMjTcJnCTQiZCPgqfaIunM6dR2mL1nJKSwuQq8lu73iJ0ZdJZBogZUTLiVZPQ59z+3Pi8cqBIO/wq2DUhHwWBvoSA7ND60mzKWHoMAaxBCXli1zye6SYPCziZXp6UWY4/uP3JxZfE+xF3QsmGnfLCyyKGRui3Hs4jtLGpokHW1SAzVDJA5Sjmn3bV8hEd3xWXhPpo3D/7IetkehkWxJxU+UTSpZU1FQ3GwlRiVYu1eDR3mfOO/xAkZjVWrmo7qOoYKfrB7ccKNh+06s4U3ZxthWCCXS051VJqItjXc3C0Dy75EDkqJ8cn+MFqNfeTGPeUuKqMDdJ9e7QAGZ2NzO3HwaH97O0yN1jmQF9P/sAEotbCfrP+HIsBUtVqr/gj/C5wc/ypeLYpoXF3DTdqIf4QBkLqgSDLm5PML0spIUwfF4K3civ3zYTzn02znHSJaTBmH1xrdfRJr+AQlRzDo30oTiVW40DbMhc6x+jgH/kjG+FfoIBZumSEU9C4u3H1Qkb5vyDQ8wiwx0astHTpUjaoiFPwumXbJ3YdL7zwAntRuCqMIm0vOVua2w2nBLyDCQvx8vR0xt+E7u5uRoMuO6eEb4QuQo/ZhErg6KL6G1er8CyN/+Ur0vak3Uf1EprKgwcP7t+/H8ILRoNsOPhDd5OQkECMC5RWjVt0/MyppKTQ4OCR8fGevdDFmEHvPSw2lsGClW3cEgeHj2QVpkDVeGLqaEvOQlOiT4RlQLz2k5/8ZOzYsWTmZuckcqcmm1C+7RTysckMyknrt+KAAVBgcMctZLO9BJ9oqxPkEjWo7zZQUNJ5mDXbIh1JU3mTxVl7mIUSqoWlSAAWvCXCtnBDHTp0iGjU8N12pdR6wAQmzu5qmz4yQIVJhEhV2VXmXeH4mCM7+o/KaV0lH5tsi+mGT8SGGlkiDClvhmCRMI8Fz3//+98YveK01LYGKvzlL3+5ePFiKCcV/CZrlpNOhQCvDXjbxxLldoZebNw35MkokdEn8g2OHwnCkfONT37kz7CQvFRo3yuoxg3JGUGgbyDgjD8f+wayMor+gMDNUyNnjwjktbTG0y3E/7yNie3AJyb4hxk0uErkpKeHKzo79SoUENzQ5CEBA0O9F0wIx44VXSFbJoUkIghJkK+n0adZBzcwcegc48L0qP8QmMAhUhCGB4UamrLwAN2gMG/awo71oQWDymbZv6pVu+HhPiA04MdeqedJwAX99a5RUFe2J5tLE+UZy2L1Kj8+kbMRKSUyUDtjZBCRrwGhsNwCRcUvMK2nK0Mz6jWq3bRaUElAPP18/sCbJkf8qFIM1KLNtMumfqQ5AEEESnOzRivNWWVusFpqcwE+GpwSqkV6ewKKDZ6t60YBEajx4O8iiQo4N7Tb9NbCtjNQkPzZnoFetP3YQppWICL5ayGPXBIEehYB1CgQN5gTYjylbE5UQgoiA1M4ztNDXGs5uW6Fbw7Ezrzg4WnJvz2LapOtEzDK18crM+scMucmM/TGkwor0VbGJz09HS+BkDWQOIojORzhERKEyLbwIKxAPsLmdBAQuJ7Kioqz+QUhRiMBazpYWzcXN1dX55UUA6+fwQCh37mtI1zC9R5EHvbROCuEeIK0wv0iBpLNNcSMcEmh/3hQ8IOkyZwY4fKggA5DbQrRZstjkp85Vc6gy4PngtXiJGQHOmjb2qhcHTKawUceeaSxVtE2f6ekoRRVG/Cf//znrENoWfBHOdvkUmSkylhYzBwdMSBlwSt3EKapRJuhXUaElAwHoyCJNasqSGzTSOk2D3YOGF44xIKCArhC4vYw0ZBK+GG0m50xY8awJJpkMNvUrmTuTgS4WXDBSTBxvqx5+df4xlTi9sAk8nRlGTDprDeeuiw2Xi3wHBBKsTvnS9pyfgR62W8F5wdUetivEIgP9eavhSFDqxlajD4MZRMdqOMPQRayLHO1VZkFmwNxA//Fvy1UjgpyaKRV+VVVXUdZftghlEQCBncJHQNlSVlrB2KakAG2UK16iZ++E4dYPVW3+6D/SAv5o2uQifSTXlIbW0Svhk62UPOgMP2gNkpGaA5tHX+2zYECzYGzUFQtoC2XBAFBoE0IsANhYz979my202zst27dilmcUgOqJYKuwstgEM2uo/FepU0NdXVmvjtwbksrVZYas6XZl09d3Y0W6kenbNBr+PIo6hrD5xaadpJLKKSQSkEjoo5hT8uGFiYFNSJkIoa6yKPw8taJ5BEhKVDovLNmTXTQkoigoPM6cyfBosVu1NXXn8nMXLf9O8i76TNmKHReiyXadpFfWXBVlFHs0GEZYK/wu4eKjZNQgVBOTA3qOeWu519c+ynpjz/+mIDLXFKmD2bK1usiTv0UB46EIcZYGyta3kxAL0JmcXCJEdEEHBzGmNBnCPFQS9Gc0hkSNAS/yXpgMUB9Ep2G+hFY8ZEuURVSPvgReDf6w9OJQ1H2QYcpakFapFqYTfJTFQeVO3KoCkFsjWkUlFiueOQEHIrDgXJAxygVUj8gQPYxFqKagIMiqqV1yqL6pDhcHuSp0jRdUpSbdBIzf07Sf/g7OsmQR44cSfTz7du3M15UuuR89913YRXJxuOXDEolDv7LQGgC6hCZKj1USd4TJ05Yf2BjseHhocymWiHde+ONNzCQx9sAkWEYpnpJEk6OAPz7+PHjiW2F5BB3nLa9ZTVyv3CPcPugulVIZBYwdxBn4BPR5Nrml7QgIAgIpShrQBBwCgT41Q6H2A4ZHcQfWr/m5H5OMTbrT0AXSD07yVvX9a2bm+u6gUjNgoAg4LQIsDkfN27clClT4BSwfGSfz+afrQjUD7wAFM+iRYs4Y9t/dv5cxTUb2bjENoZ9rx0ZxHaaPS2bWHgBhEjkRPJDWzBHGLcq8QRs6+xgmpc9ijjRbK4xX/CH28E6O7c474T8fBQ3Dg5J5ju39R6sDe4JpQzbV3QxMImKDSlMIralLDyIGBgTVpGdZqrjHb7nnnuw99xz9Og76758cOFNAQ06u45X2w01pOXkfPL1xvS8vEsnTODu6/QWQRtOgWrRij7xxBPQfFB1EGfcntzFzNdzzz0XGxv79NNPK/QZ9BMcH0wZN/Knn34KI0wa3g3S9t5770UHp/aQ9xN8hCZD8Eg9UFqwYzSHUwWYMhri9odu49LKlSsh0SA7IL94eqCx4h3GX/7yF3Jec801VIJ88qmnnmK1QGJCDcO+8QChNp4kxH3mGcKCQUP99ddfUxsdgLxTnAbydoRS9Bx9H1wkIZ7V7rWQYIyEwVWItpdeeonu0Rw1wwACC08zztDcgw8+SNMMkJysXs7Qc6hY/NkpzC9sHXIwLIgpCAhvvfWW0igIQ6lzkrvg0Ucf5SQ1EDgFooeukp+5QBFJGA0ewhC+J0+ehOaDKkJZpvCwLXTe7hKo0jR+IeFw6Q8DUeSl6IKhFFEjMk0MwbYUD2ra5SblcU0GoRRtwXHyNDcC65wva8IKcZsobwuUPrPeWLqkua8Vrl85z/0L18zdxLIkPyvEycco3RMEug0BoRS7DWppSBAQBAQBQUAQEAT6CALsbJE5wCSyJ2EfS8BT3Kuxz//888/ZveNn7aqrrrIdKkpGPDHBKpKH7Qr7bSghhGY33XQTFpRKTrb3qHvw7oQIQlFJkJN9C5sfHD+xde98SrEGStFK1RGIGM8UiucN2273eBrFvTeydv7VNusJpMc72VkdYJsKHQNPwQHnApnCwRqAUYIigYuB0mLZcHQ6k6gOgfjXSG4hVr7cvj3I3++nc+f6+/ioV502kZGXt3zjpu0HD0bHxNx1113I3xzvKvcyR6v54dq4Ybk3Yd8gxbgxIa2Ai5v9tddew0KWRwHUkqrao06YLzg+CC/mEbGe0gT3PpyFbXPQhRCCMHqKVbtyCbkiOmjSEBlQk5Ckq1atonXqQSrFJfgOFglPG2RW9IGcEF5o5WgX345I5yDIFHmdUiGRZ8jGyuGlBf23DTtDBmrmIEGfUf8pRZr7lyaUFUiC59Ldd99N3xQtLed5MOLzAeUgw4Ge5uApp/YEY+dbb72VrpIfolBpAgqPhxsUIbcAA+QZaNc0wHJwkhZ/85vfUBsJ3uhg371ixQpIPUWzCQHEo/KnP/0pfKsd/WdXoe1HquIjk0IlapfUDMwX7vZwmMt9Z8ci0WeYTYozg7bck1pWEs6MADQ3q52biDsFal7tKnPKguQjNxdEs3qeFQKZyCWWhLJm1EuSEAT6OQJCKfbzBSDDFwQEAUFAEBAEBIH2IIBgge0xqjHkNqh+SLCNZ3vPfoPYoIiM1ErZqb7yyivE02C/jYIGLgBzaSJsoD5D2AJPQVVkxoIPbRFKRkQTyJ2gGtm9sHlGFoEqjVJqhZ2VqMOWs8Gmj1aqzLUWS61O205fGZ3VJbt6CBEF1YmQn9D2dpf6zEdIKOgklgRMIqsCSoWPLBV4MTgg1hgUEuuEo0n/dJ2LA8sMRgZGeznH1xtdXQb8ZM5so3NrFTNycz/ZuHH9jh2BISEIAGGa2oQJd99DDz2E2A20lTtRKc5Nt2TJEnyuoSuEQYBo4OaFRULchDgRdgmOifsUOokbFvYBDgvNncK1KTUwX9BnqNu40yEjyED9MG5qBBglG+d5emARDPsG8tBq8FNIDmlX7Qk8L0yfwksSXBiWmTcQPCJogo6pJCA133zzzZhOww/SSUSR3Np0iXbhJZW+QYPSFtpJpXK7fxkLxTlJB+DRkEkyTDUP9aCIpGMqg8aQiV+BRk8ZIx1goZKBUpyhIKMDWJWMg4fliQeVw1MRRSGwkIdVpzRKDwH52WefVVu0SzAR3A4KoUNX6Qx4YkbNqxqgYHaoB3DUpyWjIBtk5fTp05kI0kqF5OStj/KYVaaDEUEdIvnEGJxHLtnoDPUwQAoiKldoJtv+UJyVAzlLZCS6YXtJ0s6PAHcBq4IHL9+5yu2p9Jl5Z3lA5aOi5eB5wurl1Q73FB+5BfhyF0rR+edXetidCBDBs38ZknQnuNKWICAICAKCgCAgCPRhBNjV44yJXSjbTnatyBXRB7F1/9e//oWmSR34888/j44JjcNvf/tb9ifsVdgDv/jiizAIbGsR3bAH5vfYk08+CaXIJhY9EYaH7GrYJHMeyon64RHYnKt1dkqitKLmhc9PfbXXqp8akRAydXx0gF/nE5cd6aqluu7Y6bxd+1MeuC7hhol90FUZvA8KL+hmRFgoZZh0FgMGzhwQRuxdIVBUOqYjSLapLHTP22+/jWZW6+5+87y5C+fMCTAY2lRDt2VOz8lZvmnz2u+2+xgDsNomVq9KG3VRH7gfFe0SJBTMAgwgdAMJbk9mqkmuAcKC25+r3Pvc1E3mobfUAzWpkIDwGnbzTkNUohCOZKYbHEqjdjmVgasaK4V25N8uAkRtjv7z+FIeU6QZCB3jYLyNh8xAgJERcYnBKnK/9vWQqkCYhqiEf9tXCaXosGIkDrB8VHBrzCTa1k/TjJScnf5wtm1F0p2CAOsNZSKP2ZdffhkLA25GvrJ/9atf4WKC+vnIlzKvEEhjbcBbwNOnT/NFDGMOp0waufHGjRuRDxPmG1lxp3RJKhEE+gYCXfvt0jcwklEIAoKAICAICAKCgCDQGAEEC9j9oTDCoxZRWVAYwf0hnLHlEymFDSDbTpQ7GEcrEhvs8rCwQ8WDKg15FCwS2RR2gD0tm1g0Pl2kTLQdhV7r7qf3NBo0ZksdEVqqLFZtjlMdGGMXlVZh/hxscDRehFP1v9XOIIlC2coaQAY1ePBgmETmHWmVKrNqtYauyIBAEvNhugHH/emWrQNcBtwwe1ZQQ5CQrmiu3XXiP3HF5s1f794VGhWNuBKCvqv5RLrKfWo7OwqT1fIQIB85Ws7DVW58juay0RCsh3oVGotD/dg4QWbb/I0zdO4Zu+ZaGIjSLsNxEJZW+0lVPIpbzdZqBsjNhhlodgoa1+DI7DcuJWecBAG0pXyD84bPTrSLownUspzna5qvdYS3fFnDPCrf+Fx1kv5LNwQBJ0Ggpa8iJ+midEMQEAQEAUFAEBAEBAHnRAD3dugaiJlApFE0MoT+xJmXbVexPWQ3gv4Fiz9cmKnMAhsVdrD4zlOME0ljPEiwF6xfN2zYwGYG8hFlInZ8yCIw0bKts7PSUHVGX09fbw9CP5eWm/mLDPHtrMo7pZ7qmrqcgnKNh1t8aCdQBp3Spc6thFWBmzxWDkKY7jFtdrD/GHVC0mHV+84773y+bduAAS7Xz5wZ1DXr0MEu2WZDR5aanb36m2++3rU7cmAcSiJuPQh92zySFgQEAUFARYAvWTWtJJDHYoYPb2hHKfLly6tBXu8RlxwfqWSGO+Y9H4bSvBdU3R/b1SYfBYF+i4BQiv126mXggoAgIAgIAoKAINBRBNAr4cgM92Tr1q2DHrr22mthYWwrVfcq2Fi98cYb6q4G8ysusWnhUPKjfYDEwbQKNcSXX36JGAonXyjXkEtgfgXhyK7GtuZOSQf4eroNcDH4eOEIp7C4EgrP06OTzavb3U/CxcByFhZVRgVpQ/qoShFLZ3zztRuiLi0IkY0NPnQn6/azbd/Q1nUzZgQbjV3aqCOVwyceTU5GPrk7MTFy4EDCgxAvuFVZnCM1Sx5BQBDoqwig6n3ggQewkedbVVX48vX685//nABKnFHMBRg+X7U4MOELHVe2hDPCYhoRLm/4iJGF30z1S7yvAiXjEgTaioBQim1FTPILAoKAICAICAKCgCDwIwIQf2w8oBSximpsEqXaHiJUxMwKWcSPJRtSmJcqZxCpEdcFA9gjR47g8p9NTkpKCvEo+UjwAZQRKCLtynb8o9HHU6dxM/jpamrqC4orS8rNwUZn0QNWV9dl55fX1dYFG1s3Gu04FFJDYwRYrohwz9XXv/Wf/3zewCpeO2NGSI+yivCJR5KTP1j/1Y4jR4YNH75E+MTG0yZnBAFBoBECEIX333+/3WleARL7yO4kH3mlh30AB3wiB09C9au8cWY5Iwj0cwSEUuznC0CGLwgIAk6NgMlcm1NsLiivrrLUaTxcB4Z4h/n/6ErJqbve4c6Zq+vO5ledza/08nTVe7njSY2xY6fZ4YqlAkGgkxFgo6JsNtSEbQM4dyPIBsE3EEFg4oqXOvYqthlgElXVA5o1BI+TJk3CLJr4knhaXL169a5du44ePYp7+K6gFAN9NL5aj8p6Ij9bvRYWllQ6D6Voqa7NzCv30riNjHXS2CC289hX0+ylr7r66sqKijfffBPHhQyzB1nFSrP5cFLS8k2bdh1LhE+8a8kS0Sf21YUn4xIEnAEBZNocztAT6YMg4LQICKXotFMjHRMEBIF+jUBRefXx9PKTGeVnck2wiuVVtUEGzY1TIvoPpVhhqdt1qmjVjkytl5uft0dUgHZQmH5IlO+IKB8CSPbrxSGD71UIQBfOnz///fffx6Pi3r17YRiJv4GwkfN4UYSLVOhIxoRfReKfYkkNicMBgUjsDsWLIsbRCCW6Ytwhfpq4UO9dp0tdBsCIDsD2uaa23sO98y2s29p5rJ6RTOYVlBt9NNOG9ryxbVv735fysxqvuOqq4qKijz/5pIFVHHDtjOndr1WET/zhyNGPNny1/8TJwUOGoC2aOWuW2Dv3pZUmYxEEBAFBQBDodQgIpdjrpkw63JcRqK07V1BuySu1IEkjHWb0igtxFgO0bsA9t8SSlG1yc3Xx8nQz6j1D/LzQ5fVD6uici0tytmn7sYItB/OSs0zsq1XwzdX1atqpEnhhyyisPJhc6uJi7e3kYQEBPp6ujTxht6nPFK+vr8/Mr1RK7XVxIUTD+CH+V4wLmTkySOt5kc6rTTVLZkGgmxHAQyJKQ3wpfvDBB+gNcdikxH0uLS0lWvTYsWOhETHnJGw0sVngHPkI4Wg2m3GqCAsJaYKSEUdOXdFtg85j/GDj4dTSWlePQD/3vMKKkjJzkFHXFW21qc4qc82Z9OJqS+2Q4UGDQnu+P23qfN/LDAnOMq63WJZ/9tnK81rFbmUVKy2WnUePvrtu3YETJ+Li42+++eZp4j+x760zGZEgIAgIAoJAb0NAKMXeNmPS3z6KANE2z+ZVHk8vO5NTkZxrKquoramrn3dJSL+iFE9lmV5Zl+w64JyPziMyQJsQph8Urh8S6ePt5d6viMXknIqPt2d8cyivrKJGWe8ohgzeHvHh+vCAH62eWTMZhVUIGMkD+2bwdh8eZR/s8lh6WWlFDXxfRIAWSN2JwtA1BzaTh1JLn1txAutJWvjn/WPRFbp2rDnsnaODdDGh3gg2KypracJSU/fDsYITaWVV1XVXjw+Dce6a0UitgkD7EVBNmG2rwD3ivffeu2bNGrwi7tixg7DO6lWUgTCMcIj4jN++fTt51EtKgiC2+I+//PLLiQhsd6mzPg6J0I+I8T2cVmWqqik1WdKyS/x8vXpWqIhSMjvfdDqt0OirmTE6uLNGKvV0BIGA4OBbbrnFpa5u+apVKzZv4gVSt1lAV8EnHjnyztq1B06c5Ea44447rrn2Wonv3JHZlLKCgCAgCAgCgkCnICCUYqfAKJUIAh1CoLSyZs+p4k0Hc787WsA+SqkLpV7JBUapQ7V3TWEYz8SzZQVl1VQf5KfBx5+PtqPPEw/3ATkFlZWWOuo84FLMvyMGGq4cFzpjZCB+9PqJrSuLYe3uLJVP9Na6g21cmD48UDssymdQqF6dz5KK6g0HcjYfyOMMHgbjw/SP/3QoPgfVDCQ++jb9ZHo5NN+CSWE3T43Uu1101TZnx9Msibq6cxB/VGWrrGx3zTCGI2IMt8+NSc2tzCqoTM2tOJNdQfXF5dWvfXkm1N/rsiEXxdVtd0NSUBDoIAKoCGNjY4n1TKAVrbbpQCLEXRk+fPiGDRuIuEKgZzSJkI/Yk1JQsdxEk0tMZwyfa4iTUl/PVXwvcgkr6enTpxP+hcwd7GdzxVGFj08wHk5JSc0s5f1ESkZxRIghNLAnNfLlFZbjZ/IqKiyjRgZPiLN/WdLcQOR8VyMQGBl5y623eri5fbZuHdFa6urrr5k2LSwwEGa865qmlQMnT6JP3Jd4HK3urbfdJnxi16EtNQsCgoAgIAgIAm1CoAu3l23qh2QWBPotAlBImw/lvb8lTTXwZEen83IL9vdKCP+RPwKf/FJLZpFZUYHBtsSHekM72uKWXWwmDxbTKNpC/TXemi68wZGJvbc1bUdiAR2YMTrornmxQyN8bDvTjnS4URsd4p1dZDZVQk9ZmaljKaWnM00FZZYbLguHQgKZdlTbu4rsTy7Zd6pY0Sf6entcOsS4aFrk2IF+jS3Aq2vr80osGXnn7YLR8R04UzJ9eKDteCHjyMCayS22LgzbS86fZrpDDJprJ4TR1QpL7TdHCz7ccjYp0wSrWGaqeW9L2vh4f08n8Pjm/EhKD7saAWhEWD+OlhtCq8gBXVhSUoJjRFgYbJxxpKjQMUiu7rnnnltvvRUHi3hOhFLEJTwhpGESm1Q+ttxWW682CBUNeFrA7UZOviklo8ho8PL0uOgrpq11tjt/dU1dVl55WlZJiFE795JQX68upKva3cl+WzAwOvrOO+80+vq+t3Llp1u2lldW3jBrVlx4eBexivCJx1NSP9qwAX1iUHDwTQsXXnHFFaJP7LfLTwYuCAgCgoAg4GwIdCHj4GxDlf4IAk6IAKwQNND7W8/zidilBvppiEERitlvhH7y4Isc0u9KKvrk2wzC4DIQSMPHbhqMabCtdu/bYwVf788tq6wZG++3cEpExzm+FhCD1qmvO4cqjTw1tecTLeR35FKon2bx3OhTGSZYsMzCqtScCvCxVNd9/E065No1E8KwpXWknt6bB4XmjuOFaQ0soVbjNmlYwG2zoodHOsTVlptr1+/LmTI0oE/GRIYfnzM6SKdx+/cXp8EHxvnw6RLMusfG+vUDnrn3rmjpeRMIwLzglq6JC3gwcHXVNxxNXu3Sk0G+molD/BPTSo+llpWbzGfSiyJDDVGhPSAPrKvD5Ln88Mmcc3X1YxMCpg/x69KBS+XtQMArKOjaG27gFd+yFSs+37qtssq8+KorB3YBqwifeDL17H9Wr/7+0GE/o5GA6TfddBNa4Hb0WYoIAoKAICAICAKCQFcgIJRiV6AqdQoCjiKQVWTedjg/s4FCwnFVbKj3dVPCF06OaJIVyi+zpOVUKJQiDexNKib4r6/uR5Ytt8ScmmMyVVpDA1eYrcxj7zpQnM0fE8If3d5zuvjdTamHkkvwGAiruH5PzvAon7FxiPX6slDxyFlUmeXKFA+K0F8zMcxBPhHEQOnomVI0npGBTdtd9q7F0Li3Xh5ukwYby+bF/vWj4+fOwTac+2Bb2ojbfUWo2BgrOSMItAOBEVG+eJnIK7bkFpuJ+3z6bKHRoPXW/vgV044621qE+zq/uPLQiZyM7NLB0YY5Y4K0Hn35md9WfJwnv1dw8DWwigMGvL18+YadO3F5cceCq2PDwjpRqwifeCot7fXPP/92/369wUBwGA7CoDsPCNITQUAQEAQEAUFAEBBbElkDgkCPIVBTd+50lglVGj2AQ4wK1t02J/rmKZFN8omNe7npYB6uDHuZLWvjYTRzZsIg/weviR8d5+fZEIIDoi0xray8qraZ7H3hNKbeRHkmSg+DcXMbMH6Q/5Bwh/SJ6uBNVbXr9+eoHx1JsA9EGllQXk2kl8yiKgKhYNKu+ENsrjhLjqVL1BcI8bP5lZQlckpzme3Okw+OGCehGOmnF1TllJgR1WLlbpetuY9Y+sMq4ruTDHTyhyMFOcWWBueNzZWQ84KAIOAoAv56zzljQmaPDSJAVkVl9ckz+UdP5VaazweJcrSWDuTjpi4urTqQmJ2YlKtEZZkc3wMyyQ6MoH8VhVW8+oYb7rntttioqK379r79xZqk9HRcgXYKCvgHOJ2evnTlp9/s36/z8SEsjC2fiMtRXAd0SkNSiSAgCAgCgoAgIAh0BAFRKXYEPSkrCHQIgbwS8/7k4tJya4QTP73H5eNCrh7XBnOeE2fLoJ+I5NtX494Oi/S94/LYv684SVwOINp2JH9UrN/oWENf1SniwiyroKqigTYN9sOTpo+/3iF9EIBg/44dOmzg5gO5P5sVrb3YyWZzyxSKNr2gMiWXvwoszeExowK0scE6AsJEBOq8NU24UYNuLCyvhgo/nWMiOjnEImFhJib4hxpbl0ZCPVpZyNyK1PxKuEiTudbf2zMmSBsXqh8Y6h3o49kqmY5aSe/ldtXE0GUbUhlU3blze04Xhhsjui6SdXPQyXlBoE8iQFz4ayaGl1fVbT2QC7u3/1iWywCX0YNDtF4OPYs6ggnvG8rKLQePZx9MzNJ6uY+K85s36iLPsB2pXMp2EQLaoKDrb7klNDzszXfe+eqHH/KKi+9beNPI+HhP947uL9Jyc19ZsfLbAwd0ev3ixYvhE8PDw5VREN3o6NGjRDEinJE4VeyimZVqBQFBQBAQBAQBBxHo6Fe+g81INkFAELBDgO1Tck4FqjTOQwmF4YR+TLBdnpY/Iuj45lj+kEg9UU1azqleRc9VW19vrq638L/6c5hae3m4atwxVGrJsoyuVtdQqs5cW09GYgpjgqrW2XICBspquVxTjxKNshoPNwhQxy1Vx8f5RQbpYLsIhH0spSw52zQ4Qu8gX9Zyx5zwKlSdatU+Os4Ay+ZgJ91cXQ0+HjXV9Sj+Ckote08X2wVpabIemttyJH/5tjTFdaNtnuExvj+ZHjV1WICd80rEien5lat3Zi3/Jl1VMu44WvDRlrOTRwZemuBvW4ldusJceyyt/K2NKUdSSmsvhDVX8uh1HvPGhfxkagRspodbK9p5XExecUnIuxtSWZYcBCw650KypQWstCL/CgKCgCMI4KL3pikRSJ5/SCwoKavadzSTUqOHhGq7Mt4X302mSsuhE9l7Dme4u7sOjvS94bKI6EAvRzoseXoWAVetdvKcOQM8PM698ebuQ4fQFT646Ccj4uI8OsAqFpaWLlu7dufRI1463c9+9jMkimFh1jhdynHkyJF///vfRUVFt99++4IFC4RVvACM/F8QEAQEAUFAEOgBBIRS7AHQpUlBAATgyApKLHlFZtJs1eLD9TFBOgeRgQHElxx7sO+OFhAP18FQyNYWy6sRNp7JrUjJq2DHGGH0igvx5g9Jmo+26acBYYKziqqSc0ynskypeZXQeZcO8h8crvf2clc4neb6DJmICC6joAoFHM3llFigL2ODaU6Hro1QAI4oy5CtzRgdeCbblFVYBYd1Kqt8Qpl/VKCjQDXXN+c8X2TC6Pi8CXCwQUMEHgf7CSXtp/ccFuWz9ocs+OJVu7KmDg1omSY219Qt23r2q93ZpSarkRo1wEvCzUE0s64Sz5b9u+Q0vjtvmR7FrCndYLpZCe9sPrthT7ZyBlUjHDEFoIyxQWZtNLB7TfSaWrcdLXhrQ0pGvtWsm+bcaW8ABLc1sA8Bvld/n1FUarn3yoFDWosbjjNNox4FjCvrGS4R2SMdlkMQEAQ6EYGR0b63zIxC9Xw4uaS0zLzvSCa3MFpFL274Ft8/ta8PtXX15SYL9s67DqVTf2yYz/VTIicNMrSvNinV/QgM8PCcPHOWm6fG5dVXdx048K/ly391yy1oFdvn+7i4rOzNVau+2vGDi5s7oaXhE23jsSBOLC8vZ4zp6elvvPEG5s8EbBFWsfsnXVoUBPowArW1tTiKdXNzVD/Rh6GQoQkCjiDQNIngSEnJIwgIAh1BAAd2xRVWk2eOEH/N1BFtsPDy1XtAxGAhW15Rc/RsKQydnZpMqdb2Xyiko2llBIz+9lCe7XnS2FzfMifm+olhMDV2l7BUTcwof+ajxIz8Ksgm5eq6H7L8fT1/flUcV+3yqx+Rs0ECrtmdvfK79KqLA8UgjRwW6/vwtYMISO2IXHHmiKB1O7Opjcrx9FfZEPBabagvJQpNP6oUibpDdGPHR2fQuc8fGwJFCNF28FRxbqmF0D0tFN+TVLw7sVDhE/FWGeDjGRKgZVHlFFWVmGqopLDUsjOxYESUz4SE86FpUaoeTyvbuNfqqxFOEE55YJj34ChflhY2+Jhsb9mX2xy7l1dq+fz7jMwCK59Ic0Yfz4ggnV7rTisURFwJc024IYSZ2Fy3uir4nefj7QEFyYrMLqxqrtEWhi+XBIHmEEC/zSXWGEdzefrD+XFxfl5Xx727JW3vicLScvPOA+kFRZVjhoaFBnp7OqxSdwQofKmezS7dcyQjNb2Y9wzhQd7XTQ5fMC7IkbKSx4kQcHObMG2am6eny0sv7dy3b+mnn/3pnrtDAwLaeh+VmkyvffbZ59u+qR8w4N6774ZPDAmxRmxTj/z8/O+//37v3r1wi2lpaW+++Sas4m233ebj0zbXw2qFkhAEBAFBwBYBs9l85swZDLiio6N1ur4pYrAdr6QFgY4jIJRixzGUGgSB9iDQQCme92LurXHHg5XjtSAUmTLciMFpiclquzpxiL2Bql1VCAZ/OFG49MszqdlWp4QcaAcGuLookjQopLfXn0GY9tTiEV6eF5mdHkwp+eM7R/GXp5SCDUShQm0l2MweyiOgh3Le7l+IHnztvbMpddsF+pJi/CFng7SCrjp8uuTxt4/88bbhhNqwK9v4I2wpvWJ3D3NUZKrB4WDjPH3jTFG5BXpOGQtLwnHrcoowNTHButhw/el0a7SU1buy7r8yrjlYIHwxXkZASgaQvXSI8Z75A9El8XHHiUIm7khyKaKko2fLvj1aMHagH5VzCfPzrUfyOU8aPvHKiWG/uT7BvUGyZDLXvbgmac0Oq4Fkk8fq3dk0R1GWAc3dfXnsiGhfmqYnmw7mvr/lbHKmqdJcSwSe4xnlY2JbUSdRMMCggVKkrbxis9KlJtuVk4JAmxAg5kNubi7/BgcH6/X6trIhbWrL+TMPj/L975sGr9md9cGWtApz3bFTuZm5ZRNGRYwYFMwzwa01HwWtDpA7Fz4xMbkAcWJxSSWq59AA3fVTIn469bzLvFZrkAzOhsC4iRMf/s1vzr344oGDB1/6+JPf/mxxoAH3x46y85Vm86srV36+bVv9ANdf/OIX8IlBQfbkMh4VFy1aVFJSsnHjxqqqKrSKb731FhTAPffcwz3rbIBIfwQBQaDXIbBnz55//vOfOTk5jzzyCCLoXtd/6bAg0P0IXEQfdH/z0qIg0G8RqLTUwuUpw0e35WAgDhUu3Mkh9eJ3+onUMtzbtSAYpEhafiXckMInQsfAB0UG64bGGAipqbBFGK4ePF286XCuWj8JqMOl61OwjybNjsCg9xg/1Djv0tBR8X6Y2R5KKsktappShBv6PjH/28P5FLQ2p3WPDtGNG2wcHmugoGLvjCO/19afcTDUr87LHTtZaitGpdh3KcViU43iSxHTPw+3AW21L0TYeN0kq7cpSNu1u7LQ/ZFu8jiTY8ppcE/J1QA/zcIpEQqfyMcpQwPmjws1Gqx61ZqaenhA4qgoleSWmPecLCLNYogK0j10dbzCJ3KGkCm/ujbB19te5aoUhEncd6IIGpqPYYHaW2dGj4oxsDD4yDDnXxIyb2yIpiGeTE6xGTN5pVQL/7q6uhh9zluFl1fUWl0pyiEIdAABq/G+xYI15ebNmx944IElS5bAVlRUtL4UO9Bm7yjKt8xPZ0Q/ecfIMYP8eHRD/G3bdWbdt0mn04qqa+r4jmjfMHgmYOycX1i5dVfqN7vPUC2VD47yu/+ahNtnRravTinlJAhcMn78bx55ZOy4cd8fOfLWF1/gFdHqTcOBo7q29oP1X6357juNzvvPf/7zXXfd1ZhPVKoZOXLko48+evfdd+NgEctEdv7Lli17+eWXYRgdaEeyCAKCgCDQEgK8okAEnZGRwSvGlvLJNUFAELiAgKgULyAh/xcEuheBChvDZyLdGnSOOs5Tukmg57hwPebAkFDbEwuGRPo054qRTd+B5JJvjlgJPlic8CDtrbOjF06OgNLBD92r65M37sVeFX92tcs2pl4xNkQhGcl8KLU0JbNc2TRi6fzMnSNHx1h3lVzaearo1TWnT2ZY/Rk1Pg6mln53vBAFCk1EBGlvmRV9w6RwCiKKJCLNP9ck7T1ehFwxPa/ym6P588aENK7B7oxB7wnrClNWWvGjabBdnj7w0cF9V3MjJW7J1KGBr3gmsyRKy2uYo2nDAprMnF3Cz6XzRutThgfEBF8UB4aY2qNiDVsPWg3k8YaJ/81BDW7xwV+JRk00lTEJfnZ22RqPATPGBK3dkdl484iBvwU5YkNXiEEUFai1oztjw7z5w3qa5orKz/PsTfZcPakwknzsIGhqhZLonwiwfnCZxLYBDvGLL75ITEyEW4SwiImJEcWTsiTwpnrZEGNEgNdbm1K/PZRvqa5POpN35mzhwGjjqITguCijVYSODs36zdD6wfMB0/LyiuqUjOLDp3Jy8sqZAt4YXZJgvGt+7KVxrSiUW29AcjgBAqPHjHnk0Uf//ve/r9y8Jb+o+PdL7vL3tcrSW+gaPxjWf7/jnbVrg8PD/+///m/48OEtezGLiopCxsi/SBRPnTpVWFj48ccfcy8/9thjGo2mhYbkkiAgCAgCLSPAtxKHo99qLdclVwWB/oGAUIr9Y55llM6HAAa8JQ0GxfzOthqRtVWT5uJy1aUhJ86WoiP77kjB1eNDm6MUC0rNKTkVFZVWsaHWy33y0ICfXBah4BFu9Lp7XmxiWnlGbgU/6IvLa2ADJww6H7cX49nq2vPigvuvjh8a4avwiZSdPNh4ZHRQXpmlqPS8O0hbgJFDnjxrZRvhnmaNCf7JlPPNsfMcFKZH3fZQShlKRnzz7Tld6hCl6O2uEJ2V5jqkc7Zt9aW00Ufj1SDWg8aFdGPv3eIWzH7obNd8dO5zx4fg7JKwJx9/mzZlaNN25bklFnSpSnks7n11F30RBPl6EjxHuUqY5mKTdYqRwSp6VdI6Tzc8HioZ1H/57QXNPcBlQOMILcgbVRUtIV++TSywC+t8MrMcL5lUxaoou+BgVK25cQJnd/ll5xeer4+nRHtuDJGcaRUBbjC4rby8vNWrV69YsSI1NRU+glLe3t6//OUvx4wZ02oN/SpDdKDufxYOuX5S+NcHcrcfKcDtwOmUfIjF2ChjQkxAVKjB3+DFI6jhkdXERqzhTYP1mVZQUnUqteD46bzCYuTP1j1bgMFr2qjAGyeH4123X0HatwcLL//f//3fzz777MYffigqK4NVHBQZ2cTKaECBlXEqPf1v772n8fZ2hE9UoCMkixKY5YUXXkhKSiouLuZGrqure/zxx907EGy6b8+LjE4QEARaRcD6XSWHICAItAWBi3aSbSkoeQUBQaBDCCjRdTtSxeQhAQG+msxCs9UJXXoZQsUmaytF+XWBpokN0U27OA4Mdm0LJoS+tjaZsjBZaQVVKqVIzcrXKgGpx8f526nSJiYYdx4rbEwpYphsMsNoWb+Ph0To546+yBESG05avGxkwOa9uWRSgq402W3bk9bgwA36hnPE+O27X/Qgo1CKjL3CUotfRWIo2+LQalrv5X7jZeFQighCD5wqxrq8SbTyS6EUzzttJK6LndNG7OL5U9piKolDTRrlI44slZO4PPPV2otqmR8/76a/UAj2rTKY63dl89fcQCBSHaGMWV3EdVEqCfbzaln80lxbcr6fI1BQULBy5UqUTfhig4bABTsMIwckBQopoSQaLw8eFJcM9BsT63fX3IFr9uRs3J+bmlWWnFrAH5kDA7yjwvyiwwz+vlofokvpGjzgNtRSxWOktDK/pBJXjGfSikym8zcvIaGmjwq6dkKokImN0e4DZ4YNG/aHP/zhmWee+W779t+//O//++XDcRHn3y/aje50UdF/Pf93c23tc089NXjw4Jb1ibZlPTw8rrrqKm7ep556ClYRB4uffPIJHgyef/5522ySFgQEAUGgHQg09xakHVVJEUGgbyPQ9A6wb49ZRicIOAMC8HT+DRGW4UfwKsW/bWVG8GQ3dVQgMVKgV7Ydzh9/QV1oNzrC6apOGzGvjgy4KBAwu8T40POKMzqRZeMeMb/kfOCLqBCdh4e939VAH88mCa+G5s4ryDDuPpxWdjr3vDM+pWMEe0nLszo8qq8715w3Rrsh4GQQSSMndVr3xj2xy9x7PxoJRHMB59LKGtBrEuEWBojWNTJAFx/lm5xehpRvxY7MJp2dEVIZklapp7bOReF/1WopwnpUPjZ4dbSfejWngwmtp6MiXG4B+MpWq4XpNjUofMka6u/VJi1nq5VLhr6NAIuHiLGomZYvX56ZmYkycdq0aRg+o1KET/Tz85s5cyaxWfo2CB0ZHU+OYIPnkjlRt04L33O6ODm34mRWRXpeVW5h5aHELP6sN3DDPemj9zT6emHjXGqy1PEGyeqmwOqpAN+4EcHaqcMDLx8bMjBY19Yvvo50Xsp2MwJxcXH33XcfN9fR5OR7n37mD0uWzJs4wa4PyRUVD/7lqczs7DfeeGPq1KntMFuePn06vheffvrpEydO4AJ1zZo1JpNp6dKldg3JR0FAEBAEHESAryrhEx3ESrIJAiAglKIsA0GgZxBA9EcsY6VtzELLKmvVj453iC3Z1gN5UIqnM0wEaVG1YLY14J9OsbDmJKGTDRcaVfIQHwN7WyUNl0RUX7VsualGkQT66e0MVa1ZELKpXhfVIiTKaK7ByJr0yfRyIvna2aVSJ44Uucru0uxYrBVcKCqWs77W6M9tE+7Z9s3J0wE2LC2SQAyN4W3b2meskhdOCf+/T8ogCj/fnuF3wYTZtp4QP41XQxBnTsJdmqvrbblLQrvyp+RH9oh2kjSwqxGEmD4WlW2FLadhOVUhJDGpx8QZmlvqGg83e+rpkwAAQABJREFUIre0XBvrhwDTOHa0ZhvgEh4olGLLgMnV8wjAGGZnZ3/66aeIE0lotdqFCxdOmTIFbhGhosFgQOIEnzho0CBPzzbfd/0KZUhDXjbwFTB9eODUYQG8gGD3BWWIWH7XqSJUyQVlloISCyHs84tMwf5eQX56niSRgdq4UO+4EO/oIJ2PF+4TeX+gvtroV/j1o8GiIpw8efLrr7/+v//7v998880TS5ceSj593/XX63U6UBjg43MwI+ORPz0Bn/iPf/yDm9HL66JXng4ixSsyyj755JPYWR84cIDQCsRZWrx48QcffOBgDZJNEBAEBAEVAb7R1LQkBAFBwBEEhFJ0BCXJIwh0PgJQPyqxAhWIxzr1o+ONhfpp4iN8zuZVYvu882RR+QUmyLYGdm6qD0R2fRf0Z+ez8LWJRlL5wEaRQDG2ZdXzVvLm4gMZiv2phgy0BU2p5EX2WG3VpjR7qB1rNkfDhcqq2roGr46QmwQhaTlz770KZ6eqFA+eKZk2PDA22LrvatOBAnHG8MAXPd0s1XXllVZeklmwqyHYoIG8U07ix5D9v0oXcvJsQUVawXlhKaGclUtU66M9/32BbXtyjsmuTj7WNEMzhvh5EV1HyY9iER58VIxv4+KcYU2xXJu8pJ6sqq77+uCPMfjC/PDg1koRtawk+i0CaJfefPPNVatWQSYiQiRW7LXXXgt/AQexf/9+grGkpaVBTMyaNUskio4vEistyN134ZF8SZzfyBhfvmJ4n8GOTJE/I0JUviygD6352xLLxfGeSE6nRQArZmyZn3jiCaK1fPnllx+s+3LfyVN333br5MmXrVj/5atLX2Od/O53v5s7dy72y+0eBa1ceumlf/zjHzF5/uGHH6qrq3fu3HnjjTfCKnak2nb3RwoKAoJAr0ZAWMVePX3S+e5HQCjF7sdcWhQErAh4XzB8Jo3XPEKdNA550SpS7NbmjA48llKSklO763gRIj60f3YHTJCqTCRYJ3bHttwl3uuKGyJjUIotX5iNWbS3zr3SUsvOEAVlY1rKrhX1I5UbGwy6OePv4zlioCEqSKtetU3QeRzh2Z5pMg2FBDum7E5RzNm5dGyySC89qffyMEL2NbCB2QVVBNUxDfZH3dOm4bB712vdr5gQ+sX31uDLTf4qigrUqczsnpNFc0YHDwz1xo6ehlgPh5JLj6WWKY36eXuG+Z2fPmhBH2/38opaaMojp0sQKqokI5mZoKNppTTYuLdWJayvJxbr+ElMSjcRfDzM34uwMI1zOnKGNbn6h0w1J64/W2Uh1cyS6IcIELTh7bffRopYWVmJGeaiRYuuueYao9GIw7W//OUvO3bsSEhICA8Pz8rKuuyyy0aPHi0ERLsXSQNjeIFfbHctUrDPIQBZHxsbC6uIlvDFF188dPz4H/73WY2nZ6XZzFj/9a9/TZgwoeMB1vF/Onbs2P/5n/+hiS1btuDT4PDhw7fccgvvEuQ9QZ9bUzIgQaALEcCmoQtrl6oFgb6IQNs2q30RARmTINAzCGg1rn4XIu3mlVh+OFE0KaHp+Lwt929cvH+IvxdCRVNVDVrFxmp9Imn46c5bWBNv91S2KcZG+0b8jUNnS5Um2BBGGH8kegL9vDBeg5PKyKtUI/aqncE1FuZu6kc14avzQEuofMQyekSM76IpkepVu4QjZNDOU0WEGVEK+nt72Jro2tXW2z/CBs4cFXQqoxyDcTjc/WeKLxnkNy7Or63j0ri7LpwSAaXYXEEYvWExvukFlabKWtbMG1+dIRrM7NHB8IlrdmWt3plVZbEKDv18PAdF+mAlrdQT5q+dMjxow55slsSZnIpnlh9/7KYhGGuzCCAZ1+3L/vZgXuPlp5S9eXoUq4hSSGLX7cpKzaskKBARfnAnCpNprcFcyywj3UVB2Vy3OY+e9/DZsvxia3gHKOlLhvpbw0yLSLEFyPrxJXwmvvfee+vWrSMBUfjrX/96wYIFBHQmTWwW4jlgiQmZiGIRDgLna7Nnz4Z6EPdJ/XjJyNC7CgFUhCEhITfccMOoUaPQKu7atYsbDQYQij8+Pr4d/hOb7Cis4ogRIx555BEEyLQCq3js2LElS5bAWvI6ockiclIQEAQEgcYINPk+vnE2OSMICAIKAkIpykoQBHoGAY27GyI+vc4dWoe/k2llBabqwAv6Psf7BMU2cagRRVtusbmuKUYHgi/oAk2TWVC1+0ThzBGB2LHSBMqyvBLzpn25SnOYIQ8K1atNoy48dbYM3hDC6MCZYjuFIIQU6kU1s5pA7Ea4TxSOFZW1hWWWvSeLsIYjTqiaoa2JzQfzoFyVUrjigsNqaw29KP/4eP9Nod7JWVbq7Uhy6ZaDeTB6tjyvI2NBbRodqBsS43vy7HmxoV0pmNwbJocfP1t2PK2MJcOqeH3dmQ82nyUbcwq7p6yj0bGG2aOCVNo3zOg1c2TglgO5+DEkYPSOY4X3Zezz1hLqxQXpYnlVTVXznjHHDDRcNjIQB5ElpupKc93BpOLkzHIIREhn6keDCps5wHXANRPD7pwbY9db9SMsNgbXS9edVjSzFFwyJ7YJN59qAUn0VwSwbkaWuGnTprNnrasa+0d4w4CAAJRQ7BPgE3G7tm3bNl9fXzy4bd26taioaMyYMZ0ileqvkMu4BYFWEIBD5AaE8sPPwJ133kluiD8CIqFhbKVkWy7jvXHo0KG//OUvqfyzzz6DVTx+/PiDDz74t7/9DTazLTVJXkFAEOinCAif2E8nXobdAQQ684u8A92QooJAv0MAaVVcqH7K8EBGDrWXXWTefqygfSjMGhkUbmzWgpgoz4PC9WENdqZYEH9/rODfa5Ozisx4xNt1sviFVUlFZVYNIN7yB4brB12I/syZ6yaEebpbBWB8ub6xPmXHiUJskBs+upzKMn20Nf1MdhMO9cgAh4gfQBLE8TiaWvbiqqR3t54lMjXMESc5aurOZRWbkaopH1v493S26WxOBQQWeQaGe8eH6fuw4TNjZHQsiZgQq0spRr1hb/b7W9NS8ipagKjJSxoP15umRLQg32Pt/WRGZEyIN3lg6HDlmVFQxR8BuxXCbkSsYcGksJigH51bQUOPjDEsmhGFPBDOkbVERCA0lSfSykmUV9bOvTSkuRYpe/PUyKsnhWEBTYchJVl1NJeaU5GcbYIQp4b0vIqCUsuFNWI/LIocSil96sPjxJblGrRpXKQPpGdzLdqXl8/9AwHsl4n0+qtf/QpjZ4Ku4BvxhRdeePjhh2ExFD4xLy8Pe2doRIiMV199FZ5x48aNSBQJGhsUFNS57Eb/gFxGKQi0AQGEhNCIqIM58D/QFXccTeDN4IEHHrj11lvpWV1d3alTp5Au7tu3rw0dlayCgCDQjxFg48NbEI5+jIEMXRBoAwKiUmwDWJJVEOhcBLDZnDjY+M3hfNiZ/BLL+t3ZQyP0wyKbjlzRQtOh/l7xkT5J2SbUjo2zIeYaOxCOL2DF9gwoveLymnW7s/eeKkKTiPwwtwQSx8r04YDv9jkxahgNzhB7d0iM4XByMcxgXrH55S9Of7glDfkhvS2rqEE5aG5gGBu3iLxx2ojAExnlVjawui4poxwF5Ve7c4g3TYhPvqdra8+hOAs1ej1/z+jGxdUzxRU1yzafzcivVERzs0cFx4fq4bPUDH0yMWmwcdfJIii26hprHPCN+3LO5laOijMMi/QZHG41Q1Zlg+rwgcROrAfjNnNE0EvaJLSiSjYP94t+GuHfECaawCnLt2egJMX8Wa3Nx9sD++vrJoUnhOvt4ucE+nrePD0yxF/zwda0vCKrGyz4R+oN8NPMuyTkinEhW/dj+3yeOFYrVBL4zVw8M/rSQf5f7Mran1TMWmXhWbNeyM4HWFRoa2+bCDyssbP5lcczyxPTyg4mlaTlsRisBeAo75oXA3Nq14p87LcIwBUS5nX9+vWJiYmAMG3aNMI347sN0hC9EmdYObm5uc899xzZiNZC3Gc8J65evTozMzM0NJToEDAd/RY9Gbgg0JcQgFXE0vnee+8levuyZctgFZOSknCz+PTTT0+cOPGi78K+NGwZiyAgCHQGAs39ju2MuqUOQaBvIiCUYt+cVxlVr0AAQmRwhH7CEON3R/IxdEXt9era5LvmD2yr+zw4pqnDAg4nl5yqLG9y4MF+mrmXhGQUVe1MLILHIRAwf7Y5fXTuaNbGx1+0o6Z7914R+9ePq7ILzFYdZWFVTlEVbSkBPZE0lpRXY8famEGC3pqQYMR+duV3GcmZJmxakaQpWsiGn/Lnv6whNLHUdmuGIoTrfHnN6R3HCxRpZEiAdlSswTYwsW3/+1IaVektM6KYoB2JhbW19aj/Dp8pQcq3yct9ZKzvjVMjx8YalPEGG7yWzIu9YVI4NCszaAsCtCtxcl68byx0sHIe43e7SC98pKpQP6/i2dVF5dW4MsStYaCvhpAsgQZP2EM7mpJ6mH04zasvDUUeCN0JU8xJVhd9DjRQ0OPJ20ewbLw83IZF+Vgtom2Ohso9fXX+0UE6YgQRZaWwrLq0soZFAHHpq3PHryIm3mrMa4qaa+phV19ff4a1RDQYAn8rgyG2zH1Xx08e3B7fozY9kmSfQiAlJWXt2rWYMF999dUwicOHD0cDpcZ8wNs6fCKKxa+//po4LbAM48aNw7+bQi/OmTMHzRQf+xQiMhhBoB8jAKs4cODAJUuW4Kjx9ddf5wkAq/j444//+c9/5vkgN3s/XhoydEFAEBAEBIFORuCiXWgn1y3VCQKCQGsIQK/gnw7RFjIxJFoHk0teWp00LsE/IUI/OMwHs1M7mZhSH0bKdlK90bF+kYE6iCeFQnJzhf35sW2yD430+cWVcbHB+q/2ZRc3WDorl3FmFx+hv21G1PgEY+PIJ6NjDH+6ZThmywdOFUPtwR5CACEQiwnV3zIzeuuh3J3HCznzY0sXUrBLc8cE03+suXGGWFhqUayebV/9waLCl5HzQiFkRC45xeZTOaakLBPu9o6llmKdrVydNzYYq+dG41aL9p0EFGt8qPe9VwwMMXptPZhHhBxsfq3sbXk1GlIM5FVKEfIOhG1tk21RoB50prZnGqeZ/ahALX+E3+GPRaXxcGtyyalloS8J+DM8yoMJhfJD+wWBqM7LjJGBpKGJkUmqRWwTLB6lRUhqYq3UWN02niMrPeGSWo9SxGpbXVB1OutH+3qqjQjS3jk3lob6tgm8LWiSdgSByMjIu+66y9/fXzGoVJSJSkHYBLwrvvTSS1999ZXFYnn55ZfRMMIp7N2798CBAySQKOJX0ZFWJI8gIAj0FgS4taOjo++44w60itz1/PyAVcTvAXLFGTNm4HWxtwxE+ikICALdiQDPCg40EA0yiO5sWdoSBHorAkIp9taZk373DQS8PN0mDw24ZZb5/S1p1dV1kCxE+80qrEL2haxs4fTIuaOD1ZFePiZkWLgPIkEvjRsiMvU8Cb2X293zY6+bHEYYZg5CskTaeMHjDHTh4AifAB/NtBEBmC0XlFdjUuqPHs3X09fbg7AnjflESsHyjBno95DOvXB6NdGicbTnrXEnQIqf3jM6WBcR4DVvbAgmtKFGLdyoteELB3wWQ6BsZKB2xsggCFNEbYXlFitvNWCA1tOVYC9GvcaOFcKY+rkVJ3JLzKWVtTBoqu/FqyeGXTk+tG8HZrmAnPX/MGuDwvSYCY+P899/puTgmZLM/EqCn5hr6ipsLJRti3QwzUTz16ZK6KSthbJSFnrRwUqgJlly2otWsX1RVkBZVQ2EI5ylr949Pszn0gR/Ir2wkhs3bV9YPvczBIgni40z3IGddzb4RBwsvvLKK9hEV1dXQyhcfvnlKJiABy+KxcXFGEISMqKzYs72M9RluIKAUyMAqxgREbF48WJu8L///e/0Fb+KeD/gUcCLBB4XTt176ZwgIAj0BALwiT3RrLQpCPRiBIRS7MWTJ13vAwhAl0Dq4bcOcm3t7uzU7Aqc05WaaviDXxs2sNyWUowM0PLX3KjxfMdfc1c5TyxmrFb5w4kdfCLqQoxM4TRbKMIlrFehtwaFWa1Qq2vqUJMhjlMcGo6M9h0e5csHam7SfBm9G976+OPbGTIRnaM19McAQsEMgHtqzGFll1QdTim1Zc3w67dgQhh/A4ObFmy23PneexXCLszfy6j3HBrlg0ITz4OIOjWeblC0vXdQbe05csgrLgkdHskac8EMG0ErDhn9vT2aXGxtrVzy9zEEYAkVotB2XPCJuErE7HHdunU1NTW//e1vr7vuOoU9zMjIICS02WyGYYSLbPoRZluXpAUBQaAXIsA7hrCwMEK1GAyGJ554ghGcPHnyn//8J8Ggufdt5cy9cHDSZUFAEOgSBIRV7BJYpdK+i4BQin13bmVkvQQB6Dj82V07MZwgvBBqB1JKUrJNRNXAMpQ4vF0xCBhAO7d6jrRi5R8vjoYBvehIQfLAAUFE8tdyftz5MWoA0WhcIwJ1OE9EkkZsmSA/DX1uuWyfvApiEIv89cnRtToohh8fRphv71ZzSgZBoDECCp/45ptvrlmzBvqACLCLFi1SvStu374d9SL6xMmTJ2u1/YipbwyUnBEE+jYCvDAIDAxcuHAh/g2weuZFwokTJzCF5jXDlVdeqdNdZGPRt6GQ0QkCgkCrCCh8Is8NjlYzSwZBQBAAAaEUZRkIAj2PAN9ZKLAmDzEOifCZMjygsMxSXV2Pmo+YyD3fuW7sAQ4ff3/zUISMhCf29fYMN3oFGzSNxYzd2CNpShAQBHolAvCJ6BDffvvtL774Aj7x7rvvRqZEwBZlMJwhTgvGj1dccQXhnu1spXvlgKXTgoAg0DwCUAO8Trj++usxhX722WdxrgqruHTpUh4FBHRS3zQ0X4FcEQQEgf6CAJSiwir2lwHLOAWBDiMglGKHIZQKBIFOQgBbV4yg7ZwkdlLdvaMaAv7y1zv6Kr0UBAQBZ0VA4RPfffdd+MS6urqf/exnOFMLCgpS+3v06NHDhw9HRUUR61kkiioskhAE+jYCvDzA9QEuFAnWBKWIBTQqZljFBQsWYBbdt8cuoxMEBAFBQBAQBLoIgVbsELuoValWEBAEBAFBQBAQBASBTkcAPjE9Pf29995btWoVZMHNN998++23I0W0bWjz5s2lpaUzZ86MiYlBtWR7SdJdgcCuXbtyc3O7omapUxBoKwIYOz/66KOTJk2CW4RVVLTMJSUlba1H8gsCgkCfRECRKIrVc5+cXBlUFyEglGIXASvVCgKCgCAgCAgCgkC3IqDwiR9++OHnn3+Oo7Qbb7zxjjvuIOSrbSeI8kxgFryqYfAowRlskemi9Hffffef//yHSSFUThc1IdUKAm1CAHnyww8/rIiUiQG9bNmy1atXFxUVtakSySwICAJ9FQFhFfvqzMq4uggBMXzuImClWkFAEBAEBAFBQBDoPgTYA6BP/Pjjjz/77DP0iVg4widGR0fb9gDO8Ycffjh9+vSsWbOGDRvWOEi0bWZJdxCBioqKlStXAvju3btTUlKIhGNH73awfikuCLQbgSlTpuD0wNvbe8OGDUlJSbCKOEngoUEgl3bXKQUFAUGgDyAgjhT7wCTKELoZAaEUuxlwaU4QEAQEAUFAEBAEOhkB9gBpaWnLly+HT0SfeNVVV8EnxsXF2TUDa/Dpp5/yL4FZRKJoB06nf8zPz4fhzcnJqaysJL42xM3IkSN9fHw6vSGpUBBoBwKXXHKJRqOBWCQofHJyMt4SeOUAqxgcHNyO2qSIICAI9A0E+DnB0TfGIqMQBLoHATF87h6cpRVBQBAQBAQBQUAQ6BIE+PWPPnHFihVo4sxm8/z58+ETExIS7BqDL0hMTNy5c+egQYNQzHl4eNhlkI+di0B5eTlyUbzUEVzbZDLt2LGDMNyd24TUJgh0BIHhw4ffc889ixYtIhz8mTNn3n//fXwmiN/PjkAqZQUBQUAQEAT6GwJCKfa3GZfxCgKCgCAgCAgCfQcBhU+ETFT4xHnz5sEnYtTceITQWxjhwm2hYUSIJM7XG0PUFWdgcpkjCFyibBNrG2vormhF6hQE2ocAWmZYxdtuu42g8Jjnf/DBBwiZs7Oz21eblBIEBIHejgBfWBzyC6G3z6P0vzsREEqxO9GWtgQBQUAQEAQEAUGg0xDgdz/CN8hEJIpY186ePfvOO+/EurbJBlxdXZEukgFKUbwoNglR5560WCzwicTUZm8GX0OUbYSKWEB3bitSmyDQQQTCw8Pvvffeu+66Kyws7OzZs7CKPFJkoXYQVSkuCPRSBPhd0Ut7Lt0WBHoKAfGl2FPIS7uCgCAgCAgCgoAg0CEECCKs8Ilo34i4Al04evTo5mqERpzbcDSXQc53LgIYkGLyTHBtZicqKgrj9H379mF7TlocWXYu1FJbBxHw9/dHq4hrxXfffZeFSoByaIWFCxdKQKEOAivFBYHei4AIFXvv3EnPuxkBUSl2M+DSnCAgCAgCgoAgIAh0AgLwiZgoEpIFW+bp06dj70y8hU6oV6roJASIrA2ZGBkZqdPpQhsO7EnxZUnAlk5qQaoRBDoNAeK0/LzhwNdqXl4eWkWeLeL9s9PwlYoEgV6CAK8TOHpJZ6WbgoBTICAqRaeYBumEICAICAKCgCAgCDiOAGaJ6BM/+eQTYoDAJ6JPvPTSSx0vLjm7GgHibhPiGWt0KMWioiKDweDn5weZePDgQahGhIoYRHd1H6R+QaCtCPBmAm5x2bJlJ0+eRKuI5f4tt9wiWsW2wij5BYHejoBIFHv7DEr/uxMBUSl2J9rSliAgCAgCgoAgIAh0FAHEbjhPhE/EPd+UKVPgEydOnNjRSqV8pyIA50sIXdwp4p8Ojqaurm7MmDHR0dFEwCBIC2GgO7U1qUwQ6DQECAB933334UKhrKzs448/5jnTQrQWXmns378fohwOvdN6IBUJAoJAzyGgqhSFVey5SZCWexkCQin2sgmT7goCgoAgIAgIAv0ZAZRuCp8ILTV58mSCKvBvfwbEOce+e/fuwsJCRF74UiTcM5TikCFDiMRNGv4lNTXVObstvRIEQODaa6/9xS9+gSMFGEMoRYjF5qz1Ob906dK//e1vxHUR6AQBQaAPIKBYPQuf2AemUobQbQgIpdhtUEtDgoAgIAgIAoKAINAhBPBxhoMzdvjFxcUoE5csWYJKsUM1SuEuQICoLLt27YKOoW6i4hBrG0oRj4pMGXbQx48fP3XqFALGLmhZqhQEOgeBK664As+K48ePRwoNq8jBw6dx1TDmAwcOxEp669atja/KGUFAEOh1CKgqxV7Xc+mwINBTCAil2FPIS7uCgCAgCAgCgoAg0AYE8vPzIRM5kL/hOZEIrdOmTWtDecnaXQgQMxcpIjQiZCI+E5F7kEaxOGrUqPj4eKaP0M8S+KK7ZkPaaScCxIdHqwgPDquoPHkKCgrs6goMDJwzZw7a2+3btze+apdZPgoCgoAgIAgIAn0PAaEU+96cyogEAUFAEBAEBIG+hgA81EcffcTGnn070iEERERl6WuD7CvjIawzMlIEiV5eXiqliPSDqCwTJkwg+HNiYiJBWiAZ+8qIZRx9E4GZM2fiVxHXCrhZ4PnDwYPIdqgsbzyEzp8/Hw+hn332WW1tre1VSQsCgkAvRYA3YRy9tPPSbUGgmxEQSrGbAZfmBAFBQBAQBAQBQaBtCMBPffDBB+znESqOHTuWTf6MGTPaVoXk7i4EsHqGUiTWMwEufHx8EHChVYRqUQhEhIoxMTFEboFVNJlM3dUpaUcQaCcCU6dOvf/++xFEq6wijyPbugICAmbPng1jvm7dOvGoaIuMpAWB3oiAGD73xlmTPvcsAkIp9iz+0rogIAgIAoKAICAItIQAVofvv/++wifCUj300ENIh1oqINd6FIHk5OS9e/fiQhGLUTzNKSpF+ET2afRr8ODBCQkJqD+gFCVIS49OlDTuKAKTJk2CVeSxA5n4YcNBMGi1sKenJ6GHLr/8cojylStXQqmrlyQhCAgCvQ4B5auq13VbOiwI9CACQin2IPjStCAgCAgCgoAgIAi0hAAhPt59910kiugT4RN//etfC5/YEl5OcO27775Dokh0C9zMQR3aGj7TO71eP27cOGxFYR6hYMT22QlmTLrQOgI4W3jwwQfxrlhUVMTjiMNWY+vn5zdr1qyamppVq1ZhAd16dZJDEBAEnBUBUSk668xIv5wXAaEUnXdupGeCgCAgCAgCgkB/RqCiouLtt99GogifiMHso48+Kv4TnXw9wKp8//33/HvNNdcYjUZ6q0R8Vg2fOTN06NDY2Ni0tDTIFySoTj4i6Z4goCDAK43/+q//YmGjVXyv4YA6Vy5ptVocMuCNAePozz//nPUvoAkCgoAgIAgIAv0EAaEU+8lEyzAFAUFAEBAEBIHehIDZbP7Pf/6j8IkjRoz43e9+N2XKlN40gH7Z1/379x8+fHjQoEFEdsYgFAzsDJ85g+0zQkVsopOSkhAq9kucZNC9EgHYcITSixcvRquIenrZsmU8ppSRGAyGefPmYfW8du1awp33yuFJpwUBQcDFRTF8tgZnkfAssh4EAccQEErRMZwklyAgCAgCgoAgIAh0FwLIfN544w2UQOgT4RP/+Mc/EnS1uxqXdtqJADuxb7/9FpJlzpw5BGZRalEoRVuVIufxPTdw4MCUlBShFNuJtRTrIQSIY44F9K9+9StCP7/zzju89lA0id7e3qgU8bqIdJHQz3V1dT3UQWlWEBAEOoqAuFPsKIJSvp8hIJRiP5twGa4gIAgIAoKAIODcCLAbX7p0Kdt1hU988sknCfTh3F2W3lkRwLvcli1bEGpNmDABhkUBRYn4zJzabtJQe8XFxWVnZxMhV8JZyOrpXQhg0b9kyZJnnnmmoKCAx9Srr76qEIjQ6FdffbXFYlmzZg0RinrXoKS3goAgoCBg+1UlmAgCgoAjCAil6AhKkkcQEAQEAUFAEBAEugmBV155BReKbNeHDx/Ovh0j2W5qWJrpGAKIs/CQOH/+fESIMIlKZfhSxHwMzsU2EktoaCi0Y1hYGPkzMjI61qyUFgS6GwEvL69FixYphs+wii+++CI9gEZn8fO8glVcsWJFd/dJ2hMEBIFOQgBWUayeOwlLqaZfICCUYr+YZhmkICAICAKCgCDQDgS+/vprRIKvvfZaYmIi++R21NDWIi+//DJ8Iq7KsHd+9tlnCYnQ1hokf08hgDgLq+ebbrpJtXqmJ66urgqlaCf9iImJwYY0KytLKMWemi9pt1UEtm/f/uabb27duhXFdOPMeHflYUW4Z1y+Pv/882SAVVywYAHC23Xr1u3YsaNxETkjCAgCTo6A3VeVk/dWuicIOAMC7s7QCemDICAICAKCgCAgCDgVAkQYeObppxOPH4dJhBV6/bXX7n/gAdiigICAruunyieiT4RPHDlypCgFug7tzq0ZS88TJ07gTo7QtxqNRq1cNXy2VSlyNTo6GkqR8NBCKapYScKpEMAqf+XKlevXr+cBSDQhtLdEnJ89e3ZCQoLST85fcskl//jHP/785z9/+OGHrPDHHnuMkNCffvrpyZMnP/nkE4ko5VQTKp0RBBxBAEpRYRXl54cjcEkeQQAE3P7f//t/AoQgIAgIAoKAICAICAIqApCJzz333JmUFPhE9slYrVaZzXv27GELjQs8vV6v5uzEBPbOxDpAn6jwiagUiezRifVLVV2KAIskMzPzF7/4BfJDZeLy8vI2bNgwa9YswkBXVVXNnDkzIiJC7QN6LkJCExsa2gXndOp5SQgCToIAYltoxPDwcCSKWOinp6fzDNy8efPx48d5KrJotVotj8SgoCCs+FntxHomJwueCC3IGykyZsyYqKgoISacZEKlG4KAIwjwPpXvLBT3U6dO5Q2ZI0UkjyDQzxEQlWI/XwAyfEFAEBAEBAFB4EcEiJjx+O9/v2vPnoqKipnjxv3s6qviIiKyCwre//LL7QcPvvXWW2RdvHgxXvB+LNMZKVs+ETZz2LBhwid2Bq7dVwfMC44vdTqd6kVRaVuJ+GznS5FLcDGQiUTIhVjsvl5KS4KAwwiwdGNjY3ncEcEcOS12/XANEIU5OTmbNm0iZPncuXMhEHkFwouWX//61zhYXL58Obb8OIuATD98+PDHH3982WWXsdQdblMyCgKCQA8jIBLFHp4Aab4XIiCUYi+cNOmyICAICAKCgCDQ2Qigu0lKSvrlww+npKaGBQT85Rc/Hz90qNFg8HB3DzEaIRY3/LDzP6tXE4uAH9xss6GQOqsLxHdGn1hYWMjmXOETienRWZVLPd2DAPyLwWBo3JZCKbK6Gl8SMrExJnLGqRBg9cKSwx7yEmXatGm7d+/GSSI2/jysSktLT506hWU08eghFvn3gQceID9n0DPyhIR/RNL4zTffcJXzTjUu6YwgIAg0h4DV7PncOa6Kvrg5iOS8IGCHgPxktwNEPgoCgoAgIAgIAv0OgZqamq+++go6Lysz86qpUx/8ycLwoCAvT0/lJ7W7m5vR1/faGdN1Xl5LP/2UYKbwidddd51tFI72QcYP9zcaDrboeCV76qmnhg4dKnxi+8B0zlLnl1BD3Gfn7KH0ShBoGQFkhhCLKBZDQkLQ1R44cICnJUbQeGkwmUyIFuENuYppP84WeXy99957//rXv2ASt23bxtMS80mhFFtGWK4KAoKAICAI9F4EhFLsvXMnPRcEOgeB+nMu1fUuXvIGvXPglFoEgd6HAPFJ2SH/9a9/LSspeXDRoptmzw4LDGj8fl6v1c6bOIHhvbl6NXFOidOC3Z+dlWubBo8xLOJEwknDJ06ePPmJJ54YPHiw8IltwrC3ZGadCKvSWyZL+tkkAhCLOADFVSjEIppEJIqYP2MQnZqaivNEvCgSkgUHizhtIIQL+sTy8nJMob/99ltCPxO2SJ5sTaIqJwUBZ0OgQaR4rvFPIGfrp/RHEHAeBIRSdJ65kJ4IAj2AQE2dS3ZZbX5xRXJOuaXmnKWmzlxdV11bb6mu9/fxHBblkxCmDzFo3FwH9EDnpMmeQ6DIVH0io9xSWz843MfHW1NZ4+Lm6mLQDPAU6rnnJqWLWmbf++qrr37xxRcDamufeuD+y0aN8vfxae7HtLdWO3fChFJT+Udfb8QC2t/fH81O+zoGj/nuu+++/vrrBQUFyHl+//vfE0dVWKf2gen8pZS4z87fT+mhINAyAopikcAsRGXBUcONN96IRBHe8NChQ7waKS4uJk4Lq52oLHhdJDMm/x999BEUZBdFtWq5t3JVEBAEBAFBQBDoagSEUuxqhKV+QcBJESiprP3+RMm+00VpeRUmk6XCUldff67+3Lk6/jvnwr8e7q6btO7eGrfwIN3AMO+4YG8YxhCDl7ub0ItOOqcd6RYzXl5Vm1dqScmrOJ5WnpRZnlds9vJyDw309vRw12g8fb09IwK8RkZ4xQZotMIsdgRrpynLXpdIAi+9+OKWrVuN3t5/fPi/RsbHY9rccgf1Ou2106eXmkxrv9/xwgsv3Hfffdj6tVWrSCzFDz/8EItn+MT58+c/9thjRP5l+91y03K19yIgKsXeO3fS88YI8NJFo9GEhoYGBgZi8nz55ZfjYBFPiwSKhVLkKuGtKKW4EEWlCOEIq9jW52TjduWMICAIdDUCiiNFWmnu3WpXd0DqFwR6HQJCKfa6KZMOCwIdRaDIVLM9sWDb4fyzuZXFpmozUrR6FP4unp7uUEhanYe31sNX51FhrqmsqskprU4vNB9MLtFr3AINmnEJ/pMGGxPC9UIqdXQanKZ8ZlHVnqTifUnFeUVmc01dhbmutLKmwlxbV3fOzc01LbeSX1Xubq5QzBoPV4PWzaDzCA3UDR9oHDPQL0jvpvMcICSz00xmGzqCSJCApMRZ3r9vX6i//x+WLBk3dAg+Ex2pwt/X9+bLLy8oKd24Zw8KR+yXkRk6vlvGSPCTTz6BT8RUcMGCBURKhU+U3+6OIN9787A8hDLuvdMnPW8OAcyZkSti74xBNI9BXtJgCr1v3z78LapF8Lf40ksvEYQKWbd6UhKCgCDgnAiI4bNzzov0ypkREErRmWdH+iYIdCYCWUXmjQdzMwosgQHeO47mnk4vhUnU6TyjI/xDAvRhQXotAkQ3V/48Gvij2rr62tr6moZ/cwtMGbmlx9NLz+ZVfnckf1S8/8TB/mNiDbBLndlFqasbEUCTeCKzfN/p4sSzZen5lYWlFktNvdbLIzTYJ1Cn1ZlroI1hEqsstebqmipzTZnJUldXn9Pw2lZ7tmzvqaIAH41e6zZsoHH8IP+RkTovd5GvduP8dawpFDRY6uHHMPHYsdiwsP++43bH+USlZWJA33z5vLzi4l3HjkEOIsaZM2eOI6wiu2sior755pvwiTfccMNDDz0UFxcnfGLH5rMXlBZKsRdMknSxvQjgscGv4YBYxIEDb0qOHz8OschrGxIwFKgXn3nmmccff1xYxfZiLOUEgW5CQKEUu6kxaUYQ6BMICKXYJ6ZRBiEItIZAcUXttqMFK75NN1XV6b09S8stbq6ug2KNY4eGwiLptCgTPVtwmBgSqI+LNuYXVmTllWXklGw+kHsgqWjayKAFE8KiArXCJLUGv9Nd//5E4dZDeaezTDnF5rKKGkzd/Q26IaG+0WGGIKM3ktWa2noIxQGuuNerxySefxVWsaTczF9pubmg1JyVX+HqOuBkpmnnsbyESN+RA/0ujfMNMxAj2OnGKx2yRQCHX6tWrVq+fHlqSkpCdNRvb7vt0mHDHNQn2tYzODr6xtmzCkpKDh48CDvJpVZZRfw2fvbZZ2SGT7z++usffPDB+Ph42zp7No05NmMpKSmhG7CcxHjFqpFQDL6+vhJaoYNTI5RiBwGU4r0CAR4UWEPz0ODJhqUzD7rk5GTiPnPweFENKnvFWKSTgoAgIAgIAoKAIwgIpegISpJHEOjdCJwtMK/fl7t5X3Z+iYWRIDwMNHonxAQOHhgQbPR2ZGw6aEcvD6NBGxHqGx9tPHY6P/ls4ZqdWZmF5ivGhYwdaPDRysPk/7N3HuBxFWfbtq3ee3eR3JtkueKKMc2mGEwJhBZMDwQIkJCPL/khgYSQfKGFYprB9NAxxbiDKXHvXbbcrd57l/9bnjA57Err1Tbtat9z+ZLPnjNnyjPnTHnmed+xBki3CPPVpvzP1+ZmHausa2gJDPTrkxTZOzEiKS4sOjIorM1xYvumr2haG9m9p0202MxfGMbyyvqC0uri0tp9xyoP51fDMq+KCxo3OHpEn9ARfcLF56ZbVPZPM4GF8rFjxxAJfvbZZ3m5ucP797/ryismjBhhA59IxH6+vhNHjjxeUFBaWQkT9/zzz0NWnn/++Yh1fprsf35VVFSQ7muvvcY0e/bs2bfffrtb8YnkEgUlFtmoilSO/f39YRXZ4zUjI2PmzJmye0y71WrlRShF2XvHSqwkmKcjoBYk8LHIMXLkyFGjRrGCwoYtYWFhnl40yb8g0O0REOq/21exFNDhCAgL4HBIJUJBwI0QaD3RIyuv9rO1ud9vLywuryNnSBQHp8UNTo1BjBYa7N+pvGIGGxkWyP6/YSGBkeGBe7KLVu8uzimqnZYRd05mQp+YU+zq0Km0JLAzEMBV4idrchetzzuSX4MKq09y5JC0WMhEqhWxKpJDC4lyNzDAl38qDEMuNgevqmmoqW2srm3MPlJyLL/ieGH1gdzqxCj/zAFRmf0jRvePIlYLccotVyIAn7h3714YvR9++KG0pGTEgAF3XH75pJEjbeMTVc7DQ0JmTZpcVVv76TerduzYUVdX19TUxOTZnFVE+vfFF18sWLCAvQuwCmRTF/wnurL41qRF5g8fPgylSP7Z0ZU8UyIexHpx9+7dV1xxBRvRwDNaE5WEMUFAKEUTQOSnlyBASzLs5OEl5ZViCgLdAAFhFbtBJUoRXImAUIquRFvSEgRcikDLiR57cmo+WZ37w44CLJ1Rn8XFhAztHzcoNSYqPNBm52XYR8dFBwcGJEaFB+09UHQov6Lk3zll1U1zTksakGiV5tGlKEhiPyJQXNn4r1VHlm8tLKlojI0JHdAnql9KJG40NUv4Y0Cr/uf9CQrw5V+P6BDGXvExoaXltXsOFO0/VJxfUnsov3ZDVumcyQ1nZcSHBEpHYxWkTg0ENcZ2AW+99RYuFBsbGtjZ+bZLL52ckW6/PW9yXOylM2ZU1tQsXPUtJn5vv/027wNOEo2sIhZ/uBV7/fXXCwoKkDHeeuutgwcPdmp57Yz8rLPOmjJlCpGgu1yzZg17uX7zzTds8JqUlDR8+HA7I/fOx8Xw2TvrXUotCAgCgoAnIsAol8MTcy55FgRcj4DM9FyPuaQoCLgCgfrmHjuP13yxLnfNzjY+kW1Y+veJHto/NiU+HM+J9ucArSJSR6jJjbt8MIJesSm/tr7lssnJw/uIXY/96Do+htLqxgXLDy3ZmO8f6J8+NKl/n6jk+DDehF6OGDAx6kqICeFfVERQeGjAvsPFlVUNu6ob2dqlx4keZ46KDxVW0fFV2okY4RPhxdAnbtiwobmpaVha2i2XzJkyKgPL5U7E0nHQPgkJsIrVtXUr1q+HVXznnXcIa2QV2Q0GlR984nnnnXfzzTcPGTKk48jc4g6MJ34h2UgB6MaNGwcVu3z5cjDEhpHNZAID/6PILi0tRdKILTk+IqFQ+/btSwAMpc3LkJWVhf4RhSYR4motJSUFo29cNBo3QWYj7KNHjx46dKisrAzEmpubleU1JCaW154+txFK0fytkCuCgCAgCAgC7oaASBTdrUYkP+6PgGOmE+5fTsmhIOBVCMAnbj1ag7+8DbsLMEqNjQoZ3D8WfWJsVLCFPVg6C5G/n09yfPjo1hNNTS2Hj5et2laAXe2VU3tnpIZ3NioJ72wE3lxx5JvtRYkJEbwGeE6E+HPgm6Aznxgbis9NbOq3ZxXkFVYezKv5YkPe6AFRQilqiFx/gs4OhR2bsaATZF/mtOTkq2fNnJaZ6Sg+UZVoaL9+15w3i3PNKkKBKQtoSDRsotetW4c7wptuugkTQNeDYHOKGC2OHj26srIS3hBCdufOnfn5+fhHw4r84MGDn3/+OeWCKIQNDA0NRcN42mmnXX755cnJyTpFyMEvv/xy5cqVeXl5cIUNDQ3R0dHx8fHp6elXXnkl7tUUq0i0GIavX78+NzcXghJdJ5QiNBwEJcGgFHWEHnoihs8eWnGSbUFAEBAEvAoBKEVhFb2qxqWw9iMglKL9GEoMgoB7IaD4RPwnwieyn0a/lKihA+L6946CRXJ4RpG4IXYbNSSxsbHleH7F6p1FrZhb9+gjrKLDobYnws/X5325Prd/v9j0IYl4TsQnpj2xWX6W12zEoPiw0IDte/NxsJh9vHr7karoMP+QgPZ3fbEcm9y1EwH4xMWLF2OMjJgO6go+EeLvrAkTHMsnkkl23hiRlqZZxezsbBLlOlpFNH1scgIphgtFT7QahhtldwWUlVCK4AmBCKXI30WLFr377ruwjTCJ/fr1gxP897//vW/fPqYid955p9qKBFoQ/OfNm3fkyBHIQSXPzMnJ2b9/P/4Zifn666+HXiQYG9e88cYb3OJn79691R7TEJeEQf/IXzvfhC5/XFSKXV4FkgFBQBAQBASBUyJwklE8QbfbDXreUxZWAggCDkFAKEWHwNh+JDRJzAfs91TVfuxyVRBoDwEjn8gWvUPS4uB3YJEC/J1F6MBP9U2ObGhsgb7ML6pas6c4JNAnPMQ3NS64vQzKNVcjsDqr5M2VRyIiQkYNTUqMC3OGONGkSLwSUNjIFZua2+Srn6zOiY0IzEwNC/D1eFrEpKRu/hOxG/pEEz7xwqnTItqzzLW/LOasIvbCRAurCCUHDQdZZn8qXRIDpB6ZhxsFUvatRuyJ7hJRIXyiEhsiS4RFZStt7LuhGtFjDh06lGBIDufPn4/JM7TjVVddpeyXjx8/jryRv7osqBfZMwc+kS1rLrzwQnSR7AwLngwhGEhgKK1Deu6JUIqeW3eS8y5BAKkyCxVFRUUsMOAqAR20MRvsJYXwGW8SuEdA+i3bRhnBkXNBQBAQBAQBVyLgakqRwTF9JKPn6upq+r+EhASsilxZYNekxUQCCQOulzD4mjhxYjcwWXINbpKKnQg0tfTYmVP7xfo89In4sBs2MB79IFupOHudDb6yf9/ohia8tDUXl9Wu3VsSHxlw2eSUmDDZGtXOKrX38R1HK95YcaS6oXX6hBR2UHEBn6hzjBH0hIze/n6++4+UfLYuLzrMr39ckDP1kTplOWlDAFPc1atXv//++0qf2D8l5aqZ5144dWpEaDue/hwFmWIVrz1vFlrllSf9Kr755pu0P1hAey6fCDgUgVk9U3qGLtCI9Oy4jIRDZJ6Pd8jLLruMtUO4RcSGWEYXFxdjYw6lCCG4a9cu8CeGSy+9FKNvRQowQuBB2MapU6fGxMRwlyuqClAy4pARggDjaDg4ddHT/wII5t5CKXp6PUr+XYwAzcLWrVtZuoiLi2NXq9NPP92YAT4r1mxohVitcX/vtMacy7kg4OYIQFa4eQ4le4KAuyHgUkqRJTX8jrPdJA7IWedn88S0tLSxY8fizhyrKHeDxp78MJGgm3/iiScYRjPf+Pvf/95t5gb2wCLPOhuBw8X1Szblb9hVwJ4bwwbFZwxJiIl00ZcVHOg7OC22pq6xfk9eUVn9ys0F0aF+M8ckhgW5tJFxNsIeFD8Douy8avjEPUcqR49M6d872s/XifbO7SLTLzkyMMAP+eqmfSWJUQFXTE5OiPQXpWK7WDn2In0QrBYTzs2bN2PvDJ/485nnzp42LeKnOhfHJqpig1UcnpY298ILggMCvtm4EYeDZAPNHeI7j+4HjXMMiEVWRikv+sHMzExliwDnyDkDm8bGRsycuUstYAetYEGqqcc51MgZZ5xBhMqLIgHYB4bdWqAPMIh+77334CWxfebgIn/1bjAqKo/7i003nihBiXfD4zIvGRYEugoBGhMO5My4WOWE5oVGRmUGcQbLFR9++CGNDCsQ3O2qTEq6gkC3RMDY43fLAkqhBAHHIuC62T7kGgZBTC2WLVuG6ZAqBgPl8ePHs6/iueeey7jZsWXrwtjo4ymjmnKgE2EtEaMny/kBH0bbHM4WlFnOhtz1XARKqpu+3l60dmdBc2srLvMyhyaxHbMrixMW7M/WH5XVDXsPFB0uqFm0Pj8hKmja8DYNjhwuRoAV1uMldWzJ8u+dxTjTTB+U4Ofnaj5RFZltoMelp/x705Hlm/LDA30uHJ8QK9pV578NMFnsx8IOxehc2vjEc8+9yCV8oioZHRms4s1zLkYRuXDVt/Br7AHNZBiVjYeyisDIOijdOgMVCsJ8HlaRwjKGwSZalRp+EI0hOkQ0jLhc5CJPYa+g7kI+agKRK3T0xr4eow0cTcJFwh1gUs1f+EfSwsRhypQp2DoY93tREXrQX0Z95FZUih5UZZJVd0CAhhSXEdOmTXv99ddZb9i2bRvnKmNMK5YsWYJiGu+0qKSNjYk75FzyIAh4NAKKTzzZS8siuEfXpGTedQi4jlLE5Qdr7x9//LGxcIzL8R9EN4lu8aKLLqLvpAc1BvDcc+YSKvPQi0wqLFCKBEBOsnfvXgbcY8aMQbkpLlE8t967KudQSGv3la3amtfY1DpiUELG4AQX84mq4OwoPSQttqSsNreg8mB+9Xc7i0b0DYsOFfNnV78XLa0nlm7JX745PzjIf3x6SlREEMJVV2fix/TSUiKLSmvWbzv28Q/H+sQETB0eG9BF/OaPOerm/5eWln711Vfff/+94hOxd3aNPtEE1t7x8Vecc46/n9/SNWvp5dmihAE6U2JPZBXpxLFTZuUPPhFFIeSgUiaCMMbOuuD05vykmOouJ1o9BAWJVJMrOrDJybhx47ANx24DiSJp4UCNcdEnn3yyceNG9oy+4oordFQmD3rKT+q92wzwPAVzyaenI8BSBJvI05hj4/X1118zR2DdgoYoKysLP7k0R2effTZaZmMxYRsRNqJpoC0iALMPFiRUi6SD0VKx7IGjRkhJYiMkbRotDMnheMHTZdG6mHIiCNiGAJSiYhVte1yeEgS8EAEXUYqsvSPRX7lypYKYrgsXinyuOHviL10a7pYwj7r66quxBuoGnRmFosNWheWc+YA65yKdN1fo3TnU8Lq8vPyll16CWmWygWkY7pYGDx4sI28v/BrtKXJOWf232wsLyxvwnzhmeHKX8InkH94qOT58UGpMZVV9dW3j3mOV2w5XzBgZZ0/R5NnOItB64sSx4trlmwsgmlP7RLN5jitdKLabW3ZrYffn43kV6/aVDk4J6xPbDV3otltw11+kl1m7di2zTVR1A3q36RO7hE9UBU+Ji7vmvPOS4+LeXbKUMQCsIiK+CRMmuB4We1KkB8dhCxs00y8z5cYHNLN6JU4EZIg/DA+Jn3EOU3SuRERE4CqRKwx12AlaJc1m0Jdccgn9fkc5YQBAYA6WV2EwGRHBICxdupStXWAVzzrrLI8WKlJqUSl2VPVyXRDoCAHaEKTKfP7s8oQXCyTMaJZZb2A+xdyBW7ip1c+ywgHVyBbzNFbs9USLxCoFrdM555zDioX2XM80hM3r161bh5tXmhpWO7hC04QyetasWddcc003mIVpTOREEBAEBAFBwAUIdDi6dWDa9GpI8Oj/6AWJlmElQrzJkyfDrCFdxCSKLpBZEEN2/J0zqsYO2hNVDEbEKJpWKaLExPqMK8qnO5ZTnLMYyDFixIj+/fsDCwUnGDEsXLgQBcR1112HxRMjCWOccu4pCLD2i98o6jc2NpZppwte5ubWE6t2FmUdrYyKaBMJdhWfqCooJMgPp4oVVfW79hfmltRvzi6fMDAqJNAVTY2nvCHOzmdT84nFm/MP59WgCho+IK7L+UTKi3y1X0pkSVnNpv3lqBQTowL9fDqUazkbn+4dP40PO4MdOnhwSGrq5WeeOXsa+7H8ZJ9QFxc/MjR05sSJ0eERbyz6MuvAgZdffhmxnuLgXJyTTiUHjUhLzl+6bMhQtnLGyyH9MipCqD1EPWh/oA6RE3777bfsjUBTD/LKwpcJuSogs3TMEtWmLuy7DR1JSH7SueNammk8GiJllMBPRgjkkI6Dp9izBdYStRFkoqIGCNyp/LthYKEU3bBSJEvujwC0IDQi7QzTJdp22hbaIqZUtD9QjcynVBGYWcAPPvvss0jU+dZYnKAhIiRtCMLnBx98ELf1ajiKZvy5556DVaTxUU0NzQ6RMBHjcMGQ1f0xlxx6OQJ8TSBgwarAy/GR4gsC5gg4fZ6PDpHOjE0n6eRU8oynIQ0feOABfrI4hphCeQmhJ0Or//jjjzNeZxTuWTI9Jhi4T4IWhD+lyMwEYFFVeZmToMFctGgRpTOZFcydO/fee+9lfoXZAuwqjzOvYOoCz4hckevmFSZX3B8BlpHxGcoLzMiPCSSzUHbrY/tONWhzRv6PF9dt2Fta3dAybnB0dISL9mOxUJDYyGBYxYKSmryCyr1HK9gkZFTaf9yNWXjKo2/x4fN107h1+RCktfUEXhS/3lqIhWViXFi/pIhevdyCvGN/mANHSnIKqrYdLB+SEpYQ6ZHu5OmzCgoKmIYxnevyujb/ZNCt0NVu2bx5WFraFeecPT0zs2v5RJXD4MDAyRnpLLC89vnnG7duZTZ79913u/kWpVu2bOGLpkeG0WMGjvyQJSI2W8OzIW07B6MU6EWEhMztmX4wscd/JfuQMEunaDiJpuwEY+GQaT/XcYX22GOPcQ4XCaVId4+eEf+JPEgwbNWhI6k+3iuIACLknHVWFlzhFhV9aV7dnnUFqoKSelaeJbeCQJcjQEfDYBKl4QsvvAA/SLOAryQWPEaPHo2iWWePQXAnNFEAAEAASURBVAiiZuYaXCEwB2NOmh3mFMgbuaXGorQtn3/+OcNU2hl2nIesRHat1NO0eFg90+DoOOVEEPBaBBSr6LXFl4ILAp1FwLmUIuQa62CvvfbaqlWrVM4YU8IYDhw4UE3GYM3OP/98htQPP/wwIQnDoBwr4EcffZTVe/eZsNGyMAGgOBx028wHGPdzqPExFxn3M+tgDoDQgAknagX8nqgiI1fkOof6qf7Sl8M+wKISMxZSGDsDBZEwryB+DJ2YbAilaETMg855yak73mTsSnhVeNtxf8PkE+IYblFJVBxbHIxJD+dXwx+l9Y5CJOjYyG2LLS46pG9SRGFRdV5p/aaD5cP7hvv5dFvVLd8sHy+jdhYDUlNT0RQ4jz4+ZXXUN7V+uTHvWEEtTOKwgXE+Lt/luaMcJsWFxsWE4lRx84Hy04bGxIb7u4N8sqPctnudxpx2nhkaEzw8//I5QzM544tuN/VTXkRPB721ZPHiqKDAuRdcMH3MaL+OzWxPGZtjA5CTYan97r7yipc++eSbH36g42M5bdCgQY5Nxf7YGHWogQfOyzhozLEWZI6NwGf69OlYLjMtV6nQsGNyCNWIdOjdd9/lIg/yMvBiXH/99XrPFvr6O++8E1sEDJlpJRA8GjNJc8EAgCRQO+I2kTbEeJcBBsMMLBZxCIP5gvGWJ54DJh2iJ+Zc8iwIdC0CdDR4VGQBAzcLb7zxBhIEGgRIQxhAnTEIQXbBohViBeLPf/4zy9ics/VldnY2jpV49tJLL6XPou3FzSKBGajMmDGDAIxX+TZ1PHIiCAgCfCaAwBfEIWgIAoKANQg4kVKEg2MlTfOJypZn6NCh+BJmoV5njutMz37/+9/fc889DM25/sUXX2D5CwWj1s10SAeewOXBAhC/5X6UNgVNCjQf8wFYQtQKdOSQg/AF6enpjPIhQ8kV5NEzzzxDh91RDmmSSIi5ATwpUw78lbAqyFBASxExA2e9EVkEDlDo7DknWEexyXU3RwAZC680bwXLwhAQvNXULMvCvNKTJk3izWEkx4STqaZDClJd35ydW93U2gMVWGSYY+K0P2NhwQE4VQwNLS6trN9xsKJodGNytLvkzf7SmcRAW4cWG4tOWgzG6Gxri0yJsbvrV/sZBVXUNH2zrYhBUEhwwMC+MW41HoqJDA4M8NufU7XnWOXglNDIYM+bxkAhQQzR2iNU5FtmtQBvVrTn/ESe1oVoM0VcvXo1+uj6ysrbLr3ErfhE9b1AJ/VJSLj1kktLK6uwTuAi/b5m6Ey+qa76SbNMherGmY4Ya2VYPyoavSF9t84YX/fMmTNpzHFXwioglgo8xZCA3VcJrINRapwjP//889hqwBgyfkD5yF3oQkYFuqNnUKGMM9RCIy8SAbjLkIk5P29aF75auiw2nzDWgo6n4AyoOmIVLRew3bvtXjRm0kIAC7eIoaO7HV1XibZ7t92LOpMW7lq4ZVsOLUeosyQnbogAdUczQoPDXAP5BU0HOmgEGcas0gXQN/F9MdRE2YCMUd1lrkHzgpkUplRcIQBNmfKo8OmnnzLjYHWEdowRC71YF66GGssi54JA1yLAYJ5D2syurQVJ3bMQcBalyLCY1XgW05Q+kQElQ22WyFDpm08huMuI+a677sIamnE5CMIq0ufp0bajMGVQi4oQZpC+lpG9mi3A9LEAaNKP0vWiE2T2uHv3bvrv9evXQyZSKJ0TykVzoyhFnJUgZ9C3TE6YGFBkJgbIHCAa6Lz79Omj3CcZQ6JTgFjkMF40nsOBknnMqNWEhCEF0xs4SpOcGx8xOSf/0KMMO3iWBUz+mgSQn45CAHgxJ+FArLpkyRKc4DDnxAkOTATCHFabGQ5ywjozLyFviD3p7jletetwRXh4cEpieGCAs77ozuaQhb3I8MCE2NCKyrqSyoYjRTXdmFLkM2SZhO+L+qWWcY6OPRHEIswCb4LWK3UWQxvCN7e0Hiiozitqkyj2TooIDwlwqwVWPCoGBfiydc+uI5WnDYn2OEqRyRiEETM0Vgv4qJEEYtDK+gFfNBsZozhjSobiw84v2oZ6p2vDkA1vfWVFRb8477xpmZnuo080FgcAU+Ljbp5z8bGCAtDj60CrCGjGMF17ztf6pz/9yco8qF6bhSIsFeiaacyNnKMxEkp6++23c4VxBWJSTui4GXvQC6tJC3withrcIipaEgZFRAVr6endNPlntENPx+iFoRR/VXn1VK2jE31dwah/qhPjX2MAHcx4kXMrw5uENMZmjMF43ZiQvm5yYvLT+Ig6tyZd4/zWJEKTnyax6QfNg7WbE50lfaIf1Ff0iYVbhLHnrj2PW07XcsynfNbC43Y+y5oEk5GOViJpQ9jYiqkEtswEQ5xhnEzRBdC2kDeqm01XsPTSmVFkIhMHJhHqZUAPocxoWORgLy8+Ujov1sIZtLCgQuT6WSKUQxDwWgTkQ/DaqpeC24CAswgIqCuYFMUnMovA2PnKK6+84YYbGCi3m0u6tNmzZ7MdJBQMfR4MHQwjPav6npVOkAcZ7tOtdjTIpk/lWZIzbwW4DkuIXoxdF9977z1IQGIjGAQfC3o4SILiYQSvk4NDxGoVdgD+kWjN88xFzTAyDoBTgKYkaUXz8ZfOGwsFHmSagV0zllDmkVh5hahwzkieUX2yCAkZSj7BgUEAnAXmtJwzjyV1HSGP4KeZKyw8KrjIMM/iZoXVS3IL2sxhrKcjdcxy0ikEIJ2ZSbKYjPsbptAw1Iz2GBF+/PHHaFFhkKlBrFSoEWannYpZBz5YUINQMa1fdLB7mDzrjEWEBibHhR08WlLT0FJQ4fF7C+hytXvCIj8b1iNRhE/EJxo7MkE5YQKJsSQHXyhtl/ELbTcS+y82tZw4WlRLPDCJ8Hdt/7nTEYtdfiAcSo+D+dVFFQ1DUzzSXSydBQccIhUNS0KLirdcuEX1RWOmyhdNdbtStIiIHpfEe3bv/tlZZ5192mnhbuwMC66TXclunjPnsQULPvjgAz4c+seOZtHu9PJ2mBe6Y/JvZRGgETnajYvREdQbR7t3PfQiIxOGQCihaP2UebiHFqRbZluNeNVfXUB+MmA23tIBTE5MfqoYzC+qKx1dNz6lw5hf1Lf0iXkYrqi7Ooz5iQ5jftLRsyqhjsK3e90EQBWDMX7zjHEFzcEvfvELhg06ReMJAVjNYrWSASTNJoMN413OVZwkjRcFPT1RYRT5qAeZDP5/97vfsQLKwRyH5RDmCyjc6dGYpjGS4Zs1iVx+CgJehQDfkVeVVworCNiPQPsEn/3xopiAlVN6OiZXcHY///nPO+ITVXLcnTVr1osvvsiXjKQLW2PWypB70DVCAioXIUiB6PCg0sxzSFr0ozwFiQaDaaQdiZC1cWjK+fPnY4Kqn+U6PB0H1CF+0+mhmQRCvZHcq6++CounQ3KdkTFzBjg4skTPrYxYVQDOYQyxbCUAS4is9TEyoAi/+tWvEF0ykuZZHVWnTsgMC4/wUHhZgpBiXG7yOEME5JzAC20BLKrUJMoKJPwsub322mshrcgw7lT+3//7f9jhKh0oxNYf/vAH9DWuF9SYFMEbfrL1Hrb8rAxDMzGGg9tFjQLhzoFkFWIRnQuLwwzj1DtmPSatJ3ocyK2ua2iJjw4JDnQv2WlQoG9ifGh0VHBtfWNBeTenFKkyvnQMJNlzCQ9H1DKrF7QtGDxCH2OvxJ5UNE00BXrpwvpatj4kKsXDhW2UItMLKEU3YxR7hIf4h4XQhPbKLa7LL61vbG71dxtXj9aDrEKe5Iqn06EoN1X0PqxCYc/LMhWfM3c5gR6iui13fJ1N1zw8fcSCBQsQm0wcNWrm5EkJUe6+FVJQQMDZ48ftOXTwnSVLseOjv54zZ46zUTLHTa64AAFEl6TCGqfq3axJkYGZNcEIc8qQpwygE7IypDXBHBVG5c2a2KwMaSEq81vmV8wBJ4w1wdrNns0PmmdDxe/Rfxmr42CBgTqHhYIwE1FLF7SWJqwfww+6G/QN2CHBPP7v//4vIU1iS0tL01dodZkdXHXVVRhjMR1QQ1P0jHRnrIoxa7CQDbklCHgDAu22Ud5QcCmjIGAbAk6hFCHC2O9YuSGnh2NyBeNmTqsRDKYPN2SKraNHRPrB3iyqJIxB1fcMS4gAhK6O65ib4VeoXUqRpTZINGbvzOfvv/9+tHsqHiKBvmGGjyEAUXGRhGA56cJJmskY2UBg+Le//Y21QVxiERj3IkY+kY4Zm2WsDOhoIYCQGMDc6Y6ZCOmbb731VvpmCD5jMVlIZJ5JBiiLyoyFv4y8yQbRQqQCGiHh/ig1ZadQysukepzUyTzZZuiA9BKXKBC4TGV/+9vfKuEh1+FPESRSUoqMggYukuLjqFHxicSD1y3kVJQXmsNCruSWAxHg5WEMhwNN6gu+CX0T1cp4Du0GrxzUMOaTvGPw0dAQHEZavKNsVNU1H8yp9vXzCQ8L8HW//U9CgwJiI0MOHq0rLuv+lKKqI8b6MMisfFDXNINffvklO/CiIPvXv/6F1RLrDZjDqxbPGSq25tYTx4rb/CUxMQH5jl6bLrweHhYY4O9bU9t4IK+msKKhd4yN4twuLIIxaZSJHD/72c/QpUIpwjDSd7B/C7478OaBHRmVjkKE6R/VbXzQUecsubGaRQcXGx196YwzhvbpA9HiqMidFw8WwnMvnL1p796d2Qcw+KXzhYE19qrOS1pidiUC+Pdg+KeGXmpEp/6SB32iz/UVkxP10/jXWATjdeO5jtZ4YjxXgfWVjp4lQLthTB43CXPyof+WsaPIjdd5/40/dfwmMRvDqFRMAlj+qaPV8XCiDhXbj7/+e1Hf1bdUEsaf5s8as2EMaXJuEhV3LTxoDKyDcaIO9eyPvyxdtCF8pyI3D2x+xZgHyL777ruP4Z9J5jv1ky6GORSDfwYezAIYUjJ5YbJA0oz8GU9qAQETBy4yVmGOoGYBsJDYPzHjwNupMqDuVNISWBDoZgioD5Y2maObFU2KIwg4CQGnUIr0SXBYSqLItIrpFuIdkwLwuaK0R1tB54c4EZECPR+HDsYcjN6On8j94P7Udbi2jrQMxKMkeAj08A+iKUX6TrpYRIgMamka6HRhdjAugLiB2cHbI50omWE3RuyUofNIi2yQNJydSpRu/rbbbsvMzIQxVFnSmdQn3OLQPzmh81ariIqyNN5q9xyO6fHHH+epP/7xjwwLSAjvjVyB+NM8IBcZIiCEBFVAZmmRMHCgjB6gCDFkePDBBxHIUEyFJOUiACFfeeUVAqga0amjzQR5cZuiAFH9hwZHn7R7vd2LPNLudZOL1OBJL4sTsZeEhuDlhIbAtJ+/kIy8RbxpBICJYPtgRoHYzOrMmJ/sz63C6tltOz1/Px/MsRsaWkoq6puaW/08VpJmjvwpr1B3fKcM65lRQzCxhwPG7yyKsCKCLhWzWT5kmgjaNEI6atTS3HLieGEbpejTq1d0hDvuh4N2VXHfeWV1ZdWNnaIU+ZSMyzOARpOo/56yRpwXAIEJewFzsEiAewoU+nzO9C980Sw4QSyyEkaPQ13TMut5nUPyg8kzlCKNyW9vuSVj4ECP4BMpOLUWHx31m2uv/dXf/k4XRk/37LPPOol1dQjOEonNCJhsImFzPPKgIGCOAJ2COrhlcvLjnf8usegr+kRFqH/qExWbjlNdN/7U5/rEJIzJde5yxfyivt6uVEI9YuVf+hfWMpn+YMiMERK2EYgN4fRZdmK2RQfERIzBBikiRaTVxYmtmmeh7cBiht6K/hS9RTfzvWAlehJMEDAioD9n40U5FwQEAQsIOIVShE/kUKky16JLM88BTB8kF2bO3EJnRz93wQUX4CJE9a/8RKWlptlEpbkw2D2kf+axQdvhhPHAgQPcYs6pbG045zpGpi+88AIzLn4yY4GsQZDINI+fqEvgdzAHVm5HYBWhAFiyw44YigcyTrGKWAQgNsQXJEJFnGQxJ1QZIwYLB32zIhmJROfHQni6czJJYdES0vfTr6O75IrmE5mIAib246ifFM3EuAHo0LgxPoA3hEtlGPHcc8+xMRzlUmnBkKJSZC9aFQ8++7hOYIUMSZCWYydy4E99GWf+esxkXnwLtwhs4a5tt1QGjM9ybuFQeVCvQbvBCMBdbqmQ7YbRF3VsOjwvMxsW8VYrAgJ2m1eF74KDT4CqQe/25z//2cL2BXtyqqrqm9numUwQv7sdAf4+ocH+5Ky2sbWwojElxikkF9+v+oRtKD7fsvqc9V99YkNs5o/QDigVM3wTUjJIZCr3ww8/ZCcNtM8sANAi8cGiW+QzZL1EpW4ej5VXWlpOFJXVEUlkBOsf7ri4GthWyra1osbmE2gqrSwXwfhqkFEAoH6EGRQzIppZ9bdd6LioDp768bQNFs71FZOfOph+kABWHnQQyJA5YPqU53v+stUv6zcI8ahuvGQQRtU17watusqJlfGbB8MdIR3f6VOmTBgyONSjdtzy9fEZM2TIxdNP/9fSZXheptdwbE9kjpVcEQQEgW6GgA2tdPdAwLzjoGdlqZKpClYv9JWMMTh0YR966KHLL78cKysmX7hNZF6jb6kTHqdvYkDCYqfJLfkpCHgbAmqa5m2llvIKAvYg4BRKEcaKQ2WLqb4mxYwZRVjHpEtdgRrDLBeqDjpM0TesrTFLVF0mdJ7mpyAB2zXUxXqU2BTzyAqbYgyJHFNilEGoRVRC8HSYJ0PWsChHxuBxnn76aZUisztW8OhTCfnLX/6S1BEwqjhpWfCJ9pe//AUbZPwW4xEPZR+RmPfoKhX9t1NNko6N5US6fLJKHpgzq9i4yxrmLbfcwq7ZSoHIdXhDjMqZqTKAQIYJpNjcQSA+8sgjFJAAZACW6h//+IeKhPDsZcm07a9//SuocpFywWdRHBXA/r9UAaud6HSYSIMwGeBQpBsnKn798+TNn/whgA6vztVtVUfqnOvmMZgE1iE5MQmvQqoYOHfbAyR37tyJG03qCD6io3zmlNTVN7Sc6ImotqMgXXkdSjEs2B/2Bt61ybBhugPzRFWynMBhQ5x8Vorc4S9fNIc6URc13aO+TfO/KkX1jpmkbn6RzxZRMAeya6SpqJJpfzhwtogbTXSLHKy+qE+eT1V/5iYxW/4J1GDe2NTq72/XNuKWU7HnbmCAn1Ip4kgRTaX1UdEq0pijxdai9VM+Sw1SlSDJwYnJ+ckK/0+lc0vVPidUAQta6i98JVdOmVC7AWjDqW4k5yxr8S2z8IMVPMsDLFyhQYZHZnZHjdspCWEJim5uaGq/2Eh3d6FojhKgX3/h7PeWLed7YRig1xHNQ8oVQUAQEAS8HAEGIXRMSAoQB9C7maNBbwV1iF945BpYbunJFxMc+k218srsjA6R7kmPUoiWA9fq0JFMcNQgxDxyuSIIeBUCfCDq0/CqUkthBQGbEXAKpQgXxqHyhFcOpHaa49MZ5UNlCqd+8t2iCrzzzjvVT25hK60kflxRzJS6haqLWYc6138JgPwHZ4LqCsIuTEc5h2ugT2WvFR2SnLD9LoIg2EP6VyMNgbsrfDkpSpGuGltFZvhQnEz+KYLKA9QkPo+hO6+55hoWA5kcatJBJ6FPKJTqv7miT/Rdenou8rhKkeuUSw0RoAWVqpEuXxeWaSdkKGuMGjQdFcEwcEBiCZnIg+gW+atVojoYQw1YUUyQOGHpEuKSPBBM07U6pM0nAA7/xaY0xhj0qMV48ZTntj2lorXmWQZYp8yDywKQYXUYU1Q9Ga8H9Wu8bnLO7haI0eqbWk90RvBlEonzflIKtHdBQX5+vj1DnLMhNWpi/CfgqdD8K7OzXHyPbYST4eDbUb84UV+r4qb5a3JCZrjCX2pWnZMZdUWHpHK5y2cIK8TBHAC4VJ6xA+VjtyH/ilJsaGxtbnZLjrlHD2343NjcwmYy1peRxpBWF58VOKa0/inApz3ksP4Rk5DUEVeMf/VPHVLdVT+N5zqAPoH+Y9GFgyus5dCV4EJL37XhhO6Md7K6pLSxtq7HT51v2BCbix/hdUe0il/F6tpaxgz6/XdxNiQ5QUAQEATcHwFGgzeePCxklVYUVxscDC2UQIGRBrMVOlA17mUaxWCDeQ22zyxdc5ElTDhKmERpgS0AK7cEAUFAEBAELCDgFEqRbo9DpcomLWisMPFj2mPMB4whdp10Zkywjdc5p/NjoYxJu7pOJ6f7OTVFNwlPEszQlOyOW/SLyryX3hQrOXWdGKAA1OMo+JSIT8dDj4v5M+nqhLiFfuSJJ55AcIevfeJnKqi4APR3HLhIYzbIVjBMC1U/rWPTJ6pozDDNabtly5YBC4+znKjIUxBTEKEr1BpPHRUkKRZzJhjqu2CllYYkiskDh77LCTl84IEH4BPV8iNsKVbS0LiMKpS00xjY5nNSQXpz9913K6D0JFz/5EpHF423ODc+Qn7UXfOLXNF3VRiTv+oRkzDqorGubS6yPQ+qYoI/Azvqi7pAh0WEZIwXkncYIp7laDwqWkglwM8HZ3KMHd3T8Jmckz8sHMlmaEA7i+oWimblLZYH8MSKCT/sv5WPEMzK2qfF4DDK4mhGFLGo/vJJcqIO9XkiFuagRqhZTniWz5+fOm/Uuz5XJ2RGXVR/+ZYZ4puEsfInUQX4t9HlTc0tVj7i4mBIFJVFdlPziZZO8uB8FDCtkGguyzM1wgvAh4mGjr9Qk/xVFUr9qlrmrz5RF/nJU7pOdcNlzDY1BYmGLwvjRRvO8dLIytl3mzZNHZWRGB1l5YttQ0LOeKS2vv6RV+dX1dRQs26Sc2pNVZwuLxlzk7zpLMmJICAICAKWEWAYaS7mUI8wjGFsyWE5BrkrCHgtAibDAK/FQQouCFiPgFMoRaZ8iP7gyNqYrfJydiRgRxSm/Vp4SP4Q3kOTzZ0797XXXjPJLg6GjRMMmD66RhUGLQ+2z7g71I+w6QqOyYxuQRj9K44Pa2jc5BOS7hNbM8QgbCeNvaF+Vp0we3/mmWewIDYn7EiXTXgxUoOwgATEayEqPPUUPCaOC5FA3nHHHYgEVYrGmHmWnHOF+SRskfEWmGC+B5EEXwkIJpQiZYQMNYbnHEA4TC7qn2SPzR/UTzVWMO5YzXWmnYgctTkDe9eocx60R7+jM6BPKPVdd92lf9pz0r0bdF4JKhqqGiIMelcDBYBwiHwC1Je6aHk2G9CmUmwzK2YLXffc/wR6rbqmwc83PMhpprjYlmLLz/ZK6tsHEQ6Tc/2TE31uEsz40xhMhdd/dWVZf6J4SejFk3xjG8+o2EYaAV4DzJ9xI8tCAk0QzRFtUWpqqvWRG0OiUgwOYPEGTtN0qcYYrAvPYdt4XckAr2unDJ95hK+DhSgO1+e/s82RIiJpXfm6MXmmqafvoOVXOafNx+qZ95aW2c6y0PvQ/eGL8LNvv0uIjh7Yu7edEbrs8YbGRvK8auMmviz8FNNzuSxpCwkh81fLhyoMuWL5kPGMhUfkliAgCAgCgoAgIAh0GwQY8nV21Ndtyi4FEQRsQ8AplCIzcyZLSOG++uorsoXzeHYxxt8fgn2kdjhD5ENl/sws2kim6AJcdtllqH70T+yRNRf5zjvvoIPDQZVixLD2RcCPgyqjDJBZOjwjq3NY9ar4oSBxEYLRHH4D8WmFQ67s7Gxm9cSMFzMUkXCg5FmnaHLChAclFKbQ7KSBtBD7YjzcEYZSYAqNp0ISuuKKK5juGh+kCMrtI3NL9IDGW+zUzEWuQIKgalG3mGEqTpOMoaxEFEMMOk6ki9B/ZNgYD+fIYcgDHiGVETc07uzZsyExMfHWIRHCPPzwwxpDrjNBgtLlhJyY0J36qS4/AfYuz4PDMwDFABm9YsUKWAAoBl4hKkungkEKrxlW/7w5VhYfSRrkGTEUltX0q2+KCP3vnuk62i48qa1rKq2oI4tKOue8nOBWnMPO+K3E3IZU+JDbnEGEhuoxCpu04KsBTplGgI+RhpEGioPVF37aTK+gCY0J9zuShz31f98rGzLsvEdwoajEiVFh/qFBP2kznZeo/TF39t2gU2BBi/5i7dq1LBHxmdOe4/aenpGDlSR6KOLULbzNOcSc7de//jUN/hfffZcYE33teefFR0XZHJvLHkThuW3//qdPuiVhtez3v/+9+ZKeyzJjTAhvJxg3qA6a63yMbJDluZQiAwnePV4zhkwW3mGGAQyKGB3xl/AsOrKYim81C+MiI2hyLggIAoKAICAIdBsE1FidTtNCv9ltCisFEQQcgoCzZnQQf1CKzKZg0/gykeSw+L9t2zamVchw+EQxPWbUbqQCdXmwLOMR/RljNM0cjFkZLCQDX8b3MJVYJcMbMmeDa4NW089yAs+4bt06RJHEowycGRaTLn9JGlYRnSODZpLgClP3did18JJMLRiFowGByONxQqI6xOzurLPOggt466234PKIBC4P315Mh2CCjNkgWmVWQBlh7sikTghtoyo4RVPUHg9qw2fOIZ4IAK/EFJTpDaIJdEzz588nOQb6ihwEDcgpoOAgALeICj+Pt956K7f01jeU8X/+538wpdR4En9qaqpKFzxhKgHKSDgaSyHnjkKATTmgEVeuXMlrw9vFy89LqCJnRk3FYQI/derUvn378i4ZK8tyBk6qFNsoxeKy2jo3pBTrm8qq6v18egYHOqupUfhYj5hlPJ19l2+WdwAmEUKZxQNaALy7ItHik6S1oZHhg7UnD/jWHNk3YtPe0k65KbQnxc4+iziR1penoqEUnfxWdDZv9oeHwaGbY9Xq66+/phGmGWetCKZYqd1hamAAqWUOB76xuA++7eabqysr312yNDQo+GdnnxXlQttwG0Cj9z1aUHDvU09XVlfTt2IlYOJ1xIY4HfUIq4x01iz1HTlyBLE/5/Stjorc9fFcd911NDW4WMGoQplNmOSB0tEcsTTLe8uXyUEAWiGGH9dee+1NN91EBZk8Ij8FAUFAEBAEBIHujYBHd/3du2qkdO6JgLPm+dAikHGo7SDCFH0Gh8LBLBo+BSwsfKuvvPIKe5ZpkovRLXagbJoJF0MM0GfM1mBnGPsy3FcjYHY9RkhIAGZxLLNzl1k6czaVCo8waEb8yBU1nTtlZWCnpuaEGDsjHONZtH48TrkYal9yySUQposWLWJTCKgiUiR+KCHt0JD4Cak9lTDP/OKLLy688EIIUB7BEpycEwZFIcIllRk2YOERdU7ZOSe5KVOmQMtiN0fB4RYhFgmvoqVQMI9wtcBLMZmpYi/JtIEAIAxLSFRAB1eFC0XNZqr4meUyCyXnVAccx8SJE0FP3ZK/jkUAsRKeN3mXqEc+ByqLqlSvJbUMW02tcaAHYeZGpXeWUUqKDgz0ayOhSk5Sio7NvP2x1Tc2V7ZZPfcK6XbkkfXgUN1wE3z1kIm8DHyzrB/QPJ555pksliCRVisW1kdoISSUYkZqm4eElubWxqYWfz+3MCY1Zpg2W6kUY0K7D6VInVKzNNQcyE5pmVm+gkakAedAecqnrb5uWnUjGg45p9GYcvrpeHl8ft68j1auxPz5vMmTaE0cErkzIikqK/vf554vKS9nZQsvxkDU2XbPGblSceLJRNGI2FXglYXdn5yXlgti5lVk+EFHrzod8xRZ4GR7K0xJKDUy+bS0NBYa+UlvhbMXnAzQTJk/JVcEAUFAEBAEBIHuikBHPWZ3La+USxCwHwFnUYrkDH7tlltuYUiKpTAMnc6ryYcKF4ZBMe6K8IamiDCG8hB2TLn18jiaRLZAfeqpp2DuGB+jIOBQETJPYwUezhGpF/QllKKiHZkJMG9nfIyKkPE0K/Cff/75xRdfrLNh+YRHYH/IDycvvPACzzKwhriEzkNMxOCbATdWQvB6xEOKOMmCNTBSimReu96H48P0+29/+xshyb8qJrZUlJHiq5wwmteKRWhBVXZcQEJEUhaG+KrUKBCVp0W4VIUkCOB9D8trYFRqRArOZizQsty65557dLS6yExrMR4n/0gUEXWi5RRKUYPjqBPeB0hnqGQQVuSvor+JH4oB4RJMIm8UjBJvlAnna30ehvUOCztpPVpV3YCJcUpCuFuxSHX1zZVV9THh/kP7/Ic6t75onh6SBgR90IaTB3pqWhIOKH48LbDgwcoEnDKfuWM5JtjbwSlh4aH+tXXNeUVV/ZL/s02W+4CZV1RZU9tAfngr1KvrPnmzIScs8+Cfl4MmmsaZVprlAeTG1DLNMs07zS/rWDbE3KlHaOrPOuec/IICetuXPvnE38/3vMmTOxWDywIXl5c/86/3dh88yCdw5513Ivwn8y5L/ZQJ6bVM6s59iM5TZtvmALyljJ2oC/ZSP++881huZIjy6quvwjMy8GC5VChFm7GVBwUBQUAQEAQ8EQHm12qK7YmZlzwLAl2CgBMpRYbjKO+grjDuw3EY/uPYmBKXT7AnXMe/IbZ+GPYy9YJc4yJs3a9+9StQgHGDDsNIBwmPmmxwl4Hvgw8+iJ4Oz4lwYczcUHjx8/TTTx8+fDjPMjPHVyOcGhJF3FTB0MGswbL985//pF2AO3v++eeZJCj1YrtYww/C1sGvESEHrtmUVTUTRQbWxPDBBx8ogzUihByEJ4IjUFFBDeipiLpCWphQkW0YJcKz8s+h0yUwJCNJ6EkLvBIDelIhDJlXBecvRSASfHJRLuhRCk7SKh5ghHvlKXgKCkuKip4gcuy+QZjHUcq0y1nAZlIpixcvZgJMPDpjcmI/Agg/YRIxfqQ2eXkgoKkRXle8AbRtLTFkCBXqKEYpOtQ/LTn0UEFNbX1LSXldbX2T+1CKldUNR3PLoRQHJ0al94uwH1j3jwHWGF0qNBMHsjW+fZoIXgCaMjbiYIWAr5LvlEN/+I4tFBK4QD+fIX3CNmeV5rofpVhZ3VhcUtvQ2NaCxYZ5MKVIH4TumCaUTk2pwunOWNxCcMfyGC0qn7xqwx1bvxZig7u84sor2cscpxzvL1uO7fPE9HQL4bvkVkFp6bPvvb94zZrEpCTW2HBCAlD25IRelYpgjyMiYZzAYIM+EU8jbHtFr40Ynx6f/lEnQe9J+0xnCgXMt0mtTZo0iYGE+cKbfsTyCbvAQShjIcHYhnqnP8VeQflepDWAlcPQgS6YXJGK8atH0Io7aUY7dNb0CAwt+ImenUEIbw5RcRGfm6w/GSlp/L1gr4ASlrETAVhk5VVkgEHBWTFVi5o0OKxmKUfSmG9TZLw/q/GPKgujhQsuuIBhEj9JggVIkiA25VSauyRKvRAP4w3LxZe7goAgIAgIAoKAICAICAJejoATKUWQZSQNU8ZQFb0eM2o1u+Yi41dG/9BwjONR5KkRMwNxSMNHH32UgTgeGNlRBGUiA3RCEhVhiOTSSy9lhkA8jKF5lpk59mVa6QNlc9ttt+EAiFssvBMGIRjDfdw4MqpmCvHII48wBGcvXXxaqZkMA3omHogoGaZzQsykfvPNNzM6JzMfffQR3BCDeB6HG+Jo93UhNkqnBug6AMWEMWTl/09/+pO+yAnpIjz8+c9/zsyTnOtbhEdpyOSHDKDK5Ke6RQGZd1E0okILyYH6ibtch0hl9K9kbjo8T3FO8eFqOTEmodPihMd/+9vfIiOFuhVK0YiM/ee8abxmMNTUmjqgEXkZqHreTA4qxTi3tCdF9mYZlBK2YW8plGJhSXV1bWNkWKA9ETrw2dLKupyCygB/n97xIQkR7rVvjAOLqaKCWcCuGVIAwkI5JaD94RvH9SoHn5v6TlVb5/DUjRH6+fYclRaJO8Xcwiq8wP3YkBiDdNl5XnFVVW0DyKTEBUeHB6idhbosN51PmI6ALcIQnlLRdAfouWj8aWlpt5WGnYrmAze2xp1PxPYn6Exx6UsH8f57/3pl4UJ07JMzMmyPztFP5hUXz/vwwxUbNozMyKB/B7qOuifrU6ZDpIvHsoFHgJ1vDSN0RhFUDSfED+GIbbViFblC9WHNoO7yHhKAZ1m3w965s/0gLwMrBy+//DKLBwwkIOD4utu23v7ss3vvvRdymfxADn744YekC/U8YcIE3eyT9Ntvv82LRP/LoqC6zgiEtUNIQB4kKvIGRchQBCEnS1AKE8TvtDOonln15C62yQxauAVJiotnNmrjIhnjOqQqqZAx7mK9QTaIVkUCY0hm1IiF15VXV6WoAsBX4meGPBOMbks9In8FAUFAEBAEBAEvQYDek5LSJ6pu0UtKLcUUBOxBwLmUosoZw2WmOhyWM8pkjOkQwi5MtxidYzOIVpGJB0NnxSryYVuOh2DMCowTA1byYc2QE7JKT5yoDhnuow6A3CEYTQaSIkbkTDBQmjCGVo0Io3ayCg2EahKVJaNzFGcM9AlgLALJIUaAtYRPRJBorkmhRPgxJH6UlfCSFARzV4byiBCZSKhCGSOEByQerpjwDkwtOMgwyVEKlUnCcHTU2HEdMtcYufk5gimOjmIwDy9XrERAKWehhqkCDl42/pq/HlbGdspgg5JCMCAtKOuRX1iVV1gVGxUc6O+K79pyxtgrJie/sqC4Cm+PQ/uEsROx5fAefZfG4Y033mD5gSaCNgrFEB8ymziz2Q6GhByuLB22zxMGRb29sldBUdWJHid69nAj5PMKK2vrGkFjQFJIvAeyzJA17CUCmUhjDhMEF8OaAfVLU89nrgkjV1a3SVow17j6hdT+fOHC1z77nM5iyqhRJmG65GdOYSEW2Ss3bho2ciQKfXBzCFx8bmy5RreIWA/3JugT6RbpSTHXRdQP2whPhxgfShHBHQwgYj3AocpYnqQLZimRFaD333+fqoSOpBKtBwdnxJ988gljA1Jk8YDBBusKLCZBN2MbQSNAKqx6ooJcuHAhOWFcoTtchiKoCMkJfDTrgqoXhr+j72CoAE/KXRSOBIADJVdXX301YwDyxhvIeIaECMN1BhJpaWkUHI0kSkkWQX/5y1+SHwhNxQbSLkExM3LAGF+XjrEED+qSGvsmhNVsNwcxqpY2sXLQweREEBAEBAFBQBDwEgTUXNtLCivFFATsR6DrqQdjGRiCMyBm5M0cgAkAQ2RYRVR+jM7NCTjjgx2dM6BnJM18D8dArO0zSoY65CC8ipCpiMmzUH7MRpiTEIAFf7LEkP3KK6/kKTLGOJ5WRqkjmcwQTEkFWeo3iYefTJkQFyBIRFlJccgGkwcescDiWS4mEap5hXlaNlyxkA0bYpNHNALUMof+6eyTYX3CMwZEFpQ3VNU2HS+o7JcSGRjd9d91aWU9EkX24oiLCBiacorlBGdD5Oz4YQpoNPigoBXgSpix0zhA7hjn6s7Og47ft1fP1ITgMYOj1+8uKSqpiY8J/VGcpIN0zUl5ZX1eQRWG4CQ/MCmUF6Nr8mFHqpA1COFRkcPR0DVQy6wWuFtDqvzi0WHhyXXBF1/QYU3NzLSj0A54FJLss+++/3rT5uEjR/7v738PgA7hE8kZLS2sHB8d9sUwa5D7aOtYiUxNTUUYCD0HsciCIiFZOMQknE6cr3LevHkYT5AHenb0iejyWGuEdtSk2ynLzMgBghL7YmJj3ZG3gu8dzKEm/+///g9iDpEg5ggMDDAxhlKEB8RMHjmk6uKRGeJipY3wnTKFIYRKDhtkkCFmRgvkFvEjXCeqZ6woGMbgOkPnipEM7x7cMcQooxFGSugiSWLdunWKUmQtEyaR8Ax7oD55lq2fdUKKddWx6RNITHZrAQrWQZWLau0PWoeRE0FAEBAEBAFBoHsjIHxi965fKZ0zEOh66sGkVEzO77vvPuZp7IjCuJaxMuoDLKQYr5uEtOYnkz1G3koYyPo/m64yrFcPGslEaD5mAggNsLOGFGA2opk7JgyICjloXxijM9bncUbkHMwNTjkvIgD8Aoc1uZUwgoANCAT7+0weHrvtQDmUYl5BZWl5XWwkrvq6UpvGXsNIJvOLqoIDffsnhabGh9hQLg96hPYKqRR0AK0NrMQpmwVnFy04wPeczPg1O4u37y88KzrETTiv/UdLsYXHGjcmMmBgcmhkiBttymFljdDsI6VncahLyGIrM8nrx3ZbOABBTYk17OtffMmDXcgqFpaVffLNN5+sWjVsxIj/eeABelhgtLIspwxGVHTfdM1UCoH5ABGQIhBWFQTZB/FHh84tFMRYB9Nrs8KH+E5Re/Ts2BlgFMxIQ9kInzJFFQD+DgKOJUaSg31jiMJXBpmLz0TGMAxdsB2GUiQVmEoEgwRm+AHTp9JFzEjtsFpJo0HroeKkCKoUMIaMT8gbEkv4UBSIyBKNlCLhuUu6gMk5NU6JML/AwJmf5ESvaSkzfP6yPsqhEmr3Lyl+9dVXsJ8ABQ2KZ2qIWgfWVLuJykVBQBAQBAQBQcDdEGDKz+Emg2d3A0fyIwi0i4DbUYrkkgnAXXfdxeo9voEYsqMHUaPwdgtgzUXG0wzcWW9n2M2KPaNzxAsM6LnOHIBxNiN+JTZkcsL4vt1GhIuE57AmRQkjCLgSgdFpEaMGRhUiVKxpOJ5fkRgX2rUeFfOLq/cfKamtaxrcO3T84KgAv16uRKNL0qLd4OiSpM0TRag4YVD0oD6he/YXDOob3TcpomspZnKIfjbrQGFNTZtyauzAqNSEEA+1hddkjTns7nMFjgk+6KabbqLbglWc/9lnNfX1Z4wdG+DyvZUP5+a+9dXiH7Zt6z9w4G/uv59FO6eyVNjzkoTiEznHXlhJBSHpUAWiIiR1/r700ku6sjB8xpqYIQE8oPVTCCLB4zORICfEXSN+WlSEKh6WHtVOa+DPoALXKBggs5yJITMeDFFKoj2EuUN7yAhEr0DwLPbRCBhzc3O5y7AHipCcQ18yXNEZVieIZBWfyE9WQBneENI8mMlTFn6y0Q0MJpvDkCvcOgOjneMuC2nJLUFAEBAEBAFBwP0RaJcQcP9sSw4FAdcj4I6UIh8wPsgYauOPDPUBfJ/9RB6jdobgDO5Z6meAzuSBQT+zC0UE8FdaDde/fJKioxAIDfSdNDR6x4Hy/TlVcDcD+8V0IaVYUl67O7sQq+fIML/ThsWMGeA6G3BH4enp8fTs2QMN4BkZca8sOrh1T15KQlivXg7ThdkATkND8459BUWlNS2tralJoWdmxKfEdMJpnQ0pyiPQTOjucbsBVbRu7dqauvqKquqLz5juSlbxYE7OW4sWfbN589Chw3597704MHEqn0ilYwWstXgQiwweOLgOaUinzwm8G9tDawaQK3CCDDNOKhLa3LFbeTB+UBGyQolFhaYF0frB6wE+caqoKDKiPyhFOE12isMFJ4bMrJWSEySNmqGGbXzxxRfVjs8MUbir4uREHSYZo3RIMvVFBSzF1Fc6e4JIkwMcWNPFkbTwiZ0FUMILAoKAICAIdA8EOjsk6B6lllIIAvYg4I6UoioP9oN4O7KnbObPwhsyEIdb5DC/K1cEAc9FIDM1cuzgqKKK+pLSmsM5ZTGRQWEhXaCoRZmYdahk/+GSpqaWAWnhU4fHhgd5nn2r574GOudoAGeNSfxqQ8Hh42UoRoekxvr4dJlWFJPnoznlDY0tbB0zfWTc8L7hgV4gXNV10VUnEFu458MCGsnbpo0b3126FM5sjqtYxQPHj7+9ePG3m7cMGzzkV3fckTFqlLP5RHCmf2/XHyL0nCLgGANgMgyvZ14pXDeuLHLOAXXYLk/HMqSKkHXKiRMnQsMZIyQbmEKrK5Qa42hEo/CYK1asYBMY7K8h76DtWODUy6W4ZcQyGqEihtjjx49HYsmUBkMNDmPMxnOyZ/xp4RyOktgsBOAW7lmuuuoqWE6ySqEsB5a7goAgIAgIAoJAd0VA9ZjWd7LdFQcplyBgPQLuSylaXwYJKQgIAuHBvjPS47KOVW07WH7gaGliXNigfv4uti2lDz5eULHvcHFNbUNSTNCU4bGDkv6ro5E6ciUCsA1JUYHnj098bfHBzTtzE6JDoyODumR4VFBSsz0rv7Kqzao0Y0DU5OHRMWFte9fK4QIE8M3HjsPI3EgLVvFfS5dy4gJWMfvYsXeWLIFPHDJ48O233pI5bhy+h11QXt5wLRg0Jsd1oMCJCvbIqAXh9TBANvkc9O4l6kFIQ5R6QAf9B7EIS2iMEOfOatNkZIk8CBlnDEDMmivkKbSTeHXEwhq7ZjaQwbQZhSPOnXlQ5QHOF+tpBI84XmTHGByz8giJYoms1Y7G1K0/V0ngkJpSo980KbIxHlJERoqLGDhZkSgakZFzQUAQEAQEAe9EwEKn6Z2ASKkFgY4Q6DLdSkcZkuuCgCBgGwJDUsKmjIhNiAosLa9FJ4gBsm3x2PwU5NGeA0XFpTUBfj6ZAyKnDo8JDuhKe1ubC9I9HuzVs+f5YxNHpEUWllRv3JVTU9d0Cp2SE4rNK7F68xF2DWpuae0TH3zRaUmwzL4+1qqrnJAjr4sS8gvHxDfccMPYceNg+mAVP1v1bcPJfcacgUVzS8uWrKxXFn723ZYtQwcOvPWGuWNOm+jr7ywSGcYNt4YYd0P8URwIPvUTc2YTXR6UGRsucxET47fffltZH8MzQh3yLDyaCReJSTK3iBMGcMOGDTgZhA3ct2+fcqFIeNg3vBlC1RFg8eLFuGkmclLhL6kbhX7EzMYs/CXpBQsW4CoRppJK0ZvOMWnhEThE8o+qkcgpF/wjhtKcwD+SOukSoLNV1q9fPyJE/Pjll19CUGJwTR7Y4RrdoklUbCDDrtkPPfTQRx99hLdHk7vyUxAQBAQBQUAQ8BIE6Mc5vKSwUkxBwCEIuEI44JCMSiSCgCBgGYGgAJ8zM+IO5td8s63w0LFSbJ9DgvxDXGV3XFhag9s+zGyxFBzYN3zaiNhk8ZdnucKcfxeh4pzJyU/kVu09UBQc5D8+PSXQ33VtPnzimi1H0czySvSOD77qjD6ThsSEBLouA84H2DNSUKyiyquygO7Rs8ec6dP9f6q8s78w8Ikbd+/B3nnb/v3pQ4fe/ItfjJs8xTfIiX4zcYwInXf8+HH4MvJ/6NChefPm4dgEm+JbbrlFcYKqXPB0c+bMWbNmDXtAs7Xxnj172JoZ3hB2D37tmmuuwX7ZGB6/K2rvFB6BYuMcdg+hH7wkwk/4wfT0dJwkzp8/H/khRCG7bHMXcSKSQ/jEP/3pTzo2GEPsoAm/devWZcuWQRHi5pLtnrFMV3lThtJkDOPol19+GSNorK0pEVwnakp2fP7kk0/QMCpeslPVxM4wX3zxBVliV+tt27bxJlBeft56660YxRvViGwtTbrkoaysDNtn7ZKyU8lJYEFAEBAEBAFBoHsgIBLF7lGPUgrXICCzO9fgLKkIAq5AIDk6aOqImOycqn3Hq5T5c//eUS5IGD5xy+68fYeK8aU4MCX0oonJo/tHsu+wC5KWJCwjMHlIzPdDY77fXrRtT35QgF/64PgAl7CKvBLwidl41Wz+D594dmZCRPBPrEct51zuOhABxSoiWIPz2rB+/TuLl/Ts0fPi6ac7kFVUfOKbixZt3b9/9LBhN15zzfipU/1CQhxYCvOoMGReuXIlTKK6BfennA/CDyLMNIan7LCE99xzDxQkYWDQ2HZZB8DWGKNjTQJyHcIRCg954N69e9etW6dC4hVx2rRp6hzSbfbs2URLbEQFraljQxuIqBA2UF+BPWTvaYIhqOQiltewmXq6wgl3kRCyPQviRAJQX0ggJ0yYkJWV9d1338EGQjJCAmK7reM0OSESzVHqW7hlvP766ykyEkv2j9bXzz77bMpipBQpu3qcv0arbf2InAgCgoAgIAgIAt6AgKgUvaGWpYyORUAoRcfiKbEJAl2JAB70MtMi8aDX0NSSV1LDNrtsiJEUF+brzK05FJ+YdbCoprZxUEropVN749UxKtRZpo5dia8Hps3Wz9ec0beuoWVjVunGnTn+/j5s1RLg71yDdF6J1ZuP7j9c3NzcqvSJ52YmhAuf2KXvDywVm29gmQuZtXzZMrSEaBUvPt0xrCJ84obdu9/66iv0iWNGjpx79dXjp03zCwvTJcZoF9tektZXHHKC+7877rhD8XTGCKHzzHkxxIB4MGQrFag6yEdslskVnCDmz1CKJuG5fuaZZ7JpCcbOhGSCAelGtMOGDVMJIVQkqquvvhqmD0UhYZS1NfEkJiaCszE/nCMY5BFMmzlnDxYSNQbIyMi48cYbx44diyaRtOArETYijUQCSW7JDBQnO7pQiT/72c+40qdPH/04G8Wgl0SYyV19UZ1wC0oRUSSUIjmElyQqBJsmfCKBuTJ37lwIUwro8J3xTHIlPwUBQUAQEAQEAbdFQKye3bZqJGNui0BP+Wzctm4kY4KAbQgUVzYs21KwcHVOfnljv5TI9MGJfZMjnGTxasonTuk9I0P4RNvqzYlPbTlY/uqyw9uyy6KiQoYOiO3fOzo2KthJRPPh3PKtJyWrLS2tQ/qGz5mUfE5mQliQLF85sX6tjxrrXbRyr7322orly/vEx19/4QWzp02zU6v4Xz5x3/7R6elzr7nmNPjE0P9uzYT+DqkdtsbQaqNHj7Y+t84Lif1vdXU1BB80H/QfbKPWDJokipkwpspcVPI9wpsE4CfjKIDFTpkTgsHZtRvM/EGTK1B+pEUk0JdqcxhyyE94QCK0LU6VBNnDvptSEwmRw3ual5e0yADpkpxJxuSnICAICAKCgCDgJQj88Y9/fOedd+Lj43/zm99cdtllXlJqKaYgYA8CPnj8sed5eVYQEATcDYHgAN+k6EBfv175JXXHCqsrqhqYj4aF+Pv7OXiiWHTS3hl9Yn1D0+DeYZdM6X1GRly06BPd7YXo0bb7c0xEQE5p3dG8Klwcllc29OrVMzQkABGrozKLI+uq6oZ9R0o27cw9eLQ0LjJw6ojYiyclz0iPDxX/iY5C2e54YIvYqhiNGzTflu3bj+TlJURHD+jYnPaUCZryiddee9rppxv5RGJgexA8+uHBkD1Akk4ep4zW2QEg1KDV4P7g18DEnF/TGYBiIwyHBdqRx1UwIoRStBCbjrbdE/g+HudQ7CHxkDdi5qfNcaqEiIciqPISYbuxkYpKq928yUVBQBAQBAQBQcAbEMCfyY4dOzAmYCM1bZrgDQWXMgoCNiMglKLN0MmDgoD7IqBYxdBgv+r6lrzimsKS2paWE5i7+vsjTXOAi8P6huZjBZVb9+Zj3Brg22PsoGj8J04bHit8otu+E71jgiJD/Qsq6gtK6gphFavq0SRh+op81R65Ikwiu68UltYezSvfvb9w29786pr6Uf0jZ09MvnBCUkZqRICfw1hLt8XWszIGuxQdHY2/v5ra2qzs7CO5Oclxcb3j420rxcY9e9/8chH2zqMzMuZed12bPvGnJr3o43BHuHTpUlSBuPNTrKLRz6Bt6cpTgoAgIAgIAoKAICAIOBwBRSniOQR3MUIpOhxeibBbIiCUYresVimUINAjJMC3d2ww/zDUO15YfSSvsrqmsbnlhJ+fT2AAVn62Q1RcXrs7u3Drnvy8wsqUmIBzxiZezH4sAyLDXLW7tO1Z9+4n+8YFwyqCQW1ja1FZXX5xdVlFXVNzK5IlFKydIhYxxoRWLqusLyiuyT5Swvuw52DR0dwKtvk+b1wS/PIZI2Kjw/zRVnk35G5aelhFvPXhmw+r3vWbtxw+fjwxJsYGVnH/0aPsx7Jx716cAM69/vrTpkwx4RMpP+a0OPJjExV8+SEMPHr0KHuqIFUUVtFNXw7JliAgCAgCgoAg4MUIsFUaKkWhFL34FZCidxoBoRQ7DZk8IAh4CgIIxFJigvolhAT49yqrbDxaUJVXVFXX0Izrr5bWE5i5ddbuFQrpSG7Zjn2FO7LyfXu0jh8cNfu05HNGJ/SLC/Zz5g4wngK4++cTVrF/YghWybwApZUNyFexgy6rrGMfldY2l21tr0S7RpEnTvTAN2JNfVN5ZV1BSfXx/MoDR8uyj5RmHSrG8r24tDY02Pes0QmzJiRdclpSnxjrPYVIAABAAElEQVR8yQmZ6NavA59/RETEoEGD0Cpu2Lot+8jR3vFxyBWtz3T2sWP/Wrps/Z49GZmZN9x44/jJk/0CA80fx5aWhDC5PXjwINbWmN/CKrI/ckpKirCK5nDJFUFAEBAEBAFBQBDoQgREpdiF4EvSHoqAUIoeWnGSbUHAWgTYaTc1ISQxOhCqqKq2Ka+o+nhBZWl5XWVVY2MTntDauMWTzsRMOSCUaM0trY2NrTV1jfkl1cdyK1Ci7dxX0NrU0Dc26JwxiZdMSh6VFime8qytCfcIFxHiN6x3GHJCdn9u7dGDzcFRGlK/xWW11bUNdfXNlbWN+N+sqm2orm2qqm4sqcBQujqvsOp4fsXh4+X7j5TuOVicdaDo0LFSnGnW1jVGhQcM7RN2/oTk687sO6I324ubvkjuUW7JhSkCNAjsEYxRT0tr6+YdO/ZkZyfGxuJaEderpkHNfh84fvzdJUu+27Z9WHr6TTffPH7CBFwNmoX6zwX4ROyscUvE/sVlZWX8xAL68OHDuHQUVrEj0OS6ICAICAKCgCAgCLgeAaVSZIAkvhRdD76k6KEIyC6cHlpxkm1BoBMIRIb4TRsROzA5dPvhiqzjVdk5VfllVUdyygIC/BJiQ9mhOTTEr83Lok9PJS6DZ0SShnKtsamlobGlGkqxqKqxoTEyxHf8wHA85fVPCBmQGBIi2250ohLcK2h6vwgUizsHVh7IqzlSUFNYVl9a3bg3u2DXiZ6YxiNX5HVgWwjEiey9U1vXVFffhM9EXQbYqOAg35SY4D6xQUP7RWSkho9Oi9B35cRTEKAeExISbrvttvDw8DfffPPJd9+96aKLZowda3kP6IM5OW8vXvzd1m3wiTfffDNWz0gRLRcZoeL5559PMDabzs3NhV7cvn37U089de+9944bN87ys3JXEBAEBAFBQBAQBAQB1yCAooKEGCC5JjlJRRDoBgicYhrQDUooRRAEBAEQYFcWNujg35kZcUeLancercw6VpVbXFfb0JCXizF0a31ja11Ta0/sVU+0bbgBkwiryIOI2hKiAlNj/If0jRmUEjphYHRYkLQb3eGdigj2mzI0hn+1jS15ZfWHCmoO5tXkFNcWlTdAL9bWN1Y2tqJhxNkir4SPb6+QYHjnXgG+vYICesWGB/RPDs0cGDWqb3hMWJt/Rjk8FwEIvmuuuYb8L1iw4PG332FhYfro0QEdqA4P5ebiPxE+cXhGxq233jpmzJhT8okKGRb8Z82ahZjxpZdewvAZknHXrl3/+Mc/7r//fkhJGbt77vsjORcEBAFBQBAQBLoNAlCKilXsNiWSgggCzkZAqAFnIyzxCwLuhUCgn8/g5DD+NY5rzS+vL6lqrKprrqhpOlZcl1tcW17dBIUE/4j5atvfXr36JoaMSosY2jsM5sghu0W7FxySmx49gv19BiA7TQjpkdGjsbn1aHEt0sWiyoaKmubKmqaaumbWawMDfYIDfTByh1Bm35VBSaHIVAW8boMAxsjXXXcdY2hUhP/31ts9e/lMGzM68KcW0Cwy7D1y5L2lS3/YvmN4ejraxtGjR1vJJyqg4C7POeccWMVnn30W22c2nt6zZ8+jjz76hz/8AWoSDwzdBk8piCAgCAgCgoAgIAh4LgKy0um5dSc5dz0CQim6HnNJURBwCwRQnPWNDeafzg0bdBRXNtbUN6NECwzwCfTrFeDXqX2AdUxy4qkI8FYMTAzln6cWQPJtKwJsx3zDDTf8yCq+1dSr1+QRwyMCA3uetACqa2jYeeDAix9/vPPgoTFjx95xxx2jMjM7xSeqfMFdzpgxA1bxiSeeYJ8WzK6zs7MfeeSRhx56CIISk3tbsy/PCQKCgCAgCAgCgoAgYC8CWqIorKK9UMrzXoOAbM/iNVUtBRUEToUAfSfuEaNC/cOC/YL8fdj8V7btPRVmcl8Q6D4IoBOE12ttbd2blfXFypWRcXHoCqH5isvL1+zY8fz7H2QdPTpm9Oi7f/3rzE7qE40YQUT27t07LS1t27ZtWECzQwuKxS1btgwZMgSGUbSKRqzkXBAQBAQBQUAQEARcicDKlSt37NiBe5bJkycPHTrUlUlLWoKAhyIglKKHVpxkWxAQBAQBQUAQcDACrCuwX0p8fDziwUXLV+RWVFY2NCxZvXrBwoU1jU0TJky45777MjIy7JQT8nhKSgoj9U2bNqFVZOvnnJycjRs3KlbRzsgdjIhEJwgIAoKAICAICAJeg8CKFSt27twZGRk5adIkoRS9ptqloHYhIJSiXfDJw4KAICAICAKCQDdDYNCgQZmZmaWlpfuzs9du3nzw2LHIqKiLL774vvvuGzhwoEOEhESSlJSUnp6+du3aQ4cOpaamwiquW7du+PDhEJrCKnazN0qKIwgIAoKAICAIeAQCy5cvV5SiqBQ9or4kk+6AgPhSdIdakDwIAoKAICAICAJuhADUHpuooCLEPLm8vBx9IjuoBAf/1/Wq/XmFN4S4fPLJJ++55559+/ahBcAC+oEHHnjsscdIy99fdhK3H2OJQRAQBAQBQUAQEAQEAUFAEHAiAkIpOhFciVoQEAQEAUFAEPBcBMaePJyXf7SKo0aN+uc///nrX/+a3Z/hMbGDvv/++//+97+TMjvGOC9piVkQEAQEAUFAEBAEBAEjAuzNordnMV6Xc0FAELCAQC8L9+SWICAICAKCgCAgCAgCzkMA742wis899xy2z7t372bbloqKCiys16xZU19f77x0JWZBQBAQBAQBQUAQEATaRUC2e24XFrkoCLSLgFCK7cIiFwUBQUAQEAQEAUHARQiMHDnyhRdegE9km8X+/fvX1dX99re//fe//y2soosqQJIRBAQBQUAQEAQEAQMCwioawJBTQcASAkIpWkJH7gkCgoAgIAgIAoKACxDAl+L8+fNhFfHeOGDAgObmZljFVatWQS+6IHVJQhAQBAQBQUAQEAQEAYWA8InyJggC1iMglKL1WElIQUAQEAQEAUFAEHAWAugTX3/9df5u2bKFraVJBr+K7L0orKKzEJd4BQFBQBAQBAQBQeBHBIyOFIVV/BEV+V8QOAUCQimeAiC5LQgIAoKAICAICAKuQaBv375vvfUWfOLGjRv56+fn97vf/W7RokXCKroGf0lFEBAEBAFBQBDwWgRO7s5yguLDJwql6LWvgRS8swgIpdhZxCS8ICAICAKCgCAgCDgLgeTk5HfffXfIkCHr16+HVQwNDX3ggQc+/fRTYRWdhbjEKwgIAoKAICAICAIGBIRPNIAhp4LAKRAQSvEUAMltQUAQEAQEAUFAEHAlArGxse+88056evqGDRvwrhgdHf3QQw+9//77NTU1rsyGpCUICAKCgCAgCAgC3omAsIreWe9SahsQEErRBtDkEUFAEBAEBAFBQBBwFgKM42NiYhYsWJCZmblp0yasoSEZ//rXv8IzVlVVOStViVcQEAQEAUFAEBAEBAFBQBAQBDqDgFCKnUFLwgoCgoAgIAgIAoKA8xGAVYRGfOWVV8aPH89uLSkpKfx86qmn3nzzzYqKCuenLykIAoKAICAICAKCgJciIBJFL614KbZNCAilaBNs8pAgIAgIAoKAICAIOBMBpVV8/vnnJ02atH379qSkJKSL8+bNY1fosrIyZ6YscQsCgoAgIAgIAoKA1yGgd3xmBMLhdeWXAgsCNiEglKJNsMlDgoAgIAgIAoKAIOBkBBjQK3Hi9OnTd+3ahV9F5Irz58/HJrq4uNjJiUv0goAgIAgIAoKAIOCNCAif6I21LmW2FQGhFG1FTp4TBAQBQUAQEAQEAecjEBcX95e//GXGjBnbtm0bMGAA20C/8cYbsIpFRUXOT1xSEAQEAUFAEBAEBAFvQcAoVPSWMks5BQH7EBBK0T785GlBQBAQBAQBQUAQcDICiYmJDz744Jlnnske0LCKGRkZbNWCXDE/P9/JKUv0goAgIAgIAoKAIOBdCIhK0bvqW0prHwK+9j0uTwsCgoAgIAgIAoKAIOB0BJKTk++//35/f//Vq1efffbZoaGhH3zwQWtr6w033MAtpycvCQgCgoAgIAgIAoJAt0ZASxQppbCK3bqqpXCOREAoRUeiKXEJAoKAICAICAKCgJMQwJHi3Xff7efn9/3338+cORNW8aOPPmppabnxxht79+7tpEQlWkFAEBAEBAFBQBAQBAQBQUAQaBcBoRTbhUUuCgKCgCAgCAgCgoDbIQB1+Mtf/tLHx+fbb78dP3785MmTFy5ciFYRVrFv375ul13JkCAgCAgCgoAgIAh4CAKoFJVQEYmiqBQ9pNIkm12PgFCKXV8HkgNBQBAQBAQBQUAQsBKBPn363HLLLWgV16xZk5qaOnjw4M8//1yxivy0MhIJJggIAoKAICAICAKCQLsICJ/YLixyURBoFwGhFNuFRS4KAoKAICAICAKCgJsiAKs4d+5ctIqrVq2Kjo5OSkr68ssvFavYv39/N820ZEsQEAQEAUFAEBAEPAQBYRU9pKIkm12PgFCKXV8HkgNBQBAQBAQBQUAQ6BQCsIrXXXedr6/vsmXLIiMjMYhetGiRYhUHDhzYqagksCAgCAgCgoAgIAgIAsrqGRyET5SXQRCwHoFe1geVkIKAIOCFCJSUlDBL98KCS5EFAUHAzRGAVbz66qvPP//86urqoKCgtLS0xYsXv/rqq/v27Ws3583NzcuXL6+rq2v3rlwUBAQBQUAQEAQEAUEABIRSlNdAELAeAaEUrcdKQgoC3oVAeXn5008//fDDD1dUVHhXyaW0goAg4CEIIE688sorZ82aVVNTExwcPGjQIMUq7t2716QEbAydlZX13HPPff3117JMYgKO/BQEBAFBQBAQBAQBIwLCKhrRkHNBwAICQilaAEduCQJejcBnn3325ptvsu+BiHq8+j2QwgsC7o1ASkrKFVdcAauIVhFWcdiwYUuWLEGruGfPHmPGmRugZCwqKnr99dcLCwu1cZMxjJwLAoKAICAICAKCgDcjoHd89mYQpOyCQKcQEEqxU3BJYEHAWxBobGzEMRlCRZl4e0uVSzkFAY9FIDk5+bLLLps5cyasYmho6MiRI5cuXQqruHv3bl2mXr16EeyMM87YunXrihUrEC3qW3IiCAgCgoAgIAgIAoKAcdYjKkV5HwQBKxEQStFKoCSYIOBFCNChrl69Ojs7W5kH5uTk4IPMi8ovRRUEBAFPQ4BNny+99FJYRRw1hIWFpaeno1WcP3/+rl27dFH8/f3RM7JD9HvvvZeXlyfmzxoZOREEBAFBQBAQBAQBjYDwiRoKOREETomAUIqnhEgCCAJehwD6nQ8//FBLFNeuXVtbW+t1KEiBBQFBwKMQSEhImDNnDqwibVdERASsIlpFWMWdO3eqciBURMCIUBGb6B9++EFWSjyqeiWzgoAgIAgIAoKA6xAQVtF1WEtKHo6AUIoeXoGSfUHA0QggUdy/f/+6detiY2OZgRM9c29xp+homCU+QUAQcDwCcXFxF198MX4VS0tL/fz8sIOGVXzllVd27NihEqNNw0QawhEvsYQxmjg5PjcSoyAgCAgCgoAgIAh4DgJ6VCB8oudUmuS06xEQSrHr60ByIAi4FQJIFL/66qvi4uJRo0b5+PiQN/yRHTp0qKmpya3yKZkRBAQBQcAcAdZCLrroogsvvLCgoIC77AQNq/jyyy8rVhFKMTMzc/z48du2bdu4cSNOY81jkCuCgCAgCAgCgoAg4J0ICKvonfUupbYHAaEU7UFPnhUEuhsC9KPshbps2TJfX18m3opSrKys/P7779H7dLfSSnkEAUGgOyKAt8TZs2ffcMMNw4cPp3yIrGEVX3zxRcUq4lERJSPcIpvaa/cO3REGKZMgIAgIAoKAICAIdAIB4RM7AZYEFQR+REAoxR+RkP8FAUGgRw+ci23evDkrKys1NXXgwIGKUoyKilq/fj1iH0FIEBAEBAGPQADT5gsuuODmm28eMWIEGW5oaIBVnDdvnmIVJ0+ePGzYMJo1mjsRKnpEhUomBQFBQBAQBAQBlyGA4bPYPrsMbUnI0xEQStHTa1DyLwg4EgGsnvGiSCfKDgahoaEqaowEMXw+evSo2D47EmuJSxAQBJyJAPs+41TxtttuY0sW0qH5Qn/93HPPsVsLhCMyRsjEhQsXlpSUaFWCM7MjcQsCgoAgIAgIAoKAICAICALdDQGhFLtbjUp5BAGbEWBejXXzhg0b2Nbg9NNP56+K6uyzzw4MDPz2228rKipsjlweFAQEAUHAxQiEhISce+65d955p2IVUWHDKj711FOwitOnTx8wYAArKDhVRMPo4oxJcoKAICAICAKCgCDgzgiIStGda0fy5lYICKXoVtUhmREEuhIBJIoHDhxgu+eUlBT2ZgkODla96ZgxY4YOHbp69eqcnBzCdGUWJW1BQBAQBNpDAFqQNQ9zK+agoKAzzzzzvvvuU6xia2vrihUrnnzySbwoXn755fxk62d2oxKhYnugyjVBQBAQBAQBQcCLEGAwoMYDwid6Ua1LUe1GQChFuyGUCASB7oIAhoFsgUpppkyZgs2gphRR+jAnz8vLQ8Aom7R0l9qWcggC3QqBw4cPf/zxx6tWreKkvr7eWLaAgABk1w888IBiFbn19ddfwyomJib2798foSIOFk0eMT4u54KAICAICAKCgCDgVQgIpehV1S2FtRMBoRTtBFAeFwS6DwKKUmRLFihFulKMnXXZ2M0gKSmJfZ/z8/PR9ejrciIICAKCgDsgcPz48bfffvvRRx/FWyI6xH379hkdNeDGYdKkSX/84x81qwj5+M477/AT5fWiRYtEqOgOlSh5EAQEAUFAEBAEuhABJVEkA8yDOLowJ5K0IOBBCAil6EGVJVkVBJyIAERhWVkZah32dx43bhz9KAaDujdlA+ipU6fu3bt3165ddXV1TsyHRC0ICAKCQOcRYBepP/zhD2PHjmUf50dOHp9++unu3bsLCgqUAtHX15eW7fHHH09PT1ct23fffbdnzx72ocKrAy2bCBU7j7o8IQgIAoKAICAIdE8E9CSoexZPSiUIOA4BoRQdh6XEJAh4MgL4INu0aRP+xZAoxsXFURSjSpGfWA5iAb1mzZrS0lJPLqjkXRAQBLohAuHh4WedddZDDz0Escj6BzvUP/PMM2zM8tJLL0EdomHEaUOvXr1wCzt//nx8xXIOCsrVQ01NzZdffgn5qOUJ3RAgKZIgIAgIAoKAICAIWIeA8InW4SShBIE2BIRSlPdAEBAE2hBgc4OtW7ci5MHGWSGCAzI161Y/EfgMGTKEnVJxqiibtChM5K8gIAi4FQKRkZEzZ858+OGH//znP19wwQWIr3GweO+992IQjXXzsWPHKisrExIS3n//fVhFf39/Mg/bSEOHVwe2fq6trXWr4khmBAFBQBAQBAQBQaBLEBBWsUtgl0Q9EQFfT8y05FkQEAQciwDaHMyZoRSxAZwwYYKKnGk2Dsh0h8r59OnTCfPtt99iBx0fH+/YPEhsgoAgIAg4BAF2l6KxmjhxYlZW1vLly9mMZe3atTRcI0aMQMk4a9asiIiIDz/88KabbmLLKZo+mEQOtn4eNmzYwIEDjUspDsmPRCIICAKCgCAgCAgCHoGA2Ct4RDVJJt0KAVEpulV1SGYEga5BoLm5GTtBpt/wiX379tWZUCoe/XPGjBnJycnIedD1yCYtGhY5EQQEATdEAJ11RkbGPffc88orr/zmN7+BYTxw4ADW0HPnzp03bx6rI08//TT+HFhHUQsnK1euhHY0burihoWSLAkCgoAgIAgIAoKAkxDQfKJWVDgpIYlWEOhOCAil2J1qU8oiCNiIAFbPGP1h9cys2xgFlKKxT8Vg8Nxzz2XTZxyQycTbCJScCwKCgHsiwBb2LIRce+21OFV88sknL7nkEpwqstfzLbfcgjX05ZdfjqsHvMTS0DGReOGFF6Aam5qa3LMskitBQBAQBAQBQUAQcAECjAo4XJCQJCEIdAMEhFLsBpUoRRAE7EUA0z8oRfZjOe2004xxIfMx/uQczpHNW6AUCwsLTW7JT0FAEBAE3BYBXDecccYZf/nLX3CkyLYteG9YunTp7bffzs5UcI5KkV1SUgLPyJ7RCLfdtiCSMUFAEBAEBAFBQBAQBAQBQcBNEBBK0U0qQrIhCHQZAmhz2PB0x44dmZmZbMBizAeUoskaHXsajBkzZt++fUeOHJFZtxErORcEBAH3R4AGbcCAAXfccccHH3zw2GOPnXPOOZs3bz506BCEI3pG8r9//352d2HVRFs/uX+hJIeCgCAgCAgCgoAgYD8CdP2q92/TKIpK0X5AJQbvQEAoRe+oZymlINAxAv+/vfsAk+s8zHu/O22nbe8VfYlGgCAI9k6LpChRlKhKW1bi2HHsXCd24tx7ndhxEst5nuvHj+3YcWLZSqw4VrEUSqQkkiIpir0BIEgQIOqibu91+uzM3nf2YA8GM7uD3cWW2Zn/aAWcOeU73/c7A2L3xVeUJ2p6xOHh4ZRRz7oiZeCzUYZ6Mupv2Xfeeaevr2/uUjmCAAIIZK+A/uP26KOPaqTzN77xDc2uaMyoaPz8YCzq0t3dnb21p2YIIIAAAggggAACCGSBAJFiFjwEqoDAqgpoZrG3335bHRLTI8X0gc+q6b59+zSp4pEjR4gUV/W5cXMEEFgCgb179/7e7/3ek08+qV+bm5uVKuq/bxoi3djYuASlUwQCCCCAAAIIrBEBo4uiKqtvBvRaI7WmmgissgCR4io/AG6PwKoLqJfiBx98oFHPO3fuTKnMrL0Ua2pqFD6qC4/WaTH/6k25kLcIIIDAGhJoamr6yle+8vzzz3/+859Xp8XW1tY1VHmqigACCCCAAAIIIIDAqgjYVuWu3BQBBLJEIBAIaGGWUCikvofp/xyXvkfV1k5Np/jiiy+eOXNGw6UrKyuzpC1UAwEEEFicgP6zprkUtfTzV7/6VYvFoqkVF1cOVyGAAAIIIIDAWhfQdwV6rfVWUH8EVkaASHFlnLkLAlkqoB+eq6qqlCemrPWcubq33XbbH/zBH9TX15eXl2c+k6MIIIDAGhLQwvdrqLZUFQEEEEAAAQSWSiCxOMvUlEojT1wqUsrJBwEixXx4yrQRgTkFNFuiwsRdu3ape86cJ6UdUBceDZRWHKlX2kF2IIAAAggggAACCCCAAAJrVYBUca0+Oeq94gJEiitOzg0RyCYB/X2pVFGvWSuV4W9Tm43/esxqxk4EEEAAAQQQQAABBBBYqwIZfgJaq02i3ggsmwA9jJaNloIRyBWBWCyWK02hHQgggAACCCCAAAIIIIBAqoA58FkHSBVTdXiPwBwCRIpzwLAbAQRmBILBYDwen3nH7wgggAACCCCAAAIIIIBArgkYSSJ5Yq49V9qznAIMXVxOXcpGICcEFCkacxXnRGtoBAIIILBcAvpP5djY2Msvv6wbaEKJhx9+WAtJGzdrb28/fPiwdt59990ul2u5akC5CCCAAAIIILBYAfNHHlLFxRJyXd4JECnm3SOnwQgsVMDv96uXovmD8UIv53wEEEAgfwQGBwf/9E//VO31er0NDQ179uwx2t7W1vaXf/mX+hFl9+7dRIr583mgpQgggAACa06APHHNPTIqvIoCRIqriM+tEVgbAoFAgIHPa+NRUUsEEFhtgWg02tHRoVqoQ+LTTz9tRor6D2lXV5f+Wzo5ObnadeT+CCCAAAIIIJAqYHZRTD3AewQQmFuAuRTntuEIAghMC4RCIf6K5bOAAAIILEhA2eJLL700MDCwoKs4GQEEEEAAAQRWV0C9FOmouLqPgLuvIQF6Ka6hh0VVEVgdAf1gTKS4OvTcFQEE1qaAfhSx2+3KE1955ZUvfOELGRqhLo1Hjx49d+6c/vGmqqpqx44d1113XUlJSYZLOIQAAggggAACyydAnrh8tpScewJEirn3TGkRAkssoGF6RIpLbEpxCCCQ0wIOh+O22257/fXXv/3tbz/++OM22+zfbr311ltPPvnk8ePHR0ZG9F9at9tdU1PzsY997NFHH21qasppIRqHAAIIIIBAdgno5x3zRx5Sxex6NtQmiwUY+JzFD4eqIZAdAuqlmB0VoRYIIIDA2hBwOp0PPPBAcXHxiRMn1AnR/BElufadnZ0KHF944YWzZ8/W1tbu3LkzEokcOnTom9/85quvvqp1sZJPZhsBBBBAAAEEVkZAeSKR4spQc5ccECBSzIGHSBMQWF4Beikury+lI4BAzglYrdaWlpZ77rlHKeEPfvCDWCyW3sQXX3zxvffeU3SoPom/+Zu/+Vu/9Vu/9mu/plHPihoVKZ45cyb9EvYggAACCCCAwDIJzPrvf8t0L4pFIGcEiBRz5lHSEASWS4C5FJdLlnIRQCB3BdRRUUOe9fOJosP+/v70H1TefPPN4eFhJY+f+tSnFD7eeOONOv/WW2/1eDynT58+f/587trQMgQQQAABBLJXgC6K2ftsqFn2CRApZt8zoUYIZJkAvRSz7IFQHQQQWAMCmj9x9+7d27Zt6+3t1aSKKR0VtRiLFm9RH0Z1S2xsbNRaLmpSWVnZpk2bysvLFUEODQ2tgUZSRQQQQAABBHJRgFQxF58qbVoWASLFZWGlUARySUCRYi41h7YggAACKyOguRQ//elP615agyUQCCR3VNTbeDyuQwoQtZaLWR+t9axFWoLBYMr55glsIIAAAggggMByCOivaeNvavLE5eClzFwVIFLM1SdLuxBYAgHjr1UGPi8BJUUggED+Caij4oMPPqjQ8MPpV3JHRcWIxk8s4XDYyBYNHvVb1L/iFE2/8g+MFiOAAAIIILD6AvoL2vg7evWrQg0QyHoBIsWsf0RUEIHVFiBSXO0nwP0RQGBNCugHkubm5rvvvlspocY+Ky40m6GuiOqQqFVcNG2iZlQ0/v1GJ1y8eFFDnjUCurS0lJ9nTC42EEAAAQQQQAABBLJQgEgxCx8KVUIguwQY+Jxdz4PaIIDA2hFQaPiFL3zBYrH09PQk90bUnl27dilVbGtrM9Z31tSKb7/99sGDB8fGxtavX9/U1LR2WklNEUAAAQQQyB2BRB/FwsLcaQ8tQWA5BWzLWThlI4BALgjQSzEXniJtQACB1RDQzyR79+7dsmXLqVOnkiNF1eXhhx/ev3//kSNHnnrqKQWOVVVVhw8fPnbsmGZgvPnmm1tbW1ejvtwTAQQQQAABBBBAAIH5ChApzleK8xDIWwFN9WUMystbARqOAAIIzFMgvV+Dy+X67Gc/+8d//Mf6b2lyITt37vzMZz6j7orHjx/X+i06pC6NtbW1d9xxxwMPPKCEMflkthFAAAEEEEBgWQX0847xI0+ijyK9FJfVmsJzSIBIMYceJk1BYHkEQqFQSuea5bkPpSKAAAJrXkBzID7++OMej6eystJszEMPPXTmzBlNlahVWTSLorFfi7c88cQTGuCsaRb7+/u1eIsObd++/f7779+wYQM/zJh6bCCAAAIIIIAAAghkpwCRYnY+F2qFQBYJ0Esxix4GVUEAgSwWUA5YX1//Z3/2Zyl1bGlp+aM/+qOUnXprt9sVIN53330+n09TTCiI1FLP6aexBwEEEEAAAQSWW8Dooqi78K96y01N+bkkQKSYS0+TtiCwLALqpWj+FbssN6BQBBBAII8F9KOL5k/MMYBoLD7si4YisfjUlNG0IrvVZbfo1yK7xWph2vsce+A0BwEEEMgdAf29rFfutIeWILCcAkSKy6lL2QjkhAADn3PiMdIIBBBAYNkFQtHYWGBy1BfpGgp+1D4+OB5WpmjctdzjqCp2lHkd5R6702G12TSNpH5iS/zPbi2s9NqrS4uIGpf9CXEDBBBAAIF5CBApzgOJUxBICBAp8jlAAIGrCDDw+SpAHEYAAQTyXkDdEntHwic6xk90ThxrH+8bDk9OFSozVH9EHQqGJ0OhaHwmXrSrx6LT7nAoQkyc43Fabm4tf+Sm+sZKp1N9GOkakvcfJwAQQACBlRdILM4y3bOePHHl8bnj2hUgUly7z46aI7BCAgx8XiFoboMAAgisTYGB8fDZHt+z7/W+d2qkyGErtFi2b6mx2m3qgmgtmBrzR7r6J/oHfZOxuN1msdusNqslFo9P+MJRxY3TOWP/SKhrdPK+3TVb6911pQ6XgyFna/OjQK0RQACBnBAgVcyJx0gjVkKASHEllLkHAmtagEhxTT8+Ko8AAggsk4A6c0yEJofGwz/c3/Pyh33R6FRznfe69VXjofjweGige3zMF4pGYlaLYkRLVYWnxFtUVuIqL3GWeJ2+QKSjd2xgyOfzh8ORWCAYfetw94kLoze0Vt25rWJzTZHNUlBV4vA6+U51mZ4exSKAAAIIzC5Anji7C3sRmE2Ab9RmU2EfAggkCTCXYhIGmwgggAACCQGtu9I/Gn7pw/7n3uvp6Au6XdZ9W6tOd/qeffO8fhhThujxOBprSqsq3LWV3soyl8eVGOecbLdjc7U/GO0ZmOjsG+/tHx8ZC/oD4VcPdrxzpFuxY5Ft6rO3N95zfXWZ255yYXIhbCOAAAIIILAkAsaoZ6MoUsUlIaWQfBAgUsyHp0wbEbgmAeZSvCY+LkYAAQRyTkCLrrQPBP72pQsvHuxV41oaivuHgu8eGyorc+3aWl9T6aku91SUOq1WS+ame1z2zS0V+lJHxcGRQEffWEf3aN+gb2A4EJ2M/9UzZ9t6/Y/f2tBU6VIgmbkojiKAAAIIILAkAuSJS8JIIXkiQKSYJw+aZiKweAEGPi/ejisRQACB3BLQYOfwZPx8r/8Pv3fiTMeEQkOH3RovsO7Z0djSULquoWxxPQqLHNbG2mJ93bitvnfQf6FrpLt/vKtn7MdvdR2/OP7Fu5ru2VHlYRB0bn2WaA0CCCCQVQLTq7NMZVWVqAwC2S9ApJj9z4gaIrDKAkSKq/wAuD0CCCCQHQL6Scsfnnz9o8H//J0T6qioVZvraou3b669fkvNFUOar6G2Cihb6kv0Ne4PHzjSefRk7+n28T/9/qmekdAv3NOi9aCvoWwuRQABBBBA4OoC6qVIR8WrM3EGAtMCRIp8EBBA4CoCGvgcj8evchKHEUAAAQRyXSAUib17cvg/ffOYxVJYVuK8c9/6nZtrlqnRJZ6iu29a31RXevCjzu6e8W//7GKxy/6ZWxvs1qVKL5ep4hSLAAIIILC2BcgT1/bzo/YrK0CkuLLe3A2BtSkQiUQ0FoC/X9fm06PWCCCAwBIIRCbjh86O/P7ff2SzWeqrvffcsrG5rnQJyp27CPVY3LqhqqG6+NnXT1/sGPnaj8+UuK0f2127uLHVc9+HIwgggAACCBQkD3zmpx4+EAjMU4DxI/OE4jQE8lpAkSIdFfP6E0DjEUAgvwXi8am2bt/XnjtntVi2rCv/+D1blztPNL2LPUUP3bG5vq4kEJ78k++fPnhmRPM58kIAAQQQQGBpBRQjGkmiubG05VMaAjkpQKSYk4+VRiGwxAJGL8UlLpTiEEAAAQTWiMD5/sCfP3Omsz+4Z1vNg3deV1nmWrGKFxYWlBU7P37nluoq74R/8o/+z6nTXROkiivmz40QQACBPBFI7qWYJ02mmQhcuwCR4rUbUgICuS+g6RT1t2zut5MWIoAAAgikCYwFovtPDWl95xu3VT985xa3y552yvLu0NSNleXuh+7cUlbm6hsK/s1PL8T5K2l5ySkdAQQQyF8Bo69i/rafliOwEAEixYVocS4C+SpAL8V8ffK0GwEEECho7w98/63uYrdjz7a6aHx1VkfR/Il1ld47bmzRStPvfjR44PSwNng2CCCAAAIILIcAqeJyqFJmTgoQKebkY6VRCCyxAHMpLjEoxSGAAAJrRKBzKPjMe73haOzuvY3ekuJVjPG0LMyWdZVbNlbHYvFn3ushUlwjnyCqiQACCKwNAXNIFnni2nhg1DI7BIgUs+M5UAsEsluAXorZ/XyoHQIIILAsAmP+6OsfDbx0qLey1L2usXLVf8rSGtA3bqu3WC1vfDjw4fkxUsVleeoUigACCOS9wKr/fZf3TwCANSNApLhmHhUVRWAVBaLRqPkPd6tYDW6NAAIIILCSAt0joXdODjscttYNlTaHYyVvPeu9LIWFTXUl21trI5NTz3/QF52Mz3oaOxFAAAEEEFiogLk8C3niQuk4P58FiBTz+enTdgQQQAABBBBAYHaBeHyqdzh4smPc6XTU1ZQVaOnlLHjZbdZ9OxqKHNZXPug72eWbZEbFLHgoVAEBBBDIJQFFiqSKufRAacuyChApLisvhSOAAAIIIIAAAmtSYHAicqJjIhSOl5c6y0pcWdIGBZtV5e762tJAKPbKRwORKB0Vs+TJUA0EEEAAAQQQyDsBIsW8e+Q0GAEEEEAAAQQQuKrAwFj4eMeE3W6tKHNbrVnRRdGos9Vqaa4vtVgKD5wcjDD2+aoPkhMQQAABBOYhwCxP80DiFARSBYgUU0V4jwACCCCAAAIIIDA4Hm7rmnAW2RQpZpvG+oYydVfs6A8eax9nRsVsezrUBwEEEFjTAgx8XtOPj8qvsACR4gqDczsEEEAAAQQQQCDbBUb90bM9/nF/1FVkryrzZFt1ayo9xV7n5OTU/rbhEGOfs+3xUB8EEEBgbQoYHRWJFNfm06PWqyNApLg67twVgbUlEI8zWdXaemLUFgEEELgmgcGJ8Lk+v1Zo0UIo5SXOayprGS622ywNtSVaAPr9tpFwNLYMd6BIBBBAAIH8EjAHPrM2S349eFp7bQJEitfmx9UI5IdAKBQiVcyPR00rEUAAgYRAIBwb8UW0oSkLld9lIUp5qavQUtDe5+8cDE7GprKwhlQJAQQQQGCNCpAqrtEHR7VXXiAbv0dceQXuiAACmQV8Ph+RYmYijiKAAAK5JKBlT4LhrO79p+6TAg9H4u+fHw1GsrqqufTBoC0IIIBAzguQJ+b8I6aBSyhApLiEmBSFQM4K+P0a/sbY55x9vjQMAQQQSBHQmidZHinarZbCgsQ61D0jIXoppjw+3iKAAAIIXIsAqeK16HFtXgkQKebV46axCCxSQJFiLEYfkEXqcRkCCCCw5gQik1OB7O76Z7NZpxPFgnA0PlXAwOc19xGjwggggEB2CWguRXM6xeyqGbVBIIsFiBSz+OFQNQSyRmBycjJr6kJFEEAAAQSWXSAaVS/FrP4vv2Z4TPRR1NhnRYokisv+ieAGCCCAQL4I0EUxX5407VwKASLFpVCkDAQQQAABBBBAIIcEorF4KLvnUjQXjdGKz2SKOfTRoykIIIDAKgsoUiRVXOVnwO3XjgCR4tp5VtQUAQQQQAABBBBYGYGZ4V+x2FQoK7srmhP80ktxZT4R3AUBBBDIbQFGPef286V1yyRgW6ZyKRYBBHJAwG63NzQ03H777XfddZfL5cqBFtEEBBBAAIH5CBTZrV6XbTgaCUcnx3xhZ1HWfcc4EQgb452JFOfzQDkHAQQQQGCeAvRSnCcUpyEggaz7BpGnggAC2SPwyCOP3HPPPffff39NTY3FQqfm7Hky1AQBBBBYXgGPy1ZZWjQ8HolEYmO+UG2lZ3nvt/DSh0aCxnhnl8NaaMyquPBCuAIBBBBAAAFTgI6KJgUbCMxTgEhxnlCchkA+Cjz22GP52GzajAACCOS9gLooVpUWtXVMRKKxsYlwFnoMjfqNn/3W1bgdNv7RKwsfEVVCAAEE1pKAmSfSS3EtPTbqutoCRIqr/QS4PwI5J2D+fbyglqVfZcyLnL5/QcWmnLyI0hZxiW66uKtSajuftwu90ULPv2od0gu8lgeXXtpVKzDXCYsranFXLW0dZi1tcRVb3FWzViDDzsXdZSWvylD59EOrXrHFVSC9IeaeRRSoS8L+sNcWUyGKFCd8IbO0LNmIxeMjowGjadWu6OjwQNhnzZK6UQ0EEEAAgbUoMDg4GA4n/gnN+FZ2LTaBOiOw8gJEiitvzh0RWHsCQ0NDZ8+e7ezsjEajZu0X92Oqefm1b2SoQIZDc903wyUZDi2itLkumWt/5rtnPppe5kLPVwmZL0k/uuhIMb2o9Pqn75nrqrn2p5eQvGeuq8z9s36XaR5NLirz9kIvyXx+5qOz1iT9kuV4cOl3mbUyyTszX5L5aHI5xrZx/go8tYVWTNVbqkvUusxFZT46F1ogajnnqywoWKdIcXQipF8d9izK7Cb8EX8gqrkUp+LRD954rutQ1Gph8HP6w2QPAggggMB8BUZHRzs6OoyzZ/3OYb4FcR4C+SRApJhPT5u2IrAogeHh4SeffPKll146evRoMBhcVBlchAACCCCwpgQsNmfTLSW7nigocI+NhwZHAg01xdnTgK6+CSMqjQWGf/zit+LBkeypGzVBAAEEEFjTAuSJa/rxUfkVFiBSXGFwbofA2hMYGxt77bXX9A93zc3N6bVfaP+X9BKS9xilzfoX+XLcKPnWi95e2oplqMbS3mhpS1O1jQLTn93S3iibS5vr2S1tnU3quW63oP1m3Xhws7qZPrMeXejORZS2iEsWWivj/FlvZHFErOGBKfs6fzDS0TuWPZFiLD51+uKQsTaLJTJYXlo85VqCLoqzIiyh5+KKynzVEtZZN1ra0jLUfAlvtIRFrVEBqm180pb2k5Dh07vk4CtW8yW80RIWteSeGZ7dgqqd/n1RhpI5hEA+CxAp5vPTp+0IzEtgw4YNv/zLv+z3+2c9e0F/PRslZLjEODTr3+JXvWrW6s21c67S5to/Vznan/mS9KNG69L3Z7iFcSjDJRkOXbWG6ffNUFqGQ+nlZN6TuajMR2ctea5L5to/ayHGzlkvueqDm/WqDHfRoQyXZDiU+cJZ75ihNONQ+h+6DJfMeour1mqhBWY+P/PRuWo46/4MRS3u0Kx3yeyT4UaZS0t/cBlutNC7RApdF0IVRwYtwVC0q288GJ50Fa3+940a7Dw8GmzvGonHp4ocln03NFdf/7hl6vKkHHOJZZAxLlmoT+YCF1HaXDXPUFSGQ0te2iLuteR1SC8wc60yH11EaQv6E5devrknc8XmOjrXfrPY9I0Ml6QfMluXfii95JQ9GS7JcCilEONthvMzHJq1qJQCzQaaJ2coMMMh8/KUjQyXLO5QSvnm21lLU+tm3Z/5KvNo+saKlXbVG6U/ONU281Xpzcl8iVGaftg5ffq0ZlSc9Y6zlslOBBBY/W8NeQYIIJD9Ag888ED2V5IaIoAAAggsoYA6A757avhPnjrd1R8YGPJ39o1vaalYwvIXV5R+8DtxbiAYTGSIrc3F/+bLt9WVOQuXoJPi4qrDVQgggAACOSJw4cKFr371q5rrKUfaQzMQWBEBy4rchZsggAACCCCAAAIIrCUBLXjSVOXavaFMlVZHxfbu0VgsvuoNUGfJ0xcGFSy6iqyP3dpYUewgT1z1h0IFEEAAgRwQKCkp2bRpU0VFhXop0lExBx4oTVgZASLFlXHmLggggAACCCCAwBoTqC4pumFDqdtpDUcmO7rH+oYCq9sAdZw81zEyMOhTNXZtLntgV02RjW9lV/eZcHcEEEAgRwQUJn7xi1+88847vV6v3W7PkVbRDASWWYDvw5YZmOIRQAABBBBAAIG1KeAusm5fV3LDlnL1ChweDXxwojsQmteshcvRXNVh3Bc6erpPhbudtsduaXCQJy4HNGUigAAC+SrgdDpvvPHGW265RfFivhrQbgQWJnCVaVwXVhhnI4AAAggggAACCOSQgD8Ue/3YwF89e7ZvOOR2Ofbtatp3fYPdZl3hJmpVlkAw8sqBC0dP9lgshQ/srfv9L24lUlzhp8DtEEAAAQQQQACBZAF6KSZrsI0AAggggAACCCBwWcDjtN62tfKJe1uKXTaFeh8c777QPaqAb4Vfk7H4qfNDyhM1c2JzjfsX7222WVmTZYUfArdDAAEEEEAAAQSuECBSvIKDNwgggAACCCCAAALJAmUe+8duqH38rma7zeIPRA591D0RCCefsNzbGvI8MhZ87eB55YnlxY5/9Xhra0OxhWVZltud8hFAAAEEEEAAgYwCRIoZeTiIAAIIIIAAAgjkvUBVieOT++pubC3Xos+d3WOvHrigBVtWRiWRJ46HXnjrTDgU9brs//yxLbe1ajnOlbk5d0EAAQQQQAABBBCYU4BIcU4aDiCAAAIIIIAAAggYAi3V7n/xic1ely0Wj5862//8m2ci0dhy42iE9dhE+M1D7Z3dow6H9cF9dY/urVvum1I+AggggAACCCCAwHwEWJ5lPkqcgwACCCCAAAIIIFDQNRz8d//7WFv7eEFhYevG6k/e22rVainL02dQeeLIePDld8+3nR+wWgvX13m+/X/fwjNAAAEEEEAAAQQQyBIBIsUseRBUAwEEEEAAAQQQWAMCI/7of33mzE/eTayUsnFD1b03ra8scy95qhiPT/UP+1/ef+5ix4jmcNy2vvjrv3HTGtChiggggAACCCCAQN4IECnmzaOmoQgggAACCCCAwFIIBCOxn7zf+42fXhgYDnm9zntu3rBjc/USdlYMR2Jn2offOdw+MOhzOxPjnX/n8a1LnlouhQRlIIAAAggggAAC+StApJi/z56WI4AAAggggAACixOIxuLtg8Fv/OzCTw/0Wi2F26+ru35zbVN9ibYXV6BxVSAUPdc5+lFbX3vHSHwqXlHs+EcPrf/srU026zUVey1V4loEEEAAAQQQQACBWQWIFGdlYScCCCCAAAIIIIBAJoH41FQoEv+ofezpd3te/7C/sLBw47qq7ZurNzaVa6hypitnOzbhj6hn4omzA929Y1oBRiXs3FD65fta9m1eTGmz3YF9CCCAAAIIIIAAAkspQKS4lJqUhQACCCCAAAII5JXAZGwqHI39+GDPU+90dw0ENfy5vMxVU+mtrfI21ZRUlbttc8eL4cjk4Giwb8g3MOzvHZgYHPJPKk2MT1WWOD5+S8PjtzXUljrpn5hXHycaiwACCCCAAAJrSIBIcQ09LKqKAAIIIIAAAghko4BmVxz1RX90sOfZA91Do5GCwgKtBG2zWjweR01lcbmSwSuDxUAwOjTiHxkLBkNRZYix2FQiS1SYWFp0z67qn9tds7Wp2FWkUdSMd87Gx02dEEAAAQQQQAABCRAp8jFAAAEEEEAAAQQQuFaBqakCX2jy4kDg+ff7XnyvZ9wf1R6NhlawaE2bCVGHjA6JU9qaflWVFd22o+r+66t3NJdoSRa7dcFDp6+1AVyPAAIIIIAAAgggsBABIsWFaHEuAggggAACCCCAwNwCk/GpicDksfaxIxfGjrWPn7gw7g9Nzn16QYnH3lLnua6p+JbWip0tJcUum+PK/owZruUQAggggAACCCCAwCoKECmuIj63RgABBBBAAAEEclAgHI0HIrFgeHJwPHyqy3e+zz8WiIajWs4lpokXdbSi2L6loXhTnaep0lXmcWiMs9dpK7LTMzEHPww0CQEEEEAAAQRyVYBIMVefLO1CAAEEEEAAAQRWWSAWnwqGY4oX1XtRUyXGpwr0q14aDe0usuqryGaxWJgwcZUfE7dHAAEEEEAAAQQWIUCkuAg0LkEAAQQQQAABBBBAAAEEEEAAAQQQQCB/BRhgkr/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAQG4ITE0VBCOxuH7jlTcC0dhUdDIe55nnzROnoQgggAACCGSbgC3bKkR9EEAAAQQQQAABBOYpoBQxFIl1DAbP9fpaqt1N1e4SF9/dzRNvDZ82MBY+3xeYjMXryp31FU6Xw7qGG0PVEUAAAQQQQGBtCvBN59p8btQaAQQQQACBXBcIhGP+sDKT1F5YhQWFNmviq8huddgslsJch8jYvshk/N3TQ//pWyeCoUmB/MonNvziPesK5zaR5tRMb0ZLoV4ZS+fg8ggoCJ55CAX6BC/0IeiPxl/95NzLH/QHw5OtzSW//sjGW7dW5vkfhOV5UJSKAAIIIIAAApkEiBQz6XAMAQQQQAABBFZL4I3jg88d6h0aj6RUwGErrCwpaqp0bW0q3t5cUl1a5LTn70QuE8HJZw72Kk+UUmQy9q2ftf/C3S3WuUMqX3CyfywUisR1fmOlq8xjT+Hl7XILKEwc80e7h0O6UZHdoqew0D6GR9vH2jonlCeqhNMd46c6J3ZtKPU6+a5+uR8d5SOAAAIIIIDAFQJ883EFB28QQAABBBBAIEsEuoZDZzomBsfCc9VHudl1zSVfurf57h3VnqI8HfipfCoYjl0iUt+3mPogFmSwePHDvm++dLF7MKhLfvdL2x69pWHu+HEuePZfk4DyxKfe7f7rZ86qlJYa9+8+se2GDWULKlGJ8GTsUu9ddTQNT8ajk6mdeRdUICcjgAACCCCAAAKLEMjff9VfBBaXIIAAAggggMCqCGiYs8Y4G192DXaeHuSp0aMn28f/+tlzPzrQkz4+elXqufI31cyJj93a4HHa1N+t2G3/xG0NtowjYJU9saLHyj+m5DsqDNSyKsl7Frp985byDbVud5HV6bDWVzpbG73lXnqbLlSR8xFAAAEEEEDgWgXopXitglyPAAIIIIAAAssq4LBbbt5W2Vzt1l1iU1PjgckLvf7Ofn8gmFjjuGco+ObR/hs2lG5rKl7WamRn4QqVHthVs6HW8/bJwR3NpTdtLqfXYXY+qSWslQZKq2/jgbaREV90z4ayddWuJSycohBAAAEEEEAAgXkKECnOE4rTEEAAAQQQQGB1BNxO26P76u+9vtq8vcb2vnZs8Bsvnj/VPq6dZ3r8rx8bnCtSVGdGvab0v4ICLe2ytIlbolBjyKmKTtwn8TLuqA3zXuaeRA2mz0k+7dKOmUNGmZkrfLnAggKrpXBLvVdfiXLM0i8Veuk383yjWGOvbpR4O3XlNTPVuLKAmXL0+/Q1+j1xYsaTZy1h/jtV52la1e/yUzMbYtoaBc61/9JR/Zb2mNJrkiI//9YZd79U30vlTlcwyccoPFGRmYZNbyfqZVberFJK6xJnXvr/pVPcDtu9Oy79iUg/2SwneSOldRmuunyvmfpPVzmx2/hQZ7g2+Y5sI4AAAggggEBuCxAp5vbzpXUIIIAAAgjkoICG9t69vbJvOHixzx/SwtDBycHRWaZcVPI4EYie6vadLPZCZgAAOAhJREFU6p640B8o99i3NHi2NpW0VLqXJBPRUidn+/zDvrCGYteVObc0eNVtsn88fLIzEXQq6btrW7Vxo0PnRnSyIqd1NZ7mSrfdWnixP9A5HNB6zebjaalyN1UqKbK09fgOnR1pHwzqtM313t3rS9dN99A0ztSw5YHxyPHOMfNCc0P5j9b6uJQtmnsLCjoHgxcH/ca9TnX6gpFLcy+e7Joo/siWTGGUsKnOk74KsfIkLTR8tsd3snviXJ9fTW6t97Y2eFsbizOOtE6qx7w31cZRf/RY5/jx9on+sbAG9j5wfXVVSdFkfOrdk8PReEzVu3lLhbmqifa/f3ZE64PrDpvrvPXlTpv18tw+Y4Ho+X7/iC+xzk9jhUs9Ou1JR41KqXX+0OSZHn1UfDrZYbVsaSi+rsGzuf7qrdNHq63X1z8aUp1HfYkxzV6nVevelHrsWxuL9Tg0Jj0cjXcMBjqGArqdutnqFsZ9faFJLUM06r9iDSI9BX1O1ldf8Sk9enFMTTDXiTYu169a5ltNriktMvekbySeXSh2ttd/omv8Qr9fl1zX6N3aULKuxj3rs5NDz0iiD3BNiVMfBnUNfvvU8ImO8fHgZHVJ0famkh0txRVeR/qN2IMAAggggAACeSVApJhXj5vGIoAAAgggkCMCCuwaKl0aDa2lb5XiaMljJSDaaTZPSyH/+ED33zx7TnnT9CtxRFGUErS7dlf/9qdblYkkp2nmhfPf6BwKfv2F84dPj9hthTddV/HH/2SXQrefHOr92+fOqxBnkeWb/88tihq1/fv/6yPFMeppdsuOyt/57HVapfpHB7uf298z4U+kYMbr4ZvrPn9n8xvHBr//Vue4L2L0XFMN6ypdn7ur+XO3NeouOjMam/rw/OgffPP4zHWXf7daC+/dU/sfv7QtpV0/PdL35GudY76oThWGOZfiD9/q+vHb3Zevn966+/rqX31k4/qaxDBz86UU8o1jQ//lh6fHfVETU5SK5lrqPP/5H13fUulKual57UI39OB+erjvv/34TDiimiZ6/j1fWPDXPz67b1vl731h6+/87ZHpDnsFv/PE1of21BrhoIK5v3i67UJvIrB78Oa6X3pgfXPV5bHAimi/8eKFD8+M6uhjtzf804c3lnkuB47a6Q/FXv1o4C9/fGbCf0XrNIPnxibvV7+8s6ki8RBTXvpc/cObnc8d6OkeCExOJipqPLJLp0337/vsnU2ND25QpDjsi/xof/cP3ujSUZ2psNt4jU5E/uFn7d+70s5iKfjM3c3/4hObkuPev3j6zOnO8fjlCPpSCU6n9bc/0/rxm+ouvU/7TWnm2yeH/vszZzVFQPKz08eptbnkq7+4ozYtjvzWq+1vHBmQ/7YNJZ+5vfHJ1ztPd05c+tgUJv4QbWkq/kc/t/6ObZVKvdNuyA4EEEAAAQQQyBcBIsV8edK0EwEEEEAAgRwT0ByLzpmFnmcimktN7B4O/cUzZ94+OqA8JbnVsek46rXD/UfPj/33f36j+vQlhZDJJ85rWxUocduiMS2zXDgRSISD2u4YDOpXbVuihe0DQUWKSjxDUa3Jm9hZU1akoEobCkC1aK9xpt7qNTAefvpA92FNkDceTg6nugaCL73f21LtumNrpU5LBFLxKy6cvjrxS3yqUMWab80NVUc3Sr6XcUgnGyDmmdqYjOt1RSGq2JNvdf3DK+1hxZlXHFETCs52+X75Tw/80S/v0rLFyZFucpnz3x6aiDz9bvffvXg+5cFNxiYPnRr+yfu9BqMKTOmvZ2LGEnW8spZTBdppND/dp3ck9L23Or//euesrTt5YfxX/uzgH//Krp0tpcm5n+6hD9iLB3sV1KbUJLmxboe12Jn4Zlvn69bpj0AVTX8Klvgsz1GReWJpnSsfgEq2TRam7zTroI6Tzx7o/tsXL6iX4pWnJZ7dR+dG/+l/ee8/fWWHJmQ0L9GG0lI9atV2cDzyVz8+OzIRMdl1VJ8ZLYv0jZfOK1C+a3tV8oVsI4AAAggggEBeCRAp5tXjprEIIIAAAgjkjoCSjr6RkNqjblPqLWXmWerm9s6JwTePDBg5iI6WFtvrKlyhSKy9169kRfHTwEjoW6+3//OHN5a4F79UrtNuLZ8e/qkMLjIdtyn06R4KGsTqEXZxIKDFefsn1OXwUsjVWOnUitU6YUdLScdAUENZ23sDGp2tPcMTka7BYM9gUDlpY407Go139QdUVb3aunzvHBsyIkU1p8Rj39xcYtxFv6qZF3t85tv0jW1N3p0by0anR/72j4QVWapYnVZf5SovTu2qua7O6y66/P2hkqzj7ePfe7VderpEPRM9LmtDtVsltPf4dVRtV5z6J0+d/vpv7NXC0+l3n/8e1elU58STb3QYeaLx4La2lOhe2j/hi3z9uXPzL20+Zyo1O3J+9Kk3Oo3W6Y4et00swu/oE36idXL7oydP/a/f2mdkwUaxzx7qUTCtQzMPtqC8xFFRUuRxWtVXVBVWhKdWlJdcSpCL3bbNDcU7Npbq8kg0Pjimp5AY7KwPQ12VS8F0cm1VjfW17pTuf60txXFLobJR48yewYDG+ydfNev2sYtj33uzS4PujaO6XUWpQ38EBkcSEwVoY2As/Cc/OP2///XNs2br/UMhCSiLLPbYvW67+lSqO7Au1M629okPzozqY8wI6Fnl2YkAAggggEA+CFzxHUw+NJg2IoAAAggggEAOCJzv8x84PWxMoehx2Sqnxxcb7eoaCv7D651GnqjE8Jce3vCx3TUKHNX3rnMo8Pt/f6x/JKQk6Cfv9nzqpvrrmjTtXqJT2Fsnh9RFzsz+MhPVlTt3rSt1OiyVMzPKKUXSXH4KoXqHEymnXrpd+2BiKO7gWMjs9tdUoYkUE5HiXdur922uUDTzP3564cX3epUqKsNSNTY1Fv/8vS37tpRr+4X3+77zavvQWDgciY0HopoMUTMtKhXau7n8L351d+Ie0y/N4vdP/uw9FTWzI/V33UiLQRsnqCPkD97sHJhOlL54Z9ODe+tSoit1vTTnKFRBmtLxuUO9GtCtba/b9uBNdV++p0XLTAtwcDz8Zz9q07hvHbrQ7decgPfvqlENU28/7/f9o2FNiaikWFfY7ZY9m8v+zWeu04yEupdmG/zmq+3PvpM6THveZc9+4rnewAuH+43WlXrtD+2rf+KuJk01qBBNz1H9EI+cGdXdz3X5Xjs2cO/OajO2/uDs2HhilHSi2Pv21HzujqbmKrcyR/VklKd265C+3DO9aL1FtodvrL1nR6JPnwZBP3Og5zuvtGtbvVb/5aObd7ZcDogTJRYW6BGY90rsKSj4jU9sTu4q+DcvnFffVd9031jjhPRfe0ZCB9tG9GnXIYulcGtz8b98bEuTAtPJ+Ifnxv6/751UkKpPhT54Gmn+4J7alE+CrtLnWfnmP35w/cf21Gp2SH0Iv/9290vv9ylL1edTM0LqzxqRYro8exBAAAEEEMgTASLFPHnQNBMBBBBAAIG1KqDeXh9pZeeZwEMT553vCxw+M3K222fEZC017n2t5UbzFA+1dU10DSSyPK/L9snbGx67pcEzk+woFvm3X9j2//7PD1Wm8pTjHePraz3KffpGwhrYe6Y7U1+/ZL59rRWaPVC90iqKL3VyVKQ45lekODU0GlawpPQtEJxUP0Rd1T92OalsqFAvxURLnBq1bU+kbwqPNHeeXqqP+oJ98matbV2l/o/as2tD6aEzxe+MJTqUaTZDBTpaokQXF9ksRcWXF8dQr7cZm0Q56S/FfGbSpx6ICr6Mc9Sp8KoTSvYNhw4cH9L5ihp3bSz7tel+ncb15V77v/3c1n/8JweC4ZgCpndOjdy5vcq8UXo1rrpHC5i8c3LYyOm0Is2vP7KpZWaJklKP7R8/sP7g6ZG+mU6gVy1tPid0DwY0nlpnFjmsezaX/8rH1iuDvtQ6j+PffKb1V//8kJ6LWvf2iWEN8jVjPvVFjWi5nenXA7tqrl9XqgkTM9xR5HrQRlarAfCumQ+kClQXxYqkpzlXISWuK75pVwmJ/DLjS7H7u6eGjT8jWolFyaDqqccvYc922z/7xMY/f6pNBejzo4HtD95Qa/4RSy71/r21D+2t01oxCiVVT03aeF7LB7UlYt/h8ciIP9HBlhcCCCCAAAII5KfAFd+d5CcBrUYAAQQQQACBbBbQms4/fLvr+YM9RiUVkUwHgnF1odKeihLHLVsrtSyycTQQiXWNJOaN09syj+MLdzabeaL2KE/Zu7msttLZ2RdUT7SOYQVDcUWKmjxOo3fH5p2PaHVg3VzRXpn7UrSnErT0s0aPqguY8qkbW8tfP9zfOZBY2Fe9CI2YTKmcUjx1+zKqmvKrztm5rnRbc4mRJ+qoAsRNDV6NntZ2ZWmRMp2US5b7rXA0GZ/RiU9LynzqlobSpHHiisOUkN5+ffXLh3pVea1hbbAvulYanysrXS7A9XVaTrrYpBJaVYnjvt01//DyxUWXn3Kh0TrlodqvRaI/sa8+uXX6qGiqzVt3Vr36fp9OUI+85LkI1TFWzdd0hHp95/WOYX9Ua5Vo3kxdldiVHS99pAemPRNPqtKlNbKN6km1xGW/Y1vV/3zxvM+vlWWmLvbOGabfu6NKT9n47OkpaI1vddHVhjQ0w8B8Bl9nBwa1QAABBBBAAIGlFyBSXHpTSkQAAQQQQACBJRRQ5KFBprMWuLHBq0V1799VbfT/0jnqU9Y3mujWp9xEqcfJzvFTXakpTzCsxDGROfYMKRpMbNjthTWVTn90OiLS+6u9qsqcygeV1BQ5EiORFSMqYuwfDxcmQs4C9dS7pbXytQ/6h0cTnbm03+jPVlF6aWa9uYrf1lycvFRxTWnRE3c1f3J6MV/1LkwOvOYqYWn3q2vk4EQCUy+FhsP+yKvHBo23xq/KEDUdpLHdNxwwOsQln7CgbTGqa6cuUcjbXKvQ7ooHJ+2NdVesQ72gwtNP1kB1jUE29uujMuhLbZ2Sa2MCSp0zvVzy5TJu2lJ+7NyoVnTRrlMdE71Dwafe7Cwrtm+o86pvqVaqqS1T7nb5/JXf0kdO1QsEEzXU7JxaN9z8M6I9+tOhPrzNNZ4T58d0pmZ+1CozjivBjTrrQ6hPrVl/fbY17N1iLYxPTunpX2OIbBbLBgIIIIAAAgisRQEixbX41KgzAggggAAC+SWgLmHG6GA1WytUGEGGxn5qvLPmgEseExqKxI2eborAtPTEf306MbQz5aWVMXRUL3XBM4qqKnb85qObFSGlnDnXW7fTpk5zOqqJEd0u29hERNFk/5gmU4xrOKpG6bY2eHQ00Q8uENV+o4NbfUWib9tcZWq/FntR0GOeoDVndBfjRubOldxQ/0St+WvcUZh//+KFlJ6SUjSXKPEHUtaDXlhNBag42Eh4FdeWey6P7DYKEmz6zoXd48qz/aGYZs809mnd5//94vmUDqT6kJiBqT+g3nyXr39oT63GPv/kQI/Cbj30ofGIvqz9hW2dWkhnUIveqOesMV7Y7Gh5+eIV2dJwZjXQ+OApBFSVUm6riLamzHmiYEz7lQXr+TaUO1Nqq7g80RvzymxUD+LKHSkF8xYBBBBAAAEE8kXg8ret+dJi2okAAggggAACa0pA8xL+4v3r9mwsM2r9ytGBn7zXq8VnFZoo0AmGJ5MjRaUdZuylXm9aQzlDW5WWGPPHKRnUtH0ZzpzrkMIvLesxHSnGFR1qjLYW/K2rdNeWOnWJ+ldq/YqB0bCRRjVVZRoYq2qr+5fGRc91r5Xfn8CcqY4we2ZWnpm1JoWZwtJZr7hip/K6mdWME8/ETJDNk7RTtubb+W8kMujkOHDmSrXOzMb0WVKX1Zkjs/xuOhjHyj32X7in5bbrKl79aGD/yWEtgWIk3Rq7ra/ekbCsjrWPf/7Oprunl2SZpcRl3zVVON0V17hPSv2NnVdqJiWmM3W7xmc6Uwy/I4AAAggggEBuChAp5uZzpVUIIIAAAgjkjID6SWkRld0zkaLWAu4cCLzx0aC6YB29MK4FPT59a4PZWK15oqGaxltNXHjrjkrldObRlI1tLSVux+VBnSlH5/NWi3JUFjvae9Tdcap/JOwLRdW1sLnGrf0lXru6trUPBLQstbGQdJMWBZ412pm+k81mWVxkNp96znqOcjb971KqOtsZwtF8jsYR9XTb1ORtqZozeC122zUH4mzFzGufZDTPpDFJn56sMYHjvK682kka4Kz+j+lneYpsenbGfvV43dRU3FzpSj/N2KNlW1IGYteWFenydTWeT9xUry6KZ3t9JzomTnaMa9ESdfrTutUftI1oisaNdZ6muYvVI5ieEXSu2y5+vzoY6pEpM9UtFAdrXsWUstSB0RzWrUNXXagn5XLeIoAAAggggAACRIp8BhBAAAEEEEBgLQkoo9mxvvSDc2O+QFTjVT84O3rrVq2McSn5UjbUUHEpGFKut3dz+b7NlxaDTm+kMkdN25e+f/57tJSKEUsZA5/Va1LBk+ZDVDam2evOBCa0uIo6VBqd5JRYZRj4rLDR7DQ3/wos9EyX43JwOR6MBiPx5OVrUkrTBI7VM5GiIqrNDd4v39OSco75Vk1zZVz12Dxz1g21XV0+HQ6LenoqT+xO616qTnTGsOj0y5MzYzUqOrMWs3HmqC+qnoPpV+npVxVf+tjo1tc1FX/pzqb004w9ap26sqYc1bPW0iX6UqCsKRTvvT4yPBHZf3r4Zx/0a+5FBXkX+/2dQ8GUSFHhqTmtoQbem/M5phR+jW8VzipS1B8HzZOoL6M+eohGscJUzHp+Zolzt8taNL3I+DXelMsRQAABBBBAIK8EiBTz6nHTWAQQQAABBNa8gFK8PZvKD58dfffEkKax++jC2NsnBh+/rdFoWGJlj8rEoGO9tC7zmx8N3r61Up3FjD1L/quWZ5mJFDWhXnh0PKL1K9SVT0OqNZK6rX2irdunQbXGfbWCcEpPtyWvz1ULVK9D10x41NbjUya7qS4x7eOsL9W22G3TwHNfYFIrI5/t8mmFlhvWXxqBPusl17JTq4iUeR294aDudbEvoNn9tMy0WaC6Ll7oT6ygnf7SQze7f55un9AEiFMFHmNUr1aYudjnVy/C9KvUn1Q9K7V2s5YtVuh2rts3Fohev+7S0uHp52fYo6L0MdDXVH2BuM50+RTh6fyJYEzLIqdcqKTP+Mxov7LOD8+Nfmx3Tco5S/JW83JqofBAKKC1gzQDwOELY2a8rjzxwOmR8UBi1SOFjw1V7isHQS/J/SkEAQQQQAABBHJcIPWfW3O8uTQPAQQQQAABBNa+QGuD9/oNpeqBpaYoFHu/baR39NJEeEW26VHSmxOxl5Zb0eDTP3+67Sfv9w77okZXQe2fjE9pVWitZXyNKxSrKN2uYnrwrKbSGxmLBEMxZVstVS5Fiutq3RrvfPLiuHEX7dGSzYnZG1f1pUkeDTfV4tDpkWcP9ihY1DIyequRsP5wbMQfUQxn1rGpynXvrkTgpVhKSdnXf3L+/7zd2T0cVMBnnCPVIV9EffGMlUDMCxexoeT3hunh7RI71+P75ivt5uIw6k15oG34uf09sxarLoQet35J2Co9fOH9vkNnR5TlDYyHn363+92Tw+GZFillHvVHzMqvr3XfOT3XoXoUnmof//rz53/wblePJkacaZ1+10rQHUPBlIkGz/b6T3ZO6FMXUgfFmWNi1Dj3d04Md850sVSfULNDollzhc4aRm3M+KnwdP/Joaf2d2uhGANQt04s6aPB8uYFi93QoOybZrrodg0Gvvtax8EzIxoGrnv97MP+777WbtRcw+0f09QBq/zBXGwjuQ4BBBBAAAEEVk+AXoqrZ8+dEUAAAQQQQGBRAuqVtntD2XstI0oM1VFRc9i9dXzos7cnOipqNVpNWfjYrY2nO33B0KTSMc26eKE/8NqRAY/DqnkYlf1p/Kyipc3NxU/c1VyctMLyIuqSGPjsTczHpyRII3aVCqlnn2bZ0+oi66fXexkeU4+5xKu02GEOO1Wm8+Qbnf1jiRhUlVcQqQ2lWj96t/v9MyPa1orSd++s3rcldci2ijrb7fvu6x3J+Z1iKeOtfj12fvQPv3PcjIf2tlbcd311cqqlUbqNVe62Lp/6qQ2OhV881NvWNaEmKFdSwKQ6lHgdd++suqW1QtXQq7bM+cDumqMXxi72+nXJ4TMjWul4//Gh6bkFE/8yrahR45Qt1sJ//6VtyTeavnphvyhS1BLer380EAhOqgPd8+/19o2EtFSxskJ1k7w44L/QO3svRd1m54bScz1+DTxXjPv60QGdqSk1VTf1Eg1G40ZXRJ125PzYX/7ozA2byu7bXdNY4dIY+ft31xzvmOjo86sVh9pGtJzOO8eG9KlQQqnzzdZ99cs7kuPgH7zd2d4f0NM3OkgaayDr5LHA5Llen/pX6loN5W6udrdUp87PqORTvS81eP/ouVE9OQ3x/tbPLopURekWiQ9SNKaPyr//0nazT+uTb3ed6ZzQKGkVa7yOt0/o86Zt5Zg/eufSx0ZvvS77Hdsrb55+fPoc7t1S/s7Jod6hUKJ1p4cVp9aXJYZpK/oUl85XsrmuzqMPCYmiAcuvCCCAAAIIIDB/ASLF+VtxJgIIIIAAAghki8B1jcV7NpVp1HM0Glfw9N7pkTu3Vyr/Uv0UzdzcWv75u5uePdAzNBpW0HO+x6cvHVJwph5wRues3vHw47c2XGOkqDn4NFbXQFHBCmiUXmlkq+6ybjpSNMI+nVA/3XXROFMjc1890n/uyoBMWadGc+tL55R6HQpG0yNFLaeinnHP7O8xizUKNH5Vu5RPJc9CaHNY79hamZz0CefBvbXne32nOyYUUGo1an0lF1JT7lTPRDNSVJc6LWLz+buaf/BWp4YGK401b2H0szP6YCoCi3zuuuQbJZc5z225adyxMr7nD/bqqWnxECkpZdONlHUqtmuodnUPzL6E98M31h04OaxxxKqPJq/Ul3FTl9N62/YqtVH5nfb0Dof0FZ6MK1VUpKjZNq9fX/rZOxqffqfrQo9f8XRnf0BfOjPRuqlEz01tq3Xq2ZocKX54dvRMt8/4IOkEYxUUbSS/dqzT7IrVddOfyeT92tYQ+IdvqjvTnUiTRdrRH9CX9pvl6HP1776wzYwU3zw2eOjUsNGZNKWoxMfm3Ki+jP3lJUV1FU4jUtSz27mu9KG9dT98p1sgShWPnhs7WjBmlqAhz5rxU8upa20WcycbCCCAAAIIIIDAPAUY+DxPKE5DAAEEEEAAgdURSIRKylqufJW4bQqDWhuLtVt5k9KZd08Nm6coIvncHU3/7OMbH9hTU+yxm5crfzFjIOV6Sb2+zEsXtqG6KUczerTpSmVAiuS0oRqrl5x5X+1RTmcmROomdrm/2Ww31ELMlyuadILyLdV/1jwx6azLm4kULFWu4MaNZb9w3zqthS2ZtIMFgXCih+DlIgoKytz2n9td8ysPbXjstsaqRAfMSxcpvDPyRJ2sR+ALTZq2yZcvaFudKL9wZ9Nn72ysLi8y8jUlbipcQe3e1vJH9tXPVdqmOu+X71t345Zyc1i3ztQK1Ldvr1Ivy9qkORmNEsyq6qPy4J5ate6TtzRo5sErWjdz0qXWzdw7MqkqXfF8Zk5MnJHI6dT5cU/tz9/botWBlOvNXHf5d81yeNf2qq88sH7ruhKz76oOm+Vo/s1AJJaIM6dfChMzf2BmTkyEkkaXSWOPPoSP3tzw8/e1bFtXYn5KdUiniVSfgV9/ZNM9O6vMy40NfVCNZ6y2XNpKOkM9cPXxTtrBJgIIIIAAAgjkqQC9FPP0wdNsBBBAAAEEslxAS0mUOm3B8KRGAWuV5/Tabmsq+aWPrdfiGzqk9Wo1yNQ8R1GaUqRHbqrb1lx8U2uFBtIq8BrxRxUpKiNR3zRNa1hebPe6rmm5Z+N2zdWuf/GpzepVp7dKbRqnB7oqcVFs9Buf2mwmT9e1lDhnFkRW0PPl+1rG/Fckd2bltaHmaLLI5D3GtvKdDbUe3S790Kx7pm+a2kZloOo9V1/p1HIrmrNPa5JoRK3CLKVpOlTmtWtQeXJpumm5137PzmoFuLs2lo75ourvpkBWQZvySk0PKUx1fvQWLcF3lcrXtjR6n/C0tDYVa1z2iC+qNK2y2F5RXNRc4561m55RVWVc6t5YVerQhI/9Y2ENbFdRGl+sUK+u3Knos2F6bRx9MDTZZWOVSzuNC9U6LZZy7/U1rQ3F6rqoodPT8y1q2ehE64x5D7UotibNNFM0XfLl+1s0HaeyV83XqQ6MOiQ9PV85JJbJLitSxKkQWW+TJc1tnV9TVvS5OxrVzPY+vzDHE2uoJBJFrfTidthKPTaHTfe59PrMbQ13bqs0A9yZ3bP87iqy7VhfYh5Qe7X++Kdvbdhc79WfFM0vOapFyS2FGk6up7alyatuoeZdzKse2lO7tb5YFZKh0fPXPKSNe66v1oDxWCyR825rvnyv5HPYRgABBBBAAIF8ENC8Oea/gOZDe2kjAggggAACCOSdgL7ZCUQmx/yJ1EY5jZETKVhMD1PyjUbrsWiwsBEpKn6Siddp06jbDDLCDEdjmjTQmNovsW6yy64s8nIAtkSI6p9oxJ1lHrtmLdTb/W3D//prh43if/cXtn38xjoFmil3Uy6n4Eyhpw5pVLtapAoHFSbHEiOXE1/WQtV1rtrqZE1lqNYZGbEytWKnbdZkUGHiRGhS3QmNSFEVcdisWo9Fw7d1l5RaZXirCivv9mnBG/X6LJhStYWpmi+okAzlm4cSDpHYeDCqkpUnztp90jyZDQQQQAABBBBA4KoCS/DvyVe9BycggAACCCCAAAKrKKD8yFNk09cq1iE7b63+d/paUN2EqdRMXwu6ahEna/it+g8u9EKN1VVepi/zQlXYPe/a6mQlevoyL59rQ2FlkX3B1UsvTRUucdn1lX5oafckHBKdKK/etKW9L6UhgAACCCCAQK4KpP7Tbq62k3YhgAACCCCAAAIIIIAAAggggAACCCCAwJIIECkuCSOFIIAAAggggAACCCCAAAIIIIAAAgggkC8CRIr58qRpJwIIIIAAAggggAACCCCAAAIIIIAAAksiwKRCS8JIIQgggAACCCCAAALLK6AVRbSwsnEPTUG4vDejdAQQQAABBBBAAIGMAkSKGXk4iAACCCCAAAIIIJAFAhZLQUO58+M31Rl1aalykypmwWOhCggggAACCCCQvwKFU1NT+dt6Wo4AAggggAACCCCAAAIIIIAAAggggAACCxRgLsUFgnE6AggggAACCCCAAAIIIIAAAggggAAC+S1ApJjfz5/WI4AAAggggAACCCCAAAIIIIAAAgggsEABIsUFgnE6AggggAACCCCAAAIIIIAAAggggAAC+S3A8iz5/fxpPQIIIIAAAgjkgUBkMj4RnAxGYtHJeGFhYU1pkbvImgftTjQxFIkP+yKhSMxmK3TarV6nzeWwsl50njx9mokAAggggAACyydApLh8tpSMAAIIIIAAAgisskAoGu8fDbUPBj84O9I+EFS45nRYf/WhDbvXl65yzVbq9p1Dwf/zVufJzvFSj72p0rWzpWRLQ3FNWVGJ2164UnXgPggggAACCCCAQO4JECnm3jOlRQgggAACCCCAQEJgLBA9fG70b3964UynbzIWN1BKvHZfcDI7gaamCvyhyf6xsKpnsxZWFDvUqfAaqzpVMDU0Fj55YVzl7C8o+H5BQXON+9FbGx7cU6vemlYLueI1AnM5AggggAACCOSpwLV+l5anbDQbAQQQQAABBBDIbgFfaPK7b3Z+95V2M0C0WAodNktDpcvjvDzqORaf0pkaHWy0xlVkLXbakscF6wTFfMGIRkwXOO0Wde5bvnZHYvE3jg/+4bdP6Ba1Fc5f+fiGR26su8bblbntlcUOt9MajsZjsSmV1tEf+Ppz545fHP+1Rzauq3Fbklt7jTfjcgQQQAABBBBAIG8EiBTz5lHTUAQQQAABBBDIG4H41NT33+n6h5fblQaq0QoTyzz2ytKizY3e27ZWrqvxmBKj/qjGBb95fMjYc9eOqifubi5xXf4WcXA8/NT+7jePDWnE9L7W8n/24Abz2qXfmCqIx6eMDpWa9lEh4LXfosxrv39Pjc1hOd0x0TsUHA8oP03MKfnWsUGLpeC3Pr2lttR57XehBAQQQAABBBBAIN8ELn+/mG8tp70IIIAAAggggECuCvSOhr/10kUjT9TY3qYa9+984bpd60ptVktKk8PRWPdgsK09MS5YL80vuLXJe8+OauOtflX/xAu9AZ1QZLeWe5axi6J5x6XdsFstt2yp0JeKPdPj+9ar7T97v09hpVLFo+fHnz/U95X71tFPcWnNKQ0BBBBAAAEE8kEg9dvKfGgzbUQAAQQQQAABBHJYQIN7v/N6u/riqY2aKXBjY/EffmXnDRvK0vPEdISzPb7DZ0fVyTH9UA7s2Vzv/eUHN3zy1gbljGrOwGjo/baRYX8kB5pGExBAAAEEEEAAgRUWIFJcYXBuhwACCCCAAAIILK/ARHDy+f29xqhht8v2H5/YtqXeO88ZA8Pqk9gXONfnX94qrl7pWvT5c3c2PbC31qjCxf7AS4f7V6863BkBBBBAAAEEEFirAkSKa/XJUW8EEEAAAQQQQGBWge+91WF0UdTRh/bVVZQ4FjSwt63b9+6p4VlLzrBT3RrVtVHdG/WljXn2cky+JEPh6YcWdzujnPU1HrPPZu9w8J1jg4GZ1WnSb8QeBBBAAAEEEEAAgVkFmEtxVhZ2IoAAAggggAACa1XgxUN90emljdWAR/bWlS5wjeaBkdCp9gktA+11zvcbxchkXNMUHu/0tfVMuOzWLQ2ebU0l6g+oBabnQoxPFfSPhY53jJ/onNCa1NtbSm6/rnKed5yMT53r9Z/qmjjV49NaLhtqPK0N3usait1Fl1eynuu+2m8pLNhY77lhS9l7J4eVaWr9maMXR43JFjNcxSEEEEAAAQQQQACBZIH5fqeYfA3bCCCAAAIIIIAAAlkrMDwWSXQULCjYtaWstsyp5VnmWdUSj91qLRwZj1zo8x9oG7n/+suLtMxVgm5z5MLYv/+7j0Z9kXg80UtR0zdqkLXuuXtz+W98cvOWeo/Wm065fCwQ/fZrHU+91RkIxRKdGqcKfmzp9rhsd++q3t5cknJy8ludebrb9zv/68jQaFihpJaH1tHC6dvVVbl+87Et+zaXF9nnzDHNojbXe267rkKRovaEonGliuYhNhBAAAEEEEAAAQTmI3D1b7nmUwrnIIAAAggggAACCGSDgCZDjEQTC7PotbHOO598zThZv25tLr5hY5k2NMPgwVOJHnyZX7H41Pfe6vxXXzvcPxpKrKEci2tPLDalxZT19tCp4d/+Hx++eWJQfRiTy+kdDf3Vs2e/8/LFcV9UZ07GpnSVNsZ8kcNnRt4+OZR8cvK2zvzhge5f+4v3egaDxpLNidvFp9RRUbfo6Av8/t999OzBHk0lmXzVrNvuIluF12HML6lB4kMTrNAyqxM7EUAAAQQQQACBOQWIFOek4QACCCCAAAIIILC2BJQB9o6FzCiwtrRo/l0U1dJ1NR4NQLbZLOFITKni6R5fhubrLhq5/LUfnfGHJo07qjdiY42nvMRhdEtU2Dc4GvrB290qKrmc144Ovnl8SJmgaqsz6yqdN2+v3L2lXH0kuwaC+4/NHinqFgPjob/8YVsgrI6NifKKHNZNzcVbWkrcTpsmi1RfR9Xkm69e1Jjo5NvNuq1uk3abxTk9UFo1GRwjUpzViZ0IIIAAAggggMCcAgx8npOGAwgggAACCCCAwBoTmCroGQ6ZnQurShYWKdothZsavNvXlRw5O3qxz//W8cHrGrxzCYQn43/3crsCPuOEhmr3f3hie2OlU28Ptg1/7dlzfSOJcFN9FU/urmmqcrkciYkOe0ZCxy+Oadiyth12y8P76n7+npYyr0OBYMdA4Ptvd71wsNcoMOXXYCT2zdc6JgKXeiDeuav61z++scyTWHlGSeL//OmF148MBEKTPYOh/aeHGqucVcVFKSWkvFUiWey26ZJwNDZCL8UUHd4igAACCCCAAAJXE6CX4tWEOI4AAggggAACCKwRAYWJ3SPBxNyE06+FRoq6SIuc7N2UGPs8PBE51TExHowaRaX/Go3GXzjYY+7//Se27mgpri4t0tf9u2o+cWt9ebFDRzUkef/pYSWJxpmaeLGtx5eYcrGgYN91FY/d2riuxl3usWsY8o6W0of31q1v8JhlJm+onBcOXLpdQ437tz/durHOU1XiqCx2NFe5/69PbFpfm5i0UbMrHrs4MTwxZ7XNMp0OiyJFvY1OTvnnMVbavJANBBBAAAEEEEAAAQkQKfIxQAABBBBAAAEEckZgSp0HzcbYrVq5xHw3r40Sl00dFesqXcrm2vsD+0+PzHqZMsERf0SLqxhHtQ7M5vpiDSU23jodVq00rbzPeNs1FDTnN+wfC4/6E3mfzWrZUl+slZqNCQ2n9xSur3Hv21xhXJX8a+J2vohvuouiWvQL9zbXlBaZF2pPdUnRvq0VJdMRoeJLs+9kciEp27pcddBOJbCa/zHlKG8RQAABBBBAAAEEMgsw8DmzD0cRQAABBBBAAIE1I1BYUKieifpVQZkqrYWVtQpzQWLA8Xxf6ui3ucG7d3PZs0PB7qHg/hNDm+pm6TaoYruHg2ah6mDomMkTjZ0NFS7PpSkOC4bHI6GZ8dET/qjGGuucUq+9qsyRcpXXaW+oSAydTnlpWkbdzoz9IrGpN04OTjfz8ok6Qeu36P3weDgUufoKLer26JuORK1Wi9O5EKPL92QLAQQQQAABBBDIXwEixfx99rQcAQQQQAABBHJPoKHMmUgUp18D42GFcQttY2OFa+e60p++369JBi/0+U91TaSXkMj4ZsYy62h9hdMyc1PjZC0L43XZ1A3QWMo5NLMIdTAci0QS/SgVOOorpWSHLXFVyk69VS/C7uFLQ6c1Zvq7r7SnLzszHpg0OicqvpycvHqrtdDzRCDRX1JTOmoyx/SbsgcBBBBAAAEEEEAgg8As37RlOJtDCCCAAAIIIIAAAlkroCHA9RUuc7CzIsXJhUeK6jm4sd6zY33JB20jGrOs1Zlnb29SajfrTDo6bpySdGKBxlMbEylaLAXmyGWzfI3TTs8KjaPGKtLGdu9MvGhemLyhQkyB5P0p25oL0ugvWWS3lBMppujwFgEEEEAAAQQQuJoAkeLVhDiOAAIIIIAAAgisHYFSt00zKBr11erPk7HLUyvOvxHrazw3t5YrUhzzRY9dGKspT109WYFgVenlnUO+SHp0qd6C8emRyMVuu8N2aWSxugTabBbFeeFoXEOP51klq7WwMWlA9Kam4s31nvRE0ijN7bTVlbsyl6wh0lpCenK6Ak67tXJm2sfMV3EUAQQQQAABBBBAwBQgUjQp2EAAAQQQQAABBNa8gHr5edw2DTTWAOEPz4z6Q7FyrzkSer6t0zonmxuK66tcPYPBgdGwMUA4+WLdpanicmx3+NxY7N7kzogFWiPFF1QXycTOihKHq+hSpOhx27WtSFFh5agvosPJA6YTK6WkZ5Nay8Viaax0mxWoKiv6ygPrHNOLq5g7zQ3lj5XFl+NOc3/yRu9o6FSXb7p2BU67RctGJx9lGwEEEEAAAQQQQOCqArOOU7nqVZyAAAIIIIAAAgggkKUC29aXGsOEtVDJB+dGNH3hQiuqDoCJxZe3JBZfVlc+Y6nl5EJ0QrnXbi7xfOriePtAIDkN/NmH/UMTEeOS+nKnd2b9E11lzJaoPoxaUbo3aUJGnewLxxT2Jd/I2Fa3S5VQOhP8nemY6BwKagWYlmp3+pfmglRKmF5I8p5zvf4Dp4eNPepEuXG2JWiSz2cbAQQQQAABBBBAIEXgKt9vpZzNWwQQQAABBBBAAIEsF3j8tgb7dA8+9cJ77r3e8elFSBZa59oy5+4NpUWOOZdCdjqs9+2pMYrVpIT/7cdnPjg3qgVStMz0s+/1vvBerzoh6qjCzRs2lqk048ztTSXrqhP9DdWB8eCp4ecO9mjCR+OQLnz7xODLh/uNtym/uhzWz97RaOwcGgv/7fPn/+6Vi2d7feboaXV4HAtMahUXcymYlBLMt7rR6a6J3qHEitVet21Lo7ehfJZlps3z2UAAAQQQQAABBBBIF2Dgc7oJexBAAAEEEEAAgTUssGdDWWtL8TENRo5Pnbgw/tKR/k/d3FAy20rKGRqpRUs21CUWaXn/9Misp2kVly/e1fzakYHwdC/Ig6eHleXVl7s02vlsj69rMKj5CnXhro2l168r9c4s7ryh1r29pfTYxfFxf7RvJPTM/p62Ll+Fuh8WFmgotBaYbu8LzH47u+UT++rfPjF08uK4TjjVMTE4EfnwzIhWVlFNtCCLGqvpEXXLX/q59a2N3lkL0U7N4XiwbeS1owNG9ZoqXfdcX60S5jqf/QgggAACCCCAAAKzChApzsrCTgQQQAABBBBAYK0KqEPfZ25rPNPpU+fBUCT29FtdsdjUozc3VHjtC2qS4rbbtlbOFSlqOsXWBu/P39vynVfbNYpZPSKPnBs7UjCWfIt1dZ5P3dq4rsY9s2BMgfo23rG9Ur0L3z42GInGu4eCPcNB6/Qyz1pJxuOy1VW6ugcDxiyHyUUpNawrd/7Sxzb8/csXjp0f0wlDo2F96RwdUiKptaS1bbNaHr25Xh0Pk6doNMtRJ0qFkt99veNst087Navj5sbinetKzRPYQAABBBBAAAEEEJinAJHiPKE4DQEEEEAAAQQQWDMCd2yr+lFz99Fzo+qL19EfeOqtLq2ysq2lRDMPNle5il1K3mbJ3NTXL3m1lGK3bWvTpUVaEi0vLEi5SnMpfu6OJvUTfOZA9/kefzRpBWeNmL6ptfznbqhVKGlMnmjabWnwqnuj+i2+c2JIsz0qHNR0jRofXeZ13NRaoRp+8+UL4cgsi0GrM+LtWyucDst7p0Z+dqS/f2Y968QiMIk4MfFSLqm5IxWhat1rY49+9YUmtVxMx2CwrWvi3eNDJzsnjPyxqdp9185qz8zSMeb5bCCAAAIIIIAAAghcVaBQK+td9SROQAABBBBAAAEEEFhbAm+eGPras2fP9fiUr6nm6pFXW+6sq3BubS7RCOKWqkvrNStuO3x29HyfX+dsbym5cVO52aNQezS4+L22YcWR2lZI11jlvntHlbaTX1pc+p2TQxrprEkbR/1RJXlaQFkx4vZ1JUoPnfZZZmNUh0Ld8fjF8f7R0HhwUt+OlrrtVaVFmxq83iLbTw/3KfIr89j3bC5XR8jkexnbI77ogbbh4bGweh2O+KPh6eWtVT1FpZ4i293XV6tfpJl+as3rnx3ue/P4YO9ouHc4qAHXxje/TVXuz93V9Imb6xc6JDy9PuxBAAEEEEAAAQTyUIBIMQ8fOk1GAAEEEEAAgdwXUGz38pH+n7zX+96pYQ1/NhtcW+H83S9tu6U1sZrz0r40laFWPtEwZKWB6sB4uZfg3LcJT8b9IUWKWtDZptkbdaKmYlRtFQhqhZnknoazlqG1WXRHDaBWaKobepw2d5Exivry6V1Dwf/+zNmXPugzd6luyi6Vqz5wQ43ST3M/GwgggAACCCCAAALzF2Dg8/ytOBMBBBBAAAEEEFgzAor0HthVU1NWpI5+JzrHz/cEtASzFifxBSeTRygvYXs0h6O+FlRgkc1S5L0i1FMyaK7lctWitKxKdUlR5tPUDVNZp7pearB3icfeVOVqbSzWoOy9m8rVqzHztRxFAAEEEEAAAQQQmEuAb6TmkmE/AggggAACCCCwtgWUo+1aV7ql3numx9fW7RseT0SKihobKi6Nel7bzZtf7Us9dq3pvLHOo86JpV77uhrP5npvVbEjeXz3/EriLAQQQAABBBBAAIHLAgx8vmzBFgIIIIAAAggggAACCCCAAAIIIIAAAghcVSAxZw0vBBBAAAEEEEAAAQQQQAABBBBAAAEEEEBgngJEivOE4jQEEEAAAQQQQAABBBBAAAEEEEAAAQQQSAgQKfI5QAABBBBAAAEEEEAAAQQQQAABBBBAAIEFCBApLgCLUxFAAAEEEEAAAQQQQAABBBBAAAEEEECASJHPAAIIIIAAAggggAACCCCAAAIIIIAAAggsQIBIcQFYnIoAAggggAACCCCAAAIIIIAAAggggAACRIp8BhBAAAEEEEAAAQQQQAABBBBAAAEEEEBgAQJEigvA4lQEEEAAAQQQQAABBBBAAAEEEEAAAQQQIFLkM4AAAggggAACCCCAAAIIIIAAAggggAACCxAgUlwAFqcigAACCCCAAAIIIIAAAggggAACCCCAAJEinwEEEEAAAQQQQAABBBBAAAEEEEAAAQQQWIAAkeICsDgVAQQQQAABBBBAAAEEEEAAAQQQQAABBIgU+QwggAACCCCAAAIIIIAAAggggAACCCCAwAIEiBQXgMWpCCCAAAIIIIAAAggggAACCCCAAAIIIECkyGcAAQQQQAABBBBAAAEEEEAAAQQQQAABBBYgQKS4ACxORQABBBBAAAEEEEAAAQQQQAABBBBAAAEiRT4DCCCAAAIIIIAAAggggAACCCCAAAIIILAAASLFBWBxKgIIIIAAAggggAACCCCAAAIIIIAAAggQKfIZQAABBBBAAAEEEEAAAQQQQAABBBBAAIEFCBApLgCLUxFAAAEEEEAAAQQQQAABBBBAAAEEEECASJHPAAIIIIAAAggggAACCCCAAAIIIIAAAggsQIBIcQFYnIoAAggggAACCCCAAAIIIIAAAggggAACRIp8BhBAAAEEEEAAAQQQQAABBBBAAAEEEEBgAQJEigvA4lQEEEAAAQQQQAABBBBAAAEEEEAAAQQQIFLkM4AAAggggAACCCCAAAIIIIAAAggggAACCxAgUlwAFqcigAACCCCAAAIIIIAAAggggAACCCCAAJEinwEEEEAAAQQQQAABBBBAAAEEEEAAAQQQWIAAkeICsDgVAQQQQAABBBBAAAEEEEAAAQQQQAABBIgU+QwggAACCCCAAAIIIIAAAggggAACCCCAwAIEiBQXgMWpCCCAAAIIIIAAAggggAACCCCAAAIIIECkyGcAAQQQQAABBBBAAAEEEEAAAQQQQAABBBYg8P8DAA3xveEZM1sAAAAASUVORK5CYII="
- }
- },
- "cell_type": "markdown",
- "id": "5894115c-0323-4098-83be-da49d949a53c",
- "metadata": {
- "tags": []
- },
- "source": [
- "### Self-RAG\n",
- "\n",
- "Self-RAG is a strategy for RAG that incorporates self-reflection / self-grading on retrieved documents and generations.\n",
- "\n",
- "In the [paper](https://arxiv.org/abs/2310.11511), a few decisions are made:\n",
- "\n",
- "1. Should I retrieve from retriever, `R` -\n",
- "\n",
- "* Input: `x (question)` OR `x (question)`, `y (generation)`\n",
- "* Decides when to retrieve `D` chunks with `R`\n",
- "* Output: `yes, no, continue`\n",
- "\n",
- "2. Are the retrieved passages `D` relevant to the question `x` -\n",
- "\n",
- "* * Input: (`x (question)`, `d (chunk)`) for `d` in `D`\n",
- "* `d` provides useful information to solve `x`\n",
- "* Output: `relevant, irrelevant`\n",
- "\n",
- "3. Are the LLM generation from each chunk in `D` is relevant to the chunk (hallucinations, etc) -\n",
- "\n",
- "* Input: `x (question)`, `d (chunk)`, `y (generation)` for `d` in `D`\n",
- "* All of the verification-worthy statements in `y (generation)` are supported by `d`\n",
- "* Output: `{fully supported, partially supported, no support`\n",
- "\n",
- "4. The LLM generation from each chunk in `D` is a useful response to `x (question)` -\n",
- "\n",
- "* Input: `x (question)`, `y (generation)` for `d` in `D`\n",
- "* `y (generation)` is a useful response to `x (question)`.\n",
- "* Output: `{5, 4, 3, 2, 1}`\n",
- "\n",
- "We will implement some of these ideas from scratch using [LangGraph](https://langchain-ai.github.io/langgraph/).\n",
- "\n",
- "> Figure and the explanation taken from the [LangGraph cookbook](https://github.com/langchain-ai/langgraph/blob/e3ca7bb3e9d34b09633852f4d08d55f6dcd4364b/examples/rag/langgraph_self_rag.ipynb)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "1def042d-abcc-47af-8926-a9d1e2e8154f",
- "metadata": {},
- "source": [
- "### Define the LangGraph Workflow\n",
- "\n",
- "\n",
- "The LangGraph agent operates as a multi-step workflow.\n",
- "\n",
- "- It retrieves documents, grades their relevance, generates an answer, and ensures factual accuracy (e.g., no hallucinations).\n",
- "- You can also implement self-reflection and query optimization using LangGraph nodes."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "8c4c9be8-396c-4ebc-a9e4-d4e11504c05c",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langchain_core.prompts import ChatPromptTemplate\n",
- "from langchain_core.pydantic_v1 import BaseModel, Field\n",
- "from langchain_openai import ChatOpenAI\n",
- "\n",
- "\n",
- "# Data model\n",
- "class GradeDocuments(BaseModel):\n",
- " \"\"\"Binary score for relevance check on retrieved documents.\"\"\"\n",
- "\n",
- " binary_score: str = Field(\n",
- " description=\"Documents are relevant to the question, 'yes' or 'no'\"\n",
- " )\n",
- "\n",
- "\n",
- "# LLM with function call\n",
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "structured_llm_grader = llm.with_structured_output(GradeDocuments)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You are a grader assessing relevance of a retrieved document to a user question. \\n \n",
- " It does not need to be a stringent test. The goal is to filter out erroneous retrievals. \\n\n",
- " If the document contains keyword(s) or semantic meaning related to the user question, grade it as relevant. \\n\n",
- " Give a binary score 'yes' or 'no' score to indicate whether the document is relevant to the question.\"\"\"\n",
- "grade_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\"human\", \"Retrieved document: \\n\\n {document} \\n\\n User question: {question}\"),\n",
- " ]\n",
- ")\n",
- "\n",
- "retrieval_grader = grade_prompt | structured_llm_grader"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "499173a5-8df0-4fe6-bb46-552ce496b8ba",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langchain import hub\n",
- "from langchain_core.output_parsers import StrOutputParser\n",
- "\n",
- "# Prompt\n",
- "prompt = hub.pull(\"rlm/rag-prompt\")\n",
- "\n",
- "# LLM\n",
- "llm = ChatOpenAI(model_name=\"gpt-3.5-turbo\", temperature=0)\n",
- "\n",
- "\n",
- "# Post-processing\n",
- "def format_docs(docs):\n",
- " return \"\\n\\n\".join(doc.page_content for doc in docs)\n",
- "\n",
- "\n",
- "# Chain\n",
- "rag_chain = prompt | llm | StrOutputParser()"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "d9055d3b-8e9b-494f-bf4f-d02c153639c7",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "class GradeHallucinations(BaseModel):\n",
- " \"\"\"Binary score for hallucination present in generation answer.\"\"\"\n",
- "\n",
- " binary_score: str = Field(\n",
- " description=\"Answer is grounded in the facts, 'yes' or 'no'\"\n",
- " )\n",
- "\n",
- "\n",
- "# LLM with function call\n",
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "structured_llm_grader = llm.with_structured_output(GradeHallucinations)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You are a grader assessing whether an LLM generation is grounded in / supported by a set of retrieved facts. \\n \n",
- " Give a binary score 'yes' or 'no'. 'Yes' means that the answer is grounded in / supported by the set of facts.\"\"\"\n",
- "hallucination_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\"human\", \"Set of facts: \\n\\n {documents} \\n\\n LLM generation: {generation}\"),\n",
- " ]\n",
- ")\n",
- "\n",
- "hallucination_grader = hallucination_prompt | structured_llm_grader"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "f92d351d-5ee1-48cc-ad8f-9b57ceed18ed",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "class GradeAnswer(BaseModel):\n",
- " \"\"\"Binary score to assess answer addresses question.\"\"\"\n",
- "\n",
- " binary_score: str = Field(\n",
- " description=\"Answer addresses the question, 'yes' or 'no'\"\n",
- " )\n",
- "\n",
- "\n",
- "# LLM with function call\n",
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "structured_llm_grader = llm.with_structured_output(GradeAnswer)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You are a grader assessing whether an answer addresses / resolves a question \\n \n",
- " Give a binary score 'yes' or 'no'. Yes' means that the answer resolves the question.\"\"\"\n",
- "answer_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\"human\", \"User question: \\n\\n {question} \\n\\n LLM generation: {generation}\"),\n",
- " ]\n",
- ")\n",
- "\n",
- "answer_grader = answer_prompt | structured_llm_grader"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "286a9a2a-2a62-4004-84a2-fc82e6996cf1",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You a question re-writer that converts an input question to a better version that is optimized \\n \n",
- " for vectorstore retrieval. Look at the input and try to reason about the underlying semantic intent / meaning.\"\"\"\n",
- "re_write_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\n",
- " \"human\",\n",
- " \"Here is the initial question: \\n\\n {question} \\n Formulate an improved question.\",\n",
- " ),\n",
- " ]\n",
- ")\n",
- "\n",
- "question_rewriter = re_write_prompt | llm | StrOutputParser()"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "cb9bd597-a683-433a-879d-7991cfed5cf7",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from typing import List\n",
- "\n",
- "from typing_extensions import TypedDict\n",
- "\n",
- "\n",
- "class GraphState(TypedDict):\n",
- " \"\"\"\n",
- " Represents the state of our graph.\n",
- "\n",
- " Attributes:\n",
- " question: question\n",
- " generation: LLM generation\n",
- " documents: list of documents\n",
- " \"\"\"\n",
- "\n",
- " question: str\n",
- " generation: str\n",
- " documents: List[str]"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "398e5cc2-9c41-465d-a4f4-93c82ed452f2",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "def retrieve(state):\n",
- " \"\"\"\n",
- " Retrieve documents\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): New key added to state, documents, that contains retrieved documents\n",
- " \"\"\"\n",
- " print(\"---RETRIEVE---\")\n",
- " question = state[\"question\"]\n",
- "\n",
- " # Retrieval\n",
- " documents = retriever.get_relevant_documents(question)\n",
- " return {\"documents\": documents, \"question\": question}\n",
- "\n",
- "\n",
- "def generate(state):\n",
- " \"\"\"\n",
- " Generate answer\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): New key added to state, generation, that contains LLM generation\n",
- " \"\"\"\n",
- " print(\"---GENERATE---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- "\n",
- " # RAG generation\n",
- " generation = rag_chain.invoke({\"context\": documents, \"question\": question})\n",
- " return {\"documents\": documents, \"question\": question, \"generation\": generation}\n",
- "\n",
- "\n",
- "def grade_documents(state):\n",
- " \"\"\"\n",
- " Determines whether the retrieved documents are relevant to the question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): Updates documents key with only filtered relevant documents\n",
- " \"\"\"\n",
- "\n",
- " print(\"---CHECK DOCUMENT RELEVANCE TO QUESTION---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- "\n",
- " # Score each doc\n",
- " filtered_docs = []\n",
- " for d in documents:\n",
- " score = retrieval_grader.invoke(\n",
- " {\"question\": question, \"document\": d.page_content}\n",
- " )\n",
- " grade = score.binary_score\n",
- " if grade == \"yes\":\n",
- " print(\"---GRADE: DOCUMENT RELEVANT---\")\n",
- " filtered_docs.append(d)\n",
- " else:\n",
- " print(\"---GRADE: DOCUMENT NOT RELEVANT---\")\n",
- " continue\n",
- " return {\"documents\": filtered_docs, \"question\": question}\n",
- "\n",
- "\n",
- "def transform_query(state):\n",
- " \"\"\"\n",
- " Transform the query to produce a better question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): Updates question key with a re-phrased question\n",
- " \"\"\"\n",
- "\n",
- " print(\"---TRANSFORM QUERY---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- "\n",
- " # Re-write question\n",
- " better_question = question_rewriter.invoke({\"question\": question})\n",
- " return {\"documents\": documents, \"question\": better_question}\n",
- "\n",
- "\n",
- "### Edges\n",
- "\n",
- "\n",
- "def decide_to_generate(state):\n",
- " \"\"\"\n",
- " Determines whether to generate an answer, or re-generate a question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " str: Binary decision for next node to call\n",
- " \"\"\"\n",
- "\n",
- " print(\"---ASSESS GRADED DOCUMENTS---\")\n",
- " state[\"question\"]\n",
- " filtered_documents = state[\"documents\"]\n",
- "\n",
- " if not filtered_documents:\n",
- " # All documents have been filtered check_relevance\n",
- " # We will re-generate a new query\n",
- " print(\n",
- " \"---DECISION: ALL DOCUMENTS ARE NOT RELEVANT TO QUESTION, TRANSFORM QUERY---\"\n",
- " )\n",
- " return \"transform_query\"\n",
- " else:\n",
- " # We have relevant documents, so generate answer\n",
- " print(\"---DECISION: GENERATE---\")\n",
- " return \"generate\"\n",
- "\n",
- "\n",
- "def grade_generation_v_documents_and_question(state):\n",
- " \"\"\"\n",
- " Determines whether the generation is grounded in the document and answers question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " str: Decision for next node to call\n",
- " \"\"\"\n",
- "\n",
- " print(\"---CHECK HALLUCINATIONS---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- " generation = state[\"generation\"]\n",
- "\n",
- " score = hallucination_grader.invoke(\n",
- " {\"documents\": documents, \"generation\": generation}\n",
- " )\n",
- " grade = score.binary_score\n",
- "\n",
- " # Check hallucination\n",
- " if grade == \"yes\":\n",
- " print(\"---DECISION: GENERATION IS GROUNDED IN DOCUMENTS---\")\n",
- " # Check question-answering\n",
- " print(\"---GRADE GENERATION vs QUESTION---\")\n",
- " score = answer_grader.invoke({\"question\": question, \"generation\": generation})\n",
- " grade = score.binary_score\n",
- " if grade == \"yes\":\n",
- " print(\"---DECISION: GENERATION ADDRESSES QUESTION---\")\n",
- " return \"useful\"\n",
- " else:\n",
- " print(\"---DECISION: GENERATION DOES NOT ADDRESS QUESTION---\")\n",
- " return \"not useful\"\n",
- " else:\n",
- " pprint(\"---DECISION: GENERATION IS NOT GROUNDED IN DOCUMENTS, RE-TRY---\")\n",
- " return \"not supported\""
- ]
- },
- {
- "cell_type": "markdown",
- "id": "b77061d5-fa7f-4dbc-ad5b-cc409b931bf4",
- "metadata": {},
- "source": [
- "### Compose the graph"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "f5ae35f7-ff5c-40f1-9b0e-1a8bac0dc58f",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langgraph.graph import END, StateGraph, START\n",
- "\n",
- "workflow = StateGraph(GraphState)\n",
- "\n",
- "# Define the nodes\n",
- "workflow.add_node(\"retrieve\", retrieve) # retrieve\n",
- "workflow.add_node(\"grade_documents\", grade_documents) # grade documents\n",
- "workflow.add_node(\"generate\", generate) # generatae\n",
- "workflow.add_node(\"transform_query\", transform_query) # transform_query\n",
- "\n",
- "# Build graph\n",
- "workflow.add_edge(START, \"retrieve\")\n",
- "workflow.add_edge(\"retrieve\", \"grade_documents\")\n",
- "workflow.add_conditional_edges(\n",
- " \"grade_documents\",\n",
- " decide_to_generate,\n",
- " {\n",
- " \"transform_query\": \"transform_query\",\n",
- " \"generate\": \"generate\",\n",
- " },\n",
- ")\n",
- "workflow.add_edge(\"transform_query\", \"retrieve\")\n",
- "workflow.add_conditional_edges(\n",
- " \"generate\",\n",
- " grade_generation_v_documents_and_question,\n",
- " {\n",
- " \"not supported\": \"generate\",\n",
- " \"useful\": END,\n",
- " \"not useful\": \"transform_query\",\n",
- " },\n",
- ")\n",
- "\n",
- "# Compile\n",
- "app = workflow.compile()"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "598a9ef4-cfb2-479a-9a74-b82c5781daca",
- "metadata": {},
- "source": [
- "# Serve the agent\n",
- "\n",
- "`BaseRAGQuestionAnswerer` provides `serve_callable` that lets you attach a custom Python function to an endpoint. This way, you can create your own endpoints on the Pathway server in addition to the [built-in ones](https://pathway.com/developers/ai-pipelines/rest-api).\n",
- "\n",
- "Use the `serve_callable` method to expose the LangGraph agent as an HTTP endpoint.\n",
- "The `/agent` endpoint accepts user queries, processes them through the LangGraph pipeline, and returns the final answer."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "fafc447a-c221-4251-ad40-c56cb77c338c",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "@rag_app.serve_callable(route=\"/agent\")\n",
- "async def call_agent(user_query: str) -> str:\n",
- " langgraph_input = {\"question\": user_query}\n",
- " result = app.invoke(langgraph_input)\n",
- " return result[\"generation\"]"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "a71d3943-faf8-4f74-9f9d-a8f914db2acb",
- "metadata": {},
- "source": [
- "The above Pathway endpoint,\n",
- "* Takes a `user_query` as the JSON input.\n",
- "* Passes it into the compiled LangGraph pipeline.\n",
- "* Returns the final answer from the state (result[\"generation\"])"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "6e86ac7c-db40-4636-b704-77df7c0d18a6",
- "metadata": {},
- "source": [
- "# Build and Run the Pathway server"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "963e891e-4ccf-4186-a3f2-19997b44bb86",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# This creates and runs the index, also serves the agent endpoint defined above\n",
- "\n",
- "rag_app.build_server(pathway_host, pathway_port)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "065f68f6-99b9-4d5e-8abf-796fdf67c050",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "t = rag_app.run_server(threaded=True)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "95b9772b-42ce-422f-bd40-56ba317a8249",
- "metadata": {},
- "source": [
- "List the indexed documents.\n",
- "\n",
- "This request may take a while since app is parsing the documents and building the index."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "8bc8ab3c-cfb6-41e6-a102-281caa1bb19e",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "pathway_client = RAGClient(pathway_host, pathway_port)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "aebfab0c-c827-4a47-a5b4-36361c2c68c1",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "pathway_client.list_documents()"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "1e682805-8d61-4054-aab0-47044d921157",
- "metadata": {},
- "source": [
- "# Run with a sample question\n",
- "\n",
- "Test the `/agent` endpoint by sending a sample question. The server runs the entire RAG pipeline and returns the answer."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "4676f4c8-26bd-4f36-aadf-80771b001b59",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "question: str = (\n",
- " \"How does self-RAG work? Explain the steps involved in the implementation.\"\n",
- ")"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "b84144d8-e266-4a13-a515-a55fcdc02f11",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import requests\n",
- "\n",
- "# send request to the endpoint we defined above, put the expected fields as payload\n",
- "response = requests.post(\n",
- " pathway_client.url + \"/agent\",\n",
- " json={\"user_query\": question},\n",
- ")"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "a5689309-1780-4725-8d3f-364841303def",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "response.json()"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "35051a4c-1c70-4631-9005-5a06520640e1",
- "metadata": {
- "tags": []
- },
- "source": [
- "## Summary\n",
- "\n",
- "1. **Data Ingestion:** Ingest a webpage (the Self-RAG arxiv page).\n",
- "2. **Indexing:** Pathway reads these text documents, parses, splits, and indexes them using a hybrid BM25 + semantic index.\n",
- "3. **LangGraph Agent:** Define a multi-step agent that:\n",
- " * Re-writes the query if needed.\n",
- " * Retrieves documents via the Pathway VectorStore.\n",
- " * Grades those docs for relevance.\n",
- " * Generates an answer.\n",
- " * Grades that answer for hallucination and for how well it addresses the user’s question.\n",
- " * Loops as necessary until it gets a satisfactory final response.\n",
- "4. **Serving:** Pathway’s built-in server is launched, hosting an `/agent` endpoint for queries.\n",
- "\n",
- "\n",
- "Thus, whenever you POST a `\"user_query\"` to the `/agent` endpoint, the agent pipeline runs, and returns the final answer."
- ]
- }
- ],
- "metadata": {
- "kernelspec": {
- "display_name": "Python 3 (ipykernel)",
- "language": "python",
- "name": "python3"
- },
- "language_info": {
- "codemirror_mode": {
- "name": "ipython",
- "version": 3
- },
- "file_extension": ".py",
- "mimetype": "text/x-python",
- "name": "python",
- "nbconvert_exporter": "python",
- "pygments_lexer": "ipython3",
- "version": "3.11.11"
- }
- },
- "nbformat": 4,
- "nbformat_minor": 5
-}
diff --git a/cookbooks/self-rag-agents/pathway_langgraph_agentic_rag.ipynb b/cookbooks/self-rag-agents/pathway_langgraph_agentic_rag.ipynb
deleted file mode 100644
index 03c947b7..00000000
--- a/cookbooks/self-rag-agents/pathway_langgraph_agentic_rag.ipynb
+++ /dev/null
@@ -1,942 +0,0 @@
-{
- "cells": [
- {
- "cell_type": "markdown",
- "id": "09287484-c402-4d09-a26b-588a13a331f0",
- "metadata": {
- "tags": []
- },
- "source": [
- "> The following cookbook is an adaption of the original [LangGraph cookbook](https://github.com/langchain-ai/langgraph/blob/e3ca7bb3e9d34b09633852f4d08d55f6dcd4364b/examples/rag/langgraph_self_rag.ipynb)\n",
- "\n"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "9b009d03-9465-4b1a-b64d-50a05c0dfbc5",
- "metadata": {},
- "source": [
- "# LangGraph Agents Powered by Pathway: A Complete Guide\n",
- "\n",
- "This notebook demonstrates how to use Pathway VectorStore as a LangChain Retriever to power LangGraph Agents that are synced with your documents.\n",
- "\n",
- "In this notebook, you will learn:\n",
- "- How to build a Pathway vector store that indexes documents from your data sources\n",
- "- How to create a vector index that enables semantic search through your documents\n",
- "- How to use the Pathway LangChain Retriever in a LangGraph Agent"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "f42f3015-33e6-48f4-827a-1e44541507cd",
- "metadata": {},
- "source": [
- "Magic library is used for detecting file types in the `UnstructuredParser` module.\n",
- "\n",
- "If you are running this notebook on **MacOS**, you can install it with:\n",
- "> `brew install libmagic`\n",
- "\n",
- "If you are running the notebook on **colab** or any **linux** environment, you can install it with:\n",
- "> `apt-get install libmagic1`"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "727099e5-e1d8-4f20-8240-d74ec1299ddf",
- "metadata": {},
- "source": [
- "# Setup\n",
- "\n",
- "Install the required packages and set your OpenAI API key. \n",
- "OpenAI is used for embeddings during the indexing stage and to power the LangGraph agent."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "7bdea4ea-882e-4043-8cda-4671690b33a1",
- "metadata": {},
- "outputs": [],
- "source": [
- "!pip install -U \"pathway[all]\""
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "88ec0f0e-7fa2-457f-a3d7-49a158653e24",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "!pip install -U langgraph langchain-community langchainhub langchain-openai"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "3ff9da9f-66b8-4675-8c45-afa10e891462",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import os\n",
- "\n",
- "import json\n",
- "from typing import Iterable, Literal, List\n",
- "from pydantic import BaseModel, Field\n",
- "\n",
- "# needed for the OpenAI embedder and the LLM we will use below, you can change the embedding provider, see the documentation:\n",
- "# https://pathway.com/developers/api-docs/pathway-xpacks-llm/embedders\n",
- "os.environ[\"OPENAI_API_KEY\"] = \"sk-...\""
- ]
- },
- {
- "cell_type": "markdown",
- "id": "5b04f68d-2ca4-43e5-9c8d-c8392dd65edb",
- "metadata": {},
- "source": [
- "Lets define a `DATA_PATH` folder that will store the text files/documents for indexing."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "54979252-13d3-4b94-b2ad-ec7b012aa320",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# folder that we will gather our docs in\n",
- "DATA_PATH = \"./data\"\n",
- "\n",
- "os.makedirs(DATA_PATH, exist_ok=True)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "8169934b-9a2c-433e-b034-8a97ead8d25b",
- "metadata": {},
- "source": [
- "## Load & save a webpage\n",
- "\n",
- "Define utility functions to read content from a webpage and save it locally into `DATA_PATH`.\n",
- " 1. `load_page_content`: Reads the raw text from a webpage using using a `WebBaseLoader` from `langchain_community.document_loaders`.\n",
- " 2. `ingest_webpage`: Saves the loaded content as a text file into the `DATA_PATH`. "
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "64538684-5b2b-460a-b3a5-1fe737fd8269",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import re\n",
- "from urllib.parse import urlparse\n",
- "from langchain_community.document_loaders import WebBaseLoader\n",
- "\n",
- "\n",
- "def load_page_content(url: str) -> str:\n",
- " \"\"\"Load web page content with Langchain utilities.\"\"\"\n",
- " return WebBaseLoader(url).load()[0].page_content\n",
- "\n",
- "\n",
- "def ingest_webpage(url: str) -> None:\n",
- " \"\"\"Save a webpage to local `DATA_PATH` folder.\"\"\"\n",
- " text_content = load_page_content(url)\n",
- "\n",
- " parsed_url = urlparse(url)\n",
- " file_name = parsed_url.hostname + parsed_url.path.replace(\"/\", \"_\") + \".txt\"\n",
- "\n",
- " with open(os.path.join(DATA_PATH, file_name), \"w\", encoding=\"utf-8\") as f:\n",
- " f.write(text_content)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "5bf15463-7da1-4d04-9f6d-423975e377cb",
- "metadata": {
- "tags": []
- },
- "source": [
- "Download the Self-RAG paper"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "fff7b382-2e25-415b-a3ee-06df976b3dbd",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "ingest_webpage(\"https://arxiv.org/html/2310.11511\")"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "f7e2f21e-2259-49f8-b295-0f442e35c337",
- "metadata": {
- "tags": []
- },
- "source": [
- "# Build the Pathway indexing pipeline\n",
- "\n",
- "Set up Pathway to read and index the documents saved under the `DATA_PATH`.\n",
- "\n",
- "\n",
- "1. [Connectors](https://pathway.com/developers/user-guide/connect/pathway-connectors): Use Pathway’s file reader to ingest all text files under the `DATA_PATH`.\n",
- "2. [Parsers](https://pathway.com/developers/api-docs/pathway-xpacks-llm/parsers): Utilize the UnstructuredParser to parse the documents. This parser supports multiple file types, including PDF, DOCX, and PPTX.\n",
- "3. [Text Splitters](https://pathway.com/developers/api-docs/pathway-xpacks-llm/splitters): Split the document content into chunks.\n",
- "4. [Embedders](https://pathway.com/developers/api-docs/pathway-xpacks-llm/embedders): Use OpenAI API for embeddings.\n",
- "5. [VectorStore](https://pathway.com/developers/api-docs/pathway-xpacks-llm/vectorstore): Orchestrates all the above modules."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "27c3d42a-30e1-47f8-bf3c-bd44d4a490f0",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# host and port of the RAG app\n",
- "pathway_host: str = \"0.0.0.0\"\n",
- "pathway_port: int = 8000"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "3c68a48a-8263-4b52-8c5a-206baefd22d1",
- "metadata": {},
- "source": [
- "Create the vector store that will power the index of our RAG application. \n",
- "\n",
- "We use the modules under the Pathway Xpacks to create a suitable vector store."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "094ec4e1-e972-441b-9c47-ff0ce3c8d2ff",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "import pathway as pw\n",
- "\n",
- "from pathway.xpacks.llm.vector_store import VectorStoreServer, VectorStoreClient\n",
- "from pathway.xpacks.llm import (\n",
- " embedders,\n",
- " llms,\n",
- " parsers,\n",
- " splitters,\n",
- ")\n",
- "from pathway.udfs import DiskCache\n",
- "\n",
- "# read the text files under the data folder, we can also read from Google Drive, Sharepoint, etc.\n",
- "# See connectors documentation: https://pathway.com/developers/user-guide/connect/pathway-connectors to learn more\n",
- "folder = pw.io.fs.read(\n",
- " path=f\"{DATA_PATH}/*.txt\",\n",
- " format=\"binary\",\n",
- " with_metadata=True,\n",
- ")\n",
- "\n",
- "# list of data sources to be indexed\n",
- "sources = [folder]\n",
- "\n",
- "# define the document processing steps\n",
- "parser = parsers.UnstructuredParser()\n",
- "\n",
- "text_splitter = splitters.TokenCountSplitter(min_tokens=150, max_tokens=450)\n",
- "\n",
- "embedder = embedders.OpenAIEmbedder(cache_strategy=DiskCache())\n",
- "\n",
- "vector_server = VectorStoreServer(\n",
- " *sources,\n",
- " embedder=embedder,\n",
- " splitter=text_splitter,\n",
- " parser=parser,\n",
- ")\n",
- "\n",
- "# deploy the vector store locally\n",
- "t = vector_server.run_server(pathway_host, pathway_port, threaded=True)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "34cc8823-e184-47c0-aa09-7b4035817e7d",
- "metadata": {},
- "source": [
- "[VectorStore](https://pathway.com/developers/api-docs/pathway-xpacks-llm/vectorstore) manages document ingestion, parsing, splitting, and indexing."
- ]
- },
- {
- "cell_type": "markdown",
- "id": "b2742133-a7ef-49a8-82d1-093c2d2ff2d2",
- "metadata": {},
- "source": [
- "List the indexed documents"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "8bc8ab3c-cfb6-41e6-a102-281caa1bb19e",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "pathway_client = VectorStoreClient(pathway_host, pathway_port)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "aebfab0c-c827-4a47-a5b4-36361c2c68c1",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "pathway_client.get_input_files()"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "ba734b24-63bd-4b22-a3cb-fed2393a60f4",
- "metadata": {},
- "source": [
- "# Create the LangGraph agent"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "cf15141f-9612-4d0d-a21b-11bd8530686a",
- "metadata": {},
- "source": [
- "### Create the Langchain Retriever\n",
- "\n",
- "You can now query Pathway and access up-to-date documents for your RAG applications from LangChain using [PathwayVectorClient](https://api.python.langchain.com/en/latest/vectorstores/langchain_community.vectorstores.pathway.PathwayVectorClient.html)\n",
- "\n",
- "The Langchain Retriever is a wrapper around the Pathway client, you will use it in `retrieve` part stage of the Agent"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "fefffab6-d5a3-4925-a52d-5a5c574421ea",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langchain_community.vectorstores import PathwayVectorClient"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "51d365aa-5526-4ec8-932d-e65e83ee355d",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "vectorstore_client = PathwayVectorClient(pathway_host, pathway_port)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "59624377-8481-4407-8ee3-0f014bdff30e",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "retriever = vectorstore_client.as_retriever()"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "4623f53b-013b-4bc5-8c7c-e994a2e35c57",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "# test the retriever\n",
- "# retriever.invoke({\"question\": \"evaluation\"})"
- ]
- },
- {
- "attachments": {
- "76895b7a-fcc5-4758-9fbb-510b17fdeda4.png": {
- "image/png": "iVBORw0KGgoAAAANSUhEUgAABsYAAAKICAIAAABMgdh8AAAAAXNSR0IArs4c6QAAAERlWElmTU0AKgAAAAgAAYdpAAQAAAABAAAAGgAAAAAAA6ABAAMAAAABAAEAAKACAAQAAAABAAAGxqADAAQAAAABAAACiAAAAADBOIDEAABAAElEQVR4Aey9B5xV1bm4DQxTmBlgBhiK9CYgKNJVlKLYwF6iRsUbY9TE/BNjYnI/Y270Jrm5JiYmanI1aoottoi9g2CHoGIBlN57G2aGqcD3DAu3xxkY5kxjYJ79m9/JPnuvvcqz9znxPLzvWo137tzZyE0CEpCABCQgAQlIQAISkIAEJCABCUhAAhKQQOUINKlcMUtJQAISkIAEJCABCUhAAhKQgAQkIAEJSEACEigloFL0OZCABCQgAQlIQAISkIAEJCABCUhAAhKQgATiIKBSjAOWRSUgAQlIQAISkIAEJCABCUhAAhKQgAQkIAGVos+ABCQgAQlIQAISkIAEJCABCUhAAhKQgAQkEAcBlWIcsCwqAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJqBR9BiQgAQlIQAISkIAEJCABCUhAAhKQgAQkIIE4CKgU44BlUQlIQAISkIAEJCABCUhAAhKQgAQkIAEJSECl6DMgAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJxEFApRgHLItKQAISkIAEJCABCUhAAhKQgAQkIAEJSEACKkWfAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJSCAOAirFOGBZVAISkIAEJCABCUhAAhKQgAQkIAEJSEACElAp+gxIQAISkIAEJCABCUhAAhKQgAQkIAEJSEACcRBQKcYBy6ISkIAEJCABCUhAAhKQgAQkIAEJSEACEpCAStFnQAISkIAEJCABCUhAAhKQgAQkIAEJSEACEoiDgEoxDlgWlYAEJCABCUhAAhKQgAQkIAEJSEACEpCABFSKPgMSkIAEJCABCUhAAhKQgAQkIAEJSEACEpBAHARUinHAsqgEJCABCUhAAhKQgAQkIAEJSEACEpCABCSgUvQZkIAEJCABCUhAAhKQgAQkIAEJSEACEpCABOIgoFKMA5ZFJSABCUhAAhKQgAQkIAEJSEACEpCABCQgAZWiz4AEJCABCUhAAhKQgAQkIAEJSEACEpCABCQQBwGVYhywLCoBCUhAAhKQgAQkIAEJSEACEpCABCQgAQmoFH0GJCABCUhAAhKQgAQkIAEJSEACEpCABCQggTgIqBTjgGVRCUhAAhKQgAQkIAEJSEACEpCABCQgAQlIQKXoMyABCUhAAhKQgAQkIAEJSEACEpCABCQgAQnEQUClGAcsi0pAAhKQgAQkIAEJSEACEpCABCQgAQlIQAIqRZ8BCUhAAhKQgAQkIAEJSEACEpCABCQgAQlIIA4CKsU4YFlUAhKQgAQkIAEJSEACEpCABCQgAQlIQAISUCn6DEhAAhKQgAQkIAEJSEACEpCABCQgAQlIQAJxEFApxgHLohKQgAQkIAEJSEACEpCABCQgAQlIQAISkIBK0WdAAhKQgAQkIAEJSEACEpCABCQgAQlIQAISiIOASjEOWBaVgAQkIAEJSEACEpCABCQgAQlIQAISkIAEVIo+AxKQgAQkIAEJSEACEpCABCQgAQlIQAISkEAcBFSKccCyqAQkIAEJSEACEpCABCQgAQlIQAISkIAEJKBS9BmQgAQkIAEJSEACEpCABCQgAQlIQAISkIAE4iCgUowDlkUlIAEJSEACEpCABCQgAQlIQAISkIAEJCABlaLPgAQkIAEJSEACEpCABCQgAQlIQAISkIAEJBAHAZViHLAsKgEJSEACEpCABCQgAQlIQAISkIAEJCABCagUfQYkIAEJSEACEpCABCQgAQlIQAISkIAEJCCBOAioFOOAZVEJSEACEpCABCQgAQlIQAISkIAEJCABCUhApegzIAEJSEACEpCABCQgAQlIQAISkIAEJCABCcRBQKUYByyLSkACEpCABCQgAQlIQAISkIAEJCABCUhAAipFnwEJSEACEpCABCQgAQlIQAISkIAEJCABCUggDgIqxThgWVQCEpCABCQgAQlIQAISkIAEJCABCUhAAhJQKfoMSEACEpCABCQgAQlIQAISkIAEJCABCUhAAnEQUCnGAcuiEpCABCQgAQlIQAISkIAEJCABCUhAAhKQgErRZ0ACEpCABCQgAQlIQAISkIAEJCABCUhAAhKIg4BKMQ5YFpWABCQgAQlIQAISkIAEJCABCUhAAhKQgARUij4DEpCABCQgAQlIQAISkIAEJCABCUhAAhKQQBwEVIpxwLKoBCQgAQlIQAISkIAEJCABCUhAAhKQgAQkoFL0GZCABCQgAQlIQAISkIAEJCABCUhAAhKQgATiIKBSjAOWRSUgAQlIQAISkIAEJCABCUhAAhKQgAQkIAGVos+ABCQgAQlIQAISkIAEJCABCUhAAhKQgAQkEAcBlWIcsCwqAQlIQAISkIAEJCABCUhAAhKQgAQkIAEJqBR9BiQgAQlIQAISkIAEJCABCUhAAhKQgAQkIIE4CKgU44BlUQlIQAISkIAEJCABCUhAAhKQgAQkIAEJSKCpCCQgAQlIQAISkIAEJCABCUhAAhKQgAQkcMAR2LZtW1FRUUpKSnJycuPGjQ+4/h/QHVYpHtC3z85LQAISkIAEJCABCUhAAhKQgAQkIIGGSGDjxo3vvvvu0qVLe/fuPXTo0FatWjVECvtvzCrF/cfeliUgAQlIQAISkIAEJCABCUhAAhKQgASqRODhhx++//77161bl5aW9utf//r0009v0sT5/aqEskoXybpK2LxIAhKQgAQkIAEJSEACEpCABCQgAQlIYD8RKCwsfPPNN/GJtJ+Xl5ednU0G9H7qSwNtVqXYQG+8w5aABCQgAQlIQAISkIAEJCABCUhAAgcogfnz5+fm5kadZzrFxMTE6K07dUDAxOc6gGwTEpCABCQgAQlIQAISkIAEJCABCdQuge3bt5eUlLBGR9OmTcsnwHKWbefOnYin8mdrt2f1tfYdu7aEhIQDcWGTDz74YPPmzQEt/U9KSmIg9ZX0wdkvleLBeV8dlQQkIAEJSEACEpCABCQgAQlIoOEQKC4unjdv3pQpU1BLo0eP7tu3b5mxf/rppzNmzCBbdsKECV26dFE/YVfnzp27du3aI488snnz5kEsHihukdv99ttvszxLuMsZGRlEKZa5476tbQIqxdombP0SkIAEJCABCUhAAhKQgAQkIAEJ1C4BjBgy8a9//WtOTg7xa3fddVesHSM+8Te/+Q1K8ZBDDjnhhBOMUuRmrF69+rHHHmOFEwTrMbu2wYMHZ2VlwS0WXe3etqrW/s4773z++ecI4lBBenp6cnJyVSvzuioSSLjpppuqeKmXSUACEpCABCQgAQlIQAISkIAEJCCBekAAC0ZGM69vvfUWsoxAxXbt2kX9Yh2Phx56CNv4ve99b8SIEUa0QYbIxM6dO7du3Xr9+vVvvPHGU0899fTTTwdP17JlSyRdRK++7ZDejiD+5JNP2Al9a9++/fHHH48brW9dPbj7o1I8uO+vo5OABCQgAQlIQAISkIAEJCABCTQIAkQpohHxYtu2bcMennrqqWHYZPj+13/918KFC3v27HnNNdd06NCh/kfh1c0Ny8zMJDJx/Pjxo0aNatWqFasnk0386quvohfJiQYjCcWYx7rpTOVbeeKJJ+hhNJEiFyITx4wZ07Fjx8pXYsnqEzDxufoMrUECEpCABCQgAQlIQAISkIAEJCCB/UwAUdi2bdsrr7zylltuee2115hasXfv3hx87733mEixqKjo0ksvxTnG+sTFixcT1Thr1ixm5SNeb8iQIccddxyxe7EjIRRu+fLl7777LmFxmzZt2rp1K44S14bGmjhxYqdOnWILH1j7oCC0k23QoEEDBgxgODNnziRikQzxZ5555sUXX8Q5YhvZRo4cSehifRjdypUrSW9fs2ZNbGeaNWvGKGKPVHOftaRx0EuXLuUJIWueu4yyDFnh1az5YLpcpXgw3U3HIgEJSEACEpCABCQgAQlIQAISaLgEUlNTzzjjjAceeIBVR+65557//d//ZY7FMMFi//79UWOx+bwvv/zy3XffTaova32w9DETLL700ktYRaTkscceGyASqffcc8/dfvvtxMThFsMSyZyiMErx4osvPjhYQ4mN+M1TTjmFDGIEK+GKyNZ///vfTz755AsvvEBmMbnkYMEtsqD2/ho1/O+8804MLzuxfYjVxLHH49rHFGdnZ5MjP3nyZOZqZKLG0jXCt2+nEm43Vvrb3/42iOKqc4+FsdsfffTRs88+y/yPP/nJT8rwZGhbtmzJy8tr06YNGfoVDG3JkiX0lqoIL+Uqynfr1o0HmMjTtLS0PTZdswf323NQs8OwNglIQAISkIAEJCABCUhAAhKQgAQaOAH8C2Llm9/85i9+8QtU4FVXXYWdIfIOaUgIHjGMkaAhBg3ziI5B6yDLcDFENRKuSDQiIWldu3YNsYrvv/8+xYiMw0Viavr164e1xD2hF7mQtg4m4MAheZyNMZ599tnoRaZZRFqhF4lbZDLKf/3rXySPs5TL0Ucfjbqq2cDAypBE9k2bNg3dRuFzzjknPz9/+vTphI6i/KI7u8d6uF+LFi0iXpUnoVevXrhRFGooyd1EHPOQTJ06lcDMgoICquW1TD3Lli3jeJmDGzZsWLBgQYsWLXr06FHJCTqpmYZ++tOf0ijBlRdccAH9CdVSP54RA85DiyJEC7IY964g0VGE0JZpmjWIkObcGgQl3pNRMCLs5P33389T+p3vfIfbVDGTMhVW4a1KsQrQvEQCEpCABCQgAQlIQAISkIAEJCCB+kgA0zdhwgTECg4IG0iGLPMqDhw4EIuEwYl6jHD87LPPME3XXXfdmWeeiTFE8bBO9KOPPkpo3lFHHYVSRNMgE5lVkJzfs8466+qrr6Zy7BWVcApfg3qLKoxrh74hwuK6pGqFg2vjlY0a6DM7ZV5j34az0RGcKWIR5UqH8XH4uw8//BBujzzyCN5q+PDhuMXDDjsMLFXrXlxXYYFvvfVWbijwCRH92te+hu7kZlFJ6HaoDTGHaCOokLhU7iNzQXKXibgkvJEauJZVv1nA58ILLwzl0YIIaEaHqSTfeY9dQhei9phuMvbsK6+8wgOGicb9XXbZZeeff/4+nwf0HyrwxhtvpFGqgnO0iBCp+vfeey+CkhDREIPJWfpJHvppp532jW98A+sdtc7o/va3v73++uuxlhNbSgGGgP8lbpGnGo2O7oyuqvEdlWKNI7VCCUhAAhKQgAQkIAEJSEACEpCABPYPAUQMIV2XX375z3/+c5J20UlsuBXsGKeiPhGQiNQj8BAvxrIenMIbDh06FGuGRly1ahUlOYiR4UIEzccff8xciqjJ6k+oh54jk5qGos7U9k7swKP9aCeMNPQhOhjthOMwxLix4a3YmFCSTHBiPB9++GFELcnmF110Ua3GbJKSfPPNNxNpGDKRr7jiCowhDEM/CdALzpTeYuUmTZqEQyRykORl/DKhpn/5y1+44/ScAijmxx9/HBN6xBFHoOQQcKxIg1AOIw2vqFImTyQkE43IAIn+w/3FrlRDVRg9OkATNI13RgVWrBSxmTxXf/zjH4n9pBU0JZN7hgxlOnzbbbdxNvQw9IHydI+NxxgNet5554VYRbpKKjoBm5wKJVG6IaOfoWEt2ZCnf//73+fPn3/99dfX3nSfKsXA31cJSEACEpCABCQgAQlIQAISkIAEDgYCJOSGQEUMFF5m2LBhJIHGRtIRycWGnOIVX0Miahg2k9NhyhBnKDMixVBFSKURI0awvvDs2bNvuukmDCOzCuKbmHAwyleNFxlyioRWhCatswBImZVG4q1tf5VHpbGFWEtydYn6JITw8MMPr43+cC/uuOMOzCCyjPoJMBw7diwSDZNYXiliPwFL7jBsifLDMHKLuTaydRRg0RViDFGK7MM/1idS4c9+9jPqx99h/ZCJUYp07NB4SGgCAhykezwwNBpboPw+zvGxxx4jzJNTZJczKyUZ+uw///zzoENk86zylueKyFBGh68kBpNqqZwdwmyDUpwzZw6Cmw5QGA9OYUJoUZ9cThNkcDM0HlcCIbGlPNuXXHIJJWtjUynWBlXrlIAEJCABCUhAAhKQgAQkIAEJSGD/EMAKYVgwKSS04lkIoONtcE+hQ5ipkFuKdWIhl8gZYZ2I/OJUOEthsk2/9a1vkQSNpmEhFypBUZF2yqR7J598Mqeiays/VOQmxhP7g6nEYFb+wnhL0jeMWJkt9mAskwoqpxiWFr9GvB6dR8DReSI3kVYBFNoLR4aeq6CS6pyCNpMMBomGB+SGErWH8I1uE4OKxkI/6QzN0R+ykrGKrLpTZm5EbCCSjgopTIVIXh6D0EMeGEIveUKYq5GwxCj4sUz/OR61yCmwsJUpE/uW+EGiGkmrx0LSWyIof/jDHxLXSRY5iwhFPpFsZUIXeeq4azxgRNqSkU1nGAjMQ4WIQqxi2MdLkhPNyuaU5wgPMAnprFoepr+EAAOM7UbN7qsUa5antUlAAhKQgAQkIAEJSEACEpCABCSwnwmge/r27RukD2FfQbhEfSIELBxBNZ5wwgnlM0NJiA7X4on69OmDcjrppJOQU+STku2L0+EVszZo0CBiGKNqK7+TmZlJZBnmKOTA7vNCBBZSD1PGa9jCfplxlamHIYQt+C/2o52wX6Z8BW8RbYRwEutH+vCKFSswdKgxDg4YMAACBIFCErFVQQ1VPoXD/cMf/oDBpDkcHAuPcEfCwPG/wWPSGWwaBRgXO+EgxpDsYNpFIPLK84Ckw80hKAlQxYdyNwmrxMERlkgqOqdCJ2mRmQqRyFjF8ePHl/HRoQw5zkFchrc8IWTE0w28M3GCcCaUlX6GszhBHhiSr8MUihkZGczgyVmOs8QKifChGLGrTMiI4uSpoyoeMyIow1hC8jXFGDL+MZhogPP0xj7ePBtEMhK6yKN16qmnMsxazUZXKYYb56sEJCABCUhAAhKQgAQkIAEJSEACBw8B9EoYTHnvhgxi/kSsEDP0sbgz8iVMaRcNHoODnApvqQdbhJrBPTHZImuV4KTIw8UG4o+qphSpmchH6sR/RY1WvENoG6KqzBZ1suJrq3wWSUd4HY6MmD7WwsaIESuHS8WgoRERr6z7TMAgfCLaVW5rjxfS+i233IL7CwGJrJCDqsOUQZ7kZZKIQ+giwo60dGQcC1VzJMQkIuOiyD7u3ZVXXknuMOF7rBnNENB5CDsu4daTxs5q4CQgE0UYriVokY1bzDSLhJRi7hCLwI86yUMVwcff4QeJB2SKQ2YwpFpOkXR/zTXXACr09u6778ZUcjn1YEUJJGQfqqzKEtWJW0Se8kDiHEPKNlG0YeD0H8iUBAgxoeEga9RgFcuTp2+IRbao5lraUSnWElirlYAEJCABCUhAAhKQgAQkIAEJSKCeEsAiEXCHq0ID4Z5QY4ghTCLKBnkXLcRBcByLZqB4CGzE3aCHmNgOW8So0EblbU7lR4ufKuMxK39tHZQkSg44hCXiE0nOhQPTJqJiiaQjNhOfGEwiAXGxoq1mO0Yf/vSnP7GsM9hDzQg4EoG5X2GGQeL1MIOcom9sODsSihG1ZdKc8W5kwY8bN46pMClAuCLLLiNzQ6wf95EbgSxmRLyyrgutUBs6dfny5dx9vB6p01hFnhkUIY9H6AwXhh3UHoYa3worHqrg+9ghPRkPyBop+ETsIcfBReQjGzqbIeAfeZxCJdEomAYRzkQjhrhLjlM5czvyyj4yFCzhEh5XtrC/X15VivsFu41KQAISkIAEJCABCUhAAhKQgAQksN8IMAkdXgmpxMSIxKO9/PLLeEPCu1BUBB4ifRBMmCxMEGuPEICGPcSdcYTARpQiJYOB2m8DqJ2GsXXYQ4L+MGLw2RWrt5aDrI9M6jcxfeyg1VijpvZMYhgZQu2JJ55gaWbkWjTWIOaQfdGRaIf8X6wfTpD8ZbxbdBypR74zgaj4RA5ylzGMDC1EKUbFEIXEjTI0UqEZKeufvPHGG6zxzdjJ+MYtIlh5SHgwEIuYwejCUCepyqhPdGTwiRwkQJLnBA943333sUYKo0BcEuLK4uMEKvIgEZOIHg31MIUiZ6kflUlJtqh+4h/xoThcLCQHsaXBorKP04y0ZlS+LndUinVJ27YkIAEJSEACEpCABCQgAQlIQAISqFMCe5RfzGb49a9/vUOHDmQxz507l2C0qE+4G4LCMIaEg+GSCD2LToUdIhbxSmeccQaBjWVOHbhvCZcjqg6ZyEZOMdm7ZBAT0EeiMa8k3qLb2ILYqu1hYs2YyvDee+8Nkw9GzUXhitw+ohFJTKbbWDycL3NTnnfeeQhEZGjIhuYqTB/9R9hFWcD0Pwr3I/oyqjnsEB7YvXt3buvAgQORzgRpTpkyBb3Ik0CsIhtYaJFUaFqPrkVxIgdZfSWaFZFT9JxVsEnNRjUS+koPiYS94ooryGvmLKYS9UmgYqiEJVZwnaFF4GN16Tm52PhEwkLZGG8oiWmNILDPFo7vl1eV4n7BbqMSkIAEJCABCUhAAhKQgAQkIAEJ1BYBorcQQ6yli+5BDu7RKhLXRrwYUWnkz7KCRwgNI5OU46hGekZkInPecYSot+BuOIKTIt6tZ8+eFKtO4nNtjTz+eomnQ8OxGAgGDRT4LzJ5ifhDIyITQYFJrMscbW4E0xoSHBoSzBkQpg/U3NBwa+gPRo/kdKZ3ZNVsQimxbAg4DhI9SuRplE1M/9F/3KyICgMJSjH4Yu47Lg/BRxDi9OnT+/fvj0ykEtQk26GHHooHDGKRiEUiBPGA//jHPygQ5t8M66jgDbGxzH5IPVFDFOYSrCUPD50HJj6Rhy0UoMPY6qgw6dhEPoIde4iL5BbQBAMkGpTusR+V5DmMlCLmNJKSUYG63PmyW3XZqm1JQAISkIAEJCABCUhAAhKQgAQkIIFaIoBSRAl97Wtfq7h+lOJRRx2FdkQwhXxS7BVbUJCYIPJ88UqcDR6H9FjOcnz/JpxWPKjKn0XGkQKMTOSV+DvkKUqLIZPgzCrY+Ky6NImh29hALOEDDzwQ1l+G86WXXoqPgznSMCg2LBt3IdwCcooZBaKN/mPiuKEovDCXIpKOuD/S2KPZD2mCaEEqIegP84hPJECVMEbKE1FIu+Q+85aAR4ZP/RTjckIFmT4Sfcm0myRBIx9ZxYWngrbgw7PBEtgRc47QXHCa9IqNZwkZevnll1NzpLZ55CIzyLWsNoO75ELaZYtqK79DSCZbOE6WdLT+TPmSdXBEpVgHkG1CAhKQgAQkIAEJSEACEpCABCQggXpKAHmEaWIr3z9OIbPYyp86CI4QXnfnnXcS7IbzIh4TmUigHEoLZ7dfRkfMHQuh/O1vfwvxiSg2fOI3v/lNTF8QiGV6Rc+jwECUItNcovnwocyWyBSZAwYMYO7CKGU4XIvUQyky5SJLORMOSTFMX0hDJm2ZyEHiCoPgI6KQcFSeCpomb5qEZaIFg85DRBKTyBG0NV4v6hXq88QTTyQd+9lnn43iBwmKZDJEoj7RoFFJhkY3ordEPhKoSCt7HGZUjB36H5VBoUbxmLFl6mxfpVhnqG1IAhKQgAQkIAEJSEACEpCABCQgAQnUFwKk1pLni7AbPnw4cwji4/ZjzwjcQ8YFn4g1I8aQuRFJFg5J6HvsGGGGBAmGU0QdhlVZiCtE5zEBIt4Qq1j+QlzeaaedRlYyLYaFVlDGhCJiMzlC3B9CkGRnkqwJOSS1mRpohXxknGMILdwVKbgDdDhEJlgkyJFivL3ggguQmMhNjOHbb79NbcjNMWPGhCzp2J7QIgGhSEku5zjzMKIUWbmF3O3IGMaWp10EIuOiTkQnlxP/iPktI0xjL6mDfZViHUC2CQlIQAISkIAEJCABCUhAAhKQgAQkUL8IYMGIT2S1mWDW9m/nsGYsS8KkhAQDIvhOP/30sNxKBb1ikkQ0KEvrRLnAFMayscQzQZcIQYZW/nIOsoDy//t//w9RSIgiBQhFHD9+PPWwykqY4pB9tvLXhiPDhg0jnJONJXroLZnX7BOfyHEqpwOkObOP/kMUkiJNRnmZqnCOkGeBoF//+tecItzyoYceIuCRnqMpGRQFuBxJSjgkKpM0cHYoxnEcK/3HRZKzT2BpmZrr8m1juliX7dmWBCQgAQlIQAISkIAEJCABCUhAAhKQgARiCaAU58+ff9ttt6EC0XME95U3cbHl2ce4Pfzww0QX4trOOeccVnZmvsUyZfb4FhUWLCSGLhTgLVMivvPOO8wsST44y9RE8Y9RDfSHrHASojGJwR4Sn4iCJECSyEdWAYpdRyW6am879AEXefPNNzNFY1QmTN2IUiQCkdGR10zMI/YQMiGTmg5ff/31zO1Ib1l8BqUYzc8YVVJnOyrFOkNtQxKQgAQkIAEJSEACEpCABCQgAQlIQAJ7JoDFY/ETYgYJ7ttziXJHyVMmhRmlyBSKzFpYTb+G5kMRYhWxeOg8NqZZJMuYvGZmQkTzEVo4ePBg7CEHy/Ul7gN4TMIP7733XiZ2ZCLI2Jg/ctJRiiHPOqoXn0gq93XXXYdvjQ7uxx2V4n6Eb9MSkIAEJCABCUhAAhKQgAQkIAEJSEAC9Y4Ai7cQfsiUhchE4hMRnexUU1nucZCkexNryaLbuFFmh4xN4g7lUZkkO7dr1w6VOXbsWCIZ60OiOn1TKe7xhnpQAhKQgAQkIAEJSEACEpCABCQggf1MgDAxhAsRW/iU/dwVm5dArREgFpK1p9944w2WuuaZJ+iS+EQMJjngPPxkW7PMCwGSLOfC2z2u31JrXauoYpViRXQ8JwEJSEACEpCABCQgAQlIQAISkEDdEyBAbPHixbNmzZo9e/aoUaOYJq/u+2CLEqhLAiQ+89izSAsbkpHQSCZVbN26dWpqam1ER1Z/aK74XH2G1iABCUhAAhKQgAQkIAEJSEACEpBADRAgz5SwRJaeYImMt956K6SCMoXc8OHDyf2sgQasQgL1lQDhhzhEtvrawbL9UimWJeJ7CUhAAhKQgAQkIAEJSEACEpCABOqYQJCJn3/++Xvvvffuu+8uWbIkpH/SDZawIFZRpVjHd8TmJFAxAZVixXw8KwEJSEACEpCABCQgAQlIQAISkEAtEkAmrl+/Hm9IWOLUqVNZ6LaoqIiIraZNmzKjHCtRMJGcPrEWb4BVS6BKBFSKVcLmRRKQgAQkIAEJSEACEpCABCQgAQlUm8Dq1avnz58/bddWUFDQpk2bAQMGrF27ltUqCgsLWaFi5MiRl156af/+/avdlBVIQAI1SUClWJM0rUsCEpCABCQgAQlIQAISkIAEJCCBfRLYsWPHhg0bUIfPPvvslClTsIfEIR5//PH9+vV74YUX5syZw7q3VNK9e/fTTjvtiCOO2GeFFpCABOqYgEqxjoHbnAQkIAEJSEACEpCABCQgAQlIoEETYFnbVatWPf/88y+99BI5zp07dz7llFMmTJiAZ7z99ts5uGXLFgCx4u24ceOOOuqoBg3LwUugvhJQKdbXO2O/JCABCUhAAhKQgAQkIAEJSEACBxeBnJycTZs2IROfe+45ohQ7dep0/vnnn3rqqRkZGXjG++67L/KJjJuIxREjRrRu3frgYuBoJHCQEFApHiQ30mFIQAISkIAEJCABCUhAAhKQgATqLQEWXcnOzn7llVfIdF64cCEO8ZJLLmGSxMzMTPqcm5v7yCOPPPXUU6zT0qRJk507d7I2y5FHHtmrV696OyI7JoEGTkCl2MAfAIcvAQlIQAISkIAEJCABCUhAAhKoLQLIQVKbkYlvv/32pEmT3n///bS0tLPPPnvixInkOyckJNAwq7IQtPjPf/6TbGiOUICpFbt163bMMcd07NixtnpmvRKQQPUIqBSrx8+rJSABCUhAAhKQgAQkIAEJSEACEtgTgZKSEmTizJkzn3766cmTJ6emprLWyrnnnjto0KDExMRwRXFx8RtvvPGXv/xl6dKl+MT27duTHM2FgwcP7tmz555q9ZgEJFAvCKgU68VtsBMSkIAEJCABCUhAAhKQgAQkIIGDiQDBiZ9++ulDDz2ETyTwcPz48WedddZxxx1HXnM0zO3bt3/wwQe33HILqdCNGzcmbpHgxPnz57do0YKSLPcclXRHAhKobwRUivXtjtgfCUhAAhKQgAQkIAEJSEACEpDAAU+A1Vf+8z//c/Xq1azafMEFF4wdO7bMkFjfec6cOZRZtGgRPrFt27ZMrTht2rR169bhHwlR5GCZS3wrAQnUHwIqxfpzL+yJBCQgAQlIQAISkIAEJCABCUjgICFApOHVV19NgvPpp59efkjMsbhkyZLvfve7vHI2PT39+9//flJSEsuzsM8sioYolofmEQnUKwIqxXp1O+yMBCQgAQlIQAISkIAEJCABCUjgYCCAGTznnHP2NhLU4WWXXbZs2TIKkAr9gx/8YMKECXfffffatWuHDh3av3//5OTkvV3rcQlIoD4QUCnWh7tgHyQgAQlIQAISkIAEJCABCUhAAg2FQF5eHrZxxYoVYcA/+tGPmGYRmfjvf/87Nzd3xIgRXbt2bSgsHKcEDlgCX86KesAOwY5LQAISkIAEJCABCUhAAhKQgAQkcGAQYEmWk08+GZ9I7jM9vvbaa88///xWrVqxMDRWcdiwYUOGDGnevPmBMRh7KYEGTECl2IBvvkOXgAQkIAEJSEACEpCABCQgAQnULYETTjhh5cqVwScy2eJFF12UlZXFUi0oRbKh8Yms++zCLHV7T2xNAlUhoFKsCjWvkYAEJCABCUhAAhKQgAQkIAEJSCBeAiQ4M38iApELmUtx4sSJLPSMQMQnzps3r1u3bkcddVTr1q3jrdbyEpBA3RNQKdY9c1uUgAQkIAEJSEACEpCABCQgAQk0LAJoxP/4j//49NNPSXxm5BdccMEVV1zRoUMH1mbh7XvvvUfWMyGKnTp1CkcaFh1HK4EDkIBK8QC8aXZZAhKQgAQkIAEJSEACEpCABCRw4BAoKipiTed33nmnuLiYXp955pnXXHNNZA83bNiAUkxISBg1atQhhxxy4AzLnkqgQRNwxecGffsdvAQkIAEJSEACEpCABCQgAQlIoFYJFBQU/PrXv37llVcKCwtpiLVZWJIl8okcmTFjxurVq4888kgSnxMTE2u1M1YuAQnUFAGVYk2RtB4JSEACEpCABCQgAQlIQAISkIAEvkJg27Ztd91115NPPskOJ4hD/PGPf9y1a1diEqNyRC/m5eUdd9xx5EFHB92RgATqOQGVYj2/QXZPAhKQgAQkIAEJSEACEpCABCRwQBJAIz788MMPPfTQ1q1bWYNl6NChN954Y48ePWJnS5w7d+5HH33Ut2/fgQMHpqenH5DjtNMSaJAEnEuxQd52By0BCUhAAhKQgAQkIAEJSEACEqhNAgQePvXUU/feey9TJeIQDz/88P/+7//u3bt3rE+k/c8++2zTpk0jR47s2LFjmVO12TvrloAEqkug8c6dO6tbh9dLQAISkIAEJCABCUhAAhKQgAQkIIEvCOATmTzxtttuW7p0KaKwT58+v/nNb7CKxCp+UWT3/zKL4rRp04YNG8ZEirHZ0GWK+VYCEqhvBFSK9e2O2B8JSEACEpCABCQgAQlIQAISkMABTIB8ZyzhrbfeumDBAnwimc633HILWc97GxJp0ampqU2bOjPb3gh5XAL1kYCf2Pp4V+yTBCQgAQlIQAISkIAEJCABCUjgQCSQn58/ffr0O+64I/jEzp07k+9cgU9kjC1atDgQR2qfJdDACTiXYgN/ABy+BCQgAQlIQAISkIAEJCABCUigZggUFhZ++OGHf/jDH2bPnk18Iis433zzzcyTWDO1W4sEJFCfCKgU69PdsC8SkIAEJCABCUhAAhKQgAQkIIEDk0BxcfEnn3yCT5w1axZzJmZlZf385z8fO3bsgTkaey0BCeyDgEpxH4A8LQEJSEACEpCABCQgAQlIQAISkEDFBHbs2DF37lx8IlnPlGzbtu2NN9548sknV3yVZyUggQOXgHMpHrj3zp5LQAISkIAEJCABCUhAAhKQgATqBYF58+bhE99880160759++uuu+6MM86oFz2zExKQQO0QMEqxdrhaqwQkIAEJSEACEpCABCQgAQlIoGEQ+Pzzz//4xz9OnjyZ4eITr7nmmnPPPbdhDN1RSqDhElApNtx778glIAEJSEACEpCABCQgAQlIQALVJEB84p/+9KcXX3yRevCJV1xxxfnnn9+0qTmR1eTq5RKo7wRUivX9Dtk/CUhAAhKQgAQkIAEJSEACEpBA/SSAT7z77ruff/75nTt34hMnTpx44YUXNmvWrH721l5JQAI1SEClWIMwrUoCEpCABCQgAQlIQAISkIAEJNBQCMyfP/++++579tlnS0pK8InIxIsuuqh58+YNZfyOUwINm4BKsWHff0cvAQlIQAISkIAEJCABCUhAAhKIn8DChQv//ve/P/PMM4WFhe3atWPyxK9//eutWrWKvyavkIAEDkgCKsUD8rbZaQlIQAISkIAEJCABCUhAAhKQwP4isHjx4vvvv//pp5/etm1bVlYWiztffPHFiMX91R/blYAE6p6ASrHumduiBCQgAQlIQAISkIAEJCABCUjgQCWwZMmSBx544KmnnsrJyWnTps2ECRMuueSSjh07Hqjjsd8SkECVCKgUq4TNiyQgAQlIQAISkIAEJCABCUhAAg2PwMqVKx955BF84pYtW0hzPuWUU/CJ3bp1a3gkHLEEGjoBlWJDfwIcvwQkIAEJSEACEpCABCQgAQlIoDIE1q9f/+STT5LvvHHjxoyMjBNPPBGf2Lt378pcaxkJSOAgI6BSPMhuqMORgAQkIAEJSEACEpCABCQgAQnUPIHs7OwXX3yR+MRVq1a1aNHi+OOPv/TSS/v161fzLVmjBCRwIBBoeiB00j5KQAISkIAEJCABCUhAAhKQgAQk8BUCJSUleXl5BQUFycnJ6enpTZvW4g98lmGZOnXqY489tmDBAtoaPXr0xIkTDz/88K90yDcSkEBDIlCL3zgNCaNjlYAEJCABCUhAAhKQgAQkIAEJ1BGBHTt2bN68Gbs3e/bsDRs2sEbKgAEDSEBu2bJlkyY1n4yIu5w5c+aDDz74ySefpKamHnvssfjEQYMG1dFobUYCEqiXBFSK9fK22CkJSEACEpCABCQgAQlIQAISkMCeCBQVFS1btuyll15iWsOFCxeGIn369DnvvPPGjh3btWvXpKSkPV1X9WNz58695557ZsyY0axZs6OPPvob3/jG8OHDq16dV0pAAgcFgcY7d+48KAbiICQgAQlIQAISkIAEJCABCUhAAgc5ATKd58yZ89e//nXatGlNGzdu3bJlUmJiQWHhpq1btzdqdNxxx1111VXkIycmJtYUCJZ4/vnPf/7qq6+SXo1JvPrqq4lSrKnKrUcCEjhwCRileODeO3suAQlIQAISkIAEJCABCUhAAg2IQH5+PhMa3nfffXPnzGndssUpRx9z7vFjO2ZlzVu2/Olp016bMYOzTK147bXXkgddI1Zx7dq1N9100+TJk6lt4MCBV155pT6xAT1wDlUCFRIwSrFCPJ6UgAQkIAEJSEACEpCABCQgAQnUAwLEJ77++ut/+tOfFi1Y0L9nj2+eeeaoQYMSv1iSZUtu7qvTpz/44ktLV68eNnz49ddfT6xi48aNq9PxTZs2/exnP3vllVe2b9+Oo/zBD35AYnV1KvRaCUjgYCKQwD84HEzjcSwSkIAEJCABCUhAAhKQgAQkIIGDjEBubu6kSZPwiSuXLx8zZMi1F100YsCAhJiVWFKSkg7t0qVTVtbSVas/njt31apVI0aMSEtLq7JVzM7Ovvnmm8l3Li4uPvTQQ3/0ox8df/zxBxlVhyMBCVSHgEqxOvS8VgISkIAEJCABCUhAAhKQgAQkULsEyHe+995777v33m05OReefNKVZ5/dq3On8k1iGLsdckifrl1Xrlv34ezZq9esGTJkCAuqVMEqEhH5i1/8ghVgaLpz58433HDDCSecUL5Fj0hAAg2ZgEqxId99xy4BCUhAAhKQgAQkIAEJSEAC9ZoA6zvfddddDz/8cFF+/rUXXXjRSSdlZWZW0ON2rVr16NhxycqV73/yMbGNJCzHaxULCwv/53/+5/nnn8/JycnKyvrlL385bty4Clr0lAQk0DAJOJdiw7zvjloCEpCABCQgAQlIQAISkIAE6juBkpKSO+6446GHHkpPSrrx8suPOnxA04SEynR67pIlv3/ooQ/mzSe6kHjDli1bVuYqyjBt4m9/+9tHH32UiRRTU1Nvv/32E088sZLXWkwCEmhQBIxSbFC328FKQAISkIAEJCABCUhAAhKQwIFBYOfOnX/4wx8eeOABfOJNV35rxID+lfSJDC8rI6Nvt26LVix/a8a/Fy1aNGrUqOTk5H0Omxb//Oc/YzA3btxIuvTdd99tfOI+oVlAAg2WQJMGO3IHLgEJSEACEpCABCQgAQlIQAISqLcEfv/73z/44IPpycn/fdVVQ/v1q7xPDCPq3bnzTyZOHNKnz5QpU37yk5+QBL3Pkd6/a9uwYQMl8YmjR4/e5yUWkIAEGiwBlWKDvfUOXAISkIAEJCABCUhAAhKQgATqKYHf/e53+MTmKSm/uPqqwX37JDZtGm9HCTPsWWoVLx3at8/rr79+/fXXV2wVn3vuOTTiunXraOjOO+/EJzaNv9F4O2l5CUjgwCWgUjxw7509l4AEJCABCUhAAhKQgAQkIIGDkMCtt976pU/s0ycpMbFqg2yCVezUiVjFYX37Tp06tQKrOGPGjN/85jerV68m95noyLFjx6akpFStUa+SgAQaCAGXZ2kgN9phSkACEpCABCRQfwns3Nnos5VbZy3Onr8qd8nqvI3ZhQkJjdu2SuneIa1vpxZHdmvZNSu1/va+PvVs+46duQUlJdt30qn0lKbJif7zeX26PfZFAhKoHAF8IrMZttgVnzjw0EOTq+oTo9a279ixeOXK3zzwwMzPPmdSRepPT0+PzrLzxhtv/OxnP1u2bNmOHTtY6/m0005r0aIFQY6xZdyXgAQkUIaASrEMEN9KQAISkIAEJCCBOiWwNb/44WnLX/tw7ZacouKSncUlO3agGBs1SmjSOLFpE/7atEw+eWj7C47t1CypUqt81mnv61ljL3yw5sk3V6zbXEC/rj370LFHtPUXcT27RXZHAhKoiACJyf/3f//38MMP4xP/++qrjuzdOzkpqaILKn1ut1W8/4GZn39ORjNrOsdaxfz8/Oeff/5Xv/rVd7/73bPOOqtVq1b6xEqjtaAEGi4BV3xuuPfekUtAAhKQgAQksN8JzF6+9U/PLnztg3Ubs4sKi3cQXrdLJ5b2a8fORrzlYHZe8fJ120p27BzUI2O/d7ied2Dmws3TP9u0dnNhXsH2kYe16d2xuUqxnt8yuycBCUQE8Ik//OEPX3jhhZbNmtWsT6QJMqBbNm9+WI/uS1aufPf99+fNmzdmzJikL3xlYmJit27d2rVrd9JJJ7Vu3bpJE0O8o9vijgQksFcCflPsFY0nJCABCUhAAhKQQK0S2JxX/PDry96dszFnWzGRifze69Wp+dnHdbr2nEO/e1bv4we3a5ORTAeIWiRWMSO9ZgJVanVE+73ySMju957YAQlIQAKVJ8C/JmVnZ+MTp02blpGaynosR5Lv/IXvq3w9FZdMaNKkR8eOP2a1lj59mFfxxz/+cU5OTnRJamrqhAkTsrKy9IkRE3ckIIGKCRilWDEfz0pAAhKQgAQkIIHaIjBp+qops9Zl5xbTQGpKwrmjOn1jXLdjD2tzWOcWfTqmD+6Z2aVt6obcoqSmCece1/HkQe1SEk183se9+GTZ1k+XZOfll1Bu9OFZRinug5enJSCBekAAn7h58+af/vSnaL62mZm/DD6x2vMn7nFkIVaxf4/uTK34zsyZCxcuHDlyZHJyckhzJmjRfOc9cvOgBCSwRwLOpbhHLB6UgAQkIAEJSEACtUtgzZaCXz0y94P5m8luTkpMmHhC1zOOOqRNiySmUIwazivcvmhN3raCkj6dmmeklV3uk4i8vIKSZRu2LV2fT23NU5p2zmrWLSu1bcuU8tm+RSU7Fq3NozyVd22b1io9cc3mgs9W5qzaVDrtYLuM5F4d0ju1akY4ZNR6mR0SsUNzy3Y116JZ085tmnVtm9qu5R6WBF29uWB9dmHx9h1RJe0zU9q2SKb+Zeu30e7a7MLEhMadWqfSbvtdwZhRyS15xZ8szc4pKAEFv36ZQbJ186TubdNSkvbct3VbChl+aOuVWeumzlrHrJTUNnFc1xH9Wn9Js1Ejfiq3bZl8SKtmMYx3N8vslQVF21dszKd7qzYX0HTnNqld2jTr0ia1PMyoq+5IQAISqCYBfOKGDRtuvvnmyZMnZ2Vk/PdVVw6uxvrOlewMa7AsXLnyln/c//7nn48bN+6mm25y8sRKorOYBCQQS6Bp7Bv3JSABCUhAAhKQgATqhsDUT9cvXbstrE08tE/mMYe1xnaVsVdpyQn9OjUnJzqpnOnD7r01Z8NT76zKzS/JKywpKN6BoWuWnJCW3HR4v9ZfH9U5vVnTWJuGp3tw8tJFq/MY3SUndEVWvjV7/aoN+flF2zlC/GPLtMRjDmszfmj7Dq32oAhZRvnN2RueprmCkm1fNJcamjus9cWjuqSlfCWC8rWP1r7x8fq8/NLKwzbmyKyTB7eftSj75fdXM9chuhHBl5qU0Lld6qlDO4zu36Zpwu7+rtyYf+/Li3PyiinAIexeUmITlm9unZF80uB2x/VrU4bSm3M3vDxzTe62Ulu6Oa8od1tp1CfbSzPXvD17AyIxvC19bdzoqL6tzz+uU4fMr4wReh8t3vLItOWbthZCBrdIy6jM9JSE7oekX3VqD2Tol5W4JwEJSKCGCOAT165d++tf//r1KVPaZmTcfNWVQ/r2TWxa6z/SSW3u1anTTyZeesv999N0QkLCDTfcQMrzri/dGhqb1UhAAg2AQK1/WzUAhg5RAhKQgAQkIAEJxE1g3orcnPxS+UXg3jF9W3dvl1bGlIUad4m2GCm26+i67MJH31rxxkfrlq/fVn72wFWb8uetyPn/zu9LcF9UJwtJr9iQv3B1LhVM+XgdIYQLV+ZyMLTC64oNjdZsKkBfXjCqMxGI0XF2iAF87M0VKMIVNBd7Ytf+SppbnnPDBX0z075sbt3WwsVrtjFHZFS8Y9tmTZqsm/H5ptmLtwSRGk6t3pTPTlbLpCO6tgxHiMos07dwPDkpYeHKnDc/3fCjcw5NjnGsG3OLlqzJYxGbUCx6JXqRv+ht2OmSlYoxjD24Obd48kfrJr29YsnavNiOhTKEdiJerzv70J4d0giZjL3QfQlIQALVIUCo4Jo1a1h5mfjEdpmZP/3m5UP79Wua8JV/nqlO/RVfiz3s1bnzjydO/O0DD0yZPBnJyNSKLM+iVayYm2clIIFYAs6lGEvDfQlIQAISkIAEJFBHBCa9s3LZulIh2K5VyqlD2/don1bJhrcVbn/vs40PvLZ07ebSnGV+/jVPS+zQJpXZGLflb0f55RduJ9AvPT2xT8fmUSJzTn7JlI/WbcguVWxbcos3ZBfhE1ukJyUnNsGjBS9JzQQhZmUkx3aGcMh35258aMqy0BxaLZ3mWqcSEbmtYHdzqzYWNE9P7NuxedOE3bnJa7cUbMotTklpWli0PXi69NREnN3iVbn0uEObZs1SEgoKabjR9h07t+YVt0xLGtIrk77Rfwzme59vIjIxMZEfuY137Cg9yLZ9+0703/L1+ckpCYd1asGpXYcbbcwpWr2lkLYympeuYMO4wnBat0yGbUaLZI5Hf307Nx/YPaP5F86Usp8u2fKXFxbRNzK7cYZ0jNGlpzaFBvWUlOwkQ3xjXtHoAW2jOMrQrq8SkIAEqkwAn7hy5crbbrvt1VdfbZ+Z+ZPLLjv68AF15hNDt/m/j9YtW/bu0mXJqpXvvf9Bk4SEAQMGMK9ilQflhRKQQEMj8JV/gm5og3e8EpCABCQgAQlIYL8QQHvlF2zHkdF624wUkpQr3w2CEJ96b9XmXdMFcuGpwzqM6NMKwVe8feeydXn3vbJka04RNT/99sox/dsw12H52Dpyitu1bnbioHaHdy0Vcys35L82a+0ni7PpA5bzs+Vbxw1sG/Vn5caCZ6avDs01T008dVj74Yfuaq5kx5K12/766uKtBDtu3zHprZVjB2R1asM0haWmb2TfNj3bpTOB4+NvrZgxdyN6jlaKine0yUg5eUi7I7q3xDO+8cmGybPW4hOz80rWbMznCM6Oi3u0TyfmkXWuMXq8wio7v+T9BZuZJBH/SAzj49NWjOrXplMbhlbazSE9M9tnpNAW+699tO71L+ZSHD+s/Yg+rctEFrZKTyJ4s/SyXRu6cArRlxu28S41pemwvq1OGdSOYdIQMZuPv71iwYocujF97qZZi7fQkFZxNzj/RwISqAYBfOLy5cvvvPPO13b5xB9efPExde4To+7369bt+xdeePujjz41aRI+8eKLL87IyIjOuiMBCUigAgJx/PdrBbV4SgISkIAEJCABCUig8gQ25xUXfpF03KpFElMKRtdi0ojLK7PhxcKyLSTtkrw8Z+lWChCWeOzhWReN6dyxVbNQHkXItXc+Mx89t3pj/ucrc5gYsfw60Sx6ctKgdueO7Nguo3QhFyITs/OLWQeGhZIJKmQF6sLiHUQvUiczLS5YnTN3aaltTEtpOuqIrItGdzlk12SL2NABXVvS2zueno90C82xBkvSrikcmReSP656e+7GpiQpF25HHdLhEwe3O+vojm2aJ3EJATIL1+R+vHAL7pCG6EZYgiaTWR37tg4j4pWG6A9tsRrM319ZwhH8Iwu8lK6ysmv6RRRhZAnnrc4NPacYK7oM7ZVZRilyPHZDdDLfIp0hnLNP5+bfPLFb70PSgxVlgsWM5ok/+8fsouLtBFS+NXfjEd1a1nEMUWxX3ZeABA4aAhs3bnzwwQdffeWV9q0yv3fBhSMHHtG09udPrIBe/x49vnv++X96/PEnHnuMYl//+tczM0vDxt0kULMEQnDukiVLWrdu3atXL1YYr9n6ra3uCagU6565LUpAAhKQgAQk0NAJkE0cQhQBwbSACV/kCxNpOPnDtTPmbSoDqF1myrED2vTv3ILFQ5ZtyEf8USAzPelrx3WKfCJHWMOE0LyHpi7dsKUQTbZ43baRJTtTyq4U3ahTVurgXpnBJ4ar+nZu0blt6mdLt+LvsHustpycWPof+nkF25fTXHGp42zdIum8kZ2CT+QtAYLESI4f2uGBKUtZYZnmmHbwmH5tkvbyX5fEG/Y6pDnZzfjE0ssbN0J39urYnBztxo0apzVL3J2uzLmvbjSUktjk0EPSWSzln1OXh7HPW5U7un9WNWMGEa+bcopCMnir5kms/UKqeNQ4jQ7v3eqIni1nflZ6O+atzCV0MTrrjgQkIIGqEWB950ceeeT5557r0KrVNeefN2rQkXWwHss+u3p4r17fPu+8u/71ryefeILCF154IdJnn1dVvgBh+R988EFeXukSYdR82GGHsSZM5S+3ZL0lUFxczM2le4S47nMiTpL9n3jiiTfeeKN3794XXHDBkCFDantcBQUF69evX7FiBfOW0tU2bdr06NGjS5cuzKtS2003kPr38h99DWT0DlMCEpCABCQgAQnsDwLkKX9hERuRFExub+gF3u3TpVufn7G6TKe6dUhD+aEU8X1rdy05gpIjZ5lQx493hRDGlicIMbxlikOsWeypsN8pq1lmemJs+F5soB+XkKEcSpY2t2v6xdAc1ZVpDskWzWlIivT27Vy411+JA7q26JK1O6CS+llG+bSh7Qd1L12VBb/JWtWhUV5pF2m4cHVe9rZiYidLSnYkJzdJTW4a9XnFxvy9Kcio3vnC6wAAQABJREFUkn3u0Mqm3FIZysaa2inJCWVGV1Syk/kcQz2EYZaPHt1nExaQgAQkEBEgRGvVqlVPP/30v554IqNZs6vPPWf04MH1wSeGHg7s3fuqc865+8lJTz35JG7oa1/7Gv4l6nx1dghF37p16+9//3v8DvWwCMzvfve7tLTKziBcnaa9trYJsLjQO++8g6G76qqrOnToUHFz2L2PP/4YuZyTkzNixIhaVYo8dYRDMlfphx9+SFzwli1b+I+JFi1adO3addy4caeeeur+DQ2uGNQBdPbL/3Q7gDptVyUgAQlIQAISkMABTYAAw2jhFKwWbqvi4SCzWEiEMiQ+s1gzO4gwIuz+9vKS8hdm5xQHTbYxp3CPgXUtUhOj7OBwOVnVIbH6i9p2i0g6Fpoj/ZhovvLN7Wy0k5kZv2iuqNQo7n0jLTqkNociqckJ/bu04C/2ioLi7Z+vyHn9k/ULV+XiKAnnZLUZRkE+dVpKYuQ6txWWhEZjr413P6+whKVdwlXAfObdVYmR6N11FGu5eE1pTA3b1lL5uAc/G876KgEJSKBiAvjEhQsXku88ZcqUxsXF/3HB18YOGVJ/fGLo/JGHHvqts8687Z+PID2xiuedd15WVlbF46rMWaLY5s+fj3gKhVNSUlavXk2wmJFilaFXz8t88sknTz75JDGnRLbuUynyOA0cOHDz5s1EKXbv3r1Wh/bpp58+/vjjr732GqGRqampbdu2RSnS29mzZxMpfMghh9Sq0KzVodWrylWK9ep22BkJSEACEpCABBoEAZKdiYkjvo+wRFQdS46EYeP1BvXKKE0q3rWxWMonS7KjsxzDKxZ/4e0I35vx2cbdRff0PxgxlF/5M+QLR6GF5c/GHildHWVXc9SSW4nmds18GFvBl/tMUEgqcbQk9JcnYvZYYmX20q33T176wcItRV/VrCUljVhgOqZsDewiaqP4UNzlh/M3V1CpSc8VwPGUBCRQMQF84oIFC/7xj388++yzhIhfdPLJ44YNq28+MQxhcN++l02YcPeTTz7+2GOs00IwV/VXayHhdMaMGTjKnj17EixGyNisWbM6d+7s6tIVPzYH31mc4xlnnHHkkUe2atUKq1irAyQw9vPPP8/Ozh41atQxxxyDQywsLHz99ddfeOEFPozTp09XKdYIf5VijWC0EglIQAISkIAEJBAfgZa7AhWZGXDz1sIVG/KZJDGNbOiExkf1aT2w++7VNqd+up4JCmOVItGFrFkcWkpJSujTpXnTL9Kcyzd/ePcM3GX545U/EtscydqHdq6oOVYviUIvyzeR0LQxyd5fyNLy50uPkNP9yodrp3+2ERWanJTQo0Makxs2b9YUB8osk5u2Fk35eB0rpez54nJH0aAYVSZqLHdm94GUpCZR1GRSYpP2rZtltdjNtvwl6c34+V8tmOXr9IgEIgL4f5YAXrt2LUfat2/fqVOnMCsZv4GZAoyYGqaf69atW1S+Ae6AiBC//Px8tBTxTcyGdqDkLRKjh8K4//778YlFBQXDjzzy7LFjUlNS6u1NHDV4UGFx0d+fex6r2LJlS4xMenp6dXpbVFTE9Hn8P9yYMWN4zgkce/vtt08++eRYpfjZZ5/xqJNqzUZ6LCmrZEkjnvr27YuHio1nhCdekgJ8XrZt28ZnhL4R+UjhwYMHk9nKjI3vvfcelxAQxwdn7ty55JszBM7SB05RAKHJUxQ6QIXUtnTpUlwnnzvq4Rnr2LFj9IDRn3nz5tEWDTVv3pyzNLdo0aLFixcT+ManFUfGkQgR5YlIpbbQPXrCWaLk6A+XR8Uqs4ONBQutUxuLmbCkCT2ncgjQ7qGHHhoqeeutt8BFn/F0odtY7JkzZyLUOMhXB2F6UXNwY7wEioKO/vBRokCZW8zlubm5FAMdo+Bzx5FmzZqRrk7CMogI/UPYgY5XOsn27rvvcnOjVvr3789XWbhxHKeqkPYeCtA01VJhVD7sUCH0eBgYL3US1UieMqOOLbZs2TLgcy2DZSzcBbrKQJigE2+YmLh7Auk+ffqcddZZw4YNO/bYYwcNGsS95mYBh0xtesKXamyd7leZgEqxyui8UAISkIAEJCABCVSdQLd2ae+nbEYpFhbteO+zTQO6tezXqTn2Ky0lgb9Qb4tdNi22DZKFowVSKDb6iLasWxJbIHafhVCYfzD2SLz7rPLcIXP3zyQWYxkzsG3vDnttDh/XLGbp6jJtoRP3IRQbNVq9OX/655tKfWJik/7dWrC6dKlSTG2aiFIs2bF6UyGOtUy1Zd6iUMN6zRxnkkomQ0xJ3KtSZHRhWWoKJycmDOjecvyQ9mUqjN4icImyjN66I4GaJcDPdZzLyy+/jNHgB/C5556LCqEJjMC0adOmTp1KQM0111xTs40ecLURWIRrwB1gQHAEiAZ2MDWR+qmHI0KR4BMfeOABfGLO1q29u3Q594TjO9ZENnHtDTapadMTR4xgJot7Jk1iJRms4tChQ2P1X1xN82yjb8g2xS4RLIbJIvUbr4cGQmMFdU6FeMY333wT68dBJCCiKihFlBBiCD8VSmInyV3lk4Jlw7UFZ8flODueB2QfSpHwtDvuuAMB98Mf/hD5BXlsFx+oW2+9Fd9ErCh9OP/88xFeDAq9iN+kdVKz6WdQiv369cN40nSY8JE7+Le//W3dunU0hNEbP348fXvxxRcRW1gqnNdpp53GYiOcZbDEY7700kuhNrpHSTwm/ouPMPIuLqXItcw8+NRTT0EvKMUBAwaMHDny/fffx6MRQBopxXvvvZdsYo5Eqp2ePPbYY1A66aST+D4JSpGnkaqgR5RorFLEGjO9IEAYAhuDov5nnnmGjxvqMFYp8jDQKFSpASbcDgQfrzT38MMPxyrCa6+9ls9mUIqMguRoXGGon1cIs7B4+JaLDjJespUnTZpEu9wLqmXaTT7jEyZMOP7448EYSqJKWeOFRcnp9r///W8uCUoRY8sEoIcffniwirhpLmTI9Dl0g4FAiUp4NlzTPMJezZ1q/VdmNdv2cglIQAISkIAEJNBgCRzdt9Vbn6zfnFO6NPOsRVve+HQ9Eyy2a8mCiRUhQSl2bLXb8bEQ88r128YPaZeZttfYuorqqsQ5Aicjg8k0jqs25I8f3D6K7KtEBfEVIbV53ebSyfvJCj+sa8tR/b9cGQBRWLxjZ+G+QhRZdiaaJnLpuryNWws7ti4bBBH1iSVZWqYl4goZGspya15xVsvkbllfhnJEJd2RQG0TIASPyCOsIg0REMTv7eOOO459Ynk4jlKMQm9quyf1tn5cD9YGiYPLwHfgEYhgQiHhEXjFpJCfG0mH+jMKxA1K6LnnnkNdtc7IOOmoo0YecUT96d7eeoJVPGn4sHXZW5549bV//etfuKEqp6kihrhZDB+zc8QRRxBbh98h9o1bifSJHmyi2HCF2ED0EGoJM4gAYqFeiqHDCFQM+om3Dz30EDx5HvBNUQ0oLXwWJTnOpwknxdDQYbxionlmcI5UGJwaQXNoSkqGs/fddx8reNA9WuEgjowO4yupkIg8ytBhJBRBc0Qybtq0ib6FOEEuwTbSSWTZ2LFjeSBp8fbbb8dg8iiiGuHGDpcj6Sgc7/NJc0TmPv/886hPRB6jozlkJV6MKEWsOn0L20cffcRB8MIhHGGHkhwndo9bEA5S4aOPPkqFjIWAPhwiUX7oVAQu5ZkMkWFSEnlKMTw43QZy2DgOWLagWQEFH0YEWO4aWp+dWKUYO1j2qZmNy/lEQIl9HonQq/BKByB5zz33IGQ5G+wwSpQhMGpuDQMJZpA+I0bpAMNhH7AMh8FSmA5wF9C+oU7uVNQE/zzDFywimC9Vypj1HJGp5o5KsZoAvVwCEpCABCQgAQlUhUDfjs0H985ctSk/O7c4d1vxy++vRREe179Nt7ZpIdWXvF3m7yszhV9KYkLXtmld2qUuW7uNyQ0nf7A2My1xeN/WPdunpafs/u+6HTt25uSXEK3HkYoF5T77jW6jP6G5nG0lr72/NiM1cVifVj07pKcn744XoLmt+SUEIVa/OX7eoQ63N9pZXLxjw5ZCFocJYY8sz7Jkbd6jbyyLVpshtDOnoAR7WCaXun1GShQp+f6CzV3bpY0a0KZNC4IX+ZHZiLkaS3bsYA0WZCJjp7m2GSkDe2ZMn7sRq/jxwi3/nLrs+IGlgZ8t05JCTCVX5RaWsCwM+ebVhLlP2haQQCDAb2MEx/Dhw6scF3awkkSzsp1wwgkYEJwCoU+s+EGIWbdu3dANBLKxg01AeQRbVB84zJkzh6AwLEZKcvLA3r3OHD0q6YvEzPrQvQr6kJaScvboMYtXrJz+7rtkH2P0iE2roPzeTjH2sCIwUgwDGMwd2o5oPnRwpBTD5Tz8+HQC8Qg5pAzqEHnHvWafDiCkkH0YdtQSSogYNLxYEFUIKawWlVMPdeKM8GJE9uEQEU9cGCLUcE8coQyyj88XGo4mUJlYM2qjTp4ceovVIhSObGKeK+IK6czll1+O28KyUWfQ2RdffDECCz2HMg65yfBhLWMeSOonYBDJSCv0it7SLso7rsg4OowJZbCYRMLxzj77bAQZTz5LjmDlYuVdQLfPVwZOfCiTCSIKyUDncwRSbB1RnHzhcOroo48O4hjahCiClPtO3B+fKXQhDNmwk+Ex4N6xQ5l//vOfSEnGCBDMftQNoEVWEddJYZ4EOAAcSR0Vi3ZQycSukpXMePmYE/jJneVeYJABTmzpr371K45E5bl3ICVilJ7geXGgjAV9TDxjpBSjwsDE8xJWCVLOnnLKKeSqR2fdqQ4BlWJ16HmtBCQgAQlIQAISqCIBXNiJg9t9vjxn1sItJdtL4w2ffHvF/JU5h3Vp0To9CZeHTCyzNgstcRWabMKIQ+57cRGea0te8YNTln28NHtQj0zcIlMxIvhKmHYwp+iQNs3GDWxLPVXs367LaK57+7RTh3X428uLaW5zbtGDk5d+vCR7UM8M3GLU3MatRR3bNjtxYLsQIYjrfO+zjWhN6liwMicsgbJ9+86Z8zezfDMHmSexX+fm3dullekb0zW2bpm0ZmMBOcuzFmx+4q0VrVskMz9jdm7RnOVbX5yxunlaIgtMc9WqDQWT3l7Runny4N4ZXbPSmGwxVHVIZrOsjOQFq5rQ6OLVeZPeWbl8/bbObZqhEVmspqBoR1JSE+Z8JJ86lO+SlXrq0PasLs0iOUQpvjBj9fxVucN6Z7ZtmRLqBOaWbSxRs/MbJ3StYKbIMgPxrQSqTIBf5kTT8BMaDxJlNZavDSlAeA7BPhTmElQFIVH8aK8/Kq18n2vqCGFubKNHj0Y/IZvIfCRy7emnn8ZrYDEI3UKLMH8cYU24iZpqtMr1YKCIiUNytW7RfMyQIZ3btatyVXV/YdsWzceNGD5n4UKsGTPTIXp42OLqBhIqqCLMGpfzfGKFUFdEKZLmfMkll5SZwg/ldPrpp6OxsEXEvhH9h94iBxZ/FNqlAGaK2rjF1IMKLH+XMVmoRj4gXEglXIvq4i4g/tBqbFQVwhv5oCHpCJdjbWvycIMRYylqdCSijWBYdlCKqDc2LqS3HGRE3/nOd5CG9ITWsVQcR1oxWF5DP5Fo5E3zEDLeqn0qeXJIAOcDTrLzZZddxr8xUDPeHBOK3AytxPVKt1GHfGlgTiGMpqRjdBKkBHUCh1c+O4yCkRIoyr2GErnqjKLMbaJd+LOxg0IFOBuSDgW5xy5xO9g4BTEE7h7LcJuwfnyzUS2TPCAK6QkfZ/AyXtTtDTfcwOcoFibJ2t/61rd4BjCbPFHccV6J3yxTP2e50ahJ6iH4kbETo1r+sSlzlW8rSUClWElQFpOABCQgAQlIQAI1TKDPIc1PGdq+cZNGc5duRcPlF2yf8dkm/oiGI1GKpUXQcOWbJO947OFZc5dtnTlvM+GNhNfNmLuJP0rivLgEd8b+Eb0yR/ZrU02lSD2kY5c2tzzng/mbcreVEDlITB9/ZZob2Dtz1GFtglJcm114z0uLiSukTLTh+J59bxV/HMlonvStU3uUV4rtMlOG9M58YdMafkis2Vzw52cXNktJYAibtxYxKPaPG5D1wvTSGtZtyv/bK0vY+cG5h7bPRP/t/m/ajPTEYw5rs2h13or1pb/rFq3K5Y+daOvQplnj47tGSpFEchbDOXlo+1feX7N+SyHadPbibP4oH+IfQ1xkcnLCxaM7qxQjjO7UHgF+w/NLHs1BkNTeUk35tc/P7FdeeYUIOEQAP+b5Ec7veeJ6cGrxSp/aG0ut1oxUIpyNjaAkcOEp0CWEKREmRoQa/gslQYwYPojsTnb2l0EgZJItNyend+f+x8VkqtYqnBqsfHDv3u1bZU57/wN0DJosrjg7uoEhwgmS1AwEpBjf7Rw86qijcJTcMowhHpwHOOow9fPYh3xVXoMxZCoANsqgkwgx4+YymSAhhFzIA4/wQjGHzPdQD88GAosngfpxTBxkPkECDNmnBnwZNfNgcDlHggRE/CHxif6jMNoraMegI0Od0Ss10CuGwBGuQqJdeeWVqC4iZKkQ/cdIcZRM9kfl2MldMu0QznI8VodFFe5tBwOI0OTjzNML+VCMx5gHmwHu7aoKjuMoQ64xuhbvRpRoKJyTk4Om5BUDyxE6ybcQLo8AST5Td911F/+2AWQGwig4VUET1TnFjeAWMDTuJvMhhp7QVbwhzx49524ShRrLkJk3Q1wqlHhseJYQx9y+Mt3gCA8MAY98FeCOL7roovKGtMwlvq08gao8i5Wv3ZISkIAEJCABCUhAAnsjQGrtacM6dMpq9vLMNR8s2LI+uxA/SJghv7mIWwxXoRdxam1aJrVM3b2IIfF4HVs1+9Yp3Una/XjR5iVrthWyHPIu9xjiAcOF67MLojRhjny5asmu5OLdQX1f9IxW+AsbO9EKJxzhcKc2qd86ufszGSmf0NzaPTe3bkthlKNNfnHQml9UX/Z/S4cYlY45ybgAsmZTAaGCW3OZO3FnXn4Jf/yEYIHsEX1bTRjWPijF6KLSMX7Vu54wsC0hh69/tG7lhnx4RiXDTl5BydZtpXGO0dY+M/nckR1JNn9vzsYFa3Lz8oFZWmMsPX5g5hfvSE3Z++rRUXXuSKB6BNAl5BgSwMWPebLzyleGo0GcMV8bv5AxGhgW9AdLuLDxc/qnP/0p4VSxv7rL11CdI8T7RPFi1amnMteGUezxNfYgNgTJwkbUFbFIiCSmVAMO86YhGrA/aEeMDO4J1YgQIWM09vLK9KQ6ZVBd2JkP//3vHp06tt+15E51aqv7a1MSCfIuVX7oLaxTvEoR/c0d4XKeHKJKiSNjnweVr9kwx2K3ry5GHMwgNy6MFFWHY6IwWziC3jrjjDN45tGUrAdCSbrE3SdikQ2jx80N950WkVBMz8e1GEDyc3F81Ma1NMqnjAp5mMM8g+Tb8okLTfDKVbxGKjM6zg5dQl0FDrTFE0XCb1QAw8haKAwZO8Ya3zSN7ie0kFRull0ilJjLo8IV74AOp0l57GfoLeVpkQeet4yi4ss5G0ELJamNOtkn+JFM4cjkYhLRlzTEayiJQCTPGotHSCZulEZxcLCFMEGLBDlGNyiUr5FXbgTSk+80Wo/qZ4e3oX7OEmMY2xaWExrhCBdSmK/H8mQYCDeaUzw8rLqjT4xlWP19lWL1GVqDBCQgAQlIQAISqCIB/N2g7hmd26S+9/nGuctytuQWYdAKivkptDOxaePkpglJiU2I6SMbuk/Mys7k5PZqn37N+B4fLNoy9ZP1ObnFBA9u26Uj+U9/5g0kgzizeVJS0y80IQtJJycMJZ83o/Q/vkk6ZrHj2B7jK0kHbrzrJ9vh3VpyeexZFlxmesFrJvT4YOHmaZ9uQPah6r5sLqEx0xe2apEUZR+j50b0adWjfdm85qjO1JSmHdvsYdUUahjQteV3z+g9eda6JatzGRR5x/y0pLfdO6SffdQhiNbhfVoRP8iW0KRUfZLUTP51VDM7LJN98ZguXdulvj9vM6KTSrbvsoMUJsyQ9aMPafWVpjmOyuSSYb1bvTpr7frNBeRHbyviZ0kpDipndMy9WOpAOfCVpmKbdV8CNUMA7YXvQIrhDZkrsMxPaNogEZIVBkg2RCswGxobMTjMTUZUI2uqjh07FhHJr+ua6c1Xa+GLiTCuPc6D9tWCNfCu9EO+awtyocxrmVO7i+76H6wBw8ccwZBQLCwSfofp21CKzIvH2ZAeHi7BB5H4WQPd3XsV3bt3R8TM+fjj/ILCLbm5Genpey9bH898vGDB+s2bQYq+CRFhcfWS0DOyWbkEPXfjjTeWuZaZ73iAYwNIuXHhXpcpGb0lZA9nx91Eu4dbjBHj48A0fDjB//qv/8JAIctQyQg1NGjQl5g+JCA5v3xqUEvEwQUVRXM8CVRO8i//VxFZNgqwcVWIl4xaZwcUFXBAzDFMdDZSG+mJyUJrMk0hEX/k25LPC8bY2va5z4eujCOjw7RS5mD5ejB0ZZRixJZ7gVskajJcxaeAjXjAqG+Mmq8RBOjrr7/O3AJ856DziIwmsJF/uvjDH/4QMsRjGwUgXY09Eu8+4+LW0+cyQ4veRncnqpny4fZFR/a4w4V8DAlnJk6W52ePZTxYZQJf+a/JKtfihRKQgAQkIAEJSEACVSbQpnnSaUM78Ie2IoaOKQtRaeTksh5xahI50Hv2WEQvHtO3NX9Eb2RvKybIkWhFBBwKjAVJuHDXD6XdnWqRmnjN6b321sMOmSmXjO3aaOzezpcep1oyqfkjeHBXc6Wd/LK55C/FXqfWzX50bp+K6tr7OeTdYZ2as3YNKpAZIVF7AGBGRUQhF9Hiz75+GLKVH534QRQk/rR8ZaA76ch2/DHX5KbcItKZQYQcTEtJyEhL4mz5S2h3QNcW/FEyr7BkXTbTyO+galK5WzVPatGM+ZvKX+QRCdQ8AX4kEw3E5IA4CGYJxGuUaYPf9ggyfiRjGxEopPLxS548QWaCIwqJfFKsItajzFU18hZ3Sa9+97vf1UhtdVkJToTMR7bYRjEs+KzaVorop8P792/brt3bH300oGfP8SOPOVCWZ4FVdm7u82+9tXjVKhQez1gFKi0WbLTPk8njiukLj2tsdBiujYRoFBUPbZC80VX73CFqj4g/4v6ImuSTQlbsCy+8EJQiHxliGGkOR4acIiiSaEHaxScSrIpfJkYVRRVFt+Efg9AkkvTMM89ERMa2jnQrb6D4hFb8+UJWnrhrw2iztgz53azaTLjfpEmTmMKPFitjwegGXUXzoeqohzi7YAAZFDaQg7H9ZJ9e8cpzHnk9xh4CMKOSMAm3gC8NFncmazi2J3wcCHCOCuNeYcJ0CvhH3ChzLPAvGUxXynAQpgRmRtcyXlrnXnCv6Ri6M6okrh1aJKIzzIcYjZebFRbvpiq6HYYZV7UUBiM3l+R3ulqFZW3iba6hlVcpNrQ77nglIAEJSEACEqi/BPBjTJXIX1xdxHZV4aq4mogtTFRAZloSf7EHa3YfDoRVpiV/JZyQJnCIbVvuznKqTItVwAJMlq6Ols+uTCuWkUDNEiACiERdfr0TH8TP/tjKEQr8dOcXPlaF2Dd+Y3OWn9lhvWNivvjlTxBW7CU1tR/0EL2qqQorricIi9hXyvM2HAn70es+T1GADT0R8iKDdkGgRFPUhQK19MqEemPHjPnr3//+6KuvdunQfnCfKv6LSy11b2/VFpeUTP3gg5lz5ialpODCUHJ7K7m348gvfBDptDyu1113HVFvUUk84//8z/9gFdkQSRVLuugqdkIyMuVRYEgoJgrASCKzUIrcXOwbZfhEEO3LhwVfGZYcCXFq5MVjlCiG1wst0iVEG+KPDw6OkiBWtClluJZiNIGEYp8nh2cmCsTjbbB1VMsWdY+SRGVi3rmKa5GApDwzNQHmlExqNBlAKBM9w9GFe9whVDB8wIlzJOYRi0qdqFgUKkjLqDGsGbnMBBLy5dCtWzcKYP8DDbpKu/QZrwpqeoVmpT8kgwfJCC7K8BqFi/KW7xkQ4QdplAcYnoyLjz/9h3Zsh/GwAQK3gO8u3jLAQI8a2OcS3vLKVdTMPjvwZJ+NfZoOuDDXfIkxBGIhuR0cRxkT40kZblmVp3Rg+ChdnjQEMY9xNEyqdas+AZVi9RlagwQkIAEJSEACEpCABCQggZohgI/ARGC7+DnNr/Tgv0LV/BoP853xUx9VEdseHgFzQWJy+MUee6pG9lESpJFSP7/JgxOJzEgFb8uUoSeVKYxKoFjYyu/HHvmiVGnKZJny4Qj0sDxEb+FiMCzsc4RYLTwUhAlcqhE4FVfSrkOHcSee+MH7pUuc/P3Z5zpmZbVr1ariS/b7WRTap4sW/fPllzfm5Jx+xhlE3aGf4u0VEo2wQW4EMojgWQxgVAO1MR8oBUhLZybEIPiis3vbQUsxDyAfCuwYmpJPAbaIKRqJ26UVjoSEXAxX6C33Go3IskWc5fMSRdKh6kKL5MOi6vBNWMV77rmHOFZihJFiQRriK5H1aC8KsIU8az5f+DjmXuRzyuVsUW9pDlXKfAW0jrmLuocQxIQixbCE9CQqX/EOlRAZyoOKYqNvIXCPlYhefvnl8hcOHToUUcj217/+lehCeoub45mnJPsYOvqDTyQsF4DcFEIm+XqhJN8boOCjAZOwojeQGSArLNM0HeYsLpUAT2Y84CPGTUT8xXYgLKdDDc888wyj4y1+kK8pdgCIv+PTxz0Ka79Aj/5wOeVhBRbqxPTxbyc8JEyHSsApJX//+9/zbUM9r776KoNiZ+LEiQCPbbfy+wD8v//7P5bwxqL+5Cc/KfPvNJWvx5J7JKBS3CMWD0pAAhKQgAQkIAEJSEACEtg/BPjRzu9ebAteoIw6DB3iZz9b+c5hMfZ4vHzJeI9QM4Ljt7/9LdYAC8ArG5XwGt7yGrsT7YcCu05+Kf6is9FObDEOxtu9MuVRFUSoIYMwFwR7ghEngk/EkmA6MBfIhTJmpEwNNfv20D59vn7xxctWrpw5Z84/X3r5qnPPaVZVP1KzHdtbbSvWrr0H67Ry1THHHnvJJZcQp7a3khUcxyuhuXFSZJfH+kQuwSIh44h349YwySBBdhXUEx4eCnBDKX/LLbeUKczDiS8jro3J8jjFs0SwIQdxYThHGqIGbCOqkVA7ChBzx9lQkpkZsVeEwjHTImLxscceC5VjLb/73e+iFHmEmKX07rvvDsd5ZYZBNiq5+uqrr7jiiug4vozj9957b3Qk7DB2fCIl9/hZLlM4egs3ZCvxoU8//TQSkIEzCoITeYZRbFGxsMNCxsymiiVk6gM2BCJH4I8c5GuEDeBIwxEjRuDX+HTg9QhjRIxG9ZAazHcOWpZRENp56623RqfCDlQZMhZy9OjR9CQ6SydxkQQwAhBNHB3/5je/SXmUIr364x//yNyX0Sl2QM2cjOxQ1bhx44AGJfKsWRYGm8nZn//85+Eszwaf2fPPPz82IDS2qtj98DUSe4R9HrM1a9awg9zke0ClWIZPNd+WfRarWZ2XS0ACEpCABCQgAQlIQAISkEB1CBCgRLQUCoBf/qQ9RlWhEiJXQvAO9jD8tscC8Ludt5iL4EqiS2pwh5qxijVYYY1XhUJCoxCMRh4rq4LgEch2xHQQ34TNIdSOkDQMSMUCq8Z7RYUpqalHjRx52WWX3fnnP7/47jsD+xw6etAg9EdttFX9OlmP5cEXXvxk4aJ+/ftffvnlCJ0q1EnIHgYQ8kSDIqHK13DqqadyvyhDSCBncYIEwKL/YlN6cVJhZZVwyyhPhCnFeOCDOuf550NBgBvLibBFOa34KWYGwCVRgBpAjVLEDyKVaAu/Flk5YhJ//OMfE+XHXIF8pnCO9JyrqCH0hMeejxWBw2WGgNqje7EHuQolF7oXKqFdRBiRgGPGjKF78T54XIiIpCGEHUIcyci94Bn+5S9/iSqNbRppe/311//lL3/h4adRPqeXXnopfSAVGlZ0jO8NXhk1k67y3ULIHqcoDHyO00nGQp30nyMUYxTsUAOthALQIKoX5RcmZIxa59of/OAHTE+JlgVvuISDUTH8JreVvOzoktgdSjItbDjCN973vvc97hQBj0Rlcou5C9j/b3/720CIruLrkXtK52MflWAeCavkYYhKhh2EONAoz1rV9fwbrEzPD4i3pZntB0RH7aQEJCABCUhAAhKQgAQkIIGDkgA/+3/1q1+RtEhs0fe//31+VKMI77rrrkcffZTx8qsbHRbipEgh5Ac260EzDRzLPiBH+OVPSibRTPyyO/nkk1k+BS9wUFLa26CwGAgXHATQCIsjz5T8UJAig1BaiCSybnEKeI291VA3x1Gc3LIH7r+/T+fOv/rOtzt/dTGQuunDPlvZlJ395yeeePHd93r07v2f//mfBI7x+O3zqjorwEPOvSYEFfeH6uL+8rSjlmrEz+LUkGK8Ui1yimppIt6h8RwS2IgqpUvUQPfwYlWoJ7ZdaqNjKEXMIN6TiEI6SS7wDTfcEFuMrwIsamBC6/SEjwZ+MGxl+sAHBMvGRkk6yRYxBDJ4GQWv7NMuZzGDUYHYRqN9hC/ekBBIilEYgHwAo7Nx7TAQWqdCRGeNPH5UxVjCF0JcPbHwPgkYpbhPRBaQgAQkIAEJSEACEpCABCRQpwRY65nwLnIecQexDRODc/rpp5NgyLSGN9100wUXXECBP//5z/zyRyUQQ4S/iC1/EO8H8YHCIJCTzFAyK0kOxTcRqoZvJQeW4DICoPZLWOIesROEhTImF/XNqVPvevLJ6y+9NCM9fY8l99fBLTk5f3r88Rfefbd7z17oKp7AGhE6NTgcvBi6iq0G64yq4rNT/Y9PbXQPqVcmIjLqc+wON4t/Y4iOVEwJz0hyN1tUPtoBMhx4XKMjldlB2BHyWZmS+yzDQMoHG+7zqgoK0De2Cgp4qsoEVIpVRueFEpCABCQgAQlIQAISkIAEaoUAEoHwOvIZy8xBhgIYP348k6ARiEc6JBvNB8/CXHLMEtgQfjkTtEXMEQFWmMS3336bsESsIhqCwCjSXUkyhUO8QqRW7mK5SkllJQqV7OzJ06enJidfd/HF9WdSxZy8vNsfeeT5t9/p3qsXtppU3/rmE8vh9IAEJLCfCagU9/MNsHkJSEACEpCABCQgAQlIoIETwAky9RiBObxGHgf9xLoHTAtIPBGJhwERJYm8IyzxzjvvfOX/Z+884Nus7/yf2JYtWbYs771X9t4hCWSSBMLeq5TZlh5tr8e19NpyR68tvf+1tFBGOWbZK2wIgSyyyXYSJ473npIsW5Zkefzf8pMoiheOt52v8Ms8evSb7+eRY3/0+X6/X35JYCNnePXqq6++77773JOLjUqkKIk80BBREhFbKbbANpFfSZEGKwKc09LS+m40G1B0RLWjKuIB/GznrtiIyBtXLPceBv4pi83259de+3DbN0kpKaTqI5We6z4cUBoyeC8I8JZXHr3oK12EQP8SkFyK/ctTRhMCQkAICAEhIASEgBAQAkJACAwGAbKh4c4jcxnRjkgMgzHlkM5BUDN1G6gsQXFbJUkcqiuFNfAkUsoWi+KQru48JidVHEV1f/7zn5cVF//77bdfvmiRl9dQ5iu0Nzb+4aWXPti6Tevn9/e//50qFheC1/U8Lthwakq5IWq2EO9P0gPSqg6npclaLkQCIileiFdd9iwEhIAQEAJCQAgIASEgBISAEBhBBMicSD2K3bt3s+YZM2agIVIKdvr06SPUmEm9iAMHDtx7770tDsev7rpr3eJFHkMkCiNMP/r88+u3bNX4+v71r38lcpyknCPoxpClCgEhMIQERFIcQvgytRAQAkJACAgBISAEBoRAK7nVBmTgYT0ou+ZxAW58WF8VWZwQ6CcCSIrvv/8+tU1Wr15N6PcoCMslgnvXrl0/+tGPxra0PP3wL2ePH99PqM5jmFqL5TfPPvvV7j3NLS0vv/wyeiJR5OfRX5oKASFwYRMQSfHCvv6yeyEgBISAEBACQmC0EGhuaT2cX7s9s7rCaK822+ePC75+YYyvz1AG0w0m2kN5tW9vL25obArW+YyL9puXFhwVpPb0EIFxMC+CzCUEBpYAwc5MMJqyyFGtmwI7DzzwQERo6LO/+Pf0+PiBJeg2Op/BUN/57t/9LjM3Dz3x17/+9U033dR9jWC33nIoBISAEHASEElR7gMhIASEgBAQAkJACIxsAnZHy+cHyp/9NNdidSAstraO4W/FxVPDHr4uPcBXNbL31uPVf5tt/H/vniysbCB2kPhBxMSZ6UG3L4ufEqfzEGGxxxiloRAQAoNMgOrPr7/++h/+8Ifw4OBnfvmL9Li4QUiLyb8TNbW1P/zjYxk5OQi16Ik33ngjpYEGee8ynRAQAiOdgCfl4Uf6HmT9QkAICAEhIASEgBC4MAkgHdbUNT7y+vH13xTXWx1Nza0t6IltXzPHBc1NDfL28hiGZBoam1/cmP+bV469vrnwUJ4pRO8TGaju4zrRVbceqaoxN7L9lpZWUJTVWHccr/Hx9kwM16qGJYc+blm6jwgC+fn5KDVUUBkRq5VFDj4BCqFQpZrvmzZv3nrgwOxJE0MCAgZUVURPrDAYHvzfP2dkZ6MnUuuDB3fpgE46+GBlRiEgBAaBgEiKgwBZphACQkAICAEhIASEwIAQqDHb//jeyT3HaxDUXBNEh/nOmxh8+azIyCCNK/J3f67xha8K1u8u3XCwYk+WISzAJzTgnAT8uPxe/NrZILOkTufrRQPXgP1+wGp3Z9Z8m2Ww2pv9fVWTEwLiQnz7OIuPyrN5bGtz65h6W1OjA611DOqqrbH5RHGdn8YrOVLr5SmaTh8ZS/fzJnDPPfc88cQTlGOmMLGU0D1vfBdGB4Q80heOHz++oLDwUEbGjsOHZ4wfH6LXD1C1FozsZdXVD/31b4ezsvhBuWbNmocffphi2aInXhi3m+xSCPQzAa9+Hk+GEwJCQAgIASEgBISAEBgUAg325h2ZNeiJjiannkh47+wJQT+/Ik3t7emj8iCLosrzbCbB0hrroVPGcoNNaZkaoY0N8fXXnP1VsKTGuiezxmhuNNXZpyYETIwd2D3wp6xT9jvzve+Tabw9r5obvXpGBDSQR1/bVJhbWo9j0VjXuPFgRSwya1pQ32eREYRATwjg/NqyZQvFc0+cOEE5XcoTq9V99eH2ZF5pM0IJIOfp9fr/+q//wipICZqfP/7Xx378wKTkZC/Pfk6Gi55YXFHxH08/c+iMnsikAQNsihyhF0WWLQSEQE8InP09sietpY0QEAJCQAgIASEgBITAMCFgqGt8d0dJY5s/kcDeZTPDH1ibHOLvQzLBjg9yLKK1KeIjr+48UTM5MWByfICrZXPz6QaOplYCh13nR8oBu0ZFVcrRLJsSptN4vbgh/3ihGVUxs8B8PL92WmKAWtXPf5+PFDiyzsEhgHp49OjRTZs2bd26tawMK1h1c3PzpZdeGhgYKBawwbkEI3cW7pDQ0NBf/OIXFLP+y1/+8vDfn3r0B/dPSUlRefXnH+zkT3zslVcOnDhBjZs1q1f/9re/DQ4OHrnQZOVCQAgMOYH+/Ak15JuRBQgBISAEhIAQEAJC4AIhYG1sPlZkxojHfr08x05N0aMnhup6Gq18NK+2oKJhQqzOFRk9mrjhWJyTFmRtbHn164Ks4rrGppYDuSYQzUwKHE3blL0MHwJ2u/3w4cPr16/fvn17XV1dQ0MDZxCJgoKC/vVf/1WqXgyfKzXMV4LAR9llch0++cQTj/zjud/cfdc00iz2k6pYYzI98+67Ow4d9lKpbr755nvvvRcRc5gDkeUJASEwzAlITplhfoFkeUJACAgBISAEhIAQ6IQAVVk+2lPa1BbyjIJ27cKYnuuJDEcSwyP5tQQ7dzL0qDiFIXH+uODkSD8lH9mx/NqjeWYHqRblIQT6lQDOxJycnGeeeeahhx769NNPbTabVqttbGwk0hlh6Oqrr46NjfXs7/DVft2BDDa8CBCGTPHlf3vooTq7/fcvvvTxN9vrGxr6vsRKo/GZ9977aNs3Kh+fBx988P7774+IiFCGLS4uJlS/71PICEJACFyABMSleAFedNmyEBACQkAICAEhMLIJkA+LFIFHc2vZBikUQwPVc88/UeDeLMP88UFxoT2ti8Kk5oam/KqGgkoLgma43ichVBsfpvFTq7qhScB1Za09t8JSUNVAQPaEWP/USP9u2rteQvyzO5qLq60F1dZSg5VtxgX7xoVoWHCnkd2ujq4DMkVOTgo4km8qqbI22JpzyuqRUBPCerpf1zhyIAQ6JVBfX48zEVvirl27ysvLMSQuW7bswIEDmZmZ/v7+Vqs1JCQESZHKG512l5NCoCsCRMpfddVVVPV57A9/+Ps77zQ1N106f75Oq+2q/XeeL6+pef7DD9ETPVQqxMQbbriB21XpZTab//jHP15++eXp6ekif38nSWkgBIRAOwIiKbYDIk+FgBAQAkJACAgBITDcCZDusNrcSDljFopF8ZJpYUoOwZ6sW6P2am52JlWsNNqyS+tnJAcG+HanCSpj1jY4vjpc+cW35Q22Jou9mVBidVsFGD+115UXxayYGtZpALXR4nhja+GhHFOtxUExGYYixWFEkHrptPDu/YKUhMZESd+aWjvTsVNkRI23l9bHMyHS777VSeEBnaeMdCeAgjknNZCaM0iKnDfUNxrq7SIpuiOS494RMBqNyIjbtm3bv3+/xWKJj4//4Q9/mJSU9Morr+Tm5uJPnDJlCq8uXbo0ISFBLIq9g3yB98KrePHFF5PX9o+PPfbc+g/ICYuqGODXG1WxtKrqpY8/+XT7Dn1w8M/+9V8vuugil54IZGy2BQUFf/rTn8jh+OMf/5jC0179FGd9gV9B2b4QuEAIiKR4gVxo2aYQEAJCQAgIASEwegig6FWZ7cp+vFUeFGju+d4oBh0TpS2rsaHWHcytnZkaNCNJ3333UoPtta0FO4/WUDa6Y0sciyeL6+5blaT2PiejTpnR9tLG/K0ZVaZ6BxGgSsdK45j8ioaxnmNtbQpjx9E4Y7I4Nh2pfH97SV55fdM50qNzy3kVlnKD9cErUtOi/LAudjqC62RkoCbY3xs5kvnrGppwWbpekgMh0AsClZWVO3bswJl46NAh7F0xMTH4EBcvXuzr6/vPf/5zz549CIi33Xbbhg0bOMNLUui5F5Cli0KAW+iSpUtxuT799NOvfPZZUXnZzatXR4WEnBefksrKlwnI39GmJ/7sZ0uXLWNY9xFw1P7kJz/59a9/zV2NvPjAAw9MmjRJrLXuiORYCAiBbgiIpNgNHHlJCAgBISAEhIAQEALDkUCbpNiorMzLY2xkkKbnq0RfI8ngtycNSIonCp0FXibH61Se56iB7qPVWZv2ZtV8ua/CbHFwnu4+3p56P2+6K/WjCysbPt1TOiNZPy89yH2cz/aVf3O0mgBteqH9hQepg/y9zQ2OKqP9SLbpjMboPpXzmEDp7NK6NzYXMixPmU7t7RmiV3O+wmClLDVZIA9mG5/fmPefN0/8Tm8mhWvUPp5enh4s1Wx1iKTYHrc87zGB0tJSNBf0xIyMDJPJRB66W265ZcmSJXFxcYzx/PPPf/DBB+iJd911F8VYsH1hMUOaEYtijwFLw04IIP8tXrLEX6ejBvSnO3c1t7Tcunp1dFhYJ007O1VUUfHq559v3PttUmrq3ffcgz+xnZ5IJ5VKxfnf//73WBR37txJUsUf/OAH06ZN8/HpabGvzmaWc0JACFwoBERSvFCutOxTCAgBISAEhIAQGDUE3F2KRBxjxDuvrSVH+FWhJxbXWaxNxwrNM9OCErvOMEj+wY/3lCl6IvLcnHFBa2dGcsCZD/eW7jthYOraesermwsmxwfotaelSSyKe0/UmOqdeqK3t8flc6LmTwgmwpqI5uNF5o37y7NLnLWqOz4qTPavj1QVVTn1RI2P56z0oNUzI3S+KjI5Vhhtb28vPlVUhxy594ThUJ5pdmqgu4jZcTTOaNVerBZJsd7aVGd1qqLyEALnRaCoqAiphceRI0fImajT6dauXbt8+XJCRMl2V1NT89prr7377rtYce+55x5e+t3vfocuc91111Gn5bwmksZCoCMBpL1Zs2ZhJHzzzTe3HjzIxyw3r1oVGx7esWW7M4Xl5a9/8YVTT0xLw3s4Y8aMrlRCzuO0/fOf//zb3/529+7dzc3N9913H5OKx7YdUnkqBIRARwIiKXZkImeEgBAQAkJACAgBITCsCSApVtc6o4CJ+8WIRzrF81ouEcozUgKP5NViUTyUa5pXXNeVpGhtbCbfInHNjO/pOTY+XHv3ysT0aGd9FWyDoXqf/PKGapONp8fyzNll9dMS9ayHp7tOGsoMNtpwfNHE0MvnRqVF+yn5FlOi/MiNSC5IxcBIA/dHmcGKtxHR0MvLIyXG/+5Vic4AZ8yKzmotLYH+3g+/eLTR0Uzc9I7MmqmJetV3bd1P44U0WWdxWG3NfLnPJcdCoHsCJSUlxDJ/8803hDmXlZWhsCxYsIAMiQsXLoyOjsbehZ6ImIjW43A47rjjjiuuuCIvL48EizSbPXu2h0eX5t/u55VXhYA7AZIbcjtRs+Wpp57acvAgUcnXL1sWHRrq3sb9GE3wREHBGxs27D56DD2RRJ907z5DIvfqihUr+E5SxX379qGJo4/PmTOno6vRfSI5FgJCQAiIpCj3gBAQAkJACAgBISAERhgBpDprY1tawLF4VsZ+V0bBTnZHnPKWw755ZRasf6dK6+akn67+2a6pxdZUXNPgcLRw3l+jWjw5VNETeYo+iC1x2fSwt7cUogBiA8wut0yM03l5OkW+kyV19TbnCgk6Xjg+ODFC66rfEqhVIWhSs6WjpEjmRE4qGmWgn2rVjPBxbfIl4/AgC+Sc1KApKQH7TxiY8VSppamZhX2Hpujt5aFqUzkJmuZLGUq+C4HuCdTV1aEMkhIReaW4uJhYZmxcc+fORZpJTEwk/RzdDQbDRx99hEWxoaHh1ltvvfHGG7ElfvHFF1SCvvLKK5U23c8irwqBHhJAEBw3bhyy9V9Npg2796BuX7V4ccSZqs3ugzTYbAdPnnz36027MjISU1KIYkYZ7F5PdHWnZDmh+n/729/Q0J955hlSK86fP1/Mti4+ciAEhEBHAiIpdmQiZ4SAEBACQkAICAEhMKwJkD+ReF6WiLLW0tKKF/B8VcUQf59xcTqMirgdjxaYT5V2Hobc0Nhc2WaHZC4/tSdCpDsXPFiLJoa8s6WodYxTqish12GbLZFjV6bFIJ13RKCa8tDuHaMC1RF6tfsZ5djmaK6pb2RTPIho1mq8jhTUujdjfJ8zvkSKtLB391c7Pcbb2NjkbOblNZavTtvISSHQjkB1dTV64pYtW8iZuG7duokTJ06fPp20idThVVriT/z4449fffVVxEfExJtvvjk8PBzxkS5paWnYGNsNKE+FQN8JTJ069e677/7HP/7x2Y6dtkbH1UuWxIefk1exymjaeuDAx998cyw3Ny4hAQkSHbyHeqKyPHKAoir+3//9H5I6E6EqkmkRSb3vi5cRhIAQGJUERFIclZdVNiUEhIAQEAJCQAiMZgIqL48Q3enc+U0trQ32Jr82hbHneyaSeFZq4L4sA5LiqZK6rGKzp9c5qp8ylK2R0tKn68BQWjoy8BwdEItkXMjZ4qFlNVZXgWYyLSrHgTpvyrm0Wxh6aKeVVRrszoBopTF1nz/aVdouVSLp6nLLLYrmWFvf2ANFcQzlZajowpi+THqelNotW55eOASQDufNm4c4mJycHBsbS85Ed68WguMnn3xCiWej0UjOROq0REVFWa1WoqSRGvGFhZxnWd4LB6zstC8EEAeJqefHIJLfFzt3VlRXr1kwf1pams7X197YeDQ3d+PuPdsPHy4oL+fWvfPOO3EdnpeeqKxt0aJFZFdELt+2bdtzzz1HGDVnSCHal5VLXyEgBEYrAZEUR+uVlX0JASEgBISAEBACo5YAwbyhutMlWXDqIcOdr6QImuQIbXKkX0ZebX1DE6VaAvw6qfGCK1Ap60x7EhqiKp7DdOwY5xmcf21mQfRHl2mQWGmneXLMGJbasZo0+RbJzHjOUG1PqMHicMYyOx8NtqaDp4zKcaffFWGx05fcT1ptTfZGp6SIjkleRfeX5FgIdEUgKCho1apVZBXoWNGiqqrq008/RXBBT7zqqqvQE9EcGYd45w8//DAlJeXSSy/talg5LwT6SACJUPHAvv766zsOHMgvKZmckhyk01ltNiTFjFPZjpYWKrHcdNNN6Im9jr4nVlqj0ej1+s8++wz5ktSKFDcXVbGP1066C4FRSUB+rxqVl1U2JQSEgBAQAkJACIxmAuh07i7FcpMtoeuSzV2BUKs8JyUE7DtlPFVcd6zAHNBZ2Wgm8j8jwyEvUjQ52F15bB3jrAR9RkekdopLJ0RqJMUjqiJxx65o6K5W4jpPUDOZFpWnODEjgzUhAZ0InUoDP42K5bn6dnqAUxKhsy3l4hh/Xy9/39ODd9pYTgoBdwKdlrtV9ETyJ5JIkWIspFCMj4+nl91uP3z48LFjx2644Ybg4GD3ceRYCPQvAUVVJBh5/fr1GzduPPL5Fz4qFV5Cu8OBCHjx/PnXX389ORDRBPsy7+TJk3HmMuDbb7/9wgsvULmFdKK91ij7shLpKwSEwHAmIJLicL46sjYhIASEgBAQAkJACHRCACkt9EzgM5rdgRzTvLTO66t00tnt1JSEgORIbU5JfYXBVmvB3XJGHTzTRuPtERpwOsKa6s8EHceHno10xlSYWWI+03ZMVJDaVYNF5+eNFRHbosFsR9RztVEOMBh26jHU+niGBZyOraYYy4QE3WWzI9v1dT1FEv3OUtfFNdYqs12ZC21Ud0YedQ0iB0Kg5wTc9cTLLrsMPZFSLUp3s9lMKDTHhIj2fEBpKQR6RwBVcebMmYTnx8TEbN269eTJk42NjcmpqRgYV69eTcrFXsQ7d1xJUlISNznSJBr6iy++SFlzvIoUnu7YUs4IASFwwRIQSfGCvfSycSEgBISAEBACQmCkElB5jQ3y91b7eNrszUT17jpec9slcf7nnygQXTI9xn//KWOVyW6xtpWQPheJr4+Xq46KuaFpR2b1ogkhaIVKq8amli/2Vyi1WTiD2kh9Z+WlUL0PRsVGR4upzlFc3UAlaPfkiWarQ6kHfe5sY3AmBmhVyr4cza219Q7iuxPCtO2a9fzp/mxjbtnpyjNUpHHpsD0fQVoKAYVAZWUlQaBoK2RLXLt27W233UaaReUlLIr4E/fu3cuZSZMmCTEhMDgEiLKnKBAC4tGjR7kJEbgpIkRaz36cnSyixFCrVKqXX34ZryLFzVesWBEaGtqPU8hQQkAIjGgC3xEtMqL3JosXAkJACAgBISAEhMCoJEBaw2B/7ylJzuKzhBWX1TTszzH1YqcUaZmeHJgW7d9VX3TA+DBffVtMtNXe9O0Jw8ZDFRROYVLKtnz6bdn+kwbFA0ib1Eg/l9o4JT7AX+OMMiboeNPhysN5JltbQkPO0H3vSUNWSV3HSZEqMUVOa6srjVR6NNf02pai3VkGo1slFoyUdbYmQ93pwtAdB3GdqW1wHCuorTDaOEPUc1KkNuyM49LVRg6EQE8IICN++eWXZK/jABcY1q3U1FRXx9ra2i+++AKjolSxcDGRg8EhQCQyMc733HPPAw88gNLdv3qisgVinwnnp9gL9znC4kcffVRWVjY4u5NZhIAQGP4ExKU4/K+RrFAICAEhIASEgBAQAu0J4FJcPSvywClTU1MLkcXrd5akR/m1q8jcvk9nz5PCtanRfgeyjUpZ5HZNiLBOivCbPz74871lSIeVJvuzn+UWVjYgaJYZbZ/sLcOHqHRZNj08KkXC3UAAAEAASURBVFjjCnyekxb4+be+lJOmusu3Jw0UbiZoWq9VtbSMKTNadx6vyS2ztJtLeRoTolk7OzK7tL7aZKdY8xd7yziemxYYGkCgs9MdiZpppJx0S+sdS+MJju50EE7am1p2ZtacLK5TCk+Pi9OROLKb9l2NI+eFAErK5s2b33zzTQKfKb2Cnpienu7CQsBpdnb2jh07CAilGq/rvBwIgVFDAOESVZF0ii+99BKFzm02G4lEibkeNRuUjQgBIdBrAiIp9hqddBQCQkAICAEhIASEwJARII3g5PiA1Bj/zPxaBLYDJw1vbSu6ZmFMbMj5peRHZUNuiw/Xnig8mxXRfVfhep/VsyKyiuuIICbZYlmN9YUNee4NOB4fp7tmQbTGTeAL8vO+eGpYicFaUmWl145j1bsyawiF5pjVUllFq/ak0nT73I1jxrAvMjxeOityw/7yKqON2Orj+bV8MYuiVyrFXnx8PG9YFNOVREjax71ZBmTWvHKncKnx8ZyepE+L8mu3bHkqBL6TAHWct23bRrxzSUnJypUr0RPHjx/v3stkMn311VeojcuXL58wYYL7S3IsBEYNAUq1oCp6enoS/szbgQjo6667LiEhYdRsUDYiBIRA7wh4PvLII73rKb2EgBAQAkJACAgBISAEhpAAiQv5QjtDp0NoO1FktjW34CtEUGNVyG3ER7uWd6Kk7lCOiZLNWrXXkslh7sqjn49XYXVDVkm9EsIcEuAzPVmPe1Hpi5AX4KsK0nmTS7G2oQlB0DUmB1qN16zUwFuXJ0yK03meybGoNIgJ1lDuxVRP2kSKkbYyOIZBNETKLs8dF6z3U5UZbDwPC1TPSAmMCzlb9cVX7Yy2pvpzc3NLvb2pqUlZl7Oiy+kjvIrNrdcuitH6eLltcUyDvbnSbC+sslLG+vUtRZmFZsiwmAkJAatmRbh25L5+ORYC3RCwWq3YDylMkZOTQwq522+/vV2qRO7s3Nzc5557zsfH59577x03blw3o8lLQmBEEyCjIno61Voobr5//37eHRgVg4J6UxlsRHOQxQsBIeBOQFyK7jTkWAgIASEgBISAEBACI4YAiQ4Xjg/aNT4YDyASG4Ldh9tLDmSbSBqYHK69aFJomltyw8ggzfxxwSQlDPDzDtF5u2+S9IVz0oIoz6LIhdGhvuH602WXlWbUSl42NYwyKR/vLas02pAsiXdGskSdDA1S37QoloBrd2nP1euWJXGRQep9J43VzrrPzaiTdIkO1SyZFFpaY/X29EAJTYzQYml0Xw9KKAPevCSWVW044PQqEtnd0Ih641QzES5xMqKcunfhmMDtbUerjhaac8ot2cV1dRaHYoEkHHvFtPAJMbp27eWpEOieABHN+/btI9IzKysLByL1WNrpiXRHVTl+/DgGxmXLlpHSrvsB5VUhMNIJeHt7X3/99XgVn3nmmbfffhsPL2kc3fMAjPQNyvqFgBA4XwJjnR8Zy0MICAEhIASEgBAQAkJgBBJoaW0trrY+/uGpYwVmU12j+w6uuyTu/lWJfudfBtp9kI7HFGJGHyTLIdZFqp10VBI7duGM2dpUa2mkoHOg1luJVkaXtDlaSI9IikRXUZdO+/K7qsXeVFlrt7flbaQ7mRx1GlW7qfMqLL9+5eipktP1nRnKy8sjOlhz1YLolTPC6dLp4HJSCHRKAAH7wIEDTz755MGDB5ELv/e971FXt2NLxMS//e1vu3fv/o//+A9sjB0byBkhMPoItLS0rF+//u9//3thYSFq+49//OO0tDQ8jKNvp7IjISAEvpOAuBS/E5E0EAJCQAgIASEgBITAMCWAoS82xPfhG8a9tb14X6ahuq6xtr7R0dSK1EhpFCXtYP8uHREQC2Fk4PmNqtN48eXeB6chX+5nujpGOkQY/U5tlJotbJxIbw/Psb4+XoF+qphQ3zWzI/BmfmffrqaW8xcsgRMnTjz99NOoikuXLr3jjjs61RNxZlDlOT8/f8qUKUuWLLlgWcnGLzQC1Gm55ppr0BDR0zds2FBXV/fggw9OnjyZmOgLDYXsVwgIgXN+txMcQkAICAEhIASEgBAQAiOLAIpbiL/PDy5NKpwZufNkzdG8WnO9o6m5BeHPVX95ZO2od6vF6pgW408hbLWPZ3SIZlqyfnqinpDqdmbG3g0uvS4oAmROfPzxx/fu3XvJJZfceeed06ZN63T7SIpEgFKShZBnAkI7bSMnhcBoJbBu3TpURd4pu3btolrLAw88MHfuXD8/qYI1Wi+47EsIdE5AAp875yJnhYAQEAJCQAgIASEgBEYWAUKkRUAcWZdsGK62oKDg0Ucf3blzJ3ri3XffPX369GG4SFmSEBgmBDZu3PjnP/+ZfKPEPt933328awICAobJ2mQZQkAIDAIBqfg8CJBlCiEgBISAEBACQkAICIEBJyB64oAjHu0TFBcXP/LII+iJBDJTwVn0xNF+wWV/fSWQnJwcHR2NpMiDUkVarTYuLk4ioPuKVfoLgZFDQCTFkXOtZKVCQAgIASEgBISAEBACQkAIDAyBsrKyhx9+mCjOxYsX33///aInDgxmGXW0EUhMTIyPj0dSJGMAquLYsWNTU1NFVRxtl1n2IwS6ICCSYhdg5LQQEAJCQAgIASEgBISAEBACFwaBysrKn//853v27Fm0aNGPfvQj0RMvjMsuu+wfAjgTk5KSTp06lZeXh6pIasVJkyaJqtg/cGUUITC8CYikOLyvj6xOCAgBISAEhIAQEAJCQAgIgYEkYDAYKC5BPZYFCxZQu1b0xIGELWOPTgIxMTGkU0RVJBspBdMrKipmzZrl4+ODaXF0blh2JQSEQBsBkRTlRhACQkAICAEhIASEgBAQAkLgAiVgNpspw7J///558+ZhVOyqvvMFSke2LQR6TCAyMnLcuHHZ2dmoisRBZ2Zmzpw5kxrQHh4ePR5DGgoBITDCCIikOMIumCxXCAgBISAEhIAQEAJCQAgIgX4hQITmbbfddujQodmzZz/00ENTp04VU1W/gJVBLkwC4eHhhDzn5uaiKvLYvXv3lClTQkJCRFW8MO8H2fWFQEAkxQvhKssehYAQEAJCQAgIASEgBISAEDiHQGNj47XXXnvkyJEZM2b88pe/xJ8owsc5gOSJEDh/AqGhoUjz6In5+fmEP3/99ddYF2NjY+XNdf4spYcQGAEERFIcARdJligEhIAQEAJCQAgIASEgBIRAPxJobW1du3YtpSSQP37zm9/w3dPTsx/Hl6GEwAVLICgoiISkRUVF2BUtFsvmzZsjIiLGjx9/wQKRjQuBUUxAJMVRfHFla0JACAgBISAEhIAQEAJCQAh0QmDVqlWkeyNI89e//jX+RC8vr04aySkhIAR6RSAgIADzL4XUeZfZbLadO3fyFiO1Yq8Gk05CQAgMXwIiKQ7fayMrEwJCQAgIASEgBISAEBACQqDfCaxcuZLStMRj4k/ETuXt7d3vU8iAQuBCJkBOUp1Oh/nXZDJRp8XhcBw4cMBoNC5atEjSlV7IN4bsffQREElx9F1T2ZEQEAJCQAgIASEgBISAEBACnRNYsWIFRWlTUlLwJ2KbUqvVnbeTs0JACPSBANIh5Z5RFSmClJGRQepStEWkfEzBnO9GWKRc0quvvsobkxLSfZhfugoBITAYBERSHAzKMocQEAJCQAgIASEgBISAEBACQ05A0RMTExPRE6nyrNFohnxJsgAhMFoJoBtqtdrJkyc3NzcjFDY1NVGzBXkRQZ8qLl0VbCFK+p133qG0C+/T4ODg0QpH9iUERgcBkRRHx3WUXQgBISAEhIAQEAJCQAgIASHQHQFFT4yLi/vVr341b948X1/fbqxS3Q0krwkBIdAzArzFeKNNnDiR9ALffvst2mJ5eTkHOBApA91pTSTeoaiKlIomISPiI917NpW0EgJCYAgIiKQ4BNBlSiEgBISAEBACQkAICAEhIAQGjQD1nanHQrxzdHT0ww8/vHDhQsxToicOGn+Z6EImoKiK6enper1+x44dLS0tJFjcvXs3yRZRDFUqVTs4iI9Wq/XEiRPHjh2LiYlJSkrqVHls10ueCgEhMCQERFIcEuwyqRAQAkJACAgBISAEhIAQEAKDQYAkbmvXrqXyLMYo9MTFixd3n8ptMNYkcwiBC4mAoioiIPIe3LZtG6qixWI5cuQIB+PHj/fx8WkHIyQk5ODBgzSgWnRCQkJUVFS7BvJUCAiBYUJAJMVhciFkGUJACAgBISAEhIAQEAJCQAj0MwFKQ1x77bXHjx8PDw//xS9+sXTpUtET+xmxDCcEekAAVZGKK1gOiWveunUrYiLvTYT+2tpaVMV2WQhIclpfX5+Tk3Py5ElipePj4yWpYg8YSxMhMAQERFIcAugypRAQAkJACAgBISAEhIAQEAIDTQC14vbbb8frhOnp3//938ml6O/vL/HOA41dxhcCnRJQVEVch9gVURWp1oKqmJeXR3ZFREPCol0FWzhAZOSdS4Xo4uJi0hSkpqZKUsVOqcpJITC0BERSHFr+MrsQEAJCQAgIASEgBISAEBAC/U/AYDDcf//9+/btCwwM/PnPf75mzRrRE/ufsowoBM6TAGHOCIhIhNu3b7fb7Yj+HOAjJrqZMtBeXl7KeLiJjUZjbm5uZWUllkbsjfQ6z6mkuRAQAgNOQCTFAUcsEwgBISAEhIAQEAJCQAgIASEwmASqqqp++tOf7tq1Kygo6MEHH1y3bh3VY8WfOJiXQOYSAl0RoCQL4c/EOyMm8la97rrrKPG8f/9+optJtkh5FjpSkgVVkdjn/Px8Ph4gFBpvI+/irsaU80JACAwJAZEUhwS7TCoEhIAQEAJCQAgIASEgBC4UAmRDKy0tfffddzdv3ozziCquHcu89iML4ih/9atfUQWCUMof/vCHV199NQf9OL4MJQSEQB8J4EbEdYiq+Nlnn1VUVPAmxVC8Z88eykBTlp2si4yPpEhkNEZFGlCnBRUyLS1NPhjoI3npLgT6l4BIiv3LU0YTAkJACAgBISAEhIAQEAJC4CwBtIDdu3c/8cQTGzZsoIprRkbGqZMnU2JiAoKCBkIdQLt89NFHv/76a8Kc77nnHgxQGBXPrkaOhIAQGB4ESJhIXkUioPnJgFdx4cKFR48ePXToEJHRfOpA5kRkR2yJJSUlqIp8FMHnEIQ/S52W4XH1ZBVC4DQBkRTlVhACQkAICAEhIASEgBAQAkJgQAhgMtqyZcuTTz6J/6jJ4UiOilSNad136FDmyROqltbE1FTCG/txYio5/OlPf0KhoJ7DnXfeeeONN5KdrR/Hl6GEgBDoRwJ8qICqyAP/MqrixIkTiXQ+duwYaiNeRT4V4I3c2NiYnZ1dVlZmNpv5eCA9PV2JjO7HZchQQkAI9JqASIq9RicdhYAQEAJCQAgIASEgBISAEOiSQE1NzVtvvfXaa69lHj8+NS3t7ivWrV6wYO6kSaGB+g3fbM88kTm2pTV9/HgvlarLIc7nhaKioscff5w4StKu3XbbbTfffHN4ePj5DCBthYAQGAICSIoENeNlrq6ujo2N5YOBzMxMSrKgKlJbCRmR86iKGBWRIDEqUshlCFYpUwoBIdAZAZEUO6Mi54SAEBACQkAICAEhIASEgBDoAwFUgHfeeefVV18tLS5ePnfunesuXzpzZmx4eHRoaEpsbFhQ4I5DhzOOHrVbrckpKYiAfQyCLiwsfOqppz755BOysN1000233nordR76sHzpKgSEQP8TQCh85JFH8Czz84HReeMTzsx7n7yKCIUEPnN+xYoV1GMhSYLD4SACmvP0QlJEaqyrqyMUetKkSQRH9//iZEQhIATOn4BIiufPTHoIASEgBISAEBACQkAICAEh0DWByspKirHgTzQbjeuWLL51zerpaWmeHh70QD7Q+PikxcXp/Pz2kjrt8GGr1ZqalkaEY69VRfTE55577oMPPkBPJHni7bffjr+p69XJK0JACAwNgdbW1ldeeYX6zkeOHCHAGd2QNy8CItHNEyZMwKKYlZVlt9uxItbW1qIwWiwWJEU8jCaTCVWRlkQ9U6RFPjAYmusnswqBDgREUuyARE4IASEgBISAEBACQkAICAEh0FsC6Invvffem2+80WS13nTpquuWLU+NjW03GCkUqdCi1fgeyso6eOQIauO4ceOwLLVr1pOnBQUFL7744vr169EarrrqKvREBIiedJQ2QkAIDD4BdEPeoWRZPXXq1I4dO463PVAYMSFS7hlbIlHPxDiTBRWdkWO0xZSUlLCwMIq08GbHusjx5MmTKd4y+IuXGYWAEGhHQCTFdkDkqRAQAkJACAgBISAEhIAQEAK9JFBRUYG69/Zbb411OG5YueLGFSsiQoI7HQtVEanRV+1TWFZ28PARtUaD1nC+EdBIDJie3n//ffSFK664Aj2RvGydTicnhYAQGHICOJFxHVKGJTk5GbMh5Zubm5vz8/PRFTEtYlHElsh7GesixVj8/Pyo04I5kWhoCkMT7IwKSRUXzMhYGkNCQoZ8O7IAISAERFKUe0AICAEhIASEgBAQAkJACAiBfiBQXl5O9PG777xDZsTb1qy5bNFFgf7+3YzrVBXj4kL0+pyiQspA22w2UqqhI/QwAhrdgdhqHJHoDmvXrr3jjjuIl+xmOnlJCAiB4UCANz5OQ4zJaItohXwMgD9RqeyckZGBmIjOyA8TDjjv6+ubl5eHqkizpqYmFEa+o0uSUbGHPyiGw5ZlDUJgtBIQSXG0XlnZlxAQAkJACAgBISAEBopA65gx9sbm7HJLfmVDfqU1p7w+q7S+3GSvqXPYGpttjpbm1lYVsaxjxw7UCmTc4UfAXU+8/bK1l1200K8Hgcxenp7JMTFBOt3uw0e+3b+fVIs9VBXRE19//XUyNkJi9erV6IlERw4/KrIiISAEuiTA5wcEQU+ZMiU9PZ3PAzAtIiAS6YzZGYWR4GjqsdCGR05ODhkV/P396+vreZUz06ZN43uXQ8sLQkAIDAqBsWRIHZSJZBIhIASEgBC4QAnYm1p2Ha+pMdvZf1y4Nj3GX6eR9DcX6M0g2x4FBOyOlsLqhpIaa3655URJncmChthidzSjJAb4qvx8vUP8Vb4+nv4aVWiAd6C/t17rrdPynZNeaq+xns76HPIYhQQUPfGtN98k3vmOyy+7askSb5XqvPb5yqefvfDRR44xY26++eYbbrgBFxLew65GcOmJuJkuvfTS733ve0gSXTWW80JACIwIAlRfIbSZIOhDhw5xwNscSZE4aD5mICVCSUkJGqJiWuT9/pOf/GT58uUjYl+ySCEwignIH3Wj+OLK1oTAgBAwNzi8vTx8VJ5iPRkQvt0OWm9rqjDZjPWOWoujwdbER0JqH0+dr0rvpwrV+QT7e3fbe8hetNqb39hamJFXywpWzooI1nmLpDhkF0MmFgK9JdDS0mpqcOSUWQoqLYdya0+W1BWWW9wH0wdomlpbDBZbYZWN84iMLc3N/r5eoQE+oQHq8EBNCN/1PhF6p+aI+Oij6lItch9WjkcEAUVPfPPNN1tstmuXLVs5d+756ols86pLLq4yGddv3oL3kKfXX389VZs7VRXJn/jGG2+88847LS0tq1atIn+i6Ikj4j6RRQqB7gkEBQXNnTt3zpw5iImkVty3bx/lWYh65qleryeXIqoiCiNx0zgWSbwokmL3POVVITAIBERSHATIMoUQGCUEGuzNh3JNWSV1Gm/PCfG65Ag/fCijZG/DfhtNza3FNda9WYajBbWYgyqMdmNdY2tLq5/WK1yvjgrWJEdopyXrpyfqVV7D7q90pM/mlla+wNzYjC4x7HHLAoWAEDiXAM7EvArL7pOG7cery432Okujzd7sauLrqwoN1KYnhflqvFyZrRqsjto6m7nOZmxoLDGYbScMBLTq/bzjQ9XxoZqYYE2Y3icxQhsd1JsKv66p5WA4EFD0RDS+BrP5mqVLr1u+rPv8iV2t2d/X9/a1a831ls937iRDIvfSjTfeiFexXXumI3kieiL+xJUrV952223jx49v10aeCgEhMHIJ8N7HlsjjoosuInMiwuLOnTsPHz6Mh5HPGAiIZmu8/bExEiIdEBAwcncqKxcCo4CA5FIcBRdRtjBkBIqqradK6/mOxOP+VW60GTGR2Zvx8Q1EJimkGUdza3MzglIraaoGzS14KK/2iY+yvzpYsSvTUFPXmBrtF6LzGTL6F9LEFlvTsSLz+ztL3t1ekllgrjTasSiizCHV2RtbasyNhB/iATxVZuFP9Pgw7XBjQ1DkxoMVlSZn4HNSlN/05MAgv2FqqBxu6GQ9QmDICfCTprah6UCOaf2uki0Z1R6eqoRovYenh7nezk8hLy+PIL3vpLTwmZOiU+KDwoK0IYG+yldkqH9iTGB8VGBkmH9okB8eRv5BRGcsKLcczDbuOWng3xRCoVMi/YbhByFDjn0ELcClJ9YZjavmz792+bKoPpRh1arV4cFBNbXmXDxKmZlYlhLaAh5dQMit9vnnn6MnOhyOSy65BH8iJRpcr8qBEBACo4kAtsTIyMiZM2dSHpqSLNR6pmCLqu1ht9v5Ewgjs2RQHU1XXPYyEgmIS3EkXjVZ83Ah8HVG5cb9FXg32i1I5TU2yN+bUC98fBPjdMmRWkJT+zFB/cFcE6olkqKv2nN2ahAJqtotYICe7soyVJpsisdsX5Zx3VxbWrR/P+5rgJY90ofFn3g4v/afXxfwR7iS/Fbj4xkc4OOvJvBjrLmhqdpst1ibaJZfVv/ZvorFE0NH+pZl/UJACAwTAvwDp/ijNx6srDI7EmKCYsP9W8d61tY7NGoil73CQ/2S44MnJId29W+BRu2lUfsjL7KjBpujorq+uAK1yFBZU19Wbd2eUU3Shhkper4Pky3LMs6LAEUSqO9MnHKdybR6/vxbVl+aHB19XiN0bDwhMfGuK9ZxfuuBA2++8YZGrSZVYmBQkNISSRFZISQkZM2aNcuWLZs8eXLHEeSMEBACo4wA73Qqt0RERFCOidLPpFOkOnxeXt6mTZv4+TDKNivbEQIji4BIiiPreslqhxeBMoOtqLKBkpcdl5Xbdgr/4IT4gMvnRS2eGNKPee5e3lRwMMvoaGoJD9b88Q7NoEmKvt6enh6n/2wk5Bk9q+PG5Uy/EygxWDceqDhwysjIFE9Fqp6eEjg9VU/YIBHo1Fo9mGPam+ksfkII4SVTRE/s9ysgAwqBC5RAY1MLCRPX7y7NKKjT+qrTkvRBAZqTBcaCUqPKyzM2Up+SEJwcE6j26ekvk75qFb5FviJC/A5llpVV1h3OM1WZ7WvmRC6fFhahV0t2xZF1q5HL7P333yfe2aknLlhw6+pLk/qsJyoEzqqK+/e/8MILePJXr1kTGBjIq4iJFHeeN2/euHHjJOBxZN0wsloh0BcC5EC47rrrtFrtW2+9ZbFYJkyYgFsR92JfxpS+QkAI9J1AT38L7PtMMoIQGMUEEHoC/VTobeyRX3yJSqYeRSP/ax1zLL+WShpeHmNXTg/vrz+WEBMVt9ogI106OZSAtRPFZpWHx+xxQXFhvqIpDvQl4E968id+26YnEt8RGay+ckH0FfOiA85UTJ4Yq1s4LviTcN+9mYa18yJXTQt33oRjxlBFR8ld6FohxRBQhLl1KM9qsTVzE3l7jfVXq7Tqs0qx0rjO2sQXgjjXd6zHWCrxoF2qe1aQhzuzwd5EGRkC/xGdCXDW9FhuYMX0sjjfOy0sFdla6+Op9pZ8na5rKAdCYPAI8C9YTrll/a7SHZmG9KTQ+Ch9Zm5VRlYFPxYiQvw5kxITqNH00iOfGh8cqNMcz6nKKaypNFnf2lqUX2FZPTNickKA/5kfboO3VZmpVwRqamrWr1+PP7HeZFqzcCH+xP7SE5XluKuKL77wAiexJerbVMW0tLReLVk6CQEhMLIJhIaGXnHFFf7+/pgTiYa+8847R/Z+ZPVCYFQQEElxVFxG2cRQE0D1WDM3ijq2LAQdx2xtKq5sOFVSX26wIo4UVzXsPF6dFu2XHu2M/Bq5j6QI7YNXph7Jr/VTe46L1ul85QfIgF9MQg4P55iqjM7yqTqt16qZETcvjmvnD8WmesNFsSumhlNKVVkQQfGf7ytH2nNf37q50Yh0OWX1e08ZKbPQ0Ngc5KdKifCbkhiQGK5FNDzdt6X1QK5px/FqhHIydRLFj3wZGaiJDFIHaFWUgummJo8dT1NxXW55PUpEcbVVq/aamazntgn+rpBGorYram255ZbCyobCamtNnZ0Ma7HBmvgw35QoP/yYFBl334scCwEhMKAE+MihsKrh4z1l247WhARpm5tbvtqZ3dTUQpLE8SlhyTFBftq+pkNlqHlTY6LDdUdPVRSWmL46UJFbWn/1RTHzxwVFScGWAb26/TF4fX39p59+Sn1n8ieuveiiW1avTopuX0Sl7/MoqiL/EhEB/dKLLyJnr167lqqvfR9ZRhACQmCEEuAnwLp16yj0PHi55EcoKVm2EBgsAqIIDBZpmWdUE6DG5dpZEegyrl0iLH59pOqfX+efKq7Dt4UMd7KkvqOkiJsMMcXW2GxtbMaihYtM7e1BBvuOuepxb1GPw2k/a+vSZkSjbwt2MPxornmVAyROlwSDzY1kWM5CHmceXp4eqEI8x+2IGU3JBcm8Wh+vdj5KKvNSGMS9r7fn2FnJzt/mUbXYoysO+szY7f/P36UEhlsbW1iGh8cYnG5IV+1moQ9DWdC/2tbI3rsyxKGC8Tdt2+weDNJxdqYDJsVAup+u/SqH8fNjhWYKs7BAPIPj43SLJoW00xOVteMgdOmJnOHGePazXEq4uO9sfFwAIuMzn+YUVVrdr+nMtMDvr0yclqTHS0t7bsXDOcYPd5S49+XYx9tzYkLAlfOiusp6xi26J8vw2DsnTJSiPnO7bdxXHqjz/sFlKWjr7QZ0PWXG7DLL+p0lVP5pl0bAW+UxKVF/54qEKfE6sSu6iMmBEBhQArx/y4z2T/ZVfHmw0lvlSf7cY1kVwYHaCalhqXFBAf7q/pqdwZNjA0P0msyg6oyscj7wePKj7CN5oXevSowNkTLQ/YW5/8ch5HDLli3UXDZUVl6+eDH+xMQORZn7a1ZUxfuvuUbnp92wa7cSAb328ssl3rm/8Mo4QmAkEvDy8tLpdCNx5bJmITAqCYikOCovq2xq6Amgdi2bEnqsoLaoqsFqayb22WxpL/yhITpr9VY25FdaCiobqKFM9HR8qC8Z8ZLC/UiZdyZvoXM73xyvJlmeotRUUyOlTbIx1zu2Hq2i6nS7Dc9KDXTJl4x/KNeEeuhqExWsXjA+BL0ps6ju22xjucnpgIsL8aWSzKR4nXspXsK3Nxwo71h/hvYRQerpiXqq0LiGbXeASkiALT4XwtnyqxoqTHZUy/gQX4TX5Ei/iECnbKh0YSt1tqbPvi1TdocbbsG44I76kc3RQoXQ0horvUL1PlPiAxjENSnTUWUbjxsw2XJlLdN5JoT6JoT5tpvO1WVEHJjqHZRBYKk+Kk/qomIO7dGyx4719/VSdEObvVnR9/LKLZ/sLS2ptiJKIiuj8QGN0fZnGXECRgdrItt4ogxyxRF2uRz859Sx2y4MYt+BLENOad3auVH3rExs51VkqB2Z1Y/88zhqJmMigMLf03Mss6AwbjxYzhXpdOWo3RkFtS9tzGcZSkdPDw9FsGYouh/MMnDD//TqNO6KTkeQk0JACPQvAVODY3NGFT+THY5mfhRYGuyT0iMmpoZFtZVY6d+5GA2Ncuq4cH5o7DlchH1644Fys6XxlzeMDwuQgi39DrsfBqQ6Cnris88+m5+Tc8WSJbeuXp0QFdkP43Y9RHJM9A+uuUbjo16/efOLL76o8vK6/Ior1BoRnbtGJq8IASEgBISAEBgsAiIpDhZpmefCI4CqGBPiG+jnY7U1OBxOcQQBx10lRGR5c2vRu9uK22VGpI7zqtmRD16e4opFBd4LG/MLyyztWiIU0r0jWvQXVy3m/aeMT32cjWvP1Wx2elBShN/+bONf3s9iVa7z1BH+/urE2y+Od50xWx3PfZaLMug64zqYkhwYHqDuRlLE//jpt2UvbsxvsJ7jlcN3NjUl8OEbxkXpzwqCbOTvH2Vj2GT8sCD1pAcDOkqKqJNvbS08mG2iTUqM//1rktwlRYLNP95T+srXBR2nm5EW9Ivr0iPdpnPtYvgfWG1NCLusU6dVhZyrMnezeLJ6zpsYkl9uoc3RHJMiHRLOXGFwFgoPDVFHhmhyi+sUsZI2vDR/fLAiKSIg4rrlKnDPcF2Y3d62AGU6unyTUTUvPWhu2unim8p5pnjxqwKiI5WnSJbpyNP+3rlllpLKhv0nqVWtCJvK62e/I1/uPWE4eMp5WXk405LqvEMD1XUNjtKqBlZLtzKj7d0dxSIpKojkuxAYaAIHc2v5cWqqdX7a5KvxnjM1dlJKmNdAJh+geHRaYojBbD10rJR3Pb5+qpD921WSL2+gL3Vvxs/IyEDXO3LkyGWLFl2/YvlA64nKEkP0emq/GM3mj7Zt+3LDhnHp6ZOnT+/N6qWPEBACQkAICAEh0K8EJDtVv+KUwYTAuQScBS5OW/HOfWHMGJQUYz1VMs6R25RGiChUz6g02RUrYvuefX7O+Dj+zA1N7TQeztc1NLn7GXs9FXn9ncZMpnAqQuc8OGF3NFfX2t1VToQkV6w34hTaYvtuEGtCsDp9mqhnRCvXuPg9u5mOUOhqc2O/7Ms14+AcsFsXB1LGQKmH83LfBWpVoTqfEB1e19O9wA4/na8K70+Ivw9ZEV26LX/D40ZUHkjhOo0zZyKKLV8kNcM3Sp5Q98Z11vYqM/ezizAzon6G6LxxvBKOHehPFP7Yszs5dw+sigvkNES2RdOTFzI8UB2q8w53juBz+q5odQbp2xydlFY/dzB5JgSEQF8J8NObt2RTUys/OVQqT61GRdIDZ6mmAX7w883H24sZmYcfR3yYwedSAzynDH/eBGw2m8lkstvtWo1Gp9ViGDzvIXrbAd874c9atZo11BgMmCV7O5L0EwJCQAgIASEgBPqNwOD9KtBvS5aBhMDIIUD8ppvwdXbdSDv7c4zPfp57oqAtTV6bOYs/qDAhIu7wpxQZ6CgV/fSPZrgS5KlVHsgrikuRgFCX5MYUHfMTc841GWqOt7czcyImSUWSQ8ek+MbrmwvJS4gwR1tFDOLPyHe3FmFAm5kceLr72DE4U9zFu2ZGcalcrjnOPaDBqdK6l78q2HK4UnmFrTGPsjvmOpJt+tWLGf9x8wTF6cZag7Tek5L0+08aGL7GZC+ssoQGkGXrrGjIOIdyayuMzuBZFjw5PoCiH8rgTJdVUv/SV/nbjlR1Ot3hU8Zfv5Tx8E3j56SeY6xTGg/n73hIuShOd+uYMQQyo825r7bT66BceO6KH1yapDReeaKm1uLUCw+dMnIV7lqdtGZWpE7jRV7FR147vv1YNbdcpdHuCsxHyLvtkji+XHOR6zCzuO6D3aVbD1WynnKD7c0tRUunhLnESiTgg7mmwjZTJL0igtX/c/eUxDAt0/F0x4maJz88lV/e0FFf5tU9WcZ9OSYuIqMlR/ndsjR++dQwOnKvEpj/zBc5+04YuGcKyht2nqhZOjnMtSo5EAJCYCAIZJfVbzlSWVbdoPX1To4PnjUpOizobJrggZhRGTPAz2dKerjN5jiaVUFejp3HqoP9vb+/IsHdrT9ws8vIPSHQ2Ni4bdu2J554Ijc7+6pLLr5tzZqEyIENeXZfVahe//116zw9PN/btOm/f//773//+1defbVGwp/dGcmxEBACQkAICIFBJyCS4qAjlwkvGALoLEVVVmOd08+FKuftRf3c05svM9i2ZVQpeiLqCWpRWJAGIxi2vqJyS72VKiOt+Phe3lzw8ytTFeFm2fTwjMBaRV1CG2qrmuKskTIhIYCQ2HZQSXR4ZqoxiVHaS6aHGesaCXqlVgwtq8x2khISIBzo7xMf6Sz1m5FtVPwgOAff3F7skhTRMVH6qADjGv9Efi3Lcz3t9ACtigrXisCHmEjSvVC9mkBaYniLKhowuEGGxJHPfJ47I0l/2oY2dsxlcyPR/hrb5LOtx6rHxej02rOSolNgKjDDhBmxzKAnutJsUddl+9Gq7RnVvHR6ukB1WKCaP0qZrr5tuqpa+3Mb8kj+6PJCdrry4XaytsHhoq318XQvsY0rkFfbLZgbzE+tImdlu/PKUwTK1fMikQLREzlDSeX0ON3xojoDjlFHsyIrd9qRO4QrRXJP7uGPd5ZyczbYmg31jVgdlfbYHz/5tkw5RvD9lytSSZqp6ImcXDgu+ECOqaauxBVn7ZoFJTG7uC6/zJkMVK/zXjkzYtX0cOVVuk+I87/9kvjMfDMQyPB4JN8skqILnRwIgYEgwD8BB3NMvGED9RrExJkT+7+GbzfLDtH7zpgY1WBzZOfX8G/Whn3lpM29el40/9J100teGhwCDoeDFIqPP/54aVHR7WvXEvIcFRIyOFO7ZkFV/PEN10eFhrzw4UfPv/ACHzBefc01Pj7DK+cmH57ByrVm5cDb+5xPBJWTTXyu6woQaDtF0QkPKtkN4kNZLctQ4RD2dHqEh9VDWV5zczNXeZDJDCsOshghIASEwHAmIJLicL46sraRQ6DVGavLl7JipajFvhzjQaS6Nt0nhPBP3elfKJFRqJfydZuDD7kwLcb/vrXJ89OdBjqkmUN5tf/9ZmZZtZVqGF/uLbvt4jglw93tF591jd3/1IGMnFq8isF69U+vSJ0Q113JjlnJgXwxOLmxfv/mCfQgg7mRAOekKL+fXJXKS6h1J0vq7v/bAUJQSYWXW3K22Eug1vuxOya5X4Z7/7b/SJ7TU9bN41B+7fbMGiZCXYoO0dx4cdyVc6P4mxA9NKfc8vjHp/ZlGnDGFVc2bD1WtXyqU0Li78VLJoT+r7enEg29/Wj1rUviiIF1zULFFfRExWVJ4ePYMF/Xn5jkAdyBvbFtuphQ35suiV03+/R0WaX1f/ske/8Jg1PerWjYdrx62ZSRZHNjU3wpEPjfmUNnlfAtR6p+88+jLj7KgZ/G6/ZVCXe4ZcN0b8DlWD45zJ1qapQfRZzLjTbSdwafWwmBi4WwzXcmVVbgr/aaHBeApMiY3Cr5lVaXpIgOXGJwpl3j4av24qZqJ90uGBe082h1R0mx3t5koXpM2wST4nSzUwNdbyJlNLIxTk0N3HGkihsDIV45Kd+FgBAYCAL8gN14uPL9XSV+WvWCGXFp8UNQECkixG/OlBhjrbXaYKkw2t7eUpQQpp2TesY4PxDbHuox+SGL+w9NBzkJTWd46iaKnvjnP/8ZPfFH11935cUXB2gHw7va8eL4qFTXLF3qMdbjH+vX/9///R//elx33XXIYR1bntcZNsiFaKfocQYxi0vDdeHRwwGJCt+4caO7qsiwl156aUdV8dtvvy0vL3f+K9v24NJPnTo1MTGxhxP1SzPC2Hfs2FFWVjZ79uxJkyax1H4ZtvtB2HLH8JpOu5jN5q+//rqwsHDt2rWpqamdthmqk+yCe0N5sAZ21O7+GaqFybxCQAgIgUEmMBj/cgzylmQ6ITD4BLBQUZH5RJsHEAXGYHEcKzAT3muqb2QxSDnTkgLGx54W/mrq7Dll9RRr5qWYMM01i2MUPZGnhPpSyPhnV6Y99PxhfslE0yFLvSIp9uOm0In0fqrL5kUqUiN2MJLuTUwOOHjSgGylLKwv0+WXWU4WOO2Qfr6qi6eGXbsgWhkNCyE1i3+0JvlHeWYshJjmvs2uVSRFGvh4e8yZFLxlfyVSaaXBRkWOMP3ZqtDEibtKBk9L0lPH2bXC3NL6U4Wnp1s2PQxLi2s6yl4T//sv+c7piNjdn20aWZKiv8ZLqz79UxpfqrmDLdEFQTlA2iMLZ7uTrqcUXUFyJa+h68ziCSF8uZ4qB9x46HfHi82bjlRlldS1xUQ38mcusrjLK0S2NUOd894+3aWltcp4Wu9LiPSj0POZV07/P0ynxvHa7iRPeYO4NkUtoP25pmNFzkvpeuCopUQ1TzFzVLcVi3C9JAdCQAj0L4GDeabP9pYZzI650yKGRE9UthOo06QlhNQYLfwsojgYpeRnpwTyz+hofVRWViKN5eTkrFixYu7cuXFxcWgTqEs91FwGAQuy2nvvvffUU09Z6+p+dsstaxYuIIviIMzb1RSoioRdw+fp99577rnnaHbjjTf2RYolLeMnn3zChVi0aNG4ceNctseKioq9e/eWlJRwXWbMmNHVetqdRwX7xS9+oaR6RG/iVV9fX0buKCk+//zzGD/BizjFg3l/+9vfDrKkuGHDhqeffjo/P//yyy9/8MEHB1q2AwhkyIbJZgla717BpNmuXbt++tOfIhnv3r37zTffbId6CJ9yvVBjT506RbWizMxMbr/Y2NjFixenp6er1WdrDw7hCmVqISAEhMCgERBJcdBQy0SjmQBBxM9+ktPVDuPCtYsnhyaGn/4VvLahqaZNaqR9UrjfijabnqsvhUeSI7VUvEVWQ/srqnHqKf3+oFjzkgmhrmEJJZ6erMe9yO/oofpOwnNcLb/zAHWVQGnFW5ce7bd0ytlZ6MufhfjO5k0M3rS/gkYl5+5u3azInYermto0sW3HqpMjtIF+pxdzOMekRD1r1J7oidT9UFZC1LNrugmx/hdPaj9dsM5n7oTgzQcqsL+VjjSbm9bHy5fCCG0PJEVK0CjHynf3P7FPmxzcX+5wrPfzdgUjd3jx7ImjhbXkwSSRmeIJdb1Qe+amdZ1xHTB7/Zm1BfqpOv7xj32yo85Id6PF4arAcCjbxJdrzHYH3FF2u/NvM3kIASEwQARySi3ZpfXREbrEmKF0BfprvcclhZRUmguKnTb/XUerr5gblXTmH9AB2vvQDksA7PHjxzdt2oR0gllswYIFa9asQVoaJqoiYuLLL7+s9vT83Q/uXzBlymCWZOnqujhVxYuXaHy8n3rn3WeffRah6tZbb+2q8Xeet1qtr7766uHDh1G4EIbcJUW0VFS/n/zkJ9OnT+/h5aD70qVLa2pqWBV1sS0WS1cLYEwuPR7VgoIC7IpdNRvQ88h2LIApOOAxoHMxeF1d3X//93+/9dZbq1ev/vGPfzxx4sRuZkRsra93xs1woPDsi3DczUS9eAmH6W9+85usrCzW5upOmtF/+Zd/4VbU6/Wuk3IgBISAEBj1BERSHPWXWDY4xAQWTAq5c3nCpPgAlwCEhkKtZ5aFCQFtkUCzdks01jeiH3ES01lxm0WrXYM+PiWxY1CAN/kWXeOQXO/uZQnfX5rAmY56kKtZTw4wnSneTBoT05pRaM6pOKcso8nSSIpJXm2hKojhHMF0VkqQVuNFMRDMKd8crcbeqEiKOBarTHYl2d+UJH1MqMa1ErJPuoS2elvz4YLaU2eKhChtgFlU5VwAAlml8ZzpXIMM5wO1jydfNnsz21REVVaLPDdvfPBzP52trLzMYH3q01zKKXS/kQAtLljXbdh52+NFZvREAs/5BL7zFv161seLokPfsSRlQmpYuzyS/boEGUwICAEngZzy+sO5Rsqqx0bqQwelHks33PU6zfik0JLyWuzJtdYmPmEaxZJiWFjYr371q/vvv59o2S+//JL6JxiynnzySTSX22+/fcqUKT0Pue0Gaa9f2vTVV8hq6Im/ufuueZMnDwc9UdmLt0p12aJFIXr9E2+9rXgV+6Iq9ppPx44BAQFknOTfUMSmxx577KWXXurYRjnzgx/84L777uP4gw8+eOaZZwjv7arlwJ1fuXIlkdrZ2dkc4LAbuIl6MTLuTnx/P/zhD4uKim655Zbhoyd+/PHHf/zjH7GvcpV5/44fPx6La15eHprsO++8k5yczJu3F/uVLkJACAiBEUpAJMUReuFk2cOOgLeK33ZOiyOE9GIwZIkB/qoV08InxevOvOJcNvVJ0Lk4wHhFWeeTRc6iz+4PxByCfznDLyuuOrzuDfp4TJ47f42qnZDD4jsJTD3/mczWJlPD6fotJ4vqcsjMeO5M7I4oH+fuxrSilLnPQIXni6eHf7SjhDySZJOsNNmjgrC3jSUrZXWdszALjxnJ+rjQsyFXlCjB9am8lFlodtaf6Wq61vbTKb2G+XetRoXMCiirrTm3zJJX0ZAY7swjSamWiXH+yuKp3IJ58zs3Qgz1uTW02/fg0uzMrNmXZVD0xPRY/8vnR01N0Af4OtNUUY+FmkIvbMhr3w0ZmiB3rVdtWyUi5PKeq5HB/j567WnDKc7cKcn6mOCzSrf7RIih0cFno93dX5JjISAE+k7gaKGZ3B3Bel/qO5/7Q7TvY5/3CBjn46L0aYmhx09V1Dc4dh6vueGiWE0XhafOe/Rh1gHvG+Y4hAmid6+88krsil+0PT766KPPP/8c0+JNN920bNkyl3VuMJd/ZP/+Pz72WEV5+f978F/mTprkPSiJ9nq+QT6XnTFu3A0rV/z1jTedeRVbW2+77baedx+4looKzJXtXgXjVaXBEKrGkZGR1M7md1ZuwiFcRqfXAoChoaEEPnNluw+R7rT7wJ3EXIlwbDAY/u3f/g1DMZ5EAP7P//zPu+++iy5MYkrU5OEGc+BoyMhCQAgIAZEU5R4QAv1AIFjv88fvTY4PPS15PLsh78t95URskZcwt7zeUBcYojtbkRBdx1W8AuVRqXHcxSLGeg/AH1EqlbPGdBcz9vU0CqDqTCq979qds2J1u/nWzoigKA2SIr9B7jxZkxSpJcb5wCljjdkpwgb4qWJDfKkT4urFXD2eDptbv6imrskH4yA+zDcu1LfG5FRUSdC55WhVYng8x4BzBWE5k271x1pIW1ZhtFvbdN5pKYF3rIgn26aXM6OXc3gqdxO03uk81DIP1WsUSbGg3NKuxApdqGrZqc5IlLRSfpo2lJOenhRw+ezITqdgu+66fBdt5LQQEAK9IWCocxzPM1cY7NMmBCMp9maI/u4TqFNPGxdRUmGuNVtJ1YqJkgpO/T3JMBqPH7OIJn5+fjNnzqRKxt13342uiGlxz549+/fvDwoKWrduHeJFWlpax5R8A7SN7IyM//yv/8rNzX34+3fOnjCBWOMBmqgvw6q9vS+aOrWsuvof76//+9//XlVV9bOf/awvA3bfF+WIYiZvv/02ghEiL4IX6hI1VaKiorrv2JdXka5IKXjw4MGUlJSrr75auQGIIMbQykm0LSKI243/zTffcNuQoLO2tpZe3FFz5syJiIhQhDl+v8IXeezYMfdeRGFjCfT3P/1RJS8Bk3G4ASZMmIARj7uR2HAitXHOXn/99Yjgru6c/OUvf0kANVgYAZseo5GW0T2r4GeffUZ3wsBZMx2Rzv/xj38AUBmEA+L9J0+ezFOj0bh9+3Yau8Zn2SzgiiuucJ1xHXBFNm/eTBjyyZMnSc7I1NgteZu4JHjowerAgQPsd/78+QS2b926lQSIOAp5r9E4MTHRNRoH7AVTJBtnhWRLpDubCgwMRDdkjwqfhISE//3f/wUjo/GeVX5H4lin05FJkyXxkvuYcjxMCCD1EnSPLRcpn+ShXFbl2mE45Rbi/MKFC2NiYobJamUZQmAEETj7l/kIWrQsVQgMNwL8m0QlDQJLlYVdNjsiq8ickVfLLxWbj1RNiAtwTymI5yvkjDQTHaqZPzGEFHed7oj41snd/hFFJcJe/NqCnxJ5qNMZ+36SgsKuRIeB/t4TEwNQxDod1sNjTFhAe0saNYhDAn2IDWdnO47XIDDBtrSt/jWDTE0OJOrZXT/D44YspYwfpGM6fWzI2bBo93mZLkLf+UvuzYbb8ZQE3bREfUauCZ3OVNf41cGK8ED1qmlh3xnC3IuNNNidRWyUjmpvp5XVvZYLlVKwi3Y6LGJfbJgmu81va7E6dmfVkNTSvW9uuUWJ5W/XnV3otE4bpsXaVF5j23G0moo6VChq10yeCgEhMKAETpaacyst+gBNVLhOox4WyhGflOj81SR2RFK0OZqzR7uk6Lq+6BfEeyKOYE686qqr0F9QjlBzyGb4xhtvzJo1izx9S5YsCQ8Pp6WrV78f1JWX/eUvfzl+8iTllZdMn+Hv2/m/4/0+by8GDAoIWLNgQZXB+MaXXxKRiiKA4NWLcXrSBdGB9HmUNKExv5wgTJD+EqMfMdc8FHmiJ+OcVxskNhQuRECuO8qyIimS/3Hfvn3cEtHR0e6SIhri73//+6+++ooGqGPIW1SYYZFobcTXo/QhzyF4odl9+umn7sugRDWyo7ukyLzkkaQlkiL3Gxq3knURURUC2EI5qYyA9EYmUJQ7nsKEKZgRtY6Y5fh454egPBD+qIHD1MogxcXFpI9UTJq8igjIRhRJEdmRNRNB3NbP+Q1pklDijpIilV4ILWdhCHmsH/7MQkfmVQQj+pKEsbS0FBmRZlgItVot7yYasxI2snPnTpyGSK7KXEzNq48++iiLpA30ePAS60Q6fOihh5RmPGXBynnloiO/8lble0hISHBwsCLdKo3l+/AhgKRITgneIyyJO4Gbiu8cc2O88sorpDTldhJJcfhcL1nJCCIgkuIIuliy1BFDIC3KPyXaP6fMQqFhAngz8msnJ+ioqqxsIEDr5TItUn+DWpYzk7vMhe+uy7j2T7ELBLIxzWNwQSoZBl0v9eiAvHTuslyP+vS0kc5XRTlppTVmTIK+r13Q5Sd+HXUxfItLp4a9Xl2IAlVUYamqtWeV1dfUNSqf+M4kMDboHFkQGTfA97R1jukQ4K46U/G544o7TtexzXA7Q9HrWemBGQW1+04a+OA7v6z+mU+yD+eaLp8TiSsWIRtNmTSRHY2BvdgIwdTaMwHUp0rqD2Sb0qP8uAPRrfMrLa9vLdp1rEYZ1tHcUmq0Er8foPVGT6TNVXOjNu+v4FWu1OPvZWm8PeemBXGep9R7efHL/K6ygl40MYRwy82HKtnF/lNGCkkvnxG+bGpYhF6tXC+bowU1E4nZ5QLuxdakixAQAt0QqDY3YlIODfQNDfIdsH8cupm/85d81ar4SP3xrAp7Y8vJknNqwXfeYRSd5d9oVEUeF110EV4qMu4h4uDzwrSI2kJ6PtQfDDVUIsZo0+/7brFan3/mmZ379qXHx924cmVESPDA/c7Q98XjpI8JD790wYLM/LzDp7L/+c9/Igpgeev7yJ2OgOnvhhtuQFskfR5GNqpCU0KE6i4Ii8uXL++0Sx9PomqhcCER8t1lf+MAzYuT7jVVaIlignKHNIawhesQ8Qt3HnZFfHm8hKqIFsbVpAI1DVgYLjykyby8PEVlc1+qMi8NuOUQ9XBikmyRxgT2MuDrr79OSLKr/TXXXAMHND6YMBryIpH7OBlRWhXl8eKLL+YpDRDycBQiNaKPu6yOKHFJSUnKaIh38+bN4+bnKeoPtz3bZHmuuVwHH374IckBuBCsDQciuyYPKUolcieV05XtswuEJAUgAiKCLLcHjkKKNVPnGi8nnlNFUqQlOSX/8z//Ey0VkyO3ENcayQlcLJuOLucjC3AX9AFC1DNqJrOg+OPidK1QDoYVAd413CRKzR/eJtwziqTIHcIl5jwq/LBasCxGCIwUAiIpjpQrJescSQTQxVZMC8sqriNVIkLJtqNVE+N1y6eeDhIJ1HqHBZxWwQoqLBv2ladH+Ue6FUv5zq1GBGootEHGRvTE7DJLSpSfn1ss8Hd2H9AGxMn6+6q0vl4WClub7d+eNExL0k9PPI/idyunh3+wvQRJsbm5FVsc2QORmVhzWKA6NtTX1+ecn1pMp9N6KTa3mlrndFMT9VMTRpXNbWKsbsH4YDQ+ai4jHVYa7V9+W7b7WDWCHSoqVtZ6axPaq+uycld8sr/8ja8LlDOuksoZOaYfPnlA0enmTAi5aXFM9Ln6LMkWUYQJDyeVp7Gu8bU1BwMuAABAAElEQVSv878+WK7z825sbGbS2gbnVQjRq6tNttp6B+N/vKMkVO/zP3dP8VerJsbpxicGnMh3OnORgB9764RyG+CTYHkkWFTSg7oW6TpICNMunBCSXVZfVNHALU3B2TKDjRuArfE+Qs2kI9/TY/x/f8dpH4GrrxwIASHQLwRKqq2GOntCXCi5FPtlwH4ZxFvlGRHqFxTkW2uyniwcQEkR2QJxAV+V4q7iu/JQznDMgbuC0C+76+EgCBk8CKjEooVJDXEH4xhhsO+//z6uK3QTAm/xduFBw9vIH8YsFZmmjwVnd2/a9N6GLz09PH547bVJMdEc9HC1Q9WMFU5MSrx++YrcklJchC+++CLilyKZndeSXnvtNfC6lCMMbhiX3EdAWUPMBTjyE+oD8gQqFZU6cDmhoA2QpOi+gG6OWRJ7J64TZYQwYax2yHZIiiySEGMkRTJ1onsyAhrZihUruJ04RhxENEQE7GpkVBhuP4yf5Ppk+0xx1113oaiibru6oGtTaoYF8OAluFEN+ejRo6g2l1xyiSIpcoAIjp2Q6ZAUCTdGhRw3bpwyCO8vF3amo7EiCmNm5J7HZuiay3WAzvj8889jDGR8Nqs4HNevX4/gTi+ES8TTdgHpvJWUjaBXMiylzDMzM7nEIEJaYuVcR/RErJrf+973EENZEgCZkX0Bje27ZncdsCMKPWMLBfull16KudhlzHS1kYNhSAD1mR/7/LTkZ+YwXJ4sSQiMLALn/HE+spYuqxUCw5kAJZ6To/zQR5yVRmqsBEFPSQgIC3AaFTFwTUwIoBLFkRzKGLfszqyhbPHKWeEXTQgJ0nrjEMF3Ri+Kk/DLTHiH0GBGiA3VILhwgHzz6qYCgsJw9oUH+KAWNTa1UlKZA8KrO2YqHBxi05P07AWpFE3waL75rx+cWjotbOmUsMjA074zR3MrvjP0o4SwTv58ReeKi9AaLQ5CdjYdqjTVOahMwsqnJeujgtQdHTQzUwJR3DYeqEBuO5Jb+7gy3eTQiDPTwYTqLghtI9Tmxg2zdnYkUeTv7Sg+motm19pgb+YLJm00xnLG/coiwBXXWAsqG9xPckxQs8sqGB9lczSd04sGeD0WTw49VVq/81g1Mh41pusampAscUdyKUlkyZUlc+WWgzaEclM9pb0d9qaWprZQaULpf3x5yn+8nGE0Oy2lSJzVZrLVjGUcno6L12HXpdZQ+ynHOPNpYlTkHn5ve3FemYWJaKZUJVKuNd1J5ein9iS/pmfHy99uk/JUCAiB8yRQbrSVVDe0tI7V+Hx3UfjzHLtPzXm7U58qPjLwoKHBUNtYVG3tKq9FX6YhZhMxCFsTkkH3jzNKY3vBUXmOJkL3ditBiUB4avfAb4X2x0nloF2Xrp4qP+ex0iBhYAFjBCQMRZ1BW0T7YAG0YQ1E891xxx0kzutqqO7PW8zmvzz3XGll5c9uuXlKaurwTKHYcQu+avXcyZOuXbbs+Q8/RD7jmt55550dm3V/BikKx5nrOnL54OzehZec3tE2Ax2vcgUxOq1atQqFF20Ow2CnqpP7CAN3zHpQ8bg9mOLee+9FYlMWg7RKZDR3DuqJ4smiAQfKMfodQlv3q2IEzHfo1zTjHsM5S5gz6edcvbj3XG5ZnHokRkQuxC2oKHQwpAGSNw8AKtIhk6Lcdap9o+IpjRmfW533l2si9wOuFNolu0bIY7PsjlcJDEfdQ4JEKEQcbCcpsgWskUh+LEPR4vFUIk3yQwAaSEskLWUQtEXci7RkWNe+3Kd2PybOmtQEYEespDoQWnZXC3bvJcdDS4C3Bu9WPj9Ad3Yl9Oy4JO4xbLlHjhzhXuJOwH9Kvaxe/2jtOL6cEQKjhkDnP6ZHzfZkI0JgqAj4qDwWTwrBqHii0IxKQiFdjIr471gPf3RMJLvi1DB8Z1ZbE9oQcayFlZZ3thbhO/Py8kBKowviy5wJwQ+sSe64hUXjQ97bVlxrcWo35Qbr65sKPttTxoy0RMBBWZs/IfiKedH89ZVTbvloTynaJS8hAPEqB5jdPthevCOjimOsZCtnRVw2q5O/PWj802cPmxvOCTbJr7C0jTEmu9j86OvHXTkZx8fr1s2LGhftTOyN4olIdLK4Lr/cgjZKFeYKg+2LveWsEP2I7kiKJPiJCNL8712dhIeghy6ZHJpdXFfb1EIWRUWTYtgZyYGohBy0eyAULmS60vrCcguqGVksYfL5/2fvPOCjqtL+H9ImM5lkkknvISH0JkiR3sSCncVVWQvqru11m/ruu+uu+3fVffVd111dV7Gsil1ABQERqYoivRNKCAnpvU6SmTT+38mF6zBpkz5JnvuJeObeU3/n3Dtzfvf3PE8DIBeaq6+tPxcZpHvuLqvn79544KES74RMKK45vz1WQLACJVh2w1xY55RFpfNyZxZGxRj4DOXX6jCbzDE4XH/73Bii93x/rJBAq6yB+gbmET5x9tjg2aODtxzOa7Jm6Ej8fj5/95hXvzpzMKkYApe+sYzhKAZF6pfMi/3om7SDySWcaVzcT+dxxbhQ3AVsOZS3+VAealMmnWzKSrMmXFwgQFE7KrGnG9cgZwQBQaDdCKTmV+YUW5AEenp2oW++9nVP5+WZEGM8cCwThXZmUWVXUIpYWcIKYfCIs8KWOwkNYXfAfXBAkbBB5V81Ae2i0IhQThyQLGqCNAwLGdSj5UZbvkorcC4cajY4FHa8CjOinmxTAneEJ5KTJwwfNm/CBF8ndqFoNyimJsTff8YlYzft3pWRl489LKo6hfuzy9nCRwzJYZrUUpBiaPHgxdQizB1cFYQaEidMnplEKC0IKRLwUIjdepBSpA/QmkpXocNYjUoaZFgSXCWhDqRNCbg/VU6oyGAZte2qY+w4K9y8eTPWxKxwGlJ4OtYnmPAvlGKbWnQkM5wm3SAnkkyFHiWNYhEClE5iDQ3nblcPJs+oIxUcmCki25ABZBTimE6SAZNw3EfiGPFPf/oTA8dEGjCJjMSd1SSAkI+0haU2nk9BSSRvdpg750ckuuhYUdGi/sbovslOQibiRYGwLSwk1jAzi/tRFgPvKvBJ2mQROSkI9FsEhFLst1MvA+9yBMbF+WGSnJyFzaeVGjucUooJsCJU9Na4wZqVVdV+8UMWZqRkQJPIH32CmuH3DRwKdJj3BaeEdn0N8dMsnB6x7OtU4iCTlX/546eiytZgI1xcUc3uC8UiSsnENOtba/WAc0REppjK+vl4jk1o2hMTP9UoaEcpqpXAhEIvqh+1RNgwn3dBgtBlQoLRZK5d+V1GcqaJ5rBcVoyXG36QNQzPxaWiyrqvalJ3NnNk0Mdb01DJqQxURJAOphLHgmqLagLB5qQhxgqLVeZ2JquhubLqooYI0bbNIQhtrjm1KmdOwN4Oi/QN89deOS4UTR/mzMwg0ZmJo0KAGkKpQN7ptW647CR08s1TImcPb/pHkjJGgqIgGm08XkhtTJhD/TS4pERmiHs1yD18LIb4eWGbj1k0pN6EQUbmgVnmT6txUwNwU3ZYtO9jNw5GY5hbZuFfXD0GGTSUUsrie5E88MJ2Zv5sc4j7TLuoUK8cH1plqaXdgvLq6tp6QoJDlQb4eAb6aHA82rjDckYQ6BEEkPywe+dAZQMHYSdzgD9ia42FIHvUuXPnorjpkU462GhKbgVCRU8Pd5TtDhbptmwo//x8vQIDvGstNYXlF73f6qw+ICmCZcBsk3gO7aiTbxkOhVtkupUE9UB2WL/KGw41rST4lw0qi4R/1cPuI+c5A9OhUJBKNts8pDnQzkBnoNWCwaFaesKOF3ajVd1ZCyP9Yu1alrfVhWJAAMNpIaezXQL/6NCwmePGL1u7FntYqEAkY23qJOhBMajSObwQwlvZUorIALGqxtgZGhEejcob5v88VccUtKm5jmRmZSlEmFoJZxSJImcaP3Pop5qzrQnuEZWzo6yyKmwHi8gXnSYMLAQi3VDyKAmyKYm2NtpqftpS+sBg1YVKgo+sBNYwN4hdJVxSB6LctrYZOINhODFYCEeD1JHHO1f5F3oRp4233XYb0kuVqFUKMjTcJnCTQiZCPgqfaIunM6dR2mL1nJKSwuQq8lu73iJ0ZdJZBogZUTLiVZPQ59z+3Pi8cqBIO/wq2DUhHwWBvoSA7ND60mzKWHoMAaxBCXli1zye6SYPCziZXp6UWY4/uP3JxZfE+xF3QsmGnfLCyyKGRui3Hs4jtLGpokHW1SAzVDJA5Sjmn3bV8hEd3xWXhPpo3D/7IetkehkWxJxU+UTSpZU1FQ3GwlRiVYu1eDR3mfOO/xAkZjVWrmo7qOoYKfrB7ccKNh+06s4U3ZxthWCCXS051VJqItjXc3C0Dy75EDkqJ8cn+MFqNfeTGPeUuKqMDdJ9e7QAGZ2NzO3HwaH97O0yN1jmQF9P/sAEotbCfrP+HIsBUtVqr/gj/C5wc/ypeLYpoXF3DTdqIf4QBkLqgSDLm5PML0spIUwfF4K3civ3zYTzn02znHSJaTBmH1xrdfRJr+AQlRzDo30oTiVW40DbMhc6x+jgH/kjG+FfoIBZumSEU9C4u3H1Qkb5vyDQ8wiwx0astHTpUjaoiFPwumXbJ3YdL7zwAntRuCqMIm0vOVua2w2nBLyDCQvx8vR0xt+E7u5uRoMuO6eEb4QuQo/ZhErg6KL6G1er8CyN/+Ur0vak3Uf1EprKgwcP7t+/H8ILRoNsOPhDd5OQkECMC5RWjVt0/MyppKTQ4OCR8fGevdDFmEHvPSw2lsGClW3cEgeHj2QVpkDVeGLqaEvOQlOiT4RlQLz2k5/8ZOzYsWTmZuckcqcmm1C+7RTysckMyknrt+KAAVBgcMctZLO9BJ9oqxPkEjWo7zZQUNJ5mDXbIh1JU3mTxVl7mIUSqoWlSAAWvCXCtnBDHTp0iGjU8N12pdR6wAQmzu5qmz4yQIVJhEhV2VXmXeH4mCM7+o/KaV0lH5tsi+mGT8SGGlkiDClvhmCRMI8Fz3//+98YveK01LYGKvzlL3+5ePFiKCcV/CZrlpNOhQCvDXjbxxLldoZebNw35MkokdEn8g2OHwnCkfONT37kz7CQvFRo3yuoxg3JGUGgbyDgjD8f+wayMor+gMDNUyNnjwjktbTG0y3E/7yNie3AJyb4hxk0uErkpKeHKzo79SoUENzQ5CEBA0O9F0wIx44VXSFbJoUkIghJkK+n0adZBzcwcegc48L0qP8QmMAhUhCGB4UamrLwAN2gMG/awo71oQWDymbZv6pVu+HhPiA04MdeqedJwAX99a5RUFe2J5tLE+UZy2L1Kj8+kbMRKSUyUDtjZBCRrwGhsNwCRcUvMK2nK0Mz6jWq3bRaUElAPP18/sCbJkf8qFIM1KLNtMumfqQ5AEEESnOzRivNWWVusFpqcwE+GpwSqkV6ewKKDZ6t60YBEajx4O8iiQo4N7Tb9NbCtjNQkPzZnoFetP3YQppWICL5ayGPXBIEehYB1CgQN5gTYjylbE5UQgoiA1M4ztNDXGs5uW6Fbw7Ezrzg4WnJvz2LapOtEzDK18crM+scMucmM/TGkwor0VbGJz09HS+BkDWQOIojORzhERKEyLbwIKxAPsLmdBAQuJ7Kioqz+QUhRiMBazpYWzcXN1dX55UUA6+fwQCh37mtI1zC9R5EHvbROCuEeIK0wv0iBpLNNcSMcEmh/3hQ8IOkyZwY4fKggA5DbQrRZstjkp85Vc6gy4PngtXiJGQHOmjb2qhcHTKawUceeaSxVtE2f6ekoRRVG/Cf//znrENoWfBHOdvkUmSkylhYzBwdMSBlwSt3EKapRJuhXUaElAwHoyCJNasqSGzTSOk2D3YOGF44xIKCArhC4vYw0ZBK+GG0m50xY8awJJpkMNvUrmTuTgS4WXDBSTBxvqx5+df4xlTi9sAk8nRlGTDprDeeuiw2Xi3wHBBKsTvnS9pyfgR62W8F5wdUetivEIgP9eavhSFDqxlajD4MZRMdqOMPQRayLHO1VZkFmwNxA//Fvy1UjgpyaKRV+VVVXUdZftghlEQCBncJHQNlSVlrB2KakAG2UK16iZ++E4dYPVW3+6D/SAv5o2uQifSTXlIbW0Svhk62UPOgMP2gNkpGaA5tHX+2zYECzYGzUFQtoC2XBAFBoE0IsANhYz979my202zst27dilmcUgOqJYKuwstgEM2uo/FepU0NdXVmvjtwbksrVZYas6XZl09d3Y0W6kenbNBr+PIo6hrD5xaadpJLKKSQSkEjoo5hT8uGFiYFNSJkIoa6yKPw8taJ5BEhKVDovLNmTXTQkoigoPM6cyfBosVu1NXXn8nMXLf9O8i76TNmKHReiyXadpFfWXBVlFHs0GEZYK/wu4eKjZNQgVBOTA3qOeWu519c+ynpjz/+mIDLXFKmD2bK1usiTv0UB46EIcZYGyta3kxAL0JmcXCJEdEEHBzGmNBnCPFQS9Gc0hkSNAS/yXpgMUB9Ep2G+hFY8ZEuURVSPvgReDf6w9OJQ1H2QYcpakFapFqYTfJTFQeVO3KoCkFsjWkUlFiueOQEHIrDgXJAxygVUj8gQPYxFqKagIMiqqV1yqL6pDhcHuSp0jRdUpSbdBIzf07Sf/g7OsmQR44cSfTz7du3M15UuuR89913YRXJxuOXDEolDv7LQGgC6hCZKj1USd4TJ05Yf2BjseHhocymWiHde+ONNzCQx9sAkWEYpnpJEk6OAPz7+PHjiW2F5BB3nLa9ZTVyv3CPcPugulVIZBYwdxBn4BPR5Nrml7QgIAgIpShrQBBwCgT41Q6H2A4ZHcQfWr/m5H5OMTbrT0AXSD07yVvX9a2bm+u6gUjNgoAg4LQIsDkfN27clClT4BSwfGSfz+afrQjUD7wAFM+iRYs4Y9t/dv5cxTUb2bjENoZ9rx0ZxHaaPS2bWHgBhEjkRPJDWzBHGLcq8QRs6+xgmpc9ijjRbK4xX/CH28E6O7c474T8fBQ3Dg5J5ju39R6sDe4JpQzbV3QxMImKDSlMIralLDyIGBgTVpGdZqrjHb7nnnuw99xz9Og76758cOFNAQ06u45X2w01pOXkfPL1xvS8vEsnTODu6/QWQRtOgWrRij7xxBPQfFB1EGfcntzFzNdzzz0XGxv79NNPK/QZ9BMcH0wZN/Knn34KI0wa3g3S9t5770UHp/aQ9xN8hCZD8Eg9UFqwYzSHUwWYMhri9odu49LKlSsh0SA7IL94eqCx4h3GX/7yF3Jec801VIJ88qmnnmK1QGJCDcO+8QChNp4kxH3mGcKCQUP99ddfUxsdgLxTnAbydoRS9Bx9H1wkIZ7V7rWQYIyEwVWItpdeeonu0Rw1wwACC08zztDcgw8+SNMMkJysXs7Qc6hY/NkpzC9sHXIwLIgpCAhvvfWW0igIQ6lzkrvg0Ucf5SQ1EDgFooeukp+5QBFJGA0ewhC+J0+ehOaDKkJZpvCwLXTe7hKo0jR+IeFw6Q8DUeSl6IKhFFEjMk0MwbYUD2ra5SblcU0GoRRtwXHyNDcC65wva8IKcZsobwuUPrPeWLqkua8Vrl85z/0L18zdxLIkPyvEycco3RMEug0BoRS7DWppSBAQBAQBQUAQEAT6CALsbJE5wCSyJ2EfS8BT3Kuxz//888/ZveNn7aqrrrIdKkpGPDHBKpKH7Qr7bSghhGY33XQTFpRKTrb3qHvw7oQIQlFJkJN9C5sfHD+xde98SrEGStFK1RGIGM8UiucN2273eBrFvTeydv7VNusJpMc72VkdYJsKHQNPwQHnApnCwRqAUYIigYuB0mLZcHQ6k6gOgfjXSG4hVr7cvj3I3++nc+f6+/ioV502kZGXt3zjpu0HD0bHxNx1113I3xzvKvcyR6v54dq4Ybk3Yd8gxbgxIa2Ai5v9tddew0KWRwHUkqrao06YLzg+CC/mEbGe0gT3PpyFbXPQhRCCMHqKVbtyCbkiOmjSEBlQk5Ckq1atonXqQSrFJfgOFglPG2RW9IGcEF5o5WgX345I5yDIFHmdUiGRZ8jGyuGlBf23DTtDBmrmIEGfUf8pRZr7lyaUFUiC59Ldd99N3xQtLed5MOLzAeUgw4Ge5uApp/YEY+dbb72VrpIfolBpAgqPhxsUIbcAA+QZaNc0wHJwkhZ/85vfUBsJ3uhg371ixQpIPUWzCQHEo/KnP/0pfKsd/WdXoe1HquIjk0IlapfUDMwX7vZwmMt9Z8ci0WeYTYozg7bck1pWEs6MADQ3q52biDsFal7tKnPKguQjNxdEs3qeFQKZyCWWhLJm1EuSEAT6OQJCKfbzBSDDFwQEAUFAEBAEBIH2IIBgge0xqjHkNqh+SLCNZ3vPfoPYoIiM1ErZqb7yyivE02C/jYIGLgBzaSJsoD5D2AJPQVVkxoIPbRFKRkQTyJ2gGtm9sHlGFoEqjVJqhZ2VqMOWs8Gmj1aqzLUWS61O205fGZ3VJbt6CBEF1YmQn9D2dpf6zEdIKOgklgRMIqsCSoWPLBV4MTgg1hgUEuuEo0n/dJ2LA8sMRgZGeznH1xtdXQb8ZM5so3NrFTNycz/ZuHH9jh2BISEIAGGa2oQJd99DDz2E2A20lTtRKc5Nt2TJEnyuoSuEQYBo4OaFRULchDgRdgmOifsUOokbFvYBDgvNncK1KTUwX9BnqNu40yEjyED9MG5qBBglG+d5emARDPsG8tBq8FNIDmlX7Qk8L0yfwksSXBiWmTcQPCJogo6pJCA133zzzZhOww/SSUSR3Np0iXbhJZW+QYPSFtpJpXK7fxkLxTlJB+DRkEkyTDUP9aCIpGMqg8aQiV+BRk8ZIx1goZKBUpyhIKMDWJWMg4fliQeVw1MRRSGwkIdVpzRKDwH52WefVVu0SzAR3A4KoUNX6Qx4YkbNqxqgYHaoB3DUpyWjIBtk5fTp05kI0kqF5OStj/KYVaaDEUEdIvnEGJxHLtnoDPUwQAoiKldoJtv+UJyVAzlLZCS6YXtJ0s6PAHcBq4IHL9+5yu2p9Jl5Z3lA5aOi5eB5wurl1Q73FB+5BfhyF0rR+edXetidCBDBs38ZknQnuNKWICAICAKCgCAgCPRhBNjV44yJXSjbTnatyBXRB7F1/9e//oWmSR34888/j44JjcNvf/tb9ifsVdgDv/jiizAIbGsR3bAH5vfYk08+CaXIJhY9EYaH7GrYJHMeyon64RHYnKt1dkqitKLmhc9PfbXXqp8akRAydXx0gF/nE5cd6aqluu7Y6bxd+1MeuC7hhol90FUZvA8KL+hmRFgoZZh0FgMGzhwQRuxdIVBUOqYjSLapLHTP22+/jWZW6+5+87y5C+fMCTAY2lRDt2VOz8lZvmnz2u+2+xgDsNomVq9KG3VRH7gfFe0SJBTMAgwgdAMJbk9mqkmuAcKC25+r3Pvc1E3mobfUAzWpkIDwGnbzTkNUohCOZKYbHEqjdjmVgasaK4V25N8uAkRtjv7z+FIeU6QZCB3jYLyNh8xAgJERcYnBKnK/9vWQqkCYhqiEf9tXCaXosGIkDrB8VHBrzCTa1k/TjJScnf5wtm1F0p2CAOsNZSKP2ZdffhkLA25GvrJ/9atf4WKC+vnIlzKvEEhjbcBbwNOnT/NFDGMOp0waufHGjRuRDxPmG1lxp3RJKhEE+gYCXfvt0jcwklEIAoKAICAICAKCgCDQGAEEC9j9oTDCoxZRWVAYwf0hnLHlEymFDSDbTpQ7GEcrEhvs8rCwQ8WDKg15FCwS2RR2gD0tm1g0Pl2kTLQdhV7r7qf3NBo0ZksdEVqqLFZtjlMdGGMXlVZh/hxscDRehFP1v9XOIIlC2coaQAY1ePBgmETmHWmVKrNqtYauyIBAEvNhugHH/emWrQNcBtwwe1ZQQ5CQrmiu3XXiP3HF5s1f794VGhWNuBKCvqv5RLrKfWo7OwqT1fIQIB85Ws7DVW58juay0RCsh3oVGotD/dg4QWbb/I0zdO4Zu+ZaGIjSLsNxEJZW+0lVPIpbzdZqBsjNhhlodgoa1+DI7DcuJWecBAG0pXyD84bPTrSLownUspzna5qvdYS3fFnDPCrf+Fx1kv5LNwQBJ0Ggpa8iJ+midEMQEAQEAUFAEBAEBAHnRAD3dugaiJlApFE0MoT+xJmXbVexPWQ3gv4Fiz9cmKnMAhsVdrD4zlOME0ljPEiwF6xfN2zYwGYG8hFlInZ8yCIw0bKts7PSUHVGX09fbw9CP5eWm/mLDPHtrMo7pZ7qmrqcgnKNh1t8aCdQBp3Spc6thFWBmzxWDkKY7jFtdrD/GHVC0mHV+84773y+bduAAS7Xz5wZ1DXr0MEu2WZDR5aanb36m2++3rU7cmAcSiJuPQh92zySFgQEAUFARYAvWTWtJJDHYoYPb2hHKfLly6tBXu8RlxwfqWSGO+Y9H4bSvBdU3R/b1SYfBYF+i4BQiv126mXggoAgIAgIAoKAINBRBNAr4cgM92Tr1q2DHrr22mthYWwrVfcq2Fi98cYb6q4G8ysusWnhUPKjfYDEwbQKNcSXX36JGAonXyjXkEtgfgXhyK7GtuZOSQf4eroNcDH4eOEIp7C4EgrP06OTzavb3U/CxcByFhZVRgVpQ/qoShFLZ3zztRuiLi0IkY0NPnQn6/azbd/Q1nUzZgQbjV3aqCOVwyceTU5GPrk7MTFy4EDCgxAvuFVZnCM1Sx5BQBDoqwig6n3ggQewkedbVVX48vX685//nABKnFHMBRg+X7U4MOELHVe2hDPCYhoRLm/4iJGF30z1S7yvAiXjEgTaioBQim1FTPILAoKAICAICAKCgCDwIwIQf2w8oBSximpsEqXaHiJUxMwKWcSPJRtSmJcqZxCpEdcFA9gjR47g8p9NTkpKCvEo+UjwAZQRKCLtynb8o9HHU6dxM/jpamrqC4orS8rNwUZn0QNWV9dl55fX1dYFG1s3Gu04FFJDYwRYrohwz9XXv/Wf/3zewCpeO2NGSI+yivCJR5KTP1j/1Y4jR4YNH75E+MTG0yZnBAFBoBECEIX333+/3WleARL7yO4kH3mlh30AB3wiB09C9au8cWY5Iwj0cwSEUuznC0CGLwgIAk6NgMlcm1NsLiivrrLUaTxcB4Z4h/n/6ErJqbve4c6Zq+vO5ledza/08nTVe7njSY2xY6fZ4YqlAkGgkxFgo6JsNtSEbQM4dyPIBsE3EEFg4oqXOvYqthlgElXVA5o1BI+TJk3CLJr4knhaXL169a5du44ePYp7+K6gFAN9NL5aj8p6Ij9bvRYWllQ6D6Voqa7NzCv30riNjHXS2CC289hX0+ylr7r66sqKijfffBPHhQyzB1nFSrP5cFLS8k2bdh1LhE+8a8kS0Sf21YUn4xIEnAEBZNocztAT6YMg4LQICKXotFMjHRMEBIF+jUBRefXx9PKTGeVnck2wiuVVtUEGzY1TIvoPpVhhqdt1qmjVjkytl5uft0dUgHZQmH5IlO+IKB8CSPbrxSGD71UIQBfOnz///fffx6Pi3r17YRiJv4GwkfN4UYSLVOhIxoRfReKfYkkNicMBgUjsDsWLIsbRCCW6Ytwhfpq4UO9dp0tdBsCIDsD2uaa23sO98y2s29p5rJ6RTOYVlBt9NNOG9ryxbVv735fysxqvuOqq4qKijz/5pIFVHHDtjOndr1WET/zhyNGPNny1/8TJwUOGoC2aOWuW2Dv3pZUmYxEEBAFBQBDodQgIpdjrpkw63JcRqK07V1BuySu1IEkjHWb0igtxFgO0bsA9t8SSlG1yc3Xx8nQz6j1D/LzQ5fVD6uici0tytmn7sYItB/OSs0zsq1XwzdX1atqpEnhhyyisPJhc6uJi7e3kYQEBPp6ujTxht6nPFK+vr8/Mr1RK7XVxIUTD+CH+V4wLmTkySOt5kc6rTTVLZkGgmxHAQyJKQ3wpfvDBB+gNcdikxH0uLS0lWvTYsWOhETHnJGw0sVngHPkI4Wg2m3GqCAsJaYKSEUdOXdFtg85j/GDj4dTSWlePQD/3vMKKkjJzkFHXFW21qc4qc82Z9OJqS+2Q4UGDQnu+P23qfN/LDAnOMq63WJZ/9tnK81rFbmUVKy2WnUePvrtu3YETJ+Li42+++eZp4j+x760zGZEgIAgIAoJAb0NAKMXeNmPS3z6KANE2z+ZVHk8vO5NTkZxrKquoramrn3dJSL+iFE9lmV5Zl+w64JyPziMyQJsQph8Urh8S6ePt5d6viMXknIqPt2d8cyivrKJGWe8ohgzeHvHh+vCAH62eWTMZhVUIGMkD+2bwdh8eZR/s8lh6WWlFDXxfRIAWSN2JwtA1BzaTh1JLn1txAutJWvjn/WPRFbp2rDnsnaODdDGh3gg2KypracJSU/fDsYITaWVV1XVXjw+Dce6a0UitgkD7EVBNmG2rwD3ivffeu2bNGrwi7tixg7DO6lWUgTCMcIj4jN++fTt51EtKgiC2+I+//PLLiQhsd6mzPg6J0I+I8T2cVmWqqik1WdKyS/x8vXpWqIhSMjvfdDqt0OirmTE6uLNGKvV0BIGA4OBbbrnFpa5u+apVKzZv4gVSt1lAV8EnHjnyztq1B06c5Ea44447rrn2Wonv3JHZlLKCgCAgCAgCgkCnICCUYqfAKJUIAh1CoLSyZs+p4k0Hc787WsA+SqkLpV7JBUapQ7V3TWEYz8SzZQVl1VQf5KfBx5+PtqPPEw/3ATkFlZWWOuo84FLMvyMGGq4cFzpjZCB+9PqJrSuLYe3uLJVP9Na6g21cmD48UDssymdQqF6dz5KK6g0HcjYfyOMMHgbjw/SP/3QoPgfVDCQ++jb9ZHo5NN+CSWE3T43Uu1101TZnx9Msibq6cxB/VGWrrGx3zTCGI2IMt8+NSc2tzCqoTM2tOJNdQfXF5dWvfXkm1N/rsiEXxdVtd0NSUBDoIAKoCGNjY4n1TKAVrbbpQCLEXRk+fPiGDRuIuEKgZzSJkI/Yk1JQsdxEk0tMZwyfa4iTUl/PVXwvcgkr6enTpxP+hcwd7GdzxVGFj08wHk5JSc0s5f1ESkZxRIghNLAnNfLlFZbjZ/IqKiyjRgZPiLN/WdLcQOR8VyMQGBl5y623eri5fbZuHdFa6urrr5k2LSwwEGa865qmlQMnT6JP3Jd4HK3urbfdJnxi16EtNQsCgoAgIAgIAm1CoAu3l23qh2QWBPotAlBImw/lvb8lTTXwZEen83IL9vdKCP+RPwKf/FJLZpFZUYHBtsSHekM72uKWXWwmDxbTKNpC/TXemi68wZGJvbc1bUdiAR2YMTrornmxQyN8bDvTjnS4URsd4p1dZDZVQk9ZmaljKaWnM00FZZYbLguHQgKZdlTbu4rsTy7Zd6pY0Sf6entcOsS4aFrk2IF+jS3Aq2vr80osGXnn7YLR8R04UzJ9eKDteCHjyMCayS22LgzbS86fZrpDDJprJ4TR1QpL7TdHCz7ccjYp0wSrWGaqeW9L2vh4f08n8Pjm/EhKD7saAWhEWD+OlhtCq8gBXVhSUoJjRFgYbJxxpKjQMUiu7rnnnltvvRUHi3hOhFLEJTwhpGESm1Q+ttxWW682CBUNeFrA7UZOviklo8ho8PL0uOgrpq11tjt/dU1dVl55WlZJiFE795JQX68upKva3cl+WzAwOvrOO+80+vq+t3Llp1u2lldW3jBrVlx4eBexivCJx1NSP9qwAX1iUHDwTQsXXnHFFaJP7LfLTwYuCAgCgoAg4GwIdCHj4GxDlf4IAk6IAKwQNND7W8/zidilBvppiEERitlvhH7y4Isc0u9KKvrk2wzC4DIQSMPHbhqMabCtdu/bYwVf788tq6wZG++3cEpExzm+FhCD1qmvO4cqjTw1tecTLeR35FKon2bx3OhTGSZYsMzCqtScCvCxVNd9/E065No1E8KwpXWknt6bB4XmjuOFaQ0soVbjNmlYwG2zoodHOsTVlptr1+/LmTI0oE/GRIYfnzM6SKdx+/cXp8EHxvnw6RLMusfG+vUDnrn3rmjpeRMIwLzglq6JC3gwcHXVNxxNXu3Sk0G+molD/BPTSo+llpWbzGfSiyJDDVGhPSAPrKvD5Ln88Mmcc3X1YxMCpg/x69KBS+XtQMArKOjaG27gFd+yFSs+37qtssq8+KorB3YBqwifeDL17H9Wr/7+0GE/o5GA6TfddBNa4Hb0WYoIAoKAICAICAKCQFcgIJRiV6AqdQoCjiKQVWTedjg/s4FCwnFVbKj3dVPCF06OaJIVyi+zpOVUKJQiDexNKib4r6/uR5Ytt8ScmmMyVVpDA1eYrcxj7zpQnM0fE8If3d5zuvjdTamHkkvwGAiruH5PzvAon7FxiPX6slDxyFlUmeXKFA+K0F8zMcxBPhHEQOnomVI0npGBTdtd9q7F0Li3Xh5ukwYby+bF/vWj4+fOwTac+2Bb2ojbfUWo2BgrOSMItAOBEVG+eJnIK7bkFpuJ+3z6bKHRoPXW/vgV044621qE+zq/uPLQiZyM7NLB0YY5Y4K0Hn35md9WfJwnv1dw8DWwigMGvL18+YadO3F5cceCq2PDwjpRqwifeCot7fXPP/92/369wUBwGA7CoDsPCNITQUAQEAQEAUFAEBBbElkDgkCPIVBTd+50lglVGj2AQ4wK1t02J/rmKZFN8omNe7npYB6uDHuZLWvjYTRzZsIg/weviR8d5+fZEIIDoi0xray8qraZ7H3hNKbeRHkmSg+DcXMbMH6Q/5Bwh/SJ6uBNVbXr9+eoHx1JsA9EGllQXk2kl8yiKgKhYNKu+ENsrjhLjqVL1BcI8bP5lZQlckpzme3Okw+OGCehGOmnF1TllJgR1WLlbpetuY9Y+sMq4ruTDHTyhyMFOcWWBueNzZWQ84KAIOAoAv56zzljQmaPDSJAVkVl9ckz+UdP5VaazweJcrSWDuTjpi4urTqQmJ2YlKtEZZkc3wMyyQ6MoH8VhVW8+oYb7rntttioqK379r79xZqk9HRcgXYKCvgHOJ2evnTlp9/s36/z8SEsjC2fiMtRXAd0SkNSiSAgCAgCgoAgIAh0BAFRKXYEPSkrCHQIgbwS8/7k4tJya4QTP73H5eNCrh7XBnOeE2fLoJ+I5NtX494Oi/S94/LYv684SVwOINp2JH9UrN/oWENf1SniwiyroKqigTYN9sOTpo+/3iF9EIBg/44dOmzg5gO5P5sVrb3YyWZzyxSKNr2gMiWXvwoszeExowK0scE6AsJEBOq8NU24UYNuLCyvhgo/nWMiOjnEImFhJib4hxpbl0ZCPVpZyNyK1PxKuEiTudbf2zMmSBsXqh8Y6h3o49kqmY5aSe/ldtXE0GUbUhlU3blze04Xhhsjui6SdXPQyXlBoE8iQFz4ayaGl1fVbT2QC7u3/1iWywCX0YNDtF4OPYs6ggnvG8rKLQePZx9MzNJ6uY+K85s36iLPsB2pXMp2EQLaoKDrb7klNDzszXfe+eqHH/KKi+9beNPI+HhP947uL9Jyc19ZsfLbAwd0ev3ixYvhE8PDw5VREN3o6NGjRDEinJE4VeyimZVqBQFBQBAQBAQBBxHo6Fe+g81INkFAELBDgO1Tck4FqjTOQwmF4YR+TLBdnpY/Iuj45lj+kEg9UU1azqleRc9VW19vrq638L/6c5hae3m4atwxVGrJsoyuVtdQqs5cW09GYgpjgqrW2XICBspquVxTjxKNshoPNwhQxy1Vx8f5RQbpYLsIhH0spSw52zQ4Qu8gX9Zyx5zwKlSdatU+Os4Ay+ZgJ91cXQ0+HjXV9Sj+Ckote08X2wVpabIemttyJH/5tjTFdaNtnuExvj+ZHjV1WICd80rEien5lat3Zi3/Jl1VMu44WvDRlrOTRwZemuBvW4ldusJceyyt/K2NKUdSSmsvhDVX8uh1HvPGhfxkagRspodbK9p5XExecUnIuxtSWZYcBCw650KypQWstCL/CgKCgCMI4KL3pikRSJ5/SCwoKavadzSTUqOHhGq7Mt4X302mSsuhE9l7Dme4u7sOjvS94bKI6EAvRzoseXoWAVetdvKcOQM8PM698ebuQ4fQFT646Ccj4uI8OsAqFpaWLlu7dufRI1463c9+9jMkimFh1jhdynHkyJF///vfRUVFt99++4IFC4RVvACM/F8QEAQEAUFAEOgBBIRS7AHQpUlBAATgyApKLHlFZtJs1eLD9TFBOgeRgQHElxx7sO+OFhAP18FQyNYWy6sRNp7JrUjJq2DHGGH0igvx5g9Jmo+26acBYYKziqqSc0ynskypeZXQeZcO8h8crvf2clc4neb6DJmICC6joAoFHM3llFigL2ODaU6Hro1QAI4oy5CtzRgdeCbblFVYBYd1Kqt8Qpl/VKCjQDXXN+c8X2TC6Pi8CXCwQUMEHgf7CSXtp/ccFuWz9ocs+OJVu7KmDg1omSY219Qt23r2q93ZpSarkRo1wEvCzUE0s64Sz5b9u+Q0vjtvmR7FrCndYLpZCe9sPrthT7ZyBlUjHDEFoIyxQWZtNLB7TfSaWrcdLXhrQ0pGvtWsm+bcaW8ABLc1sA8Bvld/n1FUarn3yoFDWosbjjNNox4FjCvrGS4R2SMdlkMQEAQ6EYGR0b63zIxC9Xw4uaS0zLzvSCa3MFpFL274Ft8/ta8PtXX15SYL9s67DqVTf2yYz/VTIicNMrSvNinV/QgM8PCcPHOWm6fG5dVXdx048K/ly391yy1oFdvn+7i4rOzNVau+2vGDi5s7oaXhE23jsSBOLC8vZ4zp6elvvPEG5s8EbBFWsfsnXVoUBPowArW1tTiKdXNzVD/Rh6GQoQkCjiDQNIngSEnJIwgIAh1BAAd2xRVWk2eOEH/N1BFtsPDy1XtAxGAhW15Rc/RsKQydnZpMqdb2Xyiko2llBIz+9lCe7XnS2FzfMifm+olhMDV2l7BUTcwof+ajxIz8Ksgm5eq6H7L8fT1/flUcV+3yqx+Rs0ECrtmdvfK79KqLA8UgjRwW6/vwtYMISO2IXHHmiKB1O7Opjcrx9FfZEPBabagvJQpNP6oUibpDdGPHR2fQuc8fGwJFCNF28FRxbqmF0D0tFN+TVLw7sVDhE/FWGeDjGRKgZVHlFFWVmGqopLDUsjOxYESUz4SE86FpUaoeTyvbuNfqqxFOEE55YJj34ChflhY2+Jhsb9mX2xy7l1dq+fz7jMwCK59Ic0Yfz4ggnV7rTisURFwJc024IYSZ2Fy3uir4nefj7QEFyYrMLqxqrtEWhi+XBIHmEEC/zSXWGEdzefrD+XFxfl5Xx727JW3vicLScvPOA+kFRZVjhoaFBnp7OqxSdwQofKmezS7dcyQjNb2Y9wzhQd7XTQ5fMC7IkbKSx4kQcHObMG2am6eny0sv7dy3b+mnn/3pnrtDAwLaeh+VmkyvffbZ59u+qR8w4N6774ZPDAmxRmxTj/z8/O+//37v3r1wi2lpaW+++Sas4m233ebj0zbXw2qFkhAEBAFBwBYBs9l85swZDLiio6N1ur4pYrAdr6QFgY4jIJRixzGUGgSB9iDQQCme92LurXHHg5XjtSAUmTLciMFpiclquzpxiL2Bql1VCAZ/OFG49MszqdlWp4QcaAcGuLookjQopLfXn0GY9tTiEV6eF5mdHkwp+eM7R/GXp5SCDUShQm0l2MweyiOgh3Le7l+IHnztvbMpddsF+pJi/CFng7SCrjp8uuTxt4/88bbhhNqwK9v4I2wpvWJ3D3NUZKrB4WDjPH3jTFG5BXpOGQtLwnHrcoowNTHButhw/el0a7SU1buy7r8yrjlYIHwxXkZASgaQvXSI8Z75A9El8XHHiUIm7khyKaKko2fLvj1aMHagH5VzCfPzrUfyOU8aPvHKiWG/uT7BvUGyZDLXvbgmac0Oq4Fkk8fq3dk0R1GWAc3dfXnsiGhfmqYnmw7mvr/lbHKmqdJcSwSe4xnlY2JbUSdRMMCggVKkrbxis9KlJtuVk4JAmxAg5kNubi7/BgcH6/X6trIhbWrL+TMPj/L975sGr9md9cGWtApz3bFTuZm5ZRNGRYwYFMwzwa01HwWtDpA7Fz4xMbkAcWJxSSWq59AA3fVTIn469bzLvFZrkAzOhsC4iRMf/s1vzr344oGDB1/6+JPf/mxxoAH3x46y85Vm86srV36+bVv9ANdf/OIX8IlBQfbkMh4VFy1aVFJSsnHjxqqqKrSKb731FhTAPffcwz3rbIBIfwQBQaDXIbBnz55//vOfOTk5jzzyCCLoXtd/6bAg0P0IXEQfdH/z0qIg0G8RqLTUwuUpw0e35WAgDhUu3Mkh9eJ3+onUMtzbtSAYpEhafiXckMInQsfAB0UG64bGGAipqbBFGK4ePF286XCuWj8JqMOl61OwjybNjsCg9xg/1Djv0tBR8X6Y2R5KKsktappShBv6PjH/28P5FLQ2p3WPDtGNG2wcHmugoGLvjCO/19afcTDUr87LHTtZaitGpdh3KcViU43iSxHTPw+3AW21L0TYeN0kq7cpSNu1u7LQ/ZFu8jiTY8ppcE/J1QA/zcIpEQqfyMcpQwPmjws1Gqx61ZqaenhA4qgoleSWmPecLCLNYogK0j10dbzCJ3KGkCm/ujbB19te5aoUhEncd6IIGpqPYYHaW2dGj4oxsDD4yDDnXxIyb2yIpiGeTE6xGTN5pVQL/7q6uhh9zluFl1fUWl0pyiEIdAABq/G+xYI15ebNmx944IElS5bAVlRUtL4UO9Bm7yjKt8xPZ0Q/ecfIMYP8eHRD/G3bdWbdt0mn04qqa+r4jmjfMHgmYOycX1i5dVfqN7vPUC2VD47yu/+ahNtnRravTinlJAhcMn78bx55ZOy4cd8fOfLWF1/gFdHqTcOBo7q29oP1X6357juNzvvPf/7zXXfd1ZhPVKoZOXLko48+evfdd+NgEctEdv7Lli17+eWXYRgdaEeyCAKCgCDQEgK8okAEnZGRwSvGlvLJNUFAELiAgKgULyAh/xcEuheBChvDZyLdGnSOOs5Tukmg57hwPebAkFDbEwuGRPo054qRTd+B5JJvjlgJPlic8CDtrbOjF06OgNLBD92r65M37sVeFX92tcs2pl4xNkQhGcl8KLU0JbNc2TRi6fzMnSNHx1h3lVzaearo1TWnT2ZY/Rk1Pg6mln53vBAFCk1EBGlvmRV9w6RwCiKKJCLNP9ck7T1ehFwxPa/ym6P588aENK7B7oxB7wnrClNWWvGjabBdnj7w0cF9V3MjJW7J1KGBr3gmsyRKy2uYo2nDAprMnF3Cz6XzRutThgfEBF8UB4aY2qNiDVsPWg3k8YaJ/81BDW7xwV+JRk00lTEJfnZ22RqPATPGBK3dkdl484iBvwU5YkNXiEEUFai1oztjw7z5w3qa5orKz/PsTfZcPakwknzsIGhqhZLonwiwfnCZxLYBDvGLL75ITEyEW4SwiImJEcWTsiTwpnrZEGNEgNdbm1K/PZRvqa5POpN35mzhwGjjqITguCijVYSODs36zdD6wfMB0/LyiuqUjOLDp3Jy8sqZAt4YXZJgvGt+7KVxrSiUW29AcjgBAqPHjHnk0Uf//ve/r9y8Jb+o+PdL7vL3tcrSW+gaPxjWf7/jnbVrg8PD/+///m/48OEtezGLiopCxsi/SBRPnTpVWFj48ccfcy8/9thjGo2mhYbkkiAgCAgCLSPAtxKHo99qLdclVwWB/oGAUIr9Y55llM6HAAa8JQ0GxfzOthqRtVWT5uJy1aUhJ86WoiP77kjB1eNDm6MUC0rNKTkVFZVWsaHWy33y0ICfXBah4BFu9Lp7XmxiWnlGbgU/6IvLa2ADJww6H7cX49nq2vPigvuvjh8a4avwiZSdPNh4ZHRQXpmlqPS8O0hbgJFDnjxrZRvhnmaNCf7JlPPNsfMcFKZH3fZQShlKRnzz7Tld6hCl6O2uEJ2V5jqkc7Zt9aW00Ufj1SDWg8aFdGPv3eIWzH7obNd8dO5zx4fg7JKwJx9/mzZlaNN25bklFnSpSnks7n11F30RBPl6EjxHuUqY5mKTdYqRwSp6VdI6Tzc8HioZ1H/57QXNPcBlQOMILcgbVRUtIV++TSywC+t8MrMcL5lUxaoou+BgVK25cQJnd/ll5xeer4+nRHtuDJGcaRUBbjC4rby8vNWrV69YsSI1NRU+glLe3t6//OUvx4wZ02oN/SpDdKDufxYOuX5S+NcHcrcfKcDtwOmUfIjF2ChjQkxAVKjB3+DFI6jhkdXERqzhTYP1mVZQUnUqteD46bzCYuTP1j1bgMFr2qjAGyeH4123X0HatwcLL//f//3fzz777MYffigqK4NVHBQZ2cTKaECBlXEqPf1v772n8fZ2hE9UoCMkixKY5YUXXkhKSiouLuZGrqure/zxx907EGy6b8+LjE4QEARaRcD6XSWHICAItAWBi3aSbSkoeQUBQaBDCCjRdTtSxeQhAQG+msxCs9UJXXoZQsUmaytF+XWBpokN0U27OA4Mdm0LJoS+tjaZsjBZaQVVKqVIzcrXKgGpx8f526nSJiYYdx4rbEwpYphsMsNoWb+Ph0To546+yBESG05avGxkwOa9uWRSgq402W3bk9bgwA36hnPE+O27X/Qgo1CKjL3CUotfRWIo2+LQalrv5X7jZeFQighCD5wqxrq8SbTyS6EUzzttJK6LndNG7OL5U9piKolDTRrlI44slZO4PPPV2otqmR8/76a/UAj2rTKY63dl89fcQCBSHaGMWV3EdVEqCfbzaln80lxbcr6fI1BQULBy5UqUTfhig4bABTsMIwckBQopoSQaLw8eFJcM9BsT63fX3IFr9uRs3J+bmlWWnFrAH5kDA7yjwvyiwwz+vlofokvpGjzgNtRSxWOktDK/pBJXjGfSikym8zcvIaGmjwq6dkKokImN0e4DZ4YNG/aHP/zhmWee+W779t+//O//++XDcRHn3y/aje50UdF/Pf93c23tc089NXjw4Jb1ibZlPTw8rrrqKm7ep556ClYRB4uffPIJHgyef/5522ySFgQEAUGgHQg09xakHVVJEUGgbyPQ9A6wb49ZRicIOAMC8HT+DRGW4UfwKsW/bWVG8GQ3dVQgMVKgV7Ydzh9/QV1oNzrC6apOGzGvjgy4KBAwu8T40POKMzqRZeMeMb/kfOCLqBCdh4e939VAH88mCa+G5s4ryDDuPpxWdjr3vDM+pWMEe0nLszo8qq8715w3Rrsh4GQQSSMndVr3xj2xy9x7PxoJRHMB59LKGtBrEuEWBojWNTJAFx/lm5xehpRvxY7MJp2dEVIZklapp7bOReF/1WopwnpUPjZ4dbSfejWngwmtp6MiXG4B+MpWq4XpNjUofMka6u/VJi1nq5VLhr6NAIuHiLGomZYvX56ZmYkycdq0aRg+o1KET/Tz85s5cyaxWfo2CB0ZHU+OYIPnkjlRt04L33O6ODm34mRWRXpeVW5h5aHELP6sN3DDPemj9zT6emHjXGqy1PEGyeqmwOqpAN+4EcHaqcMDLx8bMjBY19Yvvo50Xsp2MwJxcXH33XcfN9fR5OR7n37mD0uWzJs4wa4PyRUVD/7lqczs7DfeeGPq1KntMFuePn06vheffvrpEydO4AJ1zZo1JpNp6dKldg3JR0FAEBAEHESAryrhEx3ESrIJAiAglKIsA0GgZxBA9EcsY6VtzELLKmvVj453iC3Z1gN5UIqnM0wEaVG1YLY14J9OsbDmJKGTDRcaVfIQHwN7WyUNl0RUX7VsualGkQT66e0MVa1ZELKpXhfVIiTKaK7ByJr0yfRyIvna2aVSJ44Uucru0uxYrBVcKCqWs77W6M9tE+7Z9s3J0wE2LC2SQAyN4W3b2meskhdOCf+/T8ogCj/fnuF3wYTZtp4QP41XQxBnTsJdmqvrbblLQrvyp+RH9oh2kjSwqxGEmD4WlW2FLadhOVUhJDGpx8QZmlvqGg83e+rpkwAAQABJREFUIre0XBvrhwDTOHa0ZhvgEh4olGLLgMnV8wjAGGZnZ3/66aeIE0lotdqFCxdOmTIFbhGhosFgQOIEnzho0CBPzzbfd/0KZUhDXjbwFTB9eODUYQG8gGD3BWWIWH7XqSJUyQVlloISCyHs84tMwf5eQX56niSRgdq4UO+4EO/oIJ2PF+4TeX+gvtroV/j1o8GiIpw8efLrr7/+v//7v998880TS5ceSj593/XX63U6UBjg43MwI+ORPz0Bn/iPf/yDm9HL66JXng4ixSsyyj755JPYWR84cIDQCsRZWrx48QcffOBgDZJNEBAEBAEVAb7R1LQkBAFBwBEEhFJ0BCXJIwh0PgJQPyqxAhWIxzr1o+ONhfpp4iN8zuZVYvu882RR+QUmyLYGdm6qD0R2fRf0Z+ez8LWJRlL5wEaRQDG2ZdXzVvLm4gMZiv2phgy0BU2p5EX2WG3VpjR7qB1rNkfDhcqq2roGr46QmwQhaTlz770KZ6eqFA+eKZk2PDA22LrvatOBAnHG8MAXPd0s1XXllVZeklmwqyHYoIG8U07ix5D9v0oXcvJsQUVawXlhKaGclUtU66M9/32BbXtyjsmuTj7WNEMzhvh5EV1HyY9iER58VIxv4+KcYU2xXJu8pJ6sqq77+uCPMfjC/PDg1koRtawk+i0CaJfefPPNVatWQSYiQiRW7LXXXgt/AQexf/9+grGkpaVBTMyaNUskio4vEistyN134ZF8SZzfyBhfvmJ4n8GOTJE/I0JUviygD6352xLLxfGeSE6nRQArZmyZn3jiCaK1fPnllx+s+3LfyVN333br5MmXrVj/5atLX2Od/O53v5s7dy72y+0eBa1ceumlf/zjHzF5/uGHH6qrq3fu3HnjjTfCKnak2nb3RwoKAoJAr0ZAWMVePX3S+e5HQCjF7sdcWhQErAh4XzB8Jo3XPEKdNA550SpS7NbmjA48llKSklO763gRIj60f3YHTJCqTCRYJ3bHttwl3uuKGyJjUIotX5iNWbS3zr3SUsvOEAVlY1rKrhX1I5UbGwy6OePv4zlioCEqSKtetU3QeRzh2Z5pMg2FBDum7E5RzNm5dGyySC89qffyMEL2NbCB2QVVBNUxDfZH3dOm4bB712vdr5gQ+sX31uDLTf4qigrUqczsnpNFc0YHDwz1xo6ehlgPh5JLj6WWKY36eXuG+Z2fPmhBH2/38opaaMojp0sQKqokI5mZoKNppTTYuLdWJayvJxbr+ElMSjcRfDzM34uwMI1zOnKGNbn6h0w1J64/W2Uh1cyS6IcIELTh7bffRopYWVmJGeaiRYuuueYao9GIw7W//OUvO3bsSEhICA8Pz8rKuuyyy0aPHi0ERLsXSQNjeIFfbHctUrDPIQBZHxsbC6uIlvDFF188dPz4H/73WY2nZ6XZzFj/9a9/TZgwoeMB1vF/Onbs2P/5n/+hiS1btuDT4PDhw7fccgvvEuQ9QZ9bUzIgQaALEcCmoQtrl6oFgb6IQNs2q30RARmTINAzCGg1rn4XIu3mlVh+OFE0KaHp+Lwt929cvH+IvxdCRVNVDVrFxmp9Imn46c5bWBNv91S2KcZG+0b8jUNnS5Um2BBGGH8kegL9vDBeg5PKyKtUI/aqncE1FuZu6kc14avzQEuofMQyekSM76IpkepVu4QjZNDOU0WEGVEK+nt72Jro2tXW2z/CBs4cFXQqoxyDcTjc/WeKLxnkNy7Or63j0ri7LpwSAaXYXEEYvWExvukFlabKWtbMG1+dIRrM7NHB8IlrdmWt3plVZbEKDv18PAdF+mAlrdQT5q+dMjxow55slsSZnIpnlh9/7KYhGGuzCCAZ1+3L/vZgXuPlp5S9eXoUq4hSSGLX7cpKzaskKBARfnAnCpNprcFcyywj3UVB2Vy3OY+e9/DZsvxia3gHKOlLhvpbw0yLSLEFyPrxJXwmvvfee+vWrSMBUfjrX/96wYIFBHQmTWwW4jlgiQmZiGIRDgLna7Nnz4Z6EPdJ/XjJyNC7CgFUhCEhITfccMOoUaPQKu7atYsbDQYQij8+Pr4d/hOb7Cis4ogRIx555BEEyLQCq3js2LElS5bAWvI6ockiclIQEAQEgcYINPk+vnE2OSMICAIKAkIpykoQBHoGAY27GyI+vc4dWoe/k2llBabqwAv6Psf7BMU2cagRRVtusbmuKUYHgi/oAk2TWVC1+0ThzBGB2LHSBMqyvBLzpn25SnOYIQ8K1atNoy48dbYM3hDC6MCZYjuFIIQU6kU1s5pA7Ea4TxSOFZW1hWWWvSeLsIYjTqiaoa2JzQfzoFyVUrjigsNqaw29KP/4eP9Nod7JWVbq7Uhy6ZaDeTB6tjyvI2NBbRodqBsS43vy7HmxoV0pmNwbJocfP1t2PK2MJcOqeH3dmQ82nyUbcwq7p6yj0bGG2aOCVNo3zOg1c2TglgO5+DEkYPSOY4X3Zezz1hLqxQXpYnlVTVXznjHHDDRcNjIQB5ElpupKc93BpOLkzHIIREhn6keDCps5wHXANRPD7pwbY9db9SMsNgbXS9edVjSzFFwyJ7YJN59qAUn0VwSwbkaWuGnTprNnrasa+0d4w4CAAJRQ7BPgE3G7tm3bNl9fXzy4bd26taioaMyYMZ0ileqvkMu4BYFWEIBD5AaE8sPPwJ133kluiD8CIqFhbKVkWy7jvXHo0KG//OUvqfyzzz6DVTx+/PiDDz74t7/9DTazLTVJXkFAEOinCAif2E8nXobdAQQ684u8A92QooJAv0MAaVVcqH7K8EBGDrWXXWTefqygfSjMGhkUbmzWgpgoz4PC9WENdqZYEH9/rODfa5Ozisx4xNt1sviFVUlFZVYNIN7yB4brB12I/syZ6yaEebpbBWB8ub6xPmXHiUJskBs+upzKMn20Nf1MdhMO9cgAh4gfQBLE8TiaWvbiqqR3t54lMjXMESc5aurOZRWbkaopH1v493S26WxOBQQWeQaGe8eH6fuw4TNjZHQsiZgQq0spRr1hb/b7W9NS8ipagKjJSxoP15umRLQg32Pt/WRGZEyIN3lg6HDlmVFQxR8BuxXCbkSsYcGksJigH51bQUOPjDEsmhGFPBDOkbVERCA0lSfSykmUV9bOvTSkuRYpe/PUyKsnhWEBTYchJVl1NJeaU5GcbYIQp4b0vIqCUsuFNWI/LIocSil96sPjxJblGrRpXKQPpGdzLdqXl8/9AwHsl4n0+qtf/QpjZ4Ku4BvxhRdeePjhh2ExFD4xLy8Pe2doRIiMV199FZ5x48aNSBQJGhsUFNS57Eb/gFxGKQi0AQGEhNCIqIM58D/QFXccTeDN4IEHHrj11lvpWV1d3alTp5Au7tu3rw0dlayCgCDQjxFg48NbEI5+jIEMXRBoAwKiUmwDWJJVEOhcBLDZnDjY+M3hfNiZ/BLL+t3ZQyP0wyKbjlzRQtOh/l7xkT5J2SbUjo2zIeYaOxCOL2DF9gwoveLymnW7s/eeKkKTiPwwtwQSx8r04YDv9jkxahgNzhB7d0iM4XByMcxgXrH55S9Of7glDfkhvS2rqEE5aG5gGBu3iLxx2ojAExnlVjawui4poxwF5Ve7c4g3TYhPvqdra8+hOAs1ej1/z+jGxdUzxRU1yzafzcivVERzs0cFx4fq4bPUDH0yMWmwcdfJIii26hprHPCN+3LO5laOijMMi/QZHG41Q1Zlg+rwgcROrAfjNnNE0EvaJLSiSjYP94t+GuHfECaawCnLt2egJMX8Wa3Nx9sD++vrJoUnhOvt4ucE+nrePD0yxF/zwda0vCKrGyz4R+oN8NPMuyTkinEhW/dj+3yeOFYrVBL4zVw8M/rSQf5f7Mran1TMWmXhWbNeyM4HWFRoa2+bCDyssbP5lcczyxPTyg4mlaTlsRisBeAo75oXA3Nq14p87LcIwBUS5nX9+vWJiYmAMG3aNMI347sN0hC9EmdYObm5uc899xzZiNZC3Gc8J65evTozMzM0NJToEDAd/RY9Gbgg0JcQgFXE0vnee+8levuyZctgFZOSknCz+PTTT0+cOPGi78K+NGwZiyAgCHQGAs39ju2MuqUOQaBvIiCUYt+cVxlVr0AAQmRwhH7CEON3R/IxdEXt9era5LvmD2yr+zw4pqnDAg4nl5yqLG9y4MF+mrmXhGQUVe1MLILHIRAwf7Y5fXTuaNbGx1+0o6Z7914R+9ePq7ILzFYdZWFVTlEVbSkBPZE0lpRXY8famEGC3pqQYMR+duV3GcmZJmxakaQpWsiGn/Lnv6whNLHUdmuGIoTrfHnN6R3HCxRpZEiAdlSswTYwsW3/+1IaVektM6KYoB2JhbW19aj/Dp8pQcq3yct9ZKzvjVMjx8YalPEGG7yWzIu9YVI4NCszaAsCtCtxcl68byx0sHIe43e7SC98pKpQP6/i2dVF5dW4MsStYaCvhpAsgQZP2EM7mpJ6mH04zasvDUUeCN0JU8xJVhd9DjRQ0OPJ20ewbLw83IZF+Vgtom2Ohso9fXX+0UE6YgQRZaWwrLq0soZFAHHpq3PHryIm3mrMa4qaa+phV19ff4a1RDQYAn8rgyG2zH1Xx08e3B7fozY9kmSfQiAlJWXt2rWYMF999dUwicOHD0cDpcZ8wNs6fCKKxa+//po4LbAM48aNw7+bQi/OmTMHzRQf+xQiMhhBoB8jAKs4cODAJUuW4Kjx9ddf5wkAq/j444//+c9/5vkgN3s/XhoydEFAEBAEBIFORuCiXWgn1y3VCQKCQGsIQK/gnw7RFjIxJFoHk0teWp00LsE/IUI/OMwHs1M7mZhSH0bKdlK90bF+kYE6iCeFQnJzhf35sW2yD430+cWVcbHB+q/2ZRc3WDorl3FmFx+hv21G1PgEY+PIJ6NjDH+6ZThmywdOFUPtwR5CACEQiwnV3zIzeuuh3J3HCznzY0sXUrBLc8cE03+suXGGWFhqUayebV/9waLCl5HzQiFkRC45xeZTOaakLBPu9o6llmKdrVydNzYYq+dG41aL9p0EFGt8qPe9VwwMMXptPZhHhBxsfq3sbXk1GlIM5FVKEfIOhG1tk21RoB50prZnGqeZ/ahALX+E3+GPRaXxcGtyyalloS8J+DM8yoMJhfJD+wWBqM7LjJGBpKGJkUmqRWwTLB6lRUhqYq3UWN02niMrPeGSWo9SxGpbXVB1OutH+3qqjQjS3jk3lob6tgm8LWiSdgSByMjIu+66y9/fXzGoVJSJSkHYBLwrvvTSS1999ZXFYnn55ZfRMMIp7N2798CBAySQKOJX0ZFWJI8gIAj0FgS4taOjo++44w60itz1/PyAVcTvAXLFGTNm4HWxtwxE+ikICALdiQDPCg40EA0yiO5sWdoSBHorAkIp9taZk373DQS8PN0mDw24ZZb5/S1p1dV1kCxE+80qrEL2haxs4fTIuaOD1ZFePiZkWLgPIkEvjRsiMvU8Cb2X293zY6+bHEYYZg5CskTaeMHjDHTh4AifAB/NtBEBmC0XlFdjUuqPHs3X09fbg7AnjflESsHyjBno95DOvXB6NdGicbTnrXEnQIqf3jM6WBcR4DVvbAgmtKFGLdyoteELB3wWQ6BsZKB2xsggCFNEbYXlFitvNWCA1tOVYC9GvcaOFcKY+rkVJ3JLzKWVtTBoqu/FqyeGXTk+tG8HZrmAnPX/MGuDwvSYCY+P899/puTgmZLM/EqCn5hr6ipsLJRti3QwzUTz16ZK6KSthbJSFnrRwUqgJlly2otWsX1RVkBZVQ2EI5ylr949Pszn0gR/Ir2wkhs3bV9YPvczBIgni40z3IGddzb4RBwsvvLKK9hEV1dXQyhcfvnlKJiABy+KxcXFGEISMqKzYs72M9RluIKAUyMAqxgREbF48WJu8L///e/0Fb+KeD/gUcCLBB4XTt176ZwgIAj0BALwiT3RrLQpCPRiBIRS7MWTJ13vAwhAl0Dq4bcOcm3t7uzU7Aqc05WaaviDXxs2sNyWUowM0PLX3KjxfMdfc1c5TyxmrFb5w4kdfCLqQoxM4TRbKMIlrFehtwaFWa1Qq2vqUJMhjlMcGo6M9h0e5csHam7SfBm9G976+OPbGTIRnaM19McAQsEMgHtqzGFll1QdTim1Zc3w67dgQhh/A4ObFmy23PneexXCLszfy6j3HBrlg0ITz4OIOjWeblC0vXdQbe05csgrLgkdHskac8EMG0ErDhn9vT2aXGxtrVzy9zEEYAkVotB2XPCJuErE7HHdunU1NTW//e1vr7vuOoU9zMjIICS02WyGYYSLbPoRZluXpAUBQaAXIsA7hrCwMEK1GAyGJ554ghGcPHnyn//8J8Ggufdt5cy9cHDSZUFAEOgSBIRV7BJYpdK+i4BQin13bmVkvQQB6Dj82V07MZwgvBBqB1JKUrJNRNXAMpQ4vF0xCBhAO7d6jrRi5R8vjoYBvehIQfLAAUFE8tdyftz5MWoA0WhcIwJ1OE9EkkZsmSA/DX1uuWyfvApiEIv89cnRtToohh8fRphv71ZzSgZBoDECCp/45ptvrlmzBvqACLCLFi1SvStu374d9SL6xMmTJ2u1/YipbwyUnBEE+jYCvDAIDAxcuHAh/g2weuZFwokTJzCF5jXDlVdeqdNdZGPRt6GQ0QkCgkCrCCh8Is8NjlYzSwZBQBAAAaEUZRkIAj2PAN9ZKLAmDzEOifCZMjygsMxSXV2Pmo+YyD3fuW7sAQ4ff3/zUISMhCf29fYMN3oFGzSNxYzd2CNpShAQBHolAvCJ6BDffvvtL774Aj7x7rvvRqZEwBZlMJwhTgvGj1dccQXhnu1spXvlgKXTgoAg0DwCUAO8Trj++usxhX722WdxrgqruHTpUh4FBHRS3zQ0X4FcEQQEgf6CAJSiwir2lwHLOAWBDiMglGKHIZQKBIFOQgBbV4yg7ZwkdlLdvaMaAv7y1zv6Kr0UBAQBZ0VA4RPfffdd+MS6urqf/exnOFMLCgpS+3v06NHDhw9HRUUR61kkiioskhAE+jYCvDzA9QEuFAnWBKWIBTQqZljFBQsWYBbdt8cuoxMEBAFBQBAQBLoIgVbsELuoValWEBAEBAFBQBAQBASBTkcAPjE9Pf29995btWoVZMHNN998++23I0W0bWjz5s2lpaUzZ86MiYlBtWR7SdJdgcCuXbtyc3O7omapUxBoKwIYOz/66KOTJk2CW4RVVLTMJSUlba1H8gsCgkCfRECRKIrVc5+cXBlUFyEglGIXASvVCgKCgCAgCAgCgkC3IqDwiR9++OHnn3+Oo7Qbb7zxjjvuIOSrbSeI8kxgFryqYfAowRlskemi9Hffffef//yHSSFUThc1IdUKAm1CAHnyww8/rIiUiQG9bNmy1atXFxUVtakSySwICAJ9FQFhFfvqzMq4uggBMXzuImClWkFAEBAEBAFBQBDoPgTYA6BP/Pjjjz/77DP0iVg4widGR0fb9gDO8Ycffjh9+vSsWbOGDRvWOEi0bWZJdxCBioqKlStXAvju3btTUlKIhGNH73awfikuCLQbgSlTpuD0wNvbe8OGDUlJSbCKOEngoUEgl3bXKQUFAUGgDyAgjhT7wCTKELoZAaEUuxlwaU4QEAQEAUFAEBAEOhkB9gBpaWnLly+HT0SfeNVVV8EnxsXF2TUDa/Dpp5/yL4FZRKJoB06nf8zPz4fhzcnJqaysJL42xM3IkSN9fHw6vSGpUBBoBwKXXHKJRqOBWCQofHJyMt4SeOUAqxgcHNyO2qSIICAI9A0E+DnB0TfGIqMQBLoHATF87h6cpRVBQBAQBAQBQUAQ6BIE+PWPPnHFihVo4sxm8/z58+ETExIS7BqDL0hMTNy5c+egQYNQzHl4eNhlkI+di0B5eTlyUbzUEVzbZDLt2LGDMNyd24TUJgh0BIHhw4ffc889ixYtIhz8mTNn3n//fXwmiN/PjkAqZQUBQUAQEAT6GwJCKfa3GZfxCgKCgCAgCAgCfQcBhU+ETFT4xHnz5sEnYtTceITQWxjhwm2hYUSIJM7XG0PUFWdgcpkjCFyibBNrG2vormhF6hQE2ocAWmZYxdtuu42g8Jjnf/DBBwiZs7Oz21eblBIEBIHejgBfWBzyC6G3z6P0vzsREEqxO9GWtgQBQUAQEAQEAUGg0xDgdz/CN8hEJIpY186ePfvOO+/EurbJBlxdXZEukgFKUbwoNglR5560WCzwicTUZm8GX0OUbYSKWEB3bitSmyDQQQTCw8Pvvffeu+66Kyws7OzZs7CKPFJkoXYQVSkuCPRSBPhd0Ut7Lt0WBHoKAfGl2FPIS7uCgCAgCAgCgoAg0CEECCKs8Ilo34i4Al04evTo5mqERpzbcDSXQc53LgIYkGLyTHBtZicqKgrj9H379mF7TlocWXYu1FJbBxHw9/dHq4hrxXfffZeFSoByaIWFCxdKQKEOAivFBYHei4AIFXvv3EnPuxkBUSl2M+DSnCAgCAgCgoAgIAh0AgLwiZgoEpIFW+bp06dj70y8hU6oV6roJASIrA2ZGBkZqdPpQhsO7EnxZUnAlk5qQaoRBDoNAeK0/LzhwNdqXl4eWkWeLeL9s9PwlYoEgV6CAK8TOHpJZ6WbgoBTICAqRaeYBumEICAICAKCgCAgCDiOAGaJ6BM/+eQTYoDAJ6JPvPTSSx0vLjm7GgHibhPiGWt0KMWioiKDweDn5weZePDgQahGhIoYRHd1H6R+QaCtCPBmAm5x2bJlJ0+eRKuI5f4tt9wiWsW2wij5BYHejoBIFHv7DEr/uxMBUSl2J9rSliAgCAgCgoAgIAh0FAHEbjhPhE/EPd+UKVPgEydOnNjRSqV8pyIA50sIXdwp4p8Ojqaurm7MmDHR0dFEwCBIC2GgO7U1qUwQ6DQECAB933334UKhrKzs448/5jnTQrQWXmns378fohwOvdN6IBUJAoJAzyGgqhSFVey5SZCWexkCQin2sgmT7goCgoAgIAgIAv0ZAZRuCp8ILTV58mSCKvBvfwbEOce+e/fuwsJCRF74UiTcM5TikCFDiMRNGv4lNTXVObstvRIEQODaa6/9xS9+gSMFGEMoRYjF5qz1Ob906dK//e1vxHUR6AQBQaAPIKBYPQuf2AemUobQbQgIpdhtUEtDgoAgIAgIAoKAINAhBPBxhoMzdvjFxcUoE5csWYJKsUM1SuEuQICoLLt27YKOoW6i4hBrG0oRj4pMGXbQx48fP3XqFALGLmhZqhQEOgeBK664As+K48ePRwoNq8jBw6dx1TDmAwcOxEp669atja/KGUFAEOh1CKgqxV7Xc+mwINBTCAil2FPIS7uCgCAgCAgCgoAg0AYE8vPzIRM5kL/hOZEIrdOmTWtDecnaXQgQMxcpIjQiZCI+E5F7kEaxOGrUqPj4eKaP0M8S+KK7ZkPaaScCxIdHqwgPDquoPHkKCgrs6goMDJwzZw7a2+3btze+apdZPgoCgoAgIAgIAn0PAaEU+96cyogEAUFAEBAEBIG+hgA81EcffcTGnn070iEERERl6WuD7CvjIawzMlIEiV5eXiqliPSDqCwTJkwg+HNiYiJBWiAZ+8qIZRx9E4GZM2fiVxHXCrhZ4PnDwYPIdqgsbzyEzp8/Hw+hn332WW1tre1VSQsCgkAvRYA3YRy9tPPSbUGgmxEQSrGbAZfmBAFBQBAQBAQBQaBtCMBPffDBB+znESqOHTuWTf6MGTPaVoXk7i4EsHqGUiTWMwEufHx8EHChVYRqUQhEhIoxMTFEboFVNJlM3dUpaUcQaCcCU6dOvf/++xFEq6wijyPbugICAmbPng1jvm7dOvGoaIuMpAWB3oiAGD73xlmTPvcsAkIp9iz+0rogIAgIAoKAICAItIQAVofvv/++wifCUj300ENIh1oqINd6FIHk5OS9e/fiQhGLUTzNKSpF+ET2afRr8ODBCQkJqD+gFCVIS49OlDTuKAKTJk2CVeSxA5n4YcNBMGi1sKenJ6GHLr/8cojylStXQqmrlyQhCAgCvQ4B5auq13VbOiwI9CACQin2IPjStCAgCAgCgoAgIAi0hAAhPt59910kiugT4RN//etfC5/YEl5OcO27775Dokh0C9zMQR3aGj7TO71eP27cOGxFYR6hYMT22QlmTLrQOgI4W3jwwQfxrlhUVMTjiMNWY+vn5zdr1qyamppVq1ZhAd16dZJDEBAEnBUBUSk668xIv5wXAaEUnXdupGeCgCAgCAgCgkB/RqCiouLtt99GogifiMHso48+Kv4TnXw9wKp8//33/HvNNdcYjUZ6q0R8Vg2fOTN06NDY2Ni0tDTIFySoTj4i6Z4goCDAK43/+q//YmGjVXyv4YA6Vy5ptVocMuCNAePozz//nPUvoAkCgoAgIAgIAv0EAaEU+8lEyzAFAUFAEBAEBIHehIDZbP7Pf/6j8IkjRoz43e9+N2XKlN40gH7Z1/379x8+fHjQoEFEdsYgFAzsDJ85g+0zQkVsopOSkhAq9kucZNC9EgHYcITSixcvRquIenrZsmU8ppSRGAyGefPmYfW8du1awp33yuFJpwUBQcDFRTF8tgZnkfAssh4EAccQEErRMZwklyAgCAgCgoAgIAh0FwLIfN544w2UQOgT4RP/+Mc/EnS1uxqXdtqJADuxb7/9FpJlzpw5BGZRalEoRVuVIufxPTdw4MCUlBShFNuJtRTrIQSIY44F9K9+9StCP7/zzju89lA0id7e3qgU8bqIdJHQz3V1dT3UQWlWEBAEOoqAuFPsKIJSvp8hIJRiP5twGa4gIAgIAoKAIODcCLAbX7p0Kdt1hU988sknCfTh3F2W3lkRwLvcli1bEGpNmDABhkUBRYn4zJzabtJQe8XFxWVnZxMhV8JZyOrpXQhg0b9kyZJnnnmmoKCAx9Srr76qEIjQ6FdffbXFYlmzZg0RinrXoKS3goAgoCBg+1UlmAgCgoAjCAil6AhKkkcQEAQEAUFAEBAEugmBV155BReKbNeHDx/Ovh0j2W5qWJrpGAKIs/CQOH/+fESIMIlKZfhSxHwMzsU2EktoaCi0Y1hYGPkzMjI61qyUFgS6GwEvL69FixYphs+wii+++CI9gEZn8fO8glVcsWJFd/dJ2hMEBIFOQgBWUayeOwlLqaZfICCUYr+YZhmkICAICAKCgCDQDgS+/vprRIKvvfZaYmIi++R21NDWIi+//DJ8Iq7KsHd+9tlnCYnQ1hokf08hgDgLq+ebbrpJtXqmJ66urgqlaCf9iImJwYY0KytLKMWemi9pt1UEtm/f/uabb27duhXFdOPMeHflYUW4Z1y+Pv/882SAVVywYAHC23Xr1u3YsaNxETkjCAgCTo6A3VeVk/dWuicIOAMC7s7QCemDICAICAKCgCAgCDgVAkQYeObppxOPH4dJhBV6/bXX7n/gAdiigICAruunyieiT4RPHDlypCgFug7tzq0ZS88TJ07gTo7QtxqNRq1cNXy2VSlyNTo6GkqR8NBCKapYScKpEMAqf+XKlevXr+cBSDQhtLdEnJ89e3ZCQoLST85fcskl//jHP/785z9/+OGHrPDHHnuMkNCffvrpyZMnP/nkE4ko5VQTKp0RBBxBAEpRYRXl54cjcEkeQQAE3P7f//t/AoQgIAgIAoKAICAICAIqApCJzz333JmUFPhE9slYrVaZzXv27GELjQs8vV6v5uzEBPbOxDpAn6jwiagUiezRifVLVV2KAIskMzPzF7/4BfJDZeLy8vI2bNgwa9YswkBXVVXNnDkzIiJC7QN6LkJCExsa2gXndOp5SQgCToIAYltoxPDwcCSKWOinp6fzDNy8efPx48d5KrJotVotj8SgoCCs+FntxHomJwueCC3IGykyZsyYqKgoISacZEKlG4KAIwjwPpXvLBT3U6dO5Q2ZI0UkjyDQzxEQlWI/XwAyfEFAEBAEBAFB4EcEiJjx+O9/v2vPnoqKipnjxv3s6qviIiKyCwre//LL7QcPvvXWW2RdvHgxXvB+LNMZKVs+ETZz2LBhwid2Bq7dVwfMC44vdTqd6kVRaVuJ+GznS5FLcDGQiUTIhVjsvl5KS4KAwwiwdGNjY3ncEcEcOS12/XANEIU5OTmbNm0iZPncuXMhEHkFwouWX//61zhYXL58Obb8OIuATD98+PDHH3982WWXsdQdblMyCgKCQA8jIBLFHp4Aab4XIiCUYi+cNOmyICAICAKCgCDQ2Qigu0lKSvrlww+npKaGBQT85Rc/Hz90qNFg8HB3DzEaIRY3/LDzP6tXE4uAH9xss6GQOqsLxHdGn1hYWMjmXOETienRWZVLPd2DAPyLwWBo3JZCKbK6Gl8SMrExJnLGqRBg9cKSwx7yEmXatGm7d+/GSSI2/jysSktLT506hWU08eghFvn3gQceID9n0DPyhIR/RNL4zTffcJXzTjUu6YwgIAg0h4DV7PncOa6Kvrg5iOS8IGCHgPxktwNEPgoCgoAgIAgIAv0OgZqamq+++go6Lysz86qpUx/8ycLwoCAvT0/lJ7W7m5vR1/faGdN1Xl5LP/2UYKbwidddd51tFI72QcYP9zcaDrboeCV76qmnhg4dKnxi+8B0zlLnl1BD3Gfn7KH0ShBoGQFkhhCLKBZDQkLQ1R44cICnJUbQeGkwmUyIFuENuYppP84WeXy99957//rXv2ASt23bxtMS80mhFFtGWK4KAoKAICAI9F4EhFLsvXMnPRcEOgeB+nMu1fUuXvIGvXPglFoEgd6HAPFJ2SH/9a9/LSspeXDRoptmzw4LDGj8fl6v1c6bOIHhvbl6NXFOidOC3Z+dlWubBo8xLOJEwknDJ06ePPmJJ54YPHiw8IltwrC3ZGadCKvSWyZL+tkkAhCLOADFVSjEIppEJIqYP2MQnZqaivNEvCgSkgUHizhtIIQL+sTy8nJMob/99ltCPxO2SJ5sTaIqJwUBZ0OgQaR4rvFPIGfrp/RHEHAeBIRSdJ65kJ4IAj2AQE2dS3ZZbX5xRXJOuaXmnKWmzlxdV11bb6mu9/fxHBblkxCmDzFo3FwH9EDnpMmeQ6DIVH0io9xSWz843MfHW1NZ4+Lm6mLQDPAU6rnnJqWLWmbf++qrr37xxRcDamufeuD+y0aN8vfxae7HtLdWO3fChFJT+Udfb8QC2t/fH81O+zoGj/nuu+++/vrrBQUFyHl+//vfE0dVWKf2gen8pZS4z87fT+mhINAyAopikcAsRGXBUcONN96IRBHe8NChQ7waKS4uJk4Lq52oLHhdJDMm/x999BEUZBdFtWq5t3JVEBAEBAFBQBDoagSEUuxqhKV+QcBJESiprP3+RMm+00VpeRUmk6XCUldff67+3Lk6/jvnwr8e7q6btO7eGrfwIN3AMO+4YG8YxhCDl7ub0ItOOqcd6RYzXl5Vm1dqScmrOJ5WnpRZnlds9vJyDw309vRw12g8fb09IwK8RkZ4xQZotMIsdgRrpynLXpdIAi+9+OKWrVuN3t5/fPi/RsbHY9rccgf1Ou2106eXmkxrv9/xwgsv3Hfffdj6tVWrSCzFDz/8EItn+MT58+c/9thjRP5l+91y03K19yIgKsXeO3fS88YI8NJFo9GEhoYGBgZi8nz55ZfjYBFPiwSKhVLkKuGtKKW4EEWlCOEIq9jW52TjduWMICAIdDUCiiNFWmnu3WpXd0DqFwR6HQJCKfa6KZMOCwIdRaDIVLM9sWDb4fyzuZXFpmozUrR6FP4unp7uUEhanYe31sNX51FhrqmsqskprU4vNB9MLtFr3AINmnEJ/pMGGxPC9UIqdXQanKZ8ZlHVnqTifUnFeUVmc01dhbmutLKmwlxbV3fOzc01LbeSX1Xubq5QzBoPV4PWzaDzCA3UDR9oHDPQL0jvpvMcICSz00xmGzqCSJCApMRZ3r9vX6i//x+WLBk3dAg+Ex2pwt/X9+bLLy8oKd24Zw8KR+yXkRk6vlvGSPCTTz6BT8RUcMGCBURKhU+U3+6OIN9787A8hDLuvdMnPW8OAcyZkSti74xBNI9BXtJgCr1v3z78LapF8Lf40ksvEYQKWbd6UhKCgCDgnAiI4bNzzov0ypkREErRmWdH+iYIdCYCWUXmjQdzMwosgQHeO47mnk4vhUnU6TyjI/xDAvRhQXotAkQ3V/48Gvij2rr62tr6moZ/cwtMGbmlx9NLz+ZVfnckf1S8/8TB/mNiDbBLndlFqasbEUCTeCKzfN/p4sSzZen5lYWlFktNvdbLIzTYJ1Cn1ZlroI1hEqsstebqmipzTZnJUldXn9Pw2lZ7tmzvqaIAH41e6zZsoHH8IP+RkTovd5GvduP8dawpFDRY6uHHMPHYsdiwsP++43bH+USlZWJA33z5vLzi4l3HjkEOIsaZM2eOI6wiu2sior755pvwiTfccMNDDz0UFxcnfGLH5rMXlBZKsRdMknSxvQjgscGv4YBYxIEDb0qOHz8OschrGxIwFKgXn3nmmccff1xYxfZiLOUEgW5CQKEUu6kxaUYQ6BMICKXYJ6ZRBiEItIZAcUXttqMFK75NN1XV6b09S8stbq6ug2KNY4eGwiLptCgTPVtwmBgSqI+LNuYXVmTllWXklGw+kHsgqWjayKAFE8KiArXCJLUGv9Nd//5E4dZDeaezTDnF5rKKGkzd/Q26IaG+0WGGIKM3ktWa2noIxQGuuNerxySefxVWsaTczF9pubmg1JyVX+HqOuBkpmnnsbyESN+RA/0ujfMNMxAj2OnGKx2yRQCHX6tWrVq+fHlqSkpCdNRvb7vt0mHDHNQn2tYzODr6xtmzCkpKDh48CDvJpVZZRfw2fvbZZ2SGT7z++usffPDB+Ph42zp7No05NmMpKSmhG7CcxHjFqpFQDL6+vhJaoYNTI5RiBwGU4r0CAR4UWEPz0ODJhqUzD7rk5GTiPnPweFENKnvFWKSTgoAgIAgIAoKAIwgIpegISpJHEOjdCJwtMK/fl7t5X3Z+iYWRIDwMNHonxAQOHhgQbPR2ZGw6aEcvD6NBGxHqGx9tPHY6P/ls4ZqdWZmF5ivGhYwdaPDRysPk/7N3HuBxFWfbtq3ee3eR3JtkueKKMc2mGEwJhBZMDwQIkJCPL/khgYSQfKGFYprB9NAxxbiDKXHvXbbcrd57l/9bnjA57Err1Tbtat9z+ZLPnjNnyjPnTHnmed+xBki3CPPVpvzP1+ZmHausa2gJDPTrkxTZOzEiKS4sOjIorM1xYvumr2haG9m9p0202MxfGMbyyvqC0uri0tp9xyoP51fDMq+KCxo3OHpEn9ARfcLF56ZbVPZPM4GF8rFjxxAJfvbZZ3m5ucP797/ryismjBhhA59IxH6+vhNHjjxeUFBaWQkT9/zzz0NWnn/++Yh1fprsf35VVFSQ7muvvcY0e/bs2bfffrtb8YnkEgUlFtmoilSO/f39YRXZ4zUjI2PmzJmye0y71WrlRShF2XvHSqwkmKcjoBYk8LHIMXLkyFGjRrGCwoYtYWFhnl40yb8g0O0REOq/21exFNDhCAgL4HBIJUJBwI0QaD3RIyuv9rO1ud9vLywuryNnSBQHp8UNTo1BjBYa7N+pvGIGGxkWyP6/YSGBkeGBe7KLVu8uzimqnZYRd05mQp+YU+zq0Km0JLAzEMBV4idrchetzzuSX4MKq09y5JC0WMhEqhWxKpJDC4lyNzDAl38qDEMuNgevqmmoqW2srm3MPlJyLL/ieGH1gdzqxCj/zAFRmf0jRvePIlYLccotVyIAn7h3714YvR9++KG0pGTEgAF3XH75pJEjbeMTVc7DQ0JmTZpcVVv76TerduzYUVdX19TUxOTZnFVE+vfFF18sWLCAvQuwCmRTF/wnurL41qRF5g8fPgylSP7Z0ZU8UyIexHpx9+7dV1xxBRvRwDNaE5WEMUFAKEUTQOSnlyBASzLs5OEl5ZViCgLdAAFhFbtBJUoRXImAUIquRFvSEgRcikDLiR57cmo+WZ37w44CLJ1Rn8XFhAztHzcoNSYqPNBm52XYR8dFBwcGJEaFB+09UHQov6Lk3zll1U1zTksakGiV5tGlKEhiPyJQXNn4r1VHlm8tLKlojI0JHdAnql9KJG40NUv4Y0Cr/uf9CQrw5V+P6BDGXvExoaXltXsOFO0/VJxfUnsov3ZDVumcyQ1nZcSHBEpHYxWkTg0ENcZ2AW+99RYuFBsbGtjZ+bZLL52ckW6/PW9yXOylM2ZU1tQsXPUtJn5vv/027wNOEo2sIhZ/uBV7/fXXCwoKkDHeeuutgwcPdmp57Yz8rLPOmjJlCpGgu1yzZg17uX7zzTds8JqUlDR8+HA7I/fOx8Xw2TvrXUotCAgCgoAnIsAol8MTcy55FgRcj4DM9FyPuaQoCLgCgfrmHjuP13yxLnfNzjY+kW1Y+veJHto/NiU+HM+J9ucArSJSR6jJjbt8MIJesSm/tr7lssnJw/uIXY/96Do+htLqxgXLDy3ZmO8f6J8+NKl/n6jk+DDehF6OGDAx6kqICeFfVERQeGjAvsPFlVUNu6ob2dqlx4keZ46KDxVW0fFV2okY4RPhxdAnbtiwobmpaVha2i2XzJkyKgPL5U7E0nHQPgkJsIrVtXUr1q+HVXznnXcIa2QV2Q0GlR984nnnnXfzzTcPGTKk48jc4g6MJ34h2UgB6MaNGwcVu3z5cjDEhpHNZAID/6PILi0tRdKILTk+IqFQ+/btSwAMpc3LkJWVhf4RhSYR4motJSUFo29cNBo3QWYj7KNHjx46dKisrAzEmpubleU1JCaW154+txFK0fytkCuCgCAgCAgC7oaASBTdrUYkP+6PgGOmE+5fTsmhIOBVCMAnbj1ag7+8DbsLMEqNjQoZ3D8WfWJsVLCFPVg6C5G/n09yfPjo1hNNTS2Hj5et2laAXe2VU3tnpIZ3NioJ72wE3lxx5JvtRYkJEbwGeE6E+HPgm6Aznxgbis9NbOq3ZxXkFVYezKv5YkPe6AFRQilqiFx/gs4OhR2bsaATZF/mtOTkq2fNnJaZ6Sg+UZVoaL9+15w3i3PNKkKBKQtoSDRsotetW4c7wptuugkTQNeDYHOKGC2OHj26srIS3hBCdufOnfn5+fhHw4r84MGDn3/+OeWCKIQNDA0NRcN42mmnXX755cnJyTpFyMEvv/xy5cqVeXl5cIUNDQ3R0dHx8fHp6elXXnkl7tUUq0i0GIavX78+NzcXghJdJ5QiNBwEJcGgFHWEHnoihs8eWnGSbUFAEBAEvAoBKEVhFb2qxqWw9iMglKL9GEoMgoB7IaD4RPwnwieyn0a/lKihA+L6946CRXJ4RpG4IXYbNSSxsbHleH7F6p1FrZhb9+gjrKLDobYnws/X5325Prd/v9j0IYl4TsQnpj2xWX6W12zEoPiw0IDte/NxsJh9vHr7karoMP+QgPZ3fbEcm9y1EwH4xMWLF2OMjJgO6go+EeLvrAkTHMsnkkl23hiRlqZZxezsbBLlOlpFNH1scgIphgtFT7QahhtldwWUlVCK4AmBCKXI30WLFr377ruwjTCJ/fr1gxP897//vW/fPqYid955p9qKBFoQ/OfNm3fkyBHIQSXPzMnJ2b9/P/4Zifn666+HXiQYG9e88cYb3OJn79691R7TEJeEQf/IXzvfhC5/XFSKXV4FkgFBQBAQBASBUyJwklE8QbfbDXreUxZWAggCDkFAKEWHwNh+JDRJzAfs91TVfuxyVRBoDwEjn8gWvUPS4uB3YJEC/J1F6MBP9U2ObGhsgb7ML6pas6c4JNAnPMQ3NS64vQzKNVcjsDqr5M2VRyIiQkYNTUqMC3OGONGkSLwSUNjIFZua2+Srn6zOiY0IzEwNC/D1eFrEpKRu/hOxG/pEEz7xwqnTItqzzLW/LOasIvbCRAurCCUHDQdZZn8qXRIDpB6ZhxsFUvatRuyJ7hJRIXyiEhsiS4RFZStt7LuhGtFjDh06lGBIDufPn4/JM7TjVVddpeyXjx8/jryRv7osqBfZMwc+kS1rLrzwQnSR7AwLngwhGEhgKK1Deu6JUIqeW3eS8y5BAKkyCxVFRUUsMOAqAR20MRvsJYXwGW8SuEdA+i3bRhnBkXNBQBAQBAQBVyLgakqRwTF9JKPn6upq+r+EhASsilxZYNekxUQCCQOulzD4mjhxYjcwWXINbpKKnQg0tfTYmVP7xfo89In4sBs2MB79IFupOHudDb6yf9/ohia8tDUXl9Wu3VsSHxlw2eSUmDDZGtXOKrX38R1HK95YcaS6oXX6hBR2UHEBn6hzjBH0hIze/n6++4+UfLYuLzrMr39ckDP1kTplOWlDAFPc1atXv//++0qf2D8l5aqZ5144dWpEaDue/hwFmWIVrz1vFlrllSf9Kr755pu0P1hAey6fCDgUgVk9U3qGLtCI9Oy4jIRDZJ6Pd8jLLruMtUO4RcSGWEYXFxdjYw6lCCG4a9cu8CeGSy+9FKNvRQowQuBB2MapU6fGxMRwlyuqClAy4pARggDjaDg4ddHT/wII5t5CKXp6PUr+XYwAzcLWrVtZuoiLi2NXq9NPP92YAT4r1mxohVitcX/vtMacy7kg4OYIQFa4eQ4le4KAuyHgUkqRJTX8jrPdJA7IWedn88S0tLSxY8fizhyrKHeDxp78MJGgm3/iiScYRjPf+Pvf/95t5gb2wCLPOhuBw8X1Szblb9hVwJ4bwwbFZwxJiIl00ZcVHOg7OC22pq6xfk9eUVn9ys0F0aF+M8ckhgW5tJFxNsIeFD8Douy8avjEPUcqR49M6d872s/XifbO7SLTLzkyMMAP+eqmfSWJUQFXTE5OiPQXpWK7WDn2In0QrBYTzs2bN2PvDJ/485nnzp42LeKnOhfHJqpig1UcnpY298ILggMCvtm4EYeDZAPNHeI7j+4HjXMMiEVWRikv+sHMzExliwDnyDkDm8bGRsycuUstYAetYEGqqcc51MgZZ5xBhMqLIgHYB4bdWqAPMIh+77334CWxfebgIn/1bjAqKo/7i003nihBiXfD4zIvGRYEugoBGhMO5My4WOWE5oVGRmUGcQbLFR9++CGNDCsQ3O2qTEq6gkC3RMDY43fLAkqhBAHHIuC62T7kGgZBTC2WLVuG6ZAqBgPl8ePHs6/iueeey7jZsWXrwtjo4ymjmnKgE2EtEaMny/kBH0bbHM4WlFnOhtz1XARKqpu+3l60dmdBc2srLvMyhyaxHbMrixMW7M/WH5XVDXsPFB0uqFm0Pj8hKmja8DYNjhwuRoAV1uMldWzJ8u+dxTjTTB+U4Ofnaj5RFZltoMelp/x705Hlm/LDA30uHJ8QK9pV578NMFnsx8IOxehc2vjEc8+9yCV8oioZHRms4s1zLkYRuXDVt/Br7AHNZBiVjYeyisDIOijdOgMVCsJ8HlaRwjKGwSZalRp+EI0hOkQ0jLhc5CJPYa+g7kI+agKRK3T0xr4eow0cTcJFwh1gUs1f+EfSwsRhypQp2DoY93tREXrQX0Z95FZUih5UZZJVd0CAhhSXEdOmTXv99ddZb9i2bRvnKmNMK5YsWYJiGu+0qKSNjYk75FzyIAh4NAKKTzzZS8siuEfXpGTedQi4jlLE5Qdr7x9//LGxcIzL8R9EN4lu8aKLLqLvpAc1BvDcc+YSKvPQi0wqLFCKBEBOsnfvXgbcY8aMQbkpLlE8t967KudQSGv3la3amtfY1DpiUELG4AQX84mq4OwoPSQttqSsNreg8mB+9Xc7i0b0DYsOFfNnV78XLa0nlm7JX745PzjIf3x6SlREEMJVV2fix/TSUiKLSmvWbzv28Q/H+sQETB0eG9BF/OaPOerm/5eWln711Vfff/+94hOxd3aNPtEE1t7x8Vecc46/n9/SNWvp5dmihAE6U2JPZBXpxLFTZuUPPhFFIeSgUiaCMMbOuuD05vykmOouJ1o9BAWJVJMrOrDJybhx47ANx24DiSJp4UCNcdEnn3yyceNG9oy+4oordFQmD3rKT+q92wzwPAVzyaenI8BSBJvI05hj4/X1118zR2DdgoYoKysLP7k0R2effTZaZmMxYRsRNqJpoC0iALMPFiRUi6SD0VKx7IGjRkhJYiMkbRotDMnheMHTZdG6mHIiCNiGAJSiYhVte1yeEgS8EAEXUYqsvSPRX7lypYKYrgsXinyuOHviL10a7pYwj7r66quxBuoGnRmFosNWheWc+YA65yKdN1fo3TnU8Lq8vPyll16CWmWygWkY7pYGDx4sI28v/BrtKXJOWf232wsLyxvwnzhmeHKX8InkH94qOT58UGpMZVV9dW3j3mOV2w5XzBgZZ0/R5NnOItB64sSx4trlmwsgmlP7RLN5jitdKLabW3ZrYffn43kV6/aVDk4J6xPbDV3otltw11+kl1m7di2zTVR1A3q36RO7hE9UBU+Ji7vmvPOS4+LeXbKUMQCsIiK+CRMmuB4We1KkB8dhCxs00y8z5cYHNLN6JU4EZIg/DA+Jn3EOU3SuRERE4CqRKwx12AlaJc1m0Jdccgn9fkc5YQBAYA6WV2EwGRHBICxdupStXWAVzzrrLI8WKlJqUSl2VPVyXRDoCAHaEKTKfP7s8oQXCyTMaJZZb2A+xdyBW7ip1c+ywgHVyBbzNFbs9USLxCoFrdM555zDioX2XM80hM3r161bh5tXmhpWO7hC04QyetasWddcc003mIVpTOREEBAEBAFBwAUIdDi6dWDa9GpI8Oj/6AWJlmElQrzJkyfDrCFdxCSKLpBZEEN2/J0zqsYO2hNVDEbEKJpWKaLExPqMK8qnO5ZTnLMYyDFixIj+/fsDCwUnGDEsXLgQBcR1112HxRMjCWOccu4pCLD2i98o6jc2NpZppwte5ubWE6t2FmUdrYyKaBMJdhWfqCooJMgPp4oVVfW79hfmltRvzi6fMDAqJNAVTY2nvCHOzmdT84nFm/MP59WgCho+IK7L+UTKi3y1X0pkSVnNpv3lqBQTowL9fDqUazkbn+4dP40PO4MdOnhwSGrq5WeeOXsa+7H8ZJ9QFxc/MjR05sSJ0eERbyz6MuvAgZdffhmxnuLgXJyTTiUHjUhLzl+6bMhQtnLGyyH9MipCqD1EPWh/oA6RE3777bfsjUBTD/LKwpcJuSogs3TMEtWmLuy7DR1JSH7SueNammk8GiJllMBPRgjkkI6Dp9izBdYStRFkoqIGCNyp/LthYKEU3bBSJEvujwC0IDQi7QzTJdp22hbaIqZUtD9QjcynVBGYWcAPPvvss0jU+dZYnKAhIiRtCMLnBx98ELf1ajiKZvy5556DVaTxUU0NzQ6RMBHjcMGQ1f0xlxx6OQJ8TSBgwarAy/GR4gsC5gg4fZ6PDpHOjE0n6eRU8oynIQ0feOABfrI4hphCeQmhJ0Or//jjjzNeZxTuWTI9Jhi4T4IWhD+lyMwEYFFVeZmToMFctGgRpTOZFcydO/fee+9lfoXZAuwqjzOvYOoCz4hckevmFSZX3B8BlpHxGcoLzMiPCSSzUHbrY/tONWhzRv6PF9dt2Fta3dAybnB0dISL9mOxUJDYyGBYxYKSmryCyr1HK9gkZFTaf9yNWXjKo2/x4fN107h1+RCktfUEXhS/3lqIhWViXFi/pIhevdyCvGN/mANHSnIKqrYdLB+SEpYQ6ZHu5OmzCgoKmIYxnevyujb/ZNCt0NVu2bx5WFraFeecPT0zs2v5RJXD4MDAyRnpLLC89vnnG7duZTZ79913u/kWpVu2bOGLpkeG0WMGjvyQJSI2W8OzIW07B6MU6EWEhMztmX4wscd/JfuQMEunaDiJpuwEY+GQaT/XcYX22GOPcQ4XCaVId4+eEf+JPEgwbNWhI6k+3iuIACLknHVWFlzhFhV9aV7dnnUFqoKSelaeJbeCQJcjQEfDYBKl4QsvvAA/SLOAryQWPEaPHo2iWWePQXAnNFEAAEAASURBVAiiZuYaXCEwB2NOmh3mFMgbuaXGorQtn3/+OcNU2hl2nIesRHat1NO0eFg90+DoOOVEEPBaBBSr6LXFl4ILAp1FwLmUIuQa62CvvfbaqlWrVM4YU8IYDhw4UE3GYM3OP/98htQPP/wwIQnDoBwr4EcffZTVe/eZsNGyMAGgOBx028wHGPdzqPExFxn3M+tgDoDQgAknagX8nqgiI1fkOof6qf7Sl8M+wKISMxZSGDsDBZEwryB+DJ2YbAilaETMg855yak73mTsSnhVeNtxf8PkE+IYblFJVBxbHIxJD+dXwx+l9Y5CJOjYyG2LLS46pG9SRGFRdV5p/aaD5cP7hvv5dFvVLd8sHy+jdhYDUlNT0RQ4jz4+ZXXUN7V+uTHvWEEtTOKwgXE+Lt/luaMcJsWFxsWE4lRx84Hy04bGxIb7u4N8sqPctnudxpx2nhkaEzw8//I5QzM544tuN/VTXkRPB721ZPHiqKDAuRdcMH3MaL+OzWxPGZtjA5CTYan97r7yipc++eSbH36g42M5bdCgQY5Nxf7YGHWogQfOyzhozLEWZI6NwGf69OlYLjMtV6nQsGNyCNWIdOjdd9/lIg/yMvBiXH/99XrPFvr6O++8E1sEDJlpJRA8GjNJc8EAgCRQO+I2kTbEeJcBBsMMLBZxCIP5gvGWJ54DJh2iJ+Zc8iwIdC0CdDR4VGQBAzcLb7zxBhIEGgRIQxhAnTEIQXbBohViBeLPf/4zy9ics/VldnY2jpV49tJLL6XPou3FzSKBGajMmDGDAIxX+TZ1PHIiCAgCfCaAwBfEIWgIAoKANQg4kVKEg2MlTfOJypZn6NCh+BJmoV5njutMz37/+9/fc889DM25/sUXX2D5CwWj1s10SAeewOXBAhC/5X6UNgVNCjQf8wFYQtQKdOSQg/AF6enpjPIhQ8kV5NEzzzxDh91RDmmSSIi5ATwpUw78lbAqyFBASxExA2e9EVkEDlDo7DknWEexyXU3RwAZC680bwXLwhAQvNXULMvCvNKTJk3izWEkx4STqaZDClJd35ydW93U2gMVWGSYY+K0P2NhwQE4VQwNLS6trN9xsKJodGNytLvkzf7SmcRAW4cWG4tOWgzG6Gxri0yJsbvrV/sZBVXUNH2zrYhBUEhwwMC+MW41HoqJDA4M8NufU7XnWOXglNDIYM+bxkAhQQzR2iNU5FtmtQBvVrTn/ESe1oVoM0VcvXo1+uj6ysrbLr3ErfhE9b1AJ/VJSLj1kktLK6uwTuAi/b5m6Ey+qa76SbNMherGmY4Ya2VYPyoavSF9t84YX/fMmTNpzHFXwioglgo8xZCA3VcJrINRapwjP//889hqwBgyfkD5yF3oQkYFuqNnUKGMM9RCIy8SAbjLkIk5P29aF75auiw2nzDWgo6n4AyoOmIVLRew3bvtXjRm0kIAC7eIoaO7HV1XibZ7t92LOpMW7lq4ZVsOLUeosyQnbogAdUczQoPDXAP5BU0HOmgEGcas0gXQN/F9MdRE2YCMUd1lrkHzgpkUplRcIQBNmfKo8OmnnzLjYHWEdowRC71YF66GGssi54JA1yLAYJ5D2syurQVJ3bMQcBalyLCY1XgW05Q+kQElQ22WyFDpm08huMuI+a677sIamnE5CMIq0ufp0bajMGVQi4oQZpC+lpG9mi3A9LEAaNKP0vWiE2T2uHv3bvrv9evXQyZSKJ0TykVzoyhFnJUgZ9C3TE6YGFBkJgbIHCAa6Lz79Omj3CcZQ6JTgFjkMF40nsOBknnMqNWEhCEF0xs4SpOcGx8xOSf/0KMMO3iWBUz+mgSQn45CAHgxJ+FArLpkyRKc4DDnxAkOTATCHFabGQ5ywjozLyFviD3p7jletetwRXh4cEpieGCAs77ozuaQhb3I8MCE2NCKyrqSyoYjRTXdmFLkM2SZhO+L+qWWcY6OPRHEIswCb4LWK3UWQxvCN7e0Hiiozitqkyj2TooIDwlwqwVWPCoGBfiydc+uI5WnDYn2OEqRyRiEETM0Vgv4qJEEYtDK+gFfNBsZozhjSobiw84v2oZ6p2vDkA1vfWVFRb8477xpmZnuo080FgcAU+Ljbp5z8bGCAtDj60CrCGjGMF17ztf6pz/9yco8qF6bhSIsFeiaacyNnKMxEkp6++23c4VxBWJSTui4GXvQC6tJC3withrcIipaEgZFRAVr6endNPlntENPx+iFoRR/VXn1VK2jE31dwah/qhPjX2MAHcx4kXMrw5uENMZmjMF43ZiQvm5yYvLT+Ig6tyZd4/zWJEKTnyax6QfNg7WbE50lfaIf1Ff0iYVbhLHnrj2PW07XcsynfNbC43Y+y5oEk5GOViJpQ9jYiqkEtswEQ5xhnEzRBdC2kDeqm01XsPTSmVFkIhMHJhHqZUAPocxoWORgLy8+Ujov1sIZtLCgQuT6WSKUQxDwWgTkQ/DaqpeC24CAswgIqCuYFMUnMovA2PnKK6+84YYbGCi3m0u6tNmzZ7MdJBQMfR4MHQwjPav6npVOkAcZ7tOtdjTIpk/lWZIzbwW4DkuIXoxdF9977z1IQGIjGAQfC3o4SILiYQSvk4NDxGoVdgD+kWjN88xFzTAyDoBTgKYkaUXz8ZfOGwsFHmSagV0zllDmkVh5hahwzkieUX2yCAkZSj7BgUEAnAXmtJwzjyV1HSGP4KeZKyw8KrjIMM/iZoXVS3IL2sxhrKcjdcxy0ikEIJ2ZSbKYjPsbptAw1Iz2GBF+/PHHaFFhkKlBrFSoEWannYpZBz5YUINQMa1fdLB7mDzrjEWEBibHhR08WlLT0FJQ4fF7C+hytXvCIj8b1iNRhE/EJxo7MkE5YQKJsSQHXyhtl/ELbTcS+y82tZw4WlRLPDCJ8Hdt/7nTEYtdfiAcSo+D+dVFFQ1DUzzSXSydBQccIhUNS0KLirdcuEX1RWOmyhdNdbtStIiIHpfEe3bv/tlZZ5192mnhbuwMC66TXclunjPnsQULPvjgAz4c+seOZtHu9PJ2mBe6Y/JvZRGgETnajYvREdQbR7t3PfQiIxOGQCihaP2UebiHFqRbZluNeNVfXUB+MmA23tIBTE5MfqoYzC+qKx1dNz6lw5hf1Lf0iXkYrqi7Ooz5iQ5jftLRsyqhjsK3e90EQBWDMX7zjHEFzcEvfvELhg06ReMJAVjNYrWSASTNJoMN413OVZwkjRcFPT1RYRT5qAeZDP5/97vfsQLKwRyH5RDmCyjc6dGYpjGS4Zs1iVx+CgJehQDfkVeVVworCNiPQPsEn/3xopiAlVN6OiZXcHY///nPO+ITVXLcnTVr1osvvsiXjKQLW2PWypB70DVCAioXIUiB6PCg0sxzSFr0ozwFiQaDaaQdiZC1cWjK+fPnY4Kqn+U6PB0H1CF+0+mhmQRCvZHcq6++CounQ3KdkTFzBjg4skTPrYxYVQDOYQyxbCUAS4is9TEyoAi/+tWvEF0ykuZZHVWnTsgMC4/wUHhZgpBiXG7yOEME5JzAC20BLKrUJMoKJPwsub322mshrcgw7lT+3//7f9jhKh0oxNYf/vAH9DWuF9SYFMEbfrL1Hrb8rAxDMzGGg9tFjQLhzoFkFWIRnQuLwwzj1DtmPSatJ3ocyK2ua2iJjw4JDnQv2WlQoG9ifGh0VHBtfWNBeTenFKkyvnQMJNlzCQ9H1DKrF7QtGDxCH2OvxJ5UNE00BXrpwvpatj4kKsXDhW2UItMLKEU3YxR7hIf4h4XQhPbKLa7LL61vbG71dxtXj9aDrEKe5Iqn06EoN1X0PqxCYc/LMhWfM3c5gR6iui13fJ1N1zw8fcSCBQsQm0wcNWrm5EkJUe6+FVJQQMDZ48ftOXTwnSVLseOjv54zZ46zUTLHTa64AAFEl6TCGqfq3axJkYGZNcEIc8qQpwygE7IypDXBHBVG5c2a2KwMaSEq81vmV8wBJ4w1wdrNns0PmmdDxe/Rfxmr42CBgTqHhYIwE1FLF7SWJqwfww+6G/QN2CHBPP7v//4vIU1iS0tL01dodZkdXHXVVRhjMR1QQ1P0jHRnrIoxa7CQDbklCHgDAu22Ud5QcCmjIGAbAk6hFCHC2O9YuSGnh2NyBeNmTqsRDKYPN2SKraNHRPrB3iyqJIxB1fcMS4gAhK6O65ib4VeoXUqRpTZINGbvzOfvv/9+tHsqHiKBvmGGjyEAUXGRhGA56cJJmskY2UBg+Le//Y21QVxiERj3IkY+kY4Zm2WsDOhoIYCQGMDc6Y6ZCOmbb731VvpmCD5jMVlIZJ5JBiiLyoyFv4y8yQbRQqQCGiHh/ig1ZadQysukepzUyTzZZuiA9BKXKBC4TGV/+9vfKuEh1+FPESRSUoqMggYukuLjqFHxicSD1y3kVJQXmsNCruSWAxHg5WEMhwNN6gu+CX0T1cp4Du0GrxzUMOaTvGPw0dAQHEZavKNsVNU1H8yp9vXzCQ8L8HW//U9CgwJiI0MOHq0rLuv+lKKqI8b6MMisfFDXNINffvklO/CiIPvXv/6F1RLrDZjDqxbPGSq25tYTx4rb/CUxMQH5jl6bLrweHhYY4O9bU9t4IK+msKKhd4yN4twuLIIxaZSJHD/72c/QpUIpwjDSd7B/C7478OaBHRmVjkKE6R/VbXzQUecsubGaRQcXGx196YwzhvbpA9HiqMidFw8WwnMvnL1p796d2Qcw+KXzhYE19qrOS1pidiUC+Pdg+KeGXmpEp/6SB32iz/UVkxP10/jXWATjdeO5jtZ4YjxXgfWVjp4lQLthTB43CXPyof+WsaPIjdd5/40/dfwmMRvDqFRMAlj+qaPV8XCiDhXbj7/+e1Hf1bdUEsaf5s8as2EMaXJuEhV3LTxoDKyDcaIO9eyPvyxdtCF8pyI3D2x+xZgHyL777ruP4Z9J5jv1ky6GORSDfwYezAIYUjJ5YbJA0oz8GU9qAQETBy4yVmGOoGYBsJDYPzHjwNupMqDuVNISWBDoZgioD5Y2maObFU2KIwg4CQGnUIr0SXBYSqLItIrpFuIdkwLwuaK0R1tB54c4EZECPR+HDsYcjN6On8j94P7Udbi2jrQMxKMkeAj08A+iKUX6TrpYRIgMamka6HRhdjAugLiB2cHbI50omWE3RuyUofNIi2yQNJydSpRu/rbbbsvMzIQxVFnSmdQn3OLQPzmh81ariIqyNN5q9xyO6fHHH+epP/7xjwwLSAjvjVyB+NM8IBcZIiCEBFVAZmmRMHCgjB6gCDFkePDBBxHIUEyFJOUiACFfeeUVAqga0amjzQR5cZuiAFH9hwZHn7R7vd2LPNLudZOL1OBJL4sTsZeEhuDlhIbAtJ+/kIy8RbxpBICJYPtgRoHYzOrMmJ/sz63C6tltOz1/Px/MsRsaWkoq6puaW/08VpJmjvwpr1B3fKcM65lRQzCxhwPG7yyKsCKCLhWzWT5kmgjaNEI6atTS3HLieGEbpejTq1d0hDvuh4N2VXHfeWV1ZdWNnaIU+ZSMyzOARpOo/56yRpwXAIEJewFzsEiAewoU+nzO9C980Sw4QSyyEkaPQ13TMut5nUPyg8kzlCKNyW9vuSVj4ECP4BMpOLUWHx31m2uv/dXf/k4XRk/37LPPOol1dQjOEonNCJhsImFzPPKgIGCOAJ2COrhlcvLjnf8usegr+kRFqH/qExWbjlNdN/7U5/rEJIzJde5yxfyivt6uVEI9YuVf+hfWMpn+YMiMERK2EYgN4fRZdmK2RQfERIzBBikiRaTVxYmtmmeh7cBiht6K/hS9RTfzvWAlehJMEDAioD9n40U5FwQEAQsIOIVShE/kUKky16JLM88BTB8kF2bO3EJnRz93wQUX4CJE9a/8RKWlptlEpbkw2D2kf+axQdvhhPHAgQPcYs6pbG045zpGpi+88AIzLn4yY4GsQZDINI+fqEvgdzAHVm5HYBWhAFiyw44YigcyTrGKWAQgNsQXJEJFnGQxJ1QZIwYLB32zIhmJROfHQni6czJJYdES0vfTr6O75IrmE5mIAib246ifFM3EuAHo0LgxPoA3hEtlGPHcc8+xMRzlUmnBkKJSZC9aFQ8++7hOYIUMSZCWYydy4E99GWf+esxkXnwLtwhs4a5tt1QGjM9ybuFQeVCvQbvBCMBdbqmQ7YbRF3VsOjwvMxsW8VYrAgJ2m1eF74KDT4CqQe/25z//2cL2BXtyqqrqm9numUwQv7sdAf4+ocH+5Ky2sbWwojElxikkF9+v+oRtKD7fsvqc9V99YkNs5o/QDigVM3wTUjJIZCr3ww8/ZCcNtM8sANAi8cGiW+QzZL1EpW4ej5VXWlpOFJXVEUlkBOsf7ri4GthWyra1osbmE2gqrSwXwfhqkFEAoH6EGRQzIppZ9bdd6LioDp768bQNFs71FZOfOph+kABWHnQQyJA5YPqU53v+stUv6zcI8ahuvGQQRtU17watusqJlfGbB8MdIR3f6VOmTBgyONSjdtzy9fEZM2TIxdNP/9fSZXheptdwbE9kjpVcEQQEgW6GgA2tdPdAwLzjoGdlqZKpClYv9JWMMTh0YR966KHLL78cKysmX7hNZF6jb6kTHqdvYkDCYqfJLfkpCHgbAmqa5m2llvIKAvYg4BRKEcaKQ2WLqb4mxYwZRVjHpEtdgRrDLBeqDjpM0TesrTFLVF0mdJ7mpyAB2zXUxXqU2BTzyAqbYgyJHFNilEGoRVRC8HSYJ0PWsChHxuBxnn76aZUisztW8OhTCfnLX/6S1BEwqjhpWfCJ9pe//AUbZPwW4xEPZR+RmPfoKhX9t1NNko6N5US6fLJKHpgzq9i4yxrmLbfcwq7ZSoHIdXhDjMqZqTKAQIYJpNjcQSA+8sgjFJAAZACW6h//+IeKhPDsZcm07a9//SuocpFywWdRHBXA/r9UAaud6HSYSIMwGeBQpBsnKn798+TNn/whgA6vztVtVUfqnOvmMZgE1iE5MQmvQqoYOHfbAyR37tyJG03qCD6io3zmlNTVN7Sc6ImotqMgXXkdSjEs2B/2Bt61ybBhugPzRFWynMBhQ5x8Vorc4S9fNIc6URc13aO+TfO/KkX1jpmkbn6RzxZRMAeya6SpqJJpfzhwtogbTXSLHKy+qE+eT1V/5iYxW/4J1GDe2NTq72/XNuKWU7HnbmCAn1Ip4kgRTaX1UdEq0pijxdai9VM+Sw1SlSDJwYnJ+ckK/0+lc0vVPidUAQta6i98JVdOmVC7AWjDqW4k5yxr8S2z8IMVPMsDLFyhQYZHZnZHjdspCWEJim5uaGq/2Eh3d6FojhKgX3/h7PeWLed7YRig1xHNQ8oVQUAQEAS8HAEGIXRMSAoQB9C7maNBbwV1iF945BpYbunJFxMc+k218srsjA6R7kmPUoiWA9fq0JFMcNQgxDxyuSIIeBUCfCDq0/CqUkthBQGbEXAKpQgXxqHyhFcOpHaa49MZ5UNlCqd+8t2iCrzzzjvVT25hK60kflxRzJS6haqLWYc6138JgPwHZ4LqCsIuTEc5h2ugT2WvFR2SnLD9LoIg2EP6VyMNgbsrfDkpSpGuGltFZvhQnEz+KYLKA9QkPo+hO6+55hoWA5kcatJBJ6FPKJTqv7miT/Rdenou8rhKkeuUSw0RoAWVqpEuXxeWaSdkKGuMGjQdFcEwcEBiCZnIg+gW+atVojoYQw1YUUyQOGHpEuKSPBBM07U6pM0nAA7/xaY0xhj0qMV48ZTntj2lorXmWQZYp8yDywKQYXUYU1Q9Ga8H9Wu8bnLO7haI0eqbWk90RvBlEonzflIKtHdBQX5+vj1DnLMhNWpi/CfgqdD8K7OzXHyPbYST4eDbUb84UV+r4qb5a3JCZrjCX2pWnZMZdUWHpHK5y2cIK8TBHAC4VJ6xA+VjtyH/ilJsaGxtbnZLjrlHD2343NjcwmYy1peRxpBWF58VOKa0/inApz3ksP4Rk5DUEVeMf/VPHVLdVT+N5zqAPoH+Y9GFgyus5dCV4EJL37XhhO6Md7K6pLSxtq7HT51v2BCbix/hdUe0il/F6tpaxgz6/XdxNiQ5QUAQEATcHwFGgzeePCxklVYUVxscDC2UQIGRBrMVOlA17mUaxWCDeQ22zyxdc5ElTDhKmERpgS0AK7cEAUFAEBAELCDgFEqRbo9DpcomLWisMPFj2mPMB4whdp10Zkywjdc5p/NjoYxJu7pOJ6f7OTVFNwlPEszQlOyOW/SLyryX3hQrOXWdGKAA1OMo+JSIT8dDj4v5M+nqhLiFfuSJJ55AcIevfeJnKqi4APR3HLhIYzbIVjBMC1U/rWPTJ6pozDDNabtly5YBC4+znKjIUxBTEKEr1BpPHRUkKRZzJhjqu2CllYYkiskDh77LCTl84IEH4BPV8iNsKVbS0LiMKpS00xjY5nNSQXpz9913K6D0JFz/5EpHF423ODc+Qn7UXfOLXNF3VRiTv+oRkzDqorGubS6yPQ+qYoI/Azvqi7pAh0WEZIwXkncYIp7laDwqWkglwM8HZ3KMHd3T8Jmckz8sHMlmaEA7i+oWimblLZYH8MSKCT/sv5WPEMzK2qfF4DDK4mhGFLGo/vJJcqIO9XkiFuagRqhZTniWz5+fOm/Uuz5XJ2RGXVR/+ZYZ4puEsfInUQX4t9HlTc0tVj7i4mBIFJVFdlPziZZO8uB8FDCtkGguyzM1wgvAh4mGjr9Qk/xVFUr9qlrmrz5RF/nJU7pOdcNlzDY1BYmGLwvjRRvO8dLIytl3mzZNHZWRGB1l5YttQ0LOeKS2vv6RV+dX1dRQs26Sc2pNVZwuLxlzk7zpLMmJICAICAKWEWAYaS7mUI8wjGFsyWE5BrkrCHgtAibDAK/FQQouCFiPgFMoRaZ8iP7gyNqYrfJydiRgRxSm/Vp4SP4Q3kOTzZ0797XXXjPJLg6GjRMMmD66RhUGLQ+2z7g71I+w6QqOyYxuQRj9K44Pa2jc5BOS7hNbM8QgbCeNvaF+Vp0we3/mmWewIDYn7EiXTXgxUoOwgATEayEqPPUUPCaOC5FA3nHHHYgEVYrGmHmWnHOF+SRskfEWmGC+B5EEXwkIJpQiZYQMNYbnHEA4TC7qn2SPzR/UTzVWMO5YzXWmnYgctTkDe9eocx60R7+jM6BPKPVdd92lf9pz0r0bdF4JKhqqGiIMelcDBYBwiHwC1Je6aHk2G9CmUmwzK2YLXffc/wR6rbqmwc83PMhpprjYlmLLz/ZK6tsHEQ6Tc/2TE31uEsz40xhMhdd/dWVZf6J4SejFk3xjG8+o2EYaAV4DzJ9xI8tCAk0QzRFtUWpqqvWRG0OiUgwOYPEGTtN0qcYYrAvPYdt4XckAr2unDJ95hK+DhSgO1+e/s82RIiJpXfm6MXmmqafvoOVXOafNx+qZ95aW2c6y0PvQ/eGL8LNvv0uIjh7Yu7edEbrs8YbGRvK8auMmviz8FNNzuSxpCwkh81fLhyoMuWL5kPGMhUfkliAgCAgCgoAgIAh0GwQY8nV21Ndtyi4FEQRsQ8AplCIzcyZLSOG++uorsoXzeHYxxt8fgn2kdjhD5ENl/sws2kim6AJcdtllqH70T+yRNRf5zjvvoIPDQZVixLD2RcCPgyqjDJBZOjwjq3NY9ar4oSBxEYLRHH4D8WmFQ67s7Gxm9cSMFzMUkXCg5FmnaHLChAclFKbQ7KSBtBD7YjzcEYZSYAqNp0ISuuKKK5juGh+kCMrtI3NL9IDGW+zUzEWuQIKgalG3mGEqTpOMoaxEFEMMOk6ki9B/ZNgYD+fIYcgDHiGVETc07uzZsyExMfHWIRHCPPzwwxpDrjNBgtLlhJyY0J36qS4/AfYuz4PDMwDFABm9YsUKWAAoBl4hKkungkEKrxlW/7w5VhYfSRrkGTEUltX0q2+KCP3vnuk62i48qa1rKq2oI4tKOue8nOBWnMPO+K3E3IZU+JDbnEGEhuoxCpu04KsBTplGgI+RhpEGioPVF37aTK+gCY0J9zuShz31f98rGzLsvEdwoajEiVFh/qFBP2kznZeo/TF39t2gU2BBi/5i7dq1LBHxmdOe4/aenpGDlSR6KOLULbzNOcSc7de//jUN/hfffZcYE33teefFR0XZHJvLHkThuW3//qdPuiVhtez3v/+9+ZKeyzJjTAhvJxg3qA6a63yMbJDluZQiAwnePV4zhkwW3mGGAQyKGB3xl/AsOrKYim81C+MiI2hyLggIAoKAICAIdBsE1FidTtNCv9ltCisFEQQcgoCzZnQQf1CKzKZg0/gykeSw+L9t2zamVchw+EQxPWbUbqQCdXmwLOMR/RljNM0cjFkZLCQDX8b3MJVYJcMbMmeDa4NW089yAs+4bt06RJHEowycGRaTLn9JGlYRnSODZpLgClP3did18JJMLRiFowGByONxQqI6xOzurLPOggt466234PKIBC4P315Mh2CCjNkgWmVWQBlh7sikTghtoyo4RVPUHg9qw2fOIZ4IAK/EFJTpDaIJdEzz588nOQb6ihwEDcgpoOAgALeICj+Pt956K7f01jeU8X/+538wpdR4En9qaqpKFzxhKgHKSDgaSyHnjkKATTmgEVeuXMlrw9vFy89LqCJnRk3FYQI/derUvn378i4ZK8tyBk6qFNsoxeKy2jo3pBTrm8qq6v18egYHOqupUfhYj5hlPJ19l2+WdwAmEUKZxQNaALy7ItHik6S1oZHhg7UnD/jWHNk3YtPe0k65KbQnxc4+iziR1penoqEUnfxWdDZv9oeHwaGbY9Xq66+/phGmGWetCKZYqd1hamAAqWUOB76xuA++7eabqysr312yNDQo+GdnnxXlQttwG0Cj9z1aUHDvU09XVlfTt2IlYOJ1xIY4HfUIq4x01iz1HTlyBLE/5/Stjorc9fFcd911NDW4WMGoQplNmOSB0tEcsTTLe8uXyUEAWiGGH9dee+1NN91EBZk8Ij8FAUFAEBAEBIHujYBHd/3du2qkdO6JgLPm+dAikHGo7SDCFH0Gh8LBLBo+BSwsfKuvvPIKe5ZpkovRLXagbJoJF0MM0GfM1mBnGPsy3FcjYHY9RkhIAGZxLLNzl1k6czaVCo8waEb8yBU1nTtlZWCnpuaEGDsjHONZtH48TrkYal9yySUQposWLWJTCKgiUiR+KCHt0JD4Cak9lTDP/OKLLy688EIIUB7BEpycEwZFIcIllRk2YOERdU7ZOSe5KVOmQMtiN0fB4RYhFgmvoqVQMI9wtcBLMZmpYi/JtIEAIAxLSFRAB1eFC0XNZqr4meUyCyXnVAccx8SJE0FP3ZK/jkUAsRKeN3mXqEc+ByqLqlSvJbUMW02tcaAHYeZGpXeWUUqKDgz0ayOhSk5Sio7NvP2x1Tc2V7ZZPfcK6XbkkfXgUN1wE3z1kIm8DHyzrB/QPJ555pksliCRVisW1kdoISSUYkZqm4eElubWxqYWfz+3MCY1Zpg2W6kUY0K7D6VInVKzNNQcyE5pmVm+gkakAedAecqnrb5uWnUjGg45p9GYcvrpeHl8ft68j1auxPz5vMmTaE0cErkzIikqK/vf554vKS9nZQsvxkDU2XbPGblSceLJRNGI2FXglYXdn5yXlgti5lVk+EFHrzod8xRZ4GR7K0xJKDUy+bS0NBYa+UlvhbMXnAzQTJk/JVcEAUFAEBAEBIHuikBHPWZ3La+USxCwHwFnUYrkDH7tlltuYUiKpTAMnc6ryYcKF4ZBMe6K8IamiDCG8hB2TLn18jiaRLZAfeqpp2DuGB+jIOBQETJPYwUezhGpF/QllKKiHZkJMG9nfIyKkPE0K/Cff/75xRdfrLNh+YRHYH/IDycvvPACzzKwhriEzkNMxOCbATdWQvB6xEOKOMmCNTBSimReu96H48P0+29/+xshyb8qJrZUlJHiq5wwmteKRWhBVXZcQEJEUhaG+KrUKBCVp0W4VIUkCOB9D8trYFRqRArOZizQsty65557dLS6yExrMR4n/0gUEXWi5RRKUYPjqBPeB0hnqGQQVuSvor+JH4oB4RJMIm8UjBJvlAnna30ehvUOCztpPVpV3YCJcUpCuFuxSHX1zZVV9THh/kP7/Ic6t75onh6SBgR90IaTB3pqWhIOKH48LbDgwcoEnDKfuWM5JtjbwSlh4aH+tXXNeUVV/ZL/s02W+4CZV1RZU9tAfngr1KvrPnmzIScs8+Cfl4MmmsaZVprlAeTG1DLNMs07zS/rWDbE3KlHaOrPOuec/IICetuXPvnE38/3vMmTOxWDywIXl5c/86/3dh88yCdw5513Ivwn8y5L/ZQJ6bVM6s59iM5TZtvmALyljJ2oC/ZSP++881huZIjy6quvwjMy8GC5VChFm7GVBwUBQUAQEAQ8EQHm12qK7YmZlzwLAl2CgBMpRYbjKO+grjDuw3EY/uPYmBKXT7AnXMe/IbZ+GPYy9YJc4yJs3a9+9StQgHGDDsNIBwmPmmxwl4Hvgw8+iJ4Oz4lwYczcUHjx8/TTTx8+fDjPMjPHVyOcGhJF3FTB0MGswbL985//pF2AO3v++eeZJCj1YrtYww/C1sGvESEHrtmUVTUTRQbWxPDBBx8ogzUihByEJ4IjUFFBDeipiLpCWphQkW0YJcKz8s+h0yUwJCNJ6EkLvBIDelIhDJlXBecvRSASfHJRLuhRCk7SKh5ghHvlKXgKCkuKip4gcuy+QZjHUcq0y1nAZlIpixcvZgJMPDpjcmI/Agg/YRIxfqQ2eXkgoKkRXle8AbRtLTFkCBXqKEYpOtQ/LTn0UEFNbX1LSXldbX2T+1CKldUNR3PLoRQHJ0al94uwH1j3jwHWGF0qNBMHsjW+fZoIXgCaMjbiYIWAr5LvlEN/+I4tFBK4QD+fIX3CNmeV5rofpVhZ3VhcUtvQ2NaCxYZ5MKVIH4TumCaUTk2pwunOWNxCcMfyGC0qn7xqwx1bvxZig7u84sor2cscpxzvL1uO7fPE9HQL4bvkVkFp6bPvvb94zZrEpCTW2HBCAlD25IRelYpgjyMiYZzAYIM+EU8jbHtFr40Ynx6f/lEnQe9J+0xnCgXMt0mtTZo0iYGE+cKbfsTyCbvAQShjIcHYhnqnP8VeQflepDWAlcPQgS6YXJGK8atH0Io7aUY7dNb0CAwt+ImenUEIbw5RcRGfm6w/GSlp/L1gr4ASlrETAVhk5VVkgEHBWTFVi5o0OKxmKUfSmG9TZLw/q/GPKgujhQsuuIBhEj9JggVIkiA25VSauyRKvRAP4w3LxZe7goAgIAgIAoKAICAICAJejoATKUWQZSQNU8ZQFb0eM2o1u+Yi41dG/9BwjONR5KkRMwNxSMNHH32UgTgeGNlRBGUiA3RCEhVhiOTSSy9lhkA8jKF5lpk59mVa6QNlc9ttt+EAiFssvBMGIRjDfdw4MqpmCvHII48wBGcvXXxaqZkMA3omHogoGaZzQsykfvPNNzM6JzMfffQR3BCDeB6HG+Jo93UhNkqnBug6AMWEMWTl/09/+pO+yAnpIjz8+c9/zsyTnOtbhEdpyOSHDKDK5Ke6RQGZd1E0okILyYH6ibtch0hl9K9kbjo8T3FO8eFqOTEmodPihMd/+9vfIiOFuhVK0YiM/ee8abxmMNTUmjqgEXkZqHreTA4qxTi3tCdF9mYZlBK2YW8plGJhSXV1bWNkWKA9ETrw2dLKupyCygB/n97xIQkR7rVvjAOLqaKCWcCuGVIAwkI5JaD94RvH9SoHn5v6TlVb5/DUjRH6+fYclRaJO8Xcwiq8wP3YkBiDdNl5XnFVVW0DyKTEBUeHB6idhbosN51PmI6ALcIQnlLRdAfouWj8aWlpt5WGnYrmAze2xp1PxPYn6Exx6UsH8f57/3pl4UJ07JMzMmyPztFP5hUXz/vwwxUbNozMyKB/B7qOuifrU6ZDpIvHsoFHgJ1vDSN0RhFUDSfED+GIbbViFblC9WHNoO7yHhKAZ1m3w965s/0gLwMrBy+//DKLBwwkIOD4utu23v7ss3vvvRdymfxADn744YekC/U8YcIE3eyT9Ntvv82LRP/LoqC6zgiEtUNIQB4kKvIGRchQBCEnS1AKE8TvtDOonln15C62yQxauAVJiotnNmrjIhnjOqQqqZAx7mK9QTaIVkUCY0hm1IiF15VXV6WoAsBX4meGPBOMbks9In8FAUFAEBAEBAEvQYDek5LSJ6pu0UtKLcUUBOxBwLmUosoZw2WmOhyWM8pkjOkQwi5MtxidYzOIVpGJB0NnxSryYVuOh2DMCowTA1byYc2QE7JKT5yoDhnuow6A3CEYTQaSIkbkTDBQmjCGVo0Io3ayCg2EahKVJaNzFGcM9AlgLALJIUaAtYRPRJBorkmhRPgxJH6UlfCSFARzV4byiBCZSKhCGSOEByQerpjwDkwtOMgwyVEKlUnCcHTU2HEdMtcYufk5gimOjmIwDy9XrERAKWehhqkCDl42/pq/HlbGdspgg5JCMCAtKOuRX1iVV1gVGxUc6O+K79pyxtgrJie/sqC4Cm+PQ/uEsROx5fAefZfG4Y033mD5gSaCNgrFEB8ymziz2Q6GhByuLB22zxMGRb29sldBUdWJHid69nAj5PMKK2vrGkFjQFJIvAeyzJA17CUCmUhjDhMEF8OaAfVLU89nrgkjV1a3SVow17j6hdT+fOHC1z77nM5iyqhRJmG65GdOYSEW2Ss3bho2ciQKfXBzCFx8bmy5RreIWA/3JugT6RbpSTHXRdQP2whPhxgfShHBHQwgYj3AocpYnqQLZimRFaD333+fqoSOpBKtBwdnxJ988gljA1Jk8YDBBusKLCZBN2MbQSNAKqx6ooJcuHAhOWFcoTtchiKoCMkJfDTrgqoXhr+j72CoAE/KXRSOBIADJVdXX301YwDyxhvIeIaECMN1BhJpaWkUHI0kSkkWQX/5y1+SHwhNxQbSLkExM3LAGF+XjrEED+qSGvsmhNVsNwcxqpY2sXLQweREEBAEBAFBQBDwEgTUXNtLCivFFATsR6DrqQdjGRiCMyBm5M0cgAkAQ2RYRVR+jM7NCTjjgx2dM6BnJM18D8dArO0zSoY65CC8ipCpiMmzUH7MRpiTEIAFf7LEkP3KK6/kKTLGOJ5WRqkjmcwQTEkFWeo3iYefTJkQFyBIRFlJccgGkwcescDiWS4mEap5hXlaNlyxkA0bYpNHNALUMof+6eyTYX3CMwZEFpQ3VNU2HS+o7JcSGRjd9d91aWU9EkX24oiLCBiacorlBGdD5Oz4YQpoNPigoBXgSpix0zhA7hjn6s7Og47ft1fP1ITgMYOj1+8uKSqpiY8J/VGcpIN0zUl5ZX1eQRWG4CQ/MCmUF6Nr8mFHqpA1COFRkcPR0DVQy6wWuFtDqvzi0WHhyXXBF1/QYU3NzLSj0A54FJLss+++/3rT5uEjR/7v738PgA7hE8kZLS2sHB8d9sUwa5D7aOtYiUxNTUUYCD0HsciCIiFZOMQknE6cr3LevHkYT5AHenb0iejyWGuEdtSk2ynLzMgBghL7YmJj3ZG3gu8dzKEm/+///g9iDpEg5ggMDDAxhlKEB8RMHjmk6uKRGeJipY3wnTKFIYRKDhtkkCFmRgvkFvEjXCeqZ6woGMbgOkPnipEM7x7cMcQooxFGSugiSWLdunWKUmQtEyaR8Ax7oD55lq2fdUKKddWx6RNITHZrAQrWQZWLau0PWoeRE0FAEBAEBAFBoHsjIHxi965fKZ0zEOh66sGkVEzO77vvPuZp7IjCuJaxMuoDLKQYr5uEtOYnkz1G3koYyPo/m64yrFcPGslEaD5mAggNsLOGFGA2opk7JgyICjloXxijM9bncUbkHMwNTjkvIgD8Aoc1uZUwgoANCAT7+0weHrvtQDmUYl5BZWl5XWwkrvq6UpvGXsNIJvOLqoIDffsnhabGh9hQLg96hPYKqRR0AK0NrMQpmwVnFy04wPeczPg1O4u37y88KzrETTiv/UdLsYXHGjcmMmBgcmhkiBttymFljdDsI6VncahLyGIrM8nrx3ZbOABBTYk17OtffMmDXcgqFpaVffLNN5+sWjVsxIj/eeABelhgtLIspwxGVHTfdM1UCoH5ABGQIhBWFQTZB/FHh84tFMRYB9Nrs8KH+E5Re/Ts2BlgFMxIQ9kInzJFFQD+DgKOJUaSg31jiMJXBpmLz0TGMAxdsB2GUiQVmEoEgwRm+AHTp9JFzEjtsFpJo0HroeKkCKoUMIaMT8gbEkv4UBSIyBKNlCLhuUu6gMk5NU6JML/AwJmf5ESvaSkzfP6yPsqhEmr3Lyl+9dVXsJ8ABQ2KZ2qIWgfWVLuJykVBQBAQBAQBQcDdEGDKz+Emg2d3A0fyIwi0i4DbUYrkkgnAXXfdxeo9voEYsqMHUaPwdgtgzUXG0wzcWW9n2M2KPaNzxAsM6LnOHIBxNiN+JTZkcsL4vt1GhIuE57AmRQkjCLgSgdFpEaMGRhUiVKxpOJ5fkRgX2rUeFfOLq/cfKamtaxrcO3T84KgAv16uRKNL0qLd4OiSpM0TRag4YVD0oD6he/YXDOob3TcpomspZnKIfjbrQGFNTZtyauzAqNSEEA+1hddkjTns7nMFjgk+6KabbqLbglWc/9lnNfX1Z4wdG+DyvZUP5+a+9dXiH7Zt6z9w4G/uv59FO6eyVNjzkoTiEznHXlhJBSHpUAWiIiR1/r700ku6sjB8xpqYIQE8oPVTCCLB4zORICfEXSN+WlSEKh6WHtVOa+DPoALXKBggs5yJITMeDFFKoj2EuUN7yAhEr0DwLPbRCBhzc3O5y7AHipCcQ18yXNEZVieIZBWfyE9WQBneENI8mMlTFn6y0Q0MJpvDkCvcOgOjneMuC2nJLUFAEBAEBAFBwP0RaJcQcP9sSw4FAdcj4I6UIh8wPsgYauOPDPUBfJ/9RB6jdobgDO5Z6meAzuSBQT+zC0UE8FdaDde/fJKioxAIDfSdNDR6x4Hy/TlVcDcD+8V0IaVYUl67O7sQq+fIML/ThsWMGeA6G3BH4enp8fTs2QMN4BkZca8sOrh1T15KQlivXg7ThdkATkND8459BUWlNS2tralJoWdmxKfEdMJpnQ0pyiPQTOjucbsBVbRu7dqauvqKquqLz5juSlbxYE7OW4sWfbN589Chw3597704MHEqn0ilYwWstXgQiwweOLgOaUinzwm8G9tDawaQK3CCDDNOKhLa3LFbeTB+UBGyQolFhaYF0frB6wE+caqoKDKiPyhFOE12isMFJ4bMrJWSEySNmqGGbXzxxRfVjs8MUbir4uREHSYZo3RIMvVFBSzF1Fc6e4JIkwMcWNPFkbTwiZ0FUMILAoKAICAIdA8EOjsk6B6lllIIAvYg4I6UoioP9oN4O7KnbObPwhsyEIdb5DC/K1cEAc9FIDM1cuzgqKKK+pLSmsM5ZTGRQWEhXaCoRZmYdahk/+GSpqaWAWnhU4fHhgd5nn2r574GOudoAGeNSfxqQ8Hh42UoRoekxvr4dJlWFJPnoznlDY0tbB0zfWTc8L7hgV4gXNV10VUnEFu458MCGsnbpo0b3126FM5sjqtYxQPHj7+9ePG3m7cMGzzkV3fckTFqlLP5RHCmf2/XHyL0nCLgGANgMgyvZ14pXDeuLHLOAXXYLk/HMqSKkHXKiRMnQsMZIyQbmEKrK5Qa42hEo/CYK1asYBMY7K8h76DtWODUy6W4ZcQyGqEihtjjx49HYsmUBkMNDmPMxnOyZ/xp4RyOktgsBOAW7lmuuuoqWE6ySqEsB5a7goAgIAgIAoJAd0VA9ZjWd7LdFQcplyBgPQLuSylaXwYJKQgIAuHBvjPS47KOVW07WH7gaGliXNigfv4uti2lDz5eULHvcHFNbUNSTNCU4bGDkv6ro5E6ciUCsA1JUYHnj098bfHBzTtzE6JDoyODumR4VFBSsz0rv7Kqzao0Y0DU5OHRMWFte9fK4QIE8M3HjsPI3EgLVvFfS5dy4gJWMfvYsXeWLIFPHDJ48O233pI5bhy+h11QXt5wLRg0Jsd1oMCJCvbIqAXh9TBANvkc9O4l6kFIQ5R6QAf9B7EIS2iMEOfOatNkZIk8CBlnDEDMmivkKbSTeHXEwhq7ZjaQwbQZhSPOnXlQ5QHOF+tpBI84XmTHGByz8giJYoms1Y7G1K0/V0ngkJpSo980KbIxHlJERoqLGDhZkSgakZFzQUAQEAQEAe9EwEKn6Z2ASKkFgY4Q6DLdSkcZkuuCgCBgGwJDUsKmjIhNiAosLa9FJ4gBsm3x2PwU5NGeA0XFpTUBfj6ZAyKnDo8JDuhKe1ubC9I9HuzVs+f5YxNHpEUWllRv3JVTU9d0Cp2SE4rNK7F68xF2DWpuae0TH3zRaUmwzL4+1qqrnJAjr4sS8gvHxDfccMPYceNg+mAVP1v1bcPJfcacgUVzS8uWrKxXFn723ZYtQwcOvPWGuWNOm+jr7ywSGcYNt4YYd0P8URwIPvUTc2YTXR6UGRsucxET47fffltZH8MzQh3yLDyaCReJSTK3iBMGcMOGDTgZhA3ct2+fcqFIeNg3vBlC1RFg8eLFuGkmclLhL6kbhX7EzMYs/CXpBQsW4CoRppJK0ZvOMWnhEThE8o+qkcgpF/wjhtKcwD+SOukSoLNV1q9fPyJE/Pjll19CUGJwTR7Y4RrdoklUbCDDrtkPPfTQRx99hLdHk7vyUxAQBAQBQUAQ8BIE6Mc5vKSwUkxBwCEIuEI44JCMSiSCgCBgGYGgAJ8zM+IO5td8s63w0LFSbJ9DgvxDXGV3XFhag9s+zGyxFBzYN3zaiNhk8ZdnucKcfxeh4pzJyU/kVu09UBQc5D8+PSXQ33VtPnzimi1H0czySvSOD77qjD6ThsSEBLouA84H2DNSUKyiyquygO7Rs8ec6dP9f6q8s78w8Ikbd+/B3nnb/v3pQ4fe/ItfjJs8xTfIiX4zcYwInXf8+HH4MvJ/6NChefPm4dgEm+JbbrlFcYKqXPB0c+bMWbNmDXtAs7Xxnj172JoZ3hB2D37tmmuuwX7ZGB6/K2rvFB6BYuMcdg+hH7wkwk/4wfT0dJwkzp8/H/khRCG7bHMXcSKSQ/jEP/3pTzo2GEPsoAm/devWZcuWQRHi5pLtnrFMV3lThtJkDOPol19+GSNorK0pEVwnakp2fP7kk0/QMCpeslPVxM4wX3zxBVliV+tt27bxJlBeft56660YxRvViGwtTbrkoaysDNtn7ZKyU8lJYEFAEBAEBAFBoHsgIBLF7lGPUgrXICCzO9fgLKkIAq5AIDk6aOqImOycqn3Hq5T5c//eUS5IGD5xy+68fYeK8aU4MCX0oonJo/tHsu+wC5KWJCwjMHlIzPdDY77fXrRtT35QgF/64PgAl7CKvBLwidl41Wz+D594dmZCRPBPrEct51zuOhABxSoiWIPz2rB+/TuLl/Ts0fPi6ac7kFVUfOKbixZt3b9/9LBhN15zzfipU/1CQhxYCvOoMGReuXIlTKK6BfennA/CDyLMNIan7LCE99xzDxQkYWDQ2HZZB8DWGKNjTQJyHcIRCg954N69e9etW6dC4hVx2rRp6hzSbfbs2URLbEQFraljQxuIqBA2UF+BPWTvaYIhqOQiltewmXq6wgl3kRCyPQviRAJQX0ggJ0yYkJWV9d1338EGQjJCAmK7reM0OSESzVHqW7hlvP766ykyEkv2j9bXzz77bMpipBQpu3qcv0arbf2InAgCgoAgIAgIAt6AgKgUvaGWpYyORUAoRcfiKbEJAl2JAB70MtMi8aDX0NSSV1LDNrtsiJEUF+brzK05FJ+YdbCoprZxUEropVN749UxKtRZpo5dia8Hps3Wz9ec0beuoWVjVunGnTn+/j5s1RLg71yDdF6J1ZuP7j9c3NzcqvSJ52YmhAuf2KXvDywVm29gmQuZtXzZMrSEaBUvPt0xrCJ84obdu9/66iv0iWNGjpx79dXjp03zCwvTJcZoF9tektZXHHKC+7877rhD8XTGCKHzzHkxxIB4MGQrFag6yEdslskVnCDmz1CKJuG5fuaZZ7JpCcbOhGSCAelGtMOGDVMJIVQkqquvvhqmD0UhYZS1NfEkJiaCszE/nCMY5BFMmzlnDxYSNQbIyMi48cYbx44diyaRtOArETYijUQCSW7JDBQnO7pQiT/72c+40qdPH/04G8Wgl0SYyV19UZ1wC0oRUSSUIjmElyQqBJsmfCKBuTJ37lwIUwro8J3xTHIlPwUBQUAQEAQEAbdFQKye3bZqJGNui0BP+Wzctm4kY4KAbQgUVzYs21KwcHVOfnljv5TI9MGJfZMjnGTxasonTuk9I0P4RNvqzYlPbTlY/uqyw9uyy6KiQoYOiO3fOzo2KthJRPPh3PKtJyWrLS2tQ/qGz5mUfE5mQliQLF85sX6tjxrrXbRyr7322orly/vEx19/4QWzp02zU6v4Xz5x3/7R6elzr7nmNPjE0P9uzYT+DqkdtsbQaqNHj7Y+t84Lif1vdXU1BB80H/QfbKPWDJokipkwpspcVPI9wpsE4CfjKIDFTpkTgsHZtRvM/EGTK1B+pEUk0JdqcxhyyE94QCK0LU6VBNnDvptSEwmRw3ual5e0yADpkpxJxuSnICAICAKCgCDgJQj88Y9/fOedd+Lj43/zm99cdtllXlJqKaYgYA8CPnj8sed5eVYQEATcDYHgAN+k6EBfv175JXXHCqsrqhqYj4aF+Pv7OXiiWHTS3hl9Yn1D0+DeYZdM6X1GRly06BPd7YXo0bb7c0xEQE5p3dG8Klwcllc29OrVMzQkABGrozKLI+uq6oZ9R0o27cw9eLQ0LjJw6ojYiyclz0iPDxX/iY5C2e54YIvYqhiNGzTflu3bj+TlJURHD+jYnPaUCZryiddee9rppxv5RGJgexA8+uHBkD1Akk4ep4zW2QEg1KDV4P7g18DEnF/TGYBiIwyHBdqRx1UwIoRStBCbjrbdE/g+HudQ7CHxkDdi5qfNcaqEiIciqPISYbuxkYpKq928yUVBQBAQBAQBQcAbEMCfyY4dOzAmYCM1bZrgDQWXMgoCNiMglKLN0MmDgoD7IqBYxdBgv+r6lrzimsKS2paWE5i7+vsjTXOAi8P6huZjBZVb9+Zj3Brg22PsoGj8J04bHit8otu+E71jgiJD/Qsq6gtK6gphFavq0SRh+op81R65Ikwiu68UltYezSvfvb9w29786pr6Uf0jZ09MvnBCUkZqRICfw1hLt8XWszIGuxQdHY2/v5ra2qzs7CO5Oclxcb3j420rxcY9e9/8chH2zqMzMuZed12bPvGnJr3o43BHuHTpUlSBuPNTrKLRz6Bt6cpTgoAgIAgIAoKAICAIOBwBRSniOQR3MUIpOhxeibBbIiCUYresVimUINAjJMC3d2ww/zDUO15YfSSvsrqmsbnlhJ+fT2AAVn62Q1RcXrs7u3Drnvy8wsqUmIBzxiZezH4sAyLDXLW7tO1Z9+4n+8YFwyqCQW1ja1FZXX5xdVlFXVNzK5IlFKydIhYxxoRWLqusLyiuyT5Swvuw52DR0dwKtvk+b1wS/PIZI2Kjw/zRVnk35G5aelhFvPXhmw+r3vWbtxw+fjwxJsYGVnH/0aPsx7Jx716cAM69/vrTpkwx4RMpP+a0OPJjExV8+SEMPHr0KHuqIFUUVtFNXw7JliAgCAgCgoAg4MUIsFUaKkWhFL34FZCidxoBoRQ7DZk8IAh4CgIIxFJigvolhAT49yqrbDxaUJVXVFXX0Izrr5bWE5i5ddbuFQrpSG7Zjn2FO7LyfXu0jh8cNfu05HNGJ/SLC/Zz5g4wngK4++cTVrF/YghWybwApZUNyFexgy6rrGMfldY2l21tr0S7RpEnTvTAN2JNfVN5ZV1BSfXx/MoDR8uyj5RmHSrG8r24tDY02Pes0QmzJiRdclpSnxjrPYVIAABAAElEQVR8yQmZ6NavA59/RETEoEGD0Cpu2Lot+8jR3vFxyBWtz3T2sWP/Wrps/Z49GZmZN9x44/jJk/0CA80fx5aWhDC5PXjwINbWmN/CKrI/ckpKirCK5nDJFUFAEBAEBAFBQBDoQgREpdiF4EvSHoqAUIoeWnGSbUHAWgTYaTc1ISQxOhCqqKq2Ka+o+nhBZWl5XWVVY2MTntDauMWTzsRMOSCUaM0trY2NrTV1jfkl1cdyK1Ci7dxX0NrU0Dc26JwxiZdMSh6VFime8qytCfcIFxHiN6x3GHJCdn9u7dGDzcFRGlK/xWW11bUNdfXNlbWN+N+sqm2orm2qqm4sqcBQujqvsOp4fsXh4+X7j5TuOVicdaDo0LFSnGnW1jVGhQcM7RN2/oTk687sO6I324ubvkjuUW7JhSkCNAjsEYxRT0tr6+YdO/ZkZyfGxuJaEderpkHNfh84fvzdJUu+27Z9WHr6TTffPH7CBFwNmoX6zwX4ROyscUvE/sVlZWX8xAL68OHDuHQUVrEj0OS6ICAICAKCgCAgCLgeAaVSZIAkvhRdD76k6KEIyC6cHlpxkm1BoBMIRIb4TRsROzA5dPvhiqzjVdk5VfllVUdyygIC/BJiQ9mhOTTEr83Lok9PJS6DZ0SShnKtsamlobGlGkqxqKqxoTEyxHf8wHA85fVPCBmQGBIi2250ohLcK2h6vwgUizsHVh7IqzlSUFNYVl9a3bg3u2DXiZ6YxiNX5HVgWwjEiey9U1vXVFffhM9EXQbYqOAg35SY4D6xQUP7RWSkho9Oi9B35cRTEKAeExISbrvttvDw8DfffPPJd9+96aKLZowda3kP6IM5OW8vXvzd1m3wiTfffDNWz0gRLRcZoeL5559PMDabzs3NhV7cvn37U089de+9944bN87ys3JXEBAEBAFBQBAQBAQB1yCAooKEGCC5JjlJRRDoBgicYhrQDUooRRAEBAEQYFcWNujg35kZcUeLancercw6VpVbXFfb0JCXizF0a31ja11Ta0/sVU+0bbgBkwiryIOI2hKiAlNj/If0jRmUEjphYHRYkLQb3eGdigj2mzI0hn+1jS15ZfWHCmoO5tXkFNcWlTdAL9bWN1Y2tqJhxNkir4SPb6+QYHjnXgG+vYICesWGB/RPDs0cGDWqb3hMWJt/Rjk8FwEIvmuuuYb8L1iw4PG332FhYfro0QEdqA4P5ebiPxE+cXhGxq233jpmzJhT8okKGRb8Z82ahZjxpZdewvAZknHXrl3/+Mc/7r//fkhJGbt77vsjORcEBAFBQBAQBLoNAlCKilXsNiWSgggCzkZAqAFnIyzxCwLuhUCgn8/g5DD+NY5rzS+vL6lqrKprrqhpOlZcl1tcW17dBIUE/4j5atvfXr36JoaMSosY2jsM5sghu0W7FxySmx49gv19BiA7TQjpkdGjsbn1aHEt0sWiyoaKmubKmqaaumbWawMDfYIDfTByh1Bm35VBSaHIVAW8boMAxsjXXXcdY2hUhP/31ts9e/lMGzM68KcW0Cwy7D1y5L2lS3/YvmN4ejraxtGjR1vJJyqg4C7POeccWMVnn30W22c2nt6zZ8+jjz76hz/8AWoSDwzdBk8piCAgCAgCgoAgIAh4LgKy0um5dSc5dz0CQim6HnNJURBwCwRQnPWNDeafzg0bdBRXNtbUN6NECwzwCfTrFeDXqX2AdUxy4qkI8FYMTAzln6cWQPJtKwJsx3zDDTf8yCq+1dSr1+QRwyMCA3uetACqa2jYeeDAix9/vPPgoTFjx95xxx2jMjM7xSeqfMFdzpgxA1bxiSeeYJ8WzK6zs7MfeeSRhx56CIISk3tbsy/PCQKCgCAgCAgCgoAgYC8CWqIorKK9UMrzXoOAbM/iNVUtBRUEToUAfSfuEaNC/cOC/YL8fdj8V7btPRVmcl8Q6D4IoBOE12ttbd2blfXFypWRcXHoCqH5isvL1+zY8fz7H2QdPTpm9Oi7f/3rzE7qE40YQUT27t07LS1t27ZtWECzQwuKxS1btgwZMgSGUbSKRqzkXBAQBAQBQUAQEARcicDKlSt37NiBe5bJkycPHTrUlUlLWoKAhyIglKKHVpxkWxAQBAQBQUAQcDACrCuwX0p8fDziwUXLV+RWVFY2NCxZvXrBwoU1jU0TJky45777MjIy7JQT8nhKSgoj9U2bNqFVZOvnnJycjRs3KlbRzsgdjIhEJwgIAoKAICAICAJeg8CKFSt27twZGRk5adIkoRS9ptqloHYhIJSiXfDJw4KAICAICAKCQDdDYNCgQZmZmaWlpfuzs9du3nzw2LHIqKiLL774vvvuGzhwoEOEhESSlJSUnp6+du3aQ4cOpaamwiquW7du+PDhEJrCKnazN0qKIwgIAoKAICAIeAQCy5cvV5SiqBQ9or4kk+6AgPhSdIdakDwIAoKAICAICAJuhADUHpuooCLEPLm8vBx9IjuoBAf/1/Wq/XmFN4S4fPLJJ++55559+/ahBcAC+oEHHnjsscdIy99fdhK3H2OJQRAQBAQBQUAQEAQEAUFAEHAiAkIpOhFciVoQEAQEAUFAEPBcBMaePJyXf7SKo0aN+uc///nrX/+a3Z/hMbGDvv/++//+97+TMjvGOC9piVkQEAQEAUFAEBAEBAEjAuzNordnMV6Xc0FAELCAQC8L9+SWICAICAKCgCAgCAgCzkMA742wis899xy2z7t372bbloqKCiys16xZU19f77x0JWZBQBAQBAQBQUAQEATaRUC2e24XFrkoCLSLgFCK7cIiFwUBQUAQEAQEAUHARQiMHDnyhRdegE9km8X+/fvX1dX99re//fe//y2soosqQJIRBAQBQUAQEAQEAQMCwioawJBTQcASAkIpWkJH7gkCgoAgIAgIAoKACxDAl+L8+fNhFfHeOGDAgObmZljFVatWQS+6IHVJQhAQBAQBQUAQEAQEAYWA8InyJggC1iMglKL1WElIQUAQEAQEAUFAEHAWAugTX3/9df5u2bKFraVJBr+K7L0orKKzEJd4BQFBQBAQBAQBQeBHBIyOFIVV/BEV+V8QOAUCQimeAiC5LQgIAoKAICAICAKuQaBv375vvfUWfOLGjRv56+fn97vf/W7RokXCKroGf0lFEBAEBAFBQBDwWgRO7s5yguLDJwql6LWvgRS8swgIpdhZxCS8ICAICAKCgCAgCDgLgeTk5HfffXfIkCHr16+HVQwNDX3ggQc+/fRTYRWdhbjEKwgIAoKAICAICAIGBIRPNIAhp4LAKRAQSvEUAMltQUAQEAQEAUFAEHAlArGxse+88056evqGDRvwrhgdHf3QQw+9//77NTU1rsyGpCUICAKCgCAgCAgC3omAsIreWe9SahsQEErRBtDkEUFAEBAEBAFBQBBwFgKM42NiYhYsWJCZmblp0yasoSEZ//rXv8IzVlVVOStViVcQEAQEAUFAEBAEBAFBQBAQBDqDgFCKnUFLwgoCgoAgIAgIAoKA8xGAVYRGfOWVV8aPH89uLSkpKfx86qmn3nzzzYqKCuenLykIAoKAICAICAKCgJciIBJFL614KbZNCAilaBNs8pAgIAgIAoKAICAIOBMBpVV8/vnnJ02atH379qSkJKSL8+bNY1fosrIyZ6YscQsCgoAgIAgIAoKA1yGgd3xmBMLhdeWXAgsCNiEglKJNsMlDgoAgIAgIAoKAIOBkBBjQK3Hi9OnTd+3ahV9F5Irz58/HJrq4uNjJiUv0goAgIAgIAoKAIOCNCAif6I21LmW2FQGhFG1FTp4TBAQBQUAQEAQEAecjEBcX95e//GXGjBnbtm0bMGAA20C/8cYbsIpFRUXOT1xSEAQEAUFAEBAEBAFvQcAoVPSWMks5BQH7EBBK0T785GlBQBAQBAQBQUAQcDICiYmJDz744Jlnnske0LCKGRkZbNWCXDE/P9/JKUv0goAgIAgIAoKAIOBdCIhK0bvqW0prHwK+9j0uTwsCgoAgIAgIAoKAIOB0BJKTk++//35/f//Vq1efffbZoaGhH3zwQWtr6w033MAtpycvCQgCgoAgIAgIAoJAt0ZASxQppbCK3bqqpXCOREAoRUeiKXEJAoKAICAICAKCgJMQwJHi3Xff7efn9/3338+cORNW8aOPPmppabnxxht79+7tpEQlWkFAEBAEBAFBQBAQBAQBQUAQaBcBoRTbhUUuCgKCgCAgCAgCgoDbIQB1+Mtf/tLHx+fbb78dP3785MmTFy5ciFYRVrFv375ul13JkCAgCAgCgoAgIAh4CAKoFJVQEYmiqBQ9pNIkm12PgFCKXV8HkgNBQBAQBAQBQUAQsBKBPn363HLLLWgV16xZk5qaOnjw4M8//1yxivy0MhIJJggIAoKAICAICAKCQLsICJ/YLixyURBoFwGhFNuFRS4KAoKAICAICAKCgJsiAKs4d+5ctIqrVq2Kjo5OSkr68ssvFavYv39/N820ZEsQEAQEAUFAEBAEPAQBYRU9pKIkm12PgFCKXV8HkgNBQBAQBAQBQUAQ6BQCsIrXXXedr6/vsmXLIiMjMYhetGiRYhUHDhzYqagksCAgCAgCgoAgIAgIAsrqGRyET5SXQRCwHoFe1geVkIKAIOCFCJSUlDBL98KCS5EFAUHAzRGAVbz66qvPP//86urqoKCgtLS0xYsXv/rqq/v27Ws3583NzcuXL6+rq2v3rlwUBAQBQUAQEAQEAUEABIRSlNdAELAeAaEUrcdKQgoC3oVAeXn5008//fDDD1dUVHhXyaW0goAg4CEIIE688sorZ82aVVNTExwcPGjQIMUq7t2716QEbAydlZX13HPPff3117JMYgKO/BQEBAFBQBAQBAQBIwLCKhrRkHNBwAICQilaAEduCQJejcBnn3325ptvsu+BiHq8+j2QwgsC7o1ASkrKFVdcAauIVhFWcdiwYUuWLEGruGfPHmPGmRugZCwqKnr99dcLCwu1cZMxjJwLAoKAICAICAKCgDcjoHd89mYQpOyCQKcQEEqxU3BJYEHAWxBobGzEMRlCRZl4e0uVSzkFAY9FIDk5+bLLLps5cyasYmho6MiRI5cuXQqruHv3bl2mXr16EeyMM87YunXrihUrEC3qW3IiCAgCgoAgIAgIAoKAcdYjKkV5HwQBKxEQStFKoCSYIOBFCNChrl69Ojs7W5kH5uTk4IPMi8ovRRUEBAFPQ4BNny+99FJYRRw1hIWFpaeno1WcP3/+rl27dFH8/f3RM7JD9HvvvZeXlyfmzxoZOREEBAFBQBAQBAQBjYDwiRoKOREETomAUIqnhEgCCAJehwD6nQ8//FBLFNeuXVtbW+t1KEiBBQFBwKMQSEhImDNnDqwibVdERASsIlpFWMWdO3eqciBURMCIUBGb6B9++EFWSjyqeiWzgoAgIAgIAoKA6xAQVtF1WEtKHo6AUIoeXoGSfUHA0QggUdy/f/+6detiY2OZgRM9c29xp+homCU+QUAQcDwCcXFxF198MX4VS0tL/fz8sIOGVXzllVd27NihEqNNw0QawhEvsYQxmjg5PjcSoyAgCAgCgoAgIAh4DgJ6VCB8oudUmuS06xEQSrHr60ByIAi4FQJIFL/66qvi4uJRo0b5+PiQN/yRHTp0qKmpya3yKZkRBAQBQcAcAdZCLrroogsvvLCgoIC77AQNq/jyyy8rVhFKMTMzc/z48du2bdu4cSNOY81jkCuCgCAgCAgCgoAg4J0ICKvonfUupbYHAaEU7UFPnhUEuhsC9KPshbps2TJfX18m3opSrKys/P7779H7dLfSSnkEAUGgOyKAt8TZs2ffcMMNw4cPp3yIrGEVX3zxRcUq4lERJSPcIpvaa/cO3REGKZMgIAgIAoKAICAIdAIB4RM7AZYEFQR+REAoxR+RkP8FAUGgRw+ci23evDkrKys1NXXgwIGKUoyKilq/fj1iH0FIEBAEBAGPQADT5gsuuODmm28eMWIEGW5oaIBVnDdvnmIVJ0+ePGzYMJo1mjsRKnpEhUomBQFBQBAQBAQBlyGA4bPYPrsMbUnI0xEQStHTa1DyLwg4EgGsnvGiSCfKDgahoaEqaowEMXw+evSo2D47EmuJSxAQBJyJAPs+41TxtttuY0sW0qH5Qn/93HPPsVsLhCMyRsjEhQsXlpSUaFWCM7MjcQsCgoAgIAgIAoKAICAICALdDQGhFLtbjUp5BAGbEWBejXXzhg0b2Nbg9NNP56+K6uyzzw4MDPz2228rKipsjlweFAQEAUHAxQiEhISce+65d955p2IVUWHDKj711FOwitOnTx8wYAArKDhVRMPo4oxJcoKAICAICAKCgCDgzgiIStGda0fy5lYICKXoVtUhmREEuhIBJIoHDhxgu+eUlBT2ZgkODla96ZgxY4YOHbp69eqcnBzCdGUWJW1BQBAQBNpDAFqQNQ9zK+agoKAzzzzzvvvuU6xia2vrihUrnnzySbwoXn755fxk62d2oxKhYnugyjVBQBAQBAQBQcCLEGAwoMYDwid6Ua1LUe1GQChFuyGUCASB7oIAhoFsgUpppkyZgs2gphRR+jAnz8vLQ8Aom7R0l9qWcggC3QqBw4cPf/zxx6tWreKkvr7eWLaAgABk1w888IBiFbn19ddfwyomJib2798foSIOFk0eMT4u54KAICAICAKCgCDgVQgIpehV1S2FtRMBoRTtBFAeFwS6DwKKUmRLFihFulKMnXXZ2M0gKSmJfZ/z8/PR9ejrciIICAKCgDsgcPz48bfffvvRRx/FWyI6xH379hkdNeDGYdKkSX/84x81qwj5+M477/AT5fWiRYtEqOgOlSh5EAQEAUFAEBAEuhABJVEkA8yDOLowJ5K0IOBBCAil6EGVJVkVBJyIAERhWVkZah32dx43bhz9KAaDujdlA+ipU6fu3bt3165ddXV1TsyHRC0ICAKCQOcRYBepP/zhD2PHjmUf50dOHp9++unu3bsLCgqUAtHX15eW7fHHH09PT1ct23fffbdnzx72ocKrAy2bCBU7j7o8IQgIAoKAICAIdE8E9CSoexZPSiUIOA4BoRQdh6XEJAh4MgL4INu0aRP+xZAoxsXFURSjSpGfWA5iAb1mzZrS0lJPLqjkXRAQBLohAuHh4WedddZDDz0Escj6BzvUP/PMM2zM8tJLL0EdomHEaUOvXr1wCzt//nx8xXIOCsrVQ01NzZdffgn5qOUJ3RAgKZIgIAgIAoKAICAIWIeA8InW4SShBIE2BIRSlPdAEBAE2hBgc4OtW7ci5MHGWSGCAzI161Y/EfgMGTKEnVJxqiibtChM5K8gIAi4FQKRkZEzZ858+OGH//znP19wwQWIr3GweO+992IQjXXzsWPHKisrExIS3n//fVhFf39/Mg/bSEOHVwe2fq6trXWr4khmBAFBQBAQBAQBQaBLEBBWsUtgl0Q9EQFfT8y05FkQEAQciwDaHMyZoRSxAZwwYYKKnGk2Dsh0h8r59OnTCfPtt99iBx0fH+/YPEhsgoAgIAg4BAF2l6KxmjhxYlZW1vLly9mMZe3atTRcI0aMQMk4a9asiIiIDz/88KabbmLLKZo+mEQOtn4eNmzYwIEDjUspDsmPRCIICAKCgCAgCAgCHoGA2Ct4RDVJJt0KAVEpulV1SGYEga5BoLm5GTtBpt/wiX379tWZUCoe/XPGjBnJycnIedD1yCYtGhY5EQQEATdEAJ11RkbGPffc88orr/zmN7+BYTxw4ADW0HPnzp03bx6rI08//TT+HFhHUQsnK1euhHY0burihoWSLAkCgoAgIAgIAoKAkxDQfKJWVDgpIYlWEOhOCAil2J1qU8oiCNiIAFbPGP1h9cys2xgFlKKxT8Vg8Nxzz2XTZxyQycTbCJScCwKCgHsiwBb2LIRce+21OFV88sknL7nkEpwqstfzLbfcgjX05ZdfjqsHvMTS0DGReOGFF6Aam5qa3LMskitBQBAQBAQBQUAQcAECjAo4XJCQJCEIdAMEhFLsBpUoRRAE7EUA0z8oRfZjOe2004xxIfMx/uQczpHNW6AUCwsLTW7JT0FAEBAE3BYBXDecccYZf/nLX3CkyLYteG9YunTp7bffzs5UcI5KkV1SUgLPyJ7RCLfdtiCSMUFAEBAEBAFBQBAQBAQBQcBNEBBK0U0qQrIhCHQZAmhz2PB0x44dmZmZbMBizAeUoskaHXsajBkzZt++fUeOHJFZtxErORcEBAH3R4AGbcCAAXfccccHH3zw2GOPnXPOOZs3bz506BCEI3pG8r9//352d2HVRFs/uX+hJIeCgCAgCAgCgoAgYD8CdP2q92/TKIpK0X5AJQbvQEAoRe+oZymlINAxAv+/vfsAk+s8zHu/O22nbe8VfYlGgCAI9k6LpChRlKhKW1bi2HHsXCd24tx7ndhxEst5nuvHj+3YcWLZSqw4VrEUSqQkkiIpir0BIEgQIOqibu91+uzM3nf2YA8GM7uD3cWW2Zn/aAWcOeU73/c7A2L3xVeUJ2p6xOHh4ZRRz7oiZeCzUYZ6Mupv2Xfeeaevr2/uUjmCAAIIZK+A/uP26KOPaqTzN77xDc2uaMyoaPz8YCzq0t3dnb21p2YIIIAAAggggAACCGSBAJFiFjwEqoDAqgpoZrG3335bHRLTI8X0gc+q6b59+zSp4pEjR4gUV/W5cXMEEFgCgb179/7e7/3ek08+qV+bm5uVKuq/bxoi3djYuASlUwQCCCCAAAIIrBEBo4uiKqtvBvRaI7WmmgissgCR4io/AG6PwKoLqJfiBx98oFHPO3fuTKnMrL0Ua2pqFD6qC4/WaTH/6k25kLcIIIDAGhJoamr6yle+8vzzz3/+859Xp8XW1tY1VHmqigACCCCAAAIIIIDAqgjYVuWu3BQBBLJEIBAIaGGWUCikvofp/xyXvkfV1k5Np/jiiy+eOXNGw6UrKyuzpC1UAwEEEFicgP6zprkUtfTzV7/6VYvFoqkVF1cOVyGAAAIIIIDAWhfQdwV6rfVWUH8EVkaASHFlnLkLAlkqoB+eq6qqlCemrPWcubq33XbbH/zBH9TX15eXl2c+k6MIIIDAGhLQwvdrqLZUFQEEEEAAAQSWSiCxOMvUlEojT1wqUsrJBwEixXx4yrQRgTkFNFuiwsRdu3ape86cJ6UdUBceDZRWHKlX2kF2IIAAAggggAACCCCAAAJrVYBUca0+Oeq94gJEiitOzg0RyCYB/X2pVFGvWSuV4W9Tm43/esxqxk4EEEAAAQQQQAABBBBYqwIZfgJaq02i3ggsmwA9jJaNloIRyBWBWCyWK02hHQgggAACCCCAAAIIIIBAqoA58FkHSBVTdXiPwBwCRIpzwLAbAQRmBILBYDwen3nH7wgggAACCCCAAAIIIIBArgkYSSJ5Yq49V9qznAIMXVxOXcpGICcEFCkacxXnRGtoBAIIILBcAvpP5djY2Msvv6wbaEKJhx9+WAtJGzdrb28/fPiwdt59990ul2u5akC5CCCAAAIIILBYAfNHHlLFxRJyXd4JECnm3SOnwQgsVMDv96uXovmD8UIv53wEEEAgfwQGBwf/9E//VO31er0NDQ179uwx2t7W1vaXf/mX+hFl9+7dRIr583mgpQgggAACa06APHHNPTIqvIoCRIqriM+tEVgbAoFAgIHPa+NRUUsEEFhtgWg02tHRoVqoQ+LTTz9tRor6D2lXV5f+Wzo5ObnadeT+CCCAAAIIIJAqYHZRTD3AewQQmFuAuRTntuEIAghMC4RCIf6K5bOAAAIILEhA2eJLL700MDCwoKs4GQEEEEAAAQRWV0C9FOmouLqPgLuvIQF6Ka6hh0VVEVgdAf1gTKS4OvTcFQEE1qaAfhSx2+3KE1955ZUvfOELGRqhLo1Hjx49d+6c/vGmqqpqx44d1113XUlJSYZLOIQAAggggAACyydAnrh8tpScewJEirn3TGkRAkssoGF6RIpLbEpxCCCQ0wIOh+O22257/fXXv/3tbz/++OM22+zfbr311ltPPvnk8ePHR0ZG9F9at9tdU1PzsY997NFHH21qasppIRqHAAIIIIBAdgno5x3zRx5Sxex6NtQmiwUY+JzFD4eqIZAdAuqlmB0VoRYIIIDA2hBwOp0PPPBAcXHxiRMn1AnR/BElufadnZ0KHF944YWzZ8/W1tbu3LkzEokcOnTom9/85quvvqp1sZJPZhsBBBBAAAEEVkZAeSKR4spQc5ccECBSzIGHSBMQWF4Beikury+lI4BAzglYrdaWlpZ77rlHKeEPfvCDWCyW3sQXX3zxvffeU3SoPom/+Zu/+Vu/9Vu/9mu/plHPihoVKZ45cyb9EvYggAACCCCAwDIJzPrvf8t0L4pFIGcEiBRz5lHSEASWS4C5FJdLlnIRQCB3BdRRUUOe9fOJosP+/v70H1TefPPN4eFhJY+f+tSnFD7eeOONOv/WW2/1eDynT58+f/587trQMgQQQAABBLJXgC6K2ftsqFn2CRApZt8zoUYIZJkAvRSz7IFQHQQQWAMCmj9x9+7d27Zt6+3t1aSKKR0VtRiLFm9RH0Z1S2xsbNRaLmpSWVnZpk2bysvLFUEODQ2tgUZSRQQQQAABBHJRgFQxF58qbVoWASLFZWGlUARySUCRYi41h7YggAACKyOguRQ//elP615agyUQCCR3VNTbeDyuQwoQtZaLWR+t9axFWoLBYMr55glsIIAAAggggMByCOivaeNvavLE5eClzFwVIFLM1SdLuxBYAgHjr1UGPi8BJUUggED+Caij4oMPPqjQ8MPpV3JHRcWIxk8s4XDYyBYNHvVb1L/iFE2/8g+MFiOAAAIIILD6AvoL2vg7evWrQg0QyHoBIsWsf0RUEIHVFiBSXO0nwP0RQGBNCugHkubm5rvvvlspocY+Ky40m6GuiOqQqFVcNG2iZlQ0/v1GJ1y8eFFDnjUCurS0lJ9nTC42EEAAAQQQQAABBLJQgEgxCx8KVUIguwQY+Jxdz4PaIIDA2hFQaPiFL3zBYrH09PQk90bUnl27dilVbGtrM9Z31tSKb7/99sGDB8fGxtavX9/U1LR2WklNEUAAAQQQyB2BRB/FwsLcaQ8tQWA5BWzLWThlI4BALgjQSzEXniJtQACB1RDQzyR79+7dsmXLqVOnkiNF1eXhhx/ev3//kSNHnnrqKQWOVVVVhw8fPnbsmGZgvPnmm1tbW1ejvtwTAQQQQAABBBBAAIH5ChApzleK8xDIWwFN9WUMystbARqOAAIIzFMgvV+Dy+X67Gc/+8d//Mf6b2lyITt37vzMZz6j7orHjx/X+i06pC6NtbW1d9xxxwMPPKCEMflkthFAAAEEEEBgWQX0847xI0+ijyK9FJfVmsJzSIBIMYceJk1BYHkEQqFQSuea5bkPpSKAAAJrXkBzID7++OMej6eystJszEMPPXTmzBlNlahVWTSLorFfi7c88cQTGuCsaRb7+/u1eIsObd++/f7779+wYQM/zJh6bCCAAAIIIIAAAghkpwCRYnY+F2qFQBYJ0Esxix4GVUEAgSwWUA5YX1//Z3/2Zyl1bGlp+aM/+qOUnXprt9sVIN53330+n09TTCiI1FLP6aexBwEEEEAAAQSWW8Dooqi78K96y01N+bkkQKSYS0+TtiCwLALqpWj+FbssN6BQBBBAII8F9KOL5k/MMYBoLD7si4YisfjUlNG0IrvVZbfo1yK7xWph2vsce+A0BwEEEMgdAf29rFfutIeWILCcAkSKy6lL2QjkhAADn3PiMdIIBBBAYNkFQtHYWGBy1BfpGgp+1D4+OB5WpmjctdzjqCp2lHkd5R6702G12TSNpH5iS/zPbi2s9NqrS4uIGpf9CXEDBBBAAIF5CBApzgOJUxBICBAp8jlAAIGrCDDw+SpAHEYAAQTyXkDdEntHwic6xk90ThxrH+8bDk9OFSozVH9EHQqGJ0OhaHwmXrSrx6LT7nAoQkyc43Fabm4tf+Sm+sZKp1N9GOkakvcfJwAQQACBlRdILM4y3bOePHHl8bnj2hUgUly7z46aI7BCAgx8XiFoboMAAgisTYGB8fDZHt+z7/W+d2qkyGErtFi2b6mx2m3qgmgtmBrzR7r6J/oHfZOxuN1msdusNqslFo9P+MJRxY3TOWP/SKhrdPK+3TVb6911pQ6XgyFna/OjQK0RQACBnBAgVcyJx0gjVkKASHEllLkHAmtagEhxTT8+Ko8AAggsk4A6c0yEJofGwz/c3/Pyh33R6FRznfe69VXjofjweGige3zMF4pGYlaLYkRLVYWnxFtUVuIqL3GWeJ2+QKSjd2xgyOfzh8ORWCAYfetw94kLoze0Vt25rWJzTZHNUlBV4vA6+U51mZ4exSKAAAIIzC5Anji7C3sRmE2Ab9RmU2EfAggkCTCXYhIGmwgggAACCQGtu9I/Gn7pw/7n3uvp6Au6XdZ9W6tOd/qeffO8fhhThujxOBprSqsq3LWV3soyl8eVGOecbLdjc7U/GO0ZmOjsG+/tHx8ZC/oD4VcPdrxzpFuxY5Ft6rO3N95zfXWZ255yYXIhbCOAAAIIILAkAsaoZ6MoUsUlIaWQfBAgUsyHp0wbEbgmAeZSvCY+LkYAAQRyTkCLrrQPBP72pQsvHuxV41oaivuHgu8eGyorc+3aWl9T6aku91SUOq1WS+ame1z2zS0V+lJHxcGRQEffWEf3aN+gb2A4EJ2M/9UzZ9t6/Y/f2tBU6VIgmbkojiKAAAIIILAkAuSJS8JIIXkiQKSYJw+aZiKweAEGPi/ejisRQACB3BLQYOfwZPx8r/8Pv3fiTMeEQkOH3RovsO7Z0djSULquoWxxPQqLHNbG2mJ93bitvnfQf6FrpLt/vKtn7MdvdR2/OP7Fu5ru2VHlYRB0bn2WaA0CCCCQVQLTq7NMZVWVqAwC2S9ApJj9z4gaIrDKAkSKq/wAuD0CCCCQHQL6Scsfnnz9o8H//J0T6qioVZvraou3b669fkvNFUOar6G2Cihb6kv0Ne4PHzjSefRk7+n28T/9/qmekdAv3NOi9aCvoWwuRQABBBBA4OoC6qVIR8WrM3EGAtMCRIp8EBBA4CoCGvgcj8evchKHEUAAAQRyXSAUib17cvg/ffOYxVJYVuK8c9/6nZtrlqnRJZ6iu29a31RXevCjzu6e8W//7GKxy/6ZWxvs1qVKL5ep4hSLAAIIILC2BcgT1/bzo/YrK0CkuLLe3A2BtSkQiUQ0FoC/X9fm06PWCCCAwBIIRCbjh86O/P7ff2SzWeqrvffcsrG5rnQJyp27CPVY3LqhqqG6+NnXT1/sGPnaj8+UuK0f2127uLHVc9+HIwgggAACCBQkD3zmpx4+EAjMU4DxI/OE4jQE8lpAkSIdFfP6E0DjEUAgvwXi8am2bt/XnjtntVi2rCv/+D1blztPNL2LPUUP3bG5vq4kEJ78k++fPnhmRPM58kIAAQQQQGBpBRQjGkmiubG05VMaAjkpQKSYk4+VRiGwxAJGL8UlLpTiEEAAAQTWiMD5/sCfP3Omsz+4Z1vNg3deV1nmWrGKFxYWlBU7P37nluoq74R/8o/+z6nTXROkiivmz40QQACBPBFI7qWYJ02mmQhcuwCR4rUbUgICuS+g6RT1t2zut5MWIoAAAgikCYwFovtPDWl95xu3VT985xa3y552yvLu0NSNleXuh+7cUlbm6hsK/s1PL8T5K2l5ySkdAQQQyF8Bo69i/rafliOwEAEixYVocS4C+SpAL8V8ffK0GwEEECho7w98/63uYrdjz7a6aHx1VkfR/Il1ld47bmzRStPvfjR44PSwNng2CCCAAAIILIcAqeJyqFJmTgoQKebkY6VRCCyxAHMpLjEoxSGAAAJrRKBzKPjMe73haOzuvY3ekuJVjPG0LMyWdZVbNlbHYvFn3ushUlwjnyCqiQACCKwNAXNIFnni2nhg1DI7BIgUs+M5UAsEsluAXorZ/XyoHQIIILAsAmP+6OsfDbx0qLey1L2usXLVf8rSGtA3bqu3WC1vfDjw4fkxUsVleeoUigACCOS9wKr/fZf3TwCANSNApLhmHhUVRWAVBaLRqPkPd6tYDW6NAAIIILCSAt0joXdODjscttYNlTaHYyVvPeu9LIWFTXUl21trI5NTz3/QF52Mz3oaOxFAAAEEEFiogLk8C3niQuk4P58FiBTz+enTdgQQQAABBBBAYHaBeHyqdzh4smPc6XTU1ZQVaOnlLHjZbdZ9OxqKHNZXPug72eWbZEbFLHgoVAEBBBDIJQFFiqSKufRAacuyChApLisvhSOAAAIIIIAAAmtSYHAicqJjIhSOl5c6y0pcWdIGBZtV5e762tJAKPbKRwORKB0Vs+TJUA0EEEAAAQQQyDsBIsW8e+Q0GAEEEEAAAQQQuKrAwFj4eMeE3W6tKHNbrVnRRdGos9Vqaa4vtVgKD5wcjDD2+aoPkhMQQAABBOYhwCxP80DiFARSBYgUU0V4jwACCCCAAAIIIDA4Hm7rmnAW2RQpZpvG+oYydVfs6A8eax9nRsVsezrUBwEEEFjTAgx8XtOPj8qvsACR4gqDczsEEEAAAQQQQCDbBUb90bM9/nF/1FVkryrzZFt1ayo9xV7n5OTU/rbhEGOfs+3xUB8EEEBgbQoYHRWJFNfm06PWqyNApLg67twVgbUlEI8zWdXaemLUFgEEELgmgcGJ8Lk+v1Zo0UIo5SXOayprGS622ywNtSVaAPr9tpFwNLYMd6BIBBBAAIH8EjAHPrM2S349eFp7bQJEitfmx9UI5IdAKBQiVcyPR00rEUAAgYRAIBwb8UW0oSkLld9lIUp5qavQUtDe5+8cDE7GprKwhlQJAQQQQGCNCpAqrtEHR7VXXiAbv0dceQXuiAACmQV8Ph+RYmYijiKAAAK5JKBlT4LhrO79p+6TAg9H4u+fHw1GsrqqufTBoC0IIIBAzguQJ+b8I6aBSyhApLiEmBSFQM4K+P0a/sbY55x9vjQMAQQQSBHQmidZHinarZbCgsQ61D0jIXoppjw+3iKAAAIIXIsAqeK16HFtXgkQKebV46axCCxSQJFiLEYfkEXqcRkCCCCw5gQik1OB7O76Z7NZpxPFgnA0PlXAwOc19xGjwggggEB2CWguRXM6xeyqGbVBIIsFiBSz+OFQNQSyRmBycjJr6kJFEEAAAQSWXSAaVS/FrP4vv2Z4TPRR1NhnRYokisv+ieAGCCCAQL4I0EUxX5407VwKASLFpVCkDAQQQAABBBBAIIcEorF4KLvnUjQXjdGKz2SKOfTRoykIIIDAKgsoUiRVXOVnwO3XjgCR4tp5VtQUAQQQQAABBBBYGYGZ4V+x2FQoK7srmhP80ktxZT4R3AUBBBDIbQFGPef286V1yyRgW6ZyKRYBBHJAwG63NzQ03H777XfddZfL5cqBFtEEBBBAAIH5CBTZrV6XbTgaCUcnx3xhZ1HWfcc4EQgb452JFOfzQDkHAQQQQGCeAvRSnCcUpyEggaz7BpGnggAC2SPwyCOP3HPPPffff39NTY3FQqfm7Hky1AQBBBBYXgGPy1ZZWjQ8HolEYmO+UG2lZ3nvt/DSh0aCxnhnl8NaaMyquPBCuAIBBBBAAAFTgI6KJgUbCMxTgEhxnlCchkA+Cjz22GP52GzajAACCOS9gLooVpUWtXVMRKKxsYlwFnoMjfqNn/3W1bgdNv7RKwsfEVVCAAEE1pKAmSfSS3EtPTbqutoCRIqr/QS4PwI5J2D+fbyglqVfZcyLnL5/QcWmnLyI0hZxiW66uKtSajuftwu90ULPv2od0gu8lgeXXtpVKzDXCYsranFXLW0dZi1tcRVb3FWzViDDzsXdZSWvylD59EOrXrHFVSC9IeaeRRSoS8L+sNcWUyGKFCd8IbO0LNmIxeMjowGjadWu6OjwQNhnzZK6UQ0EEEAAgbUoMDg4GA4n/gnN+FZ2LTaBOiOw8gJEiitvzh0RWHsCQ0NDZ8+e7ezsjEajZu0X92Oqefm1b2SoQIZDc903wyUZDi2itLkumWt/5rtnPppe5kLPVwmZL0k/uuhIMb2o9Pqn75nrqrn2p5eQvGeuq8z9s36XaR5NLirz9kIvyXx+5qOz1iT9kuV4cOl3mbUyyTszX5L5aHI5xrZx/go8tYVWTNVbqkvUusxFZT46F1ogajnnqywoWKdIcXQipF8d9izK7Cb8EX8gqrkUp+LRD954rutQ1Gph8HP6w2QPAggggMB8BUZHRzs6OoyzZ/3OYb4FcR4C+SRApJhPT5u2IrAogeHh4SeffPKll146evRoMBhcVBlchAACCCCwpgQsNmfTLSW7nigocI+NhwZHAg01xdnTgK6+CSMqjQWGf/zit+LBkeypGzVBAAEEEFjTAuSJa/rxUfkVFiBSXGFwbofA2hMYGxt77bXX9A93zc3N6bVfaP+X9BKS9xilzfoX+XLcKPnWi95e2oplqMbS3mhpS1O1jQLTn93S3iibS5vr2S1tnU3quW63oP1m3Xhws7qZPrMeXejORZS2iEsWWivj/FlvZHFErOGBKfs6fzDS0TuWPZFiLD51+uKQsTaLJTJYXlo85VqCLoqzIiyh5+KKynzVEtZZN1ra0jLUfAlvtIRFrVEBqm180pb2k5Dh07vk4CtW8yW80RIWteSeGZ7dgqqd/n1RhpI5hEA+CxAp5vPTp+0IzEtgw4YNv/zLv+z3+2c9e0F/PRslZLjEODTr3+JXvWrW6s21c67S5to/Vznan/mS9KNG69L3Z7iFcSjDJRkOXbWG6ffNUFqGQ+nlZN6TuajMR2ctea5L5to/ayHGzlkvueqDm/WqDHfRoQyXZDiU+cJZ75ihNONQ+h+6DJfMeour1mqhBWY+P/PRuWo46/4MRS3u0Kx3yeyT4UaZS0t/cBlutNC7RApdF0IVRwYtwVC0q288GJ50Fa3+940a7Dw8GmzvGonHp4ocln03NFdf/7hl6vKkHHOJZZAxLlmoT+YCF1HaXDXPUFSGQ0te2iLuteR1SC8wc60yH11EaQv6E5devrknc8XmOjrXfrPY9I0Ml6QfMluXfii95JQ9GS7JcCilEONthvMzHJq1qJQCzQaaJ2coMMMh8/KUjQyXLO5QSvnm21lLU+tm3Z/5KvNo+saKlXbVG6U/ONU281Xpzcl8iVGaftg5ffq0ZlSc9Y6zlslOBBBY/W8NeQYIIJD9Ag888ED2V5IaIoAAAggsoYA6A757avhPnjrd1R8YGPJ39o1vaalYwvIXV5R+8DtxbiAYTGSIrc3F/+bLt9WVOQuXoJPi4qrDVQgggAACOSJw4cKFr371q5rrKUfaQzMQWBEBy4rchZsggAACCCCAAAIIrCUBLXjSVOXavaFMlVZHxfbu0VgsvuoNUGfJ0xcGFSy6iqyP3dpYUewgT1z1h0IFEEAAgRwQKCkp2bRpU0VFhXop0lExBx4oTVgZASLFlXHmLggggAACCCCAwBoTqC4pumFDqdtpDUcmO7rH+oYCq9sAdZw81zEyMOhTNXZtLntgV02RjW9lV/eZcHcEEEAgRwQUJn7xi1+88847vV6v3W7PkVbRDASWWYDvw5YZmOIRQAABBBBAAIG1KeAusm5fV3LDlnL1ChweDXxwojsQmteshcvRXNVh3Bc6erpPhbudtsduaXCQJy4HNGUigAAC+SrgdDpvvPHGW265RfFivhrQbgQWJnCVaVwXVhhnI4AAAggggAACCOSQgD8Ue/3YwF89e7ZvOOR2Ofbtatp3fYPdZl3hJmpVlkAw8sqBC0dP9lgshQ/srfv9L24lUlzhp8DtEEAAAQQQQACBZAF6KSZrsI0AAggggAACCCBwWcDjtN62tfKJe1uKXTaFeh8c777QPaqAb4Vfk7H4qfNDyhM1c2JzjfsX7222WVmTZYUfArdDAAEEEEAAAQSuECBSvIKDNwgggAACCCCAAALJAmUe+8duqH38rma7zeIPRA591D0RCCefsNzbGvI8MhZ87eB55YnlxY5/9Xhra0OxhWVZltud8hFAAAEEEEAAgYwCRIoZeTiIAAIIIIAAAgjkvUBVieOT++pubC3Xos+d3WOvHrigBVtWRiWRJ46HXnjrTDgU9brs//yxLbe1ajnOlbk5d0EAAQQQQAABBBCYU4BIcU4aDiCAAAIIIIAAAggYAi3V7n/xic1ely0Wj5862//8m2ci0dhy42iE9dhE+M1D7Z3dow6H9cF9dY/urVvum1I+AggggAACCCCAwHwEWJ5lPkqcgwACCCCAAAIIIFDQNRz8d//7WFv7eEFhYevG6k/e22rVainL02dQeeLIePDld8+3nR+wWgvX13m+/X/fwjNAAAEEEEAAAQQQyBIBIsUseRBUAwEEEEAAAQQQWAMCI/7of33mzE/eTayUsnFD1b03ra8scy95qhiPT/UP+1/ef+5ix4jmcNy2vvjrv3HTGtChiggggAACCCCAQN4IECnmzaOmoQgggAACCCCAwFIIBCOxn7zf+42fXhgYDnm9zntu3rBjc/USdlYMR2Jn2offOdw+MOhzOxPjnX/n8a1LnlouhQRlIIAAAggggAAC+StApJi/z56WI4AAAggggAACixOIxuLtg8Fv/OzCTw/0Wi2F26+ru35zbVN9ibYXV6BxVSAUPdc5+lFbX3vHSHwqXlHs+EcPrf/srU026zUVey1V4loEEEAAAQQQQACBWQWIFGdlYScCCCCAAAIIIIBAJoH41FQoEv+ofezpd3te/7C/sLBw47qq7ZurNzaVa6hypitnOzbhj6hn4omzA929Y1oBRiXs3FD65fta9m1eTGmz3YF9CCCAAAIIIIAAAkspQKS4lJqUhQACCCCAAAII5JXAZGwqHI39+GDPU+90dw0ENfy5vMxVU+mtrfI21ZRUlbttc8eL4cjk4Giwb8g3MOzvHZgYHPJPKk2MT1WWOD5+S8PjtzXUljrpn5hXHycaiwACCCCAAAJrSIBIcQ09LKqKAAIIIIAAAghko4BmVxz1RX90sOfZA91Do5GCwgKtBG2zWjweR01lcbmSwSuDxUAwOjTiHxkLBkNRZYix2FQiS1SYWFp0z67qn9tds7Wp2FWkUdSMd87Gx02dEEAAAQQQQAABCRAp8jFAAAEEEEAAAQQQuFaBqakCX2jy4kDg+ff7XnyvZ9wf1R6NhlawaE2bCVGHjA6JU9qaflWVFd22o+r+66t3NJdoSRa7dcFDp6+1AVyPAAIIIIAAAgggsBABIsWFaHEuAggggAACCCCAwNwCk/GpicDksfaxIxfGjrWPn7gw7g9Nzn16QYnH3lLnua6p+JbWip0tJcUum+PK/owZruUQAggggAACCCCAwCoKECmuIj63RgABBBBAAAEEclAgHI0HIrFgeHJwPHyqy3e+zz8WiIajWs4lpokXdbSi2L6loXhTnaep0lXmcWiMs9dpK7LTMzEHPww0CQEEEEAAAQRyVYBIMVefLO1CAAEEEEAAAQRWWSAWnwqGY4oX1XtRUyXGpwr0q14aDe0usuqryGaxWJgwcZUfE7dHAAEEEEAAAQQWIUCkuAg0LkEAAQQQQAABBBBAAAEEEEAAAQQQQCB/BRhgkr/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAAAIIIIAAAggggAACCCCwCAEixUWgcQkCCCCAAAIIIIAAAggggAACCCCAAAL5K0CkmL/PnpYjgAACCCCAQG4ITE0VBCOxuH7jlTcC0dhUdDIe55nnzROnoQgggAACCGSbgC3bKkR9EEAAAQQQQAABBOYpoBQxFIl1DAbP9fpaqt1N1e4SF9/dzRNvDZ82MBY+3xeYjMXryp31FU6Xw7qGG0PVEUAAAQQQQGBtCvBN59p8btQaAQQQQACBXBcIhGP+sDKT1F5YhQWFNmviq8huddgslsJch8jYvshk/N3TQ//pWyeCoUmB/MonNvziPesK5zaR5tRMb0ZLoV4ZS+fg8ggoCJ55CAX6BC/0IeiPxl/95NzLH/QHw5OtzSW//sjGW7dW5vkfhOV5UJSKAAIIIIAAApkEiBQz6XAMAQQQQAABBFZL4I3jg88d6h0aj6RUwGErrCwpaqp0bW0q3t5cUl1a5LTn70QuE8HJZw72Kk+UUmQy9q2ftf/C3S3WuUMqX3CyfywUisR1fmOlq8xjT+Hl7XILKEwc80e7h0O6UZHdoqew0D6GR9vH2jonlCeqhNMd46c6J3ZtKPU6+a5+uR8d5SOAAAIIIIDAFQJ883EFB28QQAABBBBAIEsEuoZDZzomBsfCc9VHudl1zSVfurf57h3VnqI8HfipfCoYjl0iUt+3mPogFmSwePHDvm++dLF7MKhLfvdL2x69pWHu+HEuePZfk4DyxKfe7f7rZ86qlJYa9+8+se2GDWULKlGJ8GTsUu9ddTQNT8ajk6mdeRdUICcjgAACCCCAAAKLEMjff9VfBBaXIIAAAggggMCqCGiYs8Y4G192DXaeHuSp0aMn28f/+tlzPzrQkz4+elXqufI31cyJj93a4HHa1N+t2G3/xG0NtowjYJU9saLHyj+m5DsqDNSyKsl7Frp985byDbVud5HV6bDWVzpbG73lXnqbLlSR8xFAAAEEEEDgWgXopXitglyPAAIIIIAAAssq4LBbbt5W2Vzt1l1iU1PjgckLvf7Ofn8gmFjjuGco+ObR/hs2lG5rKl7WamRn4QqVHthVs6HW8/bJwR3NpTdtLqfXYXY+qSWslQZKq2/jgbaREV90z4ayddWuJSycohBAAAEEEEAAgXkKECnOE4rTEEAAAQQQQGB1BNxO26P76u+9vtq8vcb2vnZs8Bsvnj/VPq6dZ3r8rx8bnCtSVGdGvab0v4ICLe2ytIlbolBjyKmKTtwn8TLuqA3zXuaeRA2mz0k+7dKOmUNGmZkrfLnAggKrpXBLvVdfiXLM0i8Veuk383yjWGOvbpR4O3XlNTPVuLKAmXL0+/Q1+j1xYsaTZy1h/jtV52la1e/yUzMbYtoaBc61/9JR/Zb2mNJrkiI//9YZd79U30vlTlcwyccoPFGRmYZNbyfqZVberFJK6xJnXvr/pVPcDtu9Oy79iUg/2SwneSOldRmuunyvmfpPVzmx2/hQZ7g2+Y5sI4AAAggggEBuCxAp5vbzpXUIIIAAAgjkoICG9t69vbJvOHixzx/SwtDBycHRWaZcVPI4EYie6vadLPZCZgAAOAhJREFU6p640B8o99i3NHi2NpW0VLqXJBPRUidn+/zDvrCGYteVObc0eNVtsn88fLIzEXQq6btrW7Vxo0PnRnSyIqd1NZ7mSrfdWnixP9A5HNB6zebjaalyN1UqKbK09fgOnR1pHwzqtM313t3rS9dN99A0ztSw5YHxyPHOMfNCc0P5j9b6uJQtmnsLCjoHgxcH/ca9TnX6gpFLcy+e7Joo/siWTGGUsKnOk74KsfIkLTR8tsd3snviXJ9fTW6t97Y2eFsbizOOtE6qx7w31cZRf/RY5/jx9on+sbAG9j5wfXVVSdFkfOrdk8PReEzVu3lLhbmqifa/f3ZE64PrDpvrvPXlTpv18tw+Y4Ho+X7/iC+xzk9jhUs9Ou1JR41KqXX+0OSZHn1UfDrZYbVsaSi+rsGzuf7qrdNHq63X1z8aUp1HfYkxzV6nVevelHrsWxuL9Tg0Jj0cjXcMBjqGArqdutnqFsZ9faFJLUM06r9iDSI9BX1O1ldf8Sk9enFMTTDXiTYu169a5ltNriktMvekbySeXSh2ttd/omv8Qr9fl1zX6N3aULKuxj3rs5NDz0iiD3BNiVMfBnUNfvvU8ImO8fHgZHVJ0famkh0txRVeR/qN2IMAAggggAACeSVApJhXj5vGIoAAAgggkCMCCuwaKl0aDa2lb5XiaMljJSDaaTZPSyH/+ED33zx7TnnT9CtxRFGUErS7dlf/9qdblYkkp2nmhfPf6BwKfv2F84dPj9hthTddV/HH/2SXQrefHOr92+fOqxBnkeWb/88tihq1/fv/6yPFMeppdsuOyt/57HVapfpHB7uf298z4U+kYMbr4ZvrPn9n8xvHBr//Vue4L2L0XFMN6ypdn7ur+XO3NeouOjMam/rw/OgffPP4zHWXf7daC+/dU/sfv7QtpV0/PdL35GudY76oThWGOZfiD9/q+vHb3Zevn966+/rqX31k4/qaxDBz86UU8o1jQ//lh6fHfVETU5SK5lrqPP/5H13fUulKual57UI39OB+erjvv/34TDiimiZ6/j1fWPDXPz67b1vl731h6+/87ZHpDnsFv/PE1of21BrhoIK5v3i67UJvIrB78Oa6X3pgfXPV5bHAimi/8eKFD8+M6uhjtzf804c3lnkuB47a6Q/FXv1o4C9/fGbCf0XrNIPnxibvV7+8s6ki8RBTXvpc/cObnc8d6OkeCExOJipqPLJLp0337/vsnU2ND25QpDjsi/xof/cP3ujSUZ2psNt4jU5E/uFn7d+70s5iKfjM3c3/4hObkuPev3j6zOnO8fjlCPpSCU6n9bc/0/rxm+ouvU/7TWnm2yeH/vszZzVFQPKz08eptbnkq7+4ozYtjvzWq+1vHBmQ/7YNJZ+5vfHJ1ztPd05c+tgUJv4QbWkq/kc/t/6ObZVKvdNuyA4EEEAAAQQQyBcBIsV8edK0EwEEEEAAgRwT0ByLzpmFnmcimktN7B4O/cUzZ94+OqA8JbnVsek46rXD/UfPj/33f36j+vQlhZDJJ85rWxUocduiMS2zXDgRSISD2u4YDOpXbVuihe0DQUWKSjxDUa3Jm9hZU1akoEobCkC1aK9xpt7qNTAefvpA92FNkDceTg6nugaCL73f21LtumNrpU5LBFLxKy6cvjrxS3yqUMWab80NVUc3Sr6XcUgnGyDmmdqYjOt1RSGq2JNvdf3DK+1hxZlXHFETCs52+X75Tw/80S/v0rLFyZFucpnz3x6aiDz9bvffvXg+5cFNxiYPnRr+yfu9BqMKTOmvZ2LGEnW8spZTBdppND/dp3ck9L23Or//euesrTt5YfxX/uzgH//Krp0tpcm5n+6hD9iLB3sV1KbUJLmxboe12Jn4Zlvn69bpj0AVTX8Klvgsz1GReWJpnSsfgEq2TRam7zTroI6Tzx7o/tsXL6iX4pWnJZ7dR+dG/+l/ee8/fWWHJmQ0L9GG0lI9atV2cDzyVz8+OzIRMdl1VJ8ZLYv0jZfOK1C+a3tV8oVsI4AAAggggEBeCRAp5tXjprEIIIAAAgjkjoCSjr6RkNqjblPqLWXmWerm9s6JwTePDBg5iI6WFtvrKlyhSKy9169kRfHTwEjoW6+3//OHN5a4F79UrtNuLZ8e/qkMLjIdtyn06R4KGsTqEXZxIKDFefsn1OXwUsjVWOnUitU6YUdLScdAUENZ23sDGp2tPcMTka7BYM9gUDlpY407Go139QdUVb3aunzvHBsyIkU1p8Rj39xcYtxFv6qZF3t85tv0jW1N3p0by0anR/72j4QVWapYnVZf5SovTu2qua7O6y66/P2hkqzj7ePfe7VderpEPRM9LmtDtVsltPf4dVRtV5z6J0+d/vpv7NXC0+l3n/8e1elU58STb3QYeaLx4La2lOhe2j/hi3z9uXPzL20+Zyo1O3J+9Kk3Oo3W6Y4et00swu/oE36idXL7oydP/a/f2mdkwUaxzx7qUTCtQzMPtqC8xFFRUuRxWtVXVBVWhKdWlJdcSpCL3bbNDcU7Npbq8kg0Pjimp5AY7KwPQ12VS8F0cm1VjfW17pTuf60txXFLobJR48yewYDG+ydfNev2sYtj33uzS4PujaO6XUWpQ38EBkcSEwVoY2As/Cc/OP2///XNs2br/UMhCSiLLPbYvW67+lSqO7Au1M629okPzozqY8wI6Fnl2YkAAggggEA+CFzxHUw+NJg2IoAAAggggEAOCJzv8x84PWxMoehx2Sqnxxcb7eoaCv7D651GnqjE8Jce3vCx3TUKHNX3rnMo8Pt/f6x/JKQk6Cfv9nzqpvrrmjTtXqJT2Fsnh9RFzsz+MhPVlTt3rSt1OiyVMzPKKUXSXH4KoXqHEymnXrpd+2BiKO7gWMjs9tdUoYkUE5HiXdur922uUDTzP3564cX3epUqKsNSNTY1Fv/8vS37tpRr+4X3+77zavvQWDgciY0HopoMUTMtKhXau7n8L351d+Ie0y/N4vdP/uw9FTWzI/V33UiLQRsnqCPkD97sHJhOlL54Z9ODe+tSoit1vTTnKFRBmtLxuUO9GtCtba/b9uBNdV++p0XLTAtwcDz8Zz9q07hvHbrQ7decgPfvqlENU28/7/f9o2FNiaikWFfY7ZY9m8v+zWeu04yEupdmG/zmq+3PvpM6THveZc9+4rnewAuH+43WlXrtD+2rf+KuJk01qBBNz1H9EI+cGdXdz3X5Xjs2cO/OajO2/uDs2HhilHSi2Pv21HzujqbmKrcyR/VklKd265C+3DO9aL1FtodvrL1nR6JPnwZBP3Og5zuvtGtbvVb/5aObd7ZcDogTJRYW6BGY90rsKSj4jU9sTu4q+DcvnFffVd9031jjhPRfe0ZCB9tG9GnXIYulcGtz8b98bEuTAtPJ+Ifnxv6/751UkKpPhT54Gmn+4J7alE+CrtLnWfnmP35w/cf21Gp2SH0Iv/9290vv9ylL1edTM0LqzxqRYro8exBAAAEEEMgTASLFPHnQNBMBBBBAAIG1KqDeXh9pZeeZwEMT553vCxw+M3K222fEZC017n2t5UbzFA+1dU10DSSyPK/L9snbGx67pcEzk+woFvm3X9j2//7PD1Wm8pTjHePraz3KffpGwhrYe6Y7U1+/ZL59rRWaPVC90iqKL3VyVKQ45lekODU0GlawpPQtEJxUP0Rd1T92OalsqFAvxURLnBq1bU+kbwqPNHeeXqqP+oJ98matbV2l/o/as2tD6aEzxe+MJTqUaTZDBTpaokQXF9ksRcWXF8dQr7cZm0Q56S/FfGbSpx6ICr6Mc9Sp8KoTSvYNhw4cH9L5ihp3bSz7tel+ncb15V77v/3c1n/8JweC4ZgCpndOjdy5vcq8UXo1rrpHC5i8c3LYyOm0Is2vP7KpZWaJklKP7R8/sP7g6ZG+mU6gVy1tPid0DwY0nlpnFjmsezaX/8rH1iuDvtQ6j+PffKb1V//8kJ6LWvf2iWEN8jVjPvVFjWi5nenXA7tqrl9XqgkTM9xR5HrQRlarAfCumQ+kClQXxYqkpzlXISWuK75pVwmJ/DLjS7H7u6eGjT8jWolFyaDqqccvYc922z/7xMY/f6pNBejzo4HtD95Qa/4RSy71/r21D+2t01oxCiVVT03aeF7LB7UlYt/h8ciIP9HBlhcCCCCAAAII5KfAFd+d5CcBrUYAAQQQQACBbBbQms4/fLvr+YM9RiUVkUwHgnF1odKeihLHLVsrtSyycTQQiXWNJOaN09syj+MLdzabeaL2KE/Zu7msttLZ2RdUT7SOYQVDcUWKmjxOo3fH5p2PaHVg3VzRXpn7UrSnErT0s0aPqguY8qkbW8tfP9zfOZBY2Fe9CI2YTKmcUjx1+zKqmvKrztm5rnRbc4mRJ+qoAsRNDV6NntZ2ZWmRMp2US5b7rXA0GZ/RiU9LynzqlobSpHHiisOUkN5+ffXLh3pVea1hbbAvulYanysrXS7A9XVaTrrYpBJaVYnjvt01//DyxUWXn3Kh0TrlodqvRaI/sa8+uXX6qGiqzVt3Vr36fp9OUI+85LkI1TFWzdd0hHp95/WOYX9Ua5Vo3kxdldiVHS99pAemPRNPqtKlNbKN6km1xGW/Y1vV/3zxvM+vlWWmLvbOGabfu6NKT9n47OkpaI1vddHVhjQ0w8B8Bl9nBwa1QAABBBBAAIGlFyBSXHpTSkQAAQQQQACBJRRQ5KFBprMWuLHBq0V1799VbfT/0jnqU9Y3mujWp9xEqcfJzvFTXakpTzCsxDGROfYMKRpMbNjthTWVTn90OiLS+6u9qsqcygeV1BQ5EiORFSMqYuwfDxcmQs4C9dS7pbXytQ/6h0cTnbm03+jPVlF6aWa9uYrf1lycvFRxTWnRE3c1f3J6MV/1LkwOvOYqYWn3q2vk4EQCUy+FhsP+yKvHBo23xq/KEDUdpLHdNxwwOsQln7CgbTGqa6cuUcjbXKvQ7ooHJ+2NdVesQ72gwtNP1kB1jUE29uujMuhLbZ2Sa2MCSp0zvVzy5TJu2lJ+7NyoVnTRrlMdE71Dwafe7Cwrtm+o86pvqVaqqS1T7nb5/JXf0kdO1QsEEzXU7JxaN9z8M6I9+tOhPrzNNZ4T58d0pmZ+1CozjivBjTrrQ6hPrVl/fbY17N1iLYxPTunpX2OIbBbLBgIIIIAAAgisRQEixbX41KgzAggggAAC+SWgLmHG6GA1WytUGEGGxn5qvLPmgEseExqKxI2eborAtPTEf306MbQz5aWVMXRUL3XBM4qqKnb85qObFSGlnDnXW7fTpk5zOqqJEd0u29hERNFk/5gmU4xrOKpG6bY2eHQ00Q8uENV+o4NbfUWib9tcZWq/FntR0GOeoDVndBfjRubOldxQ/0St+WvcUZh//+KFlJ6SUjSXKPEHUtaDXlhNBag42Eh4FdeWey6P7DYKEmz6zoXd48qz/aGYZs809mnd5//94vmUDqT6kJiBqT+g3nyXr39oT63GPv/kQI/Cbj30ofGIvqz9hW2dWkhnUIveqOesMV7Y7Gh5+eIV2dJwZjXQ+OApBFSVUm6riLamzHmiYEz7lQXr+TaUO1Nqq7g80RvzymxUD+LKHSkF8xYBBBBAAAEE8kXg8ret+dJi2okAAggggAACa0pA8xL+4v3r9mwsM2r9ytGBn7zXq8VnFZoo0AmGJ5MjRaUdZuylXm9aQzlDW5WWGPPHKRnUtH0ZzpzrkMIvLesxHSnGFR1qjLYW/K2rdNeWOnWJ+ldq/YqB0bCRRjVVZRoYq2qr+5fGRc91r5Xfn8CcqY4we2ZWnpm1JoWZwtJZr7hip/K6mdWME8/ETJDNk7RTtubb+W8kMujkOHDmSrXOzMb0WVKX1Zkjs/xuOhjHyj32X7in5bbrKl79aGD/yWEtgWIk3Rq7ra/ekbCsjrWPf/7Oprunl2SZpcRl3zVVON0V17hPSv2NnVdqJiWmM3W7xmc6Uwy/I4AAAggggEBuChAp5uZzpVUIIIAAAgjkjID6SWkRld0zkaLWAu4cCLzx0aC6YB29MK4FPT59a4PZWK15oqGaxltNXHjrjkrldObRlI1tLSVux+VBnSlH5/NWi3JUFjvae9Tdcap/JOwLRdW1sLnGrf0lXru6trUPBLQstbGQdJMWBZ412pm+k81mWVxkNp96znqOcjb971KqOtsZwtF8jsYR9XTb1ORtqZozeC122zUH4mzFzGufZDTPpDFJn56sMYHjvK682kka4Kz+j+lneYpsenbGfvV43dRU3FzpSj/N2KNlW1IGYteWFenydTWeT9xUry6KZ3t9JzomTnaMa9ESdfrTutUftI1oisaNdZ6muYvVI5ieEXSu2y5+vzoY6pEpM9UtFAdrXsWUstSB0RzWrUNXXagn5XLeIoAAAggggAACRIp8BhBAAAEEEEBgLQkoo9mxvvSDc2O+QFTjVT84O3rrVq2McSn5UjbUUHEpGFKut3dz+b7NlxaDTm+kMkdN25e+f/57tJSKEUsZA5/Va1LBk+ZDVDam2evOBCa0uIo6VBqd5JRYZRj4rLDR7DQ3/wos9EyX43JwOR6MBiPx5OVrUkrTBI7VM5GiIqrNDd4v39OSco75Vk1zZVz12Dxz1g21XV0+HQ6LenoqT+xO616qTnTGsOj0y5MzYzUqOrMWs3HmqC+qnoPpV+npVxVf+tjo1tc1FX/pzqb004w9ap26sqYc1bPW0iX6UqCsKRTvvT4yPBHZf3r4Zx/0a+5FBXkX+/2dQ8GUSFHhqTmtoQbem/M5phR+jW8VzipS1B8HzZOoL6M+eohGscJUzHp+Zolzt8taNL3I+DXelMsRQAABBBBAIK8EiBTz6nHTWAQQQAABBNa8gFK8PZvKD58dfffEkKax++jC2NsnBh+/rdFoWGJlj8rEoGO9tC7zmx8N3r61Up3FjD1L/quWZ5mJFDWhXnh0PKL1K9SVT0OqNZK6rX2irdunQbXGfbWCcEpPtyWvz1ULVK9D10x41NbjUya7qS4x7eOsL9W22G3TwHNfYFIrI5/t8mmFlhvWXxqBPusl17JTq4iUeR294aDudbEvoNn9tMy0WaC6Ll7oT6ygnf7SQze7f55un9AEiFMFHmNUr1aYudjnVy/C9KvUn1Q9K7V2s5YtVuh2rts3Fohev+7S0uHp52fYo6L0MdDXVH2BuM50+RTh6fyJYEzLIqdcqKTP+Mxov7LOD8+Nfmx3Tco5S/JW83JqofBAKKC1gzQDwOELY2a8rjzxwOmR8UBi1SOFjw1V7isHQS/J/SkEAQQQQAABBHJcIPWfW3O8uTQPAQQQQAABBNa+QGuD9/oNpeqBpaYoFHu/baR39NJEeEW26VHSmxOxl5Zb0eDTP3+67Sfv9w77okZXQe2fjE9pVWitZXyNKxSrKN2uYnrwrKbSGxmLBEMxZVstVS5Fiutq3RrvfPLiuHEX7dGSzYnZG1f1pUkeDTfV4tDpkWcP9ihY1DIyequRsP5wbMQfUQxn1rGpynXvrkTgpVhKSdnXf3L+/7zd2T0cVMBnnCPVIV9EffGMlUDMCxexoeT3hunh7RI71+P75ivt5uIw6k15oG34uf09sxarLoQet35J2Co9fOH9vkNnR5TlDYyHn363+92Tw+GZFillHvVHzMqvr3XfOT3XoXoUnmof//rz53/wblePJkacaZ1+10rQHUPBlIkGz/b6T3ZO6FMXUgfFmWNi1Dj3d04Md850sVSfULNDollzhc4aRm3M+KnwdP/Joaf2d2uhGANQt04s6aPB8uYFi93QoOybZrrodg0Gvvtax8EzIxoGrnv97MP+777WbtRcw+0f09QBq/zBXGwjuQ4BBBBAAAEEVk+AXoqrZ8+dEUAAAQQQQGBRAuqVtntD2XstI0oM1VFRc9i9dXzos7cnOipqNVpNWfjYrY2nO33B0KTSMc26eKE/8NqRAY/DqnkYlf1p/Kyipc3NxU/c1VyctMLyIuqSGPjsTczHpyRII3aVCqlnn2bZ0+oi66fXexkeU4+5xKu02GEOO1Wm8+Qbnf1jiRhUlVcQqQ2lWj96t/v9MyPa1orSd++s3rcldci2ijrb7fvu6x3J+Z1iKeOtfj12fvQPv3PcjIf2tlbcd311cqqlUbqNVe62Lp/6qQ2OhV881NvWNaEmKFdSwKQ6lHgdd++suqW1QtXQq7bM+cDumqMXxi72+nXJ4TMjWul4//Gh6bkFE/8yrahR45Qt1sJ//6VtyTeavnphvyhS1BLer380EAhOqgPd8+/19o2EtFSxskJ1k7w44L/QO3svRd1m54bScz1+DTxXjPv60QGdqSk1VTf1Eg1G40ZXRJ125PzYX/7ozA2byu7bXdNY4dIY+ft31xzvmOjo86sVh9pGtJzOO8eG9KlQQqnzzdZ99cs7kuPgH7zd2d4f0NM3OkgaayDr5LHA5Llen/pX6loN5W6udrdUp87PqORTvS81eP/ouVE9OQ3x/tbPLopURekWiQ9SNKaPyr//0nazT+uTb3ed6ZzQKGkVa7yOt0/o86Zt5Zg/eufSx0ZvvS77Hdsrb55+fPoc7t1S/s7Jod6hUKJ1p4cVp9aXJYZpK/oUl85XsrmuzqMPCYmiAcuvCCCAAAIIIDB/ASLF+VtxJgIIIIAAAghki8B1jcV7NpVp1HM0Glfw9N7pkTu3Vyr/Uv0UzdzcWv75u5uePdAzNBpW0HO+x6cvHVJwph5wRues3vHw47c2XGOkqDn4NFbXQFHBCmiUXmlkq+6ybjpSNMI+nVA/3XXROFMjc1890n/uyoBMWadGc+tL55R6HQpG0yNFLaeinnHP7O8xizUKNH5Vu5RPJc9CaHNY79hamZz0CefBvbXne32nOyYUUGo1an0lF1JT7lTPRDNSVJc6LWLz+buaf/BWp4YGK401b2H0szP6YCoCi3zuuuQbJZc5z225adyxMr7nD/bqqWnxECkpZdONlHUqtmuodnUPzL6E98M31h04OaxxxKqPJq/Ul3FTl9N62/YqtVH5nfb0Dof0FZ6MK1VUpKjZNq9fX/rZOxqffqfrQo9f8XRnf0BfOjPRuqlEz01tq3Xq2ZocKX54dvRMt8/4IOkEYxUUbSS/dqzT7IrVddOfyeT92tYQ+IdvqjvTnUiTRdrRH9CX9pvl6HP1776wzYwU3zw2eOjUsNGZNKWoxMfm3Ki+jP3lJUV1FU4jUtSz27mu9KG9dT98p1sgShWPnhs7WjBmlqAhz5rxU8upa20WcycbCCCAAAIIIIDAPAUY+DxPKE5DAAEEEEAAgdURSIRKylqufJW4bQqDWhuLtVt5k9KZd08Nm6coIvncHU3/7OMbH9hTU+yxm5crfzFjIOV6Sb2+zEsXtqG6KUczerTpSmVAiuS0oRqrl5x5X+1RTmcmROomdrm/2Ww31ELMlyuadILyLdV/1jwx6azLm4kULFWu4MaNZb9w3zqthS2ZtIMFgXCih+DlIgoKytz2n9td8ysPbXjstsaqRAfMSxcpvDPyRJ2sR+ALTZq2yZcvaFudKL9wZ9Nn72ysLi8y8jUlbipcQe3e1vJH9tXPVdqmOu+X71t345Zyc1i3ztQK1Ldvr1Ivy9qkORmNEsyq6qPy4J5ate6TtzRo5sErWjdz0qXWzdw7MqkqXfF8Zk5MnJHI6dT5cU/tz9/botWBlOvNXHf5d81yeNf2qq88sH7ruhKz76oOm+Vo/s1AJJaIM6dfChMzf2BmTkyEkkaXSWOPPoSP3tzw8/e1bFtXYn5KdUiniVSfgV9/ZNM9O6vMy40NfVCNZ6y2XNpKOkM9cPXxTtrBJgIIIIAAAgjkqQC9FPP0wdNsBBBAAAEEslxAS0mUOm3B8KRGAWuV5/Tabmsq+aWPrdfiGzqk9Wo1yNQ8R1GaUqRHbqrb1lx8U2uFBtIq8BrxRxUpKiNR3zRNa1hebPe6rmm5Z+N2zdWuf/GpzepVp7dKbRqnB7oqcVFs9Buf2mwmT9e1lDhnFkRW0PPl+1rG/Fckd2bltaHmaLLI5D3GtvKdDbUe3S790Kx7pm+a2kZloOo9V1/p1HIrmrNPa5JoRK3CLKVpOlTmtWtQeXJpumm5137PzmoFuLs2lo75ourvpkBWQZvySk0PKUx1fvQWLcF3lcrXtjR6n/C0tDYVa1z2iC+qNK2y2F5RXNRc4561m55RVWVc6t5YVerQhI/9Y2ENbFdRGl+sUK+u3Knos2F6bRx9MDTZZWOVSzuNC9U6LZZy7/U1rQ3F6rqoodPT8y1q2ehE64x5D7UotibNNFM0XfLl+1s0HaeyV83XqQ6MOiQ9PV85JJbJLitSxKkQWW+TJc1tnV9TVvS5OxrVzPY+vzDHE2uoJBJFrfTidthKPTaHTfe59PrMbQ13bqs0A9yZ3bP87iqy7VhfYh5Qe7X++Kdvbdhc79WfFM0vOapFyS2FGk6up7alyatuoeZdzKse2lO7tb5YFZKh0fPXPKSNe66v1oDxWCyR825rvnyv5HPYRgABBBBAAIF8ENC8Oea/gOZDe2kjAggggAACCOSdgL7ZCUQmx/yJ1EY5jZETKVhMD1PyjUbrsWiwsBEpKn6Siddp06jbDDLCDEdjmjTQmNovsW6yy64s8nIAtkSI6p9oxJ1lHrtmLdTb/W3D//prh43if/cXtn38xjoFmil3Uy6n4Eyhpw5pVLtapAoHFSbHEiOXE1/WQtV1rtrqZE1lqNYZGbEytWKnbdZkUGHiRGhS3QmNSFEVcdisWo9Fw7d1l5RaZXirCivv9mnBG/X6LJhStYWpmi+okAzlm4cSDpHYeDCqkpUnztp90jyZDQQQQAABBBBA4KoCS/DvyVe9BycggAACCCCAAAKrKKD8yFNk09cq1iE7b63+d/paUN2EqdRMXwu6ahEna/it+g8u9EKN1VVepi/zQlXYPe/a6mQlevoyL59rQ2FlkX3B1UsvTRUucdn1lX5oafckHBKdKK/etKW9L6UhgAACCCCAQK4KpP7Tbq62k3YhgAACCCCAAAIIIIAAAggggAACCCCAwJIIECkuCSOFIIAAAggggAACCCCAAAIIIIAAAgggkC8CRIr58qRpJwIIIIAAAggggAACCCCAAAIIIIAAAksiwKRCS8JIIQgggAACCCCAAALLK6AVRbSwsnEPTUG4vDejdAQQQAABBBBAAIGMAkSKGXk4iAACCCCAAAIIIJAFAhZLQUO58+M31Rl1aalykypmwWOhCggggAACCCCQvwKFU1NT+dt6Wo4AAggggAACCCCAAAIIIIAAAggggAACCxRgLsUFgnE6AggggAACCCCAAAIIIIAAAggggAAC+S1ApJjfz5/WI4AAAggggAACCCCAAAIIIIAAAgggsEABIsUFgnE6AggggAACCCCAAAIIIIAAAggggAAC+S3A8iz5/fxpPQIIIIAAAgjkgUBkMj4RnAxGYtHJeGFhYU1pkbvImgftTjQxFIkP+yKhSMxmK3TarV6nzeWwsl50njx9mokAAggggAACyydApLh8tpSMAAIIIIAAAgisskAoGu8fDbUPBj84O9I+EFS45nRYf/WhDbvXl65yzVbq9p1Dwf/zVufJzvFSj72p0rWzpWRLQ3FNWVGJ2164UnXgPggggAACCCCAQO4JECnm3jOlRQgggAACCCCAQEJgLBA9fG70b3964UynbzIWN1BKvHZfcDI7gaamCvyhyf6xsKpnsxZWFDvUqfAaqzpVMDU0Fj55YVzl7C8o+H5BQXON+9FbGx7cU6vemlYLueI1AnM5AggggAACCOSpwLV+l5anbDQbAQQQQAABBBDIbgFfaPK7b3Z+95V2M0C0WAodNktDpcvjvDzqORaf0pkaHWy0xlVkLXbakscF6wTFfMGIRkwXOO0Wde5bvnZHYvE3jg/+4bdP6Ba1Fc5f+fiGR26su8bblbntlcUOt9MajsZjsSmV1tEf+Ppz545fHP+1Rzauq3Fbklt7jTfjcgQQQAABBBBAIG8EiBTz5lHTUAQQQAABBBDIG4H41NT33+n6h5fblQaq0QoTyzz2ytKizY3e27ZWrqvxmBKj/qjGBb95fMjYc9eOqifubi5xXf4WcXA8/NT+7jePDWnE9L7W8n/24Abz2qXfmCqIx6eMDpWa9lEh4LXfosxrv39Pjc1hOd0x0TsUHA8oP03MKfnWsUGLpeC3Pr2lttR57XehBAQQQAABBBBAIN8ELn+/mG8tp70IIIAAAggggECuCvSOhr/10kUjT9TY3qYa9+984bpd60ptVktKk8PRWPdgsK09MS5YL80vuLXJe8+OauOtflX/xAu9AZ1QZLeWe5axi6J5x6XdsFstt2yp0JeKPdPj+9ar7T97v09hpVLFo+fHnz/U95X71tFPcWnNKQ0BBBBAAAEE8kEg9dvKfGgzbUQAAQQQQAABBHJYQIN7v/N6u/riqY2aKXBjY/EffmXnDRvK0vPEdISzPb7DZ0fVyTH9UA7s2Vzv/eUHN3zy1gbljGrOwGjo/baRYX8kB5pGExBAAAEEEEAAgRUWIFJcYXBuhwACCCCAAAIILK/ARHDy+f29xqhht8v2H5/YtqXeO88ZA8Pqk9gXONfnX94qrl7pWvT5c3c2PbC31qjCxf7AS4f7V6863BkBBBBAAAEEEFirAkSKa/XJUW8EEEAAAQQQQGBWge+91WF0UdTRh/bVVZQ4FjSwt63b9+6p4VlLzrBT3RrVtVHdG/WljXn2cky+JEPh6YcWdzujnPU1HrPPZu9w8J1jg4GZ1WnSb8QeBBBAAAEEEEAAgVkFmEtxVhZ2IoAAAggggAACa1XgxUN90emljdWAR/bWlS5wjeaBkdCp9gktA+11zvcbxchkXNMUHu/0tfVMuOzWLQ2ebU0l6g+oBabnQoxPFfSPhY53jJ/onNCa1NtbSm6/rnKed5yMT53r9Z/qmjjV49NaLhtqPK0N3usait1Fl1eynuu+2m8pLNhY77lhS9l7J4eVaWr9maMXR43JFjNcxSEEEEAAAQQQQACBZIH5fqeYfA3bCCCAAAIIIIAAAlkrMDwWSXQULCjYtaWstsyp5VnmWdUSj91qLRwZj1zo8x9oG7n/+suLtMxVgm5z5MLYv/+7j0Z9kXg80UtR0zdqkLXuuXtz+W98cvOWeo/Wm065fCwQ/fZrHU+91RkIxRKdGqcKfmzp9rhsd++q3t5cknJy8ludebrb9zv/68jQaFihpJaH1tHC6dvVVbl+87Et+zaXF9nnzDHNojbXe267rkKRovaEonGliuYhNhBAAAEEEEAAAQTmI3D1b7nmUwrnIIAAAggggAACCGSDgCZDjEQTC7PotbHOO598zThZv25tLr5hY5k2NMPgwVOJHnyZX7H41Pfe6vxXXzvcPxpKrKEci2tPLDalxZT19tCp4d/+Hx++eWJQfRiTy+kdDf3Vs2e/8/LFcV9UZ07GpnSVNsZ8kcNnRt4+OZR8cvK2zvzhge5f+4v3egaDxpLNidvFp9RRUbfo6Av8/t999OzBHk0lmXzVrNvuIluF12HML6lB4kMTrNAyqxM7EUAAAQQQQACBOQWIFOek4QACCCCAAAIIILC2BJQB9o6FzCiwtrRo/l0U1dJ1NR4NQLbZLOFITKni6R5fhubrLhq5/LUfnfGHJo07qjdiY42nvMRhdEtU2Dc4GvrB290qKrmc144Ovnl8SJmgaqsz6yqdN2+v3L2lXH0kuwaC+4/NHinqFgPjob/8YVsgrI6NifKKHNZNzcVbWkrcTpsmi1RfR9Xkm69e1Jjo5NvNuq1uk3abxTk9UFo1GRwjUpzViZ0IIIAAAggggMCcAgx8npOGAwgggAACCCCAwBoTmCroGQ6ZnQurShYWKdothZsavNvXlRw5O3qxz//W8cHrGrxzCYQn43/3crsCPuOEhmr3f3hie2OlU28Ptg1/7dlzfSOJcFN9FU/urmmqcrkciYkOe0ZCxy+Oadiyth12y8P76n7+npYyr0OBYMdA4Ptvd71wsNcoMOXXYCT2zdc6JgKXeiDeuav61z++scyTWHlGSeL//OmF148MBEKTPYOh/aeHGqucVcVFKSWkvFUiWey26ZJwNDZCL8UUHd4igAACCCCAAAJXE6CX4tWEOI4AAggggAACCKwRAYWJ3SPBxNyE06+FRoq6SIuc7N2UGPs8PBE51TExHowaRaX/Go3GXzjYY+7//Se27mgpri4t0tf9u2o+cWt9ebFDRzUkef/pYSWJxpmaeLGtx5eYcrGgYN91FY/d2riuxl3usWsY8o6W0of31q1v8JhlJm+onBcOXLpdQ437tz/durHOU1XiqCx2NFe5/69PbFpfm5i0UbMrHrs4MTwxZ7XNMp0OiyJFvY1OTvnnMVbavJANBBBAAAEEEEAAAQkQKfIxQAABBBBAAAEEckZgSp0HzcbYrVq5xHw3r40Sl00dFesqXcrm2vsD+0+PzHqZMsERf0SLqxhHtQ7M5vpiDSU23jodVq00rbzPeNs1FDTnN+wfC4/6E3mfzWrZUl+slZqNCQ2n9xSur3Hv21xhXJX8a+J2vohvuouiWvQL9zbXlBaZF2pPdUnRvq0VJdMRoeJLs+9kciEp27pcddBOJbCa/zHlKG8RQAABBBBAAAEEMgsw8DmzD0cRQAABBBBAAIE1I1BYUKieifpVQZkqrYWVtQpzQWLA8Xxf6ui3ucG7d3PZs0PB7qHg/hNDm+pm6TaoYruHg2ah6mDomMkTjZ0NFS7PpSkOC4bHI6GZ8dET/qjGGuucUq+9qsyRcpXXaW+oSAydTnlpWkbdzoz9IrGpN04OTjfz8ok6Qeu36P3weDgUufoKLer26JuORK1Wi9O5EKPL92QLAQQQQAABBBDIXwEixfx99rQcAQQQQAABBHJPoKHMmUgUp18D42GFcQttY2OFa+e60p++369JBi/0+U91TaSXkMj4ZsYy62h9hdMyc1PjZC0L43XZ1A3QWMo5NLMIdTAci0QS/SgVOOorpWSHLXFVyk69VS/C7uFLQ6c1Zvq7r7SnLzszHpg0OicqvpycvHqrtdDzRCDRX1JTOmoyx/SbsgcBBBBAAAEEEEAgg8As37RlOJtDCCCAAAIIIIAAAlkroCHA9RUuc7CzIsXJhUeK6jm4sd6zY33JB20jGrOs1Zlnb29SajfrTDo6bpySdGKBxlMbEylaLAXmyGWzfI3TTs8KjaPGKtLGdu9MvGhemLyhQkyB5P0p25oL0ugvWWS3lBMppujwFgEEEEAAAQQQuJoAkeLVhDiOAAIIIIAAAgisHYFSt00zKBr11erPk7HLUyvOvxHrazw3t5YrUhzzRY9dGKspT109WYFgVenlnUO+SHp0qd6C8emRyMVuu8N2aWSxugTabBbFeeFoXEOP51klq7WwMWlA9Kam4s31nvRE0ijN7bTVlbsyl6wh0lpCenK6Ak67tXJm2sfMV3EUAQQQQAABBBBAwBQgUjQp2EAAAQQQQAABBNa8gHr5edw2DTTWAOEPz4z6Q7FyrzkSer6t0zonmxuK66tcPYPBgdGwMUA4+WLdpanicmx3+NxY7N7kzogFWiPFF1QXycTOihKHq+hSpOhx27WtSFFh5agvosPJA6YTK6WkZ5Nay8Viaax0mxWoKiv6ygPrHNOLq5g7zQ3lj5XFl+NOc3/yRu9o6FSXb7p2BU67RctGJx9lGwEEEEAAAQQQQOCqArOOU7nqVZyAAAIIIIAAAgggkKUC29aXGsOEtVDJB+dGNH3hQiuqDoCJxZe3JBZfVlc+Y6nl5EJ0QrnXbi7xfOriePtAIDkN/NmH/UMTEeOS+nKnd2b9E11lzJaoPoxaUbo3aUJGnewLxxT2Jd/I2Fa3S5VQOhP8nemY6BwKagWYlmp3+pfmglRKmF5I8p5zvf4Dp4eNPepEuXG2JWiSz2cbAQQQQAABBBBAIEXgKt9vpZzNWwQQQAABBBBAAIEsF3j8tgb7dA8+9cJ77r3e8elFSBZa59oy5+4NpUWOOZdCdjqs9+2pMYrVpIT/7cdnPjg3qgVStMz0s+/1vvBerzoh6qjCzRs2lqk048ztTSXrqhP9DdWB8eCp4ecO9mjCR+OQLnz7xODLh/uNtym/uhzWz97RaOwcGgv/7fPn/+6Vi2d7feboaXV4HAtMahUXcymYlBLMt7rR6a6J3qHEitVet21Lo7ehfJZlps3z2UAAAQQQQAABBBBIF2Dgc7oJexBAAAEEEEAAgTUssGdDWWtL8TENRo5Pnbgw/tKR/k/d3FAy20rKGRqpRUs21CUWaXn/9Misp2kVly/e1fzakYHwdC/Ig6eHleXVl7s02vlsj69rMKj5CnXhro2l168r9c4s7ryh1r29pfTYxfFxf7RvJPTM/p62Ll+Fuh8WFmgotBaYbu8LzH47u+UT++rfPjF08uK4TjjVMTE4EfnwzIhWVlFNtCCLGqvpEXXLX/q59a2N3lkL0U7N4XiwbeS1owNG9ZoqXfdcX60S5jqf/QgggAACCCCAAAKzChApzsrCTgQQQAABBBBAYK0KqEPfZ25rPNPpU+fBUCT29FtdsdjUozc3VHjtC2qS4rbbtlbOFSlqOsXWBu/P39vynVfbNYpZPSKPnBs7UjCWfIt1dZ5P3dq4rsY9s2BMgfo23rG9Ur0L3z42GInGu4eCPcNB6/Qyz1pJxuOy1VW6ugcDxiyHyUUpNawrd/7Sxzb8/csXjp0f0wlDo2F96RwdUiKptaS1bbNaHr25Xh0Pk6doNMtRJ0qFkt99veNst087Navj5sbinetKzRPYQAABBBBAAAEEEJinAJHiPKE4DQEEEEAAAQQQWDMCd2yr+lFz99Fzo+qL19EfeOqtLq2ysq2lRDMPNle5il1K3mbJ3NTXL3m1lGK3bWvTpUVaEi0vLEi5SnMpfu6OJvUTfOZA9/kefzRpBWeNmL6ptfznbqhVKGlMnmjabWnwqnuj+i2+c2JIsz0qHNR0jRofXeZ13NRaoRp+8+UL4cgsi0GrM+LtWyucDst7p0Z+dqS/f2Y968QiMIk4MfFSLqm5IxWhat1rY49+9YUmtVxMx2CwrWvi3eNDJzsnjPyxqdp9185qz8zSMeb5bCCAAAIIIIAAAghcVaBQK+td9SROQAABBBBAAAEEEFhbAm+eGPras2fP9fiUr6nm6pFXW+6sq3BubS7RCOKWqkvrNStuO3x29HyfX+dsbym5cVO52aNQezS4+L22YcWR2lZI11jlvntHlbaTX1pc+p2TQxrprEkbR/1RJXlaQFkx4vZ1JUoPnfZZZmNUh0Ld8fjF8f7R0HhwUt+OlrrtVaVFmxq83iLbTw/3KfIr89j3bC5XR8jkexnbI77ogbbh4bGweh2O+KPh6eWtVT1FpZ4i293XV6tfpJl+as3rnx3ue/P4YO9ouHc4qAHXxje/TVXuz93V9Imb6xc6JDy9PuxBAAEEEEAAAQTyUIBIMQ8fOk1GAAEEEEAAgdwXUGz38pH+n7zX+96pYQ1/NhtcW+H83S9tu6U1sZrz0r40laFWPtEwZKWB6sB4uZfg3LcJT8b9IUWKWtDZptkbdaKmYlRtFQhqhZnknoazlqG1WXRHDaBWaKobepw2d5Exivry6V1Dwf/+zNmXPugzd6luyi6Vqz5wQ43ST3M/GwgggAACCCCAAALzF2Dg8/ytOBMBBBBAAAEEEFgzAor0HthVU1NWpI5+JzrHz/cEtASzFifxBSeTRygvYXs0h6O+FlRgkc1S5L0i1FMyaK7lctWitKxKdUlR5tPUDVNZp7pearB3icfeVOVqbSzWoOy9m8rVqzHztRxFAAEEEEAAAQQQmEuAb6TmkmE/AggggAACCCCwtgWUo+1aV7ql3numx9fW7RseT0SKihobKi6Nel7bzZtf7Us9dq3pvLHOo86JpV77uhrP5npvVbEjeXz3/EriLAQQQAABBBBAAIHLAgx8vmzBFgIIIIAAAggggAACCCCAAAIIIIAAAghcVSAxZw0vBBBAAAEEEEAAAQQQQAABBBBAAAEEEEBgngJEivOE4jQEEEAAAQQQQAABBBBAAAEEEEAAAQQQSAgQKfI5QAABBBBAAAEEEEAAAQQQQAABBBBAAIEFCBApLgCLUxFAAAEEEEAAAQQQQAABBBBAAAEEEECASJHPAAIIIIAAAggggAACCCCAAAIIIIAAAggsQIBIcQFYnIoAAggggAACCCCAAAIIIIAAAggggAACRIp8BhBAAAEEEEAAAQQQQAABBBBAAAEEEEBgAQJEigvA4lQEEEAAAQQQQAABBBBAAAEEEEAAAQQQIFLkM4AAAggggAACCCCAAAIIIIAAAggggAACCxAgUlwAFqcigAACCCCAAAIIIIAAAggggAACCCCAAJEinwEEEEAAAQQQQAABBBBAAAEEEEAAAQQQWIAAkeICsDgVAQQQQAABBBBAAAEEEEAAAQQQQAABBIgU+QwggAACCCCAAAIIIIAAAggggAACCCCAwAIEiBQXgMWpCCCAAAIIIIAAAggggAACCCCAAAIIIECkyGcAAQQQQAABBBBAAAEEEEAAAQQQQAABBBYgQKS4ACxORQABBBBAAAEEEEAAAQQQQAABBBBAAAEiRT4DCCCAAAIIIIAAAggggAACCCCAAAIIILAAASLFBWBxKgIIIIAAAggggAACCCCAAAIIIIAAAggQKfIZQAABBBBAAAEEEEAAAQQQQAABBBBAAIEFCBApLgCLUxFAAAEEEEAAAQQQQAABBBBAAAEEEECASJHPAAIIIIAAAggggAACCCCAAAIIIIAAAggsQIBIcQFYnIoAAggggAACCCCAAAIIIIAAAggggAACRIp8BhBAAAEEEEAAAQQQQAABBBBAAAEEEEBgAQJEigvA4lQEEEAAAQQQQAABBBBAAAEEEEAAAQQQIFLkM4AAAggggAACCCCAAAIIIIAAAggggAACCxAgUlwAFqcigAACCCCAAAIIIIAAAggggAACCCCAAJEinwEEEEAAAQQQQAABBBBAAAEEEEAAAQQQWIAAkeICsDgVAQQQQAABBBBAAAEEEEAAAQQQQAABBIgU+QwggAACCCCAAAIIIIAAAggggAACCCCAwAIEiBQXgMWpCCCAAAIIIIAAAggggAACCCCAAAIIIECkyGcAAQQQQAABBBBAAAEEEEAAAQQQQAABBBYg8P8DAA3xveEZM1sAAAAASUVORK5CYII="
- }
- },
- "cell_type": "markdown",
- "id": "4c02199d-6ba1-49fa-9bd6-ef36e906c553",
- "metadata": {
- "tags": []
- },
- "source": [
- "### Self-RAG\n",
- "\n",
- "Self-RAG is a strategy for RAG that incorporates self-reflection / self-grading on retrieved documents and generations.\n",
- "\n",
- "In the [paper](https://arxiv.org/abs/2310.11511), a few decisions are made:\n",
- "\n",
- "1. Should I retrieve from retriever, `R` -\n",
- "\n",
- "* Input: `x (question)` OR `x (question)`, `y (generation)`\n",
- "* Decides when to retrieve `D` chunks with `R`\n",
- "* Output: `yes, no, continue`\n",
- "\n",
- "2. Are the retrieved passages `D` relevant to the question `x` -\n",
- "\n",
- "* * Input: (`x (question)`, `d (chunk)`) for `d` in `D`\n",
- "* `d` provides useful information to solve `x`\n",
- "* Output: `relevant, irrelevant`\n",
- "\n",
- "3. Are the LLM generation from each chunk in `D` is relevant to the chunk (hallucinations, etc) -\n",
- "\n",
- "* Input: `x (question)`, `d (chunk)`, `y (generation)` for `d` in `D`\n",
- "* All of the verification-worthy statements in `y (generation)` are supported by `d`\n",
- "* Output: `{fully supported, partially supported, no support`\n",
- "\n",
- "4. The LLM generation from each chunk in `D` is a useful response to `x (question)` -\n",
- "\n",
- "* Input: `x (question)`, `y (generation)` for `d` in `D`\n",
- "* `y (generation)` is a useful response to `x (question)`.\n",
- "* Output: `{5, 4, 3, 2, 1}`\n",
- "\n",
- "We will implement some of these ideas from scratch using [LangGraph](https://langchain-ai.github.io/langgraph/).\n",
- "\n",
- "> Figure and the explanation taken from the [LangGraph cookbook](https://github.com/langchain-ai/langgraph/blob/e3ca7bb3e9d34b09633852f4d08d55f6dcd4364b/examples/rag/langgraph_self_rag.ipynb)"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "4244331f-1cdc-4548-b577-f758d1cd2bf9",
- "metadata": {},
- "source": [
- "### Define the LangGraph Workflow\n",
- "\n",
- "\n",
- "The LangGraph agent operates as a multi-step workflow.\n",
- "\n",
- "- It retrieves documents, grades their relevance, generates an answer, and ensures factual accuracy (e.g., no hallucinations).\n",
- "- You can also implement self-reflection and query optimization using LangGraph nodes."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "8c4c9be8-396c-4ebc-a9e4-d4e11504c05c",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langchain_core.prompts import ChatPromptTemplate\n",
- "from langchain_core.pydantic_v1 import BaseModel, Field\n",
- "from langchain_openai import ChatOpenAI\n",
- "\n",
- "\n",
- "# Data model\n",
- "class GradeDocuments(BaseModel):\n",
- " \"\"\"Binary score for relevance check on retrieved documents.\"\"\"\n",
- "\n",
- " binary_score: str = Field(\n",
- " description=\"Documents are relevant to the question, 'yes' or 'no'\"\n",
- " )\n",
- "\n",
- "\n",
- "# LLM with function call\n",
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "structured_llm_grader = llm.with_structured_output(GradeDocuments)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You are a grader assessing relevance of a retrieved document to a user question. \\n \n",
- " It does not need to be a stringent test. The goal is to filter out erroneous retrievals. \\n\n",
- " If the document contains keyword(s) or semantic meaning related to the user question, grade it as relevant. \\n\n",
- " Give a binary score 'yes' or 'no' score to indicate whether the document is relevant to the question.\"\"\"\n",
- "grade_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\"human\", \"Retrieved document: \\n\\n {document} \\n\\n User question: {question}\"),\n",
- " ]\n",
- ")\n",
- "\n",
- "retrieval_grader = grade_prompt | structured_llm_grader\n",
- "\n",
- "\n",
- "question = \"self rag performance\"\n",
- "docs = retriever.get_relevant_documents(question)\n",
- "doc_txt = docs[1].page_content\n",
- "print(retrieval_grader.invoke({\"question\": question, \"document\": doc_txt}))"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "499173a5-8df0-4fe6-bb46-552ce496b8ba",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langchain import hub\n",
- "from langchain_core.output_parsers import StrOutputParser\n",
- "\n",
- "# Prompt\n",
- "prompt = hub.pull(\"rlm/rag-prompt\")\n",
- "\n",
- "# LLM\n",
- "llm = ChatOpenAI(model_name=\"gpt-3.5-turbo\", temperature=0)\n",
- "\n",
- "\n",
- "# Post-processing\n",
- "def format_docs(docs):\n",
- " return \"\\n\\n\".join(doc.page_content for doc in docs)\n",
- "\n",
- "\n",
- "# Chain\n",
- "rag_chain = prompt | llm | StrOutputParser()\n",
- "\n",
- "# Run\n",
- "generation = rag_chain.invoke({\"context\": docs, \"question\": question})\n",
- "print(generation)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "d9055d3b-8e9b-494f-bf4f-d02c153639c7",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "class GradeHallucinations(BaseModel):\n",
- " \"\"\"Binary score for hallucination present in generation answer.\"\"\"\n",
- "\n",
- " binary_score: str = Field(\n",
- " description=\"Answer is grounded in the facts, 'yes' or 'no'\"\n",
- " )\n",
- "\n",
- "\n",
- "# LLM with function call\n",
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "structured_llm_grader = llm.with_structured_output(GradeHallucinations)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You are a grader assessing whether an LLM generation is grounded in / supported by a set of retrieved facts. \\n \n",
- " Give a binary score 'yes' or 'no'. 'Yes' means that the answer is grounded in / supported by the set of facts.\"\"\"\n",
- "hallucination_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\"human\", \"Set of facts: \\n\\n {documents} \\n\\n LLM generation: {generation}\"),\n",
- " ]\n",
- ")\n",
- "\n",
- "hallucination_grader = hallucination_prompt | structured_llm_grader\n",
- "hallucination_grader.invoke({\"documents\": docs, \"generation\": generation})"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "f92d351d-5ee1-48cc-ad8f-9b57ceed18ed",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "class GradeAnswer(BaseModel):\n",
- " \"\"\"Binary score to assess answer addresses question.\"\"\"\n",
- "\n",
- " binary_score: str = Field(\n",
- " description=\"Answer addresses the question, 'yes' or 'no'\"\n",
- " )\n",
- "\n",
- "\n",
- "# LLM with function call\n",
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "structured_llm_grader = llm.with_structured_output(GradeAnswer)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You are a grader assessing whether an answer addresses / resolves a question \\n \n",
- " Give a binary score 'yes' or 'no'. Yes' means that the answer resolves the question.\"\"\"\n",
- "answer_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\"human\", \"User question: \\n\\n {question} \\n\\n LLM generation: {generation}\"),\n",
- " ]\n",
- ")\n",
- "\n",
- "answer_grader = answer_prompt | structured_llm_grader\n",
- "answer_grader.invoke({\"question\": question, \"generation\": generation})"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "286a9a2a-2a62-4004-84a2-fc82e6996cf1",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "llm = ChatOpenAI(model=\"gpt-4o-mini\", temperature=0)\n",
- "\n",
- "# Prompt\n",
- "system = \"\"\"You a question re-writer that converts an input question to a better version that is optimized \\n \n",
- " for vectorstore retrieval. Look at the input and try to reason about the underlying semantic intent / meaning.\"\"\"\n",
- "re_write_prompt = ChatPromptTemplate.from_messages(\n",
- " [\n",
- " (\"system\", system),\n",
- " (\n",
- " \"human\",\n",
- " \"Here is the initial question: \\n\\n {question} \\n Formulate an improved question.\",\n",
- " ),\n",
- " ]\n",
- ")\n",
- "\n",
- "question_rewriter = re_write_prompt | llm | StrOutputParser()\n",
- "question_rewriter.invoke({\"question\": question})"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "cb9bd597-a683-433a-879d-7991cfed5cf7",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from typing import List\n",
- "\n",
- "from typing_extensions import TypedDict\n",
- "\n",
- "\n",
- "class GraphState(TypedDict):\n",
- " \"\"\"\n",
- " Represents the state of our graph.\n",
- "\n",
- " Attributes:\n",
- " question: question\n",
- " generation: LLM generation\n",
- " documents: list of documents\n",
- " \"\"\"\n",
- "\n",
- " question: str\n",
- " generation: str\n",
- " documents: List[str]"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "398e5cc2-9c41-465d-a4f4-93c82ed452f2",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "def retrieve(state):\n",
- " \"\"\"\n",
- " Retrieve documents\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): New key added to state, documents, that contains retrieved documents\n",
- " \"\"\"\n",
- " print(\"---RETRIEVE---\")\n",
- " question = state[\"question\"]\n",
- "\n",
- " # Retrieval\n",
- " documents = retriever.get_relevant_documents(question)\n",
- " return {\"documents\": documents, \"question\": question}\n",
- "\n",
- "\n",
- "def generate(state):\n",
- " \"\"\"\n",
- " Generate answer\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): New key added to state, generation, that contains LLM generation\n",
- " \"\"\"\n",
- " print(\"---GENERATE---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- "\n",
- " # RAG generation\n",
- " generation = rag_chain.invoke({\"context\": documents, \"question\": question})\n",
- " return {\"documents\": documents, \"question\": question, \"generation\": generation}\n",
- "\n",
- "\n",
- "def grade_documents(state):\n",
- " \"\"\"\n",
- " Determines whether the retrieved documents are relevant to the question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): Updates documents key with only filtered relevant documents\n",
- " \"\"\"\n",
- "\n",
- " print(\"---CHECK DOCUMENT RELEVANCE TO QUESTION---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- "\n",
- " # Score each doc\n",
- " filtered_docs = []\n",
- " for d in documents:\n",
- " score = retrieval_grader.invoke(\n",
- " {\"question\": question, \"document\": d.page_content}\n",
- " )\n",
- " grade = score.binary_score\n",
- " if grade == \"yes\":\n",
- " print(\"---GRADE: DOCUMENT RELEVANT---\")\n",
- " filtered_docs.append(d)\n",
- " else:\n",
- " print(\"---GRADE: DOCUMENT NOT RELEVANT---\")\n",
- " continue\n",
- " return {\"documents\": filtered_docs, \"question\": question}\n",
- "\n",
- "\n",
- "def transform_query(state):\n",
- " \"\"\"\n",
- " Transform the query to produce a better question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " state (dict): Updates question key with a re-phrased question\n",
- " \"\"\"\n",
- "\n",
- " print(\"---TRANSFORM QUERY---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- "\n",
- " # Re-write question\n",
- " better_question = question_rewriter.invoke({\"question\": question})\n",
- " return {\"documents\": documents, \"question\": better_question}\n",
- "\n",
- "\n",
- "### Edges\n",
- "\n",
- "\n",
- "def decide_to_generate(state):\n",
- " \"\"\"\n",
- " Determines whether to generate an answer, or re-generate a question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " str: Binary decision for next node to call\n",
- " \"\"\"\n",
- "\n",
- " print(\"---ASSESS GRADED DOCUMENTS---\")\n",
- " state[\"question\"]\n",
- " filtered_documents = state[\"documents\"]\n",
- "\n",
- " if not filtered_documents:\n",
- " # All documents have been filtered check_relevance\n",
- " # We will re-generate a new query\n",
- " print(\n",
- " \"---DECISION: ALL DOCUMENTS ARE NOT RELEVANT TO QUESTION, TRANSFORM QUERY---\"\n",
- " )\n",
- " return \"transform_query\"\n",
- " else:\n",
- " # We have relevant documents, so generate answer\n",
- " print(\"---DECISION: GENERATE---\")\n",
- " return \"generate\"\n",
- "\n",
- "\n",
- "def grade_generation_v_documents_and_question(state):\n",
- " \"\"\"\n",
- " Determines whether the generation is grounded in the document and answers question.\n",
- "\n",
- " Args:\n",
- " state (dict): The current graph state\n",
- "\n",
- " Returns:\n",
- " str: Decision for next node to call\n",
- " \"\"\"\n",
- "\n",
- " print(\"---CHECK HALLUCINATIONS---\")\n",
- " question = state[\"question\"]\n",
- " documents = state[\"documents\"]\n",
- " generation = state[\"generation\"]\n",
- "\n",
- " score = hallucination_grader.invoke(\n",
- " {\"documents\": documents, \"generation\": generation}\n",
- " )\n",
- " grade = score.binary_score\n",
- "\n",
- " # Check hallucination\n",
- " if grade == \"yes\":\n",
- " print(\"---DECISION: GENERATION IS GROUNDED IN DOCUMENTS---\")\n",
- " # Check question-answering\n",
- " print(\"---GRADE GENERATION vs QUESTION---\")\n",
- " score = answer_grader.invoke({\"question\": question, \"generation\": generation})\n",
- " grade = score.binary_score\n",
- " if grade == \"yes\":\n",
- " print(\"---DECISION: GENERATION ADDRESSES QUESTION---\")\n",
- " return \"useful\"\n",
- " else:\n",
- " print(\"---DECISION: GENERATION DOES NOT ADDRESS QUESTION---\")\n",
- " return \"not useful\"\n",
- " else:\n",
- " pprint(\"---DECISION: GENERATION IS NOT GROUNDED IN DOCUMENTS, RE-TRY---\")\n",
- " return \"not supported\""
- ]
- },
- {
- "cell_type": "markdown",
- "id": "b77061d5-fa7f-4dbc-ad5b-cc409b931bf4",
- "metadata": {},
- "source": [
- "### Compose the graph"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "f5ae35f7-ff5c-40f1-9b0e-1a8bac0dc58f",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "from langgraph.graph import END, StateGraph, START\n",
- "\n",
- "workflow = StateGraph(GraphState)\n",
- "\n",
- "# Define the nodes\n",
- "workflow.add_node(\"retrieve\", retrieve) # retrieve\n",
- "workflow.add_node(\"grade_documents\", grade_documents) # grade documents\n",
- "workflow.add_node(\"generate\", generate) # generatae\n",
- "workflow.add_node(\"transform_query\", transform_query) # transform_query\n",
- "\n",
- "# Build graph\n",
- "workflow.add_edge(START, \"retrieve\")\n",
- "workflow.add_edge(\"retrieve\", \"grade_documents\")\n",
- "workflow.add_conditional_edges(\n",
- " \"grade_documents\",\n",
- " decide_to_generate,\n",
- " {\n",
- " \"transform_query\": \"transform_query\",\n",
- " \"generate\": \"generate\",\n",
- " },\n",
- ")\n",
- "workflow.add_edge(\"transform_query\", \"retrieve\")\n",
- "workflow.add_conditional_edges(\n",
- " \"generate\",\n",
- " grade_generation_v_documents_and_question,\n",
- " {\n",
- " \"not supported\": \"generate\",\n",
- " \"useful\": END,\n",
- " \"not useful\": \"transform_query\",\n",
- " },\n",
- ")\n",
- "\n",
- "# Compile\n",
- "app = workflow.compile()"
- ]
- },
- {
- "cell_type": "markdown",
- "id": "074bd11c-0252-46cc-8903-5fa29c327e96",
- "metadata": {},
- "source": [
- "# Run with a sample question\n",
- "\n",
- "Test the `/agent` endpoint by sending a sample question. The server runs the entire RAG pipeline and returns the answer."
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "4676f4c8-26bd-4f36-aadf-80771b001b59",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "inputs = {\n",
- " \"question\": \"How does self-RAG work? Explain the steps involved in the implementation.\"\n",
- "}"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "b84144d8-e266-4a13-a515-a55fcdc02f11",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "result = app.invoke(inputs)"
- ]
- },
- {
- "cell_type": "code",
- "execution_count": null,
- "id": "a5689309-1780-4725-8d3f-364841303def",
- "metadata": {
- "tags": []
- },
- "outputs": [],
- "source": [
- "result[\"generation\"]"
- ]
- }
- ],
- "metadata": {
- "kernelspec": {
- "display_name": "Python 3 (ipykernel)",
- "language": "python",
- "name": "python3"
- },
- "language_info": {
- "codemirror_mode": {
- "name": "ipython",
- "version": 3
- },
- "file_extension": ".py",
- "mimetype": "text/x-python",
- "name": "python",
- "nbconvert_exporter": "python",
- "pygments_lexer": "ipython3",
- "version": "3.11.11"
- }
- },
- "nbformat": 4,
- "nbformat_minor": 5
-}
diff --git a/docs/README.md b/docs/README.md
new file mode 100644
index 00000000..f0d1d74e
--- /dev/null
+++ b/docs/README.md
@@ -0,0 +1,635 @@
+# serviette
+
+**A universal, no-code, always up-to-date RAG server for any vector database
+— powered by the [Pathway](https://pathway.com) Live Data Framework.**
+
+serviette stands up Retrieval-Augmented Generation over your own documents —
+text, Office files, PDFs, scans, and (with API keys) audio and video —
+without writing code. Point it at a folder, choose a vector database and an
+embedder in a YAML file (or generate one with the wizard), and run one
+command (`serviette up`) or the two components separately:
+
+- **`serviette indexer`** — a Pathway streaming pipeline that watches your files,
+ parses and chunks them, embeds the chunks and keeps your vector DB in sync
+ (additions, modifications and deletions) in real time.
+- **`serviette server`** — a FastAPI service that embeds incoming queries and
+ retrieves the most relevant chunks (and, optionally, answers them with an
+ LLM). It also serves the web chat UI on `/` (same port, same origin) unless
+ `server.serve_frontend` is disabled; the REST API lives under `/api/v1`.
+
+The indexer and the server are fully decoupled: they share only the vector
+database, so you can scale them independently.
+
+---
+
+## 1. Installation
+
+serviette requires **Python ≥ 3.10** (the minimum supported by Pathway).
+
+```bash
+pip install "serviette[local]" --extra-index-url https://download.pytorch.org/whl/cpu
+```
+
+The `local` extra brings sentence-transformers — the free, credential-free
+embedder that `serviette wizard` selects by default. It pulls the PyTorch
+stack, and the `--extra-index-url` flag makes pip take PyTorch's CPU build
+(~0.8 GB). Without it, PyTorch's default Linux wheel is installed, which
+carries the CUDA libraries (~5 GB) whether or not the machine has an NVIDIA
+GPU — leave the flag out only if you want to embed on such a GPU. (With
+`uv`, add `--index-strategy unsafe-best-match` as well.) If you intend to
+embed with OpenAI instead, a plain `pip install serviette` is enough (pick
+`openai` in the wizard).
+From a checkout, `pip install -e ".[dev,local]"` — see the README's
+[Development](../README.md#development) section for the full walkthrough.
+OpenAI support (the default `/rag` LLM and the OpenAI embedder) is built
+in — just set `OPENAI_API_KEY`.
+
+Optional extras: `docling` (layout-aware PDF + Office parsing), `ocr` (scanned images),
+`pyfilesystem` (FTP/SFTP/WebDAV/ZIP sources), `gdrive`, `sharepoint`, plus
+one extra per vector-DB client (`qdrant`, `pgvector`, …, or `all`).
+
+---
+
+## 2. Config wizard
+
+The fastest way to a chat is `serviette demo` (see the README); the fastest
+way to a config for *your* documents is the interactive wizard:
+
+```bash
+serviette wizard
+```
+
+It asks only what it must (the DuckDB + local-embeddings happy path is seven
+questions) and writes a YAML file; everything else — port, persistence,
+chunking, parser routing — gets silent, documented defaults you can edit
+later. You only *have* to provide document paths, vector-DB connection
+details (for client-server backends), API keys for keyed providers, and your
+Pathway license key.
+
+Then run the two components (in separate terminals or on separate machines):
+
+```bash
+# One command: indexer + server supervised together (dev/demo convenience)
+serviette up --config config.yaml # open http://localhost:8989
+
+# ... or run the components separately (how production deploys them):
+# 1. Index your documents into the vector DB and keep it live
+serviette indexer --config config.yaml
+
+# 2. Serve the chat UI + retrieval / RAG API on one port
+serviette server --config config.yaml # open http://localhost:8989
+
+# (optional, split deployments only) standalone UI tier on another host
+serviette frontend --config config.yaml # open http://localhost:3000
+```
+
+`indexer`, `server` and `up` check the obvious mistakes before starting
+anything: a source folder that does not exist, a `${VAR}` in the config that
+is not exported, an `openai`-typed embedder or `llm` with no key in the config
+or in `OPENAI_API_KEY`, a backend that cannot be shared by two processes. Each
+stops with a one-paragraph message, not a traceback. If the indexer or the
+server dies later, `serviette up` ends with a framed `serviette up STOPPED`
+block that names the cause when it recognises it (missing or rejected API
+key, OpenAI rate limit or quota, a port already in use, an unreachable
+database) and what to do.
+
+By default `serviette up` shows only its own progress, warnings, errors and
+the URL to open; the indexer's and the server's routine INFO lines (the
+engine's persistence and connector monitoring, one line per HTTP request)
+are hidden. `serviette up --verbose` passes them all through. The hidden
+lines are still kept for the `STOPPED` report, so a diagnosis never depends
+on the flag.
+
+Query the API (versioned under `/api/v1`; the pre-versioning `/retrieve`,
+`/rag` and `/health` paths still work as deprecated aliases):
+
+```bash
+curl -X POST http://localhost:8989/api/v1/retrieve \
+ -H 'Content-Type: application/json' \
+ -d '{"query": "how does persistence work?", "k": 5}'
+```
+
+```jsonc
+{
+ "results": [
+ {"text": "...", "metadata": {"path": "/data/docs/guide.pdf", ...}, "score": 0.95}
+ ]
+}
+```
+
+If you configured an `llm` section, the `/rag` endpoint also answers questions:
+
+```bash
+curl -X POST http://localhost:8989/api/v1/rag \
+ -H 'Content-Type: application/json' \
+ -d '{"query": "summarize the onboarding guide", "k": 5}'
+```
+
+```jsonc
+{ "answer": "...", "sources": [ {"text": "...", "metadata": {...}, "score": 0.91} ] }
+```
+
+`GET /api/v1/documents` lists the indexed documents whose name or path
+contains `q` (`case_sensitive=true` to match case; the default ignores it).
+The chat page's **Documents** panel is built on it and asks only when a
+search is submitted, never on load — an index may hold tens of thousands of
+files. Over `limit` matches (default 100, at most 1000) only the counts are
+returned and the page asks to narrow the search:
+
+```bash
+curl 'http://localhost:8989/api/v1/documents?q=report&case_sensitive=false'
+```
+
+```jsonc
+{ "total": 1240, "matched": 2, "truncated": false,
+ "documents": [ {"id": "/data/docs/report_2026.pdf", "name": "report_2026.pdf",
+ "metadata": {"path": "...", "modified_at": 1790000000, "size": 12345}, "chunks": 41}, ... ] }
+```
+
+`name` is what a person calls the document — the file name for folder, S3
+and SharePoint sources, the Drive title for Google Drive — and `id` is the
+full identity the source reports (path or Drive id). Pinecone cannot
+enumerate documents; there the endpoint answers 501.
+
+---
+
+## 3. Pathway License Key
+
+Pathway requires a **free** license key. Get yours in one click at
+**** (email or LinkedIn sign-in).
+
+Provide it either via the config file:
+
+```yaml
+pathway_license_key: ${PATHWAY_LICENSE_KEY}
+```
+
+or directly as a string. Using the `${PATHWAY_LICENSE_KEY}` form keeps the key
+out of the file — set it in the environment:
+
+```bash
+export PATHWAY_LICENSE_KEY="your-key-here"
+```
+
+`serviette wizard` notices an exported `PATHWAY_LICENSE_KEY` and offers to
+write the `${PATHWAY_LICENSE_KEY}` reference instead of asking for the key;
+`serviette demo` uses the variable the same way.
+
+The key is applied when the indexing graph is initialized.
+
+---
+
+## 4. Config reference
+
+A single YAML file can configure both the indexer and the server (a *universal*
+config), or you can split it into an indexer-only and a server-only file. Any
+string value supports `${ENV_VAR}` interpolation, so credentials never need to be
+hardcoded. A reference to a variable that is not set is a startup error naming
+the variable and the config key using it (it does not silently become an empty
+string, which would only surface later as a provider 401).
+
+| Field | Type | Default | Used by | Description |
+|---|---|---|---|---|
+| `pathway_license_key` | str | — | indexer | Free Pathway license key (or `${ENV}`). |
+| `sources` | list | — (required) | indexer | One or more sources to index (mixed types allowed). |
+| `sources[].type` | `fs`\|`gdrive`\|`s3`\|`sharepoint`\|`pyfilesystem` | `fs` | indexer | Source type — see [Sources](#sources) below. |
+| `sources[].mode` | `streaming`\|`static` | `streaming` | indexer | `streaming` watches continuously; `static` indexes once and exits. |
+| `sources[].max_backlog_size` | int\|null | `1000` | indexer | **Advanced.** Backpressure bound on in-flight entries per connector (fs/gdrive/s3). Keeps memory flat during bulk backfills; the default suits virtually everyone — not offered by the wizard, edit the YAML to change. `null` disables. |
+| **fs** `sources[].path` | str | — (required) | indexer | Directory to watch (`~` is expanded). Must exist when the indexer starts — a missing folder is an error, not an empty index. |
+| **fs** `sources[].glob` | str | `**/*` | indexer | Glob of files to include. |
+| **gdrive** `sources[].object_id` | str | — (required) | indexer | Drive folder or file id (folders scanned recursively). |
+| **gdrive** `sources[].service_user_credentials_file` | str | — (required) | indexer | Path to a Google service-account JSON credentials file. |
+| **gdrive** `sources[].file_name_pattern` | str\|list | — | indexer | Optional file-name glob(s), e.g. `*.pdf`. |
+| **gdrive** `sources[].object_size_limit` | int | — | indexer | Optional max object size in bytes. |
+| **s3** `sources[].bucket` | str | — (required) | indexer | S3 bucket name. |
+| **s3** `sources[].path` | str | `""` | indexer | Key prefix to index (`""` = whole bucket). |
+| **s3** `sources[].access_key` / `.secret_access_key` | str | AWS chain | indexer | Credentials (or `${ENV}`). |
+| **s3** `sources[].region` / `.endpoint` | str | — | indexer | Region; custom endpoint for MinIO etc. |
+| **s3** `sources[].with_path_style` | bool | `false` | indexer | Path-style addressing (MinIO and most self-hosted). |
+| **sharepoint** `sources[].url` | str | — (required) | indexer | Site URL, e.g. `https://co.sharepoint.com/sites/X`. |
+| **sharepoint** `sources[].tenant` / `.client_id` | str | — (required) | indexer | App registration (certificate auth). |
+| **sharepoint** `sources[].cert_path` / `.thumbprint` | str | — (required) | indexer | Certificate .pem and its thumbprint. |
+| **sharepoint** `sources[].root_path` | str | — (required) | indexer | Directory/file to index. |
+| **sharepoint** `sources[].recursive` | bool | `true` | indexer | Scan nested directories. |
+| **sharepoint** `sources[].refresh_interval` | int | `30` | indexer | Polling period, seconds. |
+| **pyfilesystem** `sources[].fs_url` | str | — (required) | indexer | Any PyFilesystem URL: `ftp://…`, `ssh://…`, `webdav://…`, `zip://…`, `osfs://…` (extra: `serviette[pyfilesystem]`; some protocols need a driver package). |
+| **pyfilesystem** `sources[].path` | str | `""` | indexer | Path inside the opened filesystem (recursive). |
+| **pyfilesystem** `sources[].refresh_interval` | float | `30.0` | indexer | Seconds between scans (streaming mode). |
+| `parser` | list of rules | keyless-first defaults | indexer | Routing rules `{match: ["*.pdf"], type: docling, options: {...}}` — globs are tried against the file name and its path as the source reports it (`*` matches `/`, so `*/scans/*.png` selects a folder), first match wins; unmatched files use built-in defaults (text→utf8, pdf→docling/pypdf, office→unstructured, images→paddle_ocr, audio→whisper if `OPENAI_API_KEY`, video→twelvelabs_video if `TWELVELABS_API_KEY`, else skip+warn). Types: `utf8`, `pypdf`, `docling`, `unstructured`, `paddle_ocr`, `vision_image`, `vision_slide`, `whisper`, `twelvelabs_video`, `skip`. Changing routing is fingerprint-guarded. |
+| `vector_db.type` | `duckdb`\|`pgvector`\|`milvus`\|`qdrant`\|`chroma`\|`weaviate`\|`pinecone`\|`mongodb` | — (required) | both | Vector database backend (see [Backends](#vector-database-backends)). |
+| **duckdb** `vector_db.path` | str | — (required) | both | Path to the DuckDB database file. |
+| **duckdb** `vector_db.table` | str | `serviette_embeddings` | both | Target table. |
+| **pgvector** `vector_db.connection_string` | str | — (required) | both | `postgresql://user:pass@host/db`. |
+| **pgvector** `vector_db.table` | str | `serviette_embeddings` | both | Target table. |
+| **milvus** `vector_db.uri` | str | — | both | Milvus URI, e.g. `http://localhost:19530`. |
+| **milvus** `vector_db.host` / `.port` | str / int | `localhost` / `19530` | both | Used if `uri` is omitted. |
+| **milvus** `vector_db.collection` | str | `serviette_embeddings` | both | Milvus collection. |
+| **qdrant** `vector_db.host` | str | `localhost` | both | Qdrant host. |
+| **qdrant** `vector_db.rest_port` / `.grpc_port` | int | `6333` / `6334` | server / indexer | REST (server) and gRPC (indexer) ports. |
+| **qdrant** `vector_db.api_key` | str | — | both | Qdrant Cloud API key. |
+| **qdrant** `vector_db.collection` | str | `serviette_embeddings` | both | Auto-created (cosine) if missing. |
+| **chroma** `vector_db.host` / `.port` | str / int | `localhost` / `8000` | both | Chroma server address. |
+| **chroma** `vector_db.tenant` / `.database` | str | Chroma defaults | both | Multi-tenant selectors. |
+| **chroma** `vector_db.collection` | str | `serviette_embeddings` | both | Auto-created (cosine `hnsw:space`). |
+| **weaviate** `vector_db.http_host` / `.http_port` | str / int | `localhost` / `8080` | both | HTTP endpoint. |
+| **weaviate** `vector_db.grpc_host` / `.grpc_port` | str / int | http_host / `50051` | server | gRPC endpoint (v4 client). |
+| **weaviate** `vector_db.api_key` | str | — | both | API key. |
+| **weaviate** `vector_db.collection` | str | `ServietteEmbeddings` | both | Auto-created (capitalized name). |
+| **pinecone** `vector_db.index_name` | str | — (required) | both | Auto-created (serverless, embedder's dimension, cosine). |
+| **pinecone** `vector_db.api_key` | str | `${PINECONE_API_KEY}` | both | Pinecone API key. |
+| **pinecone** `vector_db.namespace` | str | `""` | both | Optional namespace. |
+| **mongodb** `vector_db.connection_string` | str | — (required) | both | `mongodb+srv://...` for Atlas. |
+| **mongodb** `vector_db.database` / `.collection` | str | — / `serviette_embeddings` | both | Target collection (auto-created). |
+| **mongodb** `vector_db.vector_index` | str | `vector_index` | server | Atlas `vectorSearch` index name. |
+| `embedder.type` | str | `openai` | both | Embedder family (see below). |
+| `embedder.model` | str | provider default | both | Model name. |
+| `embedder.api_key` | str | — | both | API key (or `${ENV}`). |
+| `splitter.type` | `token_count`\|`recursive`\|`null` | `token_count` | indexer | Chunking strategy. `null` disables splitting — the whole document is one chunk (short, self-contained documents such as FAQ entries or product cards); written as `type: null` or `type: "null"`, both work. |
+| `splitter.chunk_size` | int | `512` | indexer | Max chunk size (tokens). |
+| `splitter.chunk_overlap` | int | `50` | indexer | Overlap (used by `recursive`). |
+| `indexer.fetch_retries` | int | `3` | indexer | Retries (exponential backoff from 1s) of a document's byte fetch before it is given up on: indexed as empty and ERROR-logged. Remote sources fail transiently under bulk backfills. |
+| `indexer.workers` | int | `1` | indexer | Worker **processes** (sharded via `pathway spawn`). Raise for large backfills — each worker carries its own embedding stack (~1 GB with local embeddings); the benchmarks run with `8`. |
+| `workdir_path` | str | `./serviette-workdir` | indexer | serviette's working directory — everything it keeps between runs: the configuration fingerprint at its top level, the Pathway persistence state (and the parse cache, `runtime_calls/`) under `persistence/`. Relative to the process's working directory. Silent default — the wizard does not ask. |
+| `persistence.enabled` | bool | `true` | indexer | See [Persistence](#5-persistence). |
+| `persistence.backend` | `filesystem` | `filesystem` | indexer | Persistence backend. |
+| `server.host` / `server.port` | str / int | `127.0.0.1` / `8989` | server | Bind address. Loopback by default; set `0.0.0.0` explicitly to listen on all interfaces (containers, remote access) — see [Security](#security--exposing-the-server). |
+| `server.serve_frontend` | bool | `true` | server | Serve the chat UI on `/` from the same port (API stays under `/api/v1`). |
+| `server.cors_origins` | list[str] | `[]` (disabled) | server | Opt-in CORS allowlist for third-party browser frontends calling the API directly from another origin. serviette's own UIs never need it. Prefer exact origins over `*`. |
+| `up.index_wait_timeout` | float\|null | `120` | up | Seconds of indexer *inactivity* after which `serviette up` stops holding the server back waiting for the first indexed chunks. Counted from the indexer's last sign of work in its log (a document being parsed, input reaching the engine, embedding progress), so a few large PDFs that take minutes to parse do not trip it. A folder whose documents all yield no text (scans without the `ocr` extra, audio without its API key, parser failures) never produces a chunk and goes quiet right after parsing, so after this long the server starts over the empty index with a warning; `null` waits forever. |
+| `llm.type` | str | `openai` | server | LLM for `/rag` (omit to disable `/rag`). |
+| `llm.model` | str | `gpt-4o-mini` | server | Chat model. |
+| `llm.api_key` | str | — | server | API key (or `${ENV}`). |
+| `llm.system_prompt` | str | built-in grounded prompt | server | Answering policy for `/rag`. The default tells the model to answer only from the provided context; override to let it blend in its own knowledge (e.g. public-domain corpora). Kept under `rag.adaptive`, which appends its no-answer instruction to it. |
+| `rag.adaptive` | `{factor, max_iterations, no_answer_string}` | — (off) | server | Adaptive RAG: answer from `k` chunks, then grow the context by `factor` and re-ask (up to `max_iterations` rounds) while the reply contains `no_answer_string` (default `No information found`). The system prompt is the `llm.system_prompt` policy plus an appended instruction to reply with that marker when the context is insufficient; a policy that allows answers from the model's own knowledge rarely triggers the marker, so the context then rarely grows. |
+| `rag.documents` | `{enabled, corpus_card, source_labels, max_context_chars, max_request_chars, max_listed_documents}` | on | server | Document-level questions on `/rag` (counts and listings, a named file as a whole, comparing files). A question that names a file with its extension is answered from that file without a search. Otherwise the ordinary attempt runs first; when its reply contains the no-answer marker, one short routing call (the question and up to `max_listed_documents` file names, never the retrieved context) chooses between continuing the search (`rag.adaptive`, if configured) and answering from the catalog or from the named documents — at most once per request, and one-way. `max_context_chars` (default `24000`) caps what any such answer reads: a document that does not fit is cut to its parts closest to the question, and a comparison shows only the differences — found line by line (ignoring spacing, hyphenation, punctuation and running page headers), so it does not depend on how the files were chunked; when there are more than fit, the ones closest to the question are shown and `notice` says how many of how many. `max_request_chars` (default `100000`) caps everything one request sends to the LLM across all its calls, the adaptive loop included: a call that no longer fits is cut down or not made, and `notice` says so. While enabled, the system prompt carries the no-answer instruction and, with `corpus_card`, one line stating the number of indexed documents; with `source_labels`, every context chunk is prefixed with its file name (`[file: pricing.md]`), which lets the model tell apart documents that disagree. Set `enabled: false` to keep the prompt and context untouched. The response gains `mode` (`search`, `catalog`, `document`, `compare`, `unresolved`), `documents` and `notice`. Counts cover indexed documents only — files that produced no text are not in the store. Ignored on Pinecone. |
+| `frontend.host` / `frontend.port` | str / int | `127.0.0.1` / `3000` | frontend (standalone) | Bind address for the split-deployment chat UI. |
+| `frontend.api_url` | str | `http://localhost:8989` | frontend (standalone) | Base URL of the API the standalone frontend proxies to — point it at the backend host in split deployments (frontend fleet / backend fleet). The browser sends requests to the frontend's same-origin proxy; the upstream address is shown in the UI for information. |
+| `frontend.title` | str | `serviette` | both | Title shown in the chat UI (embedded and standalone). |
+
+**Supported embedders** (from `pathway.xpacks.llm.embedders`): `openai`,
+`litellm` (≈100 providers), `sentence_transformer` (fully local, no
+credentials — install `serviette[local]`), `gemini` (`serviette[gemini]`),
+`bedrock` (`serviette[bedrock]` for the server side). Every family has a
+matching async client on the server side, so one `embedder` section serves both
+components; make sure the indexer and server use the **same** model so vectors
+are comparable.
+
+**Which local model.** The `sentence_transformer` default,
+`sentence-transformers/all-MiniLM-L6-v2`, is an **English-only** model: with
+French, German or Polish documents retrieval degrades to "the context does not
+contain the information" even though the files were indexed. For non-English
+or mixed corpora set `model: intfloat/multilingual-e5-small` (~100 languages,
+same size and speed) together with the prefixes it was trained with,
+`query_prefix: "query: "` and `document_prefix: "passage: "`; for the highest
+quality and long chunks, `BAAI/bge-m3` (1024-dim, ~2.3 GB, several times slower
+on CPU). `serviette wizard` asks this as its "Embedding model" step and writes
+the prefixes for you. Changing the model means re-indexing (the fingerprint
+check will say so).
+
+### Sources
+
+serviette only supports sources that offer Pathway's **`only_metadata`** read mode —
+the graph holds just paths/identifiers and metadata (never the file bytes), and
+the bytes are fetched on demand during parsing. That keeps the memory footprint
+tiny (1 GB of PDFs stays a few KB in the pipeline). Today that means:
+
+- **`fs`** — a local directory, watched recursively per `glob`.
+- **`gdrive`** — a Google Drive folder or file. Create a Google **service
+ account**, download its JSON key, share the target folder with the service
+ account's email, and point `service_user_credentials_file` at the key. See the
+ [Pathway Google Drive connector guide](https://pathway.com/developers/user-guide/connect/connectors/gdrive-connector/).
+ Install the extra: `pip install "serviette[gdrive]"`.
+- **`s3`** — an S3 bucket or key prefix, including S3-compatible stores
+ (MinIO, DigitalOcean, Wasabi) via `endpoint` + `with_path_style: true`.
+ Credentials fall back to the standard AWS chain when omitted. Install the
+ extra: `pip install "serviette[s3]"`.
+- **`sharepoint`** — a SharePoint directory or file, authenticated with an
+ app-registration certificate (`tenant`, `client_id`, `cert_path`,
+ `thumbprint`). Requires a Pathway **Scale** license and
+ `pip install "serviette[sharepoint]"`.
+
+- **`pyfilesystem`** — anything the
+ [PyFilesystem2](https://docs.pyfilesystem.org) library opens: FTP, SFTP,
+ WebDAV, even ZIP/TAR archives — selected by `fs_url` (e.g.
+ `ftp://user:pass@host/dir`, `zip://./docs.zip`). Install
+ `pip install "serviette[pyfilesystem]"`; some protocols need their own driver
+ package (`fs.sshfs`, `fs.webdavfs`).
+
+You can list several sources of mixed types in one config.
+
+### Vector database backends
+
+Every backend is written through Pathway's **native `pw.io.*` output
+connector** in snapshot/upsert mode keyed by the chunk id, so file additions,
+edits and deletions become real inserts/updates/deletes in the store. The
+server retrieves through each database's own vector-search API — there are no
+linear scans in Python anywhere.
+
+**Targets are created for you.** At startup the indexer runs
+`prepare_backend`: it creates the missing table / collection / index for
+every backend (pgvector table + HNSW index, Milvus collection, Chroma and
+Weaviate collections, the Pinecone serverless index, the MongoDB Atlas
+`vectorSearch` index), sizing the vector dimension from
+`vector_db.embedding_dimension` when set, or by introspecting the configured
+embedder otherwise. The schemas below are shown for reference — e.g. when a
+DBA manages the database — not as required manual steps.
+
+#### DuckDB (embedded — the zero-setup default)
+
+```yaml
+vector_db:
+ type: duckdb
+ path: ./embeddings.duckdb
+ table: serviette_embeddings
+```
+
+No external service and no setup: the file and table are created automatically
+(`pw.io.duckdb`, snapshot mode). Embeddings are stored as native `DOUBLE[]`
+columns and queried **inside DuckDB** with `list_cosine_similarity` — a
+vectorized, columnar scan that answers in milliseconds for local corpora.
+
+Concurrency: DuckDB allows one read-write process *or* several read-only
+processes per file — never both. serviette resolves this with Pathway's
+`detach_between_batches`: the streaming indexer releases the file lock
+between minibatches, and the server's short-lived read-only connections query
+it concurrently — live indexing and serving work on one file. A request that
+arrives while a batch is being committed waits for the lock (up to 30 s; the
+first commit of a large corpus can hold it for ~10 s), and only past that
+answers `503` with "the index is being updated — try again in a few seconds"
+(the chat shows the same text). On older Pathway builds without the flag, serviette
+warns and falls back to the hold-the-lock behavior (use `mode: static`
+there).
+
+#### pgvector
+
+Auto-created (extension, table, HNSW index). Reference schema, e.g. for
+`text-embedding-3-small` (1536 dims):
+
+```sql
+CREATE EXTENSION IF NOT EXISTS vector;
+CREATE TABLE serviette_embeddings (
+ chunk_id text PRIMARY KEY,
+ text text,
+ metadata jsonb,
+ embedding vector(1536)
+);
+```
+
+(The indexer writes the chunk primary key to the `chunk_id` column.)
+
+#### Milvus
+
+Auto-created: a collection with a VARCHAR primary key, `text` (VARCHAR),
+`metadata` (JSON) and an `embedding` (FLOAT_VECTOR) field of the embedder's
+dimension, AUTOINDEX with the `COSINE` metric.
+
+**Milvus Lite** (`uri: ./milvus.db`, a local file) is an embedded,
+single-process database: the process that opens the file locks it. It works
+for the one-process-at-a-time flow — `serviette indexer` with `mode: static`
+sources, then `serviette server` — but not with `serviette up`, which runs
+the indexer and the server as two processes against one store; `up` refuses
+such a config up front. For `up`, a live chat over a changing folder, or
+scaling the server, use a Milvus server (`uri: http://host:19530`, e.g. the
+`milvus run standalone` docker image).
+
+#### Qdrant
+
+Nothing to create: the indexer (`pw.io.qdrant`, gRPC) auto-creates the
+collection with the cosine metric on first write. The chunk's `text` and
+`metadata` travel in the point payload; the server queries over REST.
+Set `api_key` for Qdrant Cloud.
+
+#### ChromaDB
+
+Auto-created with the cosine distance (`hnsw:space`). The chunk text is
+stored as the Chroma document and the source metadata as a JSON string
+(Chroma metadata values must be scalars).
+
+#### Weaviate
+
+Auto-created (capitalized name, e.g. `ServietteEmbeddings`; vectorizer `none`).
+The chunk vector is stored as the object vector; `text` / `metadata` (JSON
+string) / `chunk_id` become properties. The server's v4 client needs both the
+HTTP and gRPC ports.
+
+#### Pinecone
+
+Auto-created: a serverless index (`vector_db.cloud` / `.region`) with the
+embedder's dimension and the cosine metric. The `text` and JSON-string
+`metadata` are stored as record metadata. The API key comes from `api_key`
+or `$PINECONE_API_KEY`.
+
+#### MongoDB Atlas Vector Search
+
+The indexer writes one document per chunk (`pw.io.mongodb`, snapshot mode).
+The collection and the Atlas `vectorSearch` index (default name
+`vector_index`, cosine, `numDimensions` from the embedder) are auto-created;
+on Atlas Local the indexer rides out the search service's slow boot with
+retries. The server retrieves with `$vectorSearch`.
+
+---
+
+## 5. Persistence
+
+When `persistence.enabled: true`, the indexer uses Pathway's built-in
+persistence backend plus a `DefaultCache` UDF call-cache on the embedder. On
+restart, Pathway replays its persisted state and re-emits only the *diffs* since
+the last run, so:
+
+- **unchanged documents are not re-embedded** (the embedder cache and operator
+ state are restored), and
+- **documents removed while the indexer was down are correctly retracted** from
+ the vector DB on the next run.
+
+The engine's state lives under `/persistence/` (the top level of
+the working directory is reserved for serviette's own files, such as the
+configuration fingerprint — the engine logs an ERROR for every foreign entry
+in the directory it is given, so the two never share a folder); the same
+`persistence/` also hosts the **parse cache** (`runtime_calls/`, via
+`pw.udfs.DefaultCache` — diskcache, LRU-bounded by
+`indexer.parse_cache_size_gb`, default 8): extracted document text stays warm
+across restarts, so unchanged documents are neither re-downloaded nor
+re-parsed. Disabling persistence also disables the parse cache.
+
+The **configuration fingerprint** (`/serviette-fingerprint.json`)
+records the chunking-relevant settings the working directory was indexed with
+(splitter, parser routing, embedder identity, library versions, chunk-id
+scheme). A change is reported as a diff on startup and the indexer refuses to
+run unless confirmed (interactively, or with
+`SERVIETTE_ACCEPT_FINGERPRINT_CHANGES=1`), because rows already in the vector
+DB keep their old chunk ids and would be left behind as orphans. The check
+runs with persistence on or off: a restart without persistence re-indexes
+everything, but does not remove those rows either.
+
+A document whose bytes cannot be fetched (after `indexer.fetch_retries`
+retries) or parsed does not stop the indexer: it is indexed as **empty** and
+logged at ERROR level with its path. That result sticks for this version of
+the object — a restart alone does not retry it — so fix the cause and then
+touch the file (or re-upload the object) to have the source re-emit it.
+
+Disabling persistence still produces identical vectors for a given set of files;
+it only forgoes the cross-restart diffing and caching.
+
+---
+
+## 6. Parsing & modalities
+
+serviette never implements its own parsers — each file is routed by extension to
+a `pathway.xpacks.llm.parsers` parser. Every format is enabled by default,
+preferring parsers that need **no API key**, and modalities whose only parser
+requires an absent key are skipped with a single clear warning (never a
+crash):
+
+- text / Markdown → as-is;
+- `.pdf` → `DoclingParser` (layout-aware, tables — `serviette[docling]`), falling
+ back to `PypdfParser`;
+- Office & co. (DOCX, PPTX, XLSX, HTML, EML, CSV, RTF, EPUB, …) →
+ `UnstructuredParser`;
+- scanned images (PNG, JPG, TIFF, …) → `PaddleOCRParser` (`serviette[ocr]`);
+- audio (MP3, WAV, …) → Whisper, enabled when `OPENAI_API_KEY` is set;
+- video (MP4, WebM, MOV, …) → TwelveLabs Pegasus (a searchable text
+ description), enabled when `TWELVELABS_API_KEY` is set.
+
+The routing is overridable per file pattern via the `parser:` config section
+(first matching rule wins; unmatched files use the defaults above) — e.g.
+route images to a vision model instead of OCR, or set a custom video prompt.
+Routing changes are fingerprint-guarded like splitter changes. Expensive
+parses (video) are cached on disk, so restarts cost nothing.
+
+Still not supported: encrypted / password-protected PDFs; Google-native files
+(Docs/Sheets/Slides) from a `gdrive` source — they have no binary download
+and would need an export step (TODO); any format the installed `unstructured`
+version cannot handle. Unsupported files are skipped and produce no chunks.
+
+---
+
+## 7. Architecture
+
+
+
+
+
+Inside the indexer, documents move through a Pathway dataflow — every stage
+below is an incremental operator, so a change to one file re-runs only that
+file's slice of the graph:
+
+
+
+
+
+**Why `only_metadata`?** The filesystem connector only ever puts *paths and
+metadata* into the graph, never file contents — so 1 GB of PDFs costs a few KB in
+the pipeline. Text is extracted on demand inside the parse UDF.
+
+**Deletion handling.** The parse UDF is non-deterministic, so Pathway memoizes
+its output and, when a file is removed, re-emits that stored text *negated*
+without re-reading the (now gone) file; the retraction flows through chunking and
+embedding and the sink deletes exactly the matching vectors.
+
+---
+
+## 8. Scaling
+
+The indexer and the server are **separate processes that share only the vector
+database**:
+
+- **Server.** Stateless and read-only against the vector DB — run as many
+ instances as you like behind a load balancer, across machines or availability
+ zones. Because it is fully async (coroutines, not a thread pool), each instance
+ handles many concurrent network-bound retrieval calls efficiently. Each
+ instance also serves the chat UI (static, zero overhead), so the UI scales
+ with the API for free.
+- **Frontend (optional split tier).** When the UI must live on a different
+ host than the API, `serviette frontend` is a separate, stateless web tier that
+ serves the same chat page and proxies to the API at `frontend.api_url`
+ server-side (the browser connects to the frontend, which calls the API).
+- **Indexer.** Runs as its own long-lived process and shards across worker
+ processes with one config line (`indexer.workers`, via `pathway spawn`) —
+ the published benchmarks run with 8; its persistence lets it resume
+ without re-embedding.
+- **Vector database.** Scaling and replicating the vector DB itself is the
+ user's responsibility and follows that database's own guidance. (The embedded
+ DuckDB backend is the exception: it lives in one file next to the indexer and
+ is meant for local / single-node setups.)
+
+Engine observability: with `indexer.monitoring_http_port` set, every worker
+process serves the Pathway engine's built-in endpoints on
+`127.0.0.1:(port + worker index)` — `GET /metrics` (Prometheus: input/output
+latency gauges, per-operator row counters) and `GET /status`.
+
+---
+
+## Security & exposing the server
+
+The API server binds to **127.0.0.1 by default**: on a laptop, `serviette up`
+serves only you. It deliberately ships **no built-in authentication** —
+that is a perimeter concern, and a reverse proxy does it better than any
+hand-rolled API key (TLS, key rotation, SSO, rate limits, audit logs come
+for free). This is the norm for tools of this class: Qdrant self-hosted
+ships with auth off, Ollama has none at all — and internet scans keep
+finding thousands of Ollama instances exposed by a careless `0.0.0.0`.
+Don't join them.
+
+To serve beyond localhost:
+
+1. Set the bind address explicitly — it is an intentional decision:
+
+ ```yaml
+ server:
+ host: 0.0.0.0 # containers / remote access; keep 127.0.0.1 otherwise
+ port: 8989
+ ```
+
+2. Put an authenticating reverse proxy in front. A complete example with
+ [Caddy](https://caddyserver.com) (TLS is automatic):
+
+ ```
+ rag.example.com {
+ basic_auth {
+ # generate the hash with: caddy hash-password
+ alice $2a$14$...bcrypt-hash...
+ }
+ reverse_proxy 127.0.0.1:8989
+ }
+ ```
+
+ With this in place serviette itself can stay on 127.0.0.1 — only the proxy
+ is exposed. Any equivalent (nginx + auth_basic, oauth2-proxy, Cloudflare
+ Access, a VPN like Tailscale) works the same way.
+
+**CORS** is deliberately not emitted by default: serviette's own UIs never
+need it (the embedded chat is same-origin; the standalone frontend proxies
+server-side, so `frontend.api_url` may point at a backend on another host —
+or another fleet — without any browser-visible cross-origin traffic), and
+the absence of CORS headers is what stops arbitrary web pages from reading
+responses off localhost instances. If you build your own browser frontend
+that calls the API directly from another origin, opt in with an explicit
+allowlist:
+
+```yaml
+server:
+ cors_origins: ["https://app.example.com"] # never "*" unless you truly mean it
+```
+
+The engine's monitoring endpoints (`indexer.monitoring_http_port`) are
+loopback-only by construction and cannot be exposed directly.
+
+---
+
+## Appendix: regenerating the demo GIF
+
+The README demo GIF is rendered with Pillow (no terminal recorder or browser
+needed), so it regenerates deterministically anywhere:
+
+```bash
+pip install pillow
+python docs/generate_demos.py # -> docs/assets/demo.gif
+```
+
+The frames show real output: the terminal lines are those of a recorded
+`serviette demo` run (heartbeats thinned), the answers are what the model
+produced on the bundled corpus before and after the `sed` edit, and the header
+statistics are the real `/api/v1/stats` values. They live as constants in the
+script (`SCRIPT_UP`, `SCRIPT_EDIT`, `ANSWER_*`, `STATS_*`) — when the output
+of `demo`/`up` or the chat UI changes, re-record and update them rather than
+inventing lines.
diff --git a/docs/assets/architecture.svg b/docs/assets/architecture.svg
new file mode 100644
index 00000000..531ea5d3
--- /dev/null
+++ b/docs/assets/architecture.svg
@@ -0,0 +1,119 @@
+
diff --git a/docs/assets/bench-memory-breakdown.png b/docs/assets/bench-memory-breakdown.png
new file mode 100644
index 00000000..a684418d
Binary files /dev/null and b/docs/assets/bench-memory-breakdown.png differ
diff --git a/docs/assets/bench-memory.png b/docs/assets/bench-memory.png
new file mode 100644
index 00000000..158301df
Binary files /dev/null and b/docs/assets/bench-memory.png differ
diff --git a/docs/assets/demo.gif b/docs/assets/demo.gif
new file mode 100644
index 00000000..724062b9
Binary files /dev/null and b/docs/assets/demo.gif differ
diff --git a/docs/assets/indexer-pipeline.svg b/docs/assets/indexer-pipeline.svg
new file mode 100644
index 00000000..ccccd06c
--- /dev/null
+++ b/docs/assets/indexer-pipeline.svg
@@ -0,0 +1,69 @@
+
diff --git a/docs/generate_demos.py b/docs/generate_demos.py
new file mode 100644
index 00000000..394ad279
--- /dev/null
+++ b/docs/generate_demos.py
@@ -0,0 +1,447 @@
+#!/usr/bin/env python3
+"""Generate the README demo GIF (terminal walkthrough + chat UI).
+
+The frames are rendered with Pillow — no terminal recorder or browser needed —
+so they regenerate deterministically anywhere:
+
+ python docs/generate_demos.py
+
+Output:
+ docs/assets/demo.gif `serviette demo` with its real output, the chat UI
+ answering a question, a live edit of a document in a
+ second terminal, and the same question answered anew
+
+What is shown is what the programs print and answer. The terminal lines are
+taken verbatim from a recorded `serviette demo` run (only the 5-second
+heartbeats are thinned out), the chat answers are what gpt-4o-mini produced on
+the bundled corpus before and after the edit, and the header statistics are the
+real `/api/v1/stats` values. When the output of `demo`/`up` or the UI changes,
+update the scripts below rather than inventing lines.
+
+Requires Pillow (``pip install pillow``).
+"""
+
+from __future__ import annotations
+
+from pathlib import Path
+
+from PIL import Image, ImageDraw, ImageFont
+
+ASSETS = Path(__file__).resolve().parent / "assets"
+
+_FONT_CANDIDATES = {
+ "mono": [
+ "/usr/share/fonts/dejavu-sans-mono-fonts/DejaVuSansMono.ttf",
+ "/usr/share/fonts/truetype/dejavu/DejaVuSansMono.ttf",
+ ],
+ "mono_bold": [
+ "/usr/share/fonts/dejavu-sans-mono-fonts/DejaVuSansMono-Bold.ttf",
+ "/usr/share/fonts/truetype/dejavu/DejaVuSansMono-Bold.ttf",
+ ],
+ "sans": [
+ "/usr/share/fonts/dejavu-sans-fonts/DejaVuSans.ttf",
+ "/usr/share/fonts/truetype/dejavu/DejaVuSans.ttf",
+ ],
+ "sans_bold": [
+ "/usr/share/fonts/dejavu-sans-fonts/DejaVuSans-Bold.ttf",
+ "/usr/share/fonts/truetype/dejavu/DejaVuSans-Bold.ttf",
+ ],
+}
+
+
+def font(kind: str, size: int) -> ImageFont.FreeTypeFont:
+ for path in _FONT_CANDIDATES[kind]:
+ if Path(path).exists():
+ return ImageFont.truetype(path, size)
+ # Fall back to regular mono/sans if a bold face is missing.
+ base = kind.replace("_bold", "")
+ if base != kind:
+ return font(base, size)
+ return ImageFont.load_default()
+
+
+def save_gif(path: Path, frames: list[Image.Image], durations: list[int], colors: int = 128) -> None:
+ path.parent.mkdir(parents=True, exist_ok=True)
+ pal = [f.convert("P", palette=Image.ADAPTIVE, colors=colors) for f in frames]
+ pal[0].save(
+ path,
+ save_all=True,
+ append_images=pal[1:],
+ duration=durations,
+ loop=0,
+ optimize=True,
+ disposal=2,
+ )
+ print(f"wrote {path} ({path.stat().st_size // 1024} KB, {len(frames)} frames)")
+
+
+# ---------------------------------------------------------------------------
+# Terminal demo
+# ---------------------------------------------------------------------------
+
+T_W, T_H = 920, 560
+T_BG = (13, 17, 23)
+T_BAR = (32, 37, 46)
+T_PROMPT = (88, 200, 120)
+T_CMD = (236, 239, 244)
+T_OUT = (148, 158, 170)
+T_ACCENT = (129, 140, 248)
+T_PAD = 24
+T_LINE_H = 26
+T_FONT = 17
+T_FIRST_Y = 56
+
+# Verbatim output of `serviette demo` (local embeddings, OPENAI_API_KEY set),
+# thinned: the heartbeat repeats every 5 s, three of them are kept.
+_INFO = "INFO "
+SCRIPT_UP = [
+ ("cmd", "serviette demo"),
+ ("out", _INFO + "Using local sentence-transformers embeddings; answers are "
+ "generated with OpenAI (OPENAI_API_KEY is set).", T_OUT),
+ ("out", "", T_OUT),
+ ("out", "─" * 72, T_OUT),
+ ("out", " serviette demo — Lumina Coffee Systems", T_CMD),
+ ("out", " Chat UI: http://localhost:8989", T_CMD),
+ ("out", " (opens after the first indexing pass — wait for the", T_OUT),
+ ("out", ' "Ready — open http://..." line below; the first run', T_OUT),
+ ("out", " also downloads the embedding model, ~1-2 min)", T_OUT),
+ ("out", "", T_OUT),
+ ("out", " Your documents live in:", T_OUT),
+ ("out", " /home/you/serviette-demo/docs", T_CMD),
+ ("out", " Anything you do there — edit a file, drop in new documents (PDF, DOCX,", T_OUT),
+ ("out", " scans, …), delete one — is reflected in the answers within seconds.", T_OUT),
+ ("out", "", T_OUT),
+ ("out", " A scripted moment to try first:", T_OUT),
+ ("out", " 1. Ask in the chat: How much does the Team tier cost? (→ 129 EUR)", T_OUT),
+ ("out", " 2. Open /home/you/serviette-demo/docs/pricing.md and change 129 EUR → 199 EUR", T_OUT),
+ ("out", " 3. Ask again — the answer follows the file", T_OUT),
+ ("out", " (watch the “indexed … ago” counter in the header)", T_OUT),
+ ("out", "", T_OUT),
+ ("out", " Ctrl-C stops everything.", T_OUT),
+ ("out", "─" * 72, T_OUT),
+ ("out", "", T_OUT),
+ ("out", _INFO + "up: indexer started (pid 1986416)", T_OUT),
+ ("out", _INFO + "up: showing progress, warnings and errors only — run with --verbose "
+ "for the full indexer and server log", T_OUT),
+ ("out", _INFO + "up: indexing in progress — the chat/API server starts once the first "
+ "documents are ready (0s elapsed)", T_OUT),
+ ("out", _INFO + "up: indexing in progress — the chat/API server starts once the first "
+ "documents are ready (16s elapsed)", T_OUT),
+ ("out", _INFO + "up: indexing in progress — the chat/API server starts once the first "
+ "documents are ready (32s elapsed)", T_OUT),
+ ("out", _INFO + "up: index is ready — starting the server (pid 2019552)", T_OUT),
+ ("out", _INFO + "up: server starting — loading the query embedder; the URL appears once "
+ "it answers (1s elapsed)", T_OUT),
+ ("out", _INFO + "up: server starting — loading the query embedder; the URL appears once "
+ "it answers (11s elapsed)", T_OUT),
+ ("out", _INFO, T_OUT),
+ ("out", " Ready — open http://localhost:8989", T_ACCENT),
+ ("out", " (Ctrl-C stops the indexer and the server)", T_OUT),
+]
+
+# `demo` keeps the first terminal; the edit happens in a second one. `sed`
+# prints nothing, and in quiet mode neither does `up` — the change shows up
+# in the chat header ("indexed 3s ago") and in the answer.
+SCRIPT_EDIT = [
+ ("cmd", "sed -i 's/129 EUR/199 EUR/' serviette-demo/docs/pricing.md"),
+]
+
+
+def _wrap_mono(text: str, fnt: ImageFont.FreeTypeFont, max_w: float) -> list[str]:
+ """Wrap one printed line the way a terminal of this width would."""
+
+ if fnt.getlength(text) <= max_w:
+ return [text]
+ words, lines, cur = text.split(" "), [], ""
+ for w in words:
+ trial = f"{cur} {w}" if cur else w
+ if fnt.getlength(trial) <= max_w:
+ cur = trial
+ else:
+ if cur:
+ lines.append(cur)
+ cur = w
+ if cur:
+ lines.append(cur)
+ return lines
+
+
+def _draw_terminal(lines, typing, title="serviette — terminal") -> Image.Image:
+ img = Image.new("RGB", (T_W, T_H), T_BG)
+ d = ImageDraw.Draw(img)
+ mono = font("mono", T_FONT)
+ mono_b = font("mono_bold", T_FONT)
+ # title bar
+ d.rounded_rectangle([0, 0, T_W, 40], radius=0, fill=T_BAR)
+ for i, c in enumerate([(255, 95, 86), (255, 189, 46), (39, 201, 63)]):
+ d.ellipse([20 + i * 22, 14, 32 + i * 22, 26], fill=c)
+ d.text((T_W // 2, 20), title, font=font("sans", 14), fill=T_OUT, anchor="mm")
+
+ # Lay out every printed line (wrapped like a terminal would), then show
+ # the tail that fits — older lines scroll off the top, as they really do.
+ max_w = T_W - 2 * T_PAD
+ rows: list[tuple[str, str, tuple]] = []
+ for kind, text, color in lines:
+ if kind == "cmd":
+ rows.append(("cmd", text, T_CMD))
+ else:
+ for piece in _wrap_mono(text, mono, max_w):
+ rows.append(("out", piece, color))
+ prompt_rows = 1 if typing is not None else 0
+ capacity = (T_H - T_FIRST_Y - 8) // T_LINE_H - prompt_rows
+ rows = rows[-capacity:] if capacity > 0 else []
+
+ y = T_FIRST_Y
+ for kind, text, color in rows:
+ if kind == "cmd":
+ d.text((T_PAD, y), "$", font=mono_b, fill=T_PROMPT)
+ d.text((T_PAD + 18, y), " " + text, font=mono_b, fill=T_CMD)
+ else:
+ d.text((T_PAD, y), text, font=mono, fill=color)
+ y += T_LINE_H
+
+ if typing is not None:
+ d.text((T_PAD, y), "$", font=mono_b, fill=T_PROMPT)
+ d.text((T_PAD + 18, y), " " + typing, font=mono_b, fill=T_CMD)
+ w = mono_b.getlength(" " + typing)
+ d.rectangle([T_PAD + 18 + w + 2, y + 2, T_PAD + 18 + w + 12, y + 20], fill=T_CMD)
+ return img
+
+
+def build_terminal(
+ script, preprinted=(), title="serviette — terminal", hold=1500
+) -> tuple[list[Image.Image], list[int], list[tuple]]:
+ frames: list[Image.Image] = []
+ durs: list[int] = []
+ printed: list[tuple] = list(preprinted)
+
+ for item in script:
+ kind = item[0]
+ if kind == "cmd":
+ text = item[1]
+ cur = ""
+ for i, ch in enumerate(text):
+ cur += ch
+ if i % 3 == 0 or i == len(text) - 1:
+ frames.append(_draw_terminal(printed, cur, title))
+ durs.append(55)
+ printed.append(("cmd", text, T_CMD))
+ frames.append(_draw_terminal(printed, None, title))
+ durs.append(350)
+ elif kind == "out":
+ printed.append(("out", item[1], item[2]))
+ frames.append(_draw_terminal(printed, None, title))
+ # The banner is printed at once; the `up:` progress lines arrive
+ # over time, so they get a longer beat each.
+ durs.append(700 if item[1].startswith(_INFO) or item[1].startswith(" ") else 120)
+
+ frames.append(_draw_terminal(printed, None, title))
+ durs.append(hold) # hold before switching to the UI scene
+ return frames, durs, printed
+
+
+# ---------------------------------------------------------------------------
+# Frontend (chat UI) demo
+# ---------------------------------------------------------------------------
+
+F_W, F_H = 760, 560
+F_BG = (255, 255, 255)
+F_BORDER = (230, 230, 233)
+F_TEXT = (31, 32, 35)
+F_SOFT = (107, 114, 128)
+F_ACCENT = (79, 70, 229)
+F_USER_BG = (31, 32, 35)
+F_ASSIST_BG = (244, 244, 246)
+F_SOFTBG = (247, 247, 248)
+
+# What gpt-4o-mini answered on the bundled corpus, before and after the edit
+# (recorded with `serviette demo`, local embeddings, k=5).
+QUESTION = "How much does the Team tier cost?"
+ANSWER_BEFORE = "The Team tier costs 129 EUR/month."
+ANSWER_AFTER = "The Team tier costs 199 EUR/month."
+# The header's live statistics line, as /api/v1/stats reported them.
+STATS_BEFORE = "duckdb · 5 chunks · 5 docs · indexed 2m ago"
+STATS_AFTER = "duckdb · 5 chunks · 5 docs · indexed 3s ago"
+SOURCES_LABEL = "5 sources"
+
+
+def _wrap(draw, text, fnt, max_w):
+ words, lines, cur = text.split(), [], ""
+ for w in words:
+ trial = (cur + " " + w).strip()
+ if draw.textlength(trial, font=fnt) <= max_w:
+ cur = trial
+ else:
+ lines.append(cur)
+ cur = w
+ if cur:
+ lines.append(cur)
+ return lines
+
+
+def _draw_frontend(exchanges, composer_text, typing, indexed_note) -> Image.Image:
+ """Render the chat with a list of (question, shown_answer_chars|None,
+ show_sources) exchanges; ``typing`` draws the assistant dots after the
+ last question instead of an answer."""
+
+ img = Image.new("RGB", (F_W, F_H), F_BG)
+ d = ImageDraw.Draw(img)
+ sans = font("sans", 16)
+ sans_b = font("sans_bold", 16)
+ small = font("sans", 13)
+
+ # header
+ d.line([0, 53, F_W, 53], fill=F_BORDER)
+ d.rounded_rectangle([20, 16, 46, 42], radius=8, fill=F_ACCENT)
+ d.text((56, 29), "serviette", font=sans_b, fill=F_TEXT, anchor="lm")
+ # right side: live statistics, then the "Documents" and settings buttons
+ x = F_W - 20
+ d.rounded_rectangle([x - 30, 15, x, 43], radius=8, outline=F_BORDER, fill=F_SOFTBG)
+ d.text((x - 15, 29), "⚙", font=font("sans", 14), fill=F_SOFT, anchor="mm")
+ x -= 38
+ d.rounded_rectangle([x - 86, 15, x, 43], radius=8, outline=F_BORDER, fill=F_SOFTBG)
+ d.text((x - 43, 29), "Documents", font=small, fill=F_SOFT, anchor="mm")
+ x -= 98
+ d.text((x, 29), indexed_note, font=small, fill=F_SOFT, anchor="rm")
+
+ y = 78
+ if not exchanges and not composer_text:
+ d.text((F_W // 2, 200), "Ask anything about your documents",
+ font=font("sans_bold", 22), fill=F_TEXT, anchor="mm")
+ d.text((F_W // 2, 232), "Answers are grounded in your indexed knowledge base.",
+ font=sans, fill=F_SOFT, anchor="mm")
+ d.text((F_W // 2, 256), "Each question is answered on its own, without memory of earlier ones.",
+ font=sans, fill=F_SOFT, anchor="mm")
+
+ for i, (question, answer_chars, show_sources) in enumerate(exchanges):
+ # user bubble (right)
+ lines = _wrap(d, question, sans, 360)
+ bw = max(d.textlength(ln, font=sans) for ln in lines) + 32
+ bh = len(lines) * 24 + 20
+ bx2 = F_W - 24
+ d.rounded_rectangle([bx2 - bw, y, bx2, y + bh], radius=18, fill=F_USER_BG)
+ for j, ln in enumerate(lines):
+ d.text((bx2 - bw + 16, y + 12 + j * 24), ln, font=sans, fill=(255, 255, 255))
+ y += bh + 14
+
+ # assistant side
+ ax = 24
+ d.ellipse([ax, y, ax + 30, y + 30], fill=F_ACCENT)
+ d.text((ax + 15, y + 15), "AI", font=font("sans_bold", 11),
+ fill=(255, 255, 255), anchor="mm")
+ bx = ax + 42
+ is_last = i == len(exchanges) - 1
+ if is_last and typing:
+ d.rounded_rectangle([bx, y, bx + 70, y + 34], radius=16, fill=F_ASSIST_BG)
+ for k, on in enumerate(typing):
+ col = F_SOFT if on else (200, 203, 209)
+ d.ellipse([bx + 16 + k * 16, y + 14, bx + 23 + k * 16, y + 21], fill=col)
+ y += 44
+ elif answer_chars is not None:
+ full = ANSWER_AFTER if i == 1 else ANSWER_BEFORE
+ shown = full[:answer_chars]
+ lines = _wrap(d, shown, sans, 470)
+ bh = len(lines) * 24 + 20
+ bw = (max((d.textlength(ln, font=sans) for ln in lines), default=0)) + 32
+ d.rounded_rectangle([bx, y, bx + max(bw, 90), y + bh], radius=18, fill=F_ASSIST_BG)
+ for j, ln in enumerate(lines):
+ d.text((bx + 16, y + 12 + j * 24), ln, font=sans, fill=F_TEXT)
+ y += bh + 8
+ if show_sources:
+ # The UI's collapsed block listing the passages used.
+ d.rounded_rectangle([bx, y, bx + 130, y + 28], radius=10,
+ fill=F_SOFTBG, outline=F_BORDER)
+ d.text((bx + 12, y + 14), "▸ " + SOURCES_LABEL, font=small,
+ fill=F_SOFT, anchor="lm")
+ y += 38
+ y += 10
+
+ # composer
+ cy = F_H - 74
+ d.rounded_rectangle([24, cy, F_W - 24, cy + 50], radius=22,
+ outline=F_BORDER, width=1, fill=F_BG)
+ text = composer_text if composer_text else "Message…"
+ color = F_TEXT if composer_text else F_SOFT
+ d.text((44, cy + 25), text, font=sans, fill=color, anchor="lm")
+ d.ellipse([F_W - 24 - 46, cy + 6, F_W - 24 - 8, cy + 44], fill=F_ACCENT)
+ cx, cyy = F_W - 24 - 27, cy + 25
+ d.line([cx - 6, cyy + 5, cx + 6, cyy - 6], fill=(255, 255, 255), width=2)
+ d.line([cx + 6, cyy - 6, cx + 1, cyy - 6], fill=(255, 255, 255), width=2)
+ d.line([cx + 6, cyy - 6, cx + 6, cyy - 1], fill=(255, 255, 255), width=2)
+ d.text((F_W // 2, F_H - 12),
+ "Enter to send · Shift+Enter for a new line · Each question is answered on its own",
+ font=font("sans", 11), fill=F_SOFT, anchor="mm")
+ return img
+
+
+def build_chat(prior, answer, indexed_note) -> tuple[list[Image.Image], list[int]]:
+ """One question/answer beat: type the question, dots, reveal ``answer``.
+
+ ``prior`` is a list of completed exchanges rendered above (the history).
+ """
+
+ frames: list[Image.Image] = []
+ durs: list[int] = []
+
+ def add(frame, dur):
+ frames.append(frame)
+ durs.append(dur)
+
+ done = [(q, chars, True) for q, chars in prior]
+ add(_draw_frontend(done, "", None, indexed_note), 900)
+ cur = ""
+ for i, ch in enumerate(QUESTION):
+ cur += ch
+ if i % 2 == 0 or i == len(QUESTION) - 1:
+ add(_draw_frontend(done, cur, None, indexed_note), 40)
+ add(_draw_frontend(done, QUESTION, None, indexed_note), 300)
+
+ pending = done + [(QUESTION, None, False)]
+ for _ in range(2):
+ for pat in [(1, 0, 0), (1, 1, 0), (1, 1, 1)]:
+ add(_draw_frontend(pending, "", pat, indexed_note), 200)
+
+ for frac in (0.4, 0.8, 1.0):
+ shown = done + [(QUESTION, int(len(answer) * frac), False)]
+ add(_draw_frontend(shown, "", None, indexed_note), 380)
+ add(_draw_frontend(done + [(QUESTION, len(answer), True)], "", None, indexed_note), 2600)
+ return frames, durs
+
+
+# ---------------------------------------------------------------------------
+# Combined demo (terminal scene -> chat UI scene, one GIF)
+# ---------------------------------------------------------------------------
+
+C_W, C_H = 920, 600
+
+
+def _onto_canvas(img: Image.Image, bg: tuple[int, int, int]) -> Image.Image:
+ canvas = Image.new("RGB", (C_W, C_H), bg)
+ canvas.paste(img, ((C_W - img.width) // 2, (C_H - img.height) // 2))
+ return canvas
+
+
+def render_combined_gif() -> None:
+ # Beat 1: `serviette demo` up to "Ready — open". Beat 2: ask about the
+ # Team tier -> 129 EUR. Beat 3: sed edits pricing.md in a second terminal.
+ # Beat 4: the same question -> 199 EUR, header says "indexed 3s ago".
+ t1_frames, t1_durs, _ = build_terminal(SCRIPT_UP)
+ c1_frames, c1_durs = build_chat([], ANSWER_BEFORE, STATS_BEFORE)
+ t2_frames, t2_durs, _ = build_terminal(
+ SCRIPT_EDIT, title="serviette — second terminal", hold=1200
+ )
+ c2_frames, c2_durs = build_chat(
+ [(QUESTION, len(ANSWER_BEFORE))], ANSWER_AFTER, STATS_AFTER
+ )
+
+ frames = [_onto_canvas(f, T_BG) for f in t1_frames]
+ frames += [_onto_canvas(f, F_BG) for f in c1_frames]
+ frames += [_onto_canvas(f, T_BG) for f in t2_frames]
+ frames += [_onto_canvas(f, F_BG) for f in c2_frames]
+ durs = t1_durs + c1_durs + t2_durs + c2_durs
+
+ save_gif(ASSETS / "demo.gif", frames, durs, colors=96)
+
+
+if __name__ == "__main__":
+ render_combined_gif()
diff --git a/pyproject.toml b/pyproject.toml
index 3f62ae1e..01f42bee 100644
--- a/pyproject.toml
+++ b/pyproject.toml
@@ -1,65 +1,161 @@
-[tool.poetry]
-name = "llm-app"
-version = "0.3.6"
-description = "LLM-App is a library for creating responsive AI applications leveraging OpenAI/Hugging Face APIs to provide responses to user queries based on live data sources. Build your own LLM application in 30 lines of code, no vector database required."
-authors = [
- "Jan Chorowski ",
- "Kamil Piechowiak ",
- "Jakub Kowalski ",
- "Michał Bartoszkiewicz ",
- "Mohamed Malhou ",
- "Sergey Kulik ",
- "Adrian Kosowski ",
- "Mateusz Lewandowski ",
- "Olivier Ruas ",
-]
-license = "MIT"
-readme = "README.md"
-keywords = ["Pathway", "LLM"]
-package-mode = false
+[build-system]
+requires = ["setuptools>=68", "wheel"]
+build-backend = "setuptools.build_meta"
+[project]
+name = "serviette"
+version = "0.1.7"
+description = "A universal, no-code RAG server for any vector database, built on the Pathway Live Data Framework."
+readme = "README.md"
+license = { file = "LICENSE" }
+authors = [{ name = "serviette contributors" }]
+keywords = ["rag", "pathway", "vector-database", "retrieval", "llm", "embeddings"]
+# Pathway requires CPython >= 3.10.
+requires-python = ">=3.10"
classifiers = [
- "Development Status :: 3 - Alpha",
- "Intended Audience :: Developers",
- "Programming Language :: Python :: Implementation :: CPython",
+ "Programming Language :: Python :: 3",
+ "Programming Language :: Python :: 3.10",
+ "Programming Language :: Python :: 3.11",
+ "Programming Language :: Python :: 3.12",
+ "Programming Language :: Python :: 3.13",
+ "Programming Language :: Python :: 3.14",
"License :: OSI Approved :: MIT License",
+ "Operating System :: OS Independent",
+]
+dependencies = [
+ # >=0.32.1: the first release with the vector-store output connectors
+ # (duckdb, schema-driven qdrant, pinecone, ...) and lazy xpack imports.
+ # Heavy document parsers (docling, unstructured) are opt-in via the
+ # serviette extras below.
+ "pathway[xpack-llm]>=0.32.1",
+ "fastapi>=0.110",
+ "uvicorn>=0.27",
+ "httpx>=0.27",
+ "pydantic>=2.0",
+ "pyyaml>=6.0",
+ # The default zero-setup vector backend (embedded, pure-wheel).
+ "duckdb>=1.0",
+ # Explicit, not via pathway[xpack-llm]'s transitive pin: the OpenAI
+ # client powers the default /rag LLM and the OpenAI embedder (~6 MB).
+ "openai>=1.0",
+ # The popular formats must work in a bare `pip install serviette`:
+ # pypdf for PDF (tiny, pure-python; the docling extra upgrades it to
+ # layout-aware parsing), unstructured for the office family (DOCX, PPTX,
+ # XLSX, HTML, EML). Same version pathway's xpack-llm-docs extra pins, so
+ # adding serviette[docling] later never conflicts. Heavy stacks stay
+ # opt-in: docling (layout/tables), ocr (scans), API keys (audio/video).
+ "pypdf>=4.0",
+ "unstructured[docx,pptx,xlsx]~=0.18.1",
+ # Resolver guard, not a real dependency of ours: unstructured requires
+ # an unpinned `numba`, and on py3.12 a clean resolve can backtrack to
+ # numba 0.53 whose llvmlite predates py3.10 and fails to build. 0.59 is
+ # the first numba with py3.12 wheels.
+ "numba>=0.59",
+ # Resolver guards for pathway[xpack-llm]: its google-generativeai pin needs
+ # protobuf<6, while pathway's unbounded google-cloud-pubsub / google-api-core
+ # resolve to releases that need protobuf>=6.33.5. Without these caps pip
+ # 25.1-25.3 backtracks through ~30 pubsub releases and dies with
+ # resolution-too-deep; older pip wanders for hours.
+ "protobuf<6",
+ "google-cloud-pubsub<2.40",
+ "google-api-core<2.34; python_version < '3.14'",
+ # google-api-core>=2.26 on 3.14 wants grpcio-status>=1.75.1, which the
+ # xpack-llm extra forbids (<1.72).
+ "google-api-core<2.26; python_version >= '3.14'",
]
-[tool.poetry.urls]
-"Homepage" = "https://github.com/pathwaycom/llm-app"
-"Source Code" = "https://github.com/pathwaycom/llm-app"
+[project.optional-dependencies]
+gdrive = ["google-api-python-client>=2.0", "google-auth>=2.0"]
+# The S3 source reads object bytes through a boto3 client. pathway >= 0.33
+# no longer depends on boto3 itself, so it is an explicit extra here.
+s3 = ["boto3>=1.26"]
+sharepoint = ["Office365-REST-Python-Client>=2.5"]
+# FTP/SFTP/WebDAV/ZIP and more via the PyFilesystem2 library.
+# setuptools<81: PyFilesystem2 imports pkg_resources at runtime; modern venvs
+# don't ship it, and setuptools>=81 removed it entirely.
+pyfilesystem = ["fs>=2.4", "setuptools<81"]
+# Local, free multimodal parsing (the keyless defaults of the parser: section
+# pick these up automatically when installed).
+docling = ["pathway[xpack-llm-docs]"] # layout-aware PDF, DOCX via unstructured
+# paddlepaddle pinned below 3.3: its PIR+oneDNN executor crashes on some
+# CPUs (ConvertPirAttribute2RuntimeAttribute); 3.0.x is solid.
+# pdf2image: the xpack's PaddleOCRParser imports it unconditionally (it
+# renders PDF/PPTX input to page images); without it the parser is
+# "unavailable" and every scan is skipped. Pure Python on top of Pillow;
+# the poppler binaries it drives are only needed for PDF input.
+ocr = ["paddleocr>=2.7", "paddlepaddle>=2.6,<3.3", "paddlex[ocr]>=3.0", "pdf2image>=1.17"]
+# One extra per vector-DB backend — install only what you use.
+pgvector = ["asyncpg>=0.29"]
+milvus = ["pymilvus>=2.4"]
+qdrant = ["qdrant-client>=1.10"]
+chroma = ["chromadb-client>=0.5"]
+weaviate = ["weaviate-client>=4.7"]
+# <10: pinecone 10 rewrites create_index(dimension=...) into the new
+# schema-based request body, which pinecone-local (and our prepare step) do
+# not speak yet.
+pinecone = ["pinecone>=5.0,<10"]
+mongodb = ["pymongo>=4.9"]
+# Local, credential-free embeddings (indexer and server side).
+local = ["sentence-transformers>=3.0"]
+gemini = ["google-generativeai>=0.8"]
+# Server-side Bedrock query embedder (the indexer side uses the xpack's
+# aioboto3, which pathway[xpack-llm] brings along).
+bedrock = ["boto3>=1.26"]
+all = [
+ "serviette[gdrive,s3,bedrock,pgvector,milvus,qdrant,chroma,weaviate,pinecone,mongodb]",
+]
+dev = [
+ "pytest>=8.0",
+ "pytest-asyncio>=0.23",
+ "ruff>=0.16,<0.17",
+ "mypy>=1.8",
+ # Clients for the per-backend integration tests (each test skips when
+ # Docker or its client is unavailable).
+ "asyncpg>=0.29",
+ "pymilvus>=2.4",
+ "qdrant-client>=1.10",
+ "chromadb-client>=0.5",
+ "weaviate-client>=4.7",
+ # Fixture builders for the multimodal parser tests (tiny, pure-python).
+ "fpdf2>=2.7",
+ "python-docx>=1.1",
+ # asyncio support is built into pinecone since 9.x (the old [asyncio]
+ # extra is gone and only produces resolver warnings).
+ "pinecone>=9.0,<10",
+ "pymongo>=4.9",
+ # Bedrock server-embedder unit tests and the S3 integration test.
+ "boto3>=1.26",
+ # Embedded Milvus engine for the Milvus integration test (the pgvector
+ # integration test instead spins up a Docker container — see docs).
+ "milvus-lite>=2.4",
+]
-[tool.poetry.dependencies]
-python = ">=3.10,<3.13"
-pathway = "^0.12.0"
+[project.scripts]
+serviette = "serviette.cli:main"
-[tool.poetry.group.linters]
-optional = true
+[project.urls]
+Homepage = "https://pathway.com"
+Documentation = "https://github.com/pathwaycom/serviette"
-[tool.poetry.group.linters.dependencies]
-black = "^24.2.0"
-isort = "^5.13.2"
-mypy = "~1.10.0"
-flake8 = "~7.0.0"
-pytest = "^8.0.2"
-types-requests = "^2.31.0"
-types-PyYAML = "^6.0.0"
+[tool.setuptools.packages.find]
+include = ["serviette*"]
-[build-system]
-requires = ["poetry-core"]
-build-backend = "poetry.core.masonry.api"
+[tool.setuptools.package-data]
+"serviette.frontend" = ["static/*"]
+"serviette.demo" = ["corpus/*.md"]
-[tool.black]
-target-version = ["py310", "py311"]
+[tool.pytest.ini_options]
+asyncio_mode = "auto"
+testpaths = ["tests"]
+markers = [
+ "slow: end-to-end tests that spin up a Pathway runtime per pass",
+ "integration: tests that require Docker (real database containers)",
+]
-[tool.isort]
-profile = "black"
+[tool.ruff]
+line-length = 100
+target-version = "py310"
-[tool.mypy]
-python_version = "3.10"
-exclude = ["templates/adaptive_rag", "templates/private_rag", "templates/document_indexing", "templates/multimodal_rag", "templates/question_answering_rag", "templates/video_rag_twelvelabs"]
-ignore_missing_imports = true
-check_untyped_defs = true
-warn_redundant_casts = true
-warn_unused_ignores = true
-strict_equality = true
+[tool.ruff.lint.per-file-ignores]
+# Integration tests import after pytest.importorskip by design.
+"tests/test_integration_*.py" = ["E402"]
diff --git a/serviette/__init__.py b/serviette/__init__.py
new file mode 100644
index 00000000..0b486aab
--- /dev/null
+++ b/serviette/__init__.py
@@ -0,0 +1,10 @@
+"""serviette — a universal, no-code RAG server built on the Pathway Live Data Framework.
+
+The project name is intentionally kept in a single constant so a rename only
+requires a find-and-replace across files plus updating ``APP_NAME`` here.
+"""
+
+APP_NAME = "serviette"
+__version__ = "0.1.7"
+
+__all__ = ["APP_NAME", "__version__"]
diff --git a/serviette/cli.py b/serviette/cli.py
new file mode 100644
index 00000000..a8eadf46
--- /dev/null
+++ b/serviette/cli.py
@@ -0,0 +1,117 @@
+"""Single ``serviette`` entrypoint dispatching all subcommands.
+
+Subcommands:
+ serviette indexer --config FILE Build & run the Pathway indexing graph
+ serviette server --config FILE Start the FastAPI retrieval/RAG server
+ serviette up --config FILE Run indexer + server together (dev/demo)
+ serviette demo Zero-to-chat demo on a bundled corpus
+ serviette wizard Interactive config-generation wizard
+"""
+
+from __future__ import annotations
+
+import argparse
+import sys
+
+from serviette import APP_NAME, __version__
+
+_OLD_PATHWAY_HINT = (
+ "Your installed pathway ({version}) predates the vector-store connectors "
+ "serviette needs (pathway >= 0.32.1). Upgrade it in this environment:\n\n"
+ " pip install -U 'pathway>=0.32.1'\n"
+)
+
+
+def _ensure_pathway_connectors() -> None:
+ """Fail with instructions, not an AttributeError, on an old pathway.
+
+ Engine-facing commands (indexer/up/demo) need the vector-store output
+ connectors that shipped in pathway 0.32.1; on an older install the first
+ symptom used to be an opaque crash deep in the stack.
+ """
+
+ import pathway as pw
+
+ if not hasattr(pw.io, "duckdb"):
+ raise SystemExit(_OLD_PATHWAY_HINT.format(version=pw.__version__))
+
+
+def main(argv: list[str] | None = None) -> None:
+ argv = list(sys.argv[1:] if argv is None else argv)
+
+ parser = argparse.ArgumentParser(prog=APP_NAME, description=__doc__)
+ parser.add_argument("--version", action="version", version=f"{APP_NAME} {__version__}")
+ sub = parser.add_subparsers(
+ dest="command",
+ required=True,
+ # Spelled out so the hidden alias below stays out of the usage line.
+ metavar="{indexer,server,up,demo,frontend,wizard}",
+ )
+ sub.add_parser("indexer", add_help=False, help="Run the indexer")
+ sub.add_parser("server", add_help=False, help="Run the server")
+ sub.add_parser("up", add_help=False, help="Run indexer + server together")
+ sub.add_parser("demo", add_help=False, help="Zero-to-chat demo on a bundled corpus")
+ sub.add_parser("frontend", add_help=False, help="Run the web chat frontend")
+ sub.add_parser("wizard", add_help=False, help="Interactive config wizard")
+ # The wizard's former name; no ``help`` keeps it out of --help. Dropped
+ # in a later release — "quickstart" promised the fastest path, which is
+ # `demo`.
+ sub.add_parser("quickstart", add_help=False)
+
+ # Parse only the first token so each subcommand owns the rest of argv.
+ args, rest = parser.parse_known_args(argv)
+
+ if args.command in ("indexer", "up", "demo"):
+ _ensure_pathway_connectors()
+ # Every subcommand but the wizard loads a config; the import is here
+ # rather than at module level to keep `--version` free of pydantic.
+ from serviette.config.schema import MissingEnvVarError
+
+ try:
+ _dispatch(args.command, rest)
+ except MissingEnvVarError as exc:
+ # A config referencing an unset ${VAR} is a user error with a known
+ # fix, not a crash: say it plainly instead of printing a traceback.
+ raise SystemExit(str(exc)) from None
+
+
+def _dispatch(command: str, rest: list[str]) -> None:
+ args = argparse.Namespace(command=command)
+ if args.command == "indexer":
+ from serviette.indexer.main import main as indexer_main
+
+ indexer_main(rest)
+ elif args.command == "server":
+ from serviette.server.config import load_server_config
+ from serviette.server.main import run
+
+ server_args = _parse_config_arg("server", rest)
+ run(load_server_config(server_args.config))
+ elif args.command == "up":
+ from serviette.up import main as up_main
+
+ up_main(rest)
+ elif args.command == "demo":
+ from serviette.demo import main as demo_main
+
+ demo_main(rest)
+ elif args.command == "frontend":
+ from serviette.frontend.config import load_frontend_config
+ from serviette.frontend.main import run
+
+ frontend_args = _parse_config_arg("frontend", rest)
+ run(load_frontend_config(frontend_args.config))
+ elif args.command in ("wizard", "quickstart"):
+ from serviette.wizard import main as wizard_main
+
+ wizard_main(rest)
+
+
+def _parse_config_arg(prog: str, rest: list[str]) -> argparse.Namespace:
+ p = argparse.ArgumentParser(prog=f"{APP_NAME} {prog}")
+ p.add_argument("--config", required=True, help="Path to the YAML config file")
+ return p.parse_args(rest)
+
+
+if __name__ == "__main__":
+ main()
diff --git a/serviette/config/__init__.py b/serviette/config/__init__.py
new file mode 100644
index 00000000..54752416
--- /dev/null
+++ b/serviette/config/__init__.py
@@ -0,0 +1,49 @@
+"""Shared configuration package for serviette."""
+
+from serviette.config.schema import (
+ ChromaConfig,
+ DuckDbConfig,
+ EmbedderConfig,
+ FrontendConfig,
+ FsSource,
+ GDriveSource,
+ LLMConfig,
+ MilvusConfig,
+ MongoDbConfig,
+ PersistenceConfig,
+ PgVectorConfig,
+ PineconeConfig,
+ QdrantConfig,
+ S3Source,
+ ServerConfig,
+ ServietteConfig,
+ SharePointSource,
+ Source,
+ SplitterConfig,
+ WeaviateConfig,
+ load_config,
+)
+
+__all__ = [
+ "ChromaConfig",
+ "DuckDbConfig",
+ "EmbedderConfig",
+ "FrontendConfig",
+ "FsSource",
+ "GDriveSource",
+ "LLMConfig",
+ "MilvusConfig",
+ "MongoDbConfig",
+ "PersistenceConfig",
+ "PgVectorConfig",
+ "PineconeConfig",
+ "QdrantConfig",
+ "S3Source",
+ "ServerConfig",
+ "ServietteConfig",
+ "SharePointSource",
+ "Source",
+ "SplitterConfig",
+ "WeaviateConfig",
+ "load_config",
+]
diff --git a/serviette/config/schema.py b/serviette/config/schema.py
new file mode 100644
index 00000000..cfa13e2c
--- /dev/null
+++ b/serviette/config/schema.py
@@ -0,0 +1,1001 @@
+"""Shared configuration schema for serviette (Pydantic v2).
+
+A single YAML file can hold both indexer and server configuration (a *universal*
+config), or the user can split it into an indexer-only and a server-only file.
+Most top-level sections are therefore optional at the schema level; each
+component validates the subset it needs via :func:`require` at startup.
+
+String values support ``${ENV_VAR}`` interpolation, resolved while the YAML is
+loaded (see :func:`load_config`). This keeps credentials out of the config file
+itself, satisfying the "no hardcoded credentials" principle.
+"""
+
+from __future__ import annotations
+
+import os
+import re
+from pathlib import Path
+from typing import Annotated, Any, ClassVar, Literal
+
+import yaml
+from pydantic import (
+ BaseModel,
+ ConfigDict,
+ Field,
+ ValidationError,
+ field_validator,
+ model_validator,
+)
+
+from serviette import APP_NAME
+
+# ---------------------------------------------------------------------------
+# Sources
+# ---------------------------------------------------------------------------
+
+
+class FsSource(BaseModel):
+ """A filesystem source watched by the indexer.
+
+ ``type`` is the discriminator across source types. Only sources with an
+ ``only_metadata`` read mode are supported (see ``GDriveSource``).
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["fs"] = "fs"
+ # A directory; ``~`` is expanded. Must exist when the indexer starts —
+ # see :func:`require_source_dirs` (a typo must not silently become an
+ # empty index).
+ path: str
+ glob: str = "**/*"
+ # "streaming" watches the path continuously (default); "static" reads the
+ # current contents once and lets the graph terminate (used for one-shot
+ # indexing and tests).
+ mode: Literal["streaming", "static"] = "streaming"
+ # Bound on entries the connector keeps in flight before downstream
+ # processing catches up. Backpressure keeps the indexer's memory flat
+ # during bulk backfills and makes sink commits arrive steadily instead of
+ # in one giant batch. None disables the bound.
+ max_backlog_size: int | None = 1000
+
+ @field_validator("path")
+ @classmethod
+ def _expand_user(cls, value: str) -> str:
+ # ``~/docs`` is what people type; the fs connector takes it literally.
+ return os.path.expanduser(value)
+
+
+class GDriveSource(BaseModel):
+ """A Google Drive source (folder or file) read in ``only_metadata`` mode.
+
+ Like the filesystem source, the graph holds only metadata; file bytes are
+ downloaded on demand by id during parsing. Requires a Google service-account
+ credentials file (see the Google Drive connector docs).
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["gdrive"] = "gdrive"
+ object_id: str
+ service_user_credentials_file: str
+ # Glob (or list of globs) on file names, e.g. "*.pdf". None = no filtering.
+ file_name_pattern: str | list[str] | None = None
+ object_size_limit: int | None = None
+ mode: Literal["streaming", "static"] = "streaming"
+ # See FsSource.max_backlog_size.
+ max_backlog_size: int | None = 1000
+
+
+class S3Source(BaseModel):
+ """An S3 bucket (or any S3-compatible store: MinIO, DigitalOcean, Wasabi)
+ read in ``only_metadata`` mode: the graph tracks object metadata only, and
+ object bytes are downloaded on demand during parsing. Credentials fall
+ back to the standard AWS chain when omitted.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["s3"] = "s3"
+ bucket: str
+ # Key or key prefix to index ("" = the whole bucket).
+ path: str = ""
+ access_key: str | None = None
+ secret_access_key: str | None = None
+ region: str | None = None
+ # Custom endpoint for self-hosted / S3-compatible storage (e.g. MinIO);
+ # such setups usually also need path-style addressing.
+ endpoint: str | None = None
+ with_path_style: bool = False
+ mode: Literal["streaming", "static"] = "streaming"
+ # See FsSource.max_backlog_size.
+ max_backlog_size: int | None = 1000
+
+ @model_validator(mode="after")
+ def _custom_endpoint_needs_region(self) -> S3Source:
+ # Without a region the AWS signature's credential scope is malformed
+ # and S3-compatible stores reject requests with an opaque
+ # AuthorizationQueryParametersError. MinIO's default is us-east-1.
+ if self.endpoint and not self.region:
+ raise ValueError(
+ "s3 source: 'region' is required when 'endpoint' is set "
+ "(use 'us-east-1' for a default MinIO installation)"
+ )
+ return self
+
+
+class SharePointSource(BaseModel):
+ """A Microsoft SharePoint directory/file read in ``only_metadata`` mode.
+
+ Uses certificate authentication (an app registration with a certificate;
+ see the Pathway SharePoint connector docs). Requires a Pathway Scale
+ license and the ``serviette[sharepoint]`` extra.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["sharepoint"] = "sharepoint"
+ url: str # e.g. https://company.sharepoint.com/sites/MySite
+ tenant: str
+ client_id: str
+ cert_path: str
+ thumbprint: str
+ root_path: str
+ recursive: bool = True
+ object_size_limit: int | None = None
+ refresh_interval: int = 30
+ mode: Literal["streaming", "static"] = "streaming"
+
+
+class PyFilesystemSource(BaseModel):
+ """Any filesystem PyFilesystem can open, watched in ``only_metadata``
+ mode: FTP, SFTP/SSH, WebDAV, ZIP/TAR archives, in-memory and more —
+ the ``fs_url`` (e.g. ``"ftp://user:pass@host/dir"``, ``"zip://docs.zip"``)
+ selects the driver. Requires the ``serviette[pyfilesystem]`` extra; some
+ protocols need their own driver package (``fs.sshfs``, ``fs.webdavfs``).
+ Credentials belong in the URL via ``${ENV_VAR}`` interpolation."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["pyfilesystem"] = "pyfilesystem"
+ fs_url: str
+ # Path inside the opened filesystem ("" = its root), scanned recursively.
+ path: str = ""
+ mode: Literal["streaming", "static"] = "streaming"
+ # Seconds between scans in streaming mode.
+ refresh_interval: float = 30.0
+ # See FsSource.max_backlog_size.
+ max_backlog_size: int | None = 1000
+
+
+class ParserRule(BaseModel):
+ """One routing rule of the ``parser:`` section: files whose name *or*
+ path (as the source reports it — absolute for ``fs``, the object key for
+ ``s3``, the server-relative URL for ``sharepoint``) matches any of the
+ ``match`` globs are parsed by ``type``; ``*`` also matches ``/``, so
+ ``*/scans/*.png`` selects a folder. Rules are checked in order, first
+ match wins; built-in keyless-first defaults cover whatever the user
+ rules don't. ``options`` are forwarded to the parser constructor
+ (e.g. ``prompt`` for twelvelabs_video, ``model``/``api_key`` for
+ whisper); ``${ENV_VAR}`` interpolation applies as everywhere."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ match: list[str] = Field(min_length=1)
+ type: Literal[
+ "utf8",
+ "pypdf",
+ "docling",
+ "unstructured",
+ "paddle_ocr",
+ "vision_image",
+ "vision_slide",
+ "whisper",
+ "twelvelabs_video",
+ "skip",
+ ]
+ options: dict[str, Any] = Field(default_factory=dict)
+
+
+Source = Annotated[
+ FsSource | GDriveSource | S3Source | SharePointSource | PyFilesystemSource,
+ Field(discriminator="type"),
+]
+
+
+# ---------------------------------------------------------------------------
+# Vector databases
+# ---------------------------------------------------------------------------
+
+
+class _HybridCapableConfig(BaseModel):
+ """Mixed into every backend whose accessor can run in-process BM25 hybrid.
+
+ ``hybrid`` fuses vector search with a BM25 keyword index built in-process
+ from the backend's stored texts (rebuilt on change, see
+ ``hybrid_refresh_seconds``) via
+ reciprocal-rank fusion — it helps entity-heavy queries (names, dates, IDs)
+ that embedding distance ranks poorly. In-process BM25 targets corpora up to
+ a few million chunks; above ``hybrid_max_chunks`` the keyword leg is skipped
+ with a warning and retrieval stays pure-vector. Native server-side keyword
+ search is the planned replacement at larger scale.
+ """
+
+ hybrid: bool = False
+ hybrid_max_chunks: int = Field(default=5_000_000, ge=1)
+ # Upper bound on how stale the in-process BM25 index may get. The index
+ # is rebuilt at once when the backend reports a change (row count; on
+ # DuckDB/pgvector also the newest ``seen_at``, which catches in-place
+ # edits), and additionally refreshed in the background once this many
+ # seconds have passed since the last build — the safety net for changes
+ # the backend's cheap signal cannot see. null disables the timed refresh.
+ hybrid_refresh_seconds: float | None = Field(default=30.0, ge=0)
+
+
+class PgVectorConfig(_HybridCapableConfig):
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["pgvector"] = "pgvector"
+ connection_string: str
+ table: str = "serviette_embeddings"
+ # Dimension of the embedding column. Used when the indexer auto-creates the
+ # table. If omitted, it is inferred from the embedder at indexer startup.
+ embedding_dimension: int | None = None
+
+
+class MilvusConfig(_HybridCapableConfig):
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["milvus"] = "milvus"
+ # Either a full URI (e.g. "http://localhost:19530" or "./milvus.db" for
+ # Milvus Lite) or host + port. ``uri`` takes precedence when provided.
+ uri: str | None = None
+ host: str = "localhost"
+ port: int = 19530
+ collection: str = "serviette_embeddings"
+ token: str | None = None
+ embedding_dimension: int | None = None
+
+ def resolved_uri(self) -> str:
+ if self.uri:
+ return self.uri
+ return f"http://{self.host}:{self.port}"
+
+ def is_lite(self) -> bool:
+ """Milvus Lite: ``uri`` is a local file (``./milvus.db``), not a URL.
+ Lite runs embedded in the process that opens the file and locks it,
+ so only one process can use it at a time."""
+
+ return bool(self.uri) and "://" not in self.uri
+
+
+class DuckDbConfig(_HybridCapableConfig):
+ """Embedded vector store backed by a local DuckDB database file.
+
+ Zero-setup: no external service. The indexer writes through Pathway's native
+ ``pw.io.duckdb`` connector in *snapshot* mode (real upserts/deletes keyed by
+ chunk id); embeddings land as native ``DOUBLE[]`` lists and retrieval runs
+ **inside DuckDB** with ``list_cosine_similarity`` — a vectorized, columnar
+ scan, not a Python loop.
+
+ Concurrency: the sink writes with ``detach_between_batches`` (Pathway
+ ≥ 0.32.1), releasing the single-writer file lock between minibatches, so
+ the server's retrying read-only connections query the same file while a
+ streaming indexer runs. On older Pathway builds serviette warns and falls
+ back to hold-the-lock behavior (use ``mode: static`` there).
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["duckdb"] = "duckdb"
+ path: str
+ table: str = "serviette_embeddings"
+
+
+class QdrantConfig(_HybridCapableConfig):
+ """Qdrant backend. The indexer writes via ``pw.io.qdrant`` (gRPC); the
+ server queries via the REST/HTTP API. The collection is auto-created on
+ first write (cosine metric) if it does not exist."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["qdrant"] = "qdrant"
+ host: str = "localhost"
+ rest_port: int = 6333
+ grpc_port: int = 6334
+ https: bool = False
+ api_key: str | None = None
+ collection: str = "serviette_embeddings"
+
+ def rest_url(self) -> str:
+ scheme = "https" if self.https else "http"
+ return f"{scheme}://{self.host}:{self.rest_port}"
+
+ def grpc_url(self) -> str:
+ scheme = "https" if self.https else "http"
+ return f"{scheme}://{self.host}:{self.grpc_port}"
+
+
+class ChromaConfig(_HybridCapableConfig):
+ """ChromaDB backend (HTTP client/server mode). The **collection must
+ already exist** (created with the cosine ``hnsw:space``); the connector
+ never creates it."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["chroma"] = "chroma"
+ host: str = "localhost"
+ port: int = 8000
+ ssl: bool = False
+ headers: dict[str, str] | None = None
+ tenant: str = "default_tenant"
+ database: str = "default_database"
+ collection: str = "serviette_embeddings"
+
+
+class WeaviateConfig(_HybridCapableConfig):
+ """Weaviate backend. The **collection must already exist**. The indexer
+ writes over HTTP; the server's v4 client also needs the gRPC port."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["weaviate"] = "weaviate"
+ http_host: str = "localhost"
+ http_port: int = 8080
+ http_secure: bool = False
+ grpc_host: str | None = None # defaults to http_host
+ grpc_port: int = 50051
+ grpc_secure: bool = False
+ api_key: str | None = None
+ collection: str = "ServietteEmbeddings"
+
+
+class PineconeConfig(BaseModel):
+ """Pinecone backend. The **index must already exist** with a dimension
+ matching the embedder (cosine metric recommended). ``host`` is only needed
+ for Pinecone Local; the managed service resolves it from the API key."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["pinecone"] = "pinecone"
+ index_name: str
+ api_key: str | None = None # falls back to PINECONE_API_KEY
+ host: str | None = None
+ namespace: str = ""
+ # Used when the indexer auto-creates a missing index.
+ embedding_dimension: int | None = None
+ cloud: str = "aws"
+ region: str = "us-east-1"
+ # In-process BM25 hybrid is NOT available on Pinecone: it has no
+ # scan-all-vectors API, so the keyword corpus cannot be built server-side.
+ # Setting this raises a clear error at startup. Native hybrid needs a
+ # second (sparse) index fed by the indexer — planned.
+ hybrid: bool = False
+
+
+class MongoDbConfig(_HybridCapableConfig):
+ """MongoDB Atlas Vector Search backend. The indexer writes documents in
+ snapshot mode via ``pw.io.mongodb``; create an Atlas ``vectorSearch`` index
+ (named ``vector_index`` by default) on the ``embedding`` path with
+ ``numDimensions`` matching the embedder."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ type: Literal["mongodb"] = "mongodb"
+ connection_string: str
+ database: str
+ collection: str = "serviette_embeddings"
+ vector_index: str = "vector_index"
+ # Used when the indexer auto-creates a missing vectorSearch index.
+ embedding_dimension: int | None = None
+
+
+VectorDBConfig = Annotated[
+ DuckDbConfig | PgVectorConfig | MilvusConfig | QdrantConfig | ChromaConfig | WeaviateConfig | PineconeConfig | MongoDbConfig,
+ Field(discriminator="type"),
+]
+
+
+# ---------------------------------------------------------------------------
+# Embedder / splitter / LLM
+# ---------------------------------------------------------------------------
+
+
+class EmbedderConfig(BaseModel):
+ """Embedder configuration.
+
+ ``type`` selects an embedder family that maps onto a
+ ``pathway.xpacks.llm.embedders`` class on the indexer side and onto an async
+ client on the server side. Any extra keys are forwarded to the underlying
+ embedder constructor / client, so provider-specific options need no schema
+ change.
+ """
+
+ model_config = ConfigDict(extra="allow")
+
+ type: str = "openai"
+ model: str | None = None
+ api_key: str | None = None
+ # Asymmetric-retrieval prefixes (e5, bge & co): prepended to the text
+ # right before embedding — ``document_prefix`` on the indexer side,
+ # ``query_prefix`` on the server side. Stored chunk text stays clean.
+ # Leave empty for symmetric models.
+ query_prefix: str = ""
+ document_prefix: str = ""
+
+
+class RerankerConfig(BaseModel):
+ """Optional second-stage reranker for retrieval.
+
+ When configured, the server fetches ``candidates`` nearest chunks from the
+ vector index, scores each (query, chunk) pair, and returns the top ``k``
+ by that score. Two scorers are available:
+
+ - ``cross_encoder`` (default): a local sentence-transformers cross-encoder
+ reads the query and the chunk *together*, so it catches matches that
+ embedding distance ranks poorly — at the cost of one model call per
+ candidate, which is why it runs on a shortlist and not on the whole
+ index. The default model is local, free and keyless.
+ - ``llm``: pointwise LLM scoring (each chunk rated 0–5 for relevance to
+ the query, in the spirit of ``pathway.xpacks.llm.rerankers.LLMReranker``).
+ Costs one cheap LLM call per candidate; ``model``/``api_key`` default to
+ the top-level ``llm`` section.
+
+ Note: pointwise rerankers optimize per-chunk relevance to the *whole*
+ question and can push out chunks needed for other hops of a multi-hop
+ question — for those, prefer ``rag.decompose`` / ``rag.mmr``.
+ """
+
+ model_config = ConfigDict(extra="allow")
+
+ type: str = "cross_encoder"
+ model: str | None = None # cross_encoder: ms-marco-MiniLM-L-6-v2; llm: llm section's
+ api_key: str | None = None # llm type only; defaults to the llm section's
+ candidates: int = Field(default=30, ge=1)
+
+
+class SplitterConfig(BaseModel):
+ """Chunking strategy: ``token_count`` (default), ``recursive``, or
+ ``null`` — no splitting, the whole document is one chunk (short,
+ self-contained documents: FAQ entries, product cards). Extra keys are
+ forwarded to the xpack splitter constructor."""
+
+ model_config = ConfigDict(extra="allow")
+
+ type: str = "token_count"
+ chunk_size: int = 512
+ chunk_overlap: int = 50
+
+ @field_validator("type", mode="before")
+ @classmethod
+ def _yaml_null_means_no_splitter(cls, value: Any) -> Any:
+ # ``type: null`` is the natural way to write it in YAML, and the
+ # YAML parser hands it over as None; treat that as the "null"
+ # splitter rather than failing validation with "expected a string".
+ return "null" if value is None else value
+
+
+class LLMConfig(BaseModel):
+ """Optional LLM configuration for the ``/rag`` endpoint."""
+
+ model_config = ConfigDict(extra="allow")
+
+ type: str = "openai"
+ model: str | None = None
+ api_key: str | None = None
+ # Sampling temperature for completions. None = provider default. Set 0 for
+ # reproducible benchmark runs; leave unset for reasoning models that
+ # reject non-default temperatures.
+ temperature: float | None = None
+ # Reasoning effort for reasoning models (gpt-5*, o*): "minimal" | "low" |
+ # "medium" | "high". None = provider default. Lower efforts cut latency
+ # and output-token cost; non-reasoning models reject the parameter, so
+ # leave unset for them.
+ reasoning_effort: str | None = None
+ # System prompt for /rag answers. None = the built-in strictly-grounded
+ # default ("answer only from the provided context") — right for private
+ # corpora where hallucinated outside knowledge is unacceptable. Override
+ # to allow blending the model's own knowledge with the context (e.g. for
+ # public-domain corpora the model has largely memorized). Adaptive RAG
+ # keeps this policy and appends its own no-answer instruction (the
+ # marker that tells it to fetch more context) — note that a policy which
+ # lets the model answer from its own knowledge rarely triggers that
+ # marker, so the context then rarely grows.
+ system_prompt: str | None = None
+
+
+class AdaptiveRagConfig(BaseModel):
+ """Adaptive RAG (Pathway research; cf. ``AdaptiveRAGQuestionAnswerer``).
+
+ ``/rag`` first answers from the requested ``k`` chunks; when the LLM
+ replies that the context is insufficient (detected via
+ ``no_answer_string``), the context is grown by ``factor`` and the question
+ re-asked, up to ``max_iterations`` attempts total. Simple questions stay
+ cheap; hard multi-hop ones get a larger context only when needed.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ factor: int = Field(default=2, ge=2)
+ max_iterations: int = Field(default=4, ge=1)
+ # The exact marker the LLM is instructed to reply with when the context
+ # does not contain the answer. Detected as a substring of the reply.
+ no_answer_string: str = "No information found"
+
+
+class DecomposeConfig(BaseModel):
+ """Multi-query retrieval for multi-hop questions.
+
+ One LLM call splits the question into standalone sub-queries ("mother of
+ the 15th first lady?", "second assassinated president?"); retrieval runs
+ for the original question and every sub-query, and the result lists are
+ fused with reciprocal-rank fusion. This keeps chunks of *different* hops
+ from competing for the same top-k slots. Requires the ``llm`` section.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ max_subqueries: int = Field(default=4, ge=2, le=10)
+
+
+class MmrConfig(BaseModel):
+ """Maximal-marginal-relevance diversification of retrieval results.
+
+ The server fetches ``candidates`` chunks and greedily selects ``k`` of
+ them, trading relevance against similarity to the already-selected set:
+ ``diversity`` is the weight of the redundancy penalty (0 = plain top-k,
+ 1 = ignore relevance). Needs hit embeddings, so the backend must support
+ returning them (DuckDB for now).
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ candidates: int = Field(default=20, ge=1)
+ diversity: float = Field(default=0.3, ge=0.0, le=1.0)
+
+
+class DocumentsConfig(BaseModel):
+ """Document-level questions on ``/rag``: how many documents there are,
+ which ones exist, what a named file says, how two files differ.
+
+ On by default (unlike the other ``rag`` strategies) — these are the first
+ questions people ask, and chunk retrieval cannot answer them. A question
+ that names a file (with its extension) is answered from that file
+ directly. Any other question goes through the ordinary search first;
+ only when the LLM reports no answer does one short extra call decide
+ between searching wider (``rag.adaptive``) and answering from the
+ document catalog or from whole documents. Every step is bounded by
+ ``max_context_chars`` and the whole request by ``max_request_chars``,
+ whatever the size of the documents.
+
+ While enabled, the ``/rag`` system prompt carries the no-answer
+ instruction ``rag.adaptive`` uses (that reply is what triggers the extra
+ call), with ``corpus_card`` one line stating the document count, and with
+ ``source_labels`` each context chunk is prefixed with its file name.
+ Ignored on backends that cannot enumerate documents (Pinecone).
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ enabled: bool = True
+ # State the number of indexed documents in the /rag system prompt, so
+ # "how many documents do you have" is answered on the first attempt.
+ corpus_card: bool = True
+ # Prefix every retrieved chunk in the /rag context with the name of its
+ # file, so the model can attribute statements and tell apart documents
+ # that disagree (e.g. two versions of one file).
+ source_labels: bool = True
+ # Upper bound, in characters, on the document material one answering
+ # call sees (a whole document, a comparison, or the catalog listing).
+ max_context_chars: int = Field(default=24_000, ge=1_000)
+ # Upper bound, in characters, on everything one /rag request sends to
+ # the LLM across all of its calls (search attempts incl. the adaptive
+ # loop, routing, the answer). A call that does not fit is cut down to
+ # what is left; when nothing useful fits, no further call is made and
+ # the response says so in ``notice``. About 4 characters per token.
+ max_request_chars: int = Field(default=100_000, ge=2_000)
+ # How many document names the routing call is shown.
+ max_listed_documents: int = Field(default=200, ge=1)
+
+
+class RagConfig(BaseModel):
+ """Optional retrieval-quality strategies for ``/retrieve`` and ``/rag``.
+
+ ``decompose`` widens *what* is retrieved, ``mmr`` diversifies *which*
+ candidates survive, ``adaptive`` retries with a larger context when the
+ answer is not found (``/rag`` only; ``decompose`` and ``mmr`` also apply
+ to ``/retrieve``, though ``decompose`` needs an ``llm`` section either
+ way). These three are opt-in and composable; ``documents`` (``/rag``
+ only) is on unless disabled.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ adaptive: AdaptiveRagConfig | None = None
+ decompose: DecomposeConfig | None = None
+ mmr: MmrConfig | None = None
+ documents: DocumentsConfig = Field(default_factory=DocumentsConfig)
+
+
+# ---------------------------------------------------------------------------
+# Persistence / server
+# ---------------------------------------------------------------------------
+
+
+class IndexerConfig(BaseModel):
+ """Indexer runtime options."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ # Number of Pathway worker PROCESSES. When > 1, `serviette indexer` re-executes
+ # itself through `pathway spawn --processes N` (one worker thread each);
+ # sinks that key rows internally (e.g. qdrant) write in parallel.
+ workers: int = Field(default=1, ge=1)
+ # Retries of a document's byte fetch before it is given up on (indexed as
+ # empty, ERROR-logged, retried on the next restart). Exponential backoff
+ # from 1s. Remote sources fail transiently under bulk backfills — rate
+ # limits, connection resets — so 0 is only for tests.
+ fetch_retries: int = Field(default=3, ge=0)
+ # Advanced. Disk budget for the parse cache (pw.udfs.DefaultCache, stored
+ # under /persistence/runtime_calls, LRU-evicted). Size it at least to
+ # the extracted-text volume of the corpus to avoid re-parse churn.
+ parse_cache_size_gb: int = Field(default=8, ge=1)
+ # Advanced. If set, the engine keeps the memoization cache of
+ # non-deterministic UDFs (parsed texts) in files in this directory
+ # instead of RAM (requires a Pathway build with pw.run's
+ # udf_cache_directory). Point it at a real disk, not tmpfs.
+ udf_cache_directory: str | None = None
+ # Advanced. First port of the inter-worker communication range used by
+ # ``pathway spawn`` when workers > 1 (each worker binds first_port + index).
+ # Shift it when several Pathway applications share a host — the default
+ # range collides and workers hang retrying "connection refused".
+ spawn_first_port: int = Field(default=10000, ge=1024, le=65000)
+ # Advanced. Base port of the Pathway engine's built-in monitoring HTTP
+ # server: every worker process serves GET /status (JSON snapshot) and
+ # GET /metrics (Prometheus) on 127.0.0.1:(port + worker index).
+ # None disables the server.
+ monitoring_http_port: int | None = Field(default=None, ge=1, le=65535)
+
+
+class PersistenceConfig(BaseModel):
+ """On-disk persistence — the silent default (the wizard does not ask).
+
+ Carries three things: incremental state across restarts (no re-embedding
+ of unchanged documents), correct retraction of files deleted while the
+ indexer was down, and the parse cache (``runtime_calls``). Advanced users
+ disable it by editing the config directly; disabling also disables the
+ parse cache.
+
+ The state lives in the ``persistence`` subdirectory of the working
+ directory (``workdir_path``, see :meth:`ServietteConfig.persistence_dir`);
+ there is no separate path to configure.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ enabled: bool = True
+ backend: Literal["filesystem"] = "filesystem"
+
+ @model_validator(mode="before")
+ @classmethod
+ def _no_path_here(cls, data: Any) -> Any:
+ if isinstance(data, dict) and "path" in data:
+ raise ValueError(
+ "persistence.path is not a setting: the persistence state lives "
+ "in the working directory — set the top-level workdir_path instead."
+ )
+ return data
+
+
+class ServerConfig(BaseModel):
+ model_config = ConfigDict(extra="forbid")
+
+ # Loopback by default: the server has no built-in auth (that is the
+ # perimeter's job — see the Security section of the docs), so listening
+ # on all interfaces must be an explicit decision ("0.0.0.0"), not a
+ # surprise on a laptop in a cafe.
+ host: str = "127.0.0.1"
+ # An uncommon default port: 8000/8080 collide with half the dev tools.
+ port: int = 8989
+ # Opt-in CORS allowlist for third-party browser frontends that call this
+ # API directly from another origin. Empty (the default) = no CORS
+ # headers at all — which is itself a protection: it stops web pages from
+ # reading responses of localhost instances (drive-by exfiltration).
+ # serviette's own UIs never need this (same origin / server-side proxy).
+ # Enable only if you know what you are doing; prefer exact origins over "*".
+ cors_origins: list[str] = Field(default_factory=list)
+ # Serve the chat UI on "/" from the same process/port (same-origin, no
+ # CORS). Disable for a pure-API deployment; the standalone
+ # `serviette frontend` command covers split UI/API deployments.
+ serve_frontend: bool = True
+
+
+class UpConfig(BaseModel):
+ """``serviette up`` supervisor options."""
+
+ model_config = ConfigDict(extra="forbid")
+
+ # Seconds ``up`` holds the server back waiting for the first indexed
+ # chunks. Normally the wait ends within seconds; it never ends when the
+ # source folder holds only documents that yield no text (scans without
+ # the OCR extra, audio without its API key, files whose parser fails),
+ # so after this long the server starts over the empty index with a
+ # warning and documents keep being indexed live. null = wait forever.
+ index_wait_timeout: float | None = Field(default=120.0, ge=0)
+
+
+class FrontendConfig(BaseModel):
+ """Web chat UI. Decoupled from the API: it only needs the API's address.
+
+ The frontend serves the page and *proxies* requests to ``api_url`` server-side
+ (no CORS, the API address never reaches the browser), so indexing, API and
+ frontend can each run on a different worker/host.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ host: str = "127.0.0.1" # loopback by default, same reasoning as ServerConfig
+ port: int = 3000
+ # Base URL of the serviette server API this frontend talks to.
+ api_url: str = "http://localhost:8989"
+ title: str = APP_NAME
+
+
+# ---------------------------------------------------------------------------
+# Root config
+# ---------------------------------------------------------------------------
+
+
+class ServietteConfig(BaseModel):
+ """Top-level universal configuration.
+
+ Sections are optional so the same model validates indexer-only and
+ server-only files. Use :meth:`for_indexer` / :meth:`for_server` to assert the
+ fields a given component requires.
+ """
+
+ model_config = ConfigDict(extra="forbid")
+
+ pathway_license_key: str | None = None
+
+ sources: list[Source] = Field(default_factory=list)
+ vector_db: VectorDBConfig | None = None
+ embedder: EmbedderConfig | None = None
+ splitter: SplitterConfig = Field(default_factory=SplitterConfig)
+ # Optional parser routing rules (see ParserRule). None: built-in defaults
+ # cover every modality, preferring keyless local parsers (best available:
+ # docling > pypdf for PDF, PaddleOCR for images) and skipping modalities
+ # whose only parser needs an absent API key (audio, video) with a warning.
+ parser: list[ParserRule] | None = None
+ indexer: IndexerConfig = Field(default_factory=IndexerConfig)
+
+ # serviette's working directory: everything it keeps on disk between
+ # runs goes under here, each concern in its own subdirectory — the
+ # Pathway persistence state (``persistence/``, together with the parse
+ # cache), and the configuration fingerprint at the top level. Relative
+ # paths resolve against the process's working directory, like every other
+ # path in the config. Silent default — the wizard does not ask.
+ workdir_path: str = "./serviette-workdir"
+ persistence: PersistenceConfig = Field(default_factory=PersistenceConfig)
+ server: ServerConfig = Field(default_factory=ServerConfig)
+ up: UpConfig = Field(default_factory=UpConfig)
+ llm: LLMConfig | None = None
+ reranker: RerankerConfig | None = None
+ rag: RagConfig | None = None
+ frontend: FrontendConfig | None = None
+
+ # -- working directory layout ---------------------------------------------
+
+ PERSISTENCE_SUBDIR: ClassVar[str] = "persistence"
+
+ def workdir(self) -> Path:
+ return Path(self.workdir_path)
+
+ def persistence_dir(self) -> Path:
+ """The directory handed to the Pathway persistence backend.
+
+ A subdirectory of its own because the engine treats every entry of the
+ directory it is given as persisted state and logs an ERROR for
+ anything it did not write.
+ """
+
+ return self.workdir() / self.PERSISTENCE_SUBDIR
+
+ # -- per-component requirements -------------------------------------------
+
+ def require(self, *fields: str) -> None:
+ missing = [f for f in fields if not getattr(self, f)]
+ if missing:
+ raise ValueError(
+ "Missing required config section(s) for this command: "
+ + ", ".join(missing)
+ )
+
+ def for_indexer(self) -> ServietteConfig:
+ self.require("sources", "vector_db", "embedder")
+ return self
+
+ def for_server(self) -> ServietteConfig:
+ self.require("vector_db", "embedder")
+ return self
+
+ def for_frontend(self) -> ServietteConfig:
+ self.require("frontend")
+ return self
+
+ def missing_source_dirs(self) -> list[str]:
+ """Paths of ``fs`` sources that are not existing directories."""
+
+ return [
+ src.path
+ for src in self.sources
+ if src.type == "fs" and not Path(src.path).is_dir()
+ ]
+
+
+def require_source_dirs(config: ServietteConfig) -> None:
+ """Abort with a plain message when an ``fs`` source directory is missing.
+
+ Called by the engine-facing commands (``indexer``, ``up``) before any
+ work starts. Without this, a mistyped path is indistinguishable from an
+ empty folder: the connector watches nothing, ``up`` serves an empty
+ index, and the user only sees "no relevant context" answers.
+ """
+
+ missing = config.missing_source_dirs()
+ if not missing:
+ return
+ listed = "\n".join(f" - {path}" for path in missing)
+ raise SystemExit(
+ "Source directory not found:\n"
+ f"{listed}\n"
+ "Check the 'path' of the fs source(s) in your config (relative paths "
+ "resolve against the current working directory; '~' is expanded), "
+ "or create the directory first — documents dropped into an existing "
+ "folder are indexed live."
+ )
+
+
+def require_multi_process_backend(config: ServietteConfig) -> None:
+ """Abort when the backend cannot serve the indexer and the server at once.
+
+ ``serviette up`` runs them as two processes against one store. Milvus
+ Lite is an embedded, single-process database: whichever process opens
+ the file first holds its lock, and the other fails with
+ ``DataDirLockedError`` — in practice ``up``'s readiness probe wins and
+ the indexer dies before indexing anything. Lite still works for the
+ one-process-at-a-time flow (``serviette indexer`` with static sources,
+ then ``serviette server``).
+ """
+
+ vdb = config.vector_db
+ if isinstance(vdb, MilvusConfig) and vdb.is_lite():
+ raise SystemExit(
+ f"Milvus Lite ({vdb.uri!r}) cannot be used with 'serviette up': it is "
+ "an embedded single-process database, and 'up' runs the indexer and "
+ "the server as two processes against the same file.\n"
+ "Use a Milvus server instead (vector_db.uri: http://host:19530 — "
+ "e.g. the 'milvus run standalone' docker image), or run the two "
+ "commands one after the other: 'serviette indexer' with "
+ "'mode: static' sources, then 'serviette server'."
+ )
+
+
+def missing_openai_credentials(config: ServietteConfig, *, roles: tuple[str, ...]) -> list[str]:
+ """The ``openai``-typed sections among ``roles`` (``"embedder"``, ``"llm"``)
+ that have no ``api_key`` and cannot fall back on ``OPENAI_API_KEY``."""
+
+ if os.environ.get("OPENAI_API_KEY"):
+ return []
+ missing = []
+ for role in roles:
+ section = getattr(config, role, None)
+ if section is not None and section.type == "openai" and not section.api_key:
+ missing.append(role)
+ return missing
+
+
+def require_openai_credentials(config: ServietteConfig, *, roles: tuple[str, ...]) -> None:
+ """Abort with a plain message when an OpenAI section has no key to use.
+
+ Without this the key is first needed deep inside a child process: the
+ indexer dies on the SDK's ``Missing credentials`` traceback after
+ ``up`` has already announced "indexing in progress", and the server
+ answers its first ``/rag`` with a 500. Checked by the engine-facing
+ commands before any work starts; ``roles`` says which sections the
+ command actually uses (the indexer embeds, the server embeds and chats).
+ """
+
+ missing = missing_openai_credentials(config, roles=roles)
+ if not missing:
+ return
+ listed = ", ".join(f"{role} (type: openai)" for role in missing)
+ raise SystemExit(
+ f"OpenAI API key missing for: {listed}.\n"
+ "Export it before starting (`export OPENAI_API_KEY=sk-...`) or set "
+ "`api_key` in those config sections. To run without OpenAI, switch the "
+ "embedder to `sentence_transformer` (free, local) and drop or change "
+ "the `llm` section."
+ )
+
+
+# ---------------------------------------------------------------------------
+# Loading + ${ENV_VAR} interpolation
+# ---------------------------------------------------------------------------
+
+_ENV_PATTERN = re.compile(r"\$\{([A-Za-z_][A-Za-z0-9_]*)\}")
+
+
+class MissingEnvVarError(ValueError):
+ """A ``${VAR}`` reference in the config names an environment variable
+ that is not set."""
+
+
+def interpolate_env(value: Any, *, strict: bool = True) -> Any:
+ """Recursively replace ``${VAR}`` occurrences in strings with env values.
+
+ A reference to an unset variable is an error (:class:`MissingEnvVarError`,
+ naming every such variable and where it is used): resolving it to an
+ empty string used to send ``api_key: ""`` to the provider, whose 401
+ ("incorrect API key") hid the actual cause. ``strict=False`` keeps the
+ empty-string behavior for callers validating the *shape* of a config
+ that is meant to run elsewhere (the wizard's tests).
+ """
+
+ missing: list[tuple[str, str]] = []
+
+ def visit(node: Any, where: str) -> Any:
+ if isinstance(node, str):
+
+ def substitute(match: re.Match[str]) -> str:
+ name = match.group(1)
+ if name not in os.environ:
+ missing.append((name, where))
+ return ""
+ return os.environ[name]
+
+ return _ENV_PATTERN.sub(substitute, node)
+ if isinstance(node, dict):
+ return {k: visit(v, f"{where}.{k}" if where else str(k)) for k, v in node.items()}
+ if isinstance(node, list):
+ return [visit(v, f"{where}[{i}]") for i, v in enumerate(node)]
+ return node
+
+ result = visit(value, "")
+ if missing and strict:
+ listed = "\n".join(
+ f" - ${{{name}}} (used in {where or 'the value'})" for name, where in missing
+ )
+ raise MissingEnvVarError(
+ "The config references environment variable(s) that are not set:\n"
+ f"{listed}\n"
+ "Export them before starting (e.g. `export OPENAI_API_KEY=sk-...`) "
+ "or replace the reference in the config."
+ )
+ return result
+
+
+def load_config(path: str | Path) -> ServietteConfig:
+ """Load, env-interpolate and validate a YAML config file."""
+
+ raw = yaml.safe_load(Path(path).read_text(encoding="utf-8")) or {}
+ if not isinstance(raw, dict):
+ raise TypeError(f"Config root must be a mapping, got {type(raw).__name__}")
+ try:
+ interpolated = interpolate_env(raw)
+ except MissingEnvVarError as exc:
+ raise MissingEnvVarError(f"Invalid configuration in {path}:\n{exc}") from None
+ try:
+ return ServietteConfig.model_validate(interpolated)
+ except ValidationError as exc: # pragma: no cover - re-raised with context
+ raise ValueError(f"Invalid configuration in {path}:\n{exc}") from exc
+
+
+def load_config_dict(data: dict[str, Any], *, strict_env: bool = True) -> ServietteConfig:
+ """Validate an already-parsed config dict.
+
+ ``strict_env=False`` tolerates ``${VAR}`` references to unset variables —
+ for validating the shape of a generated config that will run elsewhere.
+ """
+
+ return ServietteConfig.model_validate(interpolate_env(data, strict=strict_env))
diff --git a/serviette/demo/__init__.py b/serviette/demo/__init__.py
new file mode 100644
index 00000000..e8461492
--- /dev/null
+++ b/serviette/demo/__init__.py
@@ -0,0 +1,256 @@
+"""``serviette demo`` — zero-to-chat in one command.
+
+Copies a small bundled corpus (a fictional company, Lumina Coffee Systems)
+into a working directory, generates a DuckDB-backed config, and runs the
+``serviette up`` supervisor over it. The printed script walks the presenter
+through the money shot: edit ``docs/pricing.md`` and watch the answer change.
+
+Embedder/LLM selection. By default the embedder is local —
+``sentence-transformers`` when installed, the mock embedder otherwise —
+so retrieval is free and the index never depends on an API key.
+``--embedder openai`` opts into OpenAI embeddings instead: nothing to
+install, fast to start, but every indexed token costs money — meant for
+small corpora. The LLM (independently of the embedder) uses
+``OPENAI_API_KEY`` when it is set (real generated answers) and falls back
+to the mock LLM (the answer quotes the retrieved snippet) when not.
+"""
+
+from __future__ import annotations
+
+import argparse
+import importlib.util
+import logging
+import os
+import shutil
+import sys
+from pathlib import Path
+from typing import Any
+
+import yaml
+
+logger = logging.getLogger(__name__)
+
+_CORPUS_DIR = Path(__file__).parent / "corpus"
+
+_SCRIPT = """
+────────────────────────────────────────────────────────────────────────
+ serviette demo — Lumina Coffee Systems
+ Chat UI: http://localhost:{port}
+ (opens after the first indexing pass — wait for the
+ "Ready — open http://..." line below; the first run
+ also downloads the embedding model, ~1-2 min)
+
+ Your documents live in:
+ {docs_dir}
+ Anything you do there — edit a file, drop in new documents (PDF, DOCX,
+ scans, …), delete one — is reflected in the answers within seconds.
+
+ A scripted moment to try first:
+ 1. Ask in the chat: How much does the Team tier cost? (→ 129 EUR)
+ 2. Open {docs_dir}/pricing.md and change 129 EUR → 199 EUR
+ 3. Ask again — the answer follows the file
+ (watch the “indexed … ago” counter in the header)
+
+ Ctrl-C stops everything.
+────────────────────────────────────────────────────────────────────────
+"""
+
+_MOCK_NOTICE = """
+ ⚠ MOCK EMBEDDER IN USE — retrieval quality is NOT representative.
+ Neither the local embedder is installed nor an API embedder chosen,
+ so matching works on token overlap only{key_hint}.
+ For a real demo, either:
+ pip install "serviette[local]" --extra-index-url https://download.pytorch.org/whl/cpu
+ # free local embeddings (CPU PyTorch,
+ # ~0.8 GB; ~5 GB without the flag)
+ serviette demo --embedder openai # nothing to install; indexing is
+ # billed to OPENAI_API_KEY
+"""
+
+
+def mock_embedder_notice() -> str:
+ """The banner block explaining *why* the demo fell back to mock."""
+
+ key_hint = (
+ "\n (your OPENAI_API_KEY is set, but the demo never spends it on"
+ "\n indexing unless you opt in with --embedder openai)"
+ if os.environ.get("OPENAI_API_KEY")
+ else ""
+ )
+ return _MOCK_NOTICE.format(key_hint=key_hint)
+
+
+def choose_embedder() -> str:
+ """Pick the local embedder: sentence-transformers if installed, else mock.
+
+ Deliberately never an API embedder — the demo index must not depend on
+ (or spend) anyone's API key; the key only upgrades the LLM.
+ """
+
+ if importlib.util.find_spec("sentence_transformers") is not None:
+ return "sentence_transformer"
+ return "mock"
+
+
+def build_demo_config(
+ demo_dir: Path, *, port: int, embedder: str, license_key: str
+) -> dict[str, Any]:
+ """Assemble the demo config dict (pure; unit-tested)."""
+
+ config: dict[str, Any] = {
+ "pathway_license_key": license_key,
+ "sources": [
+ {"type": "fs", "path": str(demo_dir / "docs"), "glob": "**/*"}
+ ],
+ "vector_db": {
+ "type": "duckdb",
+ "path": str(demo_dir / "embeddings.duckdb"),
+ "table": "demo_embeddings",
+ },
+ "workdir_path": str(demo_dir / "workdir"),
+ "persistence": {"enabled": True, "backend": "filesystem"},
+ "server": {"host": "127.0.0.1", "port": port},
+ }
+ if embedder == "sentence_transformer":
+ config["embedder"] = {"type": "sentence_transformer"}
+ elif embedder == "openai":
+ config["embedder"] = {"type": "openai", "api_key": "${OPENAI_API_KEY}"}
+ else:
+ config["embedder"] = {"type": "mock"}
+ # The LLM (not the embedder) upgrades to OpenAI when a key is present.
+ if os.environ.get("OPENAI_API_KEY"):
+ config["llm"] = {"type": "openai", "api_key": "${OPENAI_API_KEY}"}
+ else:
+ config["llm"] = {"type": "mock"}
+ return config
+
+
+def _resolve_license_key() -> str:
+ if os.environ.get("PATHWAY_LICENSE_KEY"):
+ return "${PATHWAY_LICENSE_KEY}"
+ if not sys.stdin.isatty():
+ raise SystemExit(
+ "serviette demo needs a Pathway license key (free, one click at "
+ "https://pathway.com/framework/get-license). Set "
+ "PATHWAY_LICENSE_KEY and re-run."
+ )
+ print(
+ "serviette demo needs a (free) Pathway license key — one click at\n"
+ "https://pathway.com/framework/get-license"
+ )
+ key = input("Paste your Pathway license key: ").strip()
+ if not key:
+ print("A license key is required.", file=sys.stderr)
+ raise SystemExit(1)
+ return key
+
+
+def _reset_index_if_embedder_changed(demo_dir: Path, embedder: str) -> None:
+ """Demo data is disposable: on an embedder switch (e.g. the user exported
+ OPENAI_API_KEY since the last run), silently drop the old index instead
+ of tripping the fingerprint guard — vectors from different embedders are
+ not comparable, and re-indexing the tiny corpus takes seconds."""
+
+ config_path = demo_dir / "config.yaml"
+ if not config_path.exists():
+ return
+ try:
+ previous = yaml.safe_load(config_path.read_text())["embedder"]["type"]
+ except Exception: # noqa: BLE001 - a hand-edited config must not crash the demo
+ return
+ if previous == embedder:
+ return
+ logger.info(
+ "demo: embedder changed (%s -> %s); resetting the demo index",
+ previous,
+ embedder,
+ )
+ (demo_dir / "embeddings.duckdb").unlink(missing_ok=True)
+ shutil.rmtree(demo_dir / "workdir", ignore_errors=True)
+
+
+def prepare_demo_dir(
+ demo_dir: Path, *, port: int, license_key: str, embedder_choice: str = "local"
+) -> Path:
+ """Copy the corpus and write config.yaml; returns the config path."""
+
+ docs = demo_dir / "docs"
+ if not docs.exists():
+ shutil.copytree(_CORPUS_DIR, docs)
+ if embedder_choice == "openai":
+ if not os.environ.get("OPENAI_API_KEY"):
+ raise SystemExit(
+ "serviette demo --embedder openai needs OPENAI_API_KEY set."
+ )
+ embedder = "openai"
+ else:
+ embedder = choose_embedder()
+ _reset_index_if_embedder_changed(demo_dir, embedder)
+ if embedder == "mock":
+ logger.warning(
+ "sentence-transformers is not installed: using the mock embedder "
+ "(retrieval quality is NOT representative). For a real demo "
+ 'install "serviette[local]" --extra-index-url '
+ "https://download.pytorch.org/whl/cpu (free local embeddings) or "
+ "run with --embedder openai (uses your OPENAI_API_KEY; costs money)."
+ )
+ elif embedder == "sentence_transformer":
+ if os.environ.get("OPENAI_API_KEY"):
+ logger.info(
+ "Using local sentence-transformers embeddings; answers are "
+ "generated with OpenAI (OPENAI_API_KEY is set)."
+ )
+ else:
+ logger.info(
+ "Using local sentence-transformers embeddings; /rag will quote "
+ "retrieved snippets (set OPENAI_API_KEY for generated answers)."
+ )
+ elif embedder == "openai":
+ logger.info(
+ "Using OpenAI embeddings for indexing: fast to start, but every "
+ "indexed token is billed — keep the corpus small. For large "
+ 'collections install "serviette[local]" and use the default '
+ "local embedder."
+ )
+ config = build_demo_config(
+ demo_dir, port=port, embedder=embedder, license_key=license_key
+ )
+ config_path = demo_dir / "config.yaml"
+ config_path.write_text(
+ "# generated by `serviette demo`\n"
+ + yaml.safe_dump(config, sort_keys=False, default_flow_style=False)
+ )
+ return config_path
+
+
+def main(argv: list[str]) -> None:
+ from serviette.config.schema import load_config
+ from serviette.up import run as up_run
+
+ parser = argparse.ArgumentParser(prog="serviette demo", description=__doc__)
+ parser.add_argument("--dir", default="./serviette-demo", help="Demo working directory")
+ parser.add_argument("--port", type=int, default=8989)
+ parser.add_argument(
+ "--embedder",
+ choices=["local", "openai"],
+ default="local",
+ help="local (default): free sentence-transformers embeddings; "
+ "openai: nothing to install but indexing costs money (needs "
+ "OPENAI_API_KEY) — for small corpora",
+ )
+ args = parser.parse_args(argv)
+
+ logging.basicConfig(level=logging.INFO, format="%(levelname)s %(message)s")
+ demo_dir = Path(args.dir).resolve()
+ demo_dir.mkdir(parents=True, exist_ok=True)
+ config_path = prepare_demo_dir(
+ demo_dir,
+ port=args.port,
+ license_key=_resolve_license_key(),
+ embedder_choice=args.embedder,
+ )
+ print(_SCRIPT.format(port=args.port, docs_dir=demo_dir / "docs"))
+ embedder_type = yaml.safe_load(config_path.read_text())["embedder"]["type"]
+ if embedder_type == "mock":
+ print(mock_embedder_notice())
+ sys.exit(up_run(load_config(config_path), str(config_path)))
diff --git a/serviette/demo/corpus/faq.md b/serviette/demo/corpus/faq.md
new file mode 100644
index 00000000..d689f25a
--- /dev/null
+++ b/serviette/demo/corpus/faq.md
@@ -0,0 +1,12 @@
+# Frequently Asked Questions
+
+**Which beans can I use?** Any beans work, but Lumina Select beans are
+calibrated per machine model and give the most consistent extraction.
+
+**What happens if a machine goes offline?** Machines keep brewing offline;
+telemetry buffers locally for up to 7 days and syncs when connectivity
+returns.
+
+**Can I cancel anytime?** Yes. Subscriptions are monthly; cancellation takes
+effect at the end of the billing period, and we collect the hardware within
+two weeks.
diff --git a/serviette/demo/corpus/onboarding.md b/serviette/demo/corpus/onboarding.md
new file mode 100644
index 00000000..53aa2ea1
--- /dev/null
+++ b/serviette/demo/corpus/onboarding.md
@@ -0,0 +1,12 @@
+# Onboarding Guide
+
+Getting a new office online takes about 15 minutes:
+
+1. Unbox the machine and connect it to power and water.
+2. Scan the QR code on the drip tray to pair it with your Lumina Cloud
+ workspace.
+3. Assign the machine to a floor and set brewing profiles in the console.
+4. Run the self-test brew; the machine calibrates grind size automatically.
+
+For fleets above 50 machines our field team performs installation on site,
+included in the Enterprise tier.
diff --git a/serviette/demo/corpus/overview.md b/serviette/demo/corpus/overview.md
new file mode 100644
index 00000000..4b32b99d
--- /dev/null
+++ b/serviette/demo/corpus/overview.md
@@ -0,0 +1,10 @@
+# Lumina Coffee Systems — Company Overview
+
+Lumina Coffee Systems builds connected espresso machines for offices and
+hotels. Every machine streams telemetry (water temperature, extraction time,
+bean levels) to the Lumina Cloud, where facility managers monitor fleets in
+real time.
+
+Founded in 2019, Lumina operates in 14 countries and maintains a fleet of
+over 40,000 machines. Our flagship model is the Lumina S3; the compact
+Lumina Go targets small offices under 20 people.
diff --git a/serviette/demo/corpus/pricing.md b/serviette/demo/corpus/pricing.md
new file mode 100644
index 00000000..38d1445c
--- /dev/null
+++ b/serviette/demo/corpus/pricing.md
@@ -0,0 +1,12 @@
+# Pricing
+
+Lumina offers three subscription tiers, billed per machine per month:
+
+- **Starter** — 49 EUR/month: one Lumina Go, cloud telemetry, email support.
+- **Team** — 129 EUR/month: one Lumina S3, telemetry, priority support,
+ free bean delivery once a month.
+- **Enterprise** — custom pricing: fleet management console, SLA 99.9%,
+ dedicated account manager.
+
+All tiers include a 30-day free trial. Hardware remains the property of
+Lumina and is replaced free of charge within 48 hours if it fails.
diff --git a/serviette/demo/corpus/release-notes.md b/serviette/demo/corpus/release-notes.md
new file mode 100644
index 00000000..1b4b19b8
--- /dev/null
+++ b/serviette/demo/corpus/release-notes.md
@@ -0,0 +1,10 @@
+# Release Notes — Lumina Cloud
+
+## 2026.06
+- Predictive descaling: the console now schedules descaling based on water
+ hardness telemetry instead of fixed intervals.
+- Slack alerts for low bean levels.
+
+## 2026.04
+- Fleet dashboard groups machines by building and floor.
+- Export of consumption reports to CSV.
diff --git a/serviette/frontend/__init__.py b/serviette/frontend/__init__.py
new file mode 100644
index 00000000..27996006
--- /dev/null
+++ b/serviette/frontend/__init__.py
@@ -0,0 +1 @@
+"""Web chat frontend package."""
diff --git a/serviette/frontend/config.py b/serviette/frontend/config.py
new file mode 100644
index 00000000..f676c884
--- /dev/null
+++ b/serviette/frontend/config.py
@@ -0,0 +1,13 @@
+"""Config loading/validation for the frontend command."""
+
+from __future__ import annotations
+
+from pathlib import Path
+
+from serviette.config.schema import ServietteConfig, load_config
+
+
+def load_frontend_config(path: str | Path) -> ServietteConfig:
+ """Load a config file and assert it has a ``frontend`` section."""
+
+ return load_config(path).for_frontend()
diff --git a/serviette/frontend/main.py b/serviette/frontend/main.py
new file mode 100644
index 00000000..4b12da90
--- /dev/null
+++ b/serviette/frontend/main.py
@@ -0,0 +1,152 @@
+"""FastAPI web chat frontend (standalone, for split deployments).
+
+A thin, decoupled service: it serves the single-page chat UI and *proxies*
+requests to the configured serviette API (``frontend.api_url``). The browser only
+ever talks to this frontend's own origin, so there is no CORS to configure and
+the API address stays server-side. Use it when the UI must live on a different
+host than the API; otherwise ``serviette server`` already serves the same page on
+its own port (``server.serve_frontend``, on by default).
+
+The page and the proxy speak the versioned API surface: the browser calls
+``/api/v1/...`` on this origin and the proxy forwards to ``/api/v1/...`` on
+the upstream server.
+"""
+
+from __future__ import annotations
+
+from contextlib import asynccontextmanager
+from pathlib import Path
+
+import httpx
+from fastapi import FastAPI, Request
+from fastapi.responses import HTMLResponse, JSONResponse
+
+from serviette.config.schema import ServietteConfig
+
+_STATIC_DIR = Path(__file__).parent / "static"
+_INDEX_FILE = _STATIC_DIR / "index.html"
+
+# Endpoints on the upstream API that the frontend is allowed to proxy.
+_PROXY_ROUTES = {"rag": "/api/v1/rag", "retrieve": "/api/v1/retrieve"}
+
+
+def load_index(title: str) -> str:
+ """Return the chat page HTML with the configured title substituted.
+
+ Shared with the server's embedded-UI mode, so both serve one page.
+ """
+
+ return _INDEX_FILE.read_text(encoding="utf-8").replace("__APP_TITLE__", title)
+
+
+def create_app(config: ServietteConfig, *, client: httpx.AsyncClient | None = None) -> FastAPI:
+ """Build the frontend app.
+
+ ``client`` can be injected (tests provide an httpx client backed by a mock
+ transport); otherwise one is created against ``frontend.api_url``.
+ """
+
+ config.for_frontend()
+ fe = config.frontend
+ assert fe is not None # guaranteed by for_frontend()
+ index_html = load_index(fe.title)
+ owns_client = client is None
+
+ @asynccontextmanager
+ async def lifespan(_: FastAPI):
+ nonlocal client
+ if client is None:
+ # trust_env=False: the API is a sibling service (same host or
+ # network); routing its calls through the environment's
+ # http_proxy turns a working setup into "Could not reach the
+ # API" wherever a corporate proxy is configured.
+ client = httpx.AsyncClient(base_url=fe.api_url, timeout=120.0, trust_env=False)
+ try:
+ yield
+ finally:
+ if owns_client and client is not None:
+ await client.aclose()
+
+ app = FastAPI(title=f"{fe.title} frontend", lifespan=lifespan)
+
+ @app.get("/", response_class=HTMLResponse)
+ async def index() -> HTMLResponse:
+ return HTMLResponse(index_html)
+
+ @app.get("/api/v1/config")
+ async def frontend_config() -> JSONResponse:
+ # Informational only (shown in the header); no secrets here.
+ return JSONResponse({"title": fe.title, "api_url": fe.api_url})
+
+ async def _proxy(name: str, request: Request) -> JSONResponse:
+ try:
+ body = await request.json()
+ except Exception: # noqa: BLE001 - any malformed body proxies as empty
+ body = {}
+ assert client is not None # created in lifespan before serving
+ try:
+ upstream = await client.post(_PROXY_ROUTES[name], json=body)
+ except httpx.HTTPError as exc:
+ return JSONResponse(
+ {"detail": f"Could not reach the API at {fe.api_url}: {exc}"},
+ status_code=502,
+ )
+ try:
+ payload = upstream.json()
+ except ValueError:
+ payload = {"detail": upstream.text}
+ return JSONResponse(payload, status_code=upstream.status_code)
+
+ @app.get("/api/v1/stats")
+ async def stats() -> JSONResponse:
+ assert client is not None # created in lifespan before serving
+ try:
+ upstream = await client.get("/api/v1/stats")
+ except httpx.HTTPError:
+ return JSONResponse({"stats_available": False}, status_code=502)
+ try:
+ payload = upstream.json()
+ except ValueError:
+ payload = {"stats_available": False}
+ return JSONResponse(payload, status_code=upstream.status_code)
+
+ @app.get("/api/v1/documents")
+ async def documents(request: Request) -> JSONResponse:
+ # The document panel's search: forwarded with its query string.
+ assert client is not None # created in lifespan before serving
+ try:
+ upstream = await client.get(
+ "/api/v1/documents", params=dict(request.query_params)
+ )
+ except httpx.HTTPError as exc:
+ return JSONResponse(
+ {"detail": f"Could not reach the API at {fe.api_url}: {exc}"},
+ status_code=502,
+ )
+ try:
+ payload = upstream.json()
+ except ValueError:
+ payload = {"detail": upstream.text}
+ return JSONResponse(payload, status_code=upstream.status_code)
+
+ @app.post("/api/v1/rag")
+ async def rag(request: Request) -> JSONResponse:
+ return await _proxy("rag", request)
+
+ @app.post("/api/v1/retrieve")
+ async def retrieve(request: Request) -> JSONResponse:
+ return await _proxy("retrieve", request)
+
+ return app
+
+
+def run(config: ServietteConfig) -> None:
+ """Start uvicorn with the configured frontend host/port (used by the CLI)."""
+
+ import uvicorn
+
+ config.for_frontend()
+ fe = config.frontend
+ assert fe is not None # guaranteed by for_frontend()
+ app = create_app(config)
+ uvicorn.run(app, host=fe.host, port=fe.port)
diff --git a/serviette/frontend/static/index.html b/serviette/frontend/static/index.html
new file mode 100644
index 00000000..8bb46ce1
--- /dev/null
+++ b/serviette/frontend/static/index.html
@@ -0,0 +1,463 @@
+
+
+
+
+
+__APP_TITLE__
+
+
+
+
+
+
__APP_TITLE__
+
+
+
+
+
+
+
Indexed documents
+
+
+
Type part of a name and press Search. Leave it empty to list everything (when the index is small enough to show).
+
+
+
+
Settings
+
+
+
+
+
+
How many of the best-matching passages the assistant reads before answering a question.
+ More fragments give it more to work with on broad questions, at the cost of a slower answer.
+ Questions about a whole document or a comparison of documents read the files themselves and ignore this.
+
+
+
+
+
+
Ask anything about your documents
+
Answers are grounded in your indexed knowledge base. Each question is answered on its own, without memory of earlier ones.
+
+
+
+
+
+
+
+
+
diff --git a/serviette/indexer/__init__.py b/serviette/indexer/__init__.py
new file mode 100644
index 00000000..9d8f2805
--- /dev/null
+++ b/serviette/indexer/__init__.py
@@ -0,0 +1,6 @@
+"""Indexer package.
+
+Note: importing the Pathway graph (``serviette.indexer.graph``) pulls in the heavy
+``pathway`` dependency. The cache module is intentionally dependency-free so it
+can be imported and tested in isolation.
+"""
diff --git a/serviette/indexer/config.py b/serviette/indexer/config.py
new file mode 100644
index 00000000..af6c5102
--- /dev/null
+++ b/serviette/indexer/config.py
@@ -0,0 +1,13 @@
+"""Config loading/validation for the indexer command."""
+
+from __future__ import annotations
+
+from pathlib import Path
+
+from serviette.config.schema import ServietteConfig, load_config
+
+
+def load_indexer_config(path: str | Path) -> ServietteConfig:
+ """Load a config file and assert it has what the indexer needs."""
+
+ return load_config(path).for_indexer()
diff --git a/serviette/indexer/fingerprint.py b/serviette/indexer/fingerprint.py
new file mode 100644
index 00000000..eb92a124
--- /dev/null
+++ b/serviette/indexer/fingerprint.py
@@ -0,0 +1,226 @@
+"""Configuration fingerprint guarding deterministic re-execution.
+
+Chunking-related UDFs run with ``deterministic=True`` (see ``graph.py``), so
+on a retraction Pathway *re-runs* them instead of replaying stored results.
+That is only sound while they keep producing byte-identical outputs — which a
+config edit or a library upgrade between restarts can silently break: a
+document indexed under the old settings would be re-cut differently at
+deletion time, its old chunk ids would not match, and the vector DB would
+keep orphaned rows.
+
+To catch that, the indexer stores the full risk-relevant objects (not just a
+hash) in ``/serviette-fingerprint.json`` (at the top level of the
+working directory, never inside the engine's ``persistence/`` subdirectory —
+the engine logs an ERROR for every foreign entry in its directory):
+
+- the splitter config,
+- the embedder identity: type, model, ``document_prefix`` and every extra
+ key that shapes the vectors (``dimensions``, ``truncate_dim``,
+ ``output_dimensionality``, ``api_base``, ...) — never credentials, and
+ not the throughput knobs (batch size, capacity, retries),
+- versions of the libraries whose behavior shapes the outputs
+ (pathway, tiktoken, langchain_text_splitters),
+- the chunk-id scheme (``graph.CHUNK_ID_SCHEME``): the id derivation is a
+ deterministic UDF too, so rows written under an older scheme cannot be
+ retracted by a newer one.
+
+On startup the stored objects are compared with the current ones. The check
+does not depend on persistence being enabled: without it a restart re-indexes
+every document, and rows written under the old settings (other chunk ids)
+stay in the vector DB just the same. Any difference is reported as an
+explicit diff with a human-readable explanation of the risk, and the indexer
+refuses to start unless the user confirms — interactively on a TTY, or via
+``SERVIETTE_ACCEPT_FINGERPRINT_CHANGES=1`` in non-interactive deployments.
+Confirmation updates the stored fingerprint.
+"""
+
+from __future__ import annotations
+
+import json
+import logging
+import os
+import sys
+from typing import Any
+
+from serviette.config.schema import ServietteConfig
+
+logger = logging.getLogger(__name__)
+
+FINGERPRINT_FILENAME = "serviette-fingerprint.json"
+_FILENAME = FINGERPRINT_FILENAME # backwards-compatible alias
+ACCEPT_ENV = "SERVIETTE_ACCEPT_FINGERPRINT_CHANGES"
+_ACCEPT_ENV = ACCEPT_ENV # backwards-compatible alias
+
+_RISKS = {
+ "splitter": (
+ "Documents indexed before this change were cut with the OLD settings. "
+ "When such a document is later deleted or modified, its chunks will be "
+ "re-computed with the NEW settings, the chunk ids will not match, and "
+ "the old vectors will stay in the vector DB as orphans. Safe options: "
+ "revert the change, or re-index from scratch (drop the vector "
+ "collection and the persistence directory)."
+ ),
+ "embedder": (
+ "Vectors produced by different embedder models are not comparable: "
+ "queries embedded with the new model will rank previously indexed "
+ "documents nonsensically. Re-indexing from scratch is strongly "
+ "recommended."
+ ),
+ "parser": (
+ "Documents indexed before this change were parsed with the OLD "
+ "routing (e.g. a different PDF parser or video prompt), so their "
+ "text — and therefore their chunks and vectors — may differ from "
+ "what the NEW routing would produce. Edits/deletions of such "
+ "documents can leave orphaned vectors. If the affected formats "
+ "matter, re-index from scratch; note that defaults also resolve "
+ "from the environment (installed parser packages, API keys "
+ "present), so this can change without touching the config."
+ ),
+ "libraries": (
+ "A library upgrade can change tokenization and therefore chunk "
+ "boundaries — with the same orphaned-vectors risk as a splitter "
+ "config change. If unsure, re-index from scratch."
+ ),
+ "chunk_id": (
+ "This serviette version derives chunk ids differently from the one "
+ "that built the persisted state. Rows already in the vector DB carry "
+ "the OLD ids; when such a document is later deleted or modified, the "
+ "retraction is computed with the NEW scheme, misses them, and they "
+ "stay behind as orphans. Re-index from scratch (drop the vector "
+ "collection and the persistence directory)."
+ ),
+}
+
+
+def _library_version(module: str) -> str | None:
+ try:
+ import importlib.metadata
+
+ return importlib.metadata.version(module)
+ except Exception: # noqa: BLE001 - absent/odd packaging must not break startup
+ return None
+
+
+# Embedder keys that never belong in the fingerprint: credentials (must not
+# be written to disk), the server-side query prefix (does not shape stored
+# vectors) and throughput knobs (tuning them must not prompt a re-index).
+_EMBEDDER_EXCLUDED_KEYS = frozenset({
+ "api_key",
+ "aws_access_key_id",
+ "aws_secret_access_key",
+ "aws_session_token",
+ "default_headers",
+ "headers",
+ "query_prefix",
+ "batch_size",
+ "capacity",
+ "retries",
+})
+
+
+def _embedder_identity(config: ServietteConfig) -> dict[str, Any]:
+ """Everything in the embedder section that shapes the produced vectors.
+
+ Beyond ``type``/``model`` this is the open set of provider options that
+ change the output — ``dimensions`` (OpenAI, Bedrock Titan),
+ ``truncate_dim`` (sentence-transformers), ``output_dimensionality``
+ (Gemini), ``document_prefix`` (e5/bge), ``api_base`` (a different model
+ behind the same name) — so the section is taken wholesale minus the
+ exclusions above, rather than by allow-list that would miss the next key.
+ """
+ if not config.embedder:
+ return {}
+ dumped = config.embedder.model_dump()
+ identity = {
+ k: v
+ for k, v in dumped.items()
+ if k not in _EMBEDDER_EXCLUDED_KEYS and v is not None and v != ""
+ }
+ # Always present, even when unset, so old and new fingerprints line up.
+ identity.setdefault("type", dumped.get("type"))
+ identity.setdefault("model", dumped.get("model"))
+ return identity
+
+
+def build_fingerprint(config: ServietteConfig) -> dict[str, Any]:
+ from serviette.indexer.graph import CHUNK_ID_SCHEME, ParserRegistry
+
+ return {
+ "splitter": config.splitter.model_dump(),
+ "parser": ParserRegistry(config.parser).resolved_rules(),
+ "embedder": _embedder_identity(config),
+ "libraries": {
+ name: _library_version(name)
+ for name in ("pathway", "tiktoken", "langchain_text_splitters")
+ },
+ "chunk_id": {"scheme": CHUNK_ID_SCHEME},
+ }
+
+
+def _diff(stored: dict[str, Any], current: dict[str, Any]) -> list[str]:
+ lines: list[str] = []
+ for section, risk in _RISKS.items():
+ old, new = stored.get(section), current.get(section)
+ if old == new:
+ continue
+ lines.append(f"[{section}] stored: {json.dumps(old, sort_keys=True)}")
+ lines.append(f"[{section}] current: {json.dumps(new, sort_keys=True)}")
+ lines.append(f"[{section}] risk: {risk}")
+ return lines
+
+
+def _confirm(diff_lines: list[str]) -> bool:
+ if os.environ.get(_ACCEPT_ENV) == "1":
+ logger.warning(
+ "Fingerprint changes accepted via %s=1; proceeding.", _ACCEPT_ENV
+ )
+ return True
+ if sys.stdin.isatty():
+ answer = input(
+ "The indexing configuration changed since the last run (see above). "
+ "Proceed anyway, accepting these risks? Type 'yes' to continue: "
+ )
+ return answer.strip().lower() == "yes"
+ return False
+
+
+def check_fingerprint(config: ServietteConfig) -> None:
+ """Verify (and maintain) the stored fingerprint; may abort startup."""
+
+ directory = config.workdir()
+ directory.mkdir(parents=True, exist_ok=True)
+ path = directory / _FILENAME
+
+ current = build_fingerprint(config)
+ if not path.exists():
+ path.write_text(json.dumps(current, indent=2, sort_keys=True))
+ return
+
+ try:
+ stored = json.loads(path.read_text())
+ except (OSError, ValueError):
+ logger.warning("Unreadable fingerprint file %s; rewriting it.", path)
+ path.write_text(json.dumps(current, indent=2, sort_keys=True))
+ return
+
+ diff_lines = _diff(stored, current)
+ if not diff_lines:
+ return
+
+ logger.critical(
+ "The indexing configuration differs from the one this working "
+ "directory (%s) was indexed with:\n%s",
+ directory,
+ "\n".join(" " + line for line in diff_lines),
+ )
+ if not _confirm(diff_lines):
+ raise SystemExit(
+ "Refusing to start: the configuration change above can corrupt "
+ "incremental updates of already-indexed documents. Either revert "
+ "the change, re-index from scratch (drop the vector collection "
+ f"and the working directory {directory}), or set {_ACCEPT_ENV}=1 / "
+ "confirm interactively "
+ "to accept the risks."
+ )
+ path.write_text(json.dumps(current, indent=2, sort_keys=True))
+ logger.warning("Fingerprint updated to the current configuration.")
diff --git a/serviette/indexer/graph.py b/serviette/indexer/graph.py
new file mode 100644
index 00000000..a7bad7f2
--- /dev/null
+++ b/serviette/indexer/graph.py
@@ -0,0 +1,1028 @@
+"""Pathway graph construction for the indexer.
+
+Mirrors the llm-app ``document_indexing`` template as closely as the
+"external vector DB" goal allows, and reuses ``pathway.xpacks.llm`` parsers,
+splitters and embedders without modification.
+
+Pipeline
+--------
+``pw.io.fs.read(format="only_metadata")`` -> parse UDF (reads bytes from the
+path, extracts text via an xpack parser, memoised + persistently cached) ->
+splitter (xpack) -> flatten to one row per chunk -> embedder (xpack) ->
+vector-DB sink (duckdb / pgvector / milvus / qdrant / chroma / weaviate /
+pinecone / mongodb) — every sink is a native ``pw.io`` connector writing in
+snapshot/upsert mode, so retractions become real deletes in the target store.
+
+Deletion semantics
+------------------
+The parse UDF is registered ``deterministic=False`` (Pathway's default), so on a
+file removal Pathway re-emits the memoised parsed text *negated* and never
+re-reads the now-deleted bytes; the retraction flows through split/embed and the
+sink removes exactly the matching vectors.
+
+Parse caching
+-------------
+Cross-restart parse caching is delegated entirely to Pathway:
+``pw.udfs.DefaultCache`` stores results on disk (diskcache, LRU-bounded) under
+``/persistence/runtime_calls`` whenever persistence is enabled — which is
+the default. No caching machinery lives in serviette; disabling persistence also
+disables the parse cache (every restart re-fetches and re-parses).
+
+Failures
+--------
+One bad object must never kill the streaming pipeline, so a document whose
+bytes cannot be fetched (after ``indexer.fetch_retries`` retries with
+exponential backoff — remote sources fail transiently under bulk backfills)
+or parsed indexes as empty text, with an ERROR log naming the object. That
+empty result is final for this version of the object: a restart replays the
+persisted input through the UDF but discards the replayed output as already
+committed, so the only retry is a re-emission by the source — touch the file
+or re-upload the object once the cause is fixed.
+"""
+
+from __future__ import annotations
+
+import asyncio
+import fnmatch
+import hashlib
+import inspect
+import json
+import logging
+import os
+import time
+from pathlib import Path
+from typing import Any, ClassVar
+
+import pathway as pw
+
+from serviette.config.schema import ServietteConfig
+from serviette.indexer.sources import Fetcher, make_fetcher, read_source
+
+logger = logging.getLogger(__name__)
+
+
+# ---------------------------------------------------------------------------
+# Helpers for working with Pathway values imperatively
+# ---------------------------------------------------------------------------
+
+
+def _json_to_dict(value: Any) -> dict[str, Any]:
+ """Coerce a Pathway ``Json`` (or already-plain) value into a dict."""
+
+ if isinstance(value, dict):
+ return value
+ # pw.Json exposes the wrapped python value via ``.value`` / ``as_dict``.
+ if hasattr(value, "as_dict"):
+ return dict(value.as_dict())
+ if hasattr(value, "value"):
+ return dict(value.value)
+ return dict(value)
+
+
+def _human_size(n: int) -> str:
+ for unit in ("B", "KB", "MB", "GB"):
+ if n < 1024 or unit == "GB":
+ return f"{n:.0f} {unit}" if unit == "B" else f"{n:.1f} {unit}"
+ n /= 1024
+ return f"{n:.1f} GB" # pragma: no cover - loop always returns
+
+
+# ---------------------------------------------------------------------------
+# Parser dispatch (xpack parsers, called imperatively because only_metadata
+# means we hold paths, not bytes, in the graph)
+# ---------------------------------------------------------------------------
+
+
+class ParseError(RuntimeError):
+ """A document could not be fetched or parsed.
+
+ Raised by the fetch/parse helpers; the parse UDF catches it, logs the
+ object at ERROR level and indexes the document as empty text.
+ """
+
+
+# Exponential backoff for byte fetches: 1s, 2s, 4s, ... capped per attempt.
+_FETCH_BACKOFF_BASE = 1.0
+_FETCH_BACKOFF_CAP = 30.0
+
+
+def fetch_with_retries(fetcher: Fetcher, meta: dict, retries: int) -> tuple[bytes, str]:
+ """``fetcher.fetch(meta)`` with up to ``retries`` retries on any error.
+
+ Remote sources (Drive, S3, SharePoint) fail transiently — rate limits,
+ connection resets — exactly during the bulk backfills that hit them
+ hardest; a local file can be momentarily locked by whatever is writing
+ it. Without a retry each such blip used to become a silently empty
+ document. Raises :class:`ParseError` once the attempts are exhausted.
+ """
+
+ attempts = retries + 1
+ for attempt in range(1, attempts + 1):
+ try:
+ return fetcher.fetch(meta)
+ except Exception as exc: # backend-specific errors; retried uniformly
+ if attempt >= attempts:
+ raise ParseError(
+ f"could not fetch {meta.get('path') or meta.get('name') or meta} "
+ f"after {attempts} attempt(s): {exc}"
+ ) from exc
+ delay = min(_FETCH_BACKOFF_BASE * 2 ** (attempt - 1), _FETCH_BACKOFF_CAP)
+ logger.warning(
+ "Fetch of %s failed (attempt %d/%d): %s — retrying in %.0fs",
+ meta.get("path") or meta.get("name") or meta,
+ attempt,
+ attempts,
+ exc,
+ delay,
+ )
+ time.sleep(delay)
+ raise AssertionError("unreachable") # pragma: no cover
+
+
+class ParserRegistry:
+ """Rule-based, extension-dispatched xpack parsers.
+
+ We never implement our own parsing: each file is handed to the matching
+ ``pathway.xpacks.llm.parsers`` class. User rules (``parser:`` config) are
+ checked first; built-in defaults cover the rest with a keyless-first
+ policy — every format is enabled out of the box, routed to the best
+ parser that needs no API key, and a modality whose only parser requires
+ an absent key (audio -> OpenAI Whisper, video -> TwelveLabs) is skipped
+ with a warning instead of failing the pipeline.
+
+ Parsers expose their logic via ``__wrapped__(contents)`` returning
+ ``list[(text, metadata)]``; some are async, which we drive to completion
+ here so the enclosing UDF stays sync.
+ """
+
+ _SUFFIXES: ClassVar[dict[str, set[str]]] = {
+ "text": {".txt", ".md", ".markdown", ".text", ""},
+ "pdf": {".pdf"},
+ "image": {".png", ".jpg", ".jpeg", ".tif", ".tiff", ".bmp", ".webp"},
+ "audio": {".mp3", ".wav", ".m4a", ".flac", ".ogg", ".aac"},
+ "video": {".mp4", ".webm", ".mov", ".mkv", ".avi"},
+ # everything else -> office/unstructured
+ }
+
+ def __init__(self, rules: list | None = None) -> None:
+ self._rules = list(rules or [])
+ self._instances: dict[Any, Any] = {}
+ self._defaults: dict[str, tuple[str, dict]] = {}
+ self._warned: set[str] = set()
+
+ # -- keyless-first defaults ------------------------------------------------
+
+ @staticmethod
+ def _importable(module: str) -> bool:
+ import importlib.util
+
+ return importlib.util.find_spec(module) is not None
+
+ def _default_for(self, modality: str) -> tuple[str, dict]:
+ """Resolve the default (parser type, options) for a modality.
+
+ Preference order per modality: the best parser that runs without an
+ API key; a key-requiring parser only when its key is already present
+ in the environment; otherwise ``skip``.
+ """
+ if modality not in self._defaults:
+ kind: tuple[str, dict]
+ if modality == "text":
+ kind = ("utf8", {})
+ elif modality == "pdf":
+ # Best keyless first: docling (layout + tables) over pypdf (a
+ # core dependency, so PDFs parse in every install); the guard
+ # keeps even a broken environment skipping, never crashing.
+ if self._importable("docling"):
+ kind = ("docling", {})
+ elif self._importable("pypdf"):
+ kind = ("pypdf", {})
+ else:
+ kind = ("skip", {"reason": "PDF: install serviette[docling] (or pypdf)"})
+ elif modality == "image":
+ # PaddleOCR is local/keyless; vision parsers need an API key
+ # and are opt-in via explicit rules.
+ if self._importable("paddleocr"):
+ kind = ("paddle_ocr", {})
+ else:
+ kind = ("skip", {"reason": "images: install serviette[ocr] or configure vision_image"})
+ elif modality == "audio":
+ if os.environ.get("OPENAI_API_KEY"):
+ kind = ("whisper", {})
+ else:
+ kind = ("skip", {"reason": "audio: OPENAI_API_KEY not set (Whisper API)"})
+ elif modality == "video":
+ if os.environ.get("TWELVELABS_API_KEY"):
+ kind = ("twelvelabs_video", {})
+ else:
+ kind = ("skip", {"reason": "video: TWELVELABS_API_KEY not set"})
+ elif self._importable("unstructured"):
+ kind = ("unstructured", {})
+ else:
+ kind = ("skip", {"reason": "office formats: install serviette[docling]"})
+ self._defaults[modality] = kind
+ return self._defaults[modality]
+
+ # Modules each parser kind needs at construction time, with the install
+ # hint for the error message. Used to fail fast on explicit ``parser:``
+ # rules — a config that names an uninstallable parser should stop the
+ # indexer at startup, not crash the pipeline on the first matching file.
+ _KIND_DEPS: ClassVar[dict[str, tuple[str, str]]] = {
+ "docling": ("docling", 'pip install "serviette[docling]"'),
+ "pypdf": ("pypdf", "pip install pypdf"),
+ "unstructured": ("unstructured", 'pip install "serviette[docling]"'),
+ "paddle_ocr": ("paddleocr", 'pip install "serviette[ocr]"'),
+ }
+
+ def check_rule_deps(self) -> None:
+ """Validate that every explicit rule's parser can actually be built.
+
+ Two checks, both at startup so that a config mistake stops the
+ indexer with a plain message instead of failing inside the parse UDF
+ on the first matching file: the parser's package is installed, and
+ its constructor accepts the rule's options (a mistyped option name or
+ a value of the wrong type raises here). The built parser stays in the
+ registry's cache, so the first file pays nothing extra.
+ """
+
+ for rule in self._rules:
+ if rule.type == "skip":
+ continue
+ dep = self._KIND_DEPS.get(rule.type)
+ if dep and not self._importable(dep[0]):
+ module, hint = dep
+ raise ValueError(
+ f"parser rule {rule.match} -> {rule.type!r} needs the "
+ f"{module!r} package, which is not installed — {hint}"
+ )
+ try:
+ self._get(rule.type, dict(rule.options))
+ except Exception as exc: # any constructor failure is a config error here
+ raise ValueError(
+ f"parser rule {rule.match} -> {rule.type!r}: cannot build the "
+ f"parser with options {sorted(rule.options)}: {exc}"
+ ) from exc
+
+ def resolved_rules(self) -> list[dict]:
+ """Full routing picture (user rules + resolved defaults) for the
+ persistence fingerprint and logs. Credentials are never included."""
+
+ resolved = [
+ {
+ "match": r.match,
+ "type": r.type,
+ "options": {k: v for k, v in r.options.items() if "key" not in k.lower()},
+ }
+ for r in self._rules
+ ]
+ for modality in ["text", "pdf", "image", "audio", "video", "office"]:
+ kind, options = self._default_for(modality)
+ resolved.append({"match": [f""], "type": kind, "options": options})
+ return resolved
+
+ # -- dispatch ---------------------------------------------------------------
+
+ def _modality_for(self, suffix: str) -> str:
+ suffix = suffix.lower()
+ for modality, suffixes in self._SUFFIXES.items():
+ if suffix in suffixes:
+ return modality
+ return "office"
+
+ def _route(self, suffix: str, name: str, path: str = "") -> tuple[str, dict]:
+ """Pick (parser type, options) for a file.
+
+ A rule matches when any of its globs matches the file *name* or its
+ *path* (as the source reports it: absolute for ``fs``, the object key
+ for ``s3``, ...) — so ``*.pdf`` and ``scans/*.png`` both work. With
+ neither known, a synthetic ``x`` name keeps pure-extension
+ rules working.
+ """
+
+ candidates = [c for c in (name, path) if c] or [f"x{suffix}"]
+ for rule in self._rules:
+ if any(fnmatch.fnmatch(c, pat) for c in candidates for pat in rule.match):
+ return rule.type, dict(rule.options)
+ return self._default_for(self._modality_for(suffix))
+
+ def _get(self, kind: str, options: dict):
+ # Serialized, not tupled: option values may be dicts or lists (docling's
+ # ``pdf_pipeline_options``, unstructured's ``partition_kwargs``), which
+ # are not hashable.
+ key = (kind, json.dumps(options, sort_keys=True, default=repr))
+ if key not in self._instances:
+ from pathway.xpacks.llm import parsers
+
+ classes = {
+ "utf8": parsers.Utf8Parser,
+ "pypdf": parsers.PypdfParser,
+ "docling": parsers.DoclingParser,
+ "unstructured": parsers.UnstructuredParser,
+ "paddle_ocr": parsers.PaddleOCRParser,
+ "vision_image": parsers.ImageParser,
+ "vision_slide": parsers.SlideParser,
+ "whisper": parsers.AudioParser,
+ "twelvelabs_video": parsers.TwelveLabsVideoParser,
+ }
+ self._instances[key] = classes[kind](**options)
+ return self._instances[key]
+
+ def parse(
+ self, contents: bytes, suffix: str, name: str = "", path: str = ""
+ ) -> str:
+ kind, options = self._route(suffix, name, path)
+ if kind == "skip":
+ reason = options.get("reason", "no parser configured")
+ if reason not in self._warned:
+ self._warned.add(reason)
+ logger.warning("Skipping %r files — %s", suffix, reason)
+ return ""
+ options.pop("reason", None)
+ try:
+ parser = self._get(kind, options)
+ except Exception as exc: # noqa: BLE001 - one file must never kill the pipeline
+ # Routing guards make this unreachable for the defaults, and
+ # check_rule_deps() for explicit rules — this net catches what
+ # those cannot: lazy imports inside the xpack parsers, a default
+ # parser whose constructor fails in this environment (a missing
+ # model download, an unreachable API). Skip the format with one
+ # warning per reason instead of crashing the pipeline.
+ reason = f"parser {kind!r} unavailable: {exc}"
+ if reason not in self._warned:
+ self._warned.add(reason)
+ logger.warning("Skipping %r files — %s", suffix, reason)
+ return ""
+ try:
+ result = parser.__wrapped__(contents)
+ if inspect.isawaitable(result):
+ # Some xpack parsers return a bare Awaitable rather than a Coroutine.
+ result = asyncio.run(result) # type: ignore[arg-type]
+ except Exception as exc: # reported to the caller, not swallowed: see ParseError
+ raise ParseError(f"{kind!r} parser failed on {name or suffix!r}: {exc}") from exc
+ # result is list[(text, metadata)]; concatenate element texts — our own
+ # splitter re-chunks downstream. str() because some parsers return
+ # str-like objects (e.g. PaddleOCR's MarkdownResult), not plain str.
+ return "\n\n".join(str(text) for text, _meta in result if text)
+
+
+# ---------------------------------------------------------------------------
+# Embedder / splitter builders (xpack)
+# ---------------------------------------------------------------------------
+
+
+# OpenAI SDK *client* constructor options the server-side embedder accepts in
+# the same ``embedder`` section; the xpack has no way to take them (it builds
+# the client itself), so the indexer must refuse them instead of crashing on
+# the first chunk. ``base_url`` (own message) and ``timeout`` (also a valid
+# per-call parameter of embeddings.create) are handled separately.
+_OPENAI_CLIENT_ONLY_KEYS = frozenset(
+ {"organization", "project", "max_retries", "default_headers", "default_query"}
+)
+
+
+def build_xpack_embedder(cfg) -> pw.UDF:
+ """Construct a ``pathway.xpacks.llm.embedders`` UDF from config.
+
+ A ``DefaultCache`` strategy is attached so identical chunks are not
+ re-embedded across runs (it uses the persistence layer when enabled).
+ """
+
+ if cfg.type == "mock":
+ # Test-only deterministic embedder; runs without any provider/credentials.
+ from serviette.testing import build_mock_embedder
+
+ return build_mock_embedder()
+
+ from pathway.xpacks.llm import embedders
+
+ cache_strategy = pw.udfs.DefaultCache()
+ extra = {
+ k: v
+ for k, v in cfg.model_dump(
+ exclude={"type", "model", "api_key", "query_prefix", "document_prefix"}
+ ).items()
+ if v is not None
+ }
+ # ``retries: N`` opts into engine-level exponential backoff — the way to
+ # survive provider TPM limits on cheap API tiers, where the SDK's couple
+ # of quick retries give up long before the minute window resets.
+ retries = extra.pop("retries", None)
+ common: dict[str, Any] = {"cache_strategy": cache_strategy, **extra}
+ if retries:
+ common["retry_strategy"] = pw.udfs.ExponentialBackoffRetryStrategy(
+ max_retries=int(retries)
+ )
+ if cfg.model:
+ common["model"] = cfg.model
+
+ if cfg.type == "openai":
+ if "base_url" in common:
+ # The xpack forwards extra keys to ``embeddings.create`` (where
+ # ``base_url`` is not a parameter) and builds its client without
+ # one, so this would fail on the first chunk.
+ raise ValueError(
+ "embedder type 'openai' does not accept 'base_url' on the indexer. "
+ "For an OpenAI-compatible endpoint set the OPENAI_BASE_URL environment "
+ "variable for both the indexer and the server, or use "
+ "'type: litellm' with 'model: openai/' and 'api_base: '."
+ )
+ client_only = sorted(_OPENAI_CLIENT_ONLY_KEYS & common.keys())
+ if client_only:
+ # Same failure mode as base_url: the server routes these to the
+ # AsyncOpenAI constructor, the xpack would pass them to
+ # embeddings.create and crash on the first chunk.
+ raise ValueError(
+ f"embedder type 'openai' does not accept {client_only} on the "
+ "indexer (pathway's OpenAIEmbedder builds its own client and "
+ "forwards extra keys to embeddings.create). Alternatives: "
+ "OPENAI_ORG_ID / OPENAI_PROJECT_ID environment variables for "
+ "organization/project; 'retries: N' for engine-level backoff "
+ "instead of max_retries; 'type: litellm' for custom headers."
+ )
+ return embedders.OpenAIEmbedder(api_key=cfg.api_key, **common)
+ if cfg.type == "litellm":
+ if not cfg.model:
+ raise ValueError(
+ "embedder type 'litellm' requires a 'model' with a provider prefix, "
+ "e.g. 'openrouter/qwen/qwen3-embedding-8b' (LiteLLM has no default)."
+ )
+ return embedders.LiteLLMEmbedder(api_key=cfg.api_key, **common)
+ if cfg.type in {"sentence_transformer", "sentencetransformer"}:
+ model = common.pop("model", None) or "sentence-transformers/all-MiniLM-L6-v2"
+ common.pop("cache_strategy", None) # local model; caching adds little
+ udf = embedders.SentenceTransformerEmbedder(model=model, **common)
+ # Local models are deterministic: the engine may re-run them on
+ # retraction (cheap CPU) instead of memoizing every vector in RAM.
+ # The xpack constructor doesn't expose the flag (upstream PR pending),
+ # so it is set on the built UDF; the engine reads it at expression
+ # build time. API embedders stay memoized — a re-call costs money and
+ # is not guaranteed bit-stable. Model changes across restarts are
+ # guarded by the persistence fingerprint.
+ udf.deterministic = True
+ return udf
+ if cfg.type == "gemini":
+ return embedders.GeminiEmbedder(api_key=cfg.api_key, **common)
+ if cfg.type == "bedrock":
+ # The xpack spells the model ``model_id``; the schema's ``model`` must
+ # not fall through into its ignored kwargs (the server reads ``model``).
+ model = common.pop("model", None)
+ if model is not None:
+ common.setdefault("model_id", model)
+ return embedders.BedrockEmbedder(**common)
+ raise ValueError(f"Unsupported embedder type: {cfg.type!r}")
+
+
+def build_xpack_splitter(cfg):
+ """Construct an xpack splitter. ``token_count`` is the default."""
+
+ from pathway.xpacks.llm import splitters
+
+ class TailMergingTokenCountSplitter(splitters.TokenCountSplitter):
+ """TokenCountSplitter emits a trailing remainder even when it is far
+ below min_tokens; a title-ish tail line then becomes a near-empty
+ chunk that outranks real content. Fold such a tail into the previous
+ chunk instead (single-chunk texts are left untouched)."""
+
+ def chunk(
+ self, text: str, metadata: dict = {}, **kwargs # noqa: B006 - mirrors the xpack splitter signature
+ ) -> list[tuple[str, dict]]:
+ chunks = super().chunk(text, metadata, **kwargs)
+ if len(chunks) >= 2 and len(chunks[-1][0]) < 100:
+ text_prev, meta_prev = chunks[-2]
+ chunks[-2] = (text_prev.rstrip() + "\n" + chunks[-1][0], meta_prev)
+ chunks.pop()
+ return chunks
+
+ # Extra keys are forwarded to the xpack splitter constructor verbatim
+ # (``min_tokens``/``encoding_name`` for token_count, ``separators``/
+ # ``model_name``/... for recursive). An unknown key fails here, at
+ # startup, instead of being silently ignored — the fingerprint stores the
+ # section, so a no-op key would still prompt for a re-index when changed.
+ extra = {
+ k: v
+ for k, v in cfg.model_dump(exclude={"type", "chunk_size", "chunk_overlap"}).items()
+ if v is not None
+ }
+ if cfg.type in {"token_count", "tokencount"}:
+ # TokenCountSplitter is token-based; map chunk_size -> max_tokens.
+ # ``chunk_overlap`` does not apply (documented: used by recursive).
+ return TailMergingTokenCountSplitter(max_tokens=cfg.chunk_size, **extra)
+ if cfg.type in {"recursive", "recursive_character"}:
+ return splitters.RecursiveSplitter(
+ chunk_size=cfg.chunk_size, chunk_overlap=cfg.chunk_overlap, **extra
+ )
+ if cfg.type in {"null", "none"}:
+ if extra:
+ raise TypeError(f"splitter type 'null' takes no options, got: {sorted(extra)}")
+ return splitters.NullSplitter()
+ raise ValueError(f"Unsupported splitter type: {cfg.type!r}")
+
+
+# ---------------------------------------------------------------------------
+# Graph construction
+# ---------------------------------------------------------------------------
+
+
+def build_graph(
+ config: ServietteConfig,
+ *,
+ embedder: pw.UDF | None = None,
+ splitter=None,
+) -> pw.Table:
+ """Build the indexing graph and return the final embeddings table.
+
+ ``embedder``/``splitter`` can be injected (tests pass a mock embedder);
+ otherwise they are built from ``config``.
+ """
+
+ config.for_indexer()
+
+ registry = ParserRegistry(config.parser)
+ registry.check_rule_deps()
+ splitter = splitter if splitter is not None else build_xpack_splitter(config.splitter)
+ embedder = embedder if embedder is not None else build_xpack_embedder(config.embedder)
+
+ # -- parse UDF factory ---------------------------------------------------
+ # deterministic=False => memoised; never re-runs on retraction (the source
+ # object is gone). DefaultCache persists parsed text across restarts on
+ # disk when persistence is enabled (LRU-bounded; size from config). The
+ # fetcher makes byte retrieval source-specific (local path vs Drive download).
+ cache_strategy = pw.udfs.DefaultCache(
+ size_limit=config.indexer.parse_cache_size_gb * 2**30
+ )
+
+ fetch_retries = config.indexer.fetch_retries
+
+ def make_parse_udf(fetcher: Fetcher):
+ @pw.udf(deterministic=False, cache_strategy=cache_strategy)
+ def parse_document(metadata: pw.Json) -> str:
+ meta = _json_to_dict(metadata)
+ # Only gdrive reports a ``name``; every other source reports the
+ # object's ``path`` (absolute fs path, S3 key, server-relative
+ # SharePoint URL, in-filesystem path). Rules match on either.
+ path = str(meta.get("path") or "")
+ name = str(meta.get("name") or os.path.basename(path))
+ try:
+ contents, suffix = fetch_with_retries(fetcher, meta, fetch_retries)
+ # One line before and one after: a large PDF can take
+ # minutes, during which the engine logs nothing — these lines
+ # are what tells the user (and ``serviette up``, which reads
+ # them to tell "working" from "stuck") that the indexer is busy.
+ logger.info("parsing %s (%s)", name or path, _human_size(len(contents)))
+ started = time.monotonic()
+ text = registry.parse(contents, suffix, name, path)
+ logger.info(
+ "parsed %s: %d chars in %.1fs", name or path, len(text), time.monotonic() - started
+ )
+ return text
+ except ParseError as exc:
+ # One bad object must never kill the pipeline: index it as
+ # empty and say so loudly, per object (not once per reason).
+ # There is no automatic retry beyond fetch_retries — see the
+ # module docstring ("Failures").
+ logger.error(
+ "%s — the document is indexed as EMPTY. Fix the cause, "
+ "then touch the file / re-upload the object to retry it.",
+ exc,
+ )
+ return ""
+
+ return parse_document
+
+ # Pure-function whitelist: for these splitter types re-running the UDF is
+ # guaranteed to reproduce the original chunks, so the engine need not
+ # memoize its outputs (a full extra copy of the corpus in RAM). Guarded
+ # against config/library drift by the persistence fingerprint (see
+ # fingerprint.py). Unknown/future splitter types fall back to memoization.
+ _PURE_SPLITTERS = {"token_count", "tokencount", "recursive", "recursive_character", "null", "none"}
+ split_is_pure = config.splitter.type in _PURE_SPLITTERS
+
+ @pw.udf(deterministic=split_is_pure)
+ def split_text(text: str) -> list[str]:
+ if not text:
+ return []
+ return [chunk for chunk, _meta in splitter.chunk(text)]
+
+ @pw.udf(deterministic=True)
+ def make_id(key_json: str, text: str) -> str:
+ # key_json is the canonical per-document serialization from
+ # _metadata_key_json (the observation timestamp excluded), so the id
+ # is reproducible for (document version, text) across restarts.
+ digest = hashlib.sha256()
+ digest.update(key_json.encode("utf-8"))
+ digest.update(b"\x00")
+ digest.update(text.encode("utf-8"))
+ return digest.hexdigest()
+
+ # -- per-source: read (only_metadata) -> parse ----------------------------
+ # Each source gets its own fetcher-bound parse UDF; parsed tables share the
+ # (_metadata, text) schema and are concatenated before splitting/embedding.
+ parsed_tables: list[pw.Table] = []
+ for i, src in enumerate(config.sources):
+ table = read_source(src, name=f"source_{i}")
+ parse_document = make_parse_udf(make_fetcher(src))
+ parsed_tables.append(
+ table.select(_metadata=pw.this._metadata, text=parse_document(pw.this._metadata))
+ )
+
+ parsed = (
+ parsed_tables[0]
+ if len(parsed_tables) == 1
+ else pw.Table.concat_reindex(*parsed_tables)
+ )
+
+ # -- split -> flatten -> embed -------------------------------------------
+ # The canonical metadata JSONs (the stored form and the chunk-id key) are
+ # computed once per DOCUMENT here; flatten then replicates the references
+ # per chunk instead of re-serializing the same dict for every chunk.
+ chunked = parsed.select(
+ _metadata=pw.this._metadata,
+ meta_json=_metadata_as_json(pw.this._metadata),
+ key_json=_metadata_key_json(pw.this._metadata),
+ chunk=split_text(pw.this.text),
+ )
+ exploded = chunked.flatten(pw.this.chunk)
+ # Asymmetric-retrieval models (e5, bge) want a marker prepended to the
+ # embedded text only; chunk_id and the stored text stay prefix-free.
+ assert config.embedder is not None # enforced by for_indexer()
+ doc_prefix = config.embedder.document_prefix
+ embed_input = (
+ pw.apply_with_type(lambda t, _p=doc_prefix: _p + t, str, pw.this.chunk)
+ if doc_prefix
+ else pw.this.chunk
+ )
+ # Pathway reserves the column name "id", so the chunk's primary key lives in
+ # "chunk_id"; the sinks map it to each backend's id/primary-key field.
+ embedded = exploded.select(
+ chunk_id=make_id(pw.this.key_json, pw.this.chunk),
+ text=pw.this.chunk,
+ metadata=pw.this._metadata,
+ metadata_json=pw.this.meta_json,
+ embedding=embedder(embed_input),
+ )
+
+ _write_sink(embedded, config)
+ return embedded
+
+
+# ---------------------------------------------------------------------------
+# Sinks
+# ---------------------------------------------------------------------------
+
+
+def _write_sink(table: pw.Table, config: ServietteConfig) -> None:
+ """Route the embedded table to the configured backend sink.
+
+ ``table`` carries the metadata twice (native ``metadata`` Json and the
+ canonical ``metadata_json`` string); each sink selects exactly the columns
+ its backend stores, so nothing is written twice and backends that key rows
+ internally (qdrant, mongodb) don't carry a dead ``chunk_id`` field.
+ """
+
+ vdb = config.vector_db
+ assert vdb is not None # enforced by for_indexer()
+ # Backends storing native JSON metadata, keyed by chunk_id.
+ plain = table.select(
+ chunk_id=pw.this.chunk_id,
+ text=pw.this.text,
+ metadata=pw.this.metadata,
+ embedding=pw.this.embedding,
+ )
+ # Backends restricted to scalar record metadata: the JSON string form.
+ jsonified = table.select(
+ chunk_id=pw.this.chunk_id,
+ text=pw.this.text,
+ metadata=pw.this.metadata_json,
+ embedding=pw.this.embedding,
+ )
+ if vdb.type == "duckdb":
+ _write_duckdb(jsonified, vdb)
+ elif vdb.type == "pgvector":
+ _write_pgvector(plain, vdb)
+ elif vdb.type == "milvus":
+ _write_milvus(plain, vdb)
+ elif vdb.type == "qdrant":
+ # No chunk_id: the sink keys points internally; payload = text + metadata.
+ _write_qdrant(plain.without(pw.this.chunk_id), vdb)
+ elif vdb.type == "chroma":
+ _write_chroma(jsonified, vdb)
+ elif vdb.type == "weaviate":
+ _write_weaviate(jsonified, vdb)
+ elif vdb.type == "pinecone":
+ _write_pinecone(jsonified, vdb)
+ elif vdb.type == "mongodb":
+ # No chunk_id: snapshot mode keys documents by the internal _id.
+ _write_mongodb(plain.without(pw.this.chunk_id), vdb)
+ else: # pragma: no cover - guarded by schema
+ raise ValueError(f"Unsupported vector_db type: {vdb.type!r}")
+
+
+@pw.udf(deterministic=True)
+def _metadata_as_json(metadata: pw.Json) -> str:
+ """Serialize the metadata dict to one canonical JSON string.
+
+ Computed once per *document* (before chunk flattening) and reused for
+ every chunk as the string form stored by backends whose record metadata
+ must be scalar (duckdb/chroma/weaviate/pinecone). Keeps every field the
+ connector emitted, including ``seen_at`` (the server's ``last_indexed_at``
+ comes from it). sort_keys/ensure_ascii keep it byte-stable.
+ """
+
+ return json.dumps(_json_to_dict(metadata), sort_keys=True, ensure_ascii=True)
+
+
+# Metadata fields excluded from the chunk-id key. ``seen_at`` is the moment
+# the connector *observed* the object, not a property of the object: it
+# changes on every cold start (no persistence, or a dropped persistence
+# directory) while the document itself does not. With it in the key, every
+# such restart would write the whole corpus next to the previous copy instead
+# of upserting over it. Every other field stays in the key on purpose: any
+# field whose change makes the connector re-emit the row must make the new
+# key differ from the old one, so that a modification is a clean DELETE of
+# the old key plus INSERT of the new one in the snapshot sinks — never a
+# -1/+1 pair on the same key within one batch.
+_KEY_EXCLUDED_FIELDS = frozenset({"seen_at"})
+
+# Bump when the chunk-id derivation changes. Recorded in the persistence
+# fingerprint: ``make_id`` is deterministic, so on a retraction Pathway
+# recomputes ids with the *current* function — a different scheme than the
+# one the stored rows were written with leaves orphans behind.
+CHUNK_ID_SCHEME = 2
+
+
+@pw.udf(deterministic=True)
+def _metadata_key_json(metadata: pw.Json) -> str:
+ """The document-identity part of the chunk id: the stored metadata minus
+ the observation-only fields (see ``_KEY_EXCLUDED_FIELDS``)."""
+
+ meta = {
+ k: v for k, v in _json_to_dict(metadata).items() if k not in _KEY_EXCLUDED_FIELDS
+ }
+ return json.dumps(meta, sort_keys=True, ensure_ascii=True)
+
+
+def _write_pgvector(table: pw.Table, vdb) -> None:
+ """Write to Postgres/pgvector in snapshot mode so retractions delete rows.
+
+ The target table must exist with an ``embedding vector(n)`` column (see
+ docs/README "Config reference"). ``output_table_type='snapshot'`` keeps the
+ table as an exact replica of the current chunk set, issuing real
+ INSERT/UPDATE/DELETE keyed by ``id``.
+ """
+
+ settings = _libpq_settings(vdb.connection_string)
+ pw.io.postgres.write(
+ table,
+ settings,
+ vdb.table,
+ output_table_type="snapshot",
+ primary_key=[table.chunk_id],
+ )
+
+
+def _write_milvus(table: pw.Table, vdb) -> None:
+ pw.io.milvus.write(
+ table,
+ uri=vdb.resolved_uri(),
+ collection_name=vdb.collection,
+ primary_key=table.chunk_id,
+ )
+
+
+def _write_duckdb(table: pw.Table, vdb) -> None:
+ """Write to an embedded DuckDB file via Pathway's native connector.
+
+ Snapshot mode keyed by ``chunk_id`` keeps the table an exact replica of the
+ current chunk set (real upserts/deletes). Embeddings land as native
+ ``DOUBLE[]`` lists that the server queries in-database with
+ ``list_cosine_similarity``. The metadata travels as a JSON string: DuckDB
+ compares identifiers case-insensitively and stores ``pw.Json`` as text
+ anyway, and one explicit column keeps the accessor symmetric with the
+ other backends.
+ """
+
+ out = table
+ kwargs: dict[str, Any] = {}
+ # Release the single-writer file lock between minibatches so a separate
+ # server process can answer queries while the streaming indexer runs
+ # (pathway builds with detach_between_batches; the accessor retries through the brief lock
+ # windows). Older builds keep the previous hold-the-lock behavior.
+ if "detach_between_batches" in inspect.signature(pw.io.duckdb.write).parameters:
+ kwargs["detach_between_batches"] = True
+ else:
+ logger.warning(
+ "This pathway build lacks duckdb detach_between_batches: while a "
+ "streaming indexer runs, a separate server process cannot read "
+ "the database file."
+ )
+ pw.io.duckdb.write(
+ out,
+ table_name=vdb.table,
+ database=vdb.path,
+ output_table_type="snapshot",
+ primary_key=[out.chunk_id],
+ init_mode="create_if_not_exists",
+ **kwargs,
+ )
+
+
+def _write_qdrant(table: pw.Table, vdb) -> None:
+ """Write points to a pre-created Qdrant collection (schema-driven sink).
+
+ The sink keys points internally per row, so additions/updates/deletions map
+ to native upserts/deletes. It binds each of the collection's named vector
+ slots to the same-named table column: the ``embedding`` column feeds the
+ dense slot ``prepare._prepare_qdrant`` created; ``text`` and ``metadata``
+ are not vector slots, so they become the point payload.
+ """
+
+ pw.io.qdrant.write(
+ table,
+ vdb.grpc_url(),
+ vdb.collection,
+ api_key=vdb.api_key,
+ )
+
+
+def _write_chroma(table: pw.Table, vdb) -> None:
+ """Write to a pre-existing ChromaDB collection (cosine ``hnsw:space``)."""
+
+ out = table
+ pw.io.chroma.write(
+ out,
+ vdb.collection,
+ primary_key=out.chunk_id,
+ embedding=out.embedding,
+ document=out.text,
+ metadata_columns=[out.metadata],
+ host=vdb.host,
+ port=vdb.port,
+ ssl=vdb.ssl,
+ headers=vdb.headers,
+ tenant=vdb.tenant,
+ database=vdb.database,
+ )
+
+
+def _write_weaviate(table: pw.Table, vdb) -> None:
+ """Write to a pre-existing Weaviate collection (object vector + properties)."""
+
+ out = table
+ pw.io.weaviate.write(
+ out,
+ vdb.collection,
+ primary_key=out.chunk_id,
+ vector=out.embedding,
+ http_host=vdb.http_host,
+ http_port=vdb.http_port,
+ http_secure=vdb.http_secure,
+ api_key=vdb.api_key,
+ )
+
+
+def _write_pinecone(table: pw.Table, vdb) -> None:
+ """Write to a pre-existing Pinecone index (dimension must match)."""
+
+ out = table
+ pw.io.pinecone.write(
+ out,
+ vdb.index_name,
+ primary_key=out.chunk_id,
+ vector=out.embedding,
+ api_key=vdb.api_key,
+ host=vdb.host,
+ namespace=vdb.namespace,
+ metadata_columns=[out.text, out.metadata],
+ )
+
+
+def _write_mongodb(table: pw.Table, vdb) -> None:
+ """Write documents to MongoDB / Atlas in snapshot mode.
+
+ One document per chunk with the embedding as a BSON number array — exactly
+ the shape Atlas Vector Search queries with ``$vectorSearch`` (the user
+ creates the ``vectorSearch`` index; Pathway cannot know the dimension).
+ """
+
+ pw.io.mongodb.write(
+ table,
+ connection_string=vdb.connection_string,
+ database=vdb.database,
+ collection=vdb.collection,
+ output_table_type="snapshot",
+ )
+
+
+def _libpq_settings(connection_string: str) -> dict[str, Any]:
+ """Parse a ``postgresql://`` URL into a pw.io.postgres settings dict.
+
+ Query parameters (``?sslmode=require&connect_timeout=5``) are libpq
+ keywords and pass through verbatim — the server side (asyncpg) honours
+ them from the same string, so the indexer must too, or a TLS-only
+ database accepts queries and rejects the writer.
+ """
+
+ from urllib.parse import parse_qsl, unquote, urlparse
+
+ parsed = urlparse(connection_string)
+ settings: dict[str, Any] = dict(parse_qsl(parsed.query, keep_blank_values=False))
+ if parsed.hostname:
+ settings["host"] = parsed.hostname
+ if parsed.port:
+ settings["port"] = parsed.port
+ if parsed.username:
+ settings["user"] = unquote(parsed.username)
+ if parsed.password:
+ settings["password"] = unquote(parsed.password)
+ dbname = parsed.path.lstrip("/")
+ if dbname:
+ settings["dbname"] = dbname
+ return settings
+
+
+# ---------------------------------------------------------------------------
+# Run
+# ---------------------------------------------------------------------------
+
+
+def prepare_persistence_dir(config: ServietteConfig) -> Path:
+ """Create the engine's persistence directory and return it.
+
+ ``/persistence`` belongs to the Pathway engine alone: it scans
+ its directory and logs an ERROR for every entry it did not write, so
+ serviette's own artifacts (the fingerprint) stay at the top level of the
+ working directory, never in here.
+ """
+
+ engine_dir = config.persistence_dir()
+ engine_dir.mkdir(parents=True, exist_ok=True)
+ return engine_dir
+
+
+def persistence_config(config: ServietteConfig):
+ """Build a ``pw.persistence.Config`` (or None) from config.
+
+ Enabling persistence prevents re-embedding unchanged documents on restart:
+ Pathway replays operator state and the embedder's ``DefaultCache`` is backed
+ by this layer.
+ """
+
+ if not config.persistence.enabled:
+ return None
+ backend = pw.persistence.Backend.filesystem(str(prepare_persistence_dir(config)))
+ return pw.persistence.Config(backend)
+
+
+def run_indexer(
+ config: ServietteConfig, *, prepare: bool = True, **build_kwargs: Any
+) -> None:
+ """Prepare the backend, build the graph and run it (streaming).
+
+ ``prepare=False`` is used by spawned worker processes: the spawn parent
+ has already created the target (see ``serviette.indexer.main``).
+ """
+
+ if config.pathway_license_key:
+ pw.set_license_key(config.pathway_license_key)
+ config.for_indexer()
+ if prepare:
+ # Refuse to run against persisted state built with an incompatible
+ # config (chunking drift corrupts retractions — see fingerprint.py).
+ from serviette.indexer.fingerprint import check_fingerprint
+
+ check_fingerprint(config)
+ # Create the target table/collection/index if missing — the connectors
+ # auto-create only for duckdb and qdrant (see prepare.py).
+ from serviette.indexer.prepare import prepare_backend
+
+ prepare_backend(config)
+ build_graph(config, **build_kwargs)
+ run_kwargs: dict[str, Any] = {}
+ if config.indexer.udf_cache_directory:
+ # Spill the non-deterministic UDF memo (parsed texts) to disk
+ # instead of RAM (Pathway feature; ignored on older builds with
+ # a warning so configs stay portable).
+ if "udf_cache_directory" in inspect.signature(pw.run).parameters:
+ run_kwargs["udf_cache_directory"] = config.indexer.udf_cache_directory
+ else:
+ logger.warning(
+ "indexer.udf_cache_directory is set but this pathway build "
+ "does not support pw.run(udf_cache_directory=...); the UDF "
+ "cache stays in memory."
+ )
+ if config.indexer.monitoring_http_port:
+ # The engine's own observability server (Rust, per worker process):
+ # GET /status and GET /metrics (Prometheus) on 127.0.0.1:(base + id).
+ os.environ["PATHWAY_MONITORING_HTTP_PORT"] = str(
+ config.indexer.monitoring_http_port
+ )
+ run_kwargs["with_http_server"] = True
+ # The interactive monitoring dashboard redraws the terminal with escape
+ # codes; under `serviette up` both children share one console and it would
+ # wipe the server's logs. Metrics live on the HTTP monitoring server
+ # (indexer.monitoring_http_port) instead.
+ pw.run(
+ monitoring_level=pw.MonitoringLevel.NONE,
+ persistence_config=persistence_config(config),
+ **run_kwargs,
+ )
diff --git a/serviette/indexer/main.py b/serviette/indexer/main.py
new file mode 100644
index 00000000..897319fc
--- /dev/null
+++ b/serviette/indexer/main.py
@@ -0,0 +1,173 @@
+"""Entrypoint for ``serviette indexer``.
+
+Multi-worker runs: when ``indexer.workers`` > 1 the process prepares the
+vector-DB target once, then re-executes itself through
+``pathway spawn --processes N`` (worker *processes*, one thread each) — the
+official Pathway mechanism, which wires up the inter-process coordination env
+(``PATHWAY_PROCESS_ID`` etc.). Spawned children detect that env and skip both
+the re-spawn and the (already done) backend preparation. Signals sent to the
+parent are forwarded to the spawner *and* the workers (see
+:func:`run_forwarding_signals`) so a stop never leaves orphans behind.
+"""
+
+from __future__ import annotations
+
+import argparse
+import contextlib
+import logging
+import os
+import re
+import signal
+import subprocess
+import sys
+import time
+
+from serviette.config.schema import require_openai_credentials, require_source_dirs
+from serviette.indexer.config import load_indexer_config
+from serviette.indexer.graph import run_indexer
+
+logger = logging.getLogger(__name__)
+
+
+_KILL_GRACE = 15.0
+
+
+def run_forwarding_signals(command: list[str], *, grace: float = _KILL_GRACE) -> int:
+ """Run ``command`` to completion, forwarding SIGTERM/SIGINT to its whole
+ process group; returns its exit code.
+
+ ``pathway spawn`` starts the worker processes as plain children and
+ installs no signal handlers of its own, so a SIGTERM delivered to *this*
+ process (``serviette up``, systemd, ``docker stop``) used to kill just
+ the Python waiting on it and leave the spawner and every worker running
+ — still writing to the store, still holding the DuckDB lock and the
+ inter-worker ports. The child gets its own session so a terminal Ctrl-C
+ is not delivered to it twice (once by the terminal, once forwarded);
+ whatever signal reaches us is sent to the child's group, which covers
+ the spawner and the workers alike, and escalates to SIGKILL after
+ ``grace`` seconds.
+ """
+
+ proc = subprocess.Popen(command, start_new_session=True)
+ forwarded: list[int] = []
+
+ def _forward(signum, _frame):
+ forwarded.append(signum)
+ try:
+ os.killpg(proc.pid, signum)
+ except ProcessLookupError:
+ pass
+
+ previous = {
+ sig: signal.signal(sig, _forward) for sig in (signal.SIGTERM, signal.SIGINT)
+ }
+ kill_at: float | None = None
+ try:
+ while True:
+ try:
+ return proc.wait(timeout=0.5)
+ except subprocess.TimeoutExpired:
+ pass
+ if not forwarded:
+ continue
+ if kill_at is None:
+ kill_at = time.monotonic() + grace
+ elif time.monotonic() >= kill_at:
+ logger.warning("worker processes did not stop in %.0fs; killing them", grace)
+ with contextlib.suppress(ProcessLookupError):
+ os.killpg(proc.pid, signal.SIGKILL)
+ return proc.wait()
+ finally:
+ for sig, handler in previous.items():
+ signal.signal(sig, handler)
+
+
+def _spawn_workers(workers: int, argv: list[str], first_port: int = 10000) -> int:
+ logger.info("Spawning %d Pathway worker processes via `pathway spawn`", workers)
+ command = [
+ sys.executable,
+ "-m",
+ "pathway",
+ "spawn",
+ "--processes",
+ str(workers),
+ "--threads",
+ "1",
+ "--first-port",
+ str(first_port),
+ sys.executable,
+ "-m",
+ "serviette.cli",
+ "indexer",
+ *argv,
+ ]
+ return run_forwarding_signals(command)
+
+
+class _DropIdleMonitoringLines(logging.Filter):
+ """Hide the engine's heartbeat lines that report no work.
+
+ ``pathway_engine.connectors.monitoring`` logs every output flush and
+ every input poll — about ten lines a minute on an idle index, all saying
+ "0 entries". The same lines with a non-zero count are the user's only
+ progress indicator ("source_0: 5 entries … sent to the engine", "Done
+ writing 5 entries"), so those stay."""
+
+ _IDLE = re.compile(r"Done writing 0 entries|: 0 entries \(")
+
+ def filter(self, record: logging.LogRecord) -> bool:
+ return not self._IDLE.search(record.getMessage())
+
+
+def main(argv: list[str] | None = None) -> None:
+ parser = argparse.ArgumentParser(prog="serviette indexer")
+ parser.add_argument("--config", required=True, help="Path to the YAML config file")
+ parser.add_argument(
+ "--log-level", default="INFO", help="Logging level (default: INFO)"
+ )
+ args = parser.parse_args(argv)
+
+ logging.basicConfig(level=args.log_level.upper())
+ if logging.getLogger().getEffectiveLevel() > logging.DEBUG:
+ # The engine reports every persisted snapshot chunk at INFO
+ # ("Persisting a chunk of 105 entries (2100 -> 551 bytes)") — a line
+ # every few seconds even when nothing changes, and nothing a user can
+ # act on. Keep it, and the idle heartbeats, for --log-level DEBUG only.
+ logging.getLogger("pathway_engine.persistence").setLevel(logging.WARNING)
+ logging.getLogger("pathway_engine.connectors.monitoring").addFilter(
+ _DropIdleMonitoringLines()
+ )
+ config = load_indexer_config(args.config)
+ # A mistyped folder must stop here with a plain message, not become an
+ # empty index (the fs connector watches a missing path without complaint).
+ require_source_dirs(config)
+ require_openai_credentials(config, roles=("embedder",))
+
+ inside_spawn = "PATHWAY_PROCESS_ID" in os.environ
+ if config.indexer.workers > 1 and not inside_spawn:
+ # Check the configuration fingerprint and prepare the target once, in
+ # the parent, before any worker starts writing.
+ from serviette.indexer.fingerprint import check_fingerprint
+ from serviette.indexer.prepare import prepare_backend
+
+ check_fingerprint(config)
+ prepare_backend(config)
+ code = _spawn_workers(
+ config.indexer.workers,
+ ["--config", args.config, "--log-level", args.log_level],
+ first_port=config.indexer.spawn_first_port,
+ )
+ # A signal-terminated spawner reports -N; exit 128+N like a shell would.
+ raise SystemExit(128 - code if code < 0 else code)
+
+ try:
+ run_indexer(config, prepare=not inside_spawn)
+ except KeyboardInterrupt:
+ # Ctrl-C reaches the indexer together with `serviette up` (same
+ # process group): a deliberate stop, not an error — no traceback.
+ logging.getLogger(__name__).info("indexer: stopped")
+ raise SystemExit(130) from None
+
+
+if __name__ == "__main__":
+ main()
diff --git a/serviette/indexer/prepare.py b/serviette/indexer/prepare.py
new file mode 100644
index 00000000..098df7c2
--- /dev/null
+++ b/serviette/indexer/prepare.py
@@ -0,0 +1,380 @@
+"""Backend preparation: create the targets the output connectors don't.
+
+Pathway's output connectors auto-create their target only for DuckDB
+(``init_mode``) and Qdrant (collection on first write). Every other backend
+expects the table / collection / index to exist — so the indexer prepares
+them here at startup, and a first run against a fresh database just works:
+
+- **pgvector** — ``CREATE EXTENSION vector``, the table, and an HNSW cosine
+ index on ``embedding``.
+- **milvus** — collection ``(chunk_id VARCHAR pk, text VARCHAR, metadata
+ JSON, embedding FLOAT_VECTOR(dim))`` with a COSINE AUTOINDEX.
+- **chroma** — collection with the cosine ``hnsw:space``.
+- **weaviate** — collection with no server-side vectorizer and TEXT
+ properties matching the sink's columns.
+- **pinecone** — serverless index (cosine) with the embedder's dimension.
+- **mongodb** — collection plus the Atlas ``vectorSearch`` index on the
+ ``embedding`` path.
+
+All operations are create-if-missing (idempotent, race-tolerant). Vector
+dimension resolves from ``vector_db.embedding_dimension`` when set, otherwise
+from the embedder itself (``BaseEmbedder.get_embedding_dimension()`` — one
+probe embedding call).
+"""
+
+from __future__ import annotations
+
+import asyncio
+import logging
+from pathlib import Path
+
+from serviette.config.schema import (
+ ChromaConfig,
+ DuckDbConfig,
+ MilvusConfig,
+ MongoDbConfig,
+ PgVectorConfig,
+ PineconeConfig,
+ QdrantConfig,
+ ServietteConfig,
+ WeaviateConfig,
+)
+
+logger = logging.getLogger(__name__)
+
+
+def resolve_embedding_dimension(config: ServietteConfig) -> int:
+ explicit = getattr(config.vector_db, "embedding_dimension", None)
+ if explicit:
+ return int(explicit)
+ assert config.embedder is not None # enforced by for_indexer()
+ if config.embedder.type == "mock":
+ from serviette.testing import EMBED_DIM
+
+ return EMBED_DIM
+ from serviette.indexer.graph import build_xpack_embedder
+
+ logger.info("Resolving the embedding dimension with a probe embedding call")
+ embedder = build_xpack_embedder(config.embedder)
+ # xpack embedders subclass pw.UDF and add get_embedding_dimension().
+ return int(embedder.get_embedding_dimension()) # type: ignore[attr-defined]
+
+
+def prepare_backend(config: ServietteConfig) -> None:
+ """Create the vector-DB target for ``config`` if it does not exist."""
+
+ vdb = config.vector_db
+ assert vdb is not None # enforced by for_indexer() before we are called
+ if vdb.type == "qdrant":
+ _prepare_qdrant(config)
+ elif vdb.type == "duckdb":
+ _prepare_duckdb(config)
+ elif vdb.type == "pgvector":
+ _prepare_pgvector(config)
+ elif vdb.type == "milvus":
+ _prepare_milvus(config)
+ elif vdb.type == "chroma":
+ _prepare_chroma(config)
+ elif vdb.type == "weaviate":
+ _prepare_weaviate(config)
+ elif vdb.type == "pinecone":
+ _prepare_pinecone(config)
+ elif vdb.type == "mongodb":
+ _prepare_mongodb(config)
+
+
+def _prepare_pgvector(config: ServietteConfig) -> None:
+ import asyncpg
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, PgVectorConfig)
+ dimension = resolve_embedding_dimension(config)
+
+ async def go() -> None:
+ conn = await asyncpg.connect(vdb.connection_string)
+ try:
+ await conn.execute("CREATE EXTENSION IF NOT EXISTS vector")
+ await conn.execute(
+ f"CREATE TABLE IF NOT EXISTS {vdb.table} ("
+ f" chunk_id text PRIMARY KEY,"
+ f" text text,"
+ f" metadata jsonb,"
+ f" embedding vector({dimension})"
+ f")"
+ )
+ try:
+ await conn.execute(
+ f"CREATE INDEX IF NOT EXISTS {vdb.table}_embedding_hnsw "
+ f"ON {vdb.table} USING hnsw (embedding vector_cosine_ops)"
+ )
+ except asyncpg.PostgresError as exc:
+ # HNSW needs pgvector >= 0.5; retrieval still works unindexed.
+ logger.warning("Could not create the HNSW index: %s", exc)
+ finally:
+ await conn.close()
+
+ asyncio.run(go())
+ logger.info("pgvector: table %r ready (dimension %d)", vdb.table, dimension)
+
+
+def _prepare_milvus(config: ServietteConfig) -> None:
+ from pymilvus import DataType, MilvusClient
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, MilvusConfig)
+ kwargs = {"uri": vdb.resolved_uri()}
+ if vdb.token:
+ kwargs["token"] = vdb.token
+ client = MilvusClient(**kwargs)
+ try:
+ if client.has_collection(vdb.collection):
+ return
+ dimension = resolve_embedding_dimension(config)
+ schema = client.create_schema(auto_id=False, enable_dynamic_field=False)
+ schema.add_field("chunk_id", DataType.VARCHAR, is_primary=True, max_length=512)
+ schema.add_field("text", DataType.VARCHAR, max_length=65535)
+ schema.add_field("metadata", DataType.JSON)
+ schema.add_field("embedding", DataType.FLOAT_VECTOR, dim=dimension)
+ index = client.prepare_index_params()
+ index.add_index(
+ field_name="embedding", index_type="AUTOINDEX", metric_type="COSINE"
+ )
+ client.create_collection(vdb.collection, schema=schema, index_params=index)
+ logger.info(
+ "milvus: collection %r created (dimension %d)", vdb.collection, dimension
+ )
+ finally:
+ client.close()
+
+
+def _prepare_chroma(config: ServietteConfig) -> None:
+ import chromadb
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, ChromaConfig)
+ client = chromadb.HttpClient(
+ host=vdb.host,
+ port=vdb.port,
+ ssl=vdb.ssl,
+ headers=vdb.headers or {},
+ tenant=vdb.tenant,
+ database=vdb.database,
+ )
+ client.get_or_create_collection(vdb.collection, metadata={"hnsw:space": "cosine"})
+ logger.info("chroma: collection %r ready (cosine)", vdb.collection)
+
+
+def _prepare_weaviate(config: ServietteConfig) -> None:
+ import weaviate
+ from weaviate.classes.config import Configure, DataType, Property
+ from weaviate.connect import ConnectionParams
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, WeaviateConfig)
+ auth = weaviate.auth.AuthApiKey(vdb.api_key) if vdb.api_key else None
+ client = weaviate.WeaviateClient(
+ connection_params=ConnectionParams.from_params(
+ http_host=vdb.http_host,
+ http_port=vdb.http_port,
+ http_secure=vdb.http_secure,
+ grpc_host=vdb.grpc_host or vdb.http_host,
+ grpc_port=vdb.grpc_port,
+ grpc_secure=vdb.grpc_secure,
+ ),
+ auth_client_secret=auth,
+ )
+ client.connect()
+ try:
+ if not client.collections.exists(vdb.collection):
+ client.collections.create(
+ vdb.collection,
+ vectorizer_config=Configure.Vectorizer.none(),
+ properties=[
+ Property(name="chunk_id", data_type=DataType.TEXT),
+ Property(name="text", data_type=DataType.TEXT),
+ Property(name="metadata", data_type=DataType.TEXT),
+ ],
+ )
+ logger.info("weaviate: collection %r created", vdb.collection)
+ finally:
+ client.close()
+
+
+def _prepare_qdrant(config: ServietteConfig) -> None:
+ """Create the Qdrant collection with a single named dense vector slot.
+
+ The schema-driven ``pw.io.qdrant`` sink (Pathway ≥ 0.32.1) no longer
+ auto-creates the collection: it binds each declared vector slot to the
+ same-named table column, so the collection must pre-exist with a dense slot
+ named ``QDRANT_VECTOR_NAME`` (matching the indexer's ``embedding`` column
+ and the server accessor's search slot). The remaining columns (``text``,
+ ``metadata``) land in the point payload.
+ """
+
+ from qdrant_client import QdrantClient
+ from qdrant_client.models import Distance, VectorParams
+
+ from serviette.server.accessors.qdrant import QDRANT_VECTOR_NAME
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, QdrantConfig)
+ client = QdrantClient(url=vdb.rest_url(), api_key=vdb.api_key)
+ try:
+ if not client.collection_exists(vdb.collection):
+ dimension = resolve_embedding_dimension(config)
+ client.create_collection(
+ vdb.collection,
+ vectors_config={
+ QDRANT_VECTOR_NAME: VectorParams(
+ size=dimension, distance=Distance.COSINE
+ )
+ },
+ )
+ logger.info(
+ "qdrant: collection %r created (dimension %d, vector %r)",
+ vdb.collection,
+ dimension,
+ QDRANT_VECTOR_NAME,
+ )
+ finally:
+ client.close()
+
+
+def _prepare_pinecone(config: ServietteConfig) -> None:
+ import os
+
+ from pinecone import Pinecone, ServerlessSpec
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, PineconeConfig)
+ api_key = vdb.api_key or os.environ.get("PINECONE_API_KEY")
+ pc = Pinecone(api_key=api_key, host=vdb.host)
+ if not pc.has_index(vdb.index_name):
+ dimension = resolve_embedding_dimension(config)
+ pc.create_index(
+ name=vdb.index_name,
+ dimension=dimension,
+ metric="cosine",
+ spec=ServerlessSpec(cloud=vdb.cloud, region=vdb.region),
+ )
+ logger.info(
+ "pinecone: index %r created (dimension %d)", vdb.index_name, dimension
+ )
+
+
+def _prepare_mongodb(config: ServietteConfig) -> None:
+ from pymongo import MongoClient
+ from pymongo.operations import SearchIndexModel
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, MongoDbConfig)
+ client: MongoClient = MongoClient(vdb.connection_string)
+ try:
+ db = client[vdb.database]
+ if vdb.collection not in db.list_collection_names():
+ db.create_collection(vdb.collection)
+ coll = db[vdb.collection]
+ # Atlas Local boots mongot (the Search Index Management service)
+ # noticeably later than mongod itself; both listing and creating
+ # search indexes go through it. Ride out the boot window instead of
+ # failing the first indexer start.
+ import time
+
+ from pymongo.errors import OperationFailure
+
+ deadline = time.monotonic() + 120
+ while True:
+ try:
+ existing = list(coll.list_search_indexes(vdb.vector_index))
+ break
+ except OperationFailure as exc:
+ if (
+ "Search Index Management" not in str(exc)
+ or time.monotonic() > deadline
+ ):
+ raise
+ time.sleep(3)
+ if existing:
+ return
+ dimension = resolve_embedding_dimension(config)
+ try:
+ coll.create_search_index(
+ SearchIndexModel(
+ definition={
+ "fields": [
+ {
+ "type": "vector",
+ "path": "embedding",
+ "numDimensions": dimension,
+ "similarity": "cosine",
+ }
+ ]
+ },
+ name=vdb.vector_index,
+ type="vectorSearch",
+ )
+ )
+ logger.info(
+ "mongodb: vectorSearch index %r created (dimension %d); it "
+ "becomes queryable once Atlas finishes building it",
+ vdb.vector_index,
+ dimension,
+ )
+ except Exception as exc: # noqa: BLE001 - plain MongoDB has no mongot
+ logger.warning(
+ "Could not create the vectorSearch index (%s). Vector search "
+ "needs MongoDB Atlas or the atlas-local image; create the "
+ "index manually if your deployment supports it.",
+ exc,
+ )
+ finally:
+ client.close()
+
+
+def _prepare_duckdb(config: ServietteConfig) -> None:
+ """Create the database file and an empty table immediately.
+
+ The pw.io.duckdb writer would create both on its first flush, but that
+ only happens once there is data: with an empty source folder the file
+ would never appear and `serviette up` could not tell "still indexing" from
+ "nothing to index". An empty, correctly-shaped table makes the store
+ queryable from second one. The DDL mirrors the writer exactly — same
+ columns, and PRIMARY KEY(chunk_id) that snapshot-mode upserts require —
+ so the writer's CREATE IF NOT EXISTS + preflight accept it as-is.
+
+ The file is pinned to storage format v1.0.0: the engine bundles its own
+ DuckDB, which reads a bounded range of storage versions, while the Python
+ package creating this file upgrades independently (its dev builds write
+ the unreleased format 999 that no stable reader accepts). The pin keeps
+ the file readable by both sides regardless of that drift.
+ """
+
+ import duckdb
+
+ vdb = config.vector_db
+ # prepare_backend dispatches on vdb.type, so the narrow type holds.
+ assert isinstance(vdb, DuckDbConfig)
+ Path(vdb.path).parent.mkdir(parents=True, exist_ok=True)
+ conn = duckdb.connect()
+ try:
+ target = str(vdb.path).replace("'", "''")
+ try:
+ conn.execute(f"ATTACH '{target}' AS store (STORAGE_VERSION 'v1.0.0')")
+ except duckdb.Error:
+ # duckdb < 1.2 lacks the STORAGE_VERSION option; those builds
+ # write the v1.0.0 format natively, so a plain attach is the same.
+ conn.execute(f"ATTACH '{target}' AS store")
+ conn.execute(
+ f'CREATE TABLE IF NOT EXISTS store."{vdb.table}" ('
+ f'"chunk_id" VARCHAR PRIMARY KEY, "text" VARCHAR, '
+ f'"metadata" VARCHAR, "embedding" DOUBLE[])'
+ )
+ finally:
+ conn.close()
diff --git a/serviette/indexer/sources.py b/serviette/indexer/sources.py
new file mode 100644
index 00000000..8891f68c
--- /dev/null
+++ b/serviette/indexer/sources.py
@@ -0,0 +1,305 @@
+"""Source connectors and byte fetchers for the indexer.
+
+We only support sources that have an ``only_metadata`` read mode (like the
+filesystem connector): the Pathway graph holds just paths/identifiers and
+metadata, never the file bytes, and the bytes are fetched on demand inside the
+parse UDF. Today that is:
+
+- **fs** — ``pw.io.fs.read(format="only_metadata")``; bytes read from the local
+ path in the metadata.
+- **gdrive** — ``pw.io.gdrive.read(format="only_metadata")``; bytes downloaded by
+ file ``id`` via the Google Drive API.
+- **s3** — ``pw.io.s3.read(format="only_metadata")`` (Pathway ≥ 0.32.1);
+ bytes downloaded by object key via boto3. Covers any S3-compatible
+ store (MinIO, DigitalOcean, Wasabi) through ``endpoint``/``with_path_style``.
+- **sharepoint** — ``pathway.xpacks.connectors.sharepoint.read(
+ format="only_metadata")`` (same Pathway version; Scale license); bytes
+ downloaded by server-relative path via the same certificate-authenticated
+ ``office365`` client.
+
+- **pyfilesystem** — ``pw.io.pyfilesystem.read(format="only_metadata")``;
+ anything the PyFilesystem library opens (FTP, SFTP, WebDAV, ZIP/TAR,
+ ``osfs://``, ``mem://``); bytes re-read from the same filesystem by path.
+
+Each source type provides a :class:`Fetcher` that turns a metadata dict into
+``(bytes, suffix)`` for the parser. The fetcher is what makes the parse step
+source-agnostic.
+"""
+
+from __future__ import annotations
+
+from collections.abc import Callable
+from pathlib import Path
+from typing import Any, Protocol
+
+import pathway as pw
+
+# Drive scope sufficient to download file contents.
+_GDRIVE_SCOPES = ["https://www.googleapis.com/auth/drive.readonly"]
+
+
+# ---------------------------------------------------------------------------
+# Reading source tables in only_metadata mode
+# ---------------------------------------------------------------------------
+
+
+def read_source(src, name: str) -> pw.Table:
+ """Return an ``only_metadata`` table for ``src`` (one ``_metadata`` column).
+
+ ``name`` is the persistable connector name (unique per source).
+ """
+
+ if src.type == "fs":
+ return pw.io.fs.read(
+ src.path,
+ format="only_metadata",
+ mode=src.mode,
+ object_pattern=src.glob,
+ max_backlog_size=src.max_backlog_size,
+ name=name,
+ )
+ if src.type == "gdrive":
+ return pw.io.gdrive.read(
+ src.object_id,
+ format="only_metadata",
+ mode=src.mode,
+ service_user_credentials_file=src.service_user_credentials_file,
+ file_name_pattern=src.file_name_pattern,
+ object_size_limit=src.object_size_limit,
+ max_backlog_size=src.max_backlog_size,
+ name=name,
+ )
+ if src.type == "s3":
+ return pw.io.s3.read(
+ src.path,
+ format="only_metadata",
+ aws_s3_settings=pw.io.s3.AwsS3Settings(
+ bucket_name=src.bucket,
+ access_key=src.access_key,
+ secret_access_key=src.secret_access_key,
+ region=src.region,
+ endpoint=src.endpoint,
+ with_path_style=src.with_path_style,
+ ),
+ mode=src.mode,
+ max_backlog_size=src.max_backlog_size,
+ name=name,
+ )
+ if src.type == "pyfilesystem":
+ try:
+ from fs import open_fs
+ except ImportError as exc:
+ raise SystemExit(
+ "The 'pyfilesystem' source needs the PyFilesystem2 library: "
+ "pip install 'serviette[pyfilesystem]'"
+ ) from exc
+
+ return pw.io.pyfilesystem.read(
+ open_fs(src.fs_url),
+ path=src.path,
+ format="only_metadata",
+ mode=src.mode,
+ refresh_interval=float(src.refresh_interval),
+ max_backlog_size=src.max_backlog_size,
+ name=name,
+ )
+ if src.type == "sharepoint":
+ # NOTE: the SharePoint xpack connector has no max_backlog_size (yet).
+ # Requires a Pathway Scale license; the connector polls the site every
+ # refresh_interval seconds and emits native additions/retractions.
+ from pathway.xpacks.connectors import sharepoint
+
+ return sharepoint.read(
+ src.url,
+ tenant=src.tenant,
+ client_id=src.client_id,
+ cert_path=src.cert_path,
+ thumbprint=src.thumbprint,
+ root_path=src.root_path,
+ mode=src.mode,
+ format="only_metadata",
+ recursive=src.recursive,
+ object_size_limit=src.object_size_limit,
+ refresh_interval=src.refresh_interval,
+ )
+ raise ValueError(f"Unsupported source type: {src.type!r}") # pragma: no cover
+
+
+# ---------------------------------------------------------------------------
+# Byte fetchers
+# ---------------------------------------------------------------------------
+
+
+class Fetcher(Protocol):
+ def fetch(self, metadata: dict[str, Any]) -> tuple[bytes, str]:
+ """Return ``(contents, suffix)`` for the object described by ``metadata``."""
+
+
+class FsFetcher:
+ """Read bytes from the local filesystem path in the metadata."""
+
+ def fetch(self, metadata: dict[str, Any]) -> tuple[bytes, str]:
+ path = metadata["path"]
+ return Path(path).read_bytes(), Path(path).suffix
+
+
+class GDriveFetcher:
+ """Download bytes from Google Drive by file id.
+
+ ``download_fn`` is injectable for tests; in production it lazily builds a
+ Drive client from the service-account credentials file.
+ """
+
+ def __init__(
+ self,
+ service_user_credentials_file: str,
+ download_fn: Callable[[str], bytes] | None = None,
+ ) -> None:
+ self._credentials_file = service_user_credentials_file
+ self._download_fn = download_fn
+ self._service = None
+
+ def _service_download(self, file_id: str) -> bytes:
+ if self._service is None:
+ from google.oauth2.service_account import Credentials
+ from googleapiclient.discovery import build
+
+ creds = Credentials.from_service_account_file(
+ self._credentials_file, scopes=_GDRIVE_SCOPES
+ )
+ self._service = build("drive", "v3", credentials=creds)
+ assert self._service is not None
+ # get_media's execute() returns the raw file bytes.
+ return self._service.files().get_media(fileId=file_id).execute()
+
+ def fetch(self, metadata: dict[str, Any]) -> tuple[bytes, str]:
+ file_id = metadata["id"]
+ download = self._download_fn or self._service_download
+ contents = download(file_id)
+ # Derive the extension from the file name; Google-native docs (Docs/
+ # Sheets) have no binary download and are skipped upstream.
+ suffix = Path(metadata.get("name", "")).suffix
+ return contents, suffix
+
+
+class S3Fetcher:
+ """Download object bytes from S3 (or an S3-compatible endpoint) by key.
+
+ The ``only_metadata`` row's ``path`` field is the object key. ``client``
+ is injectable for tests; in production a ``boto3`` client is built lazily
+ from the source settings (install the ``s3`` extra for boto3).
+ """
+
+ def __init__(self, src, client=None) -> None:
+ self._src = src
+ self._client = client
+
+ def _ensure_client(self):
+ if self._client is None:
+ try:
+ import boto3
+ from botocore.config import Config
+ except ImportError as exc: # pathway >= 0.33 no longer ships boto3
+ raise RuntimeError(
+ 'The s3 source needs boto3: pip install "serviette[s3]"'
+ ) from exc
+
+ src = self._src
+ kwargs: dict[str, Any] = {}
+ if src.access_key:
+ kwargs["aws_access_key_id"] = src.access_key
+ if src.secret_access_key:
+ kwargs["aws_secret_access_key"] = src.secret_access_key
+ if src.region:
+ kwargs["region_name"] = src.region
+ if src.endpoint:
+ kwargs["endpoint_url"] = src.endpoint
+ if src.with_path_style:
+ kwargs["config"] = Config(s3={"addressing_style": "path"})
+ self._client = boto3.client("s3", **kwargs)
+ return self._client
+
+ def fetch(self, metadata: dict[str, Any]) -> tuple[bytes, str]:
+ key = metadata["path"]
+ response = self._ensure_client().get_object(Bucket=self._src.bucket, Key=key)
+ return response["Body"].read(), Path(key).suffix
+
+
+class SharePointFetcher:
+ """Download file bytes from SharePoint by server-relative path.
+
+ Reuses the same certificate authentication as the connector
+ (``office365`` ``ClientContext``); the ``only_metadata`` row's ``path``
+ field is the file's server-relative URL. ``download_fn`` is injectable
+ for tests.
+ """
+
+ def __init__(self, src, download_fn: Callable[[str], bytes] | None = None) -> None:
+ self._src = src
+ self._download_fn = download_fn
+ self._context = None
+
+ def _ensure_context(self):
+ if self._context is None:
+ from office365.sharepoint.client_context import ClientContext
+
+ src = self._src
+ self._context = ClientContext(src.url).with_client_certificate(
+ tenant=src.tenant,
+ client_id=src.client_id,
+ thumbprint=src.thumbprint,
+ cert_path=src.cert_path,
+ )
+ return self._context
+
+ def _context_download(self, path: str) -> bytes:
+ context = self._ensure_context()
+ file = context.web.get_file_by_server_relative_path(path)
+ return file.get_content().execute_query_retry().value
+
+ def fetch(self, metadata: dict[str, Any]) -> tuple[bytes, str]:
+ path = metadata["path"]
+ download = self._download_fn or self._context_download
+ return download(path), Path(path).suffix
+
+
+class PyFilesystemFetcher:
+ """Read bytes back from the PyFilesystem source by in-filesystem path.
+
+ A separate ``open_fs`` handle is created lazily per process (parse UDFs
+ run in every worker); PyFilesystem FS objects are thread-safe.
+ ``fs_factory`` is injectable for tests.
+ """
+
+ def __init__(self, src, fs_factory: Callable[[], Any] | None = None) -> None:
+ self._src = src
+ self._fs_factory = fs_factory
+ self._fs = None
+
+ def _ensure_fs(self):
+ if self._fs is None:
+ if self._fs_factory is not None:
+ self._fs = self._fs_factory()
+ else:
+ from fs import open_fs
+
+ self._fs = open_fs(self._src.fs_url)
+ return self._fs
+
+ def fetch(self, metadata: dict[str, Any]) -> tuple[bytes, str]:
+ path = metadata["path"]
+ return self._ensure_fs().readbytes(path), Path(path).suffix
+
+
+def make_fetcher(src) -> Fetcher:
+ if src.type == "fs":
+ return FsFetcher()
+ if src.type == "gdrive":
+ return GDriveFetcher(src.service_user_credentials_file)
+ if src.type == "s3":
+ return S3Fetcher(src)
+ if src.type == "sharepoint":
+ return SharePointFetcher(src)
+ if src.type == "pyfilesystem":
+ return PyFilesystemFetcher(src)
+ raise ValueError(f"Unsupported source type: {src.type!r}") # pragma: no cover
diff --git a/serviette/server/__init__.py b/serviette/server/__init__.py
new file mode 100644
index 00000000..a94316d1
--- /dev/null
+++ b/serviette/server/__init__.py
@@ -0,0 +1 @@
+"""Server package (FastAPI retrieval/RAG service)."""
diff --git a/serviette/server/accessors/__init__.py b/serviette/server/accessors/__init__.py
new file mode 100644
index 00000000..2750d77f
--- /dev/null
+++ b/serviette/server/accessors/__init__.py
@@ -0,0 +1,53 @@
+"""Async vector-database accessors.
+
+Each accessor implements :class:`AsyncVectorAccessor` and knows how to fetch the
+top-k nearest chunks for a query embedding from one backend. The server is
+decoupled from the indexer and talks to the vector DB only through these.
+"""
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+
+__all__ = ["AsyncVectorAccessor", "build_accessor"]
+
+
+def build_accessor(vector_db) -> AsyncVectorAccessor:
+ """Construct the accessor matching a ``vector_db`` config section.
+
+ Imports are local so installing only the backend you use (e.g. no
+ ``pymilvus``) does not break the others.
+ """
+
+ db_type = vector_db.type
+ if db_type == "duckdb":
+ from serviette.server.accessors.duckdb import DuckDbAccessor
+
+ return DuckDbAccessor(vector_db)
+ if db_type == "pgvector":
+ from serviette.server.accessors.pgvector import PgVectorAccessor
+
+ return PgVectorAccessor(vector_db)
+ if db_type == "milvus":
+ from serviette.server.accessors.milvus import MilvusAccessor
+
+ return MilvusAccessor(vector_db)
+ if db_type == "qdrant":
+ from serviette.server.accessors.qdrant import QdrantAccessor
+
+ return QdrantAccessor(vector_db)
+ if db_type == "chroma":
+ from serviette.server.accessors.chroma import ChromaAccessor
+
+ return ChromaAccessor(vector_db)
+ if db_type == "weaviate":
+ from serviette.server.accessors.weaviate import WeaviateAccessor
+
+ return WeaviateAccessor(vector_db)
+ if db_type == "pinecone":
+ from serviette.server.accessors.pinecone import PineconeAccessor
+
+ return PineconeAccessor(vector_db)
+ if db_type == "mongodb":
+ from serviette.server.accessors.mongodb import MongoDbAccessor
+
+ return MongoDbAccessor(vector_db)
+ raise ValueError(f"Unsupported vector_db type: {db_type!r}")
diff --git a/serviette/server/accessors/abstract.py b/serviette/server/accessors/abstract.py
new file mode 100644
index 00000000..b7a56208
--- /dev/null
+++ b/serviette/server/accessors/abstract.py
@@ -0,0 +1,121 @@
+"""Abstract base class for async vector-DB retrieval."""
+
+from __future__ import annotations
+
+from abc import ABC, abstractmethod
+from typing import Any
+
+from typing_extensions import Self
+
+
+class IndexNotReadyError(RuntimeError):
+ """The vector store exists in config but has no data yet.
+
+ Raised while the indexer is still starting or has not committed its
+ first batch (e.g. the DuckDB file or the target table/collection does
+ not exist yet). The server maps it to HTTP 503 with a friendly message
+ instead of a stack trace."""
+
+
+class IndexBusyError(IndexNotReadyError):
+ """The store has data but cannot be read at this moment.
+
+ Raised when an embedded, single-writer store (DuckDB) is being written
+ by the indexer for longer than the accessor is willing to wait — the
+ first commit of a large corpus can hold the file lock for tens of
+ seconds. Same HTTP 503 as :class:`IndexNotReadyError`, with a message
+ saying the index is being updated rather than that it is empty."""
+
+
+def document_key(metadata: dict[str, Any] | None) -> str | None:
+ """The identity of a chunk's source document, as the source reports it:
+ ``path`` (fs, s3, sharepoint, pyfilesystem) or ``id`` / ``name`` (gdrive).
+ The same rule the backends' ``stats`` use to count documents."""
+
+ if not metadata:
+ return None
+ for field in ("path", "id", "name"):
+ value = metadata.get(field)
+ if value is not None and value != "":
+ return str(value)
+ return None
+
+
+class AsyncVectorAccessor(ABC):
+ """Retrieve the nearest chunks for a query embedding from a vector store.
+
+ Implementations are async so the network-bound call to the vector DB does
+ not block the FastAPI event loop.
+ """
+
+ # Whether ``retrieve_ex(..., with_embeddings=True)`` returns hit
+ # embeddings (needed by MMR). Backends that can cheaply return stored
+ # vectors flip this to True and honor the flag.
+ supports_embeddings = False
+
+ # Whether the backend can enumerate its documents (``list_documents`` /
+ # ``document_chunks``) — what ``rag.documents`` needs. Backends that
+ # cannot list their rows at all (Pinecone) leave this False.
+ supports_catalog = False
+
+ async def list_documents(self) -> list[dict[str, Any]]:
+ """Every indexed document: ``{"id": str, "metadata": dict,
+ "chunks": int}``, where ``id`` is :func:`document_key` of its chunks
+ and ``metadata`` is that of one of them."""
+
+ raise NotImplementedError
+
+ async def document_chunks(
+ self, document: str, *, with_embeddings: bool = False
+ ) -> list[dict[str, Any]]:
+ """All chunks of the document with the given ``id``, as hit dicts
+ without a score. The store keeps no chunk order, so none is implied."""
+
+ raise NotImplementedError
+
+ @abstractmethod
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ """Return up to ``k`` results ordered by descending similarity.
+
+ Each result is a dict ``{"text": str, "metadata": dict, "score": float}``
+ where ``score`` is a cosine similarity in ``[-1, 1]`` (higher is closer).
+ """
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ """:meth:`retrieve` with optional extras; the server always calls this.
+
+ ``query_text`` lets hybrid-capable backends run a keyword search next
+ to the vector one; ``with_embeddings`` asks for an ``"embedding"`` key
+ on each hit. The default implementation ignores both and delegates,
+ so plain backends need not change.
+ """
+
+ return await self.retrieve(embedding, k)
+
+ @abstractmethod
+ async def close(self) -> None:
+ """Release any underlying connections / pools."""
+
+ async def stats(self) -> dict[str, Any]:
+ """Lightweight backend statistics for observability.
+
+ Best-effort keys: ``chunks`` (row/point count), ``documents``
+ (distinct source objects, where cheap), ``last_indexed_at`` (unix
+ seconds, where cheap). Returns ``{}`` when the backend cannot answer
+ cheaply; must never raise for routine unavailability.
+ """
+
+ return {}
+
+ async def __aenter__(self) -> Self:
+ return self
+
+ async def __aexit__(self, *exc: object) -> None:
+ await self.close()
diff --git a/serviette/server/accessors/chroma.py b/serviette/server/accessors/chroma.py
new file mode 100644
index 00000000..2beea295
--- /dev/null
+++ b/serviette/server/accessors/chroma.py
@@ -0,0 +1,151 @@
+"""Async ChromaDB accessor using the ``chromadb`` HTTP client.
+
+The indexer's ``pw.io.chroma`` sink writes each chunk with the text as the
+document and the source metadata serialized to a JSON string (Chroma metadata
+values must be scalars). The collection must be created with the cosine
+distance (``hnsw:space = cosine``); Chroma returns a *distance*, converted here
+to a similarity (``1 - distance``).
+"""
+
+from __future__ import annotations
+
+import json
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+from serviette.server.hybrid import KeywordHybridMixin
+
+_SCAN_PAGE = 1000
+
+
+def _or_empty(value: Any) -> Any:
+ """``value or []`` that survives numpy: chromadb >= 0.5 returns result
+ embeddings as ``numpy.ndarray``, whose truth value raises."""
+
+ return [] if value is None else value
+
+
+def _first_or_empty(value: Any) -> Any:
+ """First per-query entry of a query-result field (``None``-safe)."""
+
+ return value[0] if value is not None and len(value) else []
+
+
+def _chroma_metadata(meta: Any) -> dict[str, Any]:
+ raw = (meta or {}).get("metadata")
+ return json.loads(raw) if isinstance(raw, str) else (raw or {})
+
+
+class ChromaAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._config = config
+ self._client = None
+ self._collection = None
+ self._init_hybrid(config)
+
+ async def _ensure_collection(self):
+ if self._collection is None:
+ import chromadb
+
+ cfg = self._config
+ self._client = await chromadb.AsyncHttpClient(
+ host=cfg.host,
+ port=cfg.port,
+ ssl=cfg.ssl,
+ headers=cfg.headers or {},
+ tenant=cfg.tenant,
+ database=cfg.database,
+ )
+ self._collection = await self._client.get_collection(cfg.collection)
+ return self._collection
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ collection = await self._ensure_collection()
+ include = ["documents", "metadatas", "distances"]
+ if with_embeddings:
+ include.append("embeddings")
+ response = await collection.query(
+ query_embeddings=[embedding], n_results=k, include=include
+ )
+ documents = (response.get("documents") or [[]])[0]
+ metadatas = (response.get("metadatas") or [[]])[0]
+ distances = (response.get("distances") or [[]])[0]
+ embeddings = _first_or_empty(response.get("embeddings")) if with_embeddings else []
+ vector_hits: list[dict[str, Any]] = []
+ for i, (text, meta, distance) in enumerate(
+ zip(documents, metadatas, distances)
+ ):
+ hit: dict[str, Any] = {
+ "text": text or "",
+ "metadata": _chroma_metadata(meta),
+ "score": 1.0 - float(distance),
+ }
+ if with_embeddings and i < len(embeddings):
+ hit["embedding"] = [float(x) for x in embeddings[i]]
+ vector_hits.append(hit)
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ collection = await self._ensure_collection()
+ return int(await collection.count())
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ collection = await self._ensure_collection()
+ include = ["documents", "metadatas"]
+ if with_embeddings:
+ include.append("embeddings")
+ hits: list[dict[str, Any]] = []
+ offset = 0
+ while True:
+ page = await collection.get(
+ include=include, limit=_SCAN_PAGE, offset=offset
+ )
+ documents = page.get("documents") or []
+ metadatas = page.get("metadatas") or []
+ embeddings = _or_empty(page.get("embeddings"))
+ if not documents:
+ break
+ for i, (text, meta) in enumerate(zip(documents, metadatas)):
+ hit: dict[str, Any] = {
+ "text": text or "",
+ "metadata": _chroma_metadata(meta),
+ }
+ if with_embeddings and i < len(embeddings):
+ hit["embedding"] = [float(x) for x in embeddings[i]]
+ hits.append(hit)
+ if len(documents) < _SCAN_PAGE:
+ break
+ offset += _SCAN_PAGE
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ return {"chunks": await self._hybrid_count()}
+
+ async def close(self) -> None:
+ await self._close_hybrid()
+ client, self._client, self._collection = self._client, None, None
+ if client is None:
+ return
+ # chromadb's AsyncClient has no public close: its AsyncFastAPI server
+ # API keeps one httpx.AsyncClient per event loop and releases them in
+ # ``_cleanup`` (also what its ``__aexit__`` calls). The chromadb
+ # System behind the client is shared between clients with the same
+ # settings and is left alone; a surviving client lazily reopens its
+ # pool on the next request.
+ cleanup = getattr(getattr(client, "_server", None), "_cleanup", None)
+ if cleanup is not None:
+ await cleanup()
diff --git a/serviette/server/accessors/duckdb.py b/serviette/server/accessors/duckdb.py
new file mode 100644
index 00000000..9b2309e5
--- /dev/null
+++ b/serviette/server/accessors/duckdb.py
@@ -0,0 +1,302 @@
+"""DuckDB vector accessor — embedded, zero-setup, in-database vector search.
+
+Reads the table written by the indexer's ``pw.io.duckdb`` snapshot sink:
+``(chunk_id, text, metadata, embedding DOUBLE[])``. Retrieval runs entirely
+inside DuckDB with ``list_cosine_similarity`` — a vectorized, columnar scan in
+native code (no Python loop over rows). For local corpora this answers in
+milliseconds without any external service.
+
+Concurrency note: the indexer writes with ``detach_between_batches``,
+releasing the single-writer file lock between minibatches; connections here
+are short-lived and read-only and retry through those lock windows. Most are
+milliseconds, but the first commit of a real corpus (thousands of chunks with
+embeddings) holds the lock for seconds — the accessor waits up to
+``_LOCK_WAIT`` and then raises :class:`IndexBusyError` ("being updated, retry
+in a moment") rather than failing the request. Before the indexer's first
+commit the file (or table) does not exist yet — that is
+:class:`IndexNotReadyError`. The server turns both into a friendly HTTP 503
+rather than a stack trace.
+"""
+
+from __future__ import annotations
+
+import asyncio
+import json
+import logging
+from typing import Any
+
+from serviette.server.accessors.abstract import (
+ AsyncVectorAccessor,
+ IndexBusyError,
+ IndexNotReadyError,
+)
+from serviette.server.hybrid import KeywordHybridMixin
+
+logger = logging.getLogger(__name__)
+
+_LOCK_HINT = (
+ "The DuckDB database %r has been write-locked by another process for over "
+ "%.0fs. A streaming indexer normally releases the lock between batches "
+ "(seconds at most); if this keeps happening, check for a second indexer or "
+ "another DuckDB client holding the file open, or move to a client-server "
+ "backend (qdrant, pgvector, ...) for heavy concurrent indexing and serving."
+)
+
+
+class DuckDbAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._path = config.path
+ self._table = config.table
+ self._init_hybrid(config)
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ # DuckDB's Python API is synchronous; run the query off the event loop.
+ return await asyncio.to_thread(self._query, embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ vector_hits = await asyncio.to_thread(
+ self._query, embedding, k, with_embeddings=with_embeddings
+ )
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ return await asyncio.to_thread(self._count_rows)
+
+ async def _hybrid_version(self) -> tuple[int, Any]:
+ return await asyncio.to_thread(self._version)
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ return await asyncio.to_thread(self._fetch_all_rows, with_embeddings)
+
+ # How long a reader rides out the writer's lock before giving up with a
+ # 503. Sized for the first commit of a real corpus: ~5 000 chunks with
+ # embeddings held the lock for ~10 s in measurements; later batches are
+ # small and release within milliseconds.
+ _LOCK_WAIT = 30.0 # seconds
+ _LOCK_RETRY_DELAY = 0.25 # seconds
+
+ def _connect_with_retry(self):
+ import time
+
+ import duckdb
+
+ deadline = time.monotonic() + self._LOCK_WAIT
+ last_exc: Exception | None = None
+ while True:
+ try:
+ return duckdb.connect(self._path, read_only=True)
+ except duckdb.Error as exc:
+ message = str(exc).lower()
+ if "does not exist" in message:
+ # The indexer has not created the database file yet.
+ raise IndexNotReadyError(
+ f"DuckDB file {self._path!r} does not exist yet"
+ ) from exc
+ if "lock" not in message:
+ raise
+ last_exc = exc
+ if time.monotonic() >= deadline:
+ break
+ time.sleep(self._LOCK_RETRY_DELAY)
+ # Not an error of ours: the indexer is simply mid-write. Say so and
+ # let the client retry; warn in the log, since a lock held this long
+ # is unusual enough to be worth a look.
+ logger.warning(_LOCK_HINT, self._path, self._LOCK_WAIT)
+ raise IndexBusyError(
+ f"the DuckDB file {self._path!r} was write-locked by the indexer for "
+ f"over {self._LOCK_WAIT:.0f}s"
+ ) from last_exc
+
+ def _query(
+ self, embedding: list[float], k: int, *, with_embeddings: bool = False
+ ) -> list[dict[str, Any]]:
+ import duckdb
+
+ embedding_col = ", embedding" if with_embeddings else ""
+ conn = self._connect_with_retry()
+ try:
+ rows = conn.execute(
+ f"SELECT text, metadata, "
+ f" list_cosine_similarity(embedding, ?::DOUBLE[]) AS score"
+ f"{embedding_col} "
+ f'FROM "{self._table}" '
+ f"WHERE embedding IS NOT NULL "
+ f"ORDER BY score DESC NULLS LAST LIMIT ?",
+ [list(map(float, embedding)), k],
+ ).fetchall()
+ except duckdb.CatalogException as exc:
+ # The file exists but the table has not been created yet.
+ raise IndexNotReadyError(
+ f"table {self._table!r} does not exist yet in {self._path!r}"
+ ) from exc
+ finally:
+ conn.close()
+ results: list[dict[str, Any]] = []
+ for text, metadata, score, *rest in rows:
+ if isinstance(metadata, str):
+ metadata = json.loads(metadata)
+ hit: dict[str, Any] = {
+ "text": text,
+ "metadata": metadata or {},
+ "score": float(score) if score is not None else 0.0,
+ }
+ if with_embeddings:
+ hit["embedding"] = [float(x) for x in rest[0]]
+ results.append(hit)
+ return results
+
+ def _count_rows(self) -> int:
+ conn = self._connect_with_retry()
+ try:
+ (count,) = conn.execute(
+ f'SELECT count(*) FROM "{self._table}" WHERE embedding IS NOT NULL'
+ ).fetchone()
+ finally:
+ conn.close()
+ return int(count)
+
+ def _version(self) -> tuple[int, Any]:
+ """``(row count, newest seen_at)``: an edited document is re-emitted
+ with a fresher ``seen_at``, so in-place edits that keep the chunk
+ count move this where the count alone would not."""
+
+ conn = self._connect_with_retry()
+ try:
+ count, newest = conn.execute(
+ f"SELECT count(*),"
+ f" max(TRY_CAST(json_extract(metadata, '$.seen_at') AS BIGINT)) "
+ f'FROM "{self._table}" WHERE embedding IS NOT NULL'
+ ).fetchone()
+ finally:
+ conn.close()
+ return int(count), newest
+
+ def _fetch_all_rows(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ """Every stored chunk as a BM25 hit dict (read off the event loop).
+
+ Read through the same retrying read-only connections as vector search;
+ the mixin rebuilds the BM25 index only when the row count changes —
+ fine for the static/slow-moving corpora the embedded backend targets.
+ """
+
+ embedding_col = ", embedding" if with_embeddings else ""
+ conn = self._connect_with_retry()
+ try:
+ rows = conn.execute(
+ f'SELECT text, metadata{embedding_col} FROM "{self._table}" '
+ f"WHERE embedding IS NOT NULL"
+ ).fetchall()
+ finally:
+ conn.close()
+ hits = []
+ for row in rows:
+ text, metadata = row[0], row[1]
+ if isinstance(metadata, str):
+ metadata = json.loads(metadata)
+ hit: dict[str, Any] = {"text": text, "metadata": metadata or {}}
+ if with_embeddings:
+ hit["embedding"] = [float(x) for x in row[2]]
+ hits.append(hit)
+ return hits
+
+ # -- document catalog (rag.documents) -------------------------------------
+
+ # The same document identity ``_stats`` counts by.
+ _DOCUMENT_SQL = (
+ "coalesce("
+ "json_extract_string(metadata, '$.path'),"
+ "json_extract_string(metadata, '$.id'),"
+ "json_extract_string(metadata, '$.name'))"
+ )
+
+ async def _catalog_scan(self) -> list[dict[str, Any]]:
+ return await asyncio.to_thread(self._list_documents)
+
+ def _list_documents(self) -> list[dict[str, Any]]:
+ conn = self._connect_with_retry()
+ try:
+ rows = conn.execute(
+ f"SELECT {self._DOCUMENT_SQL} AS document, count(*),"
+ f" any_value(metadata) "
+ f'FROM "{self._table}" WHERE embedding IS NOT NULL '
+ f"GROUP BY document HAVING document IS NOT NULL AND document <> ''"
+ ).fetchall()
+ finally:
+ conn.close()
+ documents = []
+ for document, chunks, metadata in rows:
+ if isinstance(metadata, str):
+ metadata = json.loads(metadata)
+ documents.append(
+ {"id": document, "metadata": metadata or {}, "chunks": int(chunks)}
+ )
+ return documents
+
+ async def document_chunks(
+ self, document: str, *, with_embeddings: bool = False
+ ) -> list[dict[str, Any]]:
+ return await asyncio.to_thread(
+ self._document_chunks, document, with_embeddings
+ )
+
+ def _document_chunks(
+ self, document: str, with_embeddings: bool
+ ) -> list[dict[str, Any]]:
+ embedding_col = ", embedding" if with_embeddings else ""
+ conn = self._connect_with_retry()
+ try:
+ rows = conn.execute(
+ f'SELECT text, metadata{embedding_col} FROM "{self._table}" '
+ f"WHERE embedding IS NOT NULL AND {self._DOCUMENT_SQL} = ?",
+ [document],
+ ).fetchall()
+ finally:
+ conn.close()
+ hits = []
+ for row in rows:
+ text, metadata = row[0], row[1]
+ if isinstance(metadata, str):
+ metadata = json.loads(metadata)
+ hit: dict[str, Any] = {"text": text, "metadata": metadata or {}}
+ if with_embeddings:
+ hit["embedding"] = [float(x) for x in row[2]]
+ hits.append(hit)
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ return await asyncio.to_thread(self._stats)
+
+ def _stats(self) -> dict[str, Any]:
+ conn = self._connect_with_retry()
+ try:
+ # A document is identified by whatever the source reports: ``path``
+ # (fs, s3, sharepoint, pyfilesystem) or ``id`` / ``name`` (gdrive).
+ chunks, documents, last = conn.execute(
+ f"SELECT count(*),"
+ f" count(DISTINCT coalesce("
+ f" json_extract_string(metadata, '$.path'),"
+ f" json_extract_string(metadata, '$.id'),"
+ f" json_extract_string(metadata, '$.name'))),"
+ f" max(TRY_CAST(json_extract(metadata, '$.seen_at') AS BIGINT)) "
+ f'FROM "{self._table}"'
+ ).fetchone()
+ finally:
+ conn.close()
+ out: dict[str, Any] = {"chunks": int(chunks), "documents": int(documents)}
+ if last:
+ out["last_indexed_at"] = int(last)
+ return out
+
+ async def close(self) -> None:
+ await self._close_hybrid() # connections themselves are per-query
diff --git a/serviette/server/accessors/milvus.py b/serviette/server/accessors/milvus.py
new file mode 100644
index 00000000..5d795622
--- /dev/null
+++ b/serviette/server/accessors/milvus.py
@@ -0,0 +1,155 @@
+"""Async Milvus accessor using the ``pymilvus`` async client.
+
+Assumes the indexer wrote chunks into a Milvus collection with fields ``text``
+(VARCHAR), ``metadata`` (JSON) and ``embedding`` (FLOAT_VECTOR). Search uses the
+``COSINE`` metric so the returned distance *is* the cosine similarity.
+"""
+
+from __future__ import annotations
+
+import asyncio
+import json
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+from serviette.server.hybrid import KeywordHybridMixin
+
+
+def _entity_metadata(entity: dict) -> dict[str, Any]:
+ metadata = entity.get("metadata", {})
+ if isinstance(metadata, str):
+ metadata = json.loads(metadata)
+ return metadata or {}
+
+
+class MilvusAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._uri = config.resolved_uri()
+ self._token = config.token
+ self._collection = config.collection
+ self._client = None
+ self._scan_client = None
+ self._init_hybrid(config)
+
+ async def _ensure_client(self):
+ if self._client is None:
+ from pymilvus import AsyncMilvusClient
+
+ kwargs: dict[str, Any] = {"uri": self._uri}
+ if self._token:
+ kwargs["token"] = self._token
+ self._client = AsyncMilvusClient(**kwargs)
+ # A collection must be loaded into memory before it can be searched.
+ await self._client.load_collection(self._collection)
+ return self._client
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ client = await self._ensure_client()
+ output_fields = ["text", "metadata"]
+ if with_embeddings:
+ output_fields.append("embedding")
+ hits = await client.search(
+ collection_name=self._collection,
+ data=[embedding],
+ limit=k,
+ output_fields=output_fields,
+ search_params={"metric_type": "COSINE"},
+ )
+ vector_hits: list[dict[str, Any]] = []
+ # ``hits`` is a list (one entry per query vector) of lists of hits.
+ for hit in hits[0] if hits else []:
+ entity = hit.get("entity", hit)
+ record: dict[str, Any] = {
+ "text": entity.get("text", ""),
+ "metadata": _entity_metadata(entity),
+ "score": float(hit.get("distance", hit.get("score", 0.0))),
+ }
+ if with_embeddings and entity.get("embedding") is not None:
+ record["embedding"] = [float(x) for x in entity["embedding"]]
+ vector_hits.append(record)
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ # Not ``get_collection_stats``: its ``row_count`` covers flushed
+ # (sealed) segments only. The Pathway writer upserts without flushing
+ # — correctly, Milvus discourages per-batch flushes — and a small
+ # corpus never reaches the auto-flush thresholds, so that count stays
+ # 0 while search sees every row. ``count(*)`` includes growing
+ # segments and is Milvus's own recommendation for an exact count.
+ client = await self._ensure_client()
+ rows = await client.query(
+ collection_name=self._collection, filter="", output_fields=["count(*)"]
+ )
+ return int(rows[0].get("count(*)", 0)) if rows else 0
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ # The async client has no full-scan iterator; a short-lived sync client
+ # paginates the whole collection off the event loop. ``query_iterator``
+ # sidesteps Milvus's offset+limit query window.
+ return await asyncio.to_thread(self._scan_all, with_embeddings)
+
+ def _sync_client(self):
+ if self._scan_client is None:
+ from pymilvus import MilvusClient
+
+ kwargs: dict[str, Any] = {"uri": self._uri}
+ if self._token:
+ kwargs["token"] = self._token
+ self._scan_client = MilvusClient(**kwargs)
+ return self._scan_client
+
+ def _scan_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ client = self._sync_client()
+ fields = ["text", "metadata"]
+ if with_embeddings:
+ fields.append("embedding")
+ iterator = client.query_iterator(
+ collection_name=self._collection,
+ filter="",
+ output_fields=fields,
+ batch_size=1000,
+ )
+ hits: list[dict[str, Any]] = []
+ try:
+ while True:
+ batch = iterator.next()
+ if not batch:
+ break
+ for entity in batch:
+ hit: dict[str, Any] = {
+ "text": entity.get("text", ""),
+ "metadata": _entity_metadata(entity),
+ }
+ if with_embeddings and entity.get("embedding") is not None:
+ hit["embedding"] = [float(x) for x in entity["embedding"]]
+ hits.append(hit)
+ finally:
+ iterator.close()
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ count = await self._hybrid_count()
+ return {"chunks": count}
+
+ async def close(self) -> None:
+ await self._close_hybrid()
+ if self._client is not None:
+ await self._client.close()
+ self._client = None
+ if self._scan_client is not None:
+ self._scan_client.close()
+ self._scan_client = None
diff --git a/serviette/server/accessors/mongodb.py b/serviette/server/accessors/mongodb.py
new file mode 100644
index 00000000..a1a62c37
--- /dev/null
+++ b/serviette/server/accessors/mongodb.py
@@ -0,0 +1,122 @@
+"""Async MongoDB Atlas Vector Search accessor using ``pymongo``'s async API.
+
+The indexer's ``pw.io.mongodb`` snapshot sink stores one document per chunk
+(``chunk_id``, ``text``, ``metadata``, ``embedding`` as a number array).
+Retrieval runs an Atlas ``$vectorSearch`` aggregation against the configured
+``vectorSearch`` index (create it on the ``embedding`` path with
+``numDimensions`` matching the embedder and the cosine similarity).
+
+Atlas normalizes the cosine score to ``(1 + cosine) / 2`` ∈ [0, 1]; converted
+back to a plain cosine similarity here to match the accessor contract.
+"""
+
+from __future__ import annotations
+
+import json
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+from serviette.server.hybrid import KeywordHybridMixin
+
+# Atlas recommends ~10-20x the limit for the ANN candidate pool.
+_CANDIDATE_FACTOR = 15
+
+
+def _doc_metadata(doc: dict) -> dict[str, Any]:
+ # The sink stores the pw.Json metadata as a JSON string in BSON.
+ metadata = doc.get("metadata")
+ if isinstance(metadata, str):
+ metadata = json.loads(metadata)
+ return metadata or {}
+
+
+class MongoDbAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._config = config
+ self._client = None
+ self._init_hybrid(config)
+
+ def _ensure_collection(self):
+ if self._client is None:
+ from pymongo import AsyncMongoClient
+
+ self._client = AsyncMongoClient(self._config.connection_string)
+ return self._client[self._config.database][self._config.collection]
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ collection = self._ensure_collection()
+ projection: dict[str, Any] = {
+ "_id": 0,
+ "text": 1,
+ "metadata": 1,
+ "score": {"$meta": "vectorSearchScore"},
+ }
+ if with_embeddings:
+ projection["embedding"] = 1
+ pipeline = [
+ {
+ "$vectorSearch": {
+ "index": self._config.vector_index,
+ "path": "embedding",
+ "queryVector": list(map(float, embedding)),
+ "numCandidates": max(k * _CANDIDATE_FACTOR, 100),
+ "limit": k,
+ }
+ },
+ {"$project": projection},
+ ]
+ vector_hits: list[dict[str, Any]] = []
+ async for doc in await collection.aggregate(pipeline):
+ hit: dict[str, Any] = {
+ "text": doc.get("text", ""),
+ "metadata": _doc_metadata(doc),
+ # Undo Atlas's (1 + cosine) / 2 normalization.
+ "score": 2.0 * float(doc.get("score", 0.5)) - 1.0,
+ }
+ if with_embeddings and doc.get("embedding") is not None:
+ hit["embedding"] = [float(x) for x in doc["embedding"]]
+ vector_hits.append(hit)
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ collection = self._ensure_collection()
+ return int(await collection.estimated_document_count())
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ collection = self._ensure_collection()
+ projection: dict[str, Any] = {"_id": 0, "text": 1, "metadata": 1}
+ if with_embeddings:
+ projection["embedding"] = 1
+ hits: list[dict[str, Any]] = []
+ async for doc in collection.find({}, projection):
+ hit: dict[str, Any] = {
+ "text": doc.get("text", ""),
+ "metadata": _doc_metadata(doc),
+ }
+ if with_embeddings and doc.get("embedding") is not None:
+ hit["embedding"] = [float(x) for x in doc["embedding"]]
+ hits.append(hit)
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ return {"chunks": await self._hybrid_count()}
+
+ async def close(self) -> None:
+ await self._close_hybrid()
+ if self._client is not None:
+ await self._client.close()
+ self._client = None
diff --git a/serviette/server/accessors/pgvector.py b/serviette/server/accessors/pgvector.py
new file mode 100644
index 00000000..f1f37088
--- /dev/null
+++ b/serviette/server/accessors/pgvector.py
@@ -0,0 +1,192 @@
+"""Async pgvector accessor using ``asyncpg``.
+
+Assumes the indexer wrote chunks into a table whose columns include ``text``,
+``metadata`` (jsonb) and ``embedding`` (a ``vector(n)`` column from the pgvector
+extension). Retrieval uses pgvector's cosine-distance operator ``<=>`` and
+converts distance to a cosine *similarity* (``1 - distance``) for the response.
+"""
+
+from __future__ import annotations
+
+import json
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+from serviette.server.hybrid import KeywordHybridMixin
+
+
+def _to_vector_literal(embedding: list[float]) -> str:
+ """Render an embedding as a pgvector text literal: ``[1,2,3]``."""
+
+ return "[" + ",".join(repr(float(x)) for x in embedding) + "]"
+
+
+def _parse_metadata(value: Any) -> dict[str, Any]:
+ return json.loads(value) if isinstance(value, str) else (value or {})
+
+
+def _parse_embedding(value: Any) -> list[float]:
+ # asyncpg returns a pgvector ``vector`` column as its text literal
+ # ``[1,2,3]`` (valid JSON) unless a codec is registered.
+ if isinstance(value, str):
+ value = json.loads(value)
+ return [float(x) for x in value]
+
+
+class PgVectorAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._dsn = config.connection_string
+ self._table = config.table
+ self._pool = None
+ self._init_hybrid(config)
+
+ async def _ensure_pool(self):
+ if self._pool is None:
+ import asyncpg
+
+ self._pool = await asyncpg.create_pool(dsn=self._dsn)
+ return self._pool
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ pool = await self._ensure_pool()
+ vec = _to_vector_literal(embedding)
+ embedding_col = ", embedding" if with_embeddings else ""
+ # ``embedding <=> $1`` is cosine distance (0 = identical). Order ascending
+ # by distance and convert to similarity in the projection.
+ query = (
+ f"SELECT text, metadata, 1 - (embedding <=> $1::vector) AS score"
+ f"{embedding_col} "
+ f"FROM {self._table} "
+ f"ORDER BY embedding <=> $1::vector ASC "
+ f"LIMIT $2"
+ )
+ async with pool.acquire() as conn:
+ rows = await conn.fetch(query, vec, k)
+ vector_hits: list[dict[str, Any]] = []
+ for row in rows:
+ hit: dict[str, Any] = {
+ "text": row["text"],
+ "metadata": _parse_metadata(row["metadata"]),
+ "score": float(row["score"]),
+ }
+ if with_embeddings:
+ hit["embedding"] = _parse_embedding(row["embedding"])
+ vector_hits.append(hit)
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ pool = await self._ensure_pool()
+ async with pool.acquire() as conn:
+ return int(await conn.fetchval(f"SELECT count(*) FROM {self._table}"))
+
+ async def _hybrid_version(self) -> tuple[int, Any]:
+ # Newest seen_at moves on in-place edits the count cannot see.
+ pool = await self._ensure_pool()
+ async with pool.acquire() as conn:
+ row = await conn.fetchrow(
+ f"SELECT count(*) AS chunks, "
+ f"max((metadata->>'seen_at')::bigint) AS newest FROM {self._table}"
+ )
+ return int(row["chunks"]), row["newest"]
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ pool = await self._ensure_pool()
+ embedding_col = ", embedding" if with_embeddings else ""
+ async with pool.acquire() as conn:
+ rows = await conn.fetch(
+ f"SELECT text, metadata{embedding_col} FROM {self._table}"
+ )
+ hits: list[dict[str, Any]] = []
+ for row in rows:
+ hit: dict[str, Any] = {
+ "text": row["text"],
+ "metadata": _parse_metadata(row["metadata"]),
+ }
+ if with_embeddings:
+ hit["embedding"] = _parse_embedding(row["embedding"])
+ hits.append(hit)
+ return hits
+
+ # -- document catalog (rag.documents) -------------------------------------
+
+ # The same document identity ``stats`` counts by.
+ _DOCUMENT_SQL = "coalesce(metadata->>'path', metadata->>'id', metadata->>'name')"
+
+ async def _catalog_scan(self) -> list[dict[str, Any]]:
+ pool = await self._ensure_pool()
+ async with pool.acquire() as conn:
+ rows = await conn.fetch(
+ f"SELECT {self._DOCUMENT_SQL} AS document, count(*) AS chunks,"
+ f" min(metadata::text) AS metadata FROM {self._table} "
+ f"GROUP BY document HAVING {self._DOCUMENT_SQL} <> ''"
+ )
+ return [
+ {
+ "id": row["document"],
+ "metadata": _parse_metadata(row["metadata"]),
+ "chunks": int(row["chunks"]),
+ }
+ for row in rows
+ ]
+
+ async def document_chunks(
+ self, document: str, *, with_embeddings: bool = False
+ ) -> list[dict[str, Any]]:
+ pool = await self._ensure_pool()
+ embedding_col = ", embedding" if with_embeddings else ""
+ async with pool.acquire() as conn:
+ rows = await conn.fetch(
+ f"SELECT text, metadata{embedding_col} FROM {self._table} "
+ f"WHERE {self._DOCUMENT_SQL} = $1",
+ document,
+ )
+ hits: list[dict[str, Any]] = []
+ for row in rows:
+ hit: dict[str, Any] = {
+ "text": row["text"],
+ "metadata": _parse_metadata(row["metadata"]),
+ }
+ if with_embeddings:
+ hit["embedding"] = _parse_embedding(row["embedding"])
+ hits.append(hit)
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ pool = await self._ensure_pool()
+ async with pool.acquire() as conn:
+ # Document identity per source type: path (fs, s3, sharepoint,
+ # pyfilesystem) or id / name (gdrive).
+ row = await conn.fetchrow(
+ f"SELECT count(*) AS chunks,"
+ f" count(DISTINCT coalesce(metadata->>'path', metadata->>'id',"
+ f" metadata->>'name')) AS documents,"
+ f" max((metadata->>'seen_at')::bigint) AS last_indexed_at "
+ f"FROM {self._table}"
+ )
+ out: dict[str, Any] = {
+ "chunks": int(row["chunks"]),
+ "documents": int(row["documents"]),
+ }
+ if row["last_indexed_at"]:
+ out["last_indexed_at"] = int(row["last_indexed_at"])
+ return out
+
+ async def close(self) -> None:
+ await self._close_hybrid()
+ if self._pool is not None:
+ await self._pool.close()
+ self._pool = None
diff --git a/serviette/server/accessors/pinecone.py b/serviette/server/accessors/pinecone.py
new file mode 100644
index 00000000..96b4384c
--- /dev/null
+++ b/serviette/server/accessors/pinecone.py
@@ -0,0 +1,108 @@
+"""Async Pinecone accessor using the ``pinecone`` SDK's asyncio support.
+
+The indexer's ``pw.io.pinecone`` sink upserts each chunk keyed by ``chunk_id``
+with ``text`` and the JSON-serialized source metadata as record metadata. With
+a cosine-metric index the returned score *is* the cosine similarity.
+"""
+
+from __future__ import annotations
+
+import json
+import os
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+
+
+class PineconeAccessor(AsyncVectorAccessor):
+ # MMR works (queries can return vectors); in-process BM25 hybrid does not —
+ # Pinecone has no scan-all-vectors API to build the keyword corpus from.
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ if getattr(config, "hybrid", False):
+ raise ValueError(
+ "hybrid retrieval is not supported on the Pinecone backend: it "
+ "has no API to enumerate all stored vectors, so an in-process "
+ "BM25 corpus cannot be built. Native hybrid needs a separate "
+ "sparse index fed by the indexer (planned); "
+ "for in-process hybrid today use duckdb, qdrant, pgvector, "
+ "milvus, weaviate, chroma or mongodb."
+ )
+ self._config = config
+ self._pc = None
+ self._index = None
+
+ async def _ensure_index(self):
+ if self._index is None:
+ from pinecone import PineconeAsyncio
+
+ cfg = self._config
+ api_key = cfg.api_key or os.environ.get("PINECONE_API_KEY")
+ # ``host`` (if set) points at the control plane — e.g. Pinecone
+ # Local. The data-plane host differs per index even locally, so it
+ # is always resolved through describe_index.
+ self._pc = PineconeAsyncio(api_key=api_key, host=cfg.host)
+ description = await self._pc.describe_index(cfg.index_name)
+ index_host = description.host
+ # Pinecone Local serves indexes over plain HTTP but reports their
+ # hosts as https; mirror the control plane's scheme.
+ if cfg.host and cfg.host.startswith("http://"):
+ index_host = index_host.replace("https://", "http://", 1)
+ self._index = self._pc.IndexAsyncio(host=index_host)
+ return self._index
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ # ``query_text`` is accepted for interface parity but unused: Pinecone
+ # rejects hybrid at startup, so this path is always pure-vector.
+ index = await self._ensure_index()
+ response = await index.query(
+ vector=list(map(float, embedding)),
+ top_k=k,
+ namespace=self._config.namespace,
+ include_metadata=True,
+ include_values=with_embeddings,
+ )
+ results: list[dict[str, Any]] = []
+ for match in response.matches:
+ meta = dict(match.metadata or {})
+ raw = meta.get("metadata")
+ metadata = json.loads(raw) if isinstance(raw, str) else (raw or {})
+ hit: dict[str, Any] = {
+ "text": meta.get("text", ""),
+ "metadata": metadata,
+ "score": float(match.score),
+ }
+ if with_embeddings and getattr(match, "values", None):
+ hit["embedding"] = [float(x) for x in match.values]
+ results.append(hit)
+ return results
+
+ async def stats(self) -> dict[str, Any]:
+ index = await self._ensure_index()
+ description = await index.describe_index_stats()
+ namespace = self._config.namespace
+ if namespace:
+ ns = (description.namespaces or {}).get(namespace)
+ count = ns.vector_count if ns else 0
+ else:
+ count = description.total_vector_count
+ return {"chunks": int(count or 0)}
+
+ async def close(self) -> None:
+ if self._index is not None:
+ await self._index.close()
+ self._index = None
+ if self._pc is not None:
+ await self._pc.close()
+ self._pc = None
diff --git a/serviette/server/accessors/qdrant.py b/serviette/server/accessors/qdrant.py
new file mode 100644
index 00000000..b92a1040
--- /dev/null
+++ b/serviette/server/accessors/qdrant.py
@@ -0,0 +1,195 @@
+"""Async Qdrant accessor using ``qdrant-client``.
+
+The indexer creates the collection with a single **named** dense vector slot
+(:data:`QDRANT_VECTOR_NAME`, cosine) and the schema-driven ``pw.io.qdrant`` sink
+binds the ``embedding`` column to it; the remaining columns (``text``,
+``metadata``) live in the point payload. Searches therefore address that slot by
+name (``using=``), and the returned score *is* the cosine similarity.
+
+Hybrid mode (``hybrid: true``) adds a keyword leg: an in-process BM25 index
+is built by scrolling the collection's texts and fused with the vector
+results via reciprocal-rank fusion. The BM25 corpus is capped at
+``hybrid_max_chunks`` (in-process indexing does not scale to tens of
+millions of chunks); Qdrant-native sparse vectors are the planned
+replacement at that scale.
+"""
+
+from __future__ import annotations
+
+import logging
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor, document_key
+from serviette.server.hybrid import KeywordHybridMixin
+
+logger = logging.getLogger(__name__)
+
+_SCROLL_PAGE = 1024
+
+# The name of the collection's dense vector slot. Must match the slot
+# ``prepare._prepare_qdrant`` creates and the indexer's ``embedding`` column.
+QDRANT_VECTOR_NAME = "embedding"
+
+
+class QdrantAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._url = config.rest_url()
+ self._api_key = config.api_key
+ self._collection = config.collection
+ self._client = None
+ self._init_hybrid(config)
+
+ def _ensure_client(self):
+ if self._client is None:
+ from qdrant_client import AsyncQdrantClient
+
+ self._client = AsyncQdrantClient(url=self._url, api_key=self._api_key)
+ return self._client
+
+ @staticmethod
+ def _to_hit(point, with_embeddings: bool) -> dict[str, Any]:
+ payload = point.payload or {}
+ hit: dict[str, Any] = {
+ "text": payload.get("text", ""),
+ "metadata": payload.get("metadata") or {},
+ }
+ if with_embeddings:
+ # Named-vector collections return a dict {slot: vector}.
+ vector = getattr(point, "vector", None)
+ if isinstance(vector, dict):
+ vector = vector.get(QDRANT_VECTOR_NAME)
+ if vector is not None:
+ hit["embedding"] = [float(x) for x in vector]
+ return hit
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ client = self._ensure_client()
+ response = await client.query_points(
+ collection_name=self._collection,
+ query=embedding,
+ using=QDRANT_VECTOR_NAME,
+ limit=k,
+ with_payload=True,
+ with_vectors=with_embeddings,
+ )
+ vector_hits = [
+ {**self._to_hit(point, with_embeddings), "score": float(point.score)}
+ for point in response.points
+ ]
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ # Exact: the approximate count can stay put over small changes and
+ # would leave the BM25 index stale until the timed refresh.
+ client = self._ensure_client()
+ return int(
+ (await client.count(collection_name=self._collection, exact=True)).count
+ )
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ client = self._ensure_client()
+ hits: list[dict[str, Any]] = []
+ offset = None
+ while True:
+ points, offset = await client.scroll(
+ collection_name=self._collection,
+ limit=_SCROLL_PAGE,
+ offset=offset,
+ with_payload=True,
+ with_vectors=with_embeddings,
+ )
+ hits.extend(self._to_hit(point, with_embeddings) for point in points)
+ if offset is None:
+ break
+ return hits
+
+ # -- document catalog (rag.documents) -------------------------------------
+
+ async def _catalog_scan(self) -> list[dict[str, Any]]:
+ # Metadata only: the texts are most of the payload and the catalog
+ # does not need them.
+ client = self._ensure_client()
+ documents: dict[str, dict[str, Any]] = {}
+ offset = None
+ while True:
+ points, offset = await client.scroll(
+ collection_name=self._collection,
+ limit=_SCROLL_PAGE,
+ offset=offset,
+ with_payload=["metadata"],
+ with_vectors=False,
+ )
+ for point in points:
+ metadata = (point.payload or {}).get("metadata") or {}
+ key = document_key(metadata)
+ if key is None:
+ continue
+ entry = documents.setdefault(
+ key, {"id": key, "metadata": metadata, "chunks": 0}
+ )
+ entry["chunks"] += 1
+ if offset is None:
+ break
+ return list(documents.values())
+
+ async def document_chunks(
+ self, document: str, *, with_embeddings: bool = False
+ ) -> list[dict[str, Any]]:
+ # A payload filter on the document identity — evaluated server-side,
+ # so only the document's points travel (no payload index is created:
+ # the accessor never alters the collection).
+ from qdrant_client import models
+
+ client = self._ensure_client()
+ selector = models.Filter(
+ should=[
+ models.FieldCondition(
+ key=f"metadata.{field}", match=models.MatchValue(value=document)
+ )
+ for field in ("path", "id", "name")
+ ]
+ )
+ hits: list[dict[str, Any]] = []
+ offset = None
+ while True:
+ points, offset = await client.scroll(
+ collection_name=self._collection,
+ scroll_filter=selector,
+ limit=_SCROLL_PAGE,
+ offset=offset,
+ with_payload=True,
+ with_vectors=with_embeddings,
+ )
+ hits.extend(
+ self._to_hit(point, with_embeddings)
+ for point in points
+ if document_key((point.payload or {}).get("metadata")) == document
+ )
+ if offset is None:
+ break
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ client = self._ensure_client()
+ result = await client.count(collection_name=self._collection, exact=False)
+ return {"chunks": int(result.count)}
+
+ async def close(self) -> None:
+ await self._close_hybrid()
+ if self._client is not None:
+ await self._client.close()
+ self._client = None
diff --git a/serviette/server/accessors/weaviate.py b/serviette/server/accessors/weaviate.py
new file mode 100644
index 00000000..8b64c9d1
--- /dev/null
+++ b/serviette/server/accessors/weaviate.py
@@ -0,0 +1,127 @@
+"""Async Weaviate accessor using the v4 ``weaviate-client``.
+
+The indexer's ``pw.io.weaviate`` sink stores the chunk vector as the object
+vector and the remaining columns as properties (``chunk_id``, ``text``, and the
+source metadata serialized to a JSON string). Weaviate reports a cosine
+*distance*; converted here to a similarity (``1 - distance``).
+"""
+
+from __future__ import annotations
+
+import json
+from typing import Any
+
+from serviette.server.accessors.abstract import AsyncVectorAccessor
+from serviette.server.hybrid import KeywordHybridMixin
+
+
+def _props_to_hit(props: dict) -> dict[str, Any]:
+ props = props or {}
+ raw = props.get("metadata")
+ metadata = json.loads(raw) if isinstance(raw, str) else (raw or {})
+ return {"text": props.get("text", ""), "metadata": metadata}
+
+
+def _object_vector(obj) -> list[float] | None:
+ # v4 returns named vectors as a dict; the default (unnamed) vector lives
+ # under the "default" key.
+ vector = getattr(obj, "vector", None)
+ if isinstance(vector, dict):
+ vector = vector.get("default")
+ return [float(x) for x in vector] if vector else None
+
+
+class WeaviateAccessor(KeywordHybridMixin, AsyncVectorAccessor):
+ supports_embeddings = True
+
+ def __init__(self, config) -> None:
+ self._config = config
+ self._client = None
+ self._init_hybrid(config)
+
+ async def _ensure_client(self):
+ if self._client is None:
+ import weaviate
+ from weaviate.connect import ConnectionParams
+
+ cfg = self._config
+ auth = (
+ weaviate.auth.AuthApiKey(cfg.api_key) if cfg.api_key else None
+ )
+ self._client = weaviate.WeaviateAsyncClient(
+ connection_params=ConnectionParams.from_params(
+ http_host=cfg.http_host,
+ http_port=cfg.http_port,
+ http_secure=cfg.http_secure,
+ grpc_host=cfg.grpc_host or cfg.http_host,
+ grpc_port=cfg.grpc_port,
+ grpc_secure=cfg.grpc_secure,
+ ),
+ auth_client_secret=auth,
+ )
+ await self._client.connect()
+ return self._client
+
+ async def retrieve(self, embedding: list[float], k: int) -> list[dict[str, Any]]:
+ return await self.retrieve_ex(embedding, k)
+
+ async def retrieve_ex(
+ self,
+ embedding: list[float],
+ k: int,
+ *,
+ query_text: str | None = None,
+ with_embeddings: bool = False,
+ ) -> list[dict[str, Any]]:
+ client = await self._ensure_client()
+ from weaviate.classes.query import MetadataQuery
+
+ collection = client.collections.get(self._config.collection)
+ response = await collection.query.near_vector(
+ near_vector=list(map(float, embedding)),
+ limit=k,
+ include_vector=with_embeddings,
+ return_metadata=MetadataQuery(distance=True),
+ )
+ vector_hits: list[dict[str, Any]] = []
+ for obj in response.objects:
+ distance = obj.metadata.distance if obj.metadata else None
+ hit = _props_to_hit(obj.properties)
+ hit["score"] = 1.0 - float(distance) if distance is not None else 0.0
+ if with_embeddings:
+ vec = _object_vector(obj)
+ if vec is not None:
+ hit["embedding"] = vec
+ vector_hits.append(hit)
+ return await self._fuse(vector_hits, query_text, k, with_embeddings)
+
+ # -- hybrid hooks (KeywordHybridMixin) ------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ client = await self._ensure_client()
+ collection = client.collections.get(self._config.collection)
+ result = await collection.aggregate.over_all(total_count=True)
+ return int(result.total_count or 0)
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ client = await self._ensure_client()
+ collection = client.collections.get(self._config.collection)
+ hits: list[dict[str, Any]] = []
+ # Cursor-based full scan (server-paged), the v4 way to read every object.
+ async for obj in collection.iterator(include_vector=with_embeddings):
+ hit = _props_to_hit(obj.properties)
+ if with_embeddings:
+ vec = _object_vector(obj)
+ if vec is not None:
+ hit["embedding"] = vec
+ hits.append(hit)
+ return hits
+
+ async def stats(self) -> dict[str, Any]:
+ return {"chunks": await self._hybrid_count()}
+
+ async def close(self) -> None:
+ await self._close_hybrid()
+ if self._client is not None:
+ await self._client.close()
+ self._client = None
diff --git a/serviette/server/bm25.py b/serviette/server/bm25.py
new file mode 100644
index 00000000..87535383
--- /dev/null
+++ b/serviette/server/bm25.py
@@ -0,0 +1,77 @@
+"""Minimal in-process BM25 index shared by hybrid-capable accessors.
+
+Kept dependency-free on purpose: hybrid search must not pull in a search
+library for backends (embedded DuckDB, Qdrant) whose native keyword scoring
+serviette does not use yet. Tens of thousands of chunks tokenize in well
+under a second; the accessors cap corpus size and fall back to pure vector
+search beyond it — at that scale a backend-native sparse index is the right
+tool (native sparse-vector hybrid is planned).
+"""
+
+from __future__ import annotations
+
+import math
+import re
+from typing import Any
+
+_TOKEN_RE = re.compile(r"\w+")
+
+
+def _tokenize(text: str) -> list[str]:
+ return _TOKEN_RE.findall(text.lower())
+
+
+class Bm25Index:
+ """Okapi BM25 (k1=1.5, b=0.75) over pre-built hit dicts.
+
+ ``hits`` are accessor result dicts (``text`` / ``metadata`` and optionally
+ ``embedding``); :meth:`search` returns the same dicts with a BM25
+ ``score``. ``doc_count`` and ``has_embeddings`` let the owning accessor
+ decide when a rebuild is due.
+ """
+
+ _K1 = 1.5
+ _B = 0.75
+
+ def __init__(self, hits: list[dict[str, Any]], has_embeddings: bool) -> None:
+ self.has_embeddings = has_embeddings
+ self.doc_count = len(hits)
+ self._hits = hits
+ self._doc_terms: list[dict[str, int]] = []
+ doc_freq: dict[str, int] = {}
+ total_len = 0
+ for hit in hits:
+ terms: dict[str, int] = {}
+ for token in _tokenize(hit["text"]):
+ terms[token] = terms.get(token, 0) + 1
+ self._doc_terms.append(terms)
+ total_len += sum(terms.values())
+ for token in terms:
+ doc_freq[token] = doc_freq.get(token, 0) + 1
+ self._avg_len = (total_len / self.doc_count) if self.doc_count else 0.0
+ n = self.doc_count
+ self._idf = {
+ token: math.log(1.0 + (n - df + 0.5) / (df + 0.5))
+ for token, df in doc_freq.items()
+ }
+
+ def search(self, query: str, k: int) -> list[dict[str, Any]]:
+ query_tokens = [t for t in _tokenize(query) if t in self._idf]
+ if not query_tokens or not self.doc_count:
+ return []
+ scored: list[tuple[float, int]] = []
+ for i, terms in enumerate(self._doc_terms):
+ doc_len = sum(terms.values())
+ score = 0.0
+ for token in query_tokens:
+ tf = terms.get(token)
+ if not tf:
+ continue
+ denom = tf + self._K1 * (
+ 1 - self._B + self._B * doc_len / (self._avg_len or 1.0)
+ )
+ score += self._idf[token] * tf * (self._K1 + 1) / denom
+ if score > 0.0:
+ scored.append((score, i))
+ scored.sort(key=lambda pair: -pair[0])
+ return [{**self._hits[i], "score": score} for score, i in scored[:k]]
diff --git a/serviette/server/config.py b/serviette/server/config.py
new file mode 100644
index 00000000..53e32b1b
--- /dev/null
+++ b/serviette/server/config.py
@@ -0,0 +1,13 @@
+"""Config loading/validation for the server command."""
+
+from __future__ import annotations
+
+from pathlib import Path
+
+from serviette.config.schema import ServietteConfig, load_config
+
+
+def load_server_config(path: str | Path) -> ServietteConfig:
+ """Load a config file and assert it has what the server needs."""
+
+ return load_config(path).for_server()
diff --git a/serviette/server/decompose.py b/serviette/server/decompose.py
new file mode 100644
index 00000000..542e6964
--- /dev/null
+++ b/serviette/server/decompose.py
@@ -0,0 +1,57 @@
+"""Query decomposition for multi-hop questions.
+
+One LLM call turns a question that chains several facts into standalone
+search queries, one per fact. Retrieval then runs per sub-query and the
+lists are fused (see :mod:`serviette.server.ranking`), so chunks belonging
+to different hops stop competing for the same top-k slots — the failure
+mode single-query retrieval hits on multi-hop benchmarks like FRAMES.
+"""
+
+from __future__ import annotations
+
+import logging
+import re
+
+from serviette.server.llm import AsyncLLM
+
+logger = logging.getLogger(__name__)
+
+_DECOMPOSE_PROMPT = """\
+Split the question below into at most {n} standalone search queries, one per \
+line, each retrieving ONE fact needed to answer it. Queries must be \
+self-contained (no pronouns referring to other lines). If the question needs \
+only one fact, output the question itself as the single query. Output only \
+the queries, no numbering and no commentary.
+
+Question: {query}"""
+
+# A list marker the model may still prepend despite the prompt ("1. ", "12) ",
+# "- ", "* "). After digits a dot or bracket is required, so a query that
+# merely starts with a number ("1984 novel author") keeps it — that number is
+# usually the very fact the retrieval needs.
+_LIST_MARKER = re.compile(r"^\s*(?:[-*\u2022]|\d{1,3}[.)])\s+")
+
+
+async def decompose_query(
+ llm: AsyncLLM, query: str, max_subqueries: int
+) -> list[str]:
+ """Return retrieval queries for ``query``: itself plus LLM sub-queries.
+
+ The original question always stays first — it carries cross-hop context
+ no sub-query has. Degrades to just the original on any LLM hiccup or
+ unparseable output (never fails retrieval over an optimization).
+ """
+
+ try:
+ reply = await llm.raw(
+ _DECOMPOSE_PROMPT.format(n=max_subqueries, query=query)
+ )
+ except Exception: # noqa: BLE001 - decomposition must never break /rag
+ logger.warning("query decomposition failed; using the original query only")
+ return [query]
+ subqueries = []
+ for line in reply.splitlines():
+ cleaned = _LIST_MARKER.sub("", line, count=1).strip()
+ if cleaned and cleaned.lower() != query.strip().lower():
+ subqueries.append(cleaned)
+ return [query] + subqueries[:max_subqueries]
diff --git a/serviette/server/documents.py b/serviette/server/documents.py
new file mode 100644
index 00000000..4a7bfacd
--- /dev/null
+++ b/serviette/server/documents.py
@@ -0,0 +1,972 @@
+"""Document-level questions for ``/rag`` (``rag.documents``).
+
+Top-k chunk retrieval answers "what does the corpus say about X". It cannot
+answer questions about documents as objects: how many there are, which ones
+exist, what a named file says as a whole, how two files differ. Everything
+here is the deterministic half of that mode — the server decides *when* to
+use it (see ``create_app``):
+
+* the catalog helpers turn the accessor's per-document listing into names,
+ resolve the names a question mentions, and render the listing as context;
+* :func:`arbitrate` is the one short LLM call made after a failed ordinary
+ attempt, deciding between "search wider" and this mode;
+* the context builders pick what the answering call sees for one document
+ or for a comparison, always within a fixed character budget — the cost of
+ a request does not grow with the size of the documents.
+
+There is no notion of a document *version*: two versions are simply two
+documents that share most of their lines, which :func:`compare_context`
+detects and turns into a diff.
+"""
+
+from __future__ import annotations
+
+import datetime
+import difflib
+import logging
+import math
+import posixpath
+import re
+import unicodedata
+from collections import Counter
+from dataclasses import dataclass, field
+from typing import Any
+
+from serviette.server.accessors.abstract import document_key
+from serviette.server.llm import AsyncLLM
+
+logger = logging.getLogger(__name__)
+
+CATALOG_SYSTEM_PROMPT = (
+ "You answer questions about a collection of indexed documents using only "
+ "the catalog below. The catalog is computed by the system and is "
+ "authoritative: never count or list documents in any other way. It covers "
+ "indexed documents only — files that produced no text are not in it, so "
+ "say \"indexed documents\" rather than claiming to know every file in a "
+ "folder. Answer in the language of the question."
+)
+
+DOCUMENT_SYSTEM_PROMPT = (
+ "Answer the user's question about the document below using only the "
+ "provided excerpts, all of which come from that document. Their order is "
+ "not guaranteed to match the document. If the header says only part of "
+ "the document is shown, say that the answer is based on a part of it. "
+ "Answer in the language of the question."
+)
+
+COMPARE_SYSTEM_PROMPT = (
+ "Answer the user's question about the documents below using only the "
+ "provided material, which the system prepared by comparing the documents: "
+ "the first item says what was compared and gives exact totals, the rest "
+ "are the differences themselves. Describe what actually differs — what "
+ "was added, removed or changed, with specifics (section numbers, names, "
+ "figures), grouped by topic; never answer with the totals alone. Ignore "
+ "differences that are only spacing, hyphenation or punctuation. End with "
+ "the totals exactly as given and, if not all differences are shown, say "
+ "that the description covers only part of them. Answer in the language "
+ "of the question."
+)
+
+# For documents compared by excerpts rather than by a diff: there are no
+# computed totals here, and a model asked for totals invents them.
+EXCERPTS_SYSTEM_PROMPT = (
+ "Answer the user's question about the documents below using only the "
+ "provided material. The first item lists the documents; each of the "
+ "others is an excerpt marked with the name of the file it comes from. "
+ "These are a few excerpts per document, not the documents in full and "
+ "not a computed list of their differences: say only what the excerpts "
+ "show, say plainly that the answer rests on excerpts, and never state "
+ "how many differences there are. Answer in the language of the question."
+)
+
+# Goes with :func:`labeled`. Without it the model answers "which documents
+# do you have" from the handful of file names it happens to see — a confident,
+# incomplete list. The marker hands such questions to the catalog instead.
+SOURCE_LABELS_NOTE = (
+ "Each context excerpt starts with the name of the file it comes from. "
+ "The excerpts are a small sample: the file names on them are not the "
+ "list of indexed documents, and a few excerpts cannot show how whole "
+ "documents differ. If the question asks which documents exist, asks to "
+ "list them, asks about their dates or sizes, or asks what differs or "
+ "changed between documents or versions of a document, reply exactly "
+ '"{marker}".'
+)
+
+EXPLAIN_SYSTEM_PROMPT = (
+ "The user's question could not be answered as asked. Using only the facts "
+ "below, tell the user briefly what the problem is and what they can do "
+ "instead. Do not attempt to answer the question itself. Answer in the "
+ "language of the question."
+)
+
+_ARBITER_PROMPT = """\
+You route a question asked to a document-search assistant. A first search \
+over document contents found no answer.
+
+Indexed documents ({shown}):
+{names}
+
+Reply with exactly two lines:
+MODE: search | catalog | documents
+FILES: names separated by ";" (empty unless MODE is documents)
+
+search — the answer would be inside document contents and a wider search \
+may still find it. Also choose this for a question on a topic that has \
+nothing to do with these documents, and whenever unsure.
+catalog — the question is about the collection itself: how many documents \
+there are, which ones exist, their names, dates, sizes or types.
+documents — the question is about one or more specific documents as a \
+whole: what a document says, a summary of it, or how documents differ. Put \
+them in FILES, copying names from the list when they match, otherwise as \
+the user wrote them.
+
+Question: {query}"""
+
+# Extensions that mark a word in a question as a file name even when no such
+# file is indexed (the extensions of indexed files are added at run time).
+_FILE_EXTENSIONS = {
+ "pdf", "doc", "docx", "xls", "xlsx", "ppt", "pptx", "odt", "rtf", "txt",
+ "md", "csv", "html", "htm", "json", "xml", "eml", "epub",
+}
+# A misspelled name resolves to a document only at this similarity, and only
+# when no other document comes within the margin.
+_CLOSE_NAME = 0.85
+_CLOSE_NAME_MARGIN = 0.05
+# Two documents sharing at least this fraction of their lines are compared
+# as versions of one text (a diff); below it they are different documents.
+_VERSION_OVERLAP = 0.3
+# Lines shorter than this (after squashing) are not compared: codes and
+# table cells repeat throughout a document and say nothing on their own.
+_MIN_LINE = 12
+# From this many lines on, a chunk's first and last line are taken to be cut
+# by the splitter and are not compared (shorter chunks are whole paragraphs).
+_EDGE_LINES = 3
+# A line whose digit-masked form occurs at least this often in *both*
+# documents is running matter (page headers, numbered rows): its digits are
+# ignored, so a page number or an edition date in a header is not a change.
+# Low on purpose: a header repeats once per page, and short documents have
+# few pages.
+_RUNNING_LINES = 5
+# A passage only in one document and a passage only in the other that share
+# at least this fraction of their words are one passage edited.
+_CHANGED_SIMILARITY = 0.5
+# Pairing is quadratic in the differing passages; past this many pairs they
+# are reported as plain additions/removals instead.
+_MAX_PAIRINGS = 400_000
+# Differences shorter than this are shown after the longer ones: a stray
+# line is more often an artifact of text extraction than a change.
+_SUBSTANTIAL = 80
+
+
+def document_name(entry: dict[str, Any]) -> str:
+ """The name a person would use for a catalog entry: the source's own
+ ``name`` (gdrive) or the last component of its path."""
+
+ metadata = entry.get("metadata") or {}
+ name = metadata.get("name")
+ if isinstance(name, str) and name:
+ return name
+ key = str(entry["id"])
+ return posixpath.basename(key.replace("\\", "/").rstrip("/")) or key
+
+
+def _fold(value: str) -> str:
+ return value.casefold().strip()
+
+
+def _stem(name: str) -> str:
+ return posixpath.splitext(name)[0]
+
+
+# The name index of the catalog last seen: the accessor hands out the same
+# list object until the index changes, so one entry is enough.
+_name_index_cache: tuple[int, int, tuple] | None = None
+
+
+def _name_index(catalog: list[dict[str, Any]]) -> tuple:
+ """``(known, longest, extension_end, file_like)`` for :func:`mentioned_names`:
+ folded catalog names and paths -> spelling in the catalog, the longest of
+ them, and the two regexes for file extensions seen in the catalog."""
+
+ global _name_index_cache
+ if _name_index_cache is not None:
+ cached_id, cached_len, index = _name_index_cache
+ if cached_id == id(catalog) and cached_len == len(catalog):
+ return index
+ known: dict[str, str] = {}
+ extensions = set(_FILE_EXTENSIONS)
+ longest = 0
+ for entry in catalog:
+ name = document_name(entry)
+ for candidate in (str(entry["id"]), name):
+ needle = _fold(candidate)
+ if "." not in posixpath.basename(needle):
+ continue
+ known.setdefault(needle, candidate)
+ longest = max(longest, len(needle))
+ extension = posixpath.splitext(_fold(name))[1].lstrip(".")
+ if extension:
+ extensions.add(extension)
+ extension_end = re.compile(
+ r"\.(?:" + "|".join(re.escape(ext) for ext in sorted(extensions)) + r")(?![\w])"
+ )
+ file_like = re.compile(r"(? list[str]:
+ """Document names the question spells out literally, in question order.
+
+ Deliberately strict — this check runs before any search and bypasses it:
+ only a full path or a file name *with its extension* counts, bounded by
+ non-word characters. A bare stem ("report") is too often an ordinary
+ word; such references are left to :func:`arbitrate`. Names of files that
+ are not indexed are returned as well (as written), for
+ :func:`resolve_names` to report.
+
+ Runs in time proportional to the question, not to the catalog: every
+ ``.ext`` in the question is a candidate end of a name, and the text
+ before it is looked up in a dict of catalog names.
+ """
+
+ folded = _fold(query)
+ known, longest, extension_end, file_like = _name_index(catalog)
+
+ found: dict[str, int] = {}
+ claimed: list[tuple[int, int]] = []
+ for match in extension_end.finditer(folded):
+ end = match.end()
+ # The longest catalog name ending here wins, so a full path beats
+ # the bare file name it ends with. A name may contain spaces, so
+ # every earlier position is a possible start — bounded by the
+ # longest name in the catalog.
+ for start in range(max(0, end - longest), end):
+ if start and (folded[start - 1].isalnum() or folded[start - 1] in "_./\\"):
+ continue
+ candidate = known.get(folded[start:end])
+ if candidate is not None:
+ found.setdefault(candidate, start)
+ claimed.append((start, end))
+ break
+ # A file name that is not in the catalog is a mention too: the person
+ # asked about a specific file, and "there is no such file" is the answer
+ # — a search over other documents' contents would not be.
+ for match in file_like.finditer(folded):
+ if any(s <= match.start() < e for s, e in claimed):
+ continue
+ found.setdefault(query[match.start() : match.end()], match.start())
+ return sorted(found, key=found.__getitem__)
+
+
+@dataclass
+class Resolution:
+ """Catalog entries for the names a question refers to."""
+
+ found: list[dict[str, Any]] = field(default_factory=list)
+ # name -> close catalog names offered instead
+ missing: dict[str, list[str]] = field(default_factory=dict)
+ # name -> ids of every entry it matches
+ ambiguous: dict[str, list[str]] = field(default_factory=dict)
+
+
+def resolve_names(names: list[str], catalog: list[dict[str, Any]]) -> Resolution:
+ """Match ``names`` against the catalog: exactly (path, name, then stem),
+ else by a single close match. Anything less certain is reported as
+ missing with suggestions rather than guessed."""
+
+ resolution = Resolution()
+ seen: set[str] = set()
+
+ def add(entry: dict[str, Any]) -> None:
+ if entry["id"] not in seen:
+ seen.add(entry["id"])
+ resolution.found.append(entry)
+
+ labels = {entry["id"]: document_name(entry) for entry in catalog}
+ for name in names:
+ wanted = _fold(name)
+ if not wanted:
+ continue
+ matches: list[dict[str, Any]] = []
+ for key in (
+ lambda e: _fold(str(e["id"])),
+ lambda e: _fold(labels[e["id"]]),
+ lambda e: _fold(_stem(labels[e["id"]])),
+ ):
+ matches = [e for e in catalog if key(e) == wanted]
+ if matches:
+ break
+ if len(matches) == 1:
+ add(matches[0])
+ continue
+ if len(matches) > 1:
+ resolution.ambiguous[name] = [str(e["id"]) for e in matches]
+ continue
+ # No exact match: a typo is accepted only when one document is
+ # clearly the closest — versions are named alike ("law_2023",
+ # "law_2024"), and picking the wrong one silently is worse than asking.
+ scored = sorted(
+ (
+ (
+ max(
+ difflib.SequenceMatcher(None, wanted, form).ratio()
+ for form in (
+ _fold(labels[entry["id"]]),
+ _fold(_stem(labels[entry["id"]])),
+ )
+ ),
+ labels[entry["id"]],
+ entry,
+ )
+ for entry in catalog
+ ),
+ key=lambda item: item[0],
+ reverse=True,
+ )
+ best = scored[0] if scored else None
+ runner_up = scored[1][0] if len(scored) > 1 else 0.0
+ if (
+ best is not None
+ and best[0] >= _CLOSE_NAME
+ and best[0] - runner_up >= _CLOSE_NAME_MARGIN
+ ):
+ add(best[2])
+ continue
+ resolution.missing[name] = [
+ label for score, label, _ in scored[:5] if score >= 0.5
+ ]
+ return resolution
+
+
+# ---------------------------------------------------------------------------
+# Arbiter
+# ---------------------------------------------------------------------------
+
+
+class Budget:
+ """The ceiling on what one ``/rag`` request may send to the LLM, in
+ characters, across all of its calls (attempts, routing, the answer).
+
+ Every call is charged before it is made; one that does not fit is cut
+ down to what is left, and once too little is left no call is made at
+ all. The number of calls is bounded elsewhere (each step of the document
+ mode runs at most once) — this bounds their combined size, whatever the
+ documents, ``k`` or the adaptive loop ask for.
+ """
+
+ # Below this a call cannot carry a useful context any more.
+ _MIN_CALL = 500
+
+ def __init__(self, limit: int) -> None:
+ self.left = limit
+ self.exhausted = False
+
+ def take(self, size: int) -> bool:
+ """Charge a call of a fixed ``size``; False when it does not fit."""
+
+ if size > self.left:
+ self.exhausted = True
+ return False
+ self.left -= size
+ return True
+
+ def fit(self, fixed: int, context: list[str]) -> list[str] | None:
+ """Charge a call with ``fixed`` characters of prompt plus as many
+ leading ``context`` items as still fit. ``None`` — no call — when
+ not even one item does."""
+
+ room = self.left - fixed
+ kept: list[str] = []
+ used = 0
+ for item in context:
+ if used + len(item) > room:
+ break
+ kept.append(item)
+ used += len(item)
+ if len(kept) < len(context):
+ self.exhausted = True
+ if (context and not kept) or room < 0 or self.left < self._MIN_CALL:
+ self.exhausted = True
+ return None
+ self.left -= fixed + used
+ return kept
+
+
+@dataclass
+class Route:
+ mode: str = "search" # "search" | "catalog" | "documents"
+ files: list[str] = field(default_factory=list)
+
+
+_MODE_LINE = re.compile(r"^\s*MODE\s*:\s*([a-z]+)", re.IGNORECASE | re.MULTILINE)
+_FILES_LINE = re.compile(r"^\s*FILES\s*:(.*)$", re.IGNORECASE | re.MULTILINE)
+
+
+def parse_route(reply: str) -> Route:
+ mode_match = _MODE_LINE.search(reply)
+ mode = mode_match.group(1).lower() if mode_match else "search"
+ if mode not in ("catalog", "documents"):
+ return Route()
+ files: list[str] = []
+ files_match = _FILES_LINE.search(reply)
+ if files_match and mode == "documents":
+ files = [
+ part.strip().strip("\"'`")
+ for part in files_match.group(1).split(";")
+ if part.strip().strip("\"'`")
+ ]
+ return Route(mode=mode, files=files)
+
+
+async def arbitrate(
+ llm: AsyncLLM,
+ query: str,
+ catalog: list[dict[str, Any]],
+ max_listed: int,
+ budget: Budget | None = None,
+) -> Route:
+ """One short LLM call: does the question need a wider search or the
+ document mode? Sees the question and document names only — never the
+ retrieved context — so its cost is fixed. Degrades to "search" (the
+ ordinary path) on any LLM hiccup or unparseable reply."""
+
+ names = sorted(document_name(entry) for entry in catalog)
+ shown = (
+ f"{len(names)} total"
+ if len(names) <= max_listed
+ else f"{len(names)} total, first {max_listed} shown"
+ )
+ prompt = _ARBITER_PROMPT.format(
+ shown=shown,
+ names="\n".join(f"- {name}" for name in names[:max_listed]),
+ query=query,
+ )
+ if budget is not None and not budget.take(len(prompt)):
+ return Route()
+ try:
+ reply = await llm.raw(prompt)
+ except Exception: # noqa: BLE001 - routing must never break /rag
+ logger.warning("document-mode arbiter failed; continuing with search")
+ return Route()
+ return parse_route(reply)
+
+
+# ---------------------------------------------------------------------------
+# Context builders
+# ---------------------------------------------------------------------------
+
+
+def _timestamp(value: Any) -> str | None:
+ try:
+ seconds = int(value)
+ except (TypeError, ValueError):
+ return None
+ if seconds <= 0:
+ return None
+ return datetime.datetime.fromtimestamp(
+ seconds, tz=datetime.timezone.utc
+ ).strftime("%Y-%m-%d %H:%M UTC")
+
+
+def _describe(entry: dict[str, Any]) -> str:
+ """One catalog line: identity plus whatever the source reported."""
+
+ metadata = entry.get("metadata") or {}
+ name = document_name(entry)
+ key = str(entry["id"])
+ parts = [name if key == name else f"{name} ({key})"]
+ modified = _timestamp(metadata.get("modified_at"))
+ if modified:
+ parts.append(f"modified {modified}")
+ size = metadata.get("size")
+ if isinstance(size, (int, float)) and size >= 0:
+ parts.append(f"{int(size)} bytes")
+ parts.append(f"{entry.get('chunks', 0)} indexed parts")
+ return " | ".join(parts)
+
+
+def corpus_card(catalog: list[dict[str, Any]]) -> str:
+ """The one fact the answering prompt always carries in document mode."""
+
+ return (
+ f"The index currently holds {len(catalog)} documents "
+ "(files that produced text). Never derive the number of documents "
+ "from the context."
+ )
+
+
+def labeled(hits: list[dict[str, Any]]) -> list[str]:
+ """Chunk texts prefixed with the name of the file they come from, so
+ the model can tell documents apart — two versions of a file otherwise
+ read as one self-contradicting text."""
+
+ out = []
+ for hit in hits:
+ key = document_key(hit.get("metadata"))
+ if key is None:
+ out.append(hit["text"])
+ continue
+ name = document_name({"id": key, "metadata": hit.get("metadata")})
+ out.append(f"[file: {name}]\n{hit['text']}")
+ return out
+
+
+def catalog_context(catalog: list[dict[str, Any]], budget: int) -> list[str]:
+ """The catalog as context: exact totals first (computed here, never by
+ the model), then as many document lines as the budget allows, newest
+ first."""
+
+ types = Counter(
+ posixpath.splitext(document_name(e))[1].lower() or "(no extension)"
+ for e in catalog
+ )
+ totals = [
+ f"Indexed documents: {len(catalog)}",
+ f"Indexed parts (chunks): {sum(e.get('chunks', 0) for e in catalog)}",
+ "By type: "
+ + ", ".join(f"{ext} {n}" for ext, n in sorted(types.items())),
+ ]
+
+ def modified(entry: dict[str, Any]) -> int:
+ try:
+ return int((entry.get("metadata") or {}).get("modified_at") or 0)
+ except (TypeError, ValueError):
+ return 0
+
+ ordered = sorted(catalog, key=lambda e: (-modified(e), document_name(e)))
+ lines: list[str] = []
+ used = sum(len(t) for t in totals)
+ for entry in ordered:
+ line = "- " + _describe(entry)
+ if used + len(line) > budget:
+ break
+ lines.append(line)
+ used += len(line)
+ if len(lines) == len(ordered):
+ header = "Documents (complete list, most recently modified first):"
+ else:
+ header = (
+ f"Documents (showing {len(lines)} of {len(ordered)}, most recently "
+ "modified first — the list is incomplete, the totals are exact):"
+ )
+ return ["\n".join(totals), "\n".join([header, *lines])]
+
+
+def _unit(vector: list[float] | None) -> list[float] | None:
+ if not vector:
+ return None
+ norm = math.sqrt(sum(x * x for x in vector))
+ if norm == 0.0:
+ return None
+ return [x / norm for x in vector]
+
+
+def _dot(a: list[float] | None, b: list[float] | None) -> float:
+ if a is None or b is None:
+ return 0.0
+ return sum(x * y for x, y in zip(a, b))
+
+
+def _rank(
+ chunks: list[dict[str, Any]], query_embedding: list[float]
+) -> list[dict[str, Any]]:
+ """``chunks`` as hits scored by similarity to the question, best first."""
+
+ query_unit = _unit(query_embedding)
+ hits = [
+ {
+ "text": chunk["text"],
+ "metadata": chunk.get("metadata") or {},
+ "score": _dot(query_unit, _unit(chunk.get("embedding"))),
+ }
+ for chunk in chunks
+ ]
+ hits.sort(key=lambda h: h["score"], reverse=True)
+ return hits
+
+
+def _take(hits: list[dict[str, Any]], budget: int) -> list[dict[str, Any]]:
+ """The leading hits that fit ``budget`` characters (always at least one)."""
+
+ taken: list[dict[str, Any]] = []
+ used = 0
+ for hit in hits:
+ if taken and used + len(hit["text"]) > budget:
+ break
+ taken.append(hit)
+ used += len(hit["text"])
+ return taken
+
+
+@dataclass
+class DocumentContext:
+ """What the answering call sees, and what the response reports."""
+
+ context: list[str]
+ sources: list[dict[str, Any]]
+ notice: str | None = None
+ # Which instructions go with ``context``.
+ system_prompt: str = DOCUMENT_SYSTEM_PROMPT
+
+
+def single_document_context(
+ entry: dict[str, Any],
+ chunks: list[dict[str, Any]],
+ query_embedding: list[float],
+ budget: int,
+) -> DocumentContext:
+ """One document: all of it when it fits the budget, otherwise the parts
+ closest to the question — and the header says which."""
+
+ hits = _rank(chunks, query_embedding)
+ taken = _take(hits, budget)
+ header = "Document: " + _describe(entry)
+ notice = None
+ if len(taken) < len(hits):
+ header += (
+ f"\nOnly {len(taken)} of its {len(hits)} parts are shown (the ones "
+ "closest to the question); the document is too large to show whole."
+ )
+ notice = (
+ f"Answered from {len(taken)} of {len(hits)} parts of "
+ f"{document_name(entry)}."
+ )
+ else:
+ header += "\nThe whole document is shown."
+ return DocumentContext(
+ context=[header, *(h["text"] for h in taken)], sources=taken, notice=notice
+ )
+
+
+def _squash(text: str) -> str:
+ """``text`` reduced to what must match for two extractions of the same
+ passage to be equal: one case, no diacritics or formatting noise.
+
+ Numeric punctuation carries meaning: 1.5 is not 15, and -100 is not
+ 100. Keep decimal/grouping separators as written (their interpretation
+ depends on locale), unary signs and percent units. Other punctuation,
+ including PDF soft hyphens, is still ignored.
+ """
+
+ decomposed = unicodedata.normalize("NFKD", text)
+ numeric_marks: dict[int, str] = {}
+ for match in re.finditer(r"(? None:
+ self.chunks = chunks
+ # squashed line -> index of the first chunk containing it
+ self.lines: dict[str, int] = {}
+ # per chunk: its lines as (squashed, raw), in order
+ self.by_chunk: list[list[tuple[str, str]]] = []
+ squashed_chunks = []
+ for index, chunk in enumerate(chunks):
+ rows = [(_squash(raw), raw.strip()) for raw in chunk["text"].splitlines()]
+ squashed_chunks.append("".join(row[0] for row in rows))
+ if len(chunks) > 1 and len(rows) >= _EDGE_LINES:
+ # A window splitter cuts the first and last line of a chunk
+ # mid-line; such fragments match nothing. The chunk overlap
+ # carries the same lines whole in the neighbouring chunk. A
+ # document that is a single chunk was not cut at all.
+ rows = rows[1:-1]
+ for squashed, _raw in rows:
+ if len(squashed) >= _MIN_LINE:
+ self.lines.setdefault(squashed, index)
+ self.by_chunk.append(rows)
+ # The whole text, for finding a line that the other file wraps
+ # differently (so it is no line of its own there).
+ self.text = "\x00".join(squashed_chunks)
+ self.masked = Counter(_DIGITS.sub("#", line) for line in self.lines)
+ # Running matter also gets glued to the front of the line after it
+ # ("").
+ running = [
+ mask for mask, count in self.masked.items() if count >= _RUNNING_LINES
+ ]
+ self._running_prefix = (
+ re.compile(
+ "|".join(
+ re.escape(mask).replace("\\#", r"\d+")
+ for mask in sorted(running, key=len, reverse=True)
+ )
+ )
+ if running
+ else None
+ )
+
+ def body(self, squashed: str) -> str:
+ """``squashed`` without a running header glued to its front."""
+
+ if self._running_prefix is not None:
+ match = self._running_prefix.match(squashed)
+ if match and len(squashed) - match.end() >= _MIN_LINE:
+ return squashed[match.end() :]
+ return squashed
+
+ def overlap(self, other: _Lines) -> float:
+ total = len(self.lines) + len(other.lines)
+ if not total:
+ return 0.0
+ return 2 * len(self.lines.keys() & other.lines.keys()) / total
+
+ def passages_missing_from(self, other: _Lines) -> list[tuple[str, int]]:
+ """Runs of consecutive lines of this document that the other does
+ not contain, as ``(text, chunk index)``."""
+
+ def contains_line(line: str) -> bool:
+ # A wrapped line may occur inside a chunk, but must not match
+ # only part of a numeric expression: 15 is not 15%, nor 100
+ # the suffix of -100 or 1100.
+ start = other.text.find(line)
+ while start >= 0:
+ end = start + len(line)
+ left = other.text[start - 1] if start else ""
+ right = other.text[end] if end < len(other.text) else ""
+ partial_left = line[0].isdigit() and (
+ left.isdigit() or left in {"+", "-", ".", ","}
+ )
+ partial_right = line[-1].isdigit() and (
+ right.isdigit() or right in {".", ",", "%", "‰"}
+ )
+ if not partial_left and not partial_right:
+ return True
+ start = other.text.find(line, start + 1)
+ return False
+
+ def present(squashed: str) -> bool:
+ if squashed in other.lines:
+ return True
+ mask = _DIGITS.sub("#", squashed)
+ if (
+ self.masked[mask] >= _RUNNING_LINES
+ and other.masked[mask] >= _RUNNING_LINES
+ ):
+ return True
+ if contains_line(squashed):
+ return True
+ body = self.body(squashed)
+ return body is not squashed and contains_line(body)
+
+ verdicts: dict[str, bool] = {}
+ reported: set[str] = set()
+ passages: list[tuple[str, int]] = []
+ for index, rows in enumerate(self.by_chunk):
+ run: list[str] = []
+ for squashed, raw in [*rows, ("", "")]:
+ missing = False
+ if len(squashed) >= _MIN_LINE and squashed not in reported:
+ if squashed not in verdicts:
+ verdicts[squashed] = present(squashed)
+ missing = not verdicts[squashed]
+ if missing:
+ reported.add(squashed) # chunk overlap repeats lines
+ run.append(raw)
+ elif run:
+ passages.append(("\n".join(run), index))
+ run = []
+ return passages
+
+
+def _words(text: str) -> frozenset[str]:
+ return frozenset(re.findall(r"\w{3,}", text.casefold()))
+
+
+def _pair_changed(
+ only_a: list[tuple[str, int]], only_b: list[tuple[str, int]]
+) -> tuple[list[tuple[tuple[str, int], tuple[str, int]]], list, list]:
+ """Split differing passages into (changed pairs, removed, added) by
+ greedy best word-overlap matching."""
+
+ if not only_a or not only_b or len(only_a) * len(only_b) > _MAX_PAIRINGS:
+ return [], only_a, only_b
+ words_a = [_words(text) for text, _ in only_a]
+ words_b = [_words(text) for text, _ in only_b]
+ scored = []
+ for i, wa in enumerate(words_a):
+ if not wa:
+ continue
+ for j, wb in enumerate(words_b):
+ if not wb:
+ continue
+ similarity = len(wa & wb) / len(wa | wb)
+ if similarity >= _CHANGED_SIMILARITY:
+ scored.append((similarity, i, j))
+ scored.sort(reverse=True)
+ used_a: set[int] = set()
+ used_b: set[int] = set()
+ pairs = []
+ for _similarity, i, j in scored:
+ if i in used_a or j in used_b:
+ continue
+ used_a.add(i)
+ used_b.add(j)
+ pairs.append((only_a[i], only_b[j]))
+ removed = [p for i, p in enumerate(only_a) if i not in used_a]
+ added = [p for j, p in enumerate(only_b) if j not in used_b]
+ return pairs, removed, added
+
+
+def compare_context(
+ entries: list[dict[str, Any]],
+ chunks: list[list[dict[str, Any]]],
+ query_embedding: list[float],
+ budget: int,
+) -> DocumentContext:
+ """Two or more documents within one budget.
+
+ Exactly two documents that share most of their lines are versions of
+ one text: what they share is dropped and the model sees only the
+ differences (edited passages paired up, then additions and removals),
+ with the exact totals computed here. Anything else — unrelated documents,
+ or more than two — gets each document's parts closest to the question,
+ the budget split evenly.
+ """
+
+ names = [document_name(e) for e in entries]
+ if len(entries) == 2:
+ lines = [_Lines(chunks[0]), _Lines(chunks[1])]
+ if lines[0].overlap(lines[1]) >= _VERSION_OVERLAP:
+ return _diff_context(entries, chunks, lines, query_embedding, budget)
+
+ share = max(budget // max(len(entries), 1), 1)
+ context = [
+ "Documents compared (they share little or no identical text, so each "
+ "is represented by its parts closest to the question):\n"
+ + "\n".join("- " + _describe(e) for e in entries)
+ ]
+ sources: list[dict[str, Any]] = []
+ partial: list[str] = []
+ for name, doc_chunks in zip(names, chunks):
+ hits = _rank(doc_chunks, query_embedding)
+ taken = _take(hits, share)
+ if len(taken) < len(hits):
+ partial.append(f"{len(taken)} of {len(hits)} parts of {name}")
+ context.extend(f"[{name}] {h['text']}" for h in taken)
+ sources.extend(taken)
+ notice = "Compared using " + ", ".join(partial) + "." if partial else None
+ if partial:
+ context[0] += "\nShown: " + ", ".join(partial) + "."
+ return DocumentContext(
+ context=context,
+ sources=sources,
+ notice=notice,
+ system_prompt=EXCERPTS_SYSTEM_PROMPT,
+ )
+
+
+def _diff_context(
+ entries: list[dict[str, Any]],
+ chunks: list[list[dict[str, Any]]],
+ lines: list[_Lines],
+ query_embedding: list[float],
+ budget: int,
+) -> DocumentContext:
+ name_a, name_b = document_name(entries[0]), document_name(entries[1])
+ pairs, removed, added = _pair_changed(
+ lines[0].passages_missing_from(lines[1]),
+ lines[1].passages_missing_from(lines[0]),
+ )
+
+ # Which differences to show when not all fit: the substantial ones
+ # first, and among those the ones in the parts of the documents closest
+ # to the question.
+ query_unit = _unit(query_embedding)
+ relevance: dict[tuple[int, int], float] = {}
+
+ def score(doc: int, chunk: int) -> float:
+ if (doc, chunk) not in relevance:
+ relevance[doc, chunk] = _dot(
+ query_unit, _unit(chunks[doc][chunk].get("embedding"))
+ )
+ return relevance[doc, chunk]
+
+ # (text, [(doc, chunk)], relevance)
+ blocks: list[tuple[str, list[tuple[int, int]], float]] = []
+ for (old, old_chunk), (new, new_chunk) in pairs:
+ blocks.append(
+ (
+ f"[changed]\n{name_a}: {old}\n{name_b}: {new}",
+ [(0, old_chunk), (1, new_chunk)],
+ max(score(0, old_chunk), score(1, new_chunk)),
+ )
+ )
+ blocks.extend(
+ (f"[only in {name_b}] {text}", [(1, chunk)], score(1, chunk))
+ for text, chunk in added
+ )
+ blocks.extend(
+ (f"[only in {name_a}] {text}", [(0, chunk)], score(0, chunk))
+ for text, chunk in removed
+ )
+ blocks.sort(key=lambda block: (len(block[0]) >= _SUBSTANTIAL, block[2]), reverse=True)
+
+ shown: list[str] = []
+ sources: list[dict[str, Any]] = []
+ cited: set[tuple[int, int]] = set()
+ used = 0
+ for text, origins, _relevance in blocks:
+ if used + len(text) > budget:
+ if shown:
+ continue # a shorter difference further down may still fit
+ text = text[:budget]
+ shown.append(text)
+ used += len(text)
+ for doc, chunk in origins:
+ if (doc, chunk) not in cited:
+ cited.add((doc, chunk))
+ source = chunks[doc][chunk]
+ sources.append(
+ {
+ "text": source["text"],
+ "metadata": source.get("metadata") or {},
+ "score": score(doc, chunk),
+ }
+ )
+
+ totals = (
+ f"{len(pairs)} passages changed, {len(added)} only in {name_b}, "
+ f"{len(removed)} only in {name_a}"
+ )
+ header = (
+ "Comparison of two documents that share most of their text. "
+ "Everything they share was left out; below are the differences.\n"
+ f"- {_describe(entries[0])}\n- {_describe(entries[1])}\n"
+ f"Totals: {totals}."
+ )
+ notice = f"Compared {name_a} and {name_b}: {totals}."
+ if len(shown) < len(blocks):
+ partial = (
+ f" Showing {len(shown)} of {len(blocks)} differences (the ones "
+ "closest to the question)."
+ )
+ header += partial
+ notice += partial
+ if not blocks:
+ header += " No differences were found in the indexed text."
+ return DocumentContext(
+ context=[header, *shown],
+ sources=sources,
+ notice=notice,
+ system_prompt=COMPARE_SYSTEM_PROMPT,
+ )
diff --git a/serviette/server/embedder.py b/serviette/server/embedder.py
new file mode 100644
index 00000000..d62711f4
--- /dev/null
+++ b/serviette/server/embedder.py
@@ -0,0 +1,354 @@
+"""Query embedding for the server.
+
+Design note — why not call the xpack embedder directly?
+-------------------------------------------------------
+``pathway.xpacks.llm.embedders`` classes are Pathway *UDFs*: calling them builds
+graph nodes, not plain values, and they're meant to run inside ``pw.run``. The
+server is a network-bound async FastAPS service and is deliberately decoupled
+from Pathway (it need not even have ``pathway`` installed). So we embed a single
+query by calling the provider SDK directly as a coroutine — exactly the
+"coroutines avoid thread-pool exhaustion" rationale for choosing FastAPI.
+
+The ``type``/``model`` config keys mirror the indexer's embedder config, so the
+**same** embedder section produces matching vectors on both sides as long as the
+model matches. Tests inject a deterministic mock implementing
+:class:`AsyncEmbedder`.
+"""
+
+from __future__ import annotations
+
+from typing import Protocol, runtime_checkable
+
+
+@runtime_checkable
+class AsyncEmbedder(Protocol):
+ async def embed(self, text: str) -> list[float]:
+ ...
+
+ async def close(self) -> None:
+ ...
+
+
+class MockAsyncEmbedder:
+ """Deterministic, offline embedder (dev/test scaffold).
+
+ Uses the same hash-based ``fake_embedding`` as the indexer's ``mock``
+ embedder, so query and document vectors are produced identically and the
+ whole stack runs with no provider or credentials. Not for real semantic
+ search — switch to a real embedder for that.
+ """
+
+ async def embed(self, text: str) -> list[float]:
+ from serviette.testing import fake_embedding
+
+ return fake_embedding(text)
+
+ async def close(self) -> None:
+ return None
+
+
+# Config keys that are consumed by the schema / the indexer's UDF wrapper and
+# must never reach a provider SDK on the server side. ``batch_size``,
+# ``truncation_keep_strategy``, ``capacity`` and ``retries`` are indexer
+# throughput knobs (pathway UDF executor / xpack constructor arguments).
+_SCHEMA_KEYS = {"type", "model", "api_key", "query_prefix", "document_prefix"}
+_INDEXER_ONLY_KEYS = {"batch_size", "truncation_keep_strategy", "capacity", "retries"}
+
+
+def _extra_kwargs(config) -> dict:
+ """Extra config keys, minus schema fields and indexer-only knobs.
+
+ Where each remaining key goes (client constructor vs. per-call) is decided
+ per family below — the split must mirror what the indexer's xpack embedder
+ does with the *same* section, or query and document vectors diverge.
+ """
+ extra = config.model_dump(exclude=_SCHEMA_KEYS | _INDEXER_ONLY_KEYS)
+ return {k: v for k, v in extra.items() if v is not None}
+
+
+class OpenAIAsyncEmbedder:
+ """Embed queries with OpenAI (or any OpenAI-compatible endpoint).
+
+ Mirrors the indexer's ``OpenAIEmbedder`` xpack, which forwards extra keys
+ to ``embeddings.create`` per call (``dimensions``, ``encoding_format``,
+ ``user``). The handful of keys that belong to the client object
+ (``base_url``, ``organization``, ...) are routed there instead.
+ """
+
+ _CLIENT_KEYS = frozenset({
+ "base_url",
+ "organization",
+ "project",
+ "timeout",
+ "max_retries",
+ "default_headers",
+ "default_query",
+ })
+
+ def __init__(self, config) -> None:
+ self._model = config.model or "text-embedding-3-small"
+ self._api_key = config.api_key
+ extra = _extra_kwargs(config)
+ self._client_kwargs = {k: v for k, v in extra.items() if k in self._CLIENT_KEYS}
+ self._call_kwargs = {k: v for k, v in extra.items() if k not in self._CLIENT_KEYS}
+ self._client = None
+
+ def _ensure_client(self):
+ if self._client is None:
+ from openai import AsyncOpenAI
+
+ self._client = AsyncOpenAI(api_key=self._api_key, **self._client_kwargs)
+ return self._client
+
+ async def embed(self, text: str) -> list[float]:
+ client = self._ensure_client()
+ resp = await client.embeddings.create(
+ model=self._model, input=[text], **self._call_kwargs
+ )
+ return list(resp.data[0].embedding)
+
+ async def close(self) -> None:
+ if self._client is not None:
+ await self._client.close()
+ self._client = None
+
+
+class LiteLLMAsyncEmbedder:
+ """Embed queries through LiteLLM (``type: litellm``).
+
+ Unlike :class:`OpenAIAsyncEmbedder` this calls ``litellm.aembedding``, so
+ the provider prefix in ``model`` (``openrouter/...``, ``cohere/...``, …)
+ selects the endpoint and ``api_key`` is forwarded to *that* provider. This
+ mirrors the indexer, which embeds documents with pathway's
+ ``LiteLLMEmbedder`` for the same config section — routing the server's
+ query embeddings through the plain OpenAI client instead would send the
+ key to api.openai.com (401) or, with an OpenAI key, silently embed queries
+ with a different model than the documents.
+ """
+
+ def __init__(self, config) -> None:
+ if not config.model:
+ raise ValueError(
+ "embedder type 'litellm' requires a 'model' with a provider prefix, "
+ "e.g. 'openrouter/qwen/qwen3-embedding-8b' (LiteLLM has no default)."
+ )
+ self._model = config.model
+ self._api_key = config.api_key
+ # Extra keys are per-call kwargs for litellm.aembedding (api_base,
+ # dimensions, ...) — there is no persistent client object to construct.
+ self._call_kwargs = _extra_kwargs(config)
+
+ async def embed(self, text: str) -> list[float]:
+ import litellm
+
+ resp = await litellm.aembedding(
+ model=self._model,
+ api_key=self._api_key,
+ input=[text],
+ **self._call_kwargs,
+ )
+ return [float(x) for x in resp.data[0]["embedding"]]
+
+ async def close(self) -> None:
+ # No persistent client; nothing to release.
+ return None
+
+
+class SentenceTransformerAsyncEmbedder:
+ """Embed queries with a local sentence-transformers model.
+
+ ``is_local = True`` opts into the server's startup warm-up: the first
+ real user question must not pay the torch import + model load.
+
+ Fully local — no provider, no credentials. The (CPU/GPU-bound) encode runs
+ off the event loop in a worker thread. Mirrors the indexer's
+ ``sentence_transformer`` xpack embedder; use the same ``model`` on both
+ sides.
+ """
+
+ _DEFAULT_MODEL = "sentence-transformers/all-MiniLM-L6-v2"
+ is_local = True
+
+ def __init__(self, config) -> None:
+ self._model_name = config.model or self._DEFAULT_MODEL
+ # Forward extra config keys (device, truncate_dim, ...) to the
+ # SentenceTransformer constructor — mirrors the indexer's xpack
+ # embedder, so e.g. Matryoshka truncation stays consistent.
+ # Same split as the xpack: ``call_kwargs`` are per-``encode`` options
+ # (normalize_embeddings, ...), ``batch_size`` is indexer-only, the rest
+ # are SentenceTransformer constructor kwargs.
+ self._model_kwargs = _extra_kwargs(config)
+ self._call_kwargs = dict(self._model_kwargs.pop("call_kwargs", None) or {})
+ self._model_kwargs.setdefault("device", "cpu")
+ self._model = None
+
+ def _ensure_model(self):
+ if self._model is None:
+ from sentence_transformers import SentenceTransformer
+
+ self._model = SentenceTransformer(self._model_name, **self._model_kwargs)
+ return self._model
+
+ async def embed(self, text: str) -> list[float]:
+ import asyncio
+
+ model = await asyncio.to_thread(self._ensure_model)
+ vector = await asyncio.to_thread(model.encode, text, **self._call_kwargs)
+ return [float(x) for x in vector]
+
+ async def close(self) -> None:
+ self._model = None
+
+
+class GeminiAsyncEmbedder:
+ """Embed queries with Google Gemini (``google-generativeai`` SDK).
+
+ Mirrors the indexer's ``gemini`` xpack embedder: same default model, and
+ extra keys (``task_type``, ``output_dimensionality``, ...) go to
+ ``embed_content`` per call exactly as there.
+ """
+
+ _DEFAULT_MODEL = "models/embedding-001"
+
+ def __init__(self, config) -> None:
+ self._model = config.model or self._DEFAULT_MODEL
+ self._api_key = config.api_key
+ self._call_kwargs = _extra_kwargs(config)
+ self._configured = False
+
+ def _ensure_configured(self):
+ import google.generativeai as genai
+
+ if not self._configured:
+ genai.configure(api_key=self._api_key)
+ self._configured = True
+ return genai
+
+ async def embed(self, text: str) -> list[float]:
+ import asyncio
+
+ genai = self._ensure_configured()
+ response = await asyncio.to_thread(
+ genai.embed_content, model=self._model, content=text, **self._call_kwargs
+ )
+ return [float(x) for x in response["embedding"]]
+
+ async def close(self) -> None:
+ return None
+
+
+class BedrockAsyncEmbedder:
+ """Embed queries with AWS Bedrock (Titan models by default).
+
+ Mirrors the indexer's ``bedrock`` xpack embedder: ``model`` (or the
+ xpack's ``model_id``) picks the model, credentials/region keys go to the
+ boto3 client, and the model-specific request options (Titan:
+ ``dimensions``/``normalize``; Cohere: ``input_type``/``truncate``) go into
+ the request body — the same shapes the indexer sends. Credentials resolve
+ via the standard AWS chain when omitted. The blocking SDK call runs in a
+ worker thread.
+ """
+
+ _DEFAULT_MODEL = "amazon.titan-embed-text-v2:0"
+ _SESSION_KEYS = frozenset({
+ "region_name",
+ "aws_access_key_id",
+ "aws_secret_access_key",
+ "aws_session_token",
+ "endpoint_url",
+ })
+
+ def __init__(self, config) -> None:
+ extra = _extra_kwargs(config)
+ self._model_id = extra.pop("model_id", None) or config.model or self._DEFAULT_MODEL
+ self._client_kwargs = {k: v for k, v in extra.items() if k in self._SESSION_KEYS}
+ self._request_kwargs = {k: v for k, v in extra.items() if k not in self._SESSION_KEYS}
+ self._client = None
+
+ def _ensure_client(self):
+ if self._client is None:
+ try:
+ import boto3
+ except ImportError as exc: # pathway >= 0.33 no longer ships boto3
+ raise RuntimeError(
+ "The bedrock embedder needs boto3 on the server: "
+ 'pip install "serviette[bedrock]"'
+ ) from exc
+
+ self._client = boto3.client("bedrock-runtime", **self._client_kwargs)
+ return self._client
+
+ def _request_body(self, text: str) -> dict:
+ model = self._model_id.lower()
+ opts = self._request_kwargs
+ if "cohere" in model:
+ body: dict = {
+ "texts": [text],
+ # Queries, not documents: the indexer's default is search_document.
+ "input_type": opts.get("input_type", "search_query"),
+ }
+ if "truncate" in opts:
+ body["truncate"] = opts["truncate"]
+ return body
+ body = {"inputText": text}
+ if "titan" in model:
+ for key in ("dimensions", "normalize"):
+ if key in opts:
+ body[key] = opts[key]
+ return body
+
+ def _parse_embedding(self, payload: dict) -> list[float]:
+ if "cohere" in self._model_id.lower():
+ embeddings = payload.get("embeddings") or [[]]
+ return [float(x) for x in embeddings[0]]
+ return [float(x) for x in payload["embedding"]]
+
+ async def embed(self, text: str) -> list[float]:
+ import asyncio
+ import json
+
+ def invoke() -> list[float]:
+ client = self._ensure_client()
+ response = client.invoke_model(
+ modelId=self._model_id,
+ body=json.dumps(self._request_body(text)),
+ contentType="application/json",
+ accept="application/json",
+ )
+ return self._parse_embedding(json.loads(response["body"].read()))
+
+ return await asyncio.to_thread(invoke)
+
+ async def close(self) -> None:
+ self._client = None
+
+
+_SUPPORTED = sorted(
+ {"openai", "litellm", "sentence_transformer", "gemini", "bedrock", "mock"}
+)
+
+
+def build_embedder(config) -> AsyncEmbedder:
+ """Construct an :class:`AsyncEmbedder` from an ``EmbedderConfig``.
+
+ Every embedder family supported by the indexer (via
+ ``pathway.xpacks.llm.embedders``) has a matching async client here, so one
+ ``embedder`` config section serves both sides.
+ """
+
+ if config.type == "mock":
+ return MockAsyncEmbedder()
+ if config.type == "litellm":
+ return LiteLLMAsyncEmbedder(config)
+ if config.type == "openai":
+ return OpenAIAsyncEmbedder(config)
+ if config.type in {"sentence_transformer", "sentencetransformer"}:
+ return SentenceTransformerAsyncEmbedder(config)
+ if config.type == "gemini":
+ return GeminiAsyncEmbedder(config)
+ if config.type == "bedrock":
+ return BedrockAsyncEmbedder(config)
+ raise ValueError(
+ f"Server-side embedding for type {config.type!r} is not implemented. "
+ "Supported on the server: " + ", ".join(_SUPPORTED)
+ )
diff --git a/serviette/server/hybrid.py b/serviette/server/hybrid.py
new file mode 100644
index 00000000..299deda9
--- /dev/null
+++ b/serviette/server/hybrid.py
@@ -0,0 +1,261 @@
+"""Shared in-process BM25 hybrid retrieval for the vector accessors.
+
+A backend opts in by mixing in :class:`KeywordHybridMixin`, calling
+``_init_hybrid(config)`` from its ``__init__``, and implementing the two hooks
+``_hybrid_count`` and ``_hybrid_fetch_all``. The mixin then fuses the vector
+hits with a BM25 keyword search — built in-process from the backend's stored
+chunk texts — via reciprocal-rank fusion (see
+:func:`serviette.server.ranking.rrf_merge`).
+
+Freshness: the index is rebuilt synchronously whenever the backend's cheap
+change signal moves (``_hybrid_version``: the row count, plus the newest
+``seen_at`` where the backend can report it — an in-place edit keeps the
+count but bumps ``seen_at``), and refreshed in the background every
+``hybrid_refresh_seconds`` as a bound on staleness for whatever that signal
+misses. Queries keep being served from the previous index while a timed
+refresh runs.
+
+In-process BM25 targets corpora up to a few million chunks; above
+``hybrid_max_chunks`` the keyword leg is skipped with a one-time warning and
+retrieval degrades to pure vector search. Backends whose engine offers native
+server-side keyword scoring should prefer that (planned);
+backends that cannot enumerate their rows at all (Pinecone) cannot use this
+mixin and reject ``hybrid: true`` at startup.
+"""
+
+from __future__ import annotations
+
+import asyncio
+import logging
+import time
+from typing import Any
+
+from serviette.server.accessors.abstract import document_key
+from serviette.server.bm25 import Bm25Index
+from serviette.server.ranking import rrf_merge
+
+logger = logging.getLogger(__name__)
+
+
+class KeywordHybridMixin:
+ """In-process BM25 keyword leg + RRF fusion, shared by the accessors.
+
+ Concrete accessors provide the two backend-specific hooks below; everything
+ else (the cached BM25 index, the rebuild-on-count-change policy, the size
+ guard, the fusion) lives here so every backend behaves identically.
+ """
+
+ # Defaults keep the mixin usable even if ``_init_hybrid`` was not called
+ # (hybrid simply stays off).
+ _hybrid = False
+ _hybrid_max_chunks = 5_000_000
+
+ def _init_hybrid(self, config) -> None:
+ self._hybrid = getattr(config, "hybrid", False)
+ self._hybrid_max_chunks = getattr(config, "hybrid_max_chunks", 5_000_000)
+ self._hybrid_refresh_seconds = getattr(config, "hybrid_refresh_seconds", 30.0)
+ self._bm25: Bm25Index | None = None
+ # The backend version (see ``_hybrid_version``) the current index was
+ # built for — compared against the fresh one to decide on a rebuild.
+ # Kept separate from ``Bm25Index.doc_count`` (the exact scanned size)
+ # so a backend whose count is approximate does not rebuild per query.
+ self._bm25_built_for: tuple[int, Any] | None = None
+ self._bm25_built_at = 0.0
+ self._bm25_lock = asyncio.Lock()
+ self._bm25_refresh: asyncio.Task | None = None
+ self._warned_too_large = False
+
+ # -- backend hooks --------------------------------------------------------
+
+ async def _hybrid_count(self) -> int:
+ """A cheap (possibly approximate) row count, for cache invalidation."""
+ raise NotImplementedError
+
+ async def _hybrid_version(self) -> tuple[int, Any]:
+ """``(row count, change marker)`` — the cheap signal that the stored
+ chunks changed. The marker is any comparable value the backend can
+ report cheaply (DuckDB/pgvector: the newest ``seen_at``); ``None``
+ leaves the count as the only signal, with the timed refresh as the
+ net for changes it misses."""
+ return await self._hybrid_count(), None
+
+ async def _hybrid_fetch_all(self, with_embeddings: bool) -> list[dict[str, Any]]:
+ """Every stored chunk as a hit dict (``text``/``metadata`` and, when
+ ``with_embeddings``, ``embedding``) — the BM25 corpus."""
+ raise NotImplementedError
+
+ # -- shared fusion --------------------------------------------------------
+
+ async def _fuse(
+ self,
+ vector_hits: list[dict[str, Any]],
+ query_text: str | None,
+ k: int,
+ with_embeddings: bool,
+ ) -> list[dict[str, Any]]:
+ """Fuse the vector hits with the BM25 leg, when hybrid is enabled.
+
+ Falls back to the vector hits unchanged when hybrid is off, no query
+ text was passed, or the keyword leg returned nothing (empty corpus or
+ skipped over the size cap).
+ """
+
+ if not (self._hybrid and query_text):
+ return vector_hits
+ keyword_hits = await self._keyword_hits(query_text, k, with_embeddings)
+ if not keyword_hits:
+ return vector_hits
+ return rrf_merge([vector_hits, keyword_hits], k)
+
+ async def _keyword_hits(
+ self, query_text: str, k: int, with_embeddings: bool
+ ) -> list[dict[str, Any]]:
+ count, marker = await self._hybrid_version()
+ if count > self._hybrid_max_chunks:
+ if not self._warned_too_large:
+ self._warned_too_large = True
+ logger.warning(
+ "hybrid: ~%d chunks exceeds hybrid_max_chunks=%d — skipping "
+ "the in-process BM25 leg (retrieval stays pure-vector). "
+ "Raise the cap or move to native server-side keyword search "
+ "(planned).",
+ count,
+ self._hybrid_max_chunks,
+ )
+ return []
+ version = (count, marker)
+ bm25 = self._bm25
+ if bm25 is None or not self._index_current(version, with_embeddings):
+ # Known change (or no index yet): wait for a fresh build — a
+ # query must not be answered from chunks known to be gone.
+ bm25 = await self._rebuild(version, with_embeddings)
+ elif self._refresh_due():
+ # Timed refresh: serve the current index, rebuild behind it.
+ self._schedule_refresh(version, with_embeddings)
+ return await asyncio.to_thread(bm25.search, query_text, k)
+
+ def _index_current(self, version: tuple[int, Any], with_embeddings: bool) -> bool:
+ return (
+ self._bm25 is not None
+ and self._bm25_built_for == version
+ and self._bm25.has_embeddings == with_embeddings
+ )
+
+ def _refresh_due(self) -> bool:
+ ttl = self._hybrid_refresh_seconds
+ return ttl is not None and time.monotonic() - self._bm25_built_at >= ttl
+
+ async def _rebuild(self, version: tuple[int, Any], with_embeddings: bool) -> Bm25Index:
+ async with self._bm25_lock:
+ # A concurrent caller may have rebuilt while we waited for the lock.
+ if not self._index_current(version, with_embeddings) or self._refresh_due():
+ hits = await self._hybrid_fetch_all(with_embeddings)
+ # Tokenizing the whole corpus is CPU-bound; keep it off the loop.
+ self._bm25 = await asyncio.to_thread(Bm25Index, hits, with_embeddings)
+ self._bm25_built_for = version
+ self._bm25_built_at = time.monotonic()
+ assert self._bm25 is not None
+ return self._bm25
+
+ def _schedule_refresh(self, version: tuple[int, Any], with_embeddings: bool) -> None:
+ task = self._bm25_refresh
+ if task is not None and not task.done():
+ return # one refresh at a time
+ self._bm25_refresh = asyncio.create_task(self._refresh(version, with_embeddings))
+
+ async def _refresh(self, version: tuple[int, Any], with_embeddings: bool) -> None:
+ try:
+ await self._rebuild(version, with_embeddings)
+ except Exception as exc: # noqa: BLE001 - keep serving the previous index
+ logger.warning("hybrid: background BM25 refresh failed: %s", exc)
+
+ # -- document catalog (rag.documents) -------------------------------------
+ #
+ # Built from a scan of the stored metadata and cached the way the BM25
+ # index is: rebuilt synchronously when the backend's change signal moves
+ # (a request must not see documents known to be gone), refreshed in the
+ # background on the timer for what that signal misses, one build at a
+ # time. Listing documents therefore costs one cheap version query per
+ # request. Capped at ``hybrid_max_chunks`` like the BM25 corpus: both
+ # are in-process scans of the whole store. Backends with a query
+ # language override ``_catalog_scan`` and ``document_chunks`` with
+ # native queries.
+
+ supports_catalog = True
+ _catalog: list[dict[str, Any]] | None = None
+ _catalog_built_for: tuple[int, Any] | None = None
+ _catalog_built_at = 0.0
+ _catalog_lock: asyncio.Lock | None = None
+ _catalog_refresh: asyncio.Task | None = None
+ _warned_catalog_too_large = False
+
+ async def list_documents(self) -> list[dict[str, Any]]:
+ version = await self._hybrid_version()
+ if version[0] > self._hybrid_max_chunks:
+ if not self._warned_catalog_too_large:
+ self._warned_catalog_too_large = True
+ logger.warning(
+ "rag.documents: ~%d chunks exceeds hybrid_max_chunks=%d — the "
+ "document catalog is not built (document mode stays off).",
+ version[0],
+ self._hybrid_max_chunks,
+ )
+ raise RuntimeError("store too large for an in-process document catalog")
+ if self._catalog is None or self._catalog_built_for != version:
+ return await self._rebuild_catalog(version)
+ ttl = getattr(self, "_hybrid_refresh_seconds", None)
+ if ttl is not None and time.monotonic() - self._catalog_built_at >= ttl:
+ task = self._catalog_refresh
+ if task is None or task.done():
+ self._catalog_refresh = asyncio.create_task(
+ self._refresh_catalog(version)
+ )
+ return self._catalog
+
+ async def _rebuild_catalog(self, version: tuple[int, Any]) -> list[dict[str, Any]]:
+ if self._catalog_lock is None:
+ self._catalog_lock = asyncio.Lock()
+ async with self._catalog_lock:
+ # A concurrent caller may have rebuilt while we waited.
+ if self._catalog is None or self._catalog_built_for != version:
+ self._catalog = await self._catalog_scan()
+ self._catalog_built_for = version
+ self._catalog_built_at = time.monotonic()
+ assert self._catalog is not None
+ return self._catalog
+
+ async def _refresh_catalog(self, version: tuple[int, Any]) -> None:
+ try:
+ # Same version, so force the scan by invalidating the marker.
+ self._catalog_built_for = None
+ await self._rebuild_catalog(version)
+ except Exception as exc: # noqa: BLE001 - keep serving the previous catalog
+ self._catalog_built_for = version
+ logger.warning("rag.documents: background catalog refresh failed: %s", exc)
+
+ async def _catalog_scan(self) -> list[dict[str, Any]]:
+ documents: dict[str, dict[str, Any]] = {}
+ for hit in await self._hybrid_fetch_all(False):
+ key = document_key(hit.get("metadata"))
+ if key is None:
+ continue
+ entry = documents.setdefault(
+ key, {"id": key, "metadata": hit["metadata"], "chunks": 0}
+ )
+ entry["chunks"] += 1
+ return list(documents.values())
+
+ async def document_chunks(
+ self, document: str, *, with_embeddings: bool = False
+ ) -> list[dict[str, Any]]:
+ return [
+ hit
+ for hit in await self._hybrid_fetch_all(with_embeddings)
+ if document_key(hit.get("metadata")) == document
+ ]
+
+ async def _close_hybrid(self) -> None:
+ """Let a running background refresh finish (called from ``close``)."""
+ for task in (self._bm25_refresh, self._catalog_refresh):
+ if task is not None and not task.done():
+ await task
diff --git a/serviette/server/llm.py b/serviette/server/llm.py
new file mode 100644
index 00000000..87b24452
--- /dev/null
+++ b/serviette/server/llm.py
@@ -0,0 +1,289 @@
+"""Optional LLM chat for the ``/rag`` endpoint.
+
+Like the server embedder, this calls the provider SDK directly as a coroutine
+rather than going through a Pathway LLM-chat UDF: ``/rag`` here is pure
+retrieval + a single chat completion and requires no Pathway graph, connectors
+or UDFs, which is the condition under which the spec allows shipping it in v1.
+
+If you instead need streaming, multi-step agents, rerankers or anything that
+benefits from Pathway's incremental graph, that belongs in a separate Pathway
+service — left as a TODO and intentionally out of this decoupled server.
+"""
+
+from __future__ import annotations
+
+from typing import Protocol, runtime_checkable
+
+DEFAULT_SYSTEM_PROMPT = (
+ "You are a helpful assistant. Answer the user's question using only the "
+ "provided context. If the context is insufficient, say so."
+)
+_DEFAULT_SYSTEM_PROMPT = DEFAULT_SYSTEM_PROMPT
+
+
+@runtime_checkable
+class AsyncLLM(Protocol):
+ async def complete(
+ self, query: str, context: list[str], *, system_prompt: str | None = None
+ ) -> str:
+ ...
+
+ async def raw(self, prompt: str) -> str:
+ """One-shot completion with no RAG prompt scaffolding.
+
+ Used by retrieval-side helpers (query decomposition, LLM reranking)
+ that need the model, not the answer-from-context template.
+ """
+ ...
+
+ async def prepare(self) -> None:
+ """Pay the one-time client setup (SDK import, connection pool) now.
+
+ Called from the server's startup so the first real question does
+ not. Must not issue a billable request.
+ """
+ ...
+
+ async def close(self) -> None:
+ ...
+
+
+def _build_prompt(query: str, context: list[str]) -> str:
+ joined = "\n\n".join(f"[{i + 1}] {c}" for i, c in enumerate(context))
+ return f"Context:\n{joined}\n\nQuestion: {query}"
+
+
+class MockLLM:
+ """Offline LLM scaffold: echoes the retrieved context (no provider needed).
+
+ Lets the full RAG/chat flow run with no API key — useful for testing the
+ indexer → server → frontend stack end-to-end. Replace with a real ``llm``
+ (e.g. ``openai``) for actual generated answers.
+ """
+
+ async def complete(
+ self, query: str, context: list[str], *, system_prompt: str | None = None
+ ) -> str:
+ if not context:
+ return (
+ "(mock LLM) No relevant context was retrieved for your question. "
+ "This is the offline scaffold — set an `llm` of type `openai` for "
+ "real answers."
+ )
+ snippet = " ".join(context[0].split())
+ if len(snippet) > 320:
+ snippet = snippet[:320] + "…"
+ return (
+ f"(mock LLM) Based on {len(context)} retrieved snippet(s), the most "
+ f'relevant one says:\n\n"{snippet}"\n\n'
+ "Configure an `llm` of type `openai` for a real generated answer."
+ )
+
+ async def raw(self, prompt: str) -> str:
+ # No model behind the scaffold; callers treat "" as "helper
+ # unavailable" and fall back (e.g. decomposition keeps the original
+ # query only).
+ return ""
+
+ async def prepare(self) -> None:
+ return None
+
+ async def close(self) -> None:
+ return None
+
+
+class OpenAIChat:
+ """LLM backend on the OpenAI SDK (``type: openai``).
+
+ Extra keys of the ``llm`` section are split the way the SDK expects them:
+ the few client-level ones (``base_url``, ``organization``, ...) go to
+ ``AsyncOpenAI``, everything else (``max_tokens``, ``top_p``, ``seed``,
+ ``response_format``, ...) is a ``chat.completions.create`` parameter —
+ the same per-call treatment ``LiteLLMChat`` gives them, so one section
+ behaves identically under both types.
+ """
+
+ _CLIENT_KEYS = frozenset({
+ "base_url",
+ "organization",
+ "project",
+ "timeout",
+ "max_retries",
+ "default_headers",
+ "default_query",
+ })
+
+ def __init__(self, config) -> None:
+ self._model = config.model or "gpt-4o-mini"
+ self._api_key = config.api_key
+ # ``temperature`` is a per-request sampling knob, not a client kwarg.
+ self._temperature = getattr(config, "temperature", None)
+ self._reasoning_effort = getattr(config, "reasoning_effort", None)
+ # Configured default system prompt (None -> the strict built-in one);
+ # an explicit ``system_prompt=`` argument to ``complete`` still wins
+ # (adaptive RAG injects its no-answer marker that way).
+ self._system_prompt = getattr(config, "system_prompt", None)
+ extra = config.model_dump(
+ exclude={
+ "type", "model", "api_key", "temperature", "system_prompt",
+ "reasoning_effort",
+ }
+ )
+ extra = {k: v for k, v in extra.items() if v is not None}
+ self._client_kwargs = {k: v for k, v in extra.items() if k in self._CLIENT_KEYS}
+ self._call_kwargs = {k: v for k, v in extra.items() if k not in self._CLIENT_KEYS}
+ self._client = None
+
+ def _request_kwargs(self) -> dict:
+ kwargs: dict = dict(self._call_kwargs)
+ if self._temperature is not None:
+ kwargs["temperature"] = self._temperature
+ if self._reasoning_effort is not None:
+ kwargs["reasoning_effort"] = self._reasoning_effort
+ return kwargs
+
+ def _ensure_client(self):
+ if self._client is None:
+ from openai import AsyncOpenAI
+
+ self._client = AsyncOpenAI(api_key=self._api_key, **self._client_kwargs)
+ return self._client
+
+ async def complete(
+ self, query: str, context: list[str], *, system_prompt: str | None = None
+ ) -> str:
+ client = self._ensure_client()
+ resp = await client.chat.completions.create(
+ model=self._model,
+ messages=[
+ {
+ "role": "system",
+ "content": system_prompt
+ or self._system_prompt
+ or _DEFAULT_SYSTEM_PROMPT,
+ },
+ {"role": "user", "content": _build_prompt(query, context)},
+ ],
+ **self._request_kwargs(),
+ )
+ return resp.choices[0].message.content or ""
+
+ async def raw(self, prompt: str) -> str:
+ client = self._ensure_client()
+ resp = await client.chat.completions.create(
+ model=self._model,
+ messages=[{"role": "user", "content": prompt}],
+ **self._request_kwargs(),
+ )
+ return resp.choices[0].message.content or ""
+
+ async def prepare(self) -> None:
+ import asyncio
+
+ # Importing the openai SDK and building the client takes a second or
+ # two of blocking work; keep it off the event loop.
+ await asyncio.to_thread(self._ensure_client)
+
+ async def close(self) -> None:
+ if self._client is not None:
+ await self._client.close()
+ self._client = None
+
+
+class LiteLLMChat:
+ """LLM backend routed through LiteLLM (``type: litellm``).
+
+ Unlike ``OpenAIChat`` this calls ``litellm.acompletion``, so the provider
+ prefix in ``model`` (``openrouter/...``, ``anthropic/...``, …) selects the
+ endpoint and ``api_key`` is forwarded to *that* provider. Routing a
+ litellm-typed config through the plain OpenAI client instead would send
+ the key to api.openai.com and 401 — which is exactly the bug this class
+ exists to prevent.
+ """
+
+ def __init__(self, config) -> None:
+ if not config.model:
+ raise ValueError(
+ "llm type 'litellm' requires a 'model' with a provider prefix, "
+ "e.g. 'openrouter/moonshotai/kimi-k3'."
+ )
+ self._model = config.model
+ self._api_key = config.api_key
+ self._temperature = getattr(config, "temperature", None)
+ self._reasoning_effort = getattr(config, "reasoning_effort", None)
+ self._system_prompt = getattr(config, "system_prompt", None)
+ extra = config.model_dump(
+ exclude={
+ "type", "model", "api_key", "temperature", "system_prompt",
+ "reasoning_effort",
+ }
+ )
+ # Extra keys are per-call kwargs for litellm.acompletion (there is no
+ # persistent client object to construct).
+ self._call_kwargs = {k: v for k, v in extra.items() if v is not None}
+
+ def _request_kwargs(self) -> dict:
+ kwargs: dict = {}
+ if self._temperature is not None:
+ kwargs["temperature"] = self._temperature
+ if self._reasoning_effort is not None:
+ kwargs["reasoning_effort"] = self._reasoning_effort
+ return kwargs
+
+ async def prepare(self) -> None:
+ import asyncio
+ import importlib
+
+ # litellm is a heavy import (many seconds); do it at startup, off the
+ # event loop, rather than inside the first user's request.
+ await asyncio.to_thread(importlib.import_module, "litellm")
+
+ async def _call(self, messages: list[dict]) -> str:
+ import litellm
+
+ resp = await litellm.acompletion(
+ model=self._model,
+ api_key=self._api_key,
+ messages=messages,
+ **self._call_kwargs,
+ **self._request_kwargs(),
+ )
+ return resp.choices[0].message.content or ""
+
+ async def complete(
+ self, query: str, context: list[str], *, system_prompt: str | None = None
+ ) -> str:
+ return await self._call(
+ [
+ {
+ "role": "system",
+ "content": system_prompt
+ or self._system_prompt
+ or _DEFAULT_SYSTEM_PROMPT,
+ },
+ {"role": "user", "content": _build_prompt(query, context)},
+ ]
+ )
+
+ async def raw(self, prompt: str) -> str:
+ return await self._call([{"role": "user", "content": prompt}])
+
+ async def close(self) -> None:
+ # No persistent client; nothing to release.
+ return None
+
+
+_SUPPORTED = {"mock", "openai", "litellm"}
+
+
+def build_llm(config) -> AsyncLLM:
+ if config.type == "mock":
+ return MockLLM()
+ if config.type == "litellm":
+ return LiteLLMChat(config)
+ if config.type == "openai":
+ return OpenAIChat(config)
+ raise ValueError(
+ f"Server-side LLM for type {config.type!r} is not implemented. "
+ "Supported: " + ", ".join(sorted(_SUPPORTED))
+ )
diff --git a/serviette/server/main.py b/serviette/server/main.py
new file mode 100644
index 00000000..6811232a
--- /dev/null
+++ b/serviette/server/main.py
@@ -0,0 +1,758 @@
+"""FastAPI retrieval/RAG server.
+
+Async and coroutine-based so network-bound calls to the vector DB and embedding
+provider don't exhaust a thread pool. Fully decoupled from the indexer: it only
+reads from the vector DB, so it can be scaled horizontally and independently.
+
+API surface
+-----------
+Endpoints are versioned under ``/api/v1`` (``/api/v1/retrieve``,
+``/api/v1/rag``, ``/api/v1/health``, ``/api/v1/config``). When the API evolves
+incompatibly, a ``/api/v2`` router is added next to v1 and v1 sticks around
+for a deprecation window. The original unversioned routes (``/retrieve``,
+``/rag``, ``/health``) are kept as deprecated aliases for compatibility.
+
+Unless ``server.serve_frontend`` is disabled, the chat UI is served on ``/``
+from this same process/port — same-origin, so no CORS and no separate
+frontend tier to run. The standalone ``serviette frontend`` command remains for
+split deployments (UI host separate from the API host).
+"""
+
+from __future__ import annotations
+
+import logging
+from contextlib import asynccontextmanager
+from typing import Any
+
+from fastapi import APIRouter, FastAPI, HTTPException
+from fastapi.responses import HTMLResponse
+from pydantic import BaseModel, Field
+
+from serviette import APP_NAME
+from serviette.config.schema import (
+ AdaptiveRagConfig,
+ DocumentsConfig,
+ ServietteConfig,
+)
+from serviette.server import documents as docmode
+from serviette.server.accessors import AsyncVectorAccessor, build_accessor
+from serviette.server.accessors.abstract import IndexBusyError, IndexNotReadyError
+from serviette.server.decompose import decompose_query
+from serviette.server.embedder import AsyncEmbedder, build_embedder
+from serviette.server.llm import DEFAULT_SYSTEM_PROMPT, AsyncLLM, build_llm
+from serviette.server.ranking import interleave_merge, mmr_select
+from serviette.server.reranker import AsyncReranker, build_reranker
+
+logger = logging.getLogger(__name__)
+
+
+class RetrieveRequest(BaseModel):
+ query: str
+ k: int = Field(default=5, ge=1)
+
+
+class RetrieveResult(BaseModel):
+ text: str
+ metadata: dict[str, Any] = Field(default_factory=dict)
+ score: float
+
+
+class RetrieveResponse(BaseModel):
+ results: list[RetrieveResult]
+
+
+class DocumentEntry(BaseModel):
+ id: str
+ name: str
+ metadata: dict[str, Any] = Field(default_factory=dict)
+ chunks: int
+
+
+class DocumentsResponse(BaseModel):
+ """``GET /api/v1/documents``: the indexed documents whose name or path
+ contains ``q``. The list is left out when more than ``limit`` match —
+ the caller narrows the search instead of rendering thousands of rows."""
+
+ total: int # documents in the index
+ matched: int # of them, matching the filter
+ truncated: bool # matched > limit: ``documents`` was not sent
+ documents: list[DocumentEntry] = Field(default_factory=list)
+
+
+class RagResponse(BaseModel):
+ answer: str
+ sources: list[RetrieveResult]
+ # How the answer was produced: "search" (chunk retrieval), "catalog"
+ # (the document listing), "document" / "compare" (whole named documents)
+ # or "unresolved" (the question named documents that could not be
+ # identified). Anything but "search" comes from ``rag.documents``.
+ mode: str = "search"
+ # The documents the answer is scoped to (document / compare modes).
+ documents: list[str] = Field(default_factory=list)
+ # A system-computed remark on the answer's coverage, e.g. that only part
+ # of a document was read or how many differences were found.
+ notice: str | None = None
+
+
+class _IndexChangeTracker:
+ """Notice index changes the stored timestamps cannot show.
+
+ Accessors derive ``last_indexed_at`` from the newest row's ``seen_at``,
+ so a deletion (or an edit that only removes chunks) silently rolls the
+ value back to an older document. The tracker compares successive stats
+ snapshots and, when the row count or newest timestamp moves, records the
+ wall-clock time of that observation; ``observe`` then reports whichever
+ is later. State is per server process: after a restart the backend's
+ own value is used until the next change.
+ """
+
+ def __init__(self) -> None:
+ self._snapshot: tuple | None = None
+ self._changed_at: int | None = None
+
+ def observe(self, stats: dict[str, Any]) -> dict[str, Any]:
+ import time
+
+ key = (
+ stats.get("chunks"),
+ stats.get("documents"),
+ stats.get("last_indexed_at"),
+ )
+ if self._snapshot is None:
+ self._snapshot = key # first look: nothing to compare against
+ elif key != self._snapshot:
+ self._snapshot = key
+ self._changed_at = int(time.time())
+ stored = stats.get("last_indexed_at")
+ if self._changed_at is not None and (
+ stored is None or self._changed_at > stored
+ ):
+ stats["last_indexed_at"] = self._changed_at
+ return stats
+
+
+# Appended to a response's ``notice`` when the request ran into
+# rag.documents.max_request_chars.
+_BUDGET_NOTICE = (
+ " The request reached its LLM budget (rag.documents.max_request_chars), "
+ "so part of the material was left out."
+)
+
+# How often the server itself polls the backend for changes, so deletions
+# are stamped even while no chat page is open. Matches the page's own poll.
+_INDEX_POLL_SECONDS = 5.0
+
+
+def create_app(
+ config: ServietteConfig,
+ *,
+ embedder: AsyncEmbedder | None = None,
+ accessor: AsyncVectorAccessor | None = None,
+ llm: AsyncLLM | None = None,
+ reranker: AsyncReranker | None = None,
+) -> FastAPI:
+ """Build the FastAPI app.
+
+ The ``embedder``/``accessor``/``llm``/``reranker`` overrides exist for
+ testing (inject a mock embedder and a DuckDB accessor); in production they
+ are built from the config.
+ """
+
+ config.for_server()
+ # for_server() guarantees the sections; narrow them for the type checker.
+ assert config.vector_db is not None and config.embedder is not None
+
+ embedder = embedder or build_embedder(config.embedder)
+ accessor = accessor or build_accessor(config.vector_db)
+ # ``/rag`` is enabled only when an LLM is configured (or injected).
+ if llm is None and config.llm is not None:
+ llm = build_llm(config.llm)
+ # Reranking is opt-in: without a ``reranker`` section the vector-index
+ # order is returned as-is.
+ if reranker is None and config.reranker is not None:
+ reranker = build_reranker(config.reranker, config.llm)
+
+ # Retrieval-quality strategies (rag section) — validate at startup, not
+ # on the first unlucky request.
+ rag_cfg = config.rag
+ adaptive = rag_cfg.adaptive if rag_cfg else None
+ decompose = rag_cfg.decompose if rag_cfg else None
+ mmr = rag_cfg.mmr if rag_cfg else None
+ if decompose is not None and llm is None:
+ raise ValueError(
+ "rag.decompose requires an 'llm' config section (it uses one "
+ "LLM call to split the question into sub-queries)."
+ )
+ if mmr is not None and not accessor.supports_embeddings:
+ raise ValueError(
+ "rag.mmr needs hit embeddings, which the "
+ f"'{config.vector_db.type}' backend accessor does not return."
+ )
+ # On by default, so a backend that cannot enumerate documents turns it
+ # off quietly instead of refusing to start.
+ documents = rag_cfg.documents if rag_cfg else DocumentsConfig()
+ document_mode = documents.enabled and accessor.supports_catalog
+ if documents.enabled and not accessor.supports_catalog:
+ logger.info(
+ "rag.documents is off: the '%s' backend cannot list its documents",
+ config.vector_db.type,
+ )
+ # The reply that marks an attempt as failed: it drives the adaptive loop
+ # and, in document mode, the switch from search to documents.
+ no_answer = (
+ adaptive.no_answer_string
+ if adaptive
+ else AdaptiveRagConfig().no_answer_string
+ )
+
+ title = config.frontend.title if config.frontend else APP_NAME
+ tracker = _IndexChangeTracker()
+
+ @asynccontextmanager
+ async def lifespan(_: FastAPI):
+ # Local embedders (sentence-transformers) lazily import torch and
+ # load weights on first use — seconds the first user question must
+ # not pay. Warm them up with an invisible query before serving;
+ # API embedders skip this (a warm-up there costs real tokens).
+ if getattr(embedder, "is_local", False):
+ import time as _time
+
+ started = _time.monotonic()
+ logger.info(
+ "warming up the local embedder (importing the ML stack and "
+ "loading the model — the port opens once this is done)..."
+ )
+ await embedder.embed("serviette warmup")
+ logger.info(
+ "embedder ready in %.1fs", _time.monotonic() - started
+ )
+ if reranker is not None and getattr(reranker, "is_local", False):
+ import time as _time
+
+ started = _time.monotonic()
+ logger.info("warming up the local reranker...")
+ await reranker.rerank("serviette warmup", [{"text": "warmup"}], 1)
+ logger.info(
+ "reranker ready in %.1fs", _time.monotonic() - started
+ )
+ # API clients (LLM, LLM reranker) are built lazily; building them
+ # here moves the SDK import and connection setup out of the first
+ # /rag request. No request is made — nothing billable.
+ for name, component in (("llm", llm), ("reranker", reranker)):
+ prepare = getattr(component, "prepare", None)
+ if prepare is None:
+ continue
+ import time as _time
+
+ started = _time.monotonic()
+ await prepare()
+ logger.info(
+ "%s client ready in %.1fs", name, _time.monotonic() - started
+ )
+ import asyncio
+
+ async def _poll_index() -> None:
+ # Failures here are the backend being not-ready or briefly
+ # locked; the next tick simply looks again.
+ while True:
+ try:
+ tracker.observe(await accessor.stats())
+ except Exception as exc: # noqa: BLE001 - advisory only
+ logger.debug("index poll skipped: %s", exc)
+ await asyncio.sleep(_INDEX_POLL_SECONDS)
+
+ poller = asyncio.create_task(_poll_index())
+ try:
+ yield
+ finally:
+ poller.cancel()
+ await accessor.close()
+ await embedder.close()
+ if llm is not None:
+ await llm.close()
+ if reranker is not None:
+ await reranker.close()
+
+ app = FastAPI(title=f"{title} server", lifespan=lifespan)
+
+ if config.server and config.server.cors_origins:
+ # Off by default on purpose (see ServerConfig.cors_origins); an
+ # explicit allowlist opts in third-party browser frontends.
+ from fastapi.middleware.cors import CORSMiddleware
+
+ app.add_middleware(
+ CORSMiddleware,
+ allow_origins=config.server.cors_origins,
+ allow_methods=["*"],
+ allow_headers=["*"],
+ )
+
+ @app.exception_handler(IndexNotReadyError)
+ async def _index_not_ready(_request, exc: IndexNotReadyError):
+ # The indexer simply hasn't written its first batch yet, or is in
+ # the middle of writing one — normal states, not errors worth a
+ # stack trace.
+ from fastapi.responses import JSONResponse
+
+ if isinstance(exc, IndexBusyError):
+ detail = (
+ "The index is being updated — the indexer is writing a batch "
+ "of documents right now. Try again in a few seconds."
+ )
+ else:
+ detail = (
+ "The index is not ready yet — the indexer is still "
+ "starting or hasn't written its first documents. "
+ "Try again in a moment."
+ )
+ return JSONResponse(
+ status_code=503,
+ content={"detail": detail, "reason": str(exc)},
+ headers={"Retry-After": "5"},
+ )
+ v1 = APIRouter(prefix="/api/v1")
+
+ async def health() -> dict[str, str]:
+ return {"status": "ok"}
+
+ # Asymmetric-retrieval models (e5, bge) expect a query-side marker; the
+ # indexer applies the matching document_prefix. Empty for symmetric models.
+ backend_type = config.vector_db.type
+ query_prefix = config.embedder.query_prefix
+ rerank_candidates = config.reranker.candidates if config.reranker else 0
+
+ async def _queries(query: str) -> list[str]:
+ """The retrieval queries for ``query``: itself, plus its LLM
+ sub-queries when ``rag.decompose`` is on. Computed once per request —
+ the adaptive loop re-searches with a growing ``k`` and must not pay
+ (or re-roll) the decomposition on every round."""
+
+ if decompose is None:
+ return [query]
+ assert llm is not None # validated at startup when decompose is set
+ return await decompose_query(llm, query, decompose.max_subqueries)
+
+ async def _search(
+ query: str, k: int, queries: list[str] | None = None
+ ) -> list[dict[str, Any]]:
+ """Retrieval pipeline: (decompose) → fetch pool → (rerank) → (MMR) → top-k.
+
+ Each optional stage is driven by its config section; with none of
+ them configured this reduces to the plain embed-and-retrieve path.
+ ``queries`` lets a caller that searches repeatedly (adaptive RAG)
+ pass the decomposition it already obtained.
+ """
+
+ # A reranker or MMR selects k out of a wider candidate pool.
+ pool = max(k, rerank_candidates, mmr.candidates if mmr else 0)
+ need_embeddings = mmr is not None
+
+ if queries is None:
+ queries = await _queries(query)
+
+ async def fetch(q: str) -> list[dict[str, Any]]:
+ embedding = await embedder.embed(query_prefix + q)
+ return await accessor.retrieve_ex(
+ embedding, pool, query_text=q, with_embeddings=need_embeddings
+ )
+
+ if len(queries) == 1:
+ hits = await fetch(query)
+ else:
+ import asyncio
+
+ per_query = await asyncio.gather(*(fetch(q) for q in queries))
+ # Round-robin, not summed RRF: each sub-query's best chunk is
+ # guaranteed a slot (see interleave_merge).
+ hits = interleave_merge(list(per_query), pool)
+
+ if reranker is not None:
+ # Keep the pool wide when MMR still has to diversify after us.
+ keep = max(k, mmr.candidates) if mmr else k
+ hits = await reranker.rerank(query, hits, keep)
+ if mmr is not None:
+ hits = mmr_select(hits, k, mmr.diversity)
+ hits = hits[:k]
+ # Embeddings are pipeline plumbing, not API surface.
+ return [{key: v for key, v in h.items() if key != "embedding"} for h in hits]
+
+ async def retrieve(req: RetrieveRequest) -> RetrieveResponse:
+ hits = await _search(req.query, req.k)
+ return RetrieveResponse(results=[RetrieveResult(**h) for h in hits])
+
+ async def rag(req: RetrieveRequest) -> RagResponse:
+ if llm is None:
+ raise HTTPException(
+ status_code=501,
+ detail="The /rag endpoint requires an 'llm' config section.",
+ )
+ catalog = await _catalog() if document_mode else []
+ # One ceiling for everything this request sends to the LLM, across
+ # all of its calls (see docmode.Budget).
+ budget = docmode.Budget(documents.max_request_chars) if catalog else None
+ if catalog:
+ # A file named outright needs no search to find it — and a search
+ # would not find it anyway: chunk texts do not carry file names.
+ named = docmode.mentioned_names(req.query, catalog)
+ if named:
+ return await _answer_documents(req.query, catalog, named, budget)
+ if adaptive is None and not catalog:
+ hits = await _search(req.query, req.k)
+ answer = await llm.complete(req.query, [h["text"] for h in hits])
+ return RagResponse(
+ answer=answer, sources=[RetrieveResult(**h) for h in hits]
+ )
+ # The system prompt is independent parts: the answering *policy* (the
+ # configured llm.system_prompt, or the built-in grounded default),
+ # in document mode the corpus card, and the no-answer *protocol* —
+ # always appended, since the marker is what tells the loop below that
+ # the attempt failed.
+ policy = getattr(config.llm, "system_prompt", None) or DEFAULT_SYSTEM_PROMPT
+ card = (
+ f"\n\n{docmode.corpus_card(catalog)}"
+ if catalog and documents.corpus_card
+ else ""
+ )
+ label_sources = bool(catalog) and documents.source_labels
+ if label_sources:
+ card += "\n\n" + docmode.SOURCE_LABELS_NOTE.format(marker=no_answer)
+ system_prompt = (
+ f"{policy}{card}\n\n"
+ "If the provided context does not contain the information needed "
+ f'to answer, reply exactly "{no_answer}".'
+ )
+ # Adaptive RAG: grow the context geometrically while the LLM reports
+ # that it cannot answer from what it was given. Without rag.adaptive
+ # there is a single attempt.
+ k = req.k
+ queries = await _queries(req.query)
+ arbitrated = False
+ answer, hits = no_answer, []
+ for _iteration in range(adaptive.max_iterations if adaptive else 1):
+ found = await _search(req.query, k, queries)
+ context = (
+ docmode.labeled(found) if label_sources else [h["text"] for h in found]
+ )
+ attempt = await _complete(budget, req.query, context, system_prompt)
+ if attempt is None:
+ break # out of budget: keep the previous attempt's outcome
+ answer, hits = attempt[0], found[: len(attempt[1])]
+ if no_answer not in answer:
+ break
+ if catalog and not arbitrated:
+ # First failure: one short call decides who continues — the
+ # loop (a wider search may still find it) or document mode
+ # (no amount of chunks answers a question about documents).
+ # The switch is one-way and happens at most once.
+ arbitrated = True
+ route = await docmode.arbitrate(
+ llm, req.query, catalog, documents.max_listed_documents, budget
+ )
+ if route.mode == "catalog":
+ return await _answer_catalog(req.query, catalog, budget)
+ if route.mode == "documents":
+ return await _answer_documents(
+ req.query, catalog, route.files, budget
+ )
+ if adaptive is None:
+ break
+ if len(found) < k:
+ # Retrieval returned less than asked: the corpus (or the
+ # candidate pool) is exhausted, so a larger k would hand the
+ # LLM the very same context again. Stop instead of repeating
+ # the identical call until max_iterations.
+ break
+ k *= adaptive.factor
+ notice = None
+ if catalog and no_answer in answer:
+ notice = (
+ f"No answer was found in the {len(catalog)} indexed documents."
+ )
+ if budget is not None and budget.exhausted:
+ notice += _BUDGET_NOTICE
+ return RagResponse(
+ answer=answer,
+ sources=[RetrieveResult(**h) for h in hits],
+ notice=notice,
+ )
+
+ async def _complete(
+ budget: docmode.Budget | None,
+ query: str,
+ context: list[str],
+ system_prompt: str | None,
+ ) -> tuple[str, list[str]] | None:
+ """One answering call within the request's budget: the reply and the
+ context it was actually given (trailing items are dropped when the
+ budget is short), or ``None`` when nothing useful fits any more."""
+
+ assert llm is not None
+ if budget is not None:
+ fitted = budget.fit(len(system_prompt or "") + len(query), context)
+ if fitted is None:
+ return None
+ context = fitted
+ reply = await llm.complete(query, context, system_prompt=system_prompt)
+ return reply, context
+
+ async def _catalog() -> list[dict[str, Any]]:
+ """The document catalog, or ``[]`` when it cannot be had right now —
+ document mode is an addition and must never fail the ordinary path
+ (which reports a not-ready index properly on its own)."""
+
+ try:
+ return await accessor.list_documents()
+ except Exception as exc: # noqa: BLE001 - fall back to plain search
+ logger.debug("document catalog unavailable: %s", exc)
+ return []
+
+ async def _answer_catalog(
+ query: str, catalog: list[dict[str, Any]], budget: docmode.Budget | None
+ ) -> RagResponse:
+ context = docmode.catalog_context(catalog, documents.max_context_chars)
+ reply = await _complete(
+ budget, query, context, docmode.CATALOG_SYSTEM_PROMPT
+ )
+ if reply is None:
+ # Out of budget: the totals are the system's own and stand alone.
+ return RagResponse(
+ answer=context[0], sources=[], mode="catalog", notice=_BUDGET_NOTICE.strip()
+ )
+ return RagResponse(answer=reply[0], sources=[], mode="catalog")
+
+ async def _unresolved(
+ query: str, facts: str, budget: docmode.Budget | None
+ ) -> RagResponse:
+ """The question cannot be answered as asked: say why, concretely.
+ The facts are computed here; the LLM only words them in the user's
+ language, and they stand on their own if it fails to."""
+
+ try:
+ reply = await _complete(
+ budget, query, [facts], docmode.EXPLAIN_SYSTEM_PROMPT
+ )
+ except Exception: # noqa: BLE001 - the facts are the answer then
+ logger.warning("could not word a document-mode error; sending facts")
+ reply = None
+ answer = reply[0] if reply else ""
+ return RagResponse(
+ answer=answer.strip() or facts,
+ sources=[],
+ mode="unresolved",
+ notice=facts,
+ )
+
+ async def _answer_documents(
+ query: str,
+ catalog: list[dict[str, Any]],
+ names: list[str],
+ budget: docmode.Budget | None,
+ ) -> RagResponse:
+ """Answer from whole named documents: one is read (in full, or its
+ parts closest to the question), several are compared."""
+
+ assert llm is not None
+ resolution = docmode.resolve_names(names, catalog)
+ problems = [
+ f'No indexed document is named "{name}".'
+ + (f" Similar names: {', '.join(similar)}." if similar else "")
+ for name, similar in resolution.missing.items()
+ ]
+ if resolution.missing and not any(resolution.missing.values()):
+ # Nothing close to offer: show what there is instead.
+ names_known = sorted(docmode.document_name(e) for e in catalog)
+ shown = ", ".join(names_known[:20])
+ more = len(names_known) - 20
+ problems.append(
+ f"Indexed documents: {shown}"
+ + (f" and {more} more." if more > 0 else ".")
+ )
+ problems += [
+ f'"{name}" matches several indexed documents: {", ".join(ids)}. '
+ "Use the full path to say which one."
+ for name, ids in resolution.ambiguous.items()
+ ]
+ if not problems and not resolution.found:
+ problems = [
+ (
+ "The question is about specific documents but does not "
+ f"name them. There are {len(catalog)} indexed documents; "
+ "name the files to use."
+ )
+ ]
+ if problems:
+ return await _unresolved(query, " ".join(problems), budget)
+
+ entries = resolution.found
+ chunks = [
+ await accessor.document_chunks(entry["id"], with_embeddings=True)
+ for entry in entries
+ ]
+ gone = [
+ docmode.document_name(entry)
+ for entry, doc_chunks in zip(entries, chunks)
+ if not doc_chunks
+ ]
+ if gone:
+ return await _unresolved(
+ query, f"No longer in the index: {', '.join(gone)}.", budget
+ )
+ query_embedding = await embedder.embed(query_prefix + query)
+ limit = documents.max_context_chars
+ if len(entries) == 1:
+ mode = "document"
+ built = docmode.single_document_context(
+ entries[0], chunks[0], query_embedding, limit
+ )
+ else:
+ import asyncio
+
+ mode = "compare"
+ # Pairing changed passages is CPU-bound; keep it off the loop.
+ built = await asyncio.to_thread(
+ docmode.compare_context, entries, chunks, query_embedding, limit
+ )
+ reply = await _complete(budget, query, built.context, built.system_prompt)
+ notice = built.notice
+ if reply is None or len(reply[1]) < len(built.context):
+ notice = (notice or "") + _BUDGET_NOTICE
+ return RagResponse(
+ # Out of budget: the header (what was read, the exact totals) is
+ # the system's own and stands alone.
+ answer=reply[0] if reply else built.context[0],
+ sources=[RetrieveResult(**h) for h in built.sources],
+ mode=mode,
+ documents=[str(entry["id"]) for entry in entries],
+ notice=notice.strip() if notice else None,
+ )
+
+ async def stats() -> dict[str, Any]:
+ # Best-effort observability: backend identity + whatever the accessor
+ # can answer cheaply. Never fails the endpoint over a backend hiccup.
+ data: dict[str, Any] = {"backend": backend_type}
+ try:
+ data.update(tracker.observe(await accessor.stats()))
+ except Exception: # noqa: BLE001 - stats are advisory
+ data["stats_available"] = False
+ return data
+
+ async def list_documents(
+ q: str = "", case_sensitive: bool = False, limit: int = 100
+ ) -> DocumentsResponse:
+ """The document catalog, filtered by a fragment of the name or path.
+
+ Served from the accessor's cached catalog (nothing is scanned per
+ request), and only on demand — the chat page asks when the person
+ opens its document panel and searches, never on load.
+ """
+
+ if not accessor.supports_catalog:
+ raise HTTPException(
+ status_code=501,
+ detail=f"The '{backend_type}' backend cannot list its documents.",
+ )
+ limit = max(0, min(limit, 1000))
+ catalog = await accessor.list_documents()
+ needle = q if case_sensitive else q.casefold()
+
+ def matches(entry: dict[str, Any]) -> bool:
+ if not needle:
+ return True
+ haystacks = (docmode.document_name(entry), str(entry["id"]))
+ return any(
+ (needle in h) if case_sensitive else (needle in h.casefold())
+ for h in haystacks
+ )
+
+ matched = [entry for entry in catalog if matches(entry)]
+ truncated = len(matched) > limit
+ documents = (
+ []
+ if truncated
+ else [
+ DocumentEntry(
+ id=str(e["id"]),
+ name=docmode.document_name(e),
+ metadata=e.get("metadata") or {},
+ chunks=int(e.get("chunks", 0)),
+ )
+ for e in sorted(matched, key=docmode.document_name)
+ ]
+ )
+ return DocumentsResponse(
+ total=len(catalog), matched=len(matched), truncated=truncated, documents=documents
+ )
+
+ async def ui_config() -> dict[str, str]:
+ # Informational, consumed by the chat page; an empty api_url means
+ # "same origin" (embedded mode). No secrets here.
+ return {"title": title, "api_url": ""}
+
+ v1.get("/health")(health)
+ v1.post("/retrieve", response_model=RetrieveResponse)(retrieve)
+ v1.post("/rag", response_model=RagResponse)(rag)
+ v1.get("/stats")(stats)
+ v1.get("/documents", response_model=DocumentsResponse)(list_documents)
+ v1.get("/config")(ui_config)
+ app.include_router(v1)
+
+ # Pre-versioning aliases, kept for compatibility; will be removed after a
+ # deprecation window. New clients must use /api/v1/*.
+ app.get("/health", deprecated=True)(health)
+ app.post("/retrieve", response_model=RetrieveResponse, deprecated=True)(retrieve)
+ app.post("/rag", response_model=RagResponse, deprecated=True)(rag)
+
+ if config.server.serve_frontend:
+ from serviette.frontend.main import load_index
+
+ index_html = load_index(title)
+
+ @app.get("/", response_class=HTMLResponse, include_in_schema=False)
+ async def index() -> HTMLResponse:
+ return HTMLResponse(index_html)
+
+ return app
+
+
+class _DropPollingAccessLines(logging.Filter):
+ """Hide the access-log lines of the endpoints that are polled, not asked.
+
+ The chat UI refreshes ``/stats`` every few seconds and ``serviette up``
+ probes ``/health`` while waiting for the server: logged, they fill an idle
+ terminal with one identical line per poll and bury the requests that
+ matter (``/rag``, ``/retrieve``). uvicorn logs every request as
+ ``'%s - "%s %s HTTP/%s" %d'`` with the path as the third argument."""
+
+ _POLLED = ("/api/v1/stats", "/health")
+
+ def filter(self, record: logging.LogRecord) -> bool:
+ args = record.args
+ if isinstance(args, tuple) and len(args) == 5:
+ path = str(args[2]).split("?", 1)[0]
+ return path not in self._POLLED
+ return True
+
+
+def run(config: ServietteConfig) -> None:
+ """Start uvicorn with the configured host/port (used by the CLI)."""
+
+ import uvicorn
+
+ from serviette.config.schema import require_openai_credentials
+
+ # The embedder is needed on the first /retrieve and the LLM on the first
+ # /rag: without a key both would fail as a 500 then. Say it now instead.
+ require_openai_credentials(config, roles=("embedder", "llm"))
+
+ # uvicorn configures only its own loggers; without a root handler the
+ # warm-up progress above is silently dropped and the user stares at
+ # "Waiting for application startup." for as long as the model loads.
+ if not logging.getLogger().handlers:
+ logging.basicConfig(level=logging.INFO, format="%(levelname)s %(message)s")
+ # Chatty at INFO: one line per HTTP request (httpx) and per model file
+ # the hub checks (sentence-transformers / huggingface_hub).
+ for name in ("httpx", "httpcore", "sentence_transformers", "huggingface_hub"):
+ logging.getLogger(name).setLevel(logging.WARNING)
+ logging.getLogger("uvicorn.access").addFilter(_DropPollingAccessLines())
+ app = create_app(config)
+ uvicorn.run(app, host=config.server.host, port=config.server.port)
diff --git a/serviette/server/ranking.py b/serviette/server/ranking.py
new file mode 100644
index 00000000..1665f238
--- /dev/null
+++ b/serviette/server/ranking.py
@@ -0,0 +1,118 @@
+"""Rank fusion and diversification — pure functions over hit dicts.
+
+Hits are the accessor result dicts (``text`` / ``metadata`` / ``score``,
+plus ``embedding`` when the accessor was asked for it). Scores coming from
+different queries or different scorers are not comparable, so fusion here is
+rank-based (reciprocal-rank fusion) rather than score-based.
+"""
+
+from __future__ import annotations
+
+import math
+from typing import Any
+
+# The standard RRF dampening constant (Cormack et al.): small enough that
+# top ranks dominate, large enough that a #1 in one list does not drown a
+# consistent #3 in every list.
+RRF_K = 60
+
+
+def rrf_merge(
+ result_lists: list[list[dict[str, Any]]], limit: int
+) -> list[dict[str, Any]]:
+ """Fuse ranked result lists with reciprocal-rank fusion.
+
+ A hit appearing in several lists (same ``text``) sums its 1/(RRF_K + rank)
+ contributions, so chunks that answer *several* sub-queries rise. The fused
+ RRF value replaces ``score`` — original per-query similarities are not
+ comparable across lists.
+ """
+
+ fused: dict[str, dict[str, Any]] = {}
+ scores: dict[str, float] = {}
+ for hits in result_lists:
+ for rank, hit in enumerate(hits):
+ key = hit["text"]
+ scores[key] = scores.get(key, 0.0) + 1.0 / (RRF_K + rank + 1)
+ # Keep the first-seen dict (embedding included when present).
+ fused.setdefault(key, hit)
+ merged = [
+ {**fused[key], "score": score}
+ for key, score in sorted(scores.items(), key=lambda kv: -kv[1])
+ ]
+ return merged[:limit]
+
+
+def interleave_merge(
+ result_lists: list[list[dict[str, Any]]], limit: int
+) -> list[dict[str, Any]]:
+ """Round-robin fusion for multi-query (decomposed) retrieval.
+
+ Takes every list's rank-1 hit, then every rank-2, and so on, deduplicating
+ by ``text``. Unlike summed RRF this *guarantees* the top hit of each
+ sub-query a slot — for multi-hop questions a chunk that is perfect for one
+ hop must beat a chunk that is mediocre for every hop. Hits keep their own
+ per-query scores (not comparable across lists; order is the contract).
+ """
+
+ merged: list[dict[str, Any]] = []
+ seen: set[str] = set()
+ for rank in range(max((len(hits) for hits in result_lists), default=0)):
+ for hits in result_lists:
+ if rank >= len(hits) or len(merged) >= limit:
+ continue
+ hit = hits[rank]
+ if hit["text"] not in seen:
+ seen.add(hit["text"])
+ merged.append(hit)
+ return merged[:limit]
+
+
+def _cosine(a: list[float], b: list[float]) -> float:
+ dot = sum(x * y for x, y in zip(a, b))
+ na = math.sqrt(sum(x * x for x in a))
+ nb = math.sqrt(sum(x * x for x in b))
+ if na == 0.0 or nb == 0.0:
+ return 0.0
+ return dot / (na * nb)
+
+
+def mmr_select(
+ hits: list[dict[str, Any]], k: int, diversity: float
+) -> list[dict[str, Any]]:
+ """Greedy maximal-marginal-relevance selection of ``k`` hits.
+
+ Relevance is the incoming order's score min-max-normalized over the pool;
+ redundancy is the max cosine similarity to the already-selected set (via
+ each hit's ``embedding``). ``diversity`` weighs redundancy: 0 reduces to
+ plain top-k, 1 ignores relevance entirely. Hits missing an embedding are
+ treated as maximally novel rather than dropped.
+ """
+
+ if k >= len(hits) or not hits:
+ return list(hits)
+ lo = min(h["score"] for h in hits)
+ hi = max(h["score"] for h in hits)
+ span = (hi - lo) or 1.0
+ relevance = [(h["score"] - lo) / span for h in hits]
+
+ selected: list[int] = []
+ remaining = list(range(len(hits)))
+ while remaining and len(selected) < k:
+ best_i, best_val = remaining[0], -math.inf
+ for i in remaining:
+ emb = hits[i].get("embedding")
+ redundancy = 0.0
+ if emb is not None and selected:
+ sims = [
+ _cosine(emb, hits[j]["embedding"])
+ for j in selected
+ if hits[j].get("embedding") is not None
+ ]
+ redundancy = max(sims) if sims else 0.0
+ value = (1.0 - diversity) * relevance[i] - diversity * redundancy
+ if value > best_val:
+ best_i, best_val = i, value
+ selected.append(best_i)
+ remaining.remove(best_i)
+ return [hits[i] for i in selected]
diff --git a/serviette/server/reranker.py b/serviette/server/reranker.py
new file mode 100644
index 00000000..d8385b0d
--- /dev/null
+++ b/serviette/server/reranker.py
@@ -0,0 +1,182 @@
+"""Second-stage reranking for the server.
+
+Mirrors the embedder module's design: a small async protocol, local
+inference moved off the event loop with ``asyncio.to_thread``, and a
+``build_reranker`` factory driven by the config section. The cross-encoder
+scores every (query, chunk) candidate pair jointly, which recovers matches
+that bi-encoder distance ranks poorly; it only ever sees the shortlist the
+vector index returns, so cost stays bounded by ``candidates``, not corpus
+size.
+"""
+
+from __future__ import annotations
+
+from typing import Any, Protocol, runtime_checkable
+
+
+@runtime_checkable
+class AsyncReranker(Protocol):
+ async def rerank(
+ self, query: str, hits: list[dict[str, Any]], k: int
+ ) -> list[dict[str, Any]]:
+ ...
+
+ async def close(self) -> None:
+ ...
+
+
+class CrossEncoderReranker:
+ """Rerank with a local sentence-transformers cross-encoder.
+
+ ``is_local = True`` opts into the server's startup warm-up, same as the
+ local embedder: the first user question must not pay the model load.
+ """
+
+ _DEFAULT_MODEL = "cross-encoder/ms-marco-MiniLM-L-6-v2"
+ is_local = True
+
+ # ``CrossEncoder.predict`` options; every other extra key is a
+ # constructor kwarg (``device``, ``max_length``, ``trust_remote_code``, ...).
+ _PREDICT_KEYS = frozenset({
+ "batch_size",
+ "show_progress_bar",
+ "num_workers",
+ "activation_fct",
+ "apply_softmax",
+ "convert_to_numpy",
+ "convert_to_tensor",
+ })
+
+ def __init__(self, config) -> None:
+ self._model_name = config.model or self._DEFAULT_MODEL
+ extra = config.model_dump(exclude={"type", "model", "api_key", "candidates"})
+ extra = {k: v for k, v in extra.items() if v is not None}
+ self._model_kwargs = {k: v for k, v in extra.items() if k not in self._PREDICT_KEYS}
+ self._model_kwargs.setdefault("device", "cpu")
+ self._predict_kwargs = {k: v for k, v in extra.items() if k in self._PREDICT_KEYS}
+ self._model = None
+
+ def _ensure_model(self):
+ if self._model is None:
+ from sentence_transformers import CrossEncoder
+
+ self._model = CrossEncoder(self._model_name, **self._model_kwargs)
+ return self._model
+
+ async def rerank(
+ self, query: str, hits: list[dict[str, Any]], k: int
+ ) -> list[dict[str, Any]]:
+ import asyncio
+
+ if not hits:
+ return hits
+ model = await asyncio.to_thread(self._ensure_model)
+ scores = await asyncio.to_thread(
+ model.predict, [(query, hit["text"]) for hit in hits], **self._predict_kwargs
+ )
+ reranked = [
+ {**hit, "score": float(score)}
+ for score, hit in sorted(
+ zip(scores, hits), key=lambda pair: -float(pair[0])
+ )
+ ]
+ return reranked[:k]
+
+ async def close(self) -> None:
+ self._model = None
+
+
+_RERANK_PROMPT = """\
+Rate how relevant the document is for answering the query, as an integer \
+from 0 (irrelevant) to 5 (directly answers it). Respond with the number only.
+
+Query: {query}
+
+Document: {doc}"""
+
+
+class LLMReranker:
+ """Pointwise LLM reranking, after ``pathway.xpacks.llm.rerankers.LLMReranker``.
+
+ Each candidate is rated 0–5 by an LLM (one cheap call per candidate,
+ issued concurrently). An unparseable rating scores the candidate 0 rather
+ than failing the request. ``is_local = False``: nothing to warm up.
+ """
+
+ is_local = False
+
+ def __init__(self, config, llm_config=None, *, chat=None) -> None:
+ # The scorer is any AsyncLLM (only ``raw`` is used). Tests inject a
+ # fake via ``chat``; production lazily builds the configured backend
+ # (build_llm) from the reranker section, falling back to the
+ # top-level llm section.
+ self._chat = chat
+ self._config = config
+ self._llm_config = llm_config
+
+ def _ensure_chat(self):
+ if self._chat is None:
+ merged = dict(self._llm_config.model_dump() if self._llm_config else {})
+ overrides = self._config.model_dump(exclude={"type", "candidates"})
+ merged.update({k: v for k, v in overrides.items() if v is not None})
+ merged.setdefault("type", "openai")
+
+ from serviette.config.schema import LLMConfig
+ from serviette.server.llm import build_llm
+
+ # build_llm, not OpenAIChat directly: a litellm-typed llm section
+ # must route through LiteLLM, not the plain OpenAI client.
+ self._chat = build_llm(LLMConfig(**merged))
+ return self._chat
+
+ async def prepare(self) -> None:
+ """Build the scoring LLM client now (no request), see AsyncLLM.prepare."""
+
+ chat = self._ensure_chat()
+ prepare = getattr(chat, "prepare", None)
+ if prepare is not None:
+ await prepare()
+
+ async def rerank(
+ self, query: str, hits: list[dict[str, Any]], k: int
+ ) -> list[dict[str, Any]]:
+ import asyncio
+
+ if not hits:
+ return hits
+ chat = self._ensure_chat()
+
+ async def score(hit: dict[str, Any]) -> float:
+ reply = await chat.raw(
+ _RERANK_PROMPT.format(query=query, doc=hit["text"])
+ )
+ return _parse_rating(reply)
+
+ scores = await asyncio.gather(*(score(hit) for hit in hits))
+ reranked = [
+ {**hit, "score": float(s)}
+ for s, hit in sorted(zip(scores, hits), key=lambda pair: -pair[0])
+ ]
+ return reranked[:k]
+
+ async def close(self) -> None:
+ if self._chat is not None:
+ await self._chat.close()
+ self._chat = None
+
+
+def _parse_rating(reply: str) -> float:
+ """First number in the reply, or 0.0 when there is none."""
+
+ import re
+
+ match = re.search(r"\d+(?:\.\d+)?", reply)
+ return float(match.group()) if match else 0.0
+
+
+def build_reranker(config, llm_config=None) -> AsyncReranker:
+ if config.type in {"cross_encoder", "crossencoder"}:
+ return CrossEncoderReranker(config)
+ if config.type == "llm":
+ return LLMReranker(config, llm_config)
+ raise ValueError(f"Unsupported reranker type: {config.type!r}")
diff --git a/serviette/testing.py b/serviette/testing.py
new file mode 100644
index 00000000..617b0544
--- /dev/null
+++ b/serviette/testing.py
@@ -0,0 +1,38 @@
+"""Test-support helpers (not part of the public API; not user-documented).
+
+Provides a deterministic, dependency-free fake embedding shared by the test
+suite and by the test-only ``mock`` embedder type, so the indexer can run
+end-to-end without any embedding provider or credentials.
+"""
+
+from __future__ import annotations
+
+import hashlib
+
+# numpy is a transitive dependency of pathway; importing it at module scope keeps
+# it visible in this module's globals so Pathway can resolve the mock embedder's
+# ``-> np.ndarray`` return annotation.
+import numpy as np
+
+EMBED_DIM = 384
+
+
+def fake_embedding(text: str) -> list[float]:
+ """Deterministic fake embedding: SHA-256 of ``text`` tiled to 384 floats."""
+
+ digest = hashlib.sha256(text.encode("utf-8")).digest() # 32 bytes
+ repeats = (EMBED_DIM // len(digest)) + 1
+ raw = (digest * repeats)[:EMBED_DIM]
+ return [b / 255.0 for b in raw]
+
+
+def build_mock_embedder():
+ """Return a Pathway UDF mock embedder (imports pathway lazily)."""
+
+ import pathway as pw
+
+ @pw.udf(deterministic=True) # pure hash; the engine need not memoize it
+ def embed(text: str) -> np.ndarray:
+ return np.array(fake_embedding(text), dtype=float)
+
+ return embed
diff --git a/serviette/up.py b/serviette/up.py
new file mode 100644
index 00000000..13bfa5ff
--- /dev/null
+++ b/serviette/up.py
@@ -0,0 +1,662 @@
+"""``serviette up`` — run the indexer and the server together from one config.
+
+A deliberately dumb supervisor: it spawns ``serviette indexer``, waits until
+the vector store is queryable (printing an "indexing in progress" heartbeat
+— the chat page must never open onto a guaranteed error), then spawns
+``serviette server`` and waits until its ``/api/v1/health`` answers before
+printing the URL to open (uvicorn binds the port only after the lifespan
+warm-up — a local embedder imports torch and loads its model there, tens of
+seconds during which the port is not even listening). No refresh loops —
+every backend runs its native streaming mode, so freshness is seconds
+everywhere. Teardown rules:
+
+- SIGINT/SIGTERM → terminate both children, exit 0.
+- server exits (any code) → terminate the indexer, exit with the server code.
+- indexer exits non-zero → terminate the server, exit with that code.
+- indexer exits 0 (all sources were ``mode: static``) → one-shot indexing
+ finished; the server keeps serving.
+
+This is a dev/demo convenience; production deployments still run the
+components separately (see docs/README "Scaling").
+"""
+
+from __future__ import annotations
+
+import logging
+import os
+import re
+import signal
+import subprocess
+import sys
+import threading
+import time
+
+from serviette.config.schema import (
+ ServietteConfig,
+ require_multi_process_backend,
+ require_openai_credentials,
+ require_source_dirs,
+)
+
+logger = logging.getLogger(__name__)
+
+_POLL_INTERVAL = 0.3
+_TERM_GRACE = 10.0
+
+
+# How many of a child's last output lines are kept for the failure report.
+_TAIL_LINES = 80
+
+# Routine lines of a child's output, hidden unless ``--verbose``: INFO/DEBUG
+# records of Python logging in either common format ("INFO:name:msg",
+# "INFO msg", uvicorn's "INFO: msg"), and tqdm progress bars. Everything
+# else — warnings, errors, tracebacks (whose continuation lines are
+# indented), Rust panics, a child's own print() — passes through.
+_ROUTINE_LINE = re.compile(r"^(INFO|DEBUG)\b|^\s*(Batches|Loading weights):\s")
+
+# Lines of the indexer's output that prove it is working on documents — the
+# per-document ``parsing …`` / ``parsed …`` lines of serviette's parse UDF,
+# the xpack parsers' own progress, non-zero input batches reaching the
+# engine, and the embedder's progress bar. ``_wait_for_index`` measures its
+# timeout from the last such line, so a slow parse is not mistaken for an
+# index that will never fill (see ``Activity`` below).
+_ACTIVITY_LINE = re.compile(
+ r"\b(parsing|parsed) \S|starting to parse|completed parsing"
+ r"|\b[1-9]\d* entries \(\d+ minibatch|^\s*Batches:\s"
+)
+_EMBEDDING_LINE = re.compile(r"^\s*Batches:\s")
+_PARSING_LINE = re.compile(r":parsing (?P.+?) \([^)]*\)\s*$")
+_PARSED_LINE = re.compile(r":parsed (?P.+?): \d+ chars in ")
+
+
+def _is_routine(line: str) -> bool:
+ return bool(_ROUTINE_LINE.match(line)) or not line.strip()
+
+
+class Activity:
+ """What the indexer was last seen doing, gathered from its output.
+
+ Updated by the output-forwarding thread, read by ``_wait_for_index``:
+ ``last_seen`` is the time of the last line matching ``_ACTIVITY_LINE``
+ (the spawn time until then), ``current`` the document being parsed, if
+ any, and ``parsed`` how many documents finished parsing."""
+
+ def __init__(self) -> None:
+ self.last_seen = time.monotonic()
+ self.current: str | None = None
+ self.parsed = 0
+ self.embedding = False # the embedder's progress bar was the last thing seen
+ self._lock = threading.Lock()
+
+ def observe(self, line: str) -> None:
+ if not _ACTIVITY_LINE.search(line):
+ return
+ with self._lock:
+ self.last_seen = time.monotonic()
+ self.embedding = bool(_EMBEDDING_LINE.match(line))
+ if m := _PARSING_LINE.search(line):
+ self.current = m.group("name")
+ elif m := _PARSED_LINE.search(line):
+ self.parsed += 1
+ if self.current == m.group("name"):
+ self.current = None
+
+ def describe(self) -> str:
+ with self._lock:
+ parsed = f"{self.parsed} parsed so far" if self.parsed else ""
+ if self.current is not None:
+ return f"parsing {os.path.basename(self.current)}" + (f" ({parsed})" if parsed else "")
+ if self.embedding:
+ return "embedding" + (f" ({parsed})" if parsed else "")
+ return f"{self.parsed} documents parsed" if self.parsed else "waiting for the first documents"
+
+
+def _spawn(
+ command: str,
+ config_path: str,
+ *,
+ env: dict[str, str] | None = None,
+ verbose: bool = True,
+) -> subprocess.Popen:
+ """Start a child whose output passes through ``up``.
+
+ ``up`` keeps the child's last lines (``proc.tail``) so that, when the
+ child dies, the report can name the cause instead of leaving the user to
+ find the right traceback among the engine's INFO lines. With ``verbose``
+ every line reaches the terminal as it arrives; otherwise only the ones
+ that are not routine (see ``_ROUTINE_LINE``) — the tail keeps them all
+ either way. ``PYTHONUNBUFFERED`` keeps the child from block-buffering now
+ that its stdout is a pipe.
+ """
+
+ from collections import deque
+
+ proc = subprocess.Popen(
+ [sys.executable, "-m", "serviette.cli", command, "--config", config_path],
+ env={**(env if env is not None else os.environ), "PYTHONUNBUFFERED": "1"},
+ stdout=subprocess.PIPE,
+ stderr=subprocess.STDOUT,
+ text=True,
+ errors="replace",
+ )
+ tail: deque[str] = deque(maxlen=_TAIL_LINES)
+ activity = Activity()
+
+ def forward() -> None:
+ assert proc.stdout is not None
+ for line in iter(proc.stdout.readline, ""):
+ tail.append(line.rstrip("\n"))
+ activity.observe(line)
+ if verbose or not _is_routine(line):
+ sys.stderr.write(line)
+ sys.stderr.flush()
+
+ threading.Thread(target=forward, name=f"up-{command}-output", daemon=True).start()
+ proc.tail = tail # type: ignore[attr-defined]
+ proc.activity = activity # type: ignore[attr-defined]
+ return proc
+
+
+# Known ways a child dies, matched against its last output lines: the
+# cause named for the user, and what to do about it.
+_FAILURE_HINTS: list[tuple[str, str, str]] = [
+ (
+ r"Missing credentials|OPENAI_API_KEY",
+ "no OpenAI API key was available",
+ "export OPENAI_API_KEY=sk-... (or set api_key in the config section) and start again.",
+ ),
+ (
+ r"insufficient_quota|exceeded your current quota",
+ "the OpenAI account has no remaining quota",
+ ("check billing at https://platform.openai.com, or switch the embedder to "
+ "sentence_transformer (free, local)."),
+ ),
+ (
+ r"Error code: 429|RateLimitError|rate_limit_exceeded",
+ ("OpenAI rate limit (HTTP 429) while embedding — the indexer stops at the "
+ "first failed batch"),
+ ("start again (persistence resumes from what was already processed); to stay "
+ "under the limit index the folder in parts or lower indexer.workers."),
+ ),
+ (
+ r"Error code: 401|AuthenticationError|Incorrect API key",
+ "the OpenAI API key was rejected",
+ "check OPENAI_API_KEY / api_key in the config.",
+ ),
+ (
+ r"address already in use",
+ "the server port is already taken",
+ "stop the other process or change server.port.",
+ ),
+ (
+ r"DataDirLockedError|another process holds the lock",
+ "the embedded database file is locked by another process",
+ "stop the other serviette/Milvus process, or use a database server.",
+ ),
+ (
+ r"license",
+ "the Pathway license key is missing or invalid",
+ ("get a free key at https://pathway.com/framework/get-license and export "
+ "PATHWAY_LICENSE_KEY."),
+ ),
+ (
+ (r"Connection refused|error sending request|ConnectError|Failed to connect|"
+ r"Name or service not known"),
+ "a network service (the vector database or an API) could not be reached",
+ "check that it is running and that host/port in the config are right.",
+ ),
+]
+
+
+def _failure_report(name: str, code: int, tail: list[str] | None) -> str:
+ """The block printed when a child dies: unmistakable, with the cause
+ recognised from the child's last lines where possible."""
+
+ import re
+
+ cause = advice = None
+ if tail:
+ text = "\n".join(tail)
+ for pattern, hint_cause, hint_advice in _FAILURE_HINTS:
+ if re.search(pattern, text, re.IGNORECASE):
+ cause, advice = hint_cause, hint_advice
+ break
+ lines = [
+ "",
+ "=" * 72,
+ f"serviette up STOPPED: the {name} exited with code {code}.",
+ ]
+ if cause:
+ lines.append(f"Cause: {cause}.")
+ lines.append(f"What to do: {advice}")
+ else:
+ lines.append(
+ f"The {name}'s last traceback above says why; the lines before it "
+ "are routine engine output."
+ )
+ lines.append("=" * 72)
+ return "\n".join(lines)
+
+
+def _report_exit(name: str, code: int, proc: subprocess.Popen) -> None:
+ import time as _time
+
+ # Give the forwarding thread a moment to drain the child's last lines.
+ _time.sleep(0.2)
+ logger.error(_failure_report(name, code, list(getattr(proc, "tail", None) or [])))
+
+
+def _confirm_fingerprint(config: ServietteConfig) -> dict[str, str]:
+ """Ask the fingerprint question here, not in the indexer child.
+
+ The child shares this terminal; its ``input()`` prompt would sit under
+ the "indexing in progress" heartbeat printed every few seconds, so the
+ user sees progress while the indexer actually waits for a "yes". Same
+ check (diff, prompt on a TTY, refusal otherwise), same env override —
+ just asked before anything else is printed. Returns the environment for
+ the child, which tells it the answer is already given.
+ """
+
+ from serviette.indexer.fingerprint import ACCEPT_ENV, check_fingerprint
+
+ check_fingerprint(config) # updates the stored fingerprint on "yes"
+ return {**os.environ, ACCEPT_ENV: "1"}
+
+
+def _terminate(proc: subprocess.Popen, name: str) -> None:
+ if proc.poll() is not None:
+ return
+ proc.terminate()
+ try:
+ proc.wait(timeout=_TERM_GRACE)
+ except subprocess.TimeoutExpired:
+ logger.warning("%s did not stop in %.0fs; killing it", name, _TERM_GRACE)
+ proc.kill()
+ proc.wait()
+
+
+def _warn_duckdb_streaming(config: ServietteConfig) -> None:
+ # Pathway builds with detach_between_batches in the duckdb sink
+ # (>= 0.32.1) release the file lock between minibatches and the
+ # server reads the file concurrently; only warn on older builds, where a
+ # STREAMING indexer holds the file read-write for its lifetime.
+ if config.vector_db and config.vector_db.type == "duckdb" and any(
+ src.mode == "streaming" for src in config.sources
+ ):
+ import inspect
+
+ import pathway as pw
+
+ supported = (
+ "detach_between_batches"
+ in inspect.signature(pw.io.duckdb.write).parameters
+ )
+ if not supported:
+ logger.warning(
+ "DuckDB + streaming sources on this pathway build: the indexer "
+ "holds the database file read-write, so server queries will "
+ "fail with a lock error until the indexer stops. Upgrade "
+ "pathway (duckdb detach_between_batches) or use a "
+ "client-server backend for live serving."
+ )
+
+
+_WAIT_HEARTBEAT = 5.0
+
+
+def _sources_look_empty(config: ServietteConfig) -> bool:
+ """True when every source is a local folder with no matching files.
+
+ Only decidable for ``fs`` sources; any remote source counts as
+ potentially non-empty. Used to let `serviette up` serve an empty index
+ immediately (a legitimate state — drop files in later and watch them
+ appear) instead of waiting forever for chunks that will never come.
+ """
+
+ import fnmatch
+ from pathlib import Path
+
+ for src in config.sources:
+ if src.type != "fs":
+ return False
+ base = Path(src.path)
+ if not base.exists():
+ continue
+ for candidate in base.rglob("*"):
+ if candidate.is_file() and fnmatch.fnmatch(
+ str(candidate.relative_to(base)), src.glob.removeprefix("**/")
+ ):
+ return False
+ return True
+
+
+def _index_ready(config: ServietteConfig, *, allow_empty: bool = False) -> bool:
+ """True once the vector store answers a trivial query.
+
+ Uses the same accessor as the server, so "ready" here is exactly
+ "the first server request will not fail with not-ready".
+ """
+
+ import asyncio
+
+ from serviette.server.accessors import build_accessor
+ from serviette.server.accessors.abstract import IndexNotReadyError
+
+ async def _probe() -> bool:
+ accessor = build_accessor(config.vector_db)
+ try:
+ stats = await accessor.stats()
+ if allow_empty:
+ # Sources are empty folders: a queryable-but-empty store is
+ # the correct steady state; serve it and index files live as
+ # they appear.
+ return True
+ # prepare_backend creates empty tables/collections at indexer
+ # startup — "queryable" is not "has data". The indexer runs
+ # forever in streaming mode, so the only start signal is actual
+ # content: wait for the first chunks.
+ chunks = stats.get("chunks")
+ return True if chunks is None else chunks > 0
+ except IndexNotReadyError:
+ return False
+ finally:
+ await accessor.close()
+
+ try:
+ return asyncio.run(_probe())
+ except Exception: # noqa: BLE001 - backend may not even be reachable yet
+ return False
+
+
+def _wait_for_index(
+ config: ServietteConfig,
+ indexer: subprocess.Popen,
+ *,
+ should_stop=lambda: False,
+ ready=_index_ready,
+) -> int | None:
+ """Block until the store is queryable; heartbeat to the console.
+
+ Returns the indexer's exit code if it died before producing anything
+ (the caller aborts), otherwise None once the index is ready. Like
+ ``_wait_for_server``, ``should_stop`` lets a signal handler cut the wait
+ short (returns None; the caller checks the flag) — otherwise a SIGTERM
+ during a long first indexing pass would be ignored until the first
+ chunks land. ``ready`` is injectable for tests.
+
+ The wait is bounded by ``up.index_wait_timeout``: a non-empty folder
+ whose documents all yield no text (scans without OCR, audio without its
+ API key, parser failures) never produces a chunk, and the indexer keeps
+ running in streaming mode — without the bound ``up`` would heartbeat
+ forever. On expiry the server starts over the empty index with a
+ warning; whatever becomes indexable later shows up live.
+
+ Activity: the bound is measured from the indexer's last sign of work
+ (``indexer.activity``, fed by its output — see ``_ACTIVITY_LINE``), not
+ from the start. Parsing a few large PDFs takes minutes and produces no
+ chunk until the first one is through; a timeout counted from the start
+ fired in the middle of that and announced an empty index that was about
+ to fill. The empty-text case is unchanged: parsing finishes quickly,
+ then nothing happens for ``timeout`` seconds.
+ """
+
+ started = time.monotonic()
+ last_beat = 0.0
+ timeout = config.up.index_wait_timeout
+ activity: Activity | None = getattr(indexer, "activity", None)
+ allow_empty = _sources_look_empty(config)
+ if allow_empty:
+ logger.info(
+ "up: the source folders are empty — starting with an empty "
+ "index; documents dropped in later are indexed live"
+ )
+ while not ready(config, allow_empty=allow_empty):
+ if should_stop():
+ return None
+ code = indexer.poll()
+ if code is not None and code != 0:
+ return code
+ if code == 0:
+ # Static run finished but the store is still not queryable —
+ # nothing was produced (e.g. empty source); let the caller
+ # decide, the server can legitimately serve an empty index.
+ return None
+ now = time.monotonic()
+ last_sign = max(started, activity.last_seen) if activity is not None else started
+ if timeout is not None and now - last_sign >= timeout:
+ logger.warning(
+ "up: no document produced a chunk, and the indexer showed no "
+ "activity for %.0fs — starting the server over an empty index "
+ "anyway. Check the indexer log above for skipped or failed "
+ "documents (a parser missing its package or API key, fetch "
+ "errors); documents keep being indexed live. Tune or disable "
+ "this with up.index_wait_timeout.",
+ now - last_sign,
+ )
+ return None
+ if now - last_beat >= _WAIT_HEARTBEAT:
+ last_beat = now
+ logger.info(
+ "up: indexing in progress — %s; the chat/API server starts once "
+ "the first documents are ready (%.0fs elapsed)",
+ activity.describe() if activity is not None else "waiting for the first documents",
+ now - started,
+ )
+ time.sleep(1.0)
+ return None
+
+
+def _server_url(config: ServietteConfig) -> str:
+ """The URL a browser on this machine opens (0.0.0.0 -> localhost)."""
+
+ host = config.server.host
+ if host in ("0.0.0.0", "127.0.0.1", "::"):
+ host = "localhost"
+ return f"http://{host}:{config.server.port}"
+
+
+def _probe_host(host: str) -> str:
+ """The address ``up`` probes for the configured bind address.
+
+ A wildcard bind (0.0.0.0 / ::) is not connectable as written but listens
+ on loopback; a specific address or hostname is reachable only as itself
+ — probing loopback for it (as ``up`` used to) never succeeds. An IPv6
+ literal must be bracketed in a URL.
+ """
+
+ if host in ("", "0.0.0.0"):
+ return "127.0.0.1"
+ if host == "::":
+ return "[::1]"
+ if ":" in host:
+ return f"[{host}]"
+ return host
+
+
+def _server_ready(config: ServietteConfig) -> bool:
+ """True once the server answers ``/api/v1/health`` on its bind address."""
+
+ import httpx
+
+ url = (
+ f"http://{_probe_host(config.server.host)}:{config.server.port}"
+ "/api/v1/health"
+ )
+ try:
+ # trust_env=False: a loopback probe must never go through the
+ # http_proxy / HTTPS_PROXY of the environment — corporate proxies
+ # refuse 127.0.0.1 and the wait below would never end.
+ response = httpx.get(url, timeout=2.0, trust_env=False)
+ except httpx.HTTPError:
+ return False
+ return response.status_code == 200
+
+
+def _wait_for_server(
+ config: ServietteConfig,
+ server: subprocess.Popen,
+ indexer: subprocess.Popen,
+ *,
+ should_stop=lambda: False,
+ ready=_server_ready,
+) -> int | None:
+ """Block until the server answers its health check; heartbeat meanwhile.
+
+ Returns the exit code of a child that died first (the caller aborts
+ with it), otherwise None once the server is ready. ``should_stop`` lets
+ a signal handler cut the wait short (returns None; the caller checks
+ the flag). ``ready`` is injectable for tests.
+ """
+
+ started = time.monotonic()
+ last_beat = 0.0
+ while not ready(config):
+ if should_stop():
+ return None
+ server_code = server.poll()
+ if server_code is not None:
+ return server_code
+ indexer_code = indexer.poll()
+ if indexer_code is not None and indexer_code != 0:
+ return indexer_code
+ now = time.monotonic()
+ if now - last_beat >= _WAIT_HEARTBEAT:
+ last_beat = now
+ logger.info(
+ "up: server starting — loading the query embedder; the URL "
+ "appears once it answers (%.0fs elapsed)",
+ now - started,
+ )
+ time.sleep(0.5)
+ return None
+
+
+def run(config: ServietteConfig, config_path: str, *, verbose: bool = False) -> int:
+ """Supervise the two children; returns the exit code for the CLI.
+
+ ``verbose`` passes the children's full output through; by default the
+ engine's routine INFO lines are hidden so that ``up``'s own progress and
+ the URL to open stay visible (they are still kept for a failure report).
+ """
+
+ config.for_indexer()
+ config.for_server()
+ # The readiness probe goes through httpx, which logs every request at
+ # INFO — that would print one line per health poll (here rather than in
+ # ``main`` so that ``serviette demo``, which calls ``run`` directly, is
+ # covered too).
+ logging.getLogger("httpx").setLevel(logging.WARNING)
+ # Fail fast on a mistyped source folder: otherwise the indexer watches
+ # nothing, the "empty folder" path below starts the server, and the user
+ # only sees "no relevant context" answers.
+ require_source_dirs(config)
+ # Fail before anything starts on a backend that cannot be shared by the
+ # two processes (Milvus Lite): started anyway, the indexer dies on the
+ # file lock our own readiness probe holds.
+ require_multi_process_backend(config)
+ # The indexer would die on the SDK's "Missing credentials" traceback
+ # seconds after "indexing in progress", the server on its first request.
+ require_openai_credentials(config, roles=("embedder", "llm"))
+ _warn_duckdb_streaming(config)
+
+ indexer = _spawn(
+ "indexer", config_path, env=_confirm_fingerprint(config), verbose=verbose
+ )
+ logger.info("up: indexer started (pid %d)", indexer.pid)
+ if not verbose:
+ logger.info(
+ "up: showing progress, warnings and errors only — run with "
+ "--verbose for the full indexer and server log"
+ )
+
+ shutdown_requested = False
+
+ def _on_signal(signum, _frame):
+ nonlocal shutdown_requested
+ shutdown_requested = True
+
+ previous = {
+ sig: signal.signal(sig, _on_signal) for sig in (signal.SIGINT, signal.SIGTERM)
+ }
+
+ server: subprocess.Popen | None = None
+ try:
+ # The chat page must never open onto a guaranteed "index not ready"
+ # error: hold the server back until the store answers a probe.
+ failed = _wait_for_index(
+ config, indexer, should_stop=lambda: shutdown_requested
+ )
+ if failed is not None:
+ _report_exit("indexer", failed, indexer)
+ return failed
+ if shutdown_requested:
+ logger.info("up: shutting down")
+ return 0
+
+ server = _spawn("server", config_path, verbose=verbose)
+ logger.info("up: index is ready — starting the server (pid %d)", server.pid)
+ # The port is not listening until the server's warm-up finishes;
+ # announcing the URL before that sends the user to a "connection
+ # refused" page.
+ failed = _wait_for_server(
+ config, server, indexer, should_stop=lambda: shutdown_requested
+ )
+ if failed is not None:
+ if server.poll() is not None:
+ _report_exit("server", failed, server)
+ else:
+ _report_exit("indexer", failed, indexer)
+ return failed
+ if shutdown_requested:
+ logger.info("up: shutting down")
+ return 0
+ logger.info(
+ "\n\n Ready — open %s\n (Ctrl-C stops the indexer and the server)\n",
+ _server_url(config),
+ )
+ static_done_logged = False
+ while True:
+ if shutdown_requested:
+ logger.info("up: shutting down")
+ return 0
+
+ server_code = server.poll()
+ if server_code is not None:
+ _report_exit("server", server_code, server)
+ return server_code
+
+ indexer_code = indexer.poll()
+ if indexer_code is not None and indexer_code != 0:
+ _report_exit("indexer", indexer_code, indexer)
+ return indexer_code
+ if indexer_code == 0 and not static_done_logged:
+ # Static sources: one-shot indexing done; keep serving.
+ logger.info("up: indexing finished; server keeps running")
+ static_done_logged = True
+
+ time.sleep(_POLL_INTERVAL)
+ finally:
+ _terminate(indexer, "indexer")
+ if server is not None:
+ _terminate(server, "server")
+ for sig, handler in previous.items():
+ signal.signal(sig, handler)
+
+
+def main(argv: list[str]) -> None:
+ import argparse
+
+ from serviette.config.schema import load_config
+
+ parser = argparse.ArgumentParser(prog="serviette up", description=__doc__)
+ parser.add_argument("--config", required=True)
+ parser.add_argument(
+ "--verbose",
+ action="store_true",
+ help="pass the indexer's and the server's full output through "
+ "(by default routine INFO lines are hidden)",
+ )
+ args = parser.parse_args(argv)
+
+ logging.basicConfig(level=logging.INFO, format="%(levelname)s %(message)s")
+ sys.exit(run(load_config(args.config), args.config, verbose=args.verbose))
diff --git a/serviette/wizard.py b/serviette/wizard.py
new file mode 100644
index 00000000..82e95cb8
--- /dev/null
+++ b/serviette/wizard.py
@@ -0,0 +1,829 @@
+"""Interactive terminal wizard: ``serviette wizard``.
+
+Generates a serviette YAML config by asking a short series of questions. In a real
+terminal, multiple-choice questions are navigated with the **arrow keys** (↑/↓ to
+move, Enter to select) and text questions come with their default **pre-filled
+and editable** — press Enter to accept, or edit in place. When stdin is not a TTY
+(tests, pipes), it falls back to numbered/typed input with the same semantics.
+
+Document sources are collected in a **loop**: the first source is required, then
+you may keep adding more (filesystem today; S3 / SharePoint / Google Drive are
+planned and slot into ``SOURCE_TYPES`` + :meth:`Wizard._collect_source` without
+touching the rest of the flow).
+
+The config-building logic (:func:`build_config`) is kept pure and separate from
+the I/O so it can be unit-tested without a terminal.
+"""
+
+from __future__ import annotations
+
+import argparse
+import importlib.util
+import os
+import sys
+from abc import ABC, abstractmethod
+from collections.abc import Callable
+from pathlib import Path
+from typing import Any
+
+import yaml
+
+from serviette import APP_NAME
+
+# Embedder families supported by pathway.xpacks.llm.embedders.
+# The default requires no API key at all (fully local).
+EMBEDDER_CHOICES = ["sentence_transformer", "openai", "litellm", "gemini", "bedrock"]
+EMBEDDER_LABELS = [
+ "sentence_transformer (local \u00b7 no API key needed)",
+ "openai",
+ "litellm",
+ "gemini",
+ "bedrock",
+]
+
+# Document source types offered by the wizard. Only sources with an
+# only_metadata read mode are supported.
+SOURCE_TYPES: list[tuple[str, str]] = [
+ ("fs", "Filesystem (local directory)"),
+ ("gdrive", "Google Drive"),
+ ("s3", "S3 / MinIO / S3-compatible bucket"),
+ ("sharepoint", "Microsoft SharePoint"),
+ ("pyfilesystem", "FTP / SFTP / WebDAV / ZIP (PyFilesystem URL)"),
+]
+
+# Default environment-variable references per provider, so generated configs
+# never hardcode a credential (the "no hardcoded credentials" principle).
+_ENV_REF = {
+ "openai": "${OPENAI_API_KEY}",
+ "litellm": "${OPENAI_API_KEY}",
+ "gemini": "${GEMINI_API_KEY}",
+ "bedrock": None,
+ "sentence_transformer": None,
+}
+
+# Embedders whose Python package is an optional extra: (module to probe,
+# install command). The others ride on packages the base install has.
+_EMBEDDER_PACKAGE = {
+ "sentence_transformer": (
+ "sentence_transformers",
+ 'pip install "serviette[local]" --extra-index-url https://download.pytorch.org/whl/cpu',
+ ),
+ "gemini": ("google.generativeai", 'pip install "serviette[gemini]"'),
+ "bedrock": ("boto3", 'pip install "serviette[bedrock]"'),
+}
+
+
+def _installed(module: str) -> bool:
+ return importlib.util.find_spec(module) is not None
+
+
+# Local (sentence-transformers) models the wizard offers, with what a user
+# needs to pick one: languages, speed, vector size. ``prefixes`` are the
+# query/passage markers a model was trained with (E5 family); the wizard
+# writes them into the config so both sides apply them. The last entry lets
+# the user type any Hugging Face model id.
+LOCAL_MODELS: list[tuple[str | None, str, dict[str, str]]] = [
+ (
+ "sentence-transformers/all-MiniLM-L6-v2",
+ (
+ "all-MiniLM-L6-v2 — English only · smallest and fastest · 384-dim "
+ "(reads the first 256 tokens of each chunk)"
+ ),
+ {},
+ ),
+ (
+ "intfloat/multilingual-e5-small",
+ (
+ "multilingual-e5-small — ~100 languages (French, German, Spanish, Polish, "
+ "Russian, Chinese, …) · same speed class · 384-dim · pick this for "
+ "non-English or mixed documents"
+ ),
+ {"query_prefix": "query: ", "document_prefix": "passage: "},
+ ),
+ (
+ "BAAI/bge-m3",
+ (
+ "bge-m3 — 100+ languages · highest quality, long chunks (8k tokens) · "
+ "1024-dim · ~2.3 GB download, several times slower on CPU"
+ ),
+ {},
+ ),
+ (None, "Other — type a Hugging Face model id", {}),
+]
+LOCAL_MODEL_LABELS = [label for _, label, _ in LOCAL_MODELS]
+
+
+# Simple, brand-neutral defaults suggested by the wizard.
+DEFAULT_COLLECTION = "embeddings"
+
+
+# ---------------------------------------------------------------------------
+# Pure config builder (no I/O)
+# ---------------------------------------------------------------------------
+
+
+def _duckdb_table_exists(path: str, table: str) -> bool:
+ try:
+ import duckdb
+
+ conn = duckdb.connect(path, read_only=True)
+ try:
+ tables = {row[0] for row in conn.execute("SHOW TABLES").fetchall()}
+ finally:
+ conn.close()
+ return table in tables
+ except Exception: # noqa: BLE001 - unreadable file: let the indexer report
+ return False
+
+
+def build_config(answers: dict[str, Any]) -> dict[str, Any]:
+ """Assemble a config dict from collected ``answers``.
+
+ Only the sections relevant to ``answers['config_type']`` are emitted.
+ ``answers['sources']`` is a list of fully-formed source dicts (one per source
+ the user added in the loop).
+ """
+
+ config_type = answers["config_type"]
+ needs_indexer = config_type in {"universal", "indexer"}
+ needs_server = config_type in {"universal", "server"}
+
+ config: dict[str, Any] = {"pathway_license_key": answers["license_key"]}
+
+ if needs_indexer:
+ config["sources"] = answers["sources"]
+
+ config["vector_db"] = _vector_db_section(answers)
+ config["embedder"] = _embedder_section(answers)
+
+ if needs_indexer:
+ config["splitter"] = {
+ "type": "token_count",
+ "chunk_size": answers.get("chunk_size", 512),
+ "chunk_overlap": answers.get("chunk_overlap", 50),
+ }
+ # The working directory (./serviette-workdir) and persistence (on)
+ # are silent defaults: neither is emitted and the wizard does not
+ # ask — advanced users set `workdir_path` / `persistence:` by hand.
+
+ if needs_server:
+ config["server"] = {
+ "host": answers.get("server_host", "127.0.0.1"),
+ "port": answers.get("server_port", 8989),
+ }
+ # /rag (and the web chat) is always on; ``llm`` only picks what
+ # answers. ``mock`` needs no key and quotes the best snippet verbatim.
+ config["llm"] = _llm_section(answers)
+
+ return config
+
+
+def _vector_db_section(answers: dict[str, Any]) -> dict[str, Any]:
+ vdb_type = answers["vector_db_type"]
+ collection = answers.get("collection", DEFAULT_COLLECTION)
+ if vdb_type == "duckdb":
+ return {
+ "type": "duckdb",
+ "path": answers["duckdb_path"],
+ "table": collection,
+ }
+ if vdb_type == "milvus":
+ section: dict[str, Any] = {"type": "milvus", "collection": collection}
+ if answers.get("milvus_uri"):
+ section["uri"] = answers["milvus_uri"]
+ else:
+ section["host"] = answers.get("milvus_host", "localhost")
+ section["port"] = answers.get("milvus_port", 19530)
+ return section
+ if vdb_type == "qdrant":
+ section = {
+ "type": "qdrant",
+ "host": answers.get("qdrant_host", "localhost"),
+ "collection": collection,
+ }
+ if answers.get("qdrant_api_key"):
+ section["api_key"] = answers["qdrant_api_key"]
+ return section
+ if vdb_type == "chroma":
+ return {
+ "type": "chroma",
+ "host": answers.get("chroma_host", "localhost"),
+ "port": answers.get("chroma_port", 8000),
+ "collection": collection,
+ }
+ if vdb_type == "weaviate":
+ section = {
+ "type": "weaviate",
+ "http_host": answers.get("weaviate_host", "localhost"),
+ "http_port": answers.get("weaviate_port", 8080),
+ "collection": answers.get("weaviate_collection", "ServietteEmbeddings"),
+ }
+ if answers.get("weaviate_api_key"):
+ section["api_key"] = answers["weaviate_api_key"]
+ return section
+ if vdb_type == "pinecone":
+ return {
+ "type": "pinecone",
+ "index_name": answers["pinecone_index"],
+ "api_key": answers.get("pinecone_api_key", "${PINECONE_API_KEY}"),
+ }
+ if vdb_type == "mongodb":
+ return {
+ "type": "mongodb",
+ "connection_string": answers["mongodb_connection_string"],
+ "database": answers["mongodb_database"],
+ "collection": collection,
+ }
+ return {
+ "type": "pgvector",
+ "connection_string": answers["pg_connection_string"],
+ "table": collection,
+ }
+
+
+def _embedder_section(answers: dict[str, Any]) -> dict[str, Any]:
+ etype = answers["embedder_type"]
+ section: dict[str, Any] = {"type": etype}
+ if answers.get("embedder_model"):
+ section["model"] = answers["embedder_model"]
+ section.update(answers.get("embedder_prefixes") or {})
+ api_key = answers.get("embedder_api_key", _ENV_REF.get(etype))
+ if api_key:
+ section["api_key"] = api_key
+ return section
+
+
+def _llm_section(answers: dict[str, Any]) -> dict[str, Any]:
+ llm_type = answers.get("llm_type", "mock")
+ section: dict[str, Any] = {"type": llm_type}
+ if llm_type == "mock":
+ return section
+ if answers.get("llm_model"):
+ section["model"] = answers["llm_model"]
+ api_key = answers.get("llm_api_key", _ENV_REF.get(llm_type))
+ if api_key:
+ section["api_key"] = api_key
+ return section
+
+
+def dump_yaml(config: dict[str, Any]) -> str:
+ header = f"# {APP_NAME} config — generated by `{APP_NAME} wizard`\n"
+ return header + yaml.safe_dump(config, sort_keys=False, default_flow_style=False)
+
+
+# ---------------------------------------------------------------------------
+# Prompters: arrow-key interactive vs. scripted (tests / non-TTY)
+# ---------------------------------------------------------------------------
+
+
+class Prompter(ABC):
+ """Abstracts the three primitives the wizard needs."""
+
+ def info(self, message: str) -> None:
+ print(message)
+
+ @abstractmethod
+ def select(self, prompt: str, options: list[str], default_index: int = 0) -> int:
+ """Return the index of the chosen option."""
+
+ @abstractmethod
+ def text(self, prompt: str, default: str | None = None, *, required: bool = False) -> str:
+ """Return a (possibly default/pre-filled) text value."""
+
+ def confirm(self, prompt: str, default: bool = True) -> bool:
+ idx = self.select(prompt, ["Yes", "No"], default_index=0 if default else 1)
+ return idx == 0
+
+
+class ScriptedPrompter(Prompter):
+ """Numbered/typed prompts driven by injectable I/O (tests, non-TTY)."""
+
+ def __init__(
+ self,
+ input_fn: Callable[[str], str] = input,
+ output_fn: Callable[[str], None] = print,
+ ) -> None:
+ self._input = input_fn
+ self._output = output_fn
+
+ def info(self, message: str) -> None:
+ self._output(message)
+
+ def select(self, prompt: str, options: list[str], default_index: int = 0) -> int:
+ self._output(prompt)
+ for i, opt in enumerate(options, start=1):
+ marker = " (default)" if i - 1 == default_index else ""
+ self._output(f" [{i}] {opt}{marker}")
+ while True:
+ raw = self._input(f" Enter number [1-{len(options)}] [{default_index + 1}]: ").strip()
+ if not raw:
+ return default_index
+ if raw.isdigit() and 1 <= int(raw) <= len(options):
+ return int(raw) - 1
+ self._output(" Invalid choice.")
+
+ def text(self, prompt: str, default: str | None = None, *, required: bool = False) -> str:
+ suffix = f" [{default}]" if default else ""
+ while True:
+ raw = self._input(f" {prompt}{suffix}: ").strip()
+ if raw:
+ return raw
+ if default is not None and not required:
+ return default
+ if default:
+ return default
+ self._output(" This field is required.")
+
+
+class InteractivePrompter(Prompter):
+ """Arrow-key menus and pre-filled editable text for a real terminal."""
+
+ # -- low-level key reading ------------------------------------------------
+
+ @staticmethod
+ def _read_key() -> str:
+ import termios
+ import tty
+
+ fd = sys.stdin.fileno()
+ old = termios.tcgetattr(fd)
+ try:
+ tty.setraw(fd)
+ ch = sys.stdin.read(1)
+ if ch == "\x03": # Ctrl-C
+ raise KeyboardInterrupt
+ if ch == "\x04": # Ctrl-D
+ raise EOFError
+ if ch in ("\r", "\n"):
+ return "enter"
+ if ch == "\x1b": # escape sequence (arrow keys)
+ seq = sys.stdin.read(2)
+ return {"[A": "up", "[B": "down", "[C": "right", "[D": "left"}.get(seq, "esc")
+ return ch
+ finally:
+ termios.tcsetattr(fd, termios.TCSADRAIN, old)
+
+ def select(self, prompt: str, options: list[str], default_index: int = 0) -> int:
+ print(prompt)
+ print(" (use ↑/↓ arrows, Enter to select)")
+ active = default_index
+ # Initial render.
+ for i, opt in enumerate(options):
+ print(self._render_option(opt, i == active))
+ while True:
+ key = self._read_key()
+ if key == "up":
+ active = (active - 1) % len(options)
+ elif key == "down":
+ active = (active + 1) % len(options)
+ elif key.isdigit() and 1 <= int(key) <= len(options):
+ active = int(key) - 1
+ elif key == "enter":
+ # Leave the menu rendered with the final selection.
+ return active
+ else:
+ continue
+ # Re-render: move cursor up over the option lines and rewrite.
+ sys.stdout.write(f"\x1b[{len(options)}A")
+ for i, opt in enumerate(options):
+ sys.stdout.write("\x1b[2K" + self._render_option(opt, i == active) + "\n")
+ sys.stdout.flush()
+
+ @staticmethod
+ def _render_option(label: str, active: bool) -> str:
+ if active:
+ return f" \x1b[7m › {label} \x1b[0m" # reverse video
+ return f" {label}"
+
+ def text(self, prompt: str, default: str | None = None, *, required: bool = False) -> str:
+ import readline
+
+ prefill = default or ""
+
+ def hook() -> None:
+ readline.insert_text(prefill)
+ readline.redisplay()
+
+ while True:
+ readline.set_pre_input_hook(hook)
+ try:
+ value = input(f" {prompt}: ").strip()
+ finally:
+ readline.set_pre_input_hook()
+ if value:
+ return value
+ if not required and default is not None:
+ return default
+ print(" This field is required.")
+
+
+def _default_prompter() -> Prompter:
+ if sys.stdin.isatty() and sys.stdout.isatty():
+ return InteractivePrompter()
+ return ScriptedPrompter()
+
+
+# ---------------------------------------------------------------------------
+# The wizard flow
+# ---------------------------------------------------------------------------
+
+
+class Wizard:
+ def __init__(
+ self,
+ prompter: Prompter | None = None,
+ *,
+ input_fn: Callable[[str], str] | None = None,
+ output_fn: Callable[[str], None] | None = None,
+ ) -> None:
+ if prompter is not None:
+ self.p = prompter
+ elif input_fn is not None or output_fn is not None:
+ self.p = ScriptedPrompter(input_fn or input, output_fn or print)
+ else:
+ self.p = _default_prompter()
+ self._step = 0
+
+ def _section(self, title: str) -> None:
+ self._step += 1
+ self.p.info(f"\nStep {self._step}: {title}")
+
+ # -- sources loop --------------------------------------------------------
+
+ def _collect_sources(self) -> list[dict[str, Any]]:
+ sources: list[dict[str, Any]] = []
+ while True:
+ first = not sources
+ labels = [label for _, label in SOURCE_TYPES]
+ done_index = -1 # sentinel: no "done" option on the first pick
+ if not first:
+ done_index = len(labels)
+ labels = labels + ["Done — no more sources"]
+ prompt = "Add a document source:" if first else "Add another source?"
+ idx = self.p.select(prompt, labels, default_index=0 if first else done_index)
+ if done_index != -1 and idx == done_index:
+ break
+ stype = SOURCE_TYPES[idx][0]
+ sources.append(self._collect_source(stype))
+ return sources
+
+ def _resolve_missing_dir(self, path: str) -> bool:
+ """Ask what to do about a folder that does not exist; True keeps
+ ``path`` (created or as typed), False means ask for another path."""
+
+ while True:
+ choice = self.p.select(
+ "What now?",
+ [
+ "Create it now (empty; drop documents in later)",
+ "Enter a different path",
+ "Keep it as typed (I will create it before running the indexer)",
+ ],
+ default_index=0,
+ )
+ if choice == 1:
+ return False
+ if choice == 2:
+ return True
+ try:
+ Path(path).mkdir(parents=True)
+ except OSError as exc:
+ self.p.info(f" Could not create {path!r}: {exc}")
+ continue # back to the question
+ self.p.info(f" Created {path!r}.")
+ return True
+
+ def _embedder_available(self, etype: str) -> bool:
+ """Warn when the chosen embedder's package is not installed; True
+ keeps the choice, False means pick another embedder.
+
+ Without this the wizard finishes fine and the missing package only
+ surfaces as a ModuleNotFoundError deep in the indexer at ``serviette
+ up`` — a plain ``pip install serviette`` (the README's first command)
+ has no sentence-transformers, yet that is the wizard's default."""
+
+ probe = _EMBEDDER_PACKAGE.get(etype)
+ if probe is None or _installed(probe[0]):
+ return True
+ module, command = probe
+ self.p.info(
+ f" ! {etype} needs the {module.split('.')[0]} package, which is not installed "
+ f"in this Python environment. Install it before running the stack:\n"
+ f" {command}"
+ )
+ choice = self.p.select(
+ "What now?",
+ [
+ "Keep it (I will install the package before `serviette up`)",
+ "Choose another embedder",
+ ],
+ default_index=0,
+ )
+ return choice == 0
+
+ def _collect_source(self, stype: str) -> dict[str, Any]:
+ if stype == "fs":
+ while True:
+ path = os.path.expanduser(self.p.text("Directory path", required=True))
+ if Path(path).is_dir():
+ break
+ # The indexer refuses to start on a missing folder. Say so
+ # plainly while the user is still at the keyboard, and offer
+ # to create it: for a fresh setup the folder usually does not
+ # exist yet, for a typo the question is the chance to notice.
+ self.p.info(f" ! Directory {path!r} does not exist.")
+ if self._resolve_missing_dir(path):
+ break
+ # glob is an advanced setting: default emitted into the YAML,
+ # edit it there.
+ return {"type": "fs", "path": path, "glob": "**/*"}
+ if stype == "gdrive":
+ object_id = self.p.text("Google Drive folder/file id", required=True)
+ creds = self.p.text(
+ "Service-account credentials JSON file", default="./credentials.json"
+ )
+ pattern = self.p.text("File name pattern (e.g. *.pdf, blank = all)", default="")
+ source: dict[str, Any] = {
+ "type": "gdrive",
+ "object_id": object_id,
+ "service_user_credentials_file": creds,
+ }
+ if pattern:
+ source["file_name_pattern"] = pattern
+ return source
+ if stype == "s3":
+ bucket = self.p.text("Bucket name", required=True)
+ prefix = self.p.text("Key prefix to index (blank = whole bucket)", default="")
+ endpoint = self.p.text(
+ "Custom endpoint (blank for AWS; e.g. http://localhost:9000 for MinIO)",
+ default="",
+ )
+ source = {
+ "type": "s3",
+ "bucket": bucket,
+ "path": prefix,
+ "access_key": "${AWS_ACCESS_KEY_ID}",
+ "secret_access_key": "${AWS_SECRET_ACCESS_KEY}",
+ }
+ if endpoint:
+ source["endpoint"] = endpoint
+ source["with_path_style"] = True # the norm for self-hosted S3
+ # Required with a custom endpoint (signature scope).
+ source["region"] = self.p.text("Region", default="us-east-1")
+ return source
+ if stype == "sharepoint":
+ return {
+ "type": "sharepoint",
+ "url": self.p.text(
+ "Site URL (https://company.sharepoint.com/sites/MySite)", required=True
+ ),
+ "tenant": self.p.text("Tenant id (GUID)", required=True),
+ "client_id": self.p.text("Client id of the app registration", required=True),
+ "cert_path": self.p.text("Certificate .pem path", default="./sharepoint.pem"),
+ "thumbprint": self.p.text("Certificate thumbprint", required=True),
+ "root_path": self.p.text("Root path to index (e.g. Shared Documents)", required=True),
+ }
+ if stype == "pyfilesystem":
+ return {
+ "type": "pyfilesystem",
+ "fs_url": self.p.text(
+ 'Filesystem URL (e.g. "ftp://user:pass@host/dir", "zip://./docs.zip")',
+ required=True,
+ ),
+ "path": self.p.text("Path inside it to index", default=""),
+ }
+ raise ValueError(f"Unsupported source type: {stype!r}") # pragma: no cover
+
+ # -- the full flow -------------------------------------------------------
+
+ def run(self) -> dict[str, Any]:
+ answers: dict[str, Any] = {}
+
+ self._section("What to generate?")
+ type_idx = self.p.select(
+ "Config type:",
+ ["Universal config", "Indexer config only", "Server config only"],
+ default_index=0,
+ )
+ config_type = ["universal", "indexer", "server"][type_idx]
+ answers["config_type"] = config_type
+ needs_indexer = config_type in {"universal", "indexer"}
+ needs_server = config_type in {"universal", "server"}
+
+ if needs_indexer:
+ self._section("Document sources")
+ answers["sources"] = self._collect_sources()
+
+ self._section("Vector database")
+ vdb_values = [
+ "duckdb",
+ "pgvector",
+ "qdrant",
+ "milvus",
+ "chroma",
+ "weaviate",
+ "pinecone",
+ "mongodb",
+ ]
+ vdb_labels = [
+ "duckdb (local file · zero setup · in-database vector search)",
+ "pgvector (Postgres)",
+ "qdrant",
+ "milvus",
+ "chroma",
+ "weaviate",
+ "pinecone",
+ "mongodb (Atlas Vector Search)",
+ ]
+ vdb_idx = self.p.select("Vector database:", vdb_labels, default_index=0)
+ answers["vector_db_type"] = vdb_values[vdb_idx]
+
+ vdb_type = answers["vector_db_type"]
+ if vdb_type == "duckdb":
+ # Zero-question happy path: defaults are used silently; the user
+ # is only consulted when a file/table already exists, so nothing
+ # gets overwritten by accident.
+ path = "./embeddings.duckdb"
+ if Path(path).exists():
+ self._section("Vector DB connection")
+ path = self.p.text(
+ f"DuckDB file {path} already exists; path to use", default=path
+ )
+ answers["duckdb_path"] = path
+ answers["collection"] = DEFAULT_COLLECTION
+ if Path(path).exists() and _duckdb_table_exists(path, DEFAULT_COLLECTION):
+ answers["collection"] = self.p.text(
+ f"Table {DEFAULT_COLLECTION!r} already exists in {path}; table to use",
+ default=DEFAULT_COLLECTION,
+ )
+ elif vdb_type == "milvus":
+ self._section("Vector DB connection")
+ uri = self.p.text("Milvus URI (leave blank to use host + port)", default="")
+ answers["milvus_uri"] = uri or None
+ if not answers["milvus_uri"]:
+ answers["milvus_host"] = self.p.text("Milvus host", default="localhost")
+ answers["milvus_port"] = int(self.p.text("Milvus port", default="19530"))
+ elif vdb_type == "qdrant":
+ self._section("Vector DB connection")
+ answers["qdrant_host"] = self.p.text("Qdrant host", default="localhost")
+ answers["qdrant_api_key"] = self.p.text(
+ "Qdrant API key (blank for none)", default=""
+ ) or None
+ elif vdb_type == "chroma":
+ self._section("Vector DB connection")
+ answers["chroma_host"] = self.p.text("Chroma host", default="localhost")
+ answers["chroma_port"] = int(self.p.text("Chroma port", default="8000"))
+ elif vdb_type == "weaviate":
+ self._section("Vector DB connection")
+ answers["weaviate_host"] = self.p.text("Weaviate host", default="localhost")
+ answers["weaviate_port"] = int(self.p.text("Weaviate HTTP port", default="8080"))
+ answers["weaviate_collection"] = self.p.text(
+ "Weaviate collection (capitalized)", default="ServietteEmbeddings"
+ )
+ answers["weaviate_api_key"] = self.p.text(
+ "Weaviate API key (blank for none)", default=""
+ ) or None
+ elif vdb_type == "pinecone":
+ self._section("Vector DB connection")
+ answers["pinecone_index"] = self.p.text("Pinecone index name", required=True)
+ answers["pinecone_api_key"] = self.p.text(
+ "Pinecone API key", default="${PINECONE_API_KEY}"
+ )
+ elif vdb_type == "mongodb":
+ self._section("Vector DB connection")
+ answers["mongodb_connection_string"] = self.p.text(
+ "MongoDB connection string (mongodb+srv://... for Atlas)", required=True
+ )
+ answers["mongodb_database"] = self.p.text("Database name", required=True)
+ else:
+ self._section("Vector DB connection")
+ answers["pg_connection_string"] = self.p.text(
+ "Postgres connection string (postgresql://user:pass@host/db)", required=True
+ )
+
+ if vdb_type not in {"pinecone", "weaviate", "duckdb"}: # handled above
+ self._section("Collection / table name")
+ answers["collection"] = self.p.text(
+ "Collection / table name", default=DEFAULT_COLLECTION
+ )
+
+ self._section("Embedder")
+ emb_idx = self.p.select("Embedder:", EMBEDDER_LABELS, default_index=0)
+ while not self._embedder_available(EMBEDDER_CHOICES[emb_idx]):
+ emb_idx = self.p.select("Embedder:", EMBEDDER_LABELS, default_index=emb_idx)
+ answers["embedder_type"] = EMBEDDER_CHOICES[emb_idx]
+
+ # 9) The local embedder needs no key, but the model decides which
+ # languages work: the default is English-only, and a French corpus
+ # with it looks like "the context does not contain the information".
+ if answers["embedder_type"] == "sentence_transformer":
+ self._section("Embedding model")
+ model_idx = self.p.select("Embedding model:", LOCAL_MODEL_LABELS, default_index=0)
+ model, _label, prefixes = LOCAL_MODELS[model_idx]
+ if model is None:
+ model = self.p.text("Hugging Face model id", required=True)
+ answers["embedder_model"] = model
+ answers["embedder_prefixes"] = prefixes
+ env_ref = _ENV_REF.get(answers["embedder_type"])
+ if env_ref is not None:
+ self._section("Embedder model + API key")
+ if answers["embedder_type"] == "litellm":
+ # LiteLLM has no default model; the provider prefix is what
+ # routes the call, so a blank answer would fail on both sides.
+ answers["embedder_model"] = self.p.text(
+ "Embedder model (provider/model, e.g. openrouter/qwen/qwen3-embedding-8b)",
+ default="",
+ required=True,
+ )
+ else:
+ answers["embedder_model"] = self.p.text("Embedder model (blank for default)", default="") or None
+ answers["embedder_api_key"] = self.p.text("API key", default=env_ref)
+
+ # Splitter is not asked about: defaults are emitted into the YAML
+ # for the user to tune there; workdir/persistence stay implicit.
+
+ if needs_server:
+ # Host/port are silent defaults (127.0.0.1:8989 — loopback + uncommon port, no
+ # tool conflicts); emitted into the YAML for later tuning.
+ self._section("Chat answers")
+ self.p.info(
+ " The /rag endpoint and the web chat are always available. This picks\n"
+ " the LLM that turns the retrieved snippets into an answer:\n"
+ " mock - no LLM and no API key. The chat replies with the best\n"
+ " matching snippet quoted verbatim: good for checking what\n"
+ " gets retrieved, but the answers are not natural language.\n"
+ " openai - real generated answers from the OpenAI API (needs\n"
+ " OPENAI_API_KEY).\n"
+ " litellm - any provider LiteLLM supports (needs that provider's key)."
+ )
+ llm_types = ["mock", "openai", "litellm"]
+ llm_idx = self.p.select(
+ "LLM for chat answers:",
+ ["mock (no LLM: quote the best snippet)", "openai", "litellm"],
+ default_index=0,
+ )
+ answers["llm_type"] = llm_types[llm_idx]
+ if answers["llm_type"] != "mock":
+ answers["llm_model"] = self.p.text("LLM model", default="gpt-4o-mini")
+ answers["llm_api_key"] = self.p.text(
+ "LLM API key", default=_ENV_REF.get(answers["llm_type"], "${OPENAI_API_KEY}")
+ )
+
+ self._section("Pathway License Key")
+ self.p.info(
+ " Pathway requires a free license key. Get yours in one click at "
+ "https://pathway.com/framework/get-license (email or LinkedIn sign-in)."
+ )
+ if os.environ.get("PATHWAY_LICENSE_KEY"):
+ # Already exported: reference the variable rather than copying
+ # the secret into the file (the way the LLM API key is handled).
+ self.p.info(
+ " PATHWAY_LICENSE_KEY is set in your environment — press Enter to "
+ "reference it from the config, or paste a key to store it instead."
+ )
+ answers["license_key"] = self.p.text(
+ "Pathway license key", default="${PATHWAY_LICENSE_KEY}"
+ )
+ else:
+ answers["license_key"] = self.p.text(
+ "Paste your Pathway license key", required=True
+ )
+
+ self._section("Output file path")
+ answers["output_path"] = self.p.text("Output file path", default="./config.yaml")
+
+ return answers
+
+
+# ---------------------------------------------------------------------------
+# Entrypoint
+# ---------------------------------------------------------------------------
+
+
+def main(argv: list[str] | None = None) -> None:
+ parser = argparse.ArgumentParser(
+ prog=f"{APP_NAME} wizard", description="Interactively generate a YAML config."
+ )
+ parser.parse_args(argv)
+ wizard = Wizard()
+ try:
+ answers = wizard.run()
+ except (KeyboardInterrupt, EOFError):
+ print("\nAborted.")
+ sys.exit(1)
+
+ config = build_config(answers)
+ output_path = answers["output_path"]
+ with open(output_path, "w", encoding="utf-8") as fh:
+ fh.write(dump_yaml(config))
+ print(f"\nWrote {answers['config_type']} config to {output_path}")
+ print(
+ "Advanced settings (file glob patterns, chunking/splitter, "
+ "persistence, backpressure, table names) can be tuned by editing "
+ f"{output_path}."
+ )
+ print(f"Run it with: {APP_NAME} up --config {output_path}")
+
+
+if __name__ == "__main__":
+ main()
diff --git a/setup.cfg b/setup.cfg
deleted file mode 100644
index 88fa474d..00000000
--- a/setup.cfg
+++ /dev/null
@@ -1,9 +0,0 @@
-[flake8]
-exclude =
- .git
-
-max-line-length = 119
-docstring-convention = google
-extend-ignore =
- # Black (https://black.readthedocs.io/en/stable/guides/using_black_with_other_tools.html#flake8)
- E203, E701
diff --git a/templates/adaptive_rag/.env.example b/templates/adaptive_rag/.env.example
deleted file mode 100644
index b82e13a2..00000000
--- a/templates/adaptive_rag/.env.example
+++ /dev/null
@@ -1 +0,0 @@
-OPENAI_API_KEY="sk-***"
diff --git a/templates/adaptive_rag/Dockerfile b/templates/adaptive_rag/Dockerfile
deleted file mode 100644
index 2e2ca8a6..00000000
--- a/templates/adaptive_rag/Dockerfile
+++ /dev/null
@@ -1,16 +0,0 @@
-FROM pathwaycom/pathway:latest
-
-WORKDIR /app
-
-RUN apt-get update \
- && apt-get install -y python3-opencv tesseract-ocr-eng \
- && rm -rf /var/lib/apt/lists/* /var/cache/apt/archives/*
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-EXPOSE 8000
-
-CMD ["python", "app.py"]
diff --git a/templates/adaptive_rag/README.md b/templates/adaptive_rag/README.md
deleted file mode 100644
index 9090a741..00000000
--- a/templates/adaptive_rag/README.md
+++ /dev/null
@@ -1,168 +0,0 @@
-
-
-
-# End to end Adaptive RAG with Pathway Live Data Framework
-
-This is the accompanying code for deploying the `adaptive RAG` technique with Pathway. To understand the technique and learn how it can save tokens without sacrificing accuracy, read [our showcase](https://pathway.com/developers/templates/rag/adaptive-rag).
-
-To learn more about building & deploying RAG applications with Pathway Live Data Framework, including containerization, refer to [demo question answering](../question_answering_rag/README.md).
-
-## Introduction
-This app relies on modules provided under `pathway.xpacks.llm`.
-
-`BaseRAGQuestionAnswerer` is the base class to build RAG applications with Pathway Live Data Framework vector store and Pathway Live Data Framework xpack components.
-It is meant to get you started with your RAG application right away.
-
-Here, we extend the `BaseRAGQuestionAnswerer` to implement the adaptive retrieval and reply to requests in the endpoint `/v2/answer`.
-Since we are interested in changing the behavior and logic of the RAG, we only modify `answer` function that handles all this logic, and then replies to the post request.
-
-`answer` function takes the `pw_ai_queries` table as the input, this table contains the prompt, and other arguments coming from the post request, see the `BaseRAGQuestionAnswerer` class and defined schemas to learn more about getting inputs with post requests.
-We use the data in this table to call our adaptive retrieval logic.
-
-To do that, we use `answer_with_geometric_rag_strategy_from_index` implementation provided under the `pathway.xpacks.llm.question_answering`.
-This function takes an index, LLM, prompt and adaptive parameters such as the starting number of documents. Then, iteratively asks the question to the LLM with an increasing number of context documents retrieved from the index.
-
-We encourage you to check the implementation of `answer_with_geometric_rag_strategy_from_index`.
-
-## Customizing the pipeline
-
-The code can be modified by changing the `app.yaml` configuration file. To read more about YAML files used in Pathway templates, read [our guide](https://pathway.com/developers/templates/configure-yaml).
-
-In the `app.yaml` file we define:
-- input connectors
-- LLM
-- embedder
-- index
-and any of these can be replaced or, if no longer needed, removed. For components that can be used check
-Pathway [LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview), or you can implement your own.
-
-You can also check our other templates - [Question Answering RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag),
-[Multimodal RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/multimodal_rag) or
-[Private RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/private_rag). As all of these only differ
-in the YAML configuration file, you can also use them as an inspiration for your custom pipeline.
-
-Here some examples of what can be modified.
-
-### LLM Model
-
-You can choose any of the models offered by Open AI, like GPT-5, GPT-4.1, or GPT-4o.
-You can find the whole list on their [models page](https://platform.openai.com/docs/models).
-
-You simply need to change the `model` to the one you want to use, e.g., to use GPT-5:
-```yaml
-$llm: !pw.xpacks.llm.llms.OpenAIChat
- model: "gpt-5"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache
- capacity: 8
-```
-
-The default model is `gpt-4.1-mini`.
-
-You can also use different provider, by using different class from [Pathway Live Data Framework LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview),
-e.g. here is configuration for locally run Mistral model.
-
-```yaml
-$llm: !pw.xpacks.llm.llms.LiteLLMChat
- model: "ollama/mistral"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DiskCache
- temperature: 0
- top_p: 1
- api_base: "http://localhost:11434"
-```
-
-### Webserver
-
-You can configure the host and the port of the webserver.
-Here is the default configuration:
-```yaml
-host: "0.0.0.0"
-port: 8000
-```
-
-### Cache
-
-You can configure whether you want to enable cache or persistence, to avoid repeated API accesses, and where the cache is stored.
-Default values:
-```yaml
-persistence_mode: !pw.PersistenceMode.UDF_CACHING
-persistence_backend: !pw.persistence.Backend.filesystem
- path: ".Cache"
-```
-
-### Data sources
-
-You can configure the data sources by changing `$sources` in `app.yaml`.
-You can add as many data sources as you want. You can have several sources of the same kind, for instance, several local sources from different folders.
-The sections below describe how to configure local, Google Drive and Sharepoint source, and you can check the examples of YAML configuration in our [user guide](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples/). While these are not described in this Section, you can also use any input [connector](https://pathway.com/developers/user-guide/connecting-to-data/connectors) from Pathway package.
-
-By default, the app uses a local data source to read documents from the `data` folder.
-
-#### Local Data Source
-
-The local data source is configured by using map with tag `!pw.io.fs.read`. Then set `path` to denote the path to a folder with files to be indexed.
-
-#### Google Drive Data Source
-
-The Google Drive data source is enabled by using map with tag `!pw.io.gdrive.read`. The map must contain two main parameters:
-- `object_id`, containing the ID of the folder that needs to be indexed. It can be found from the URL in the web interface, where it's the last part of the address. For example, the publicly available demo folder in Google Drive has the URL `https://drive.google.com/drive/folders/1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`. Consequently, the last part of this address is `1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`, hence this is the `object_id` you would need to specify.
-- `service_user_credentials_file`, containing the path to the credentials files for the Google [service account](https://cloud.google.com/iam/docs/service-account-overview). To get more details on setting up the service account and getting credentials, you can also refer to [this tutorial](https://pathway.com/developers/user-guide/connectors/gdrive-connector#setting-up-google-drive).
-
-Besides, to speed up the indexing process you may want to specify the `refresh_interval` parameter, denoted by an integer number of seconds. It corresponds to the frequency between two sequential folder scans. If unset, it defaults to 30 seconds.
-
-For the full list of the available parameters, please refer to the Google Drive connector [documentation](https://pathway.com/developers/api-docs/pathway-io/gdrive#pathway.io.gdrive.read).
-
-#### SharePoint Data Source
-
-This data source requires Scale or Enterprise [license key](https://pathway.com/pricing) - you can obtain free Scale key on [Pathway website](https://pathway.com/get-license).
-
-To use it, set the map tag to be `!pw.xpacks.connectors.sharepoint.read`, and then provide values of `url`, `tenant`, `client_id`, `cert_path`, `thumbprint` and `root_path`. To read about the meaning of these arguments, check the Sharepoint connector [documentation](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read).
-
-## Running the app
-To run the app, depending on the configuration, you may need to set up environmntal variables with LLM provider keys. By default, this template uses OpenAI API, so to run it you need to set `OPENAI_API_KEY` environmental key or create an `.env` file in this directory with your key: `OPENAI_API_KEY=sk-...`. If you modify the code to use another LLM provider, you may need to set a relevant API key.
-
-### With Docker
-In order to let the pipeline get updated with each change in local files, you need to mount the folder onto the docker. The following commands show how to do that.
-
-```bash
-# Build the image in this folder
-docker build -t adaptiverag .
-
-# Run the image, mount the `data` folder into image
-# -e is used to pass value of OPENAI_API_KEY environmental variable
-docker run -v ./data:/app/data -e OPENAI_API_KEY -p 8000:8000 adaptiverag
-```
-
-### Locally
-To run locally you need to install the Pathway Live Data Framework app with LLM dependencies using:
-```bash
-pip install pathway[all]
-```
-
-Then change your directory in the terminal to this folder and run the app:
-```bash
-python app.py
-```
-
-## Using the app
-
-Finally, query the application with;
-
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/answer' -H 'accept: */*' -H 'Content-Type: application/json' -d '{
- "prompt": "What is the start date of the contract?"
-}'
-```
-> `{"response": "December 21, 2015 [6]"}`
diff --git a/templates/adaptive_rag/app.py b/templates/adaptive_rag/app.py
deleted file mode 100644
index 314342e9..00000000
--- a/templates/adaptive_rag/app.py
+++ /dev/null
@@ -1,76 +0,0 @@
-import logging
-from warnings import warn
-
-import pathway as pw
-from dotenv import load_dotenv
-from pathway.xpacks.llm.question_answering import SummaryQuestionAnswerer
-from pathway.xpacks.llm.servers import QASummaryRestServer
-from pydantic import BaseModel, ConfigDict, InstanceOf
-
-# To use advanced features with Pathway Live Data Framework Scale, get your free license key from
-# https://pathway.com/features and paste it below.
-# To use Pathway Live Data Framework Community, comment out the line below.
-pw.set_license_key("demo-license-key-with-telemetry")
-
-logging.basicConfig(
- level=logging.INFO,
- format="%(asctime)s %(name)s %(levelname)s %(message)s",
- datefmt="%Y-%m-%d %H:%M:%S",
-)
-
-load_dotenv()
-
-
-class App(BaseModel):
- question_answerer: InstanceOf[SummaryQuestionAnswerer]
- host: str = "0.0.0.0"
- port: int = 8000
-
- with_cache: bool | None = None # deprecated
- persistence_backend: pw.persistence.Backend | None = None
- persistence_mode: pw.PersistenceMode | None = pw.PersistenceMode.UDF_CACHING
- terminate_on_error: bool = False
-
- def run(self) -> None:
- server = QASummaryRestServer( # noqa: F841
- self.host, self.port, self.question_answerer
- )
-
- if self.persistence_mode is None:
- if self.with_cache is True:
- warn(
- "`with_cache` is deprecated. Please use `persistence_mode` instead.",
- DeprecationWarning,
- )
- persistence_mode = pw.PersistenceMode.UDF_CACHING
- else:
- persistence_mode = None
- else:
- persistence_mode = self.persistence_mode
-
- if persistence_mode is not None:
- if self.persistence_backend is None:
- persistence_backend = pw.persistence.Backend.filesystem("./Cache")
- else:
- persistence_backend = self.persistence_backend
- persistence_config = pw.persistence.Config(
- persistence_backend,
- persistence_mode=persistence_mode,
- )
- else:
- persistence_config = None
-
- pw.run(
- persistence_config=persistence_config,
- terminate_on_error=self.terminate_on_error,
- monitoring_level=pw.MonitoringLevel.NONE,
- )
-
- model_config = ConfigDict(extra="forbid", arbitrary_types_allowed=True)
-
-
-if __name__ == "__main__":
- with open("app.yaml") as f:
- config = pw.load_yaml(f)
- app = App(**config)
- app.run()
diff --git a/templates/adaptive_rag/app.yaml b/templates/adaptive_rag/app.yaml
deleted file mode 100644
index f49f327f..00000000
--- a/templates/adaptive_rag/app.yaml
+++ /dev/null
@@ -1,114 +0,0 @@
-# This YAML configuration file is used to set up and configure the Adaptive RAG template.
-# It defines various components such as data sources, language models, embedders, splitters, parsers, and retrievers.
-# Each section is configured to specify how the template should process and handle data for generating responses.
-# You can learn more about the YAML syntax here: https://pathway.com/developers/templates/configure-yaml
-
-
-
-# $sources defines the data sources used to read the data which will be indexed in the RAG.
-# You can learn more how to configure data sources here:
-# https://pathway.com/developers/templates/yaml-examples/data-sources-examples
-
-$sources:
- # File System connector, reading data locally.
- - !pw.io.fs.read
- path: data
- format: binary
- with_metadata: true
-
- # Uncomment to use the SharePoint connector
- # - !pw.xpacks.connectors.sharepoint.read
- # url: $SHAREPOINT_URL
- # tenant: $SHAREPOINT_TENANT
- # client_id: $SHAREPOINT_CLIENT_ID
- # cert_path: sharepointcert.pem
- # thumbprint: $SHAREPOINT_THUMBPRINT
- # root_path: $SHAREPOINT_ROOT
- # with_metadata: true
- # refresh_interval: 30
-
- # Uncomment to use the Google Drive connector
- # - !pw.io.gdrive.read
- # object_id: $DRIVE_ID
- # service_user_credentials_file: gdrive_indexer.json
- # file_name_pattern:
- # - "*.pdf"
- # - "*.pptx"
- # object_size_limit: null
- # with_metadata: true
- # refresh_interval: 30
-
-
-
-# Configures the LLM model settings for generating responses.
-# The list of available Pathway LLM wrappers is available here:
-# https://pathway.com/developers/api-docs/pathway-xpacks-llm/llms
-# You can learn more about those in our documentation:
-# https://pathway.com/developers/templates/rag-customization/llm-chats
-
-$llm: !pw.xpacks.llm.llms.OpenAIChat
- model: "gpt-4.1-mini"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache {}
- temperature: 0
- capacity: 8
-
-# Specifies the embedder model for converting text into embeddings.
-$embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder
- model: "text-embedding-3-small"
- cache_strategy: !pw.udfs.DefaultCache {}
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy {}
-
-# Defines the splitter settings for dividing text into smaller chunks.
-$splitter: !pw.xpacks.llm.splitters.TokenCountSplitter
- max_tokens: 400
-
-# Configures the parser for processing and extracting information from documents.
-$parser: !pw.xpacks.llm.parsers.DoclingParser
- async_mode: "fully_async"
- chunk: false
- cache_strategy: !pw.udfs.DefaultCache {}
-
-# Sets up the retriever factory for indexing and retrieving documents.
-$retriever_factory: !pw.indexing.UsearchKnnFactory
- reserved_space: 1000
- embedder: $embedder
- metric: !pw.indexing.USearchMetricKind.COS
-
-# Manages the storage and retrieval of documents for the RAG template.
-$document_store: !pw.xpacks.llm.document_store.DocumentStore
- docs: $sources
- parser: $parser
- splitter: $splitter
- retriever_factory: $retriever_factory
-
-# Configures the question-answering component using the RAG approach.
-# The component builds a RAG over an index.
-# You can interact with obtained RAG using a REST API.
-# You can learn more about the available operations here:
-# https://pathway.com/developers/templates/rag-customization/rest-api
-question_answerer: !pw.xpacks.llm.question_answering.AdaptiveRAGQuestionAnswerer
- llm: $llm
- indexer: $document_store
- n_starting_documents: 2
- factor: 2
- max_iterations: 4
-
-# Change host and port of the webserver by uncommenting these lines
-# host: "0.0.0.0"
-# port: 8000
-
-# By default, caching is enabled for UDFs with cache_strategy set.
-# You can disable it by uncommenting the following line.
-# persistence_mode: null
-# You can also set persistence_mode to !pw.PersistenceMode.PERSISTING to enable persistence
-# across restarts.
-# By default, when enabled, Cache is stored in .Cache directory.
-# You can customize the location by uncommenting and modifying the following lines:
-# persistence_backend: !pw.persistence.Backend.filesystem
-# path: ".Cache"
-
-# If `terminate_on_error` is true then the program will terminate whenever any error is encountered.
-# Defaults to false, uncomment the following line if you want to set it to true
-# terminate_on_error: true
diff --git a/templates/adaptive_rag/data/IdeanomicsInc_20160330_10-K_EX-10.26_9512211_EX-10.26_Content License Agreement.pdf b/templates/adaptive_rag/data/IdeanomicsInc_20160330_10-K_EX-10.26_9512211_EX-10.26_Content License Agreement.pdf
deleted file mode 100644
index aa1a1686..00000000
Binary files a/templates/adaptive_rag/data/IdeanomicsInc_20160330_10-K_EX-10.26_9512211_EX-10.26_Content License Agreement.pdf and /dev/null differ
diff --git a/templates/adaptive_rag/requirements.txt b/templates/adaptive_rag/requirements.txt
deleted file mode 100644
index e6c9cccb..00000000
--- a/templates/adaptive_rag/requirements.txt
+++ /dev/null
@@ -1 +0,0 @@
-python-dotenv~=1.0
diff --git a/templates/document_indexing/Dockerfile b/templates/document_indexing/Dockerfile
deleted file mode 100644
index 2e2ca8a6..00000000
--- a/templates/document_indexing/Dockerfile
+++ /dev/null
@@ -1,16 +0,0 @@
-FROM pathwaycom/pathway:latest
-
-WORKDIR /app
-
-RUN apt-get update \
- && apt-get install -y python3-opencv tesseract-ocr-eng \
- && rm -rf /var/lib/apt/lists/* /var/cache/apt/archives/*
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-EXPOSE 8000
-
-CMD ["python", "app.py"]
diff --git a/templates/document_indexing/README.md b/templates/document_indexing/README.md
deleted file mode 100644
index 6e313f1b..00000000
--- a/templates/document_indexing/README.md
+++ /dev/null
@@ -1,199 +0,0 @@
-
-
-# Realtime Document Indexing: Vector Store with always-up-to-date knowledge
-
-This is a basic service for a real-time document indexing pipeline powered by [Pathway Live Data Framework](https://github.com/pathwaycom/pathway).
-
-The capabilities of the pipeline include:
-
-- Real-time document indexing from Microsoft 365 SharePoint, Google Drive, or a local directory;
-- Similarity search by user query;
-- Filtering by the metadata according to the condition given in [JMESPath format](https://jmespath.org/);
-- Basic stats on the indexer's health.
-
-## Summary of the Pipeline
-
-This example spawns a lightweight webserver that accepts queries on three possible endpoints:
-- `/v1/retrieve` to perform similarity search;
-- `/v1/statistics` to get the basic stats about the indexer's health;
-- `/v1/inputs` to retrieve the metadata of all files currently processed by the indexer.
-
-Please refer to the Open API doc on Hosted Pipelines [website](https://pathway.com/solutions/ai-pipelines) for the format of the requests to the endpoints.
-
-## How It Works
-
-This pipeline uses several Pathway Live Data Framework connectors to read the data from the local drive, Google Drive, and Microsoft SharePoint sources. It allows you to poll the changes with low latency and to do the modifications tracking. So, if something changes in the tracked files, the corresponding change is reflected in the internal collections. The contents are read into a single Pathway Live Data Framework Table as binary objects.
-
-After that, those binary objects are parsed with [unstructured](https://unstructured.io/) library and split into chunks. With the usage of OpenAI API, the pipeline embeds the obtained chunks.
-
-Finally, the embeddings are indexed with the capabilities of Pathway Live Data Framework's machine-learning library. The user can then query the created index with simple HTTP requests to the endpoints mentioned above.
-
-## Pipeline Organization
-
-This folder contains several objects:
-- `app.py`, the pipeline code using Pathway Live Data Framework and written in Python;
-- `app.yaml`, the file containing configuration of the pipeline, like embedding model, sources, or the server address;
-- `requirements.txt`, the textfile denoting the pip dependencies for running this pipeline. It can be passed to `pip install -r ...` to install everything that is needed to launch the pipeline locally;
-- `Dockerfile`, the Docker configuration for running the pipeline in the container;
-- `docker-compose.yml`, the docker-compose configuration for running the pipeline along with the chat UI;
-- `.env`, a short environment variables configuration file where the OpenAI key must be stored;
-- `files-for-indexing/`, a folder with exemplary files that can be used for the test runs.
-
-## Customizing the pipeline
-
-The code can be modified by changing the `app.yaml` configuration file. To read more about YAML files used in Pathway Live Data Framework templates, read [our guide](https://pathway.com/developers/templates/configure-yaml).
-
-In the `app.yaml` file we define:
-- input connectors
-- embedder
-- index
-and any of these can be replaced or, if no longer needed, removed. For components that can be used check
-The Pathway Live Data Framework [LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview), or you can implement your own.
-
-Here some examples of what can be modified.
-
-### Embedding Model
-
-By default this template uses locally run model `mixedbread-ai/mxbai-embed-large-v1`. If you wish, you can replace this with any other model, by changing
-`$embedder` in `app.yaml`. For example, to use OpenAI embedder, set:
-```yaml
-$embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder
- model: "text-embedding-ada-002"
- cache_strategy: !pw.udfs.DiskCache
-```
-
-If you choose to use a provider, that requires API key, remember to set appropriate environmental values (you can also set them in `.env` file).
-
-### Webserver
-
-You can configure the host and the port of the webserver.
-Here is the default configuration:
-```yaml
-host: "0.0.0.0"
-port: 8000
-```
-
-### Cache
-
-You can configure whether you want to enable cache, to avoid repeated API accesses, and where the cache is stored.
-Default values:
-```yaml
-with_cache: True
-cache_backend: !pw.persistence.Backend.filesystem
- path: ".Cache"
-```
-
-### Data sources
-
-You can configure the data sources by changing `$sources` in `app.yaml`.
-You can add as many data sources as you want. You can have several sources of the same kind, for instance, several local sources from different folders.
-The sections below describe how to configure local, Google Drive and Sharepoint source, and you can check the examples of YAML configuration in our [user guide](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples/). While these are not described in this Section, you can also use any input [connector](https://pathway.com/developers/user-guide/connecting-to-data/connectors) from Pathway Live Data Framework package.
-
-By default, the app uses a local data source to read documents from the `files-from-indexing` folder.
-
-#### Local Data Source
-
-The local data source is configured by using map with tag `!pw.io.fs.read`. Then set `path` to denote the path to a folder with files to be indexed.
-
-#### Google Drive Data Source
-
-The Google Drive data source is enabled by using map with tag `!pw.io.gdrive.read`. The map must contain two main parameters:
-- `object_id`, containing the ID of the folder that needs to be indexed. It can be found from the URL in the web interface, where it's the last part of the address. For example, the publicly available demo folder in Google Drive has the URL `https://drive.google.com/drive/folders/1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`. Consequently, the last part of this address is `1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`, hence this is the `object_id` you would need to specify.
-- `service_user_credentials_file`, containing the path to the credentials files for the Google [service account](https://cloud.google.com/iam/docs/service-account-overview). To get more details on setting up the service account and getting credentials, you can also refer to [this tutorial](https://pathway.com/developers/user-guide/connectors/gdrive-connector#setting-up-google-drive).
-
-Besides, to speed up the indexing process you may want to specify the `refresh_interval` parameter, denoted by an integer number of seconds. It corresponds to the frequency between two sequential folder scans. If unset, it defaults to 30 seconds.
-
-For the full list of the available parameters, please refer to the Google Drive connector [documentation](https://pathway.com/developers/api-docs/pathway-io/gdrive#pathway.io.gdrive.read).
-
-#### SharePoint Data Source
-
-This data source requires Scale or Enterprise [license key](https://pathway.com/pricing) - you can obtain free Scale key on [Pathway website](https://pathway.com/get-license).
-
-To use it, set the map tag to be `!pw.xpacks.connectors.sharepoint.read`, and then provide values of `url`, `tenant`, `client_id`, `cert_path`, `thumbprint` and `root_path`. To read about the meaning of these arguments, check the Sharepoint connector [documentation](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read).
-
-## Running the Example
-
-### Locally
-
-This example can be run locally by executing `python main.py` in this directory. It has several command-line arguments:
-- `--host` denoting the host, where the server will run. The default setting is `0.0.0.0`;
-- `--port` denoting the port, where the server will accept requests. The default setting is `8000`;
-- `--sources-config` pointing to a data source configuration file, `sources_configuration.yaml` by default. You can customize it to change the folders indexed by the vector store. The free version supports `local` and `gdrive` hosted files, while the commercial one also supports `sharepoint` hosted folders. By default, the `local` option indexes files from the `files-for-indexing/` folder that is prefilled with exemplary documents.
-
-Please note that the local run requires the dependencies to be installed. It can be done with a simple pip command:
-
-```bash
-pip install -r requirements.txt
-```
-
-### With Docker
-
-First, create or fill the `.env` file in this folder (`/document_indexing_rag`) with your OpenAI key `OPENAI_API_KEY=sk-*******`.
-
-To run jointly the vector indexing pipeline and a simple UI please execute:
-
-```bash
-docker compose up --build
-```
-
-Then, the UI will run at http://127.0.0.1:8501 by default. You can access it by following this URL in your web browser.
-
-The `docker-compose.yml` file declares a [volume bind mount](https://docs.docker.com/reference/cli/docker/container/run/#volume) that makes changes to files under `files-for-indexing/` made on your host computer visible inside the docker container. If the index does not react to file changes, please check that the bind mount works
-by running `docker compose exec pathway_vector_indexer ls -l /app/files-for-indexing/` and verifying that all files are visible.
-
-Alternatively, you can launch just the indexing pipeline as a single Docker container:
-
-```bash
-docker build -t vector_indexer .
-docker run -v `pwd`/files-for-indexing:/app/files-for-indexing -p 8000:8000 vector_indexer
-```
-
-The volume overlay is important - without it, docker will not see changes to files under the `files-for-indexing` folder.
-
-## Querying the Example
-
-Since the pipeline spawns an HTTP server and interacts with the user using the REST protocol, you can test it locally by sending requests with `curl`. To get the target address for the request, you can refer to the routes in the first section: `v1/retrieve`, `v1/statistics`, and `v1/inputs` and the Open API docs available at the Hosted Pipelines webpage.
-
-Let's assume that the server runs with the default settings and therefore uses port 8000. That being said, you can query the similarity search endpoint with the following command:
-
-```bash
-curl -X 'GET' \
- 'http://localhost:8000/v1/retrieve?query=Pathway%20data%20processing%20framework&k=2' \
- -H 'accept: */*'
-```
-
-Above, there are two CGI parameters to be customized: the `query`, which should contain the [urlencoded](https://en.wikipedia.org/wiki/Percent-encoding) search terms, and an integer `k` denoting the number of documents you want to retrieve.
-
-Apart from the querying part, there is a health-check endpoint that shows the number of documents currently indexed and the most recent indexing time. It can be accessed, in a similar way, with the following command:
-
-```bash
-curl -X 'GET' \
- 'http://localhost:8000/v1/statistics' \
- -H 'accept: */*'
-```
-
-Finally, there is a way to see the metadata of all documents that are currently indexed. To do that, you need to query the `v1/inputs` endpoint. The request command then looks as follows:
-
-```bash
-curl -X 'GET' \
- 'http://localhost:8000/v1/inputs' \
- -H 'accept: */*'
-```
-
-Please make sure that you've changed the port in the requests if you did that when launching the main script.
-
-## Adding Files to Index
-
-To test index updates, simply add more files to the `files-for-indexing` folder if the local data source is used.
-If you are using Google Drive, simply upload your files in the folder configured in the `sources_configuration.yaml` file.
-
-Then you can use the similarity search and stats endpoints, provided below.
diff --git a/templates/document_indexing/app.py b/templates/document_indexing/app.py
deleted file mode 100644
index 6463c132..00000000
--- a/templates/document_indexing/app.py
+++ /dev/null
@@ -1,75 +0,0 @@
-import logging
-from warnings import warn
-
-import pathway as pw
-from dotenv import load_dotenv
-from pathway.xpacks.llm.document_store import DocumentStore
-from pathway.xpacks.llm.servers import DocumentStoreServer
-from pydantic import BaseModel, ConfigDict, InstanceOf
-
-# To use advanced features with Pathway Live Data Framework Scale, get your free license key from
-# https://pathway.com/features and paste it below.
-# To use Pathway Live Data Framework Community, comment out the line below.
-pw.set_license_key("demo-license-key-with-telemetry")
-
-logging.basicConfig(
- level=logging.INFO,
- format="%(asctime)s %(name)s %(levelname)s %(message)s",
- datefmt="%Y-%m-%d %H:%M:%S",
-)
-
-load_dotenv()
-
-
-class App(BaseModel):
- document_store: InstanceOf[DocumentStore]
- host: str = "0.0.0.0"
- port: int = 8000
-
- with_cache: bool | None = None # deprecated
- persistence_backend: pw.persistence.Backend | None = None
- persistence_mode: pw.PersistenceMode | None = pw.PersistenceMode.UDF_CACHING
- terminate_on_error: bool = False
-
- def run(self) -> None:
- server = DocumentStoreServer( # noqa: F841
- self.host, self.port, self.document_store
- )
- if self.persistence_mode is None:
- if self.with_cache is True:
- warn(
- "`with_cache` is deprecated. Please use `persistence_mode` instead.",
- DeprecationWarning,
- )
- persistence_mode = pw.PersistenceMode.UDF_CACHING
- else:
- persistence_mode = None
- else:
- persistence_mode = self.persistence_mode
-
- if persistence_mode is not None:
- if self.persistence_backend is None:
- persistence_backend = pw.persistence.Backend.filesystem("./Cache")
- else:
- persistence_backend = self.persistence_backend
- persistence_config = pw.persistence.Config(
- persistence_backend,
- persistence_mode=persistence_mode,
- )
- else:
- persistence_config = None
-
- pw.run(
- persistence_config=persistence_config,
- terminate_on_error=self.terminate_on_error,
- monitoring_level=pw.MonitoringLevel.NONE,
- )
-
- model_config = ConfigDict(extra="forbid", arbitrary_types_allowed=True)
-
-
-if __name__ == "__main__":
- with open("app.yaml") as f:
- config = pw.load_yaml(f)
- app = App(**config)
- app.run()
diff --git a/templates/document_indexing/app.yaml b/templates/document_indexing/app.yaml
deleted file mode 100644
index b26d70df..00000000
--- a/templates/document_indexing/app.yaml
+++ /dev/null
@@ -1,88 +0,0 @@
-# This YAML configuration file is used to set up and configure the Document indexing RAG template.
-# It defines various components such as data sources, embedders, splitters, parsers, and retrievers.
-# Each section is configured to specify how the template should process and handle data for answering the queries.
-# You can learn more about the YAML syntax here: https://pathway.com/developers/templates/configure-yaml
-
-
-# $sources defines the data sources used to read the data which will be indexed in the RAG.
-# You can learn more how to configure data sources here:
-# https://pathway.com/developers/templates/yaml-examples/data-sources-examples
-
-$sources:
- # File System connector, reading data locally.
- - !pw.io.fs.read
- path: files-for-indexing
- format: binary
- with_metadata: true
-
- # Uncomment to use the SharePoint connector
- # - !pw.xpacks.connectors.sharepoint.read
- # url: $SHAREPOINT_URL
- # tenant: $SHAREPOINT_TENANT
- # client_id: $SHAREPOINT_CLIENT_ID
- # cert_path: sharepointcert.pem
- # thumbprint: $SHAREPOINT_THUMBPRINT
- # root_path: $SHAREPOINT_ROOT
- # with_metadata: true
- # refresh_interval: 30
-
- # Uncomment to use the Google Drive connector
- # - !pw.io.gdrive.read
- # object_id: $DRIVE_ID
- # service_user_credentials_file: gdrive_indexer.json
- # file_name_pattern:
- # - "*.pdf"
- # - "*.pptx"
- # object_size_limit: null
- # with_metadata: true
- # refresh_interval: 30
-
-# Model used for embedding
-$embedding_model: "mixedbread-ai/mxbai-embed-large-v1"
-
-# Specifies the embedder model for converting text into embeddings.
-$embedder: !pw.xpacks.llm.embedders.SentenceTransformerEmbedder
- model: $embedding_model
- call_kwargs:
- show_progress_bar: False
-
-# Defines the splitter settings for dividing text into smaller chunks.
-$splitter: !pw.xpacks.llm.splitters.TokenCountSplitter
- max_tokens: 400
-
-# Configures the parser for processing and extracting information from documents.
-$parser: !pw.xpacks.llm.parsers.DoclingParser
- async_mode: "fully_async"
- chunk: false
- cache_strategy: !pw.udfs.DefaultCache {}
-
-# Sets up the retriever factory for indexing and retrieving documents.
-$retriever_factory: !pw.indexing.UsearchKnnFactory
- reserved_space: 1000
- embedder: $embedder
- metric: !pw.indexing.USearchMetricKind.COS
-
-# Manages the storage and retrieval of documents for the RAG template.
-document_store: !pw.xpacks.llm.document_store.DocumentStore
- docs: $sources
- parser: $parser
- splitter: $splitter
- retriever_factory: $retriever_factory
-
-# Change host and port of the webserver by uncommenting these lines
-# host: "0.0.0.0"
-# port: 8000
-
-# By default, caching is enabled for UDFs with cache_strategy set.
-# You can disable it by uncommenting the following line.
-# persistence_mode: null
-# You can also set persistence_mode to !pw.PersistenceMode.PERSISTING to enable persistence
-# across restarts.
-# By default, when enabled, Cache is stored in .Cache directory.
-# You can customize the location by uncommenting and modifying the following lines:
-# persistence_backend: !pw.persistence.Backend.filesystem
-# path: ".Cache"
-
-# If `terminate_on_error` is true then the program will terminate whenever any error is encountered.
-# Defaults to false, uncomment the following line if you want to set it to true
-# terminate_on_error: true
diff --git a/templates/document_indexing/docker-compose.yml b/templates/document_indexing/docker-compose.yml
deleted file mode 100644
index 3a44dca2..00000000
--- a/templates/document_indexing/docker-compose.yml
+++ /dev/null
@@ -1,22 +0,0 @@
-version: "3.8"
-services:
- pathway_vector_indexer:
- build:
- context: .
- ports:
- - "8000:8000"
- environment:
- OPENAI_API_KEY: "${OPENAI_API_KEY}"
- volumes:
- - "./files-for-indexing:/app/files-for-indexing"
- streamlit_ui:
- depends_on:
- - pathway_vector_indexer
- build:
- context: https://github.com/pathway-labs/realtime-indexer-qa-chat.git
- ports:
- - "8501:8501"
- environment:
- OPENAI_API_KEY: "${OPENAI_API_KEY}"
- PATHWAY_HOST: "pathway_vector_indexer"
- PATHWAY_PORT: "8000"
diff --git a/templates/document_indexing/files-for-indexing/2023q2-alphabet-earnings-release.pdf b/templates/document_indexing/files-for-indexing/2023q2-alphabet-earnings-release.pdf
deleted file mode 100644
index 665d796a..00000000
Binary files a/templates/document_indexing/files-for-indexing/2023q2-alphabet-earnings-release.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/Always up-to-date Vector Data Indexing pipeline _ Pathway.pdf b/templates/document_indexing/files-for-indexing/Always up-to-date Vector Data Indexing pipeline _ Pathway.pdf
deleted file mode 100644
index 04fa0743..00000000
Binary files a/templates/document_indexing/files-for-indexing/Always up-to-date Vector Data Indexing pipeline _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/Build an LLM App _ Pathway.pdf b/templates/document_indexing/files-for-indexing/Build an LLM App _ Pathway.pdf
deleted file mode 100644
index bbaf8b81..00000000
Binary files a/templates/document_indexing/files-for-indexing/Build an LLM App _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/Launching Pathway + LlamaIndex.pdf b/templates/document_indexing/files-for-indexing/Launching Pathway + LlamaIndex.pdf
deleted file mode 100644
index d9237747..00000000
Binary files a/templates/document_indexing/files-for-indexing/Launching Pathway + LlamaIndex.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/Realtime Classification with Nearest Neighbors (1_2) _ Pathway.pdf b/templates/document_indexing/files-for-indexing/Realtime Classification with Nearest Neighbors (1_2) _ Pathway.pdf
deleted file mode 100644
index 3e9eb06c..00000000
Binary files a/templates/document_indexing/files-for-indexing/Realtime Classification with Nearest Neighbors (1_2) _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/Realtime Twitter Analysis App _ Pathway.pdf b/templates/document_indexing/files-for-indexing/Realtime Twitter Analysis App _ Pathway.pdf
deleted file mode 100644
index 1d1b4c93..00000000
Binary files a/templates/document_indexing/files-for-indexing/Realtime Twitter Analysis App _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/Use LLMs to Ingest Raw Text into DB _ Pathway.pdf b/templates/document_indexing/files-for-indexing/Use LLMs to Ingest Raw Text into DB _ Pathway.pdf
deleted file mode 100644
index b0fb0efc..00000000
Binary files a/templates/document_indexing/files-for-indexing/Use LLMs to Ingest Raw Text into DB _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/arxiv 2307.13116.pdf b/templates/document_indexing/files-for-indexing/arxiv 2307.13116.pdf
deleted file mode 100644
index 6fbc9149..00000000
Binary files a/templates/document_indexing/files-for-indexing/arxiv 2307.13116.pdf and /dev/null differ
diff --git a/templates/document_indexing/files-for-indexing/pw.io.http _ Pathway.pdf b/templates/document_indexing/files-for-indexing/pw.io.http _ Pathway.pdf
deleted file mode 100644
index a92a1f7d..00000000
Binary files a/templates/document_indexing/files-for-indexing/pw.io.http _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_indexing/requirements.txt b/templates/document_indexing/requirements.txt
deleted file mode 100644
index e6c9cccb..00000000
--- a/templates/document_indexing/requirements.txt
+++ /dev/null
@@ -1 +0,0 @@
-python-dotenv~=1.0
diff --git a/templates/document_store_mcp_server/.env.example b/templates/document_store_mcp_server/.env.example
deleted file mode 100644
index 7fd2babe..00000000
--- a/templates/document_store_mcp_server/.env.example
+++ /dev/null
@@ -1 +0,0 @@
-PATHWAY_LICENSE_KEY="YOUR PATHWAY KEY" # can be obtained here: https://pathway.com/user/license
diff --git a/templates/document_store_mcp_server/Dockerfile b/templates/document_store_mcp_server/Dockerfile
deleted file mode 100644
index fdf81882..00000000
--- a/templates/document_store_mcp_server/Dockerfile
+++ /dev/null
@@ -1,16 +0,0 @@
-FROM pathwaycom/pathway:latest
-
-WORKDIR /app
-
-RUN apt-get update \
- && apt-get install -y python3-opencv tesseract-ocr-eng \
- && rm -rf /var/lib/apt/lists/* /var/cache/apt/archives/*
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-EXPOSE 8068
-
-CMD ["python", "app.py"]
diff --git a/templates/document_store_mcp_server/README.md b/templates/document_store_mcp_server/README.md
deleted file mode 100644
index 13a0c236..00000000
--- a/templates/document_store_mcp_server/README.md
+++ /dev/null
@@ -1,197 +0,0 @@
-
-
-# MCP Server with Realtime Document Indexing
-
-This is a template for exposing a real-time document indexing pipeline powered by [Pathway](https://github.com/pathwaycom/pathway) as an Model Context Protocol (MCP) server.
-
-The [Model Context Protocol (MCP)](https://modelcontextprotocol.io/docs/getting-started/intro) is designed to standardize the way applications interact with large language models (LLMs). It serves as a bridge, much like a universal connector, enabling seamless integration between AI models and various data sources and tools. This protocol facilitates the creation of sophisticated AI workflows and agents, enhancing the capabilities of LLMs by connecting them with real-world data and functionalities.
-
-The capabilities of the pipeline include:
-
-- Real-time document indexing from Microsoft 365 SharePoint, Google Drive, or a local directory;
-- Similarity search by user query;
-- Filtering by the metadata according to the condition given in [JMESPath format](https://jmespath.org/);
-- The documents are available from a standardized MCP server.
-
-## Summary of the Pipeline
-
-This example spawns an MCP server that has three tools:
-- `retrieve_query` to perform similarity search on the indexed documents,
-- `statistics_query` to get the basic stats about the indexer's health,
-- `inputs_query` to retrieve the metadata of all files currently processed by the indexer.
-
-You can get specification of those tools by querying the `list_tools` on the MCP server.
-
-## How It Works
-
-This pipeline uses several Pathway Live Data Framework connectors to read the data from the local drive, Google Drive, or Microsoft SharePoint sources. It allows you to poll the changes with low latency and to do the modifications tracking. So, if something changes in the tracked files, the corresponding change is reflected in the internal collections. The contents are read into a single Pathway Live Data Framework Table as binary objects.
-
-After that, those binary objects are parsed with the [Docling](https://www.docling.ai/) library and split into chunks. With the usage of the [SentenceTransformer](https://www.sbert.net/) embedder, the pipeline embeds the obtained chunks.
-
-Finally, the embeddings are indexed with the capabilities of Pathway Live Data Framework's machine-learning library. The user can then query the created index by connecting to the MCP server using an MCP client.
-
-## Pipeline Organization
-
-This folder contains several objects:
-- `app.py`, the pipeline code using Pathway Live Data Framework and written in Python;
-- `app.yaml`, the file containing configuration of the pipeline, like embedding model, sources, or the server address;
-- `requirements.txt`, the textfile denoting the pip dependencies for running this pipeline. It can be passed to `pip install -r requirements.txt` to install everything that is needed to launch the pipeline locally;
-- `Dockerfile`, the Docker configuration for running the pipeline in the container;
-- `docker-compose.yml`, the docker-compose configuration for running the pipeline along with the chat UI;
-- `files-for-indexing/`, a folder with exemplary files that can be used for the test runs.
-
-## Customizing the pipeline
-
-The code can be modified by changing the `app.yaml` configuration file. To read more about YAML files used in Pathway Live Data Framework templates, read [our guide](https://pathway.com/developers/templates/configure-yaml).
-
-In the `app.yaml` file we define:
-- input connectors
-- embedder
-- index
-and any of these can be replaced or, if no longer needed, removed. For components that can be used check
-The Pathway Live Data Framework [LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview), or you can implement your own.
-
-Here some examples of what can be modified.
-
-### Embedding Model
-
-By default this template uses locally run model `mixedbread-ai/mxbai-embed-large-v1`. If you wish, you can replace this with any other model, by changing
-`$embedder` in `app.yaml`. For example, to use OpenAI embedder, set:
-```yaml
-$embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder
- model: "text-embedding-3-small"
- cache_strategy: !pw.udfs.DefaultCache {}
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy {}
-```
-
-If you choose to use a provider, that requires API key, remember to set appropriate environmental values (you can also set them in the `.env` file) - e.g. for using OpenAI embedders, set the `OPENAI_API_KEY` variable.
-
-### Webserver
-
-You can configure the name, the host and the port of the MCP server.
-Here is the default configuration:
-```yaml
-mcp_http: !pw.xpacks.llm.mcp_server.PathwayMcp
- name: "Streamable MCP Server"
- transport: "streamable-http"
- host: "localhost"
- port: 8068
- serve:
- - $document_store
-```
-
-### Cache
-
-You can configure whether you want to enable cache or persistence, to avoid repeated API accesses, and where the cache is stored.
-Default values:
-```yaml
-persistence_mode: !pw.PersistenceMode.UDF_CACHING
-persistence_backend: !pw.persistence.Backend.filesystem
- path: ".Cache"
-```
-
-### Data sources
-
-You can configure the data sources by changing `$sources` in `app.yaml`.
-You can add as many data sources as you want. You can have several sources of the same kind, for instance, several local sources from different folders.
-The sections below describe how to configure local, Google Drive and Sharepoint source, and you can check the examples of YAML configuration in our [user guide](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples/). While these are not described in this Section, you can also use any input [connector](https://pathway.com/developers/user-guide/connecting-to-data/connectors) from Pathway package.
-
-By default, the app uses a local data source to read documents from the `files-from-indexing` folder.
-
-#### Local Data Source
-
-The local data source is configured by using map with tag `!pw.io.fs.read`. Then set `path` to denote the path to a folder with files to be indexed.
-
-#### Google Drive Data Source
-
-The Google Drive data source is enabled by using map with tag `!pw.io.gdrive.read`. The map must contain two main parameters:
-- `object_id`, containing the ID of the folder that needs to be indexed. It can be found from the URL in the web interface, where it's the last part of the address. For example, the publicly available demo folder in Google Drive has the URL `https://drive.google.com/drive/folders/1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`. Consequently, the last part of this address is `1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`, hence this is the `object_id` you would need to specify.
-- `service_user_credentials_file`, containing the path to the credentials files for the Google [service account](https://cloud.google.com/iam/docs/service-account-overview). To get more details on setting up the service account and getting credentials, you can also refer to [this tutorial](https://pathway.com/developers/user-guide/connectors/gdrive-connector#setting-up-google-drive).
-
-Besides, to speed up the indexing process you may want to specify the `refresh_interval` parameter, denoted by an integer number of seconds. It corresponds to the frequency between two sequential folder scans. If unset, it defaults to 30 seconds.
-
-For the full list of the available parameters, please refer to the Google Drive connector [documentation](https://pathway.com/developers/api-docs/pathway-io/gdrive#pathway.io.gdrive.read).
-
-#### SharePoint Data Source
-
-This data source requires Scale or Enterprise [license key](https://pathway.com/pricing) - you can obtain free Scale key on [Pathway website](https://pathway.com/get-license).
-
-To use it, set the map tag to be `!pw.xpacks.connectors.sharepoint.read`, and then provide values of `url`, `tenant`, `client_id`, `cert_path`, `thumbprint` and `root_path`. To read about the meaning of these arguments, check the Sharepoint connector [documentation](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read).
-
-## Running the Template
-
-### Pathway Live Data Framework License Key
-The Pathway Live Data Framework MCP Server requires a Pathway Live Data Framework license key, so before you run the template, you need to set the license key. This template is available for free via [Pathway Live Data Framework Scale](https://pathway.com/features), for which you can get the license key [here](https://pathway.com/user/license). Once you have your license key, create a `.env` file, in which set `PATHWAY_LICENSE_KEY` to your license key - see `.env.example` for an example of `.env` file.
-
-### Locally
-
-This template can be run locally by executing `python app.py` in this directory. Please note that the local run requires the `Pathway` library and other dependencies to be installed. It can be done with a pip command:
-
-```bash
-pip install pathway[all]
-pip install -r requirements.txt
-```
-
-### With Docker`.
-
-To run jointly the MCP server with real-time document indexint, please execute:
-
-```bash
-docker compose up --build
-```
-
-The `docker-compose.yml` file declares a [volume bind mount](https://docs.docker.com/reference/cli/docker/container/run/#volume) that makes changes to files under `files-for-indexing/` made on your host computer visible inside the docker container. If the index does not react to file changes, please check that the bind mount works
-by running `docker compose exec pathway_vector_indexer ls -l /app/files-for-indexing/` and verifying that all files are visible.
-
-
-## Querying the Template with an MCP client
-
-To test your examples, you need an MCP client which will connect to your MCP server. You can use the fastmcp package to define a client as follows:
-
-```python
-import asyncio
-from fastmcp import Client
-
-# Change the URL if you change the default values in the app.yaml
-PATHWAY_MCP_URL = "http://localhost:8068/mcp/"
-
-client = Client(PATHWAY_MCP_URL)
-
-
-async def main():
- async with client:
- tools = await client.list_tools()
- print(tools)
-
- async with client:
- result = await client.call_tool(
- name="retrieve_query",
- arguments={"query": "How to create a webserver in Pathway?", "k": 3},
- )
- print(result)
-
-
-asyncio.run(main())
-
-```
-
-You can list the different tools available in the MCP server using the `list_tools` of the client. To access a given tool, you can use the method call_tool, with the name and arguments parameters. The arguments should be a dict of the different values: in this case, the `retrieve_query` tool has two required arguments: `query` and `k`.
-
-## Using MCP server in Claude Desktop
-To use MCP server created by this template in Claude Desktop, follow the [guide in Pathway's documentation](https://pathway.com/developers/user-guide/llm-xpack/pathway-mcp-claude-desktop).
-
-## Adding Files to Index
-
-To test index updates, simply add more files to the `files-for-indexing` folder if the local data source is used.
-If you are using Google Drive, simply upload your files in the folder configured in the `sources_configuration.yaml` file.
-
-Then you can use the similarity search and stats endpoints, provided below.
diff --git a/templates/document_store_mcp_server/__init__.py b/templates/document_store_mcp_server/__init__.py
deleted file mode 100644
index e69de29b..00000000
diff --git a/templates/document_store_mcp_server/app.py b/templates/document_store_mcp_server/app.py
deleted file mode 100644
index 5d4cc41c..00000000
--- a/templates/document_store_mcp_server/app.py
+++ /dev/null
@@ -1,52 +0,0 @@
-import logging
-
-import pathway as pw
-from dotenv import load_dotenv
-from pathway.xpacks.llm.mcp_server import PathwayMcp
-from pydantic import BaseModel, ConfigDict
-
-logging.basicConfig(
- level=logging.INFO,
- format="%(asctime)s %(name)s %(levelname)s %(message)s",
- datefmt="%Y-%m-%d %H:%M:%S",
-)
-
-load_dotenv()
-
-
-class App(BaseModel):
- mcp_http: PathwayMcp
- host: str = "0.0.0.0"
- port: int = 8000
-
- terminate_on_error: bool = False
- persistence_backend: pw.persistence.Backend | None = None
- persistence_mode: pw.PersistenceMode | None = pw.PersistenceMode.UDF_CACHING
-
- def run(self) -> None:
- if self.persistence_mode is not None:
- if self.persistence_backend is None:
- persistence_backend = pw.persistence.Backend.filesystem("./Cache")
- else:
- persistence_backend = self.persistence_backend
- persistence_config = pw.persistence.Config(
- persistence_backend,
- persistence_mode=self.persistence_mode,
- )
- else:
- persistence_config = None
- pw.run(
- terminate_on_error=self.terminate_on_error,
- persistence_config=persistence_config,
- monitoring_level=pw.MonitoringLevel.NONE,
- )
-
- model_config = ConfigDict(extra="forbid", arbitrary_types_allowed=True)
-
-
-if __name__ == "__main__":
- with open("app.yaml") as f:
- config = pw.load_yaml(f)
- print(config)
- app = App(**config)
- app.run()
diff --git a/templates/document_store_mcp_server/app.yaml b/templates/document_store_mcp_server/app.yaml
deleted file mode 100644
index 65a540b4..00000000
--- a/templates/document_store_mcp_server/app.yaml
+++ /dev/null
@@ -1,93 +0,0 @@
-# This YAML configuration file is used to set up and configure the Document indexing RAG template.
-# It defines various components such as data sources, embedders, splitters, parsers, and retrievers.
-# Each section is configured to specify how the template should process and handle data for answering the queries.
-# You can learn more about the YAML syntax here: https://pathway.com/developers/templates/configure-yaml
-
-
-# $sources defines the data sources used to read the data which will be indexed in the RAG.
-# You can learn more how to configure data sources here:
-# https://pathway.com/developers/templates/yaml-examples/data-sources-examples
-
-$sources:
- # File System connector, reading data locally.
- - !pw.io.fs.read
- path: files-for-indexing
- format: binary
- with_metadata: true
-
- # Uncomment to use the SharePoint connector
- # - !pw.xpacks.connectors.sharepoint.read
- # url: $SHAREPOINT_URL
- # tenant: $SHAREPOINT_TENANT
- # client_id: $SHAREPOINT_CLIENT_ID
- # cert_path: sharepointcert.pem
- # thumbprint: $SHAREPOINT_THUMBPRINT
- # root_path: $SHAREPOINT_ROOT
- # with_metadata: true
- # refresh_interval: 30
-
- # Uncomment to use the Google Drive connector
- # - !pw.io.gdrive.read
- # object_id: $DRIVE_ID
- # service_user_credentials_file: gdrive_indexer.json
- # file_name_pattern:
- # - "*.pdf"
- # - "*.pptx"
- # object_size_limit: null
- # with_metadata: true
- # refresh_interval: 30
-
-# Model used for embedding
-$embedding_model: "mixedbread-ai/mxbai-embed-large-v1"
-
-# Specifies the embedder model for converting text into embeddings.
-$embedder: !pw.xpacks.llm.embedders.SentenceTransformerEmbedder
- model: $embedding_model
- call_kwargs:
- show_progress_bar: False
-
-# Defines the splitter settings for dividing text into smaller chunks.
-$splitter: !pw.xpacks.llm.splitters.TokenCountSplitter
- max_tokens: 400
-
-# Configures the parser for processing and extracting information from documents.
-$parser: !pw.xpacks.llm.parsers.DoclingParser
- async_mode: "fully_async"
- chunk: false
- cache_strategy: !pw.udfs.DefaultCache {}
-
-# Sets up the retriever factory for indexing and retrieving documents.
-$retriever_factory: !pw.indexing.UsearchKnnFactory
- reserved_space: 1000
- embedder: $embedder
- metric: !pw.indexing.USearchMetricKind.COS
-
-# Manages the storage and retrieval of documents for the RAG template.
-$document_store: !pw.xpacks.llm.document_store.DocumentStore
- docs: $sources
- parser: $parser
- splitter: $splitter
- retriever_factory: $retriever_factory
-
-# Streamable MCP server, can be proxied
-mcp_http: !pw.xpacks.llm.mcp_server.PathwayMcp
- name: "Streamable MCP Server"
- transport: "streamable-http"
- host: "0.0.0.0"
- port: 8068
- serve:
- - $document_store
-
-# By default, caching is enabled for UDFs with cache_strategy set.
-# You can disable it by uncommenting the following line.
-# persistence_mode: null
-# You can also set persistence_mode to !pw.PersistenceMode.PERSISTING to enable persistence
-# across restarts.
-# By default, when enabled, Cache is stored in .Cache directory.
-# You can customize the location by uncommenting and modifying the following lines:
-# persistence_backend: !pw.persistence.Backend.filesystem
-# path: ".Cache"
-
-# If `terminate_on_error` is true then the program will terminate whenever any error is encountered.
-# Defaults to false, uncomment the following line if you want to set it to true
-# terminate_on_error: true
diff --git a/templates/document_store_mcp_server/docker-compose.yml b/templates/document_store_mcp_server/docker-compose.yml
deleted file mode 100644
index a3cdfb52..00000000
--- a/templates/document_store_mcp_server/docker-compose.yml
+++ /dev/null
@@ -1,11 +0,0 @@
-version: "3.8"
-services:
- pathway_mcp_server:
- build:
- context: .
- ports:
- - "8068:8068"
- environment:
- PATHWAY_LICENSE_KEY: $PATHWAY_LICENSE_KEY
- volumes:
- - "./files-for-indexing:/app/files-for-indexing"
diff --git a/templates/document_store_mcp_server/files-for-indexing/2023q2-alphabet-earnings-release.pdf b/templates/document_store_mcp_server/files-for-indexing/2023q2-alphabet-earnings-release.pdf
deleted file mode 100644
index 665d796a..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/2023q2-alphabet-earnings-release.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/Always up-to-date Vector Data Indexing pipeline _ Pathway.pdf b/templates/document_store_mcp_server/files-for-indexing/Always up-to-date Vector Data Indexing pipeline _ Pathway.pdf
deleted file mode 100644
index 04fa0743..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/Always up-to-date Vector Data Indexing pipeline _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/Build an LLM App _ Pathway.pdf b/templates/document_store_mcp_server/files-for-indexing/Build an LLM App _ Pathway.pdf
deleted file mode 100644
index bbaf8b81..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/Build an LLM App _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/Launching Pathway + LlamaIndex.pdf b/templates/document_store_mcp_server/files-for-indexing/Launching Pathway + LlamaIndex.pdf
deleted file mode 100644
index d9237747..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/Launching Pathway + LlamaIndex.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/Realtime Classification with Nearest Neighbors (1_2) _ Pathway.pdf b/templates/document_store_mcp_server/files-for-indexing/Realtime Classification with Nearest Neighbors (1_2) _ Pathway.pdf
deleted file mode 100644
index 3e9eb06c..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/Realtime Classification with Nearest Neighbors (1_2) _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/Realtime Twitter Analysis App _ Pathway.pdf b/templates/document_store_mcp_server/files-for-indexing/Realtime Twitter Analysis App _ Pathway.pdf
deleted file mode 100644
index 1d1b4c93..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/Realtime Twitter Analysis App _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/Use LLMs to Ingest Raw Text into DB _ Pathway.pdf b/templates/document_store_mcp_server/files-for-indexing/Use LLMs to Ingest Raw Text into DB _ Pathway.pdf
deleted file mode 100644
index b0fb0efc..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/Use LLMs to Ingest Raw Text into DB _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/arxiv 2307.13116.pdf b/templates/document_store_mcp_server/files-for-indexing/arxiv 2307.13116.pdf
deleted file mode 100644
index 6fbc9149..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/arxiv 2307.13116.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/files-for-indexing/pw.io.http _ Pathway.pdf b/templates/document_store_mcp_server/files-for-indexing/pw.io.http _ Pathway.pdf
deleted file mode 100644
index a92a1f7d..00000000
Binary files a/templates/document_store_mcp_server/files-for-indexing/pw.io.http _ Pathway.pdf and /dev/null differ
diff --git a/templates/document_store_mcp_server/requirements.txt b/templates/document_store_mcp_server/requirements.txt
deleted file mode 100644
index e6c9cccb..00000000
--- a/templates/document_store_mcp_server/requirements.txt
+++ /dev/null
@@ -1 +0,0 @@
-python-dotenv~=1.0
diff --git a/templates/drive_alert/Dockerfile b/templates/drive_alert/Dockerfile
deleted file mode 100644
index aed67038..00000000
--- a/templates/drive_alert/Dockerfile
+++ /dev/null
@@ -1,6 +0,0 @@
-FROM pathwaycom/pathway:latest
-WORKDIR /app
-COPY . .
-EXPOSE 8080
-
-CMD ["python", "app.py"]
diff --git a/templates/drive_alert/README.md b/templates/drive_alert/README.md
deleted file mode 100644
index 6ee6d6de..00000000
--- a/templates/drive_alert/README.md
+++ /dev/null
@@ -1,134 +0,0 @@
-# Pathway Live Data Framework + LLM + Slack notification: RAG App with real-time alerting when answers change in documents
-
-Microservice for a context-aware alerting ChatGPT assistant.
-
-This demo is very similar to the `alert` example, the only difference is the data source (Google Drive)
-For the demo, alerts are sent to Slack (you need to provide `slack_alert_channel_id` and `slack_alert_token`),
-you can either put these env variables in .env file,
-or create env variables in the terminal (i.e. export in bash).
-
-The program then starts a REST API endpoint serving queries about Google Docs stored in a
-Google Drive folder.
-
-We can create notifications by asking from Streamlit or sending query to API stating we want to be notified.
-One example would be `Tell me and alert about the start date of the campaign for Magic Cola`
-
-## How Does It Work?
-
-First, Pathway Live Data Framework connects to Google Drive, extracts all documents, splits them into chunks, turns them into
-vectors using OpenAI embedding service, and store in a nearest neighbor index.
-
-Each query text is first turned into a vector, then relevant document chunks are found
-using the nearest neighbor index. A prompt is built from the relevant chunk
-and sent to the OpenAI GPT3.5 chat service for processing and answering.
-
-After an initial answer is provided, Pathway Live Data Framework monitors changes to documents and selectively
-re-triggers potentially affected queries. If the new answer is significantly different from
-the previously presented one, a new notification is created.
-
-## How to run the project
-
-Before running the app, you will need to give the app access to the Google Drive folder, we follow the steps below.
-
-In order to access files on your Google Drive from the Pathway Live Data Framework app, you will need a Google Cloud project and a service user.
-
-### Create a new project in the Google API console:
-
-- Go to [https://console.cloud.google.com/projectcreate](https://console.cloud.google.com/projectcreate) and create new project
-- Enable Google Drive API by going to [https://console.cloud.google.com/apis/library/drive.googleapis.com](https://console.cloud.google.com/apis/library/drive.googleapis.com), make sure the newly created project is selected in the top left corner
-- Configure consent screen:
- - Go to [https://console.cloud.google.com/apis/credentials/consent](https://console.cloud.google.com/apis/credentials/consent)
- - If using a private Gmail, select "External", and go next.
- - Fill required parameters: application name, user support, and developer email (your email is fine)
- - On the next screen click "Add or remove scopes" search for "drive.readonly" and select this scope
- - Save and click through other steps
-- Create service user:
-
- - Go to [https://console.cloud.google.com/apis/credentials](https://console.cloud.google.com/apis/credentials)
- - Click "+ Create credentials" and create a service account
- - Name the service user and click through the next steps
-- Generate service user key:
- - Once more go to [https://console.cloud.google.com/apis/credentials](https://console.cloud.google.com/apis/credentials) and click on your newly created user (under Service Accounts)
- - Go to "Keys", click "Add key" -> "Create new key" -> "JSON"
-
- A JSON file will be saved to your computer.
-
-Rename this JSON file to `secrets.json` and put it under `templates/drive_alert` next to `app.py` so that it is easily reachable from the app.
-
-You can now share desired Google Drive resources with the created user.
-Note the email ending with `gserviceaccount.com` we will share the folder with this email.
-
-Once you've done it, you will need an ID of some file or directory. You can obtain it manually by right-clicking on the file -> share -> copy link. It will be part of the URL.
-
-[https://drive.google.com/file/d/[FILE_ID]/view?usp=drive_link](https://drive.google.com/file/d/%5BFILE_ID%5D/view?usp=drive_link)
-
-For folders,
-First, right-click on the folder and click share, link will be of the format: [https://drive.google.com/drive/folders/[folder_id]?usp=drive_link](https://drive.google.com/drive/folders/%7Bfolder_id%7D?usp=drive_link)
-Copy the folder_id from the URL.
-Second, click on share and share the folder with the email ending with `gserviceaccount.com`
-
-### Setup Slack notifications:
-
-For this demo, Slack notifications are optional and notifications will be printed if no Slack API keys are provided. See: [Slack Apps](https://api.slack.com/apps) and [Getting a token](https://api.slack.com/tutorials/tracks/getting-a-token).
-Your Slack application will need at least `chat:write.public` scope enabled.
-
-### Setup environment:
-Set your env variables in the .env file placed in this directory.
-
-```bash
-OPENAI_API_KEY=sk-...
-SLACK_ALERT_CHANNEL_ID= # If unset, alerts will be printed to the terminal
-SLACK_ALERT_TOKEN=
-FILE_OR_DIRECTORY_ID= # file or folder ID that you want to track that we have retrieved earlier
-GOOGLE_CREDS=./secrets.json # Default location of Google Drive authorization secrets
-PATHWAY_PERSISTENT_STORAGE= # Set this variable if you want to use caching
-```
-
-### Run with Docker
-
-To run jointly the Alert pipeline and a simple UI execute:
-
-```bash
-docker compose up --build
-```
-
-Then, the UI will run at http://0.0.0.0:8501 by default. You can access it by following this URL in your web browser.
-
-The `docker-compose.yml` file declares a [volume bind mount](https://docs.docker.com/reference/cli/docker/container/run/#volume) that makes changes to files under `data/` made on your host computer visible inside the docker container. The files in `data/live` are indexed by the pipeline - you can paste new files there and they will impact the computations.
-
-### Run manually
-
-Alternatively, you can run each service separately.
-
-Make sure you have installed poetry dependencies with `--extras unstructured`.
-```bash
-poetry install --with examples --extras unstructured
-```
-
-Then run:
-```bash
-poetry run python app.py
-```
-
-If all dependencies are managed manually rather than using poetry, you can alternatively use:
-```bash
-python app.py
-```
-
-To run the Streamlit UI, run:
-```bash
-streamlit run ui/server.py --server.port 8501 --server.address 0.0.0.0
-```
-
-### Querying the pipeline
-
-To create alerts, you can call the REST API:
-
-```bash
-curl --data '{
- "user": "user",
- "query": "When does the magic cola campaign start? Alert me if the start date changes."
-}' http://localhost:8080/ | jq
-```
-
-or access the Streamlit UI at `0.0.0.0:8501`.
diff --git a/templates/drive_alert/__init__.py b/templates/drive_alert/__init__.py
deleted file mode 100644
index 05656682..00000000
--- a/templates/drive_alert/__init__.py
+++ /dev/null
@@ -1,3 +0,0 @@
-from .app import run
-
-__all__ = ["run"]
diff --git a/templates/drive_alert/app.py b/templates/drive_alert/app.py
deleted file mode 100644
index 4fa47d04..00000000
--- a/templates/drive_alert/app.py
+++ /dev/null
@@ -1,301 +0,0 @@
-"""
-Microservice for a context-aware alerting ChatGPT assistant.
-
-This demo is very similar to the `alert` example, the only difference is the data source (Google Drive)
-For the demo, alerts are sent to Slack (you need to provide `slack_alert_channel_id` and `slack_alert_token`),
-you can either put these env variables in .env file under llm-app directory,
-or create env variables in the terminal (i.e. export in bash).
-
-The program then starts a REST API endpoint serving queries about Google Docs stored in a
-Google Drive folder.
-
-We can create notifications by asking from Streamlit or sending query to API stating we want to be notified.
-One example would be `Tell me and alert about the start date of the campaign for Magic Cola`
-
-How Does It Work?
-First, Pathway connects to Google Drive, extracts all documents, splits them into chunks, turns them into
-vectors using OpenAI embedding service, and store in a nearest neighbor index.
-
-Each query text is first turned into a vector, then relevant document chunks are found
-using the nearest neighbor index. A prompt is built from the relevant chunk
-and sent to the OpenAI GPT3.5 chat service for processing and answering.
-
-After an initial answer is provided, Pathway monitors changes to documents and selectively
-re-triggers potentially affected queries. If the new answer is significantly different from
-the previously presented one, a new notification is created.
-
-Please check the README.md in this directory for how-to-run instructions.
-"""
-
-import asyncio
-import os
-
-import dotenv
-import pathway as pw
-from pathway.stdlib.ml.index import KNNIndex
-from pathway.xpacks.llm.embedders import OpenAIEmbedder
-from pathway.xpacks.llm.llms import OpenAIChat, prompt_chat_single_qa
-from pathway.xpacks.llm.parsers import UnstructuredParser
-from pathway.xpacks.llm.splitters import TokenCountSplitter
-
-# To use advanced features with Pathway Live Data Framework Scale, get your free license key from
-# https://pathway.com/features and paste it below.
-# To use Pathway Live Data Framework Community, comment out the line below.
-pw.set_license_key("demo-license-key-with-telemetry")
-
-dotenv.load_dotenv()
-
-
-class DocumentInputSchema(pw.Schema):
- doc: str
-
-
-class QueryInputSchema(pw.Schema):
- query: str
- user: str
-
-
-# Helper Functions
-@pw.udf
-def build_prompt(documents, query):
- docs_str = "\n".join(
- [f"Doc-({idx}) -> {doc}" for idx, doc in enumerate(documents[::-1])]
- )
- prompt = f"""Given a set of documents, answer user query. If answer is not in docs, say it cant be inferred.
-
-Docs: {docs_str}
-Query: '{query}'
-Final Response:"""
- return prompt
-
-
-@pw.udf
-def build_prompt_check_for_alert_request_and_extract_query(query: str) -> str:
- prompt = f"""Evaluate the user's query and identify if there is a request for notifications on answer alterations:
- User Query: '{query}'
-
- Respond with 'Yes' if there is a request for alerts, and 'No' if not,
- followed by the query without the alerting request part.
-
- Examples:
- "Tell me about windows in Pathway" => "No. Tell me about windows in Pathway"
- "Tell me and alert about windows in Pathway" => "Yes. Tell me about windows in Pathway"
- """
- return prompt
-
-
-@pw.udf
-def split_answer(answer: str) -> tuple[bool, str]:
- alert_enabled = "yes" in answer[:3].lower()
- true_query = answer[3:].strip(' ."')
- return alert_enabled, true_query
-
-
-def build_prompt_compare_answers(new: str, old: str) -> str:
- prompt = f"""
- Are the two following responses deviating?
- Answer with Yes or No.
-
- First response: "{old}"
-
- Second response: "{new}"
- """
- return prompt
-
-
-def make_query_id(user, query) -> str:
- return str(hash(query + user))
-
-
-@pw.udf
-def construct_notification_message(query: str, response: str) -> str:
- return f'New response for question "{query}":\n{response}'
-
-
-@pw.udf
-def construct_message(response, alert_flag, metainfo=None):
- if alert_flag:
- if metainfo:
- response += "\n" + str(metainfo)
- return response + "\n\n🔔 Activated"
- return response
-
-
-def decision_to_bool(decision: str) -> bool:
- return "yes" in decision.lower()
-
-
-def run(
- *,
- object_id=os.environ.get("FILE_OR_DIRECTORY_ID", ""),
- api_key: str = os.environ.get("OPENAI_API_KEY", ""),
- host: str = os.environ.get("PATHWAY_REST_CONNECTOR_HOST", "0.0.0.0"),
- port: int = int(os.environ.get("PATHWAY_REST_CONNECTOR_PORT", "8080")),
- embedder_locator: str = "text-embedding-ada-002",
- embedding_dimension: int = 1536,
- model_locator: str = "gpt-3.5-turbo",
- max_tokens: int = 400,
- temperature: float = 0.0,
- slack_alert_channel_id=os.environ.get("SLACK_ALERT_CHANNEL_ID", ""),
- slack_alert_token=os.environ.get("SLACK_ALERT_TOKEN", ""),
- service_user_credentials_file=os.environ.get(
- "GOOGLE_CREDS", "templates/drive_alert/secrets.json"
- ),
- **kwargs,
-):
- # Part I: Build index
- embedder = OpenAIEmbedder(
- api_key=api_key,
- model=embedder_locator,
- retry_strategy=pw.asynchronous.FixedDelayRetryStrategy(),
- cache_strategy=pw.asynchronous.DefaultCache(),
- )
-
- # We start building the computational graph. Each pathway variable represents a
- # dynamically changing table.
-
- # The files table contains contents of documents in Google Drive.
- # Pathway automatically tracks changes to files and propagates these changes through
- # following computations.
- # Other Pathway connectors can be used as well - notably:
- # - pw.io.fs.read to load and track changes to the local drive and
- # - pw.io.s3.read to use an S3-compatible storage
- files = pw.io.gdrive.read(
- object_id=object_id,
- service_user_credentials_file=service_user_credentials_file,
- refresh_interval=30, # interval between fetch operations in seconds, lower this for more responsiveness
- )
- parser = UnstructuredParser()
- documents = files.select(texts=parser(pw.this.data))
- documents = documents.flatten(pw.this.texts)
- documents = documents.select(texts=pw.this.texts[0])
-
- splitter = TokenCountSplitter()
- documents = documents.select(
- chunks=splitter(pw.this.texts, min_tokens=40, max_tokens=120)
- )
- documents = documents.flatten(pw.this.chunks)
- documents = documents.select(chunk=pw.this.chunks[0])
-
- enriched_documents = documents + documents.select(data=embedder(pw.this.chunk))
-
- # The index is updated each time a file changes.
- index = KNNIndex(
- enriched_documents.data, enriched_documents, n_dimensions=embedding_dimension
- )
-
- # Part II: receive queries, detect intent and prepare cleaned query
-
- # The rest_connector returns a table of all queries under processing
- query, response_writer = pw.io.http.rest_connector(
- host=host,
- port=port,
- schema=QueryInputSchema,
- autocommit_duration_ms=50,
- delete_completed_queries=False,
- )
-
- model = OpenAIChat(
- api_key=api_key,
- model=model_locator,
- temperature=temperature,
- max_tokens=max_tokens,
- retry_strategy=pw.asynchronous.FixedDelayRetryStrategy(),
- cache_strategy=pw.asynchronous.DefaultCache(),
- )
-
- # Pre-process the queries:
- # - detect alerting intent
- # - then embed the query for nearest neighbor retrieval
- query += query.select(
- prompt=build_prompt_check_for_alert_request_and_extract_query(query.query)
- )
- query += query.select(
- tupled=split_answer(
- model(
- prompt_chat_single_qa(pw.this.prompt),
- max_tokens=100,
- )
- ),
- )
- query = query.select(
- pw.this.user,
- alert_enabled=pw.this.tupled[0],
- query=pw.this.tupled[1],
- )
-
- query += query.select(
- data=embedder(pw.this.query),
- query_id=pw.apply(make_query_id, pw.this.user, pw.this.query),
- )
-
- # Part III: respond to queries
-
- # The context is a dynamic table: Pathway updates it each time:
- # - a new query arrives
- # - a source document is changed significantly enough to change the set of
- # nearest neighbors
- query_context = query + index.get_nearest_items(query.data, k=3).select(
- documents_list=pw.this.chunk
- ).with_universe_of(query)
-
- # then we answer the queries using retrieved documents
- prompt = query_context.select(
- pw.this.query_id,
- pw.this.query,
- pw.this.alert_enabled,
- prompt=build_prompt(pw.this.documents_list, pw.this.query),
- )
-
- responses = prompt.select(
- pw.this.query_id,
- pw.this.query,
- pw.this.alert_enabled,
- response=model(
- prompt_chat_single_qa(pw.this.prompt),
- ),
- )
-
- output = responses.select(
- result=construct_message(pw.this.response, pw.this.alert_enabled)
- )
-
- # and send the answers back to the asking users
- response_writer(output)
-
- # Part IV: send alerts about responses which changed significantly.
-
- # However, for the queries with alerts the processing continues
- # whenever the set of documents retrieved for a query changes,
- # the table of responses is updated.
- responses = responses.filter(pw.this.alert_enabled)
-
- def acceptor(new: str, old: str) -> bool:
- if new == old:
- return False
-
- # TODO: clean after udfs can be used as common functions
- prompt = [dict(role="system", content=build_prompt_compare_answers(new, old))]
- decision = asyncio.run(model.__wrapped__(prompt, max_tokens=20))
- return decision_to_bool(decision)
-
- # Each update is compared with the previous one for deduplication
- deduplicated_responses = pw.stateful.deduplicate(
- responses,
- col=responses.response,
- acceptor=acceptor,
- instance=responses.query_id,
- )
-
- # Significant alerts are sent to the user
- alerts = deduplicated_responses.select(
- message=construct_notification_message(pw.this.query, pw.this.response)
- )
- pw.io.slack.send_alerts(alerts.message, slack_alert_channel_id, slack_alert_token)
-
- # Finally, we execute the computation graph
- pw.run(monitoring_level=pw.MonitoringLevel.NONE)
-
-
-if __name__ == "__main__":
- run()
diff --git a/templates/drive_alert/docker-compose.yml b/templates/drive_alert/docker-compose.yml
deleted file mode 100644
index 55f5b1c5..00000000
--- a/templates/drive_alert/docker-compose.yml
+++ /dev/null
@@ -1,19 +0,0 @@
-version: "3.8"
-services:
- pathway:
- build:
- context: .
- ports:
- - "8080:8080"
- environment:
- OPENAI_API_KEY:
- PATHWAY_PERSISTENT_STORAGE:
- streamlit_ui:
- depends_on:
- - pathway
- build:
- context: ./ui
- ports:
- - "8501:8501"
- environment:
- PATHWAY_REST_CONNECTOR_HOST: "pathway"
diff --git a/templates/drive_alert/drive_alert_demo.gif b/templates/drive_alert/drive_alert_demo.gif
deleted file mode 100644
index 62c432ee..00000000
Binary files a/templates/drive_alert/drive_alert_demo.gif and /dev/null differ
diff --git a/templates/drive_alert/ui/Dockerfile b/templates/drive_alert/ui/Dockerfile
deleted file mode 100644
index 78e21216..00000000
--- a/templates/drive_alert/ui/Dockerfile
+++ /dev/null
@@ -1,11 +0,0 @@
-FROM python:3.11
-
-WORKDIR /app
-
-RUN pip install streamlit python-dotenv
-
-COPY . .
-
-EXPOSE 8501
-
-CMD ["streamlit", "run", "server.py", "--server.port", "8501", "--server.address", "0.0.0.0"]
diff --git a/templates/drive_alert/ui/server.py b/templates/drive_alert/ui/server.py
deleted file mode 100644
index ff6cd83e..00000000
--- a/templates/drive_alert/ui/server.py
+++ /dev/null
@@ -1,69 +0,0 @@
-import os
-
-import requests
-import streamlit as st
-from dotenv import load_dotenv
-
-api_host = "localhost"
-api_port = 8080
-
-load_dotenv()
-api_host = os.environ.get("PATHWAY_REST_CONNECTOR_HOST", "127.0.0.1")
-api_port = int(os.environ.get("PATHWAY_REST_CONNECTOR_PORT", 8080))
-
-with st.sidebar:
- st.markdown("## How to query your data\n")
- st.markdown(
- """Enter your question, optionally
-ask to be alerted.\n"""
- )
- st.markdown(
- "Example: 'When does the magic cola campaign start? Alert me if the start date changes'",
- )
- st.markdown(
- """[View the source code on GitHub](
-https://github.com/pathwaycom/llm-app/templates/drive_alert/app.py)"""
- )
- st.markdown("## Current Alerts:\n")
-
-
-# Streamlit UI elements
-st.title("Google Drive notifications with LLM")
-
-prompt = st.text_input("How can I help you today?")
-# prompt = st.chat_input("How can I help you today?")
-# Initialize chat history
-if "messages" not in st.session_state:
- st.session_state.messages = []
-
-# Display chat messages from history on app rerun
-for message in st.session_state.messages:
- with st.chat_message(message["role"]):
- st.markdown(message["content"])
-
-
-# React to user input
-if prompt:
- # Display user message in chat message container
- with st.chat_message("user"):
- st.markdown(prompt)
-
- # Add user message to chat history
- st.session_state.messages.append({"role": "user", "content": prompt})
-
- for message in st.session_state.messages:
- if message["role"] == "user":
- st.sidebar.text(f"📩 {message['content']}")
-
- url = f"http://{api_host}:{api_port}/"
- data = {"query": prompt, "user": "user"}
-
- response = requests.post(url, json=data)
-
- if response.status_code == 200:
- response = response.json()
- with st.chat_message("assistant"):
- st.markdown(response)
- st.session_state.messages.append({"role": "assistant", "content": response})
- else:
- st.error(f"Failed to send data. Status code: {response.status_code}")
diff --git a/templates/multimodal_rag/.env.example b/templates/multimodal_rag/.env.example
deleted file mode 100644
index b82e13a2..00000000
--- a/templates/multimodal_rag/.env.example
+++ /dev/null
@@ -1 +0,0 @@
-OPENAI_API_KEY="sk-***"
diff --git a/templates/multimodal_rag/Dockerfile b/templates/multimodal_rag/Dockerfile
deleted file mode 100644
index 2e2ca8a6..00000000
--- a/templates/multimodal_rag/Dockerfile
+++ /dev/null
@@ -1,16 +0,0 @@
-FROM pathwaycom/pathway:latest
-
-WORKDIR /app
-
-RUN apt-get update \
- && apt-get install -y python3-opencv tesseract-ocr-eng \
- && rm -rf /var/lib/apt/lists/* /var/cache/apt/archives/*
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-EXPOSE 8000
-
-CMD ["python", "app.py"]
diff --git a/templates/multimodal_rag/README.md b/templates/multimodal_rag/README.md
deleted file mode 100644
index 650974f9..00000000
--- a/templates/multimodal_rag/README.md
+++ /dev/null
@@ -1,281 +0,0 @@
-
-
-# Multimodal RAG with Pathway Live Data Framework: Process your Financial Reports and Tables with GPT-4o
-
-## **Overview**
-
-This app template showcases how you can build a multimodal RAG application and launch a document processing pipeline that utilizes a vision language model like the `GPT-4o` for parsing. The Pathway Live Data Framework processes unstructured financial documents within specified directories, extracting and storing the information in a scalable in-memory index. This index is optimized for dynamic RAG, ensuring that search results are continuously updated as documents are modified or new files are added.
-
-Using this approach, you can make your AI application run in permanent connection with your drive, in sync with your documents which include visually formatted elements: tables, charts, images, etc.
-
-We specifically use `GPT-4o` to improve the table data extraction accuracy and demonstrate how this approach outperforms the industry-standard RAG toolkits.
-
-In this showcase, we focused on the finance domain because financial documents often rely heavily on tables in various forms. This showcase highlights the limitations of traditional RAG setups, which struggle to answer questions based on table data. By contrast, our multimodal RAG approach excels in extracting accurate information from tables.
-
-The following GIF shows a snippet from our experiments:
-
-
-
-If you want to skip the explanations, you can directly find the code [here](#Running-the-app).
-
-## Table of contents
-
-This includes the technical details to the steps to create a REST Endpoint to run the dynamic RAG application via Docker and modify it for your use-cases.
-
-- [Overview](#Overview)
-- [Architecture](#Architecture)
-- [Pipeline Organization](#Pipeline-Organization)
-- [Customizing the pipeline](#Customizing-the-pipeline)
-- [Running the app](#Running-the-app)
-- [Conclusion](#Conclusion)
-
-
-## Architecture
-
-We use `GPT-4o` in two separate places in the flow of data:
-- Extracting and understanding the tables inside the PDF
-- Answering questions with the retrieved context
-
-
-
-The architecture of this multimodal RAG application involves several key components:
-
-- **Data Ingestion**: Ingests data from various sources like local folders, Google Drive, or SharePoint.
-- **Document Parsing and Embedding**: Utilizes `DoclingParser` for parsing documents and `OpenAIEmbedder` for embedding text. This includes handling and processing images within PDFs.
-- **Document Store**: The `DocumentStoreServer` indexes parsed documents and retrieves relevant chunks for answering questions.
-- **Question Answering**: Uses the `BaseRAGQuestionAnswerer` class to call `GPT-4o` for generating responses based on the retrieved context.
-- **Server Setup**: Sets up a REST endpoint to serve the RAG application.
-
-For more advanced RAG options, make sure to check out [rerankers](https://pathway.com/developers/api-docs/pathway-xpacks-llm/rerankers) and the [adaptive rag example](../adaptive_rag/).
-
-
-## Pipeline Organization
-
-This folder contains several objects:
-- `app.py`, the main application code using Pathway Live Data Framework and written in Python. It reads configuration from `app.yaml`, and runs a server answering queries to the defined pipeline.
-- `app.yaml`, YAML configuration file, that defines components of the pipeline.
-- `Dockerfile`, the Docker configuration for running the pipeline in a container. It includes instructions for installing dependencies and setting up the runtime environment.
-- `requirements.txt`, the dependencies for the pipeline. This file can be passed to `pip install -r requirements.txt` to install everything needed to launch the pipeline locally.
-- `.env`, a short environment variables configuration file where the OpenAI key must be stored. This file ensures secure handling of sensitive information.
-- `data/`, a folder with exemplary files that can be used for test runs. It includes sample financial documents to demonstrate the pipeline's capabilities.
-
-## Customizing the pipeline
-
-The code can be modified by changing the `app.yaml` configuration file. To read more about YAML files used in Pathway templates, read [our guide](https://pathway.com/developers/user-guide/llm-xpack/yaml-templates).
-
-In the `app.yaml` file we define:
-- input connectors
-- LLM
-- embedder
-- index
-and any of these can be replaced or, if no longer needed, removed. For components that can be used check
-Pathway [LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview), or you can implement your own.
-
-You can also check our other templates - [Question Answering RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag),
-[Multimodal RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/multimodal_rag) or
-[Private RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/private_rag). As all of these only differ
-in the YAML configuration file, you can also use them as an inspiration for your custom pipeline.
-
-Here some examples of what can be modified.
-
-### LLM Model
-
-This template by default uses two llm models - GPT-4.1-mini for answering queries and GPT-4o for parsing tables and images.
-
-You can replace either of them with other Open AI models, like GPT-4.1 or GPT-5, but keep in mind that the model used for parsing needs to support image input.
-You can find the whole list on their [models page](https://platform.openai.com/docs/models).
-
-To change the model of the answering llm, you simply need to change the `model` in the `$llm` variable to the one you want to use, e.g. to use `GPT-5` set:
-```yaml
-$llm: !pw.xpacks.llm.llms.OpenAIChat
- model: "gpt-5"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache {}
- temperature: 0
- capacity: 8
-```
-
-You can also use different provider, by using different class from [Pathway Live Data Framework LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview),
-e.g. here is configuration for locally run Mistral model with Ollama.
-
-```yaml
-$llm: !pw.xpacks.llm.llms.LiteLLMChat
- model: "ollama/mistral"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DiskCache
- temperature: 0
- top_p: 1
- api_base: "http://localhost:11434"
-```
-
-You can also change LLM used for parsing in the same way, by changing `!parsing_llm` in `app.yaml`, just keep in mind to use a multimodal model.
-
-### Webserver
-
-You can configure the host and the port of the webserver.
-Here is the default configuration:
-```yaml
-host: "0.0.0.0"
-port: 8000
-```
-
-### Cache
-
-You can configure whether you want to enable cache or persistence, to avoid repeated API accesses, and where the cache is stored.
-Default values:
-```yaml
-persistence_mode: !pw.PersistenceMode.UDF_CACHING
-persistence_backend: !pw.persistence.Backend.filesystem
- path: ".Cache"
-```
-
-### Data sources
-
-You can configure the data sources by changing `$sources` in `app.yaml`.
-You can add as many data sources as you want. You can have several sources of the same kind, for instance, several local sources from different folders.
-The sections below describe how to configure local, Google Drive and Sharepoint source, and you can check the examples of YAML configuration in our [user guide](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples/). While these are not described in this Section, you can also use any input [connector](https://pathway.com/developers/user-guide/connecting-to-data/connectors) from Pathway package.
-
-By default, the app uses a local data source to read documents from the `data` folder.
-
-
-
-## Running the app
-
-> Note: Recommended way of running the Pathway Live Data Framework on Windows is Docker, refer to [Running with the Docker section](#with-docker).
-
-First, make sure to install the requirements by running:
-
-```bash
-pip install -r requirements.txt -U
-```
-Then, create a `.env` file in this directory and put your API key with `OPENAI_API_KEY=sk-...`, or add the `api_key` argument to `OpenAIChat` and `OpenAIEmbedder`.
-
-Then, simply run with `python app.py` in this directory.
-
-### With Docker
-
-First, make sure to have your OpenAI API key in the environment, you can create a `.env` file as mentioned above, or specify the `api_key` argument in the `OpenAIChat` and `OpenAIEmbedder`.
-
-In order to let the pipeline get updated with each change in local files, you need to mount the `data` folder inside the docker. The following commands show how to do that.
-
-The following commands will:
-- mount the `data` folder inside the Docker
-- build the image
-- run the app and expose the port `8000`.
-
-You can omit the ```-v `pwd`/data:/app/data``` part if you are not using local files as a data source.
-
-```bash
-# Make sure you are in the right directory.
-cd templates/multimodal_rag/
-
-# Build the image in this folder
-docker build -t rag .
-
-# Run the image, mount the `data` folder into image and expose the port `8000`
-docker run -v `pwd`/data:/app/data -p 8000:8000 rag
-```
-
-
-## Querying the pipeline
-
-Follow the [steps below](#running-the-app) to set up the service. This will create a REST endpoint on your selected host and port, running a service that is connected to your file folder, and ready to answer your questions. There are no extra dependencies.
-
-In this demo, we run the service on localhost (`0.0.0.0:8000`). You can connect your own front end or application to this endpoint. Here, we test the service with `curl`.
-
-First, let's check the files contained in your folder are currently indexed:
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/list_documents' -H 'accept: */*' -H 'Content-Type: application/json'
-```
-
-This will return the list of files e.g. if you start with the [data folder](./data) provided in the demo, the answer will be as follows:
-> `[{"modified_at": 1715765613, "owner": "berke", "path": "data/20230203_alphabet_10K.pdf", "seen_at": 1715768762}]`
-
-In the default app setup, the connected folder is a local file folder. You can add more folders and file sources, such as [Google Drive](https://pathway.com/developers/user-guide/connectors/gdrive-connector#google-drive-connector) or [Sharepoint](https://pathway.com/developers/user-guide/connecting-to-data/connectors#tutorials), by adding a line of code to the template.
-
-If you now add or remove files from your connected folder, you can repeat the request and see the index file list has been updated automatically. You can look into the logs of the service to see the progress of the indexing of new and modified files. PDF files of 100 pages should normally take under 10 seconds to sync, and the indexing parallelizes if multiple files are added at a single time.
-
-Now, let's ask a question from one of the tables inside the report. In our tests, regular RAG applications struggled with the tables and couldn't answer to this question correctly.
-
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/answer' -H 'accept: */*' -H 'Content-Type: application/json' -d '{
- "prompt": "How much was Operating lease cost in 2021?"
-}'
-```
-> `{"response": "$2,699 million"}`
-
-This response was correct thanks to the initial LLM parsing step.
-When we check the context that is sent to the LLM, we see that the Pathway Live Data Framework included the table in the context where as other RAG applications failed to include the table.
-
-
-Let's try another one,
-
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/answer' -H 'accept: */*' -H 'Content-Type: application/json' -d '{
- "prompt": "What is the operating income for the fiscal year of 2022?"
-}'
-```
-> `{"response": "$74,842 million"}`
-
-Another example, let's ask a question that can be answered from the table on the 48th page of the PDF.
-
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/answer' -H 'accept: */*' -H 'Content-Type: application/json' -d '{
- "prompt": "How much was Marketable securities worth in 2021 in the consolidated balance sheets?"
-}'
-```
-> `{"response": "$118,704 million"}`
-
-
-Now, let's also fetch the context documents,
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/answer' -H 'accept: */*' -H 'Content-Type: application/json' -d '{
- "prompt": "How much was Operating lease cost in 2021?", "return_context_docs": true
-}'
-```
-> `{"response": "$2,699 million", "context_docs": [{"text": "..."}, ...]`
-
-Looking good!
-
-## Conclusion
-
-This showcase demonstrates setting up a powerful RAG pipeline with advanced table parsing capabilities, unlocking new finance use cases. While we've only scratched the surface, there's more to explore:
-
-- Re-ranking: Prioritize the most relevant results for your specific query.
-- Knowledge graphs: Leverage relationships between entities to improve understanding.
-- Hybrid indexing: Combine different indexing strategies for optimal retrieval.
-- Adaptive reranking: Iteratively enlarge the context for optimal accuracy, see [our example](../adaptive_rag/README.md).
-Stay tuned for future examples exploring these advanced techniques with Pathway Live Data Framework!
-
-RAG applications are most effective when tailored to your specific use case. Here's how you can customize yours:
-
-- Document parsers and splitters: Fine-tune how documents are processed and broken down for analysis.
-- Indexing and retrieval strategies: Choose the most efficient approach for your data and search needs.
-- User Interface (UI): Design a user-friendly interface that caters to your end users' workflows.
-
-Ready to Get Started?
-
-Let's discuss how we can help you build a powerful, customized RAG application. [Reach us here to talk or request a demo!](https://pathway.com/solutions/slides-ai-search?modal=requestdemo)
-
-
-## Quick Links:
-
-- [Pathway Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
-- [Pathway Live Data Framework App Templates](https://pathway.com/developers/templates)
-- [Discord Community of Pathway Live Data Framework](https://discord.gg/pathway)
-- [Pathway Issue Tracker](https://github.com/pathwaycom/pathway/issues)
-- [End-to-end dynamic RAG pipeline with Pathway](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
-- [Using Pathway Live Data Framework as a retriever with LlamaIndex](https://docs.llamaindex.ai/en/stable/examples/retrievers/pathway_retriever/)
-
-Make sure to drop a "Star" to our repositories if you found this resource helpful!
diff --git a/templates/multimodal_rag/app.py b/templates/multimodal_rag/app.py
deleted file mode 100644
index 314342e9..00000000
--- a/templates/multimodal_rag/app.py
+++ /dev/null
@@ -1,76 +0,0 @@
-import logging
-from warnings import warn
-
-import pathway as pw
-from dotenv import load_dotenv
-from pathway.xpacks.llm.question_answering import SummaryQuestionAnswerer
-from pathway.xpacks.llm.servers import QASummaryRestServer
-from pydantic import BaseModel, ConfigDict, InstanceOf
-
-# To use advanced features with Pathway Live Data Framework Scale, get your free license key from
-# https://pathway.com/features and paste it below.
-# To use Pathway Live Data Framework Community, comment out the line below.
-pw.set_license_key("demo-license-key-with-telemetry")
-
-logging.basicConfig(
- level=logging.INFO,
- format="%(asctime)s %(name)s %(levelname)s %(message)s",
- datefmt="%Y-%m-%d %H:%M:%S",
-)
-
-load_dotenv()
-
-
-class App(BaseModel):
- question_answerer: InstanceOf[SummaryQuestionAnswerer]
- host: str = "0.0.0.0"
- port: int = 8000
-
- with_cache: bool | None = None # deprecated
- persistence_backend: pw.persistence.Backend | None = None
- persistence_mode: pw.PersistenceMode | None = pw.PersistenceMode.UDF_CACHING
- terminate_on_error: bool = False
-
- def run(self) -> None:
- server = QASummaryRestServer( # noqa: F841
- self.host, self.port, self.question_answerer
- )
-
- if self.persistence_mode is None:
- if self.with_cache is True:
- warn(
- "`with_cache` is deprecated. Please use `persistence_mode` instead.",
- DeprecationWarning,
- )
- persistence_mode = pw.PersistenceMode.UDF_CACHING
- else:
- persistence_mode = None
- else:
- persistence_mode = self.persistence_mode
-
- if persistence_mode is not None:
- if self.persistence_backend is None:
- persistence_backend = pw.persistence.Backend.filesystem("./Cache")
- else:
- persistence_backend = self.persistence_backend
- persistence_config = pw.persistence.Config(
- persistence_backend,
- persistence_mode=persistence_mode,
- )
- else:
- persistence_config = None
-
- pw.run(
- persistence_config=persistence_config,
- terminate_on_error=self.terminate_on_error,
- monitoring_level=pw.MonitoringLevel.NONE,
- )
-
- model_config = ConfigDict(extra="forbid", arbitrary_types_allowed=True)
-
-
-if __name__ == "__main__":
- with open("app.yaml") as f:
- config = pw.load_yaml(f)
- app = App(**config)
- app.run()
diff --git a/templates/multimodal_rag/app.yaml b/templates/multimodal_rag/app.yaml
deleted file mode 100644
index e37589f4..00000000
--- a/templates/multimodal_rag/app.yaml
+++ /dev/null
@@ -1,125 +0,0 @@
-# This YAML configuration file is used to set up and configure the Multimodal RAG template.
-# It defines various components such as data sources, language models, embedders, splitters, parsers, and retrievers.
-# Each section is configured to specify how the template should process and handle data for generating responses.
-# You can learn more about the YAML syntax here: https://pathway.com/developers/templates/configure-yaml
-
-
-
-# $sources defines the data sources used to read the data which will be indexed in the RAG.
-# You can learn more how to configure data sources here:
-# https://pathway.com/developers/templates/yaml-examples/data-sources-examples
-
-$sources:
- # File System connector, reading data locally.
- - !pw.io.fs.read
- path: data
- format: binary
- with_metadata: true
-
- # Uncomment to use the SharePoint connector
- # - !pw.xpacks.connectors.sharepoint.read
- # url: $SHAREPOINT_URL
- # tenant: $SHAREPOINT_TENANT
- # client_id: $SHAREPOINT_CLIENT_ID
- # cert_path: sharepointcert.pem
- # thumbprint: $SHAREPOINT_THUMBPRINT
- # root_path: $SHAREPOINT_ROOT
- # with_metadata: true
- # refresh_interval: 30
-
- # Uncomment to use the Google Drive connector
- # - !pw.io.gdrive.read
- # object_id: $DRIVE_ID
- # service_user_credentials_file: gdrive_indexer.json
- # file_name_pattern:
- # - "*.pdf"
- # - "*.pptx"
- # object_size_limit: null
- # with_metadata: true
- # refresh_interval: 30
-
-
-
-# Configures the LLM model settings for generating responses.
-# The list of available Pathway LLM wrappers is available here:
-# https://pathway.com/developers/api-docs/pathway-xpacks-llm/llms
-# You can learn more about those in our documentation:
-# https://pathway.com/developers/templates/rag-customization/llm-chats
-
-$llm: !pw.xpacks.llm.llms.OpenAIChat
- model: "gpt-4.1-mini"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache {}
- temperature: 0
- capacity: 8
- async_mode: "fully_async"
-
-# Specifies the embedder model for converting text into embeddings.
-$embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder
- model: "text-embedding-3-small"
- cache_strategy: !pw.udfs.DefaultCache {}
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy {}
-
-# Defines the llm to be used for parsing images.
-$parsing_llm: !pw.xpacks.llm.llms.OpenAIChat
- model: "gpt-4o"
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache {}
- async_mode: "fully_async"
-
-# Configures the parser for processing and extracting information from documents.
-$parser: !pw.xpacks.llm.parsers.DoclingParser
- multimodal_llm: $parsing_llm
- image_parsing_strategy: "llm"
- table_parsing_strategy: "llm"
- async_mode: "fully_async"
- chunk: false
- cache_strategy: !pw.udfs.DefaultCache {}
-
-# Sets up the splitter for chunking the documents.
-$splitter: !pw.xpacks.llm.splitters.TokenCountSplitter
- max_tokens: 400
-
-# Sets up the retriever factory for indexing and retrieving documents.
-$retriever_factory: !pw.indexing.UsearchKnnFactory
- reserved_space: 1000
- embedder: $embedder
- metric: !pw.indexing.USearchMetricKind.COS
-
-# Manages the storage and retrieval of documents for the RAG template.
-$document_store: !pw.xpacks.llm.document_store.DocumentStore
- docs: $sources
- parser: $parser
- splitter: $splitter
- retriever_factory: $retriever_factory
-
-# Configures the question-answering component using the RAG approach.
-question_answerer: !pw.xpacks.llm.question_answering.BaseRAGQuestionAnswerer
- llm: $llm
- indexer: $document_store
- # You can set the number of documents to be included as the context of the query
- # search_topk: 6
- # You can use your own prompt for querying.
- # For that set prompt_template to string with `{query}` used as a placeholder for the question,
- # and `{context}` as a placeholder for context documents.
- # prompt_template: "Given these documents: {context}, please answer the question: {query}"
-
-# Change host and port of the webserver by uncommenting these lines
-# host: "0.0.0.0"
-# port: 8000
-
-# By default, caching is enabled for UDFs with cache_strategy set.
-# You can disable it by uncommenting the following line.
-# persistence_mode: null
-# You can also set persistence_mode to !pw.PersistenceMode.PERSISTING to enable persistence
-# across restarts.
-# By default, when enabled, Cache is stored in .Cache directory.
-# You can customize the location by uncommenting and modifying the following lines:
-# persistence_backend: !pw.persistence.Backend.filesystem
-# path: ".Cache"
-
-# If `terminate_on_error` is true then the program will terminate whenever any error is encountered.
-# Defaults to false, uncomment the following line if you want to set it to true
-# terminate_on_error: true
diff --git a/templates/multimodal_rag/data/20230203_alphabet_10K.pdf b/templates/multimodal_rag/data/20230203_alphabet_10K.pdf
deleted file mode 100644
index 9a1ec660..00000000
Binary files a/templates/multimodal_rag/data/20230203_alphabet_10K.pdf and /dev/null differ
diff --git a/templates/multimodal_rag/gpt4o.gif b/templates/multimodal_rag/gpt4o.gif
deleted file mode 100644
index db553142..00000000
Binary files a/templates/multimodal_rag/gpt4o.gif and /dev/null differ
diff --git a/templates/multimodal_rag/gpt4o_with_pathway_comparison.gif b/templates/multimodal_rag/gpt4o_with_pathway_comparison.gif
deleted file mode 100644
index a96e0bd2..00000000
Binary files a/templates/multimodal_rag/gpt4o_with_pathway_comparison.gif and /dev/null differ
diff --git a/templates/multimodal_rag/requirements.txt b/templates/multimodal_rag/requirements.txt
deleted file mode 100644
index 2442a906..00000000
--- a/templates/multimodal_rag/requirements.txt
+++ /dev/null
@@ -1,3 +0,0 @@
-pathway[all]
-python-dotenv~=1.0
-mpmath~=1.3
diff --git a/templates/private_rag/Dockerfile b/templates/private_rag/Dockerfile
deleted file mode 100644
index 2e2ca8a6..00000000
--- a/templates/private_rag/Dockerfile
+++ /dev/null
@@ -1,16 +0,0 @@
-FROM pathwaycom/pathway:latest
-
-WORKDIR /app
-
-RUN apt-get update \
- && apt-get install -y python3-opencv tesseract-ocr-eng \
- && rm -rf /var/lib/apt/lists/* /var/cache/apt/archives/*
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-EXPOSE 8000
-
-CMD ["python", "app.py"]
diff --git a/templates/private_rag/README.md b/templates/private_rag/README.md
deleted file mode 100644
index 30bea3e1..00000000
--- a/templates/private_rag/README.md
+++ /dev/null
@@ -1,249 +0,0 @@
-
-
-# Fully private RAG with Pathway Live Data Framework
-
-## **Overview**
-
-Retrieval-Augmented Generation (RAG) is a powerful method for answering questions using a private knowledge database. Ensuring data security is essential, especially for sensitive information like trade secrets, confidential IP, GDPR-protected data, and internal documents. This showcase demonstrates setting up a private RAG pipeline with adaptive retrieval using Pathway Live Data Framework, Mistral, and Ollama. The provided code deploys this adaptive RAG technique with Pathway Live Data Framework, ensuring no API access or data leaves the local machine.
-
-The app utilizes modules under `pathway.xpacks.llm`. The `BaseRAGQuestionAnswerer` class is the foundation for building RAG applications with the Pathway Live Data Framework vector store and xpack components, enabling a quick start with RAG applications.
-
-This example uses `AdaptiveRAGQuestionAnswerer`, an extension of `BaseRAGQuestionAnswerer` with adaptive retrieval. For more on building and deploying RAG applications with Pathway Live Data Framework, including containerization, refer to the demo on question answering.
-
-The application responds to requests at the `/v2/answer` endpoint. The `answer_query` function takes the `pw_ai_queries` table as input, containing prompts and other arguments from the post request. This table's data is used to call the adaptive retrieval logic.
-
-The `AdaptiveRAGQuestionAnswerer` implementation under `pathway.xpacks.llm.question_answering` builds a RAG app with the Pathway Live Data Framework vector store and components. It supports two question answering strategies, short (concise) and long (detailed) responses, set during the post request. It allows LLM agnosticity, giving the freedom to choose between proprietary or open-source LLMs. It adapts the number of chunks used as a context, starting with `n_starting_documents` chunks and increasing until an answer is found.
-
-To learn more about building & deploying RAG applications with Pathway Live Data Framework, including containerization, refer to [demo question answering](../question_answering_rag/README.md).
-
-
-## Table of contents
-
-This includes the technical details to the steps to create a REST Endpoint to run the application via Docker and modify it for your use-cases.
-
-- [Overview](#Overview)
-- [Architecture](#Architecture)
-- [Deploying and using a local LLM](#Deploying-and-using-a-local-LLM)
-- [Running the app](#Running-the-app)
-- [Querying the app/pipeline](#Querying-the-app/pipeline)
-- [Modifying the code](#Modifying-the-code)
-- [Conclusion](#Conclusion)
-
-
-## Architecture
-
-
-
-The architecture consists of two connected technology bricks, which will run as services on your machine:
-- Pathway Live Data Framework brings support for real-time data synchronization pipelines out of the box, and the possibility of secure private document handling with enterprise connectors for synchronizing Sharepoint and Google Drive incrementally. The Pathway Live Data Framework service you'll run performs live document indexing pipeline, and will use Pathway Live Data Framework’s built-in vector store.
-- The language model you use will be a Mistral 7B, which you will locally deploy as an Ollama service. This model was chosen for its performance and compact size.
-
-## Customizing the pipeline
-
-The code can be modified by changing the `app.yaml` configuration file. To read more about YAML files used in Pathway templates, read [our guide](https://pathway.com/developers/templates/configure-yaml).
-
-In the `app.yaml` file we define:
-- input connectors
-- LLM
-- embedder
-- index
-and any of these can be replaced or, if no longer needed, removed. For components that can be used check
-Pathway [LLM xpack](https://pathway.com/developers/user-guide/llm-xpack/overview), or you can implement your own.
-
-You can also check our other templates - [Question Answering RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag),
-[Multimodal RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/multimodal_rag) or
-[Private RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/private_rag). As all of these only differ
-in the YAML configuration file, you can also use them as an inspiration for your custom pipeline.
-
-Here some examples of what can be modified.
-
-### LLM Model
-
-This template is prepared to run by default locally. However, the pipeline is LLM model agnostic, so you can change them to use other locally deployed model, or even
-use LLM model available through API calls. For discussion on models used in this template check [the dedicated Section](#deploying-and-using-a-local-LLM).
-
-### Webserver
-
-You can configure the host and the port of the webserver.
-Here is the default configuration:
-```yaml
-host: "0.0.0.0"
-port: 8000
-```
-
-### Cache
-
-You can configure whether you want to enable cache or persistence, to avoid repeated API accesses, and where the cache is stored.
-Default values:
-```yaml
-persistence_mode: !pw.PersistenceMode.UDF_CACHING
-persistence_backend: !pw.persistence.Backend.filesystem
- path: ".Cache"
-```
-
-### Data sources
-
-You can configure the data sources by changing `$sources` in `app.yaml`.
-You can add as many data sources as you want. You can have several sources of the same kind, for instance, several local sources from different folders.
-The sections below describe how to configure local, Google Drive and Sharepoint source, and you can check the examples of YAML configuration in our [user guide](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples/). While these are not described in this Section, you can also use any input [connector](https://pathway.com/developers/user-guide/connecting-to-data/connectors) from Pathway package.
-
-By default, the app uses a local data source to read documents from the `data` folder.
-
-#### Local Data Source
-
-The local data source is configured by using map with tag `!pw.io.fs.read`. Then set `path` to denote the path to a folder with files to be indexed.
-
-#### Google Drive Data Source
-
-The Google Drive data source is enabled by using map with tag `!pw.io.gdrive.read`. The map must contain two main parameters:
-- `object_id`, containing the ID of the folder that needs to be indexed. It can be found from the URL in the web interface, where it's the last part of the address. For example, the publicly available demo folder in Google Drive has the URL `https://drive.google.com/drive/folders/1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`. Consequently, the last part of this address is `1cULDv2OaViJBmOfG5WB0oWcgayNrGtVs`, hence this is the `object_id` you would need to specify.
-- `service_user_credentials_file`, containing the path to the credentials files for the Google [service account](https://cloud.google.com/iam/docs/service-account-overview). To get more details on setting up the service account and getting credentials, you can also refer to [this tutorial](https://pathway.com/developers/user-guide/connectors/gdrive-connector#setting-up-google-drive).
-
-Besides, to speed up the indexing process you may want to specify the `refresh_interval` parameter, denoted by an integer number of seconds. It corresponds to the frequency between two sequential folder scans. If unset, it defaults to 30 seconds.
-
-For the full list of the available parameters, please refer to the Google Drive connector [documentation](https://pathway.com/developers/api-docs/pathway-io/gdrive#pathway.io.gdrive.read).
-
-#### SharePoint Data Source
-
-This data source requires Scale or Enterprise [license key](https://pathway.com/pricing) - you can obtain free Scale key on [Pathway website](https://pathway.com/get-license).
-
-To use it, set the map tag to be `!pw.xpacks.connectors.sharepoint.read`, and then provide values of `url`, `tenant`, `client_id`, `cert_path`, `thumbprint` and `root_path`. To read about the meaning of these arguments, check the Sharepoint connector [documentation](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read).
-
-
-## Deploying and using a local LLM
-
-### Embedding Model Selection
-
-You will use `pathway.xpacks.llm.embedders` module to load open-source embedding models from the HuggingFace model library. For this showcase, pick the `avsolatorio/GIST-small-Embedding-v0` model which has a dimension of 384 as it is compact and performed well in our tests.
-
-```yaml
-$embedding_model: "avsolatorio/GIST-small-Embedding-v0"
-
-$embedder: !pw.xpacks.llm.embedders.SentenceTransformerEmbedder
- model: $embedding_model
- call_kwargs:
- show_progress_bar: False
-```
-
-If you would like to use a higher-dimensional model, here are some possible alternatives you could use instead:
-
-- mixedbread-ai/mxbai-embed-large-v1
-- avsolatorio/GIST-Embedding-v0
-
-For other possible choices, take a look at the [MTEB Leaderboard](https://huggingface.co/spaces/mteb/leaderboard) managed by HuggingFace.
-
-
-### Local LLM Deployment
-
-Due to its size and performance it is best to run the `Mistral 7B` LLM. Here you would deploy it as a service running on GPU, using `Ollama`.
-
-To run local LLM, you can refer to these steps:
-- Download Ollama from [ollama.com/download](https://ollama.com/download)
-- In your terminal, run `ollama serve`
-- In another terminal, run `ollama run mistral`
-
-You can now test it with the following request:
-
-```bash
-curl -X POST http://localhost:11434/api/generate -d '{
- "model": "mistral",
- "prompt":"Here is a story about llamas eating grass"
- }'
-```
-
-
-### LLM Initialization
-
-Now you will initialize the LLM instance that will call the local model.
-
-```yaml
-$llm_model: "ollama/mistral"
-
-$llm: !pw.xpacks.llm.llms.LiteLLMChat
- model: $llm_model
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache {}
- temperature: 0
- api_base: "http://localhost:11434"
- # api_base: "http://host.docker.internal:11434" # use this when you are running the app in the Docker on Mac or Windows
- async_mode: "fully_async"
-```
-
-## Running the app
-
-First, make sure your local LLM is up and running. By default, the pipeline tries to access the LLM at `http://localhost:11434`. You can change that by setting `api_base` value in the app.yaml file.
-
-### With Docker
-In order to let the pipeline get updated with each change in local files, you need to mount the folder onto the docker. The following commands show how to do that.
-
-#### Linux
-```bash
-# Build the image in this folder
-docker build -t privaterag .
-
-# Run the image, mount the `data` folder into image
-docker run --net host -v ./data:/app/data privaterag
-```
-
-#### Mac or Windows
-In the `app.yaml` change `api_base` to be `http://host.docker.internal:11434`. Then run:
-
-```bash
-# Build the image in this folder
-docker build -t privaterag .
-
-# Run the image, mount the `data` folder into image
-docker run -v ./data:/app/data -p 8000:8000 privaterag
-```
-
-### Locally
-To run locally you need to install the Pathway Live Data Framework app with LLM dependencies using:
-```bash
-pip install pathway[all]
-```
-
-Then change your directory in the terminal to this folder and run the app:
-```bash
-python app.py
-```
-
-## Querying the app/pipeline
-
-Finally, query the application with;
-
-```bash
-curl -X 'POST' 'http://0.0.0.0:8000/v2/answer' -H 'accept: */*' -H 'Content-Type: application/json' -d '{
- "prompt": "What is the start date of the contract?"
-}'
-```
-> `{"response": "December 21, 2015 [6]"}`
-
-
-## Conclusion:
-
-Now you have a fully private RAG set up with Pathway Live Data Framework and Ollama. All your data remains safe on your system. Moreover, the set-up is optimized for speed, thanks to how Ollama runs the LLM, and how Pathway Live Data Framework’s adaptive retrieval mechanism reduces token consumption while preserving the accuracy of the RAG.
-
-This is a full production-ready set-up which includes reading your data sources, parsing the data, and serving the endpoint.
-This private RAG setup can be run entirely locally with open-source LLMs, making it ideal for organizations with sensitive data and explainable AI needs.
-
-## Quick Links:
-
-- [Pathway Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
-- [Pathway Live Data Framework App Templates](https://pathway.com/developers/templates)
-- [Discord Community of Pathway Live Data Framework](https://discord.gg/pathway)
-- [Pathway Issue Tracker](https://github.com/pathwaycom/pathway/issues)
-- [End-to-end dynamic RAG pipeline with Pathway](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
-- [Using Pathway Live Data Framework as a vector store with Langchain](https://python.langchain.com/v0.2/docs/integrations/vectorstores/pathway/)
-- [Using Pathway Live Data Framework as a retriever with LlamaIndex](https://docs.llamaindex.ai/en/stable/examples/retrievers/pathway_retriever/)
-
-Make sure to drop a “Star” to our repositories if you found this resource helpful!
diff --git a/templates/private_rag/app.py b/templates/private_rag/app.py
deleted file mode 100644
index 314342e9..00000000
--- a/templates/private_rag/app.py
+++ /dev/null
@@ -1,76 +0,0 @@
-import logging
-from warnings import warn
-
-import pathway as pw
-from dotenv import load_dotenv
-from pathway.xpacks.llm.question_answering import SummaryQuestionAnswerer
-from pathway.xpacks.llm.servers import QASummaryRestServer
-from pydantic import BaseModel, ConfigDict, InstanceOf
-
-# To use advanced features with Pathway Live Data Framework Scale, get your free license key from
-# https://pathway.com/features and paste it below.
-# To use Pathway Live Data Framework Community, comment out the line below.
-pw.set_license_key("demo-license-key-with-telemetry")
-
-logging.basicConfig(
- level=logging.INFO,
- format="%(asctime)s %(name)s %(levelname)s %(message)s",
- datefmt="%Y-%m-%d %H:%M:%S",
-)
-
-load_dotenv()
-
-
-class App(BaseModel):
- question_answerer: InstanceOf[SummaryQuestionAnswerer]
- host: str = "0.0.0.0"
- port: int = 8000
-
- with_cache: bool | None = None # deprecated
- persistence_backend: pw.persistence.Backend | None = None
- persistence_mode: pw.PersistenceMode | None = pw.PersistenceMode.UDF_CACHING
- terminate_on_error: bool = False
-
- def run(self) -> None:
- server = QASummaryRestServer( # noqa: F841
- self.host, self.port, self.question_answerer
- )
-
- if self.persistence_mode is None:
- if self.with_cache is True:
- warn(
- "`with_cache` is deprecated. Please use `persistence_mode` instead.",
- DeprecationWarning,
- )
- persistence_mode = pw.PersistenceMode.UDF_CACHING
- else:
- persistence_mode = None
- else:
- persistence_mode = self.persistence_mode
-
- if persistence_mode is not None:
- if self.persistence_backend is None:
- persistence_backend = pw.persistence.Backend.filesystem("./Cache")
- else:
- persistence_backend = self.persistence_backend
- persistence_config = pw.persistence.Config(
- persistence_backend,
- persistence_mode=persistence_mode,
- )
- else:
- persistence_config = None
-
- pw.run(
- persistence_config=persistence_config,
- terminate_on_error=self.terminate_on_error,
- monitoring_level=pw.MonitoringLevel.NONE,
- )
-
- model_config = ConfigDict(extra="forbid", arbitrary_types_allowed=True)
-
-
-if __name__ == "__main__":
- with open("app.yaml") as f:
- config = pw.load_yaml(f)
- app = App(**config)
- app.run()
diff --git a/templates/private_rag/app.yaml b/templates/private_rag/app.yaml
deleted file mode 100644
index 9ef08c90..00000000
--- a/templates/private_rag/app.yaml
+++ /dev/null
@@ -1,119 +0,0 @@
-# This YAML configuration file is used to set up and configure the Private RAG template.
-# It defines various components such as data sources, language models, embedders, splitters, parsers, and retrievers.
-# Each section is configured to specify how the template should process and handle data for generating responses.
-# You can learn more about the YAML syntax here: https://pathway.com/developers/templates/configure-yaml
-
-
-
-# $sources defines the data sources used to read the data which will be indexed in the RAG.
-# You can learn more how to configure data sources here:
-# https://pathway.com/developers/templates/yaml-examples/data-sources-examples
-
-$sources:
- # File System connector, reading data locally.
- - !pw.io.fs.read
- path: data
- format: binary
- with_metadata: true
-
- # Uncomment to use the SharePoint connector
- # - !pw.xpacks.connectors.sharepoint.read
- # url: $SHAREPOINT_URL
- # tenant: $SHAREPOINT_TENANT
- # client_id: $SHAREPOINT_CLIENT_ID
- # cert_path: sharepointcert.pem
- # thumbprint: $SHAREPOINT_THUMBPRINT
- # root_path: $SHAREPOINT_ROOT
- # with_metadata: true
- # refresh_interval: 30
-
- # Uncomment to use the Google Drive connector
- # - !pw.io.gdrive.read
- # object_id: $DRIVE_ID
- # service_user_credentials_file: gdrive_indexer.json
- # file_name_pattern:
- # - "*.pdf"
- # - "*.pptx"
- # object_size_limit: null
- # with_metadata: true
- # refresh_interval: 30
-
-
-
-# Configures the LLM model settings for generating responses.
-# The list of available Pathway LLM wrappers is available here:
-# https://pathway.com/developers/api-docs/pathway-xpacks-llm/llms
-# You can learn more about those in our documentation:
-# https://pathway.com/developers/templates/rag-customization/llm-chats
-
-
-$llm_model: "ollama/mistral"
-
-$llm: !pw.xpacks.llm.llms.LiteLLMChat
- model: $llm_model
- retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy
- max_retries: 6
- cache_strategy: !pw.udfs.DefaultCache {}
- temperature: 0
- api_base: "http://localhost:11434"
- # api_base: "http://host.docker.internal:11434" # use this when you are running the app in the Docker on Mac or Windows
- async_mode: "fully_async"
-
-$embedding_model: "avsolatorio/GIST-small-Embedding-v0"
-
-# Specifies the embedder model for converting text into embeddings.
-$embedder: !pw.xpacks.llm.embedders.SentenceTransformerEmbedder
- model: $embedding_model
- call_kwargs:
- show_progress_bar: False
-
-# Sets up the splitter for chunking the documents.
-$splitter: !pw.xpacks.llm.splitters.TokenCountSplitter
- max_tokens: 400
-
-# Configures the parser for processing and extracting information from documents.
-$parser: !pw.xpacks.llm.parsers.DoclingParser
- table_parsing_strategy: "llm"
- async_mode: "fully_async"
- chunk: false
- cache_strategy: !pw.udfs.DefaultCache {}
-
-# Sets up the retriever factory for indexing and retrieving documents.
-$retriever_factory: !pw.indexing.UsearchKnnFactory
- reserved_space: 1000
- embedder: $embedder
- metric: !pw.indexing.USearchMetricKind.COS
-
-# Manages the storage and retrieval of documents for the RAG template.
-$document_store: !pw.xpacks.llm.document_store.DocumentStore
- docs: $sources
- parser: $parser
- splitter: $splitter
- retriever_factory: $retriever_factory
-
-# Configures the question-answering component using the RAG approach.
-question_answerer: !pw.xpacks.llm.question_answering.AdaptiveRAGQuestionAnswerer
- llm: $llm
- indexer: $document_store
- n_starting_documents: 2
- factor: 2
- max_iterations: 4
- strict_prompt: true
-
-# Change host and port of the webserver by uncommenting these lines
-# host: "0.0.0.0"
-# port: 8000
-
-# By default, caching is enabled for UDFs with cache_strategy set.
-# You can disable it by uncommenting the following line.
-# persistence_mode: null
-# You can also set persistence_mode to !pw.PersistenceMode.PERSISTING to enable persistence
-# across restarts.
-# By default, when enabled, Cache is stored in .Cache directory.
-# You can customize the location by uncommenting and modifying the following lines:
-# persistence_backend: !pw.persistence.Backend.filesystem
-# path: ".Cache"
-
-# If `terminate_on_error` is true then the program will terminate whenever any error is encountered.
-# Defaults to false, uncomment the following line if you want to set it to true
-# terminate_on_error: true
diff --git a/templates/private_rag/data/IdeanomicsInc_20160330_10-K_EX-10.26_9512211_EX-10.26_Content License Agreement.pdf b/templates/private_rag/data/IdeanomicsInc_20160330_10-K_EX-10.26_9512211_EX-10.26_Content License Agreement.pdf
deleted file mode 100644
index aa1a1686..00000000
Binary files a/templates/private_rag/data/IdeanomicsInc_20160330_10-K_EX-10.26_9512211_EX-10.26_Content License Agreement.pdf and /dev/null differ
diff --git a/templates/private_rag/private_rag.png b/templates/private_rag/private_rag.png
deleted file mode 100644
index 9979b0cf..00000000
Binary files a/templates/private_rag/private_rag.png and /dev/null differ
diff --git a/templates/private_rag/requirements.txt b/templates/private_rag/requirements.txt
deleted file mode 100644
index 2442a906..00000000
--- a/templates/private_rag/requirements.txt
+++ /dev/null
@@ -1,3 +0,0 @@
-pathway[all]
-python-dotenv~=1.0
-mpmath~=1.3
diff --git a/templates/question_answering_rag/.env.example b/templates/question_answering_rag/.env.example
deleted file mode 100644
index b82e13a2..00000000
--- a/templates/question_answering_rag/.env.example
+++ /dev/null
@@ -1 +0,0 @@
-OPENAI_API_KEY="sk-***"
diff --git a/templates/question_answering_rag/Dockerfile b/templates/question_answering_rag/Dockerfile
deleted file mode 100644
index 1cc7f91d..00000000
--- a/templates/question_answering_rag/Dockerfile
+++ /dev/null
@@ -1,16 +0,0 @@
-ARG PATHWAY_SRC_IMAGE=pathwaycom/pathway:latest
-
-FROM ${PATHWAY_SRC_IMAGE}
-
-WORKDIR /app
-
-RUN apt-get update \
- && apt-get install -y python3-opencv tesseract-ocr-eng poppler-utils libreoffice \
- && rm -rf /var/lib/apt/lists/* /var/cache/apt/archives/*
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-CMD ["python", "app.py"]
diff --git a/templates/question_answering_rag/README.md b/templates/question_answering_rag/README.md
deleted file mode 100644
index 4f72e2ca..00000000
--- a/templates/question_answering_rag/README.md
+++ /dev/null
@@ -1,422 +0,0 @@
-
-
-# Pathway Live Data Framework + PostgreSQL + LLM: app for querying financial reports with live document structuring pipeline
-
-The aim of this pipeline is to extract and structure the data out of unstructured data (PDFs, queries)
-on the fly.
-
-This example consists of two separate parts that can be used independently.
-1 - Pipeline 1: Proactive data pipeline that is always live and tracking file changes,
- it reads documents, structures them and writes results to PostgreSQL.
-2 - Pipeline 2: Query answering pipeline that reads user queries, and answers them by
- generating SQL queries that are run on the data stored in PostgreSQL.
-
-
-Specifically, Pipeline 1 reads in a collection of financial PDF documents from a local directory
-(that can be synchronized with a Dropbox account), tokenizes each document using the tiktoken encoding,
-then extracts, using the OpenAI API, the wanted fields.
-The values are stored in a Pathway Live Data Framework table which is then output to a PostgreSQL instance.
-
-Pipeline 2 then starts a REST API endpoint serving queries about programming in Pathway Live Data Framework.
-
-Each query text is converted into a SQL query using the OpenAI API.
-
-Architecture diagram and description are at
-https://pathway.com/developers/templates/rag/unstructured-to-structured
-
-
-⚠️ This project requires a running PostgreSQL instance.
-
-🔵 The extracted fields from the PDFs documents are the following:
-- company_symbol: str
-- year: int
-- quarter: str
-- revenue_md: float
-- eps: float
-- net_income_md: float
-
-⚠️ The revenue and net income are expressed in millions of dollars, the eps is in dollars.
-
-🔵 The script uses a prompt to instruct the Language Model and generate SQL queries that adhere to the specified format.
-The allowed queries follow a particular pattern:
-1. The SELECT clause should specify columns or standard aggregator operators (SUM, COUNT, MIN, MAX, AVG).
-2. The WHERE clause should include conditions using standard binary operators (<, >, =, etc.),
- with support for AND and OR logic.
-3. To prevent 'psycopg2.errors.GroupingError', relevant columns from the WHERE clause are included
- in the GROUP BY clause.
-4. For readability, if no aggregator is used, the company_symbol, year,
- and quarter are included in addition to the wanted columns.
-
-Example:
-"What is the net income of all companies?" should return:
-Response:
-'SELECT company_symbol, net_income_md, quarter, net_income_md FROM table;'
-
-
-## Project architecture:
-```
-.
-├── postgresql/
-│ └── init-db.sql
-├── ui/
-│ └── server.py
-├── __init__.py
-├── app.py
-└── docker-compose.yml
-```
-
-## Running the Pipeline
-
-### Setup environment:
-
-Set your env variables in the .env file placed in this directory.
-
-```bash
-OPENAI_API_KEY=sk-...
-PATHWAY_PERSISTENT_STORAGE= # Set this variable if you want to use caching
-```
-
-### With Docker
-
-To run jointly the Unstructured to SQL on the fly pipeline and a simple UI please execute:
-
-```bash
-docker compose up --build
-```
-
-Then, the UI will run at http://127.0.0.1:8501 by default. You can access it by following this URL in your web browser.
-
-The `docker-compose.yml` file declares a [volume bind mount](https://docs.docker.com/reference/cli/docker/container/run/#volume) that makes changes to files under `data/` made on your host computer visible inside the docker container. The files in `data/quarterly_earnings` are indexed by the pipeline - you can paste new files there and they will impact the computations.
-
-### Manually
-
-Alternatively, you can run each service separately. To run PostgreSQL use Docker. To run it, run:
-`docker compose up -d postgres`.
-
-To install the dependencies, run:
-`pip install -r requirements.txt`
-Then run:
-`python app.py`
-
-This will run the pipeline, which you can access through REST API at `localhost:8080`. For example, you can send questions using curl:
-```
-curl --data '{
- "user": "user",
- "query": "What is the maximum quarterly revenue achieved by Apple?"
-}' http://localhost:8080/ | jq
-```
-
-You can also run the Streamlit interface:
-`streamlit run ui/server.py`
-
diff --git a/templates/unstructured_to_sql_on_the_fly/Unstructured_to_SQL_diagram.png b/templates/unstructured_to_sql_on_the_fly/Unstructured_to_SQL_diagram.png
deleted file mode 100644
index 61cd51f7..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/Unstructured_to_SQL_diagram.png and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/__init__.py b/templates/unstructured_to_sql_on_the_fly/__init__.py
deleted file mode 100644
index 05656682..00000000
--- a/templates/unstructured_to_sql_on_the_fly/__init__.py
+++ /dev/null
@@ -1,3 +0,0 @@
-from .app import run
-
-__all__ = ["run"]
diff --git a/templates/unstructured_to_sql_on_the_fly/app.py b/templates/unstructured_to_sql_on_the_fly/app.py
deleted file mode 100644
index 8ff49979..00000000
--- a/templates/unstructured_to_sql_on_the_fly/app.py
+++ /dev/null
@@ -1,333 +0,0 @@
-"""
-Microservice for accounting assistant.
-
-The aim of this project is to extract and structure the data out of unstructured data (PDFs, queries)
-on the fly.
-
-This example consists of two separate parts that can be used independently.
-1 - Pipeline 1: Proactive data pipeline that is always live and tracking file changes,
- it reads documents, structures them and writes results to PostgreSQL.
-2 - Pipeline 2: Query answering pipeline that reads user queries, and answers them by
- generating SQL queries that are run on the data stored in PostgreSQL.
-
-
-Specifically, Pipeline 1 reads in a collection of financial PDF documents from a local directory
-(that can be synchronized with a Dropbox account), tokenizes each document using the tiktoken encoding,
-then extracts, using the OpenAI API, the wanted fields.
-The values are stored in a Pathway table which is then output to a PostgreSQL instance.
-
-Pipeline 2 then starts a REST API endpoint serving queries about programming in Pathway.
-
-Each query text is converted into a SQL query using the OpenAI API.
-
-Architecture diagram and description are at
-https://pathway.com/developers/templates/rag/unstructured-to-structured
-
-
-⚠️ This project requires a running PostgreSQL instance.
-
-🔵 The extracted fields from the PDFs documents are the following:
-- company_symbol: str
-- year: int
-- quarter: str
-- revenue_md: float
-- eps: float
-- net_income_md: float
-
-⚠️ The revenue and net income are expressed in millions of dollars, the eps is in dollars.
-
-🔵 The script uses a prompt to instruct the Language Model and generate SQL queries that adhere to the specified format.
-The allowed queries follow a particular pattern:
-1. The SELECT clause should specify columns or standard aggregator operators (SUM, COUNT, MIN, MAX, AVG).
-2. The WHERE clause should include conditions using standard binary operators (<, >, =, etc.),
- with support for AND and OR logic.
-3. To prevent 'psycopg2.errors.GroupingError', relevant columns from the WHERE clause are included
- in the GROUP BY clause.
-4. For readability, if no aggregator is used, the company_symbol, year,
- and quarter are included in addition to the wanted columns.
-
-Example:
-"What is the net income of all companies?" should return:
-Response:
-'SELECT company_symbol, net_income_md, quarter, net_income_md FROM table;'
-
-
-Please check the README.md in this directory for how-to-run instructions.
-"""
-
-import json
-import logging
-import os
-
-import dotenv
-import pathway as pw
-import psycopg
-import tiktoken
-from pathway.stdlib.utils.col import unpack_col
-from pathway.xpacks.llm.llms import OpenAIChat, prompt_chat_single_qa
-from pathway.xpacks.llm.parsers import UnstructuredParser
-
-# To use advanced features with Pathway Live Data Framework Scale, get your free license key from
-# https://pathway.com/features and paste it below.
-# To use Pathway Live Data Framework Community, comment out the line below.
-pw.set_license_key("demo-license-key-with-telemetry")
-
-dotenv.load_dotenv()
-
-
-class FinancialStatementSchema(pw.Schema):
- company_symbol: str
- year: int
- quarter: str
- revenue_md: float
- eps: float
- net_income_md: float
-
-
-class NLQuerySchema(pw.Schema):
- query: str
- user: str
-
-
-@pw.udf
-def build_prompt_structure(
- texts: list[str],
- max_tokens: int = 8000,
- encoding_name: str = "cl100k_base",
-):
- """
- Insert instructions for the LLM here.
- max_tokens for the context. If gpt-3.5-turbo-16k is used, set it to 16k.
- """
- docs_str = " ".join(texts)
- encoding = tiktoken.get_encoding(encoding_name)
- prompt_prefix = "Given the following quarterly earnings release : \n"
- prompt_suffix = (
- f" \nfill in this schema for the quarter in question {FinancialStatementSchema.typehints()}\n"
- + """while respecting the instructions:
- - amounts should be in millions of dollars.
- - Parse quarterly data and ignore yearly records if present.
- - Your answer should be parseable by json. i.e. json.loads(response) doesn't throw any errors."""
- )
-
- prefix_tokens = len(list(encoding.encode_ordinary(prompt_prefix)))
- suffix_tokens = len(list(encoding.encode_ordinary(prompt_suffix)))
-
- # Calculate available tokens for docs_str
- available_tokens = max_tokens - (prefix_tokens + suffix_tokens)
-
- # Tokenize docs_str and truncate if needed
- doc_tokens = list(encoding.encode_ordinary(docs_str))
- if len(doc_tokens) > available_tokens:
- logging.warning("Document is too large for one query.")
- docs_str = encoding.decode(doc_tokens[:available_tokens])
-
- prompt = prompt_prefix + docs_str + prompt_suffix
- return prompt
-
-
-@pw.udf
-def build_prompt_query(postresql_table: str, query: str) -> str:
- prompt = f"""Transform the given query '{query}' into a specific SQL SELECT statement format.
- For invalid queries, return the string 'None'. The result should be executable in PostgreSQL.
-
- The query should include the following components:
- The SELECT clause should specify one or more columns from the table {postresql_table}.
- You can use column names or standard aggregator operators such as SUM, COUNT, MIN, MAX, or AVG
- to retrieve data from the columns.
- The WHERE clause should include conditions that use standard binary operators (e.g., <, >, =) to filter the data.
- You can use AND and OR operators to combine multiple conditions.
- If any columns from the WHERE clause are used in the conditions, please ensure that those columns are included
- in the GROUP BY clause to prevent the 'psycopg2.errors.GroupingError.'
- You may use logical reasoning to decide which columns should be part of the GROUP BY clause.
-
- The columns are from {postresql_table} table whose schema is:
- company_symbol (str)
- year (int)
- quarter (str)
- revenue_md (float)
- eps (float)
- net_income_md (float)
-
- Quarter values are Q1, Q2, Q3 or Q4.
- The company_symbol is the stock name: for example AAPL for Apple and GOOG for Google.
-
- If no aggregator are used, please always add the company_symbol, year,
- and quarter in addition of the wanted columns:
- "What is the net income of all companies?" should return:
- 'SELECT company_symbol, net_income_md, quarter, net_income_md FROM {postresql_table};'
-
- Please ensure that the generated SQL query follows this structure and constraints.
- For example, a valid query might look like:
- 'SELECT company_symbol, SUM(net_income_md) FROM {postresql_table}
- WHERE year = 2022 AND eps > 1.0 GROUP BY company_symbol;'
-
-
- Make sure the query adheres to the specified format, and that it includes GROUP BY clause
- if you aggregate results
- and do not include any other SQL commands or clauses besides the SELECT statement.
- Thank you!"""
- return prompt
-
-
-@pw.udf
-def parse_str_to_list(response: str) -> list:
- dct = json.loads(response)
- return [dct[k] for k in sorted(dct)]
-
-
-def structure_on_the_fly(
- documents: pw.Table,
- api_key: str,
- model_locator: str,
- max_tokens: int,
- temperature: float,
-):
- prompt = documents.select(prompt=build_prompt_structure(pw.this.texts))
-
- model = OpenAIChat(
- api_key=api_key,
- model=model_locator,
- temperature=temperature,
- max_tokens=max_tokens,
- retry_strategy=pw.udfs.ExponentialBackoffRetryStrategy(),
- cache_strategy=pw.udfs.DefaultCache(),
- )
-
- responses = prompt.select(
- result=model(prompt_chat_single_qa(pw.this.prompt)),
- )
-
- responses = responses.select(values=parse_str_to_list(pw.this.result))
- result = unpack_col(responses.values, *sorted(FinancialStatementSchema.keys()))
- result = result.with_columns(
- eps=pw.apply(float, pw.this.eps),
- net_income_md=pw.apply(float, pw.this.net_income_md),
- revenue_md=pw.apply(float, pw.this.revenue_md),
- )
- return result
-
-
-def unstructured_query(
- postgreSQL_settings,
- postgreSQL_table,
- api_key: str,
- model_locator: str,
- max_tokens: int,
- temperature: float,
- host: str,
- port: int,
-):
- query, response_writer = pw.io.http.rest_connector(
- host=host,
- port=port,
- schema=NLQuerySchema,
- autocommit_duration_ms=50,
- delete_completed_queries=True,
- )
-
- query += query.select(prompt=build_prompt_query(postgreSQL_table, pw.this.query))
-
- model = OpenAIChat(
- api_key=api_key,
- model=model_locator,
- temperature=temperature,
- max_tokens=max_tokens,
- retry_strategy=pw.udfs.ExponentialBackoffRetryStrategy(),
- cache_strategy=pw.udfs.DefaultCache(),
- )
-
- query += query.select(
- sql_query=model(prompt_chat_single_qa(pw.this.prompt)),
- )
-
- # Connecting to the document database for queries
- connection_string = psycopg.conninfo.make_conninfo(**postgreSQL_settings)
- conn = psycopg.connect(connection_string)
- cursor = conn.cursor()
-
- @pw.udf
- def execute_sql_query(sql_query):
- cursor.execute(sql_query)
- answer = cursor.fetchall()
- # answer = answer[0][0]
- conn.commit()
- return answer
-
- query = query.select(
- pw.this.query,
- pw.this.sql_query,
- result=execute_sql_query(
- pw.this.sql_query,
- ),
- )
- answers = query.select(result=pw.make_tuple(pw.this.sql_query, pw.this.result))
- response_writer(answers)
-
-
-@pw.udf
-def strip_metadata(docs: list[tuple[str, dict]]) -> list[str]:
- return [doc[0] for doc in docs]
-
-
-def run(
- *,
- data_dir: str = os.environ.get("PATHWAY_DATA_DIR", "./data/quarterly_earnings"),
- api_key: str = os.environ.get("OPENAI_API_KEY", ""),
- host: str = os.environ.get("PATHWAY_REST_CONNECTOR_HOST", "0.0.0.0"),
- port: int = int(os.environ.get("PATHWAY_REST_CONNECTOR_PORT", "8080")),
- model_locator: str = "gpt-3.5-turbo", # "gpt-4", # gpt-3.5-turbo-16k
- max_tokens: int = 120,
- temperature: float = 0.0,
- postresql_host: str = os.environ.get("POSTGRESQL_HOST", "localhost"),
- postresql_port: str = os.environ.get("POSTGRESQL_PORT", "5432"),
- postresql_db: str = os.environ.get("POSTGRESQL_DB", "STRUCTUREDDB"),
- postresql_user: str = os.environ.get("POSTGRESQL_USER", "user"),
- postresql_password: str = os.environ.get("POSTGRESQL_PASSWORD", "password"),
- postresql_table: str = os.environ.get("POSTGRESQL_TABLE", "quarterly_earnings"),
- **kwargs,
-):
- #
- # # Pipeline 1 - parsing documents into a PostgreSql table
- #
- postgreSQL_settings = {
- "host": postresql_host,
- "port": postresql_port,
- "dbname": postresql_db,
- "user": postresql_user,
- "password": postresql_password,
- }
-
- files = pw.io.fs.read(
- data_dir,
- format="binary",
- )
- parser = UnstructuredParser()
- unstructured_documents = files.select(texts=parser(pw.this.data)).select(
- texts=strip_metadata(pw.this.texts)
- )
- structured_table = structure_on_the_fly(
- unstructured_documents, api_key, model_locator, max_tokens, temperature
- )
- pw.io.postgres.write(structured_table, postgreSQL_settings, postresql_table)
- pw.io.csv.write(structured_table, "./data/quarterly_earnings.csv")
-
- #
- # # Pipeline 2 - query answering using PostgreSql
- #
- unstructured_query(
- postgreSQL_settings,
- postresql_table,
- api_key,
- model_locator,
- max_tokens,
- temperature,
- host,
- port,
- )
-
- pw.run(monitoring_level=pw.MonitoringLevel.NONE)
-
-
-if __name__ == "__main__":
- run()
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/2023q2-alphabet-earnings-release.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/2023q2-alphabet-earnings-release.pdf
deleted file mode 100644
index 665d796a..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/2023q2-alphabet-earnings-release.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY22_Q4_Consolidated_Financial_Statements.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY22_Q4_Consolidated_Financial_Statements.pdf
deleted file mode 100644
index 34122cc0..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY22_Q4_Consolidated_Financial_Statements.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q1_Consolidated_Financial_Statements.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q1_Consolidated_Financial_Statements.pdf
deleted file mode 100644
index 418812d7..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q1_Consolidated_Financial_Statements.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q2_Consolidated_Financial_Statements.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q2_Consolidated_Financial_Statements.pdf
deleted file mode 100644
index 180ad4d3..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q2_Consolidated_Financial_Statements.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q3_Consolidated_Financial_Statements.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q3_Consolidated_Financial_Statements.pdf
deleted file mode 100644
index 593675dd..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/FY23_Q3_Consolidated_Financial_Statements.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/Meta-03-31-2023-Exhibit-99-1-FINAL-v2.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/Meta-03-31-2023-Exhibit-99-1-FINAL-v2.pdf
deleted file mode 100644
index 232275d0..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/Meta-03-31-2023-Exhibit-99-1-FINAL-v2.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/goog-exhibit-99-1-q1-2023-19.pdf b/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/goog-exhibit-99-1-q1-2023-19.pdf
deleted file mode 100644
index 4bf8cd02..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/data/quarterly_earnings/goog-exhibit-99-1-q1-2023-19.pdf and /dev/null differ
diff --git a/templates/unstructured_to_sql_on_the_fly/docker-compose.yml b/templates/unstructured_to_sql_on_the_fly/docker-compose.yml
deleted file mode 100644
index 68c889bc..00000000
--- a/templates/unstructured_to_sql_on_the_fly/docker-compose.yml
+++ /dev/null
@@ -1,51 +0,0 @@
-version: "3.8"
-services:
- postgres:
- container_name: postgres
- image: postgres
- ports:
- - 5432:5432
- environment:
- - POSTGRES_USER=user
- - POSTGRES_PASSWORD=password
- - POSTGRES_DB=STRUCTUREDDB
- - PGPASSWORD=password
- volumes:
- - ./postgres/init-db.sql:/docker-entrypoint-initdb.d/init-db.sql
- expose:
- - 5432
- healthcheck:
- test:
- [
- "CMD-SHELL",
- "pg_isready -h 0.0.0.0 -p 5432 -U user -d STRUCTUREDDB"
- ]
- interval: 5s
- timeout: 5s
- retries: 5
- pathway:
- depends_on:
- postgres:
- condition: service_healthy
- build:
- context: .
- ports:
- - "8080:8080"
- environment:
- OPENAI_API_KEY: "${OPENAI_API_KEY}"
- PATHWAY_REST_CONNECTOR_HOST:
- PATHWAY_REST_CONNECTOR_PORT:
- PATHWAY_PERSISTENT_STORAGE:
- POSTGRESQL_HOST: "postgres"
- volumes:
- - "./data:/app/data"
- streamlit_ui:
- depends_on:
- - pathway
- build:
- context: ./ui
- ports:
- - "8501:8501"
- environment:
- PATHWAY_HOST: "pathway"
- PATHWAY_PORT: "8080"
diff --git a/templates/unstructured_to_sql_on_the_fly/postgres/init-db.sql b/templates/unstructured_to_sql_on_the_fly/postgres/init-db.sql
deleted file mode 100644
index f542b634..00000000
--- a/templates/unstructured_to_sql_on_the_fly/postgres/init-db.sql
+++ /dev/null
@@ -1,10 +0,0 @@
-CREATE TABLE IF NOT EXISTS quarterly_earnings (
- company_symbol TEXT NOT NULL,
- eps FLOAT NOT NULL,
- net_income_md FLOAT NOT NULL,
- quarter TEXT NOT NULL,
- revenue_md FLOAT NOT NULL,
- year BIGINT NOT NULL,
- time BIGINT NOT NULL,
- diff INTEGER NOT NULL
-);
\ No newline at end of file
diff --git a/templates/unstructured_to_sql_on_the_fly/requirements.txt b/templates/unstructured_to_sql_on_the_fly/requirements.txt
deleted file mode 100644
index 9171a131..00000000
--- a/templates/unstructured_to_sql_on_the_fly/requirements.txt
+++ /dev/null
@@ -1,2 +0,0 @@
-python-dotenv~=1.0
-psycopg~=3.1
diff --git a/templates/unstructured_to_sql_on_the_fly/ui/Dockerfile b/templates/unstructured_to_sql_on_the_fly/ui/Dockerfile
deleted file mode 100644
index e3544a8d..00000000
--- a/templates/unstructured_to_sql_on_the_fly/ui/Dockerfile
+++ /dev/null
@@ -1,11 +0,0 @@
-FROM python:3.11
-
-WORKDIR /app
-
-RUN pip install streamlit
-
-COPY . .
-
-EXPOSE 8501
-
-CMD ["streamlit", "run", "server.py", "--server.port", "8501", "--server.address", "0.0.0.0"]
diff --git a/templates/unstructured_to_sql_on_the_fly/ui/server.py b/templates/unstructured_to_sql_on_the_fly/ui/server.py
deleted file mode 100644
index 6aa425f6..00000000
--- a/templates/unstructured_to_sql_on_the_fly/ui/server.py
+++ /dev/null
@@ -1,78 +0,0 @@
-import os
-
-import pandas as pd
-import requests
-import streamlit as st
-
-api_host = os.environ.get("PATHWAY_HOST", "localhost")
-api_port = os.environ.get("PATHWAY_PORT", 8000)
-
-with st.sidebar:
- st.markdown(
- "## How to query your data\n"
- "Enter your question about financial data\n"
- "Example: What is the average quarterly net income achieved by all companies in the fourth quarter?"
- )
- st.markdown("---")
- st.markdown("# Units")
- st.markdown(
- "⚠️ The revenue and net income are expressed in millions of dollars,"
- " the eps is in dollars per share."
- )
- st.markdown("---")
- st.markdown("# About")
- st.markdown(
- "Financial LLM app to synthesize on the fly the data in your financial documents."
- "It uses Pathway's [LLM App features](https://github.com/pathwaycom/llm-app) "
- "to build and maintain a real-time database and synthesize your documents "
- " using LLM(Large Language Model) and store the data in PostgreSQL.\n"
- )
- st.markdown(
- """[View the source code on GitHub](
-https://github.com/pathwaycom/llm-app/templates/unstructured_to_sql_on_the_fly/app.py)"""
- )
-
-
-# Streamlit UI elements
-st.title("📈 Financial summary with LLM App")
-
-question = st.text_input(
- "Search for something",
- placeholder="What summary are looking for?",
-)
-
-
-def json_to_table(json_value):
- result = ""
- for row in json_value:
- for col_value in row:
- result = result + str(col_value) + "\t"
- result = result + "\n"
- return result
-
-
-# Handle Discounts API request if data source is selected and a question is provided
-if question:
- url = f"http://{api_host}:{api_port}/"
- try:
- data = {"user": "user", "query": question}
- response = requests.post(url, json=data)
-
- if response.status_code == 200:
- response_JSON = response.json()
- sql_query = response_JSON[0]
- answer = response_JSON[1]
- dataframe = pd.DataFrame.from_records(answer)
- st.write("### Answer")
- st.write("Resulting SQL query:")
- st.write(sql_query)
- st.write("SQL Answer:")
- st.dataframe(dataframe)
- else:
- st.error(
- f"Failed to send data to Finance API. Status code: {response.status_code}"
- )
- except Exception as e:
- st.write("### Parsing error:")
- st.write("Couldn't parse the entry.")
- st.write(str(e))
diff --git a/templates/unstructured_to_sql_on_the_fly/unstructured_to_sql_demo.gif b/templates/unstructured_to_sql_on_the_fly/unstructured_to_sql_demo.gif
deleted file mode 100644
index 64df84f3..00000000
Binary files a/templates/unstructured_to_sql_on_the_fly/unstructured_to_sql_demo.gif and /dev/null differ
diff --git a/templates/video_rag_twelvelabs/.env.example b/templates/video_rag_twelvelabs/.env.example
deleted file mode 100644
index 514ea8f0..00000000
--- a/templates/video_rag_twelvelabs/.env.example
+++ /dev/null
@@ -1,10 +0,0 @@
-# TwelveLabs API key, used by the Pegasus video parser and the Marengo embedder.
-# Get a free key at https://twelvelabs.io
-TWELVELABS_API_KEY=
-
-# OpenAI API key, used by the question-answering LLM.
-OPENAI_API_KEY=
-
-# Pathway license key, required by the TwelveLabsVideoParser.
-# Get a free key at https://pathway.com/features
-PATHWAY_LICENSE_KEY=
diff --git a/templates/video_rag_twelvelabs/Dockerfile b/templates/video_rag_twelvelabs/Dockerfile
deleted file mode 100644
index 957987d5..00000000
--- a/templates/video_rag_twelvelabs/Dockerfile
+++ /dev/null
@@ -1,12 +0,0 @@
-FROM pathwaycom/pathway:latest
-
-WORKDIR /app
-
-COPY requirements.txt .
-RUN pip install -U --no-cache-dir -r requirements.txt
-
-COPY . .
-
-EXPOSE 8000
-
-CMD ["python", "app.py"]
diff --git a/templates/video_rag_twelvelabs/README.md b/templates/video_rag_twelvelabs/README.md
deleted file mode 100644
index 520b18c7..00000000
--- a/templates/video_rag_twelvelabs/README.md
+++ /dev/null
@@ -1,118 +0,0 @@
-



 +
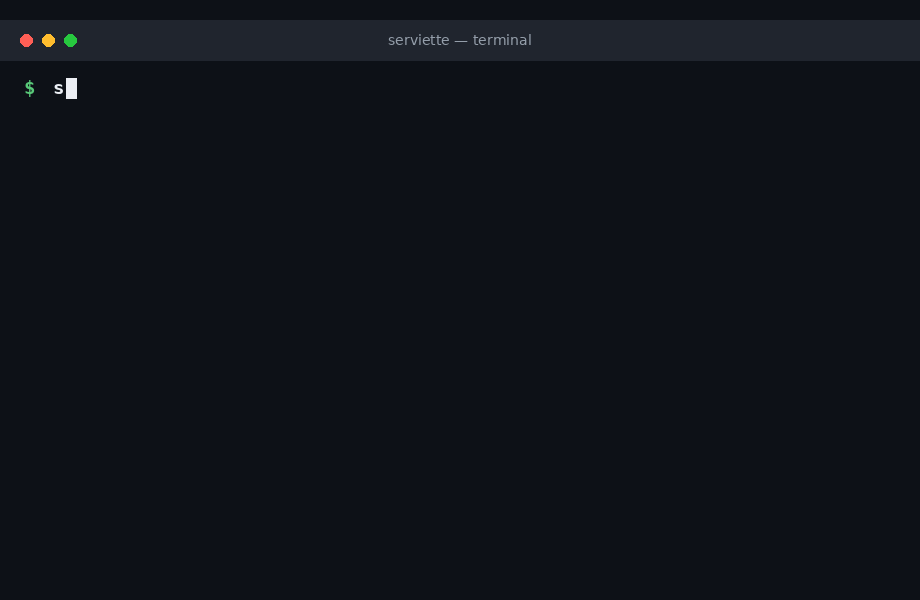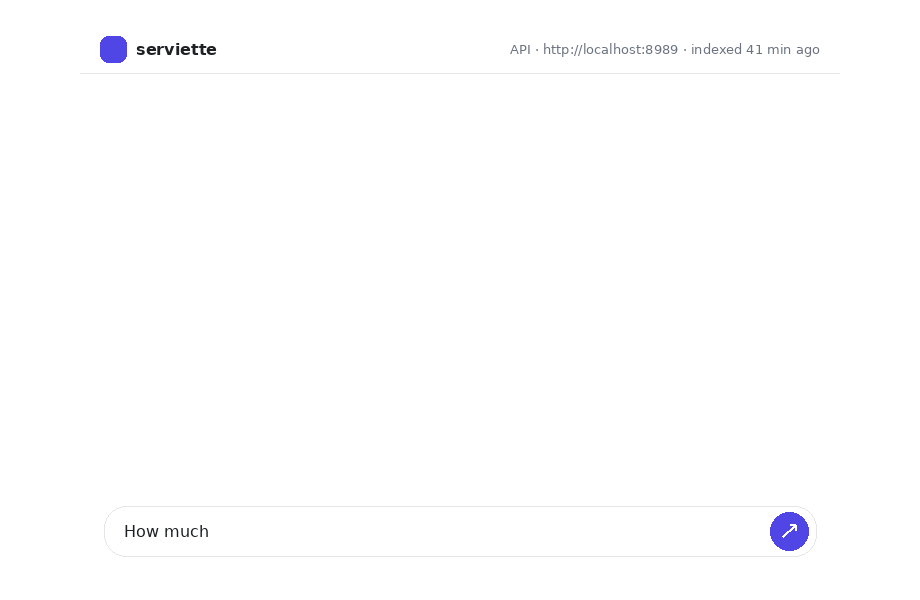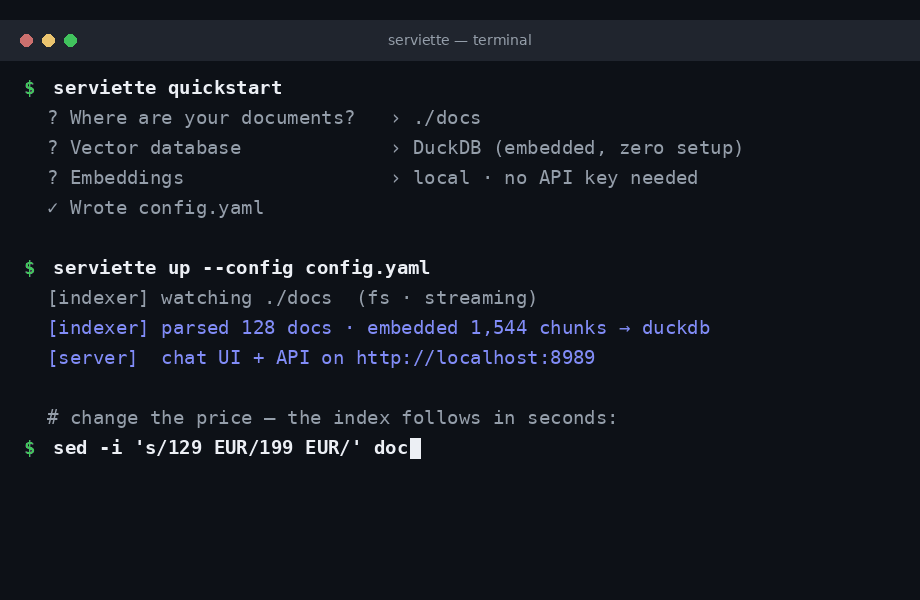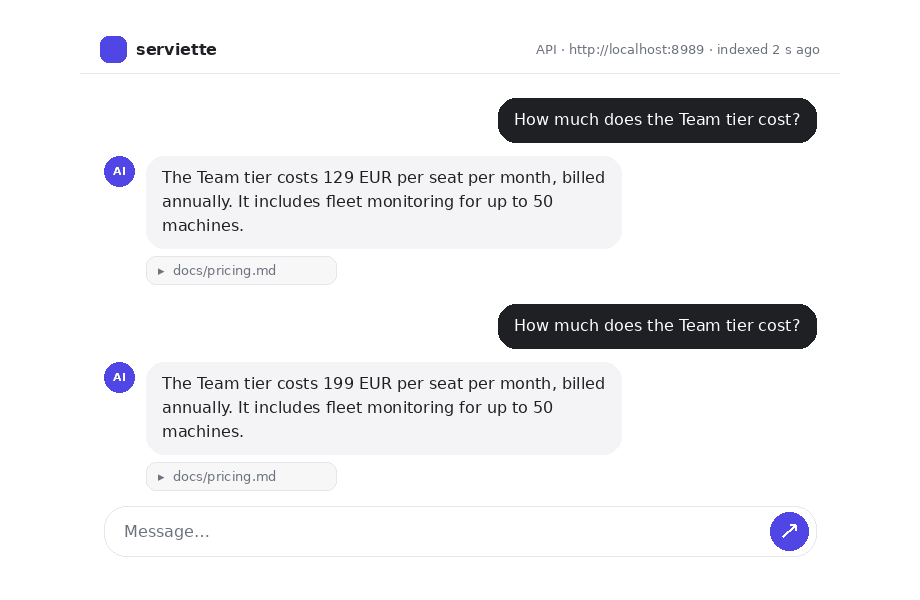 +
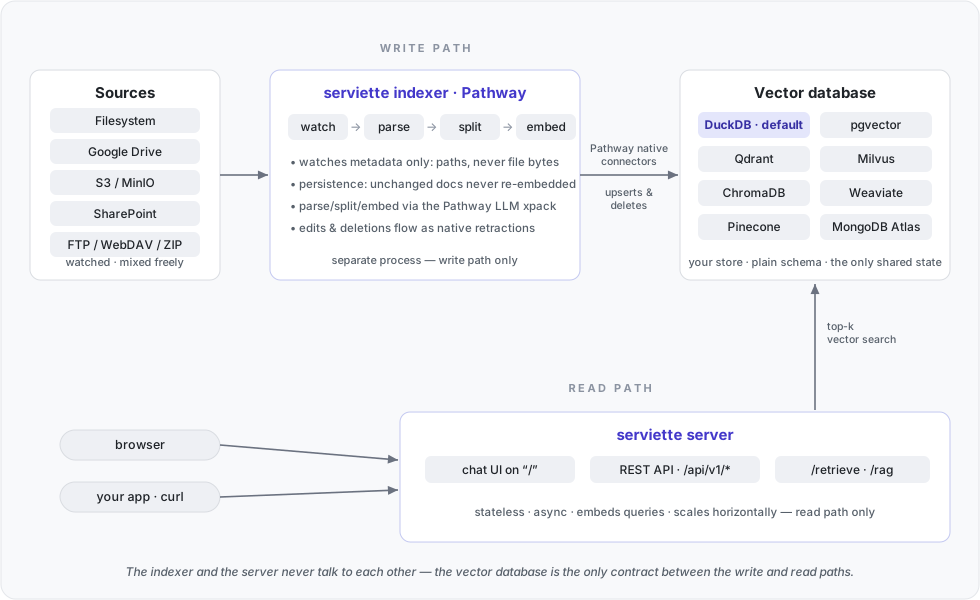 +
 +
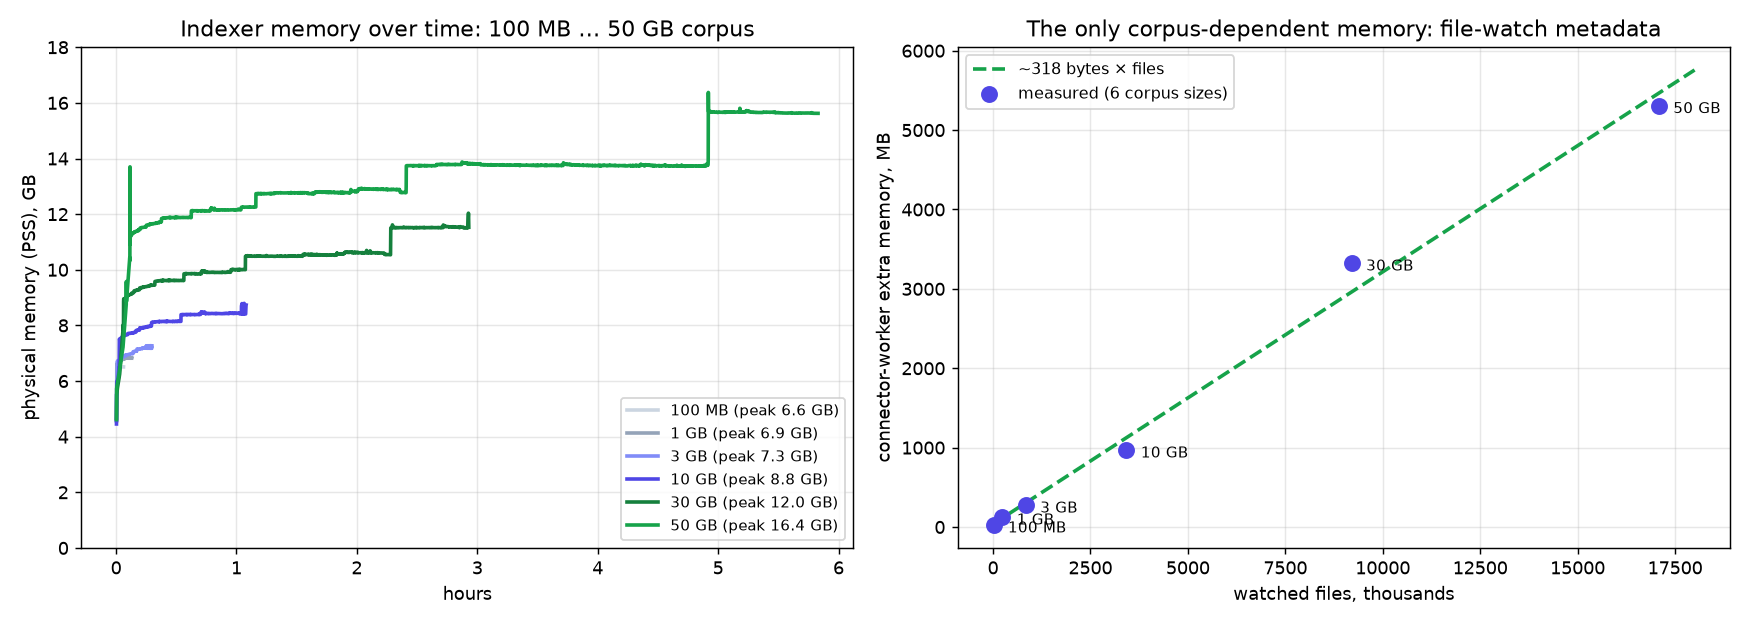

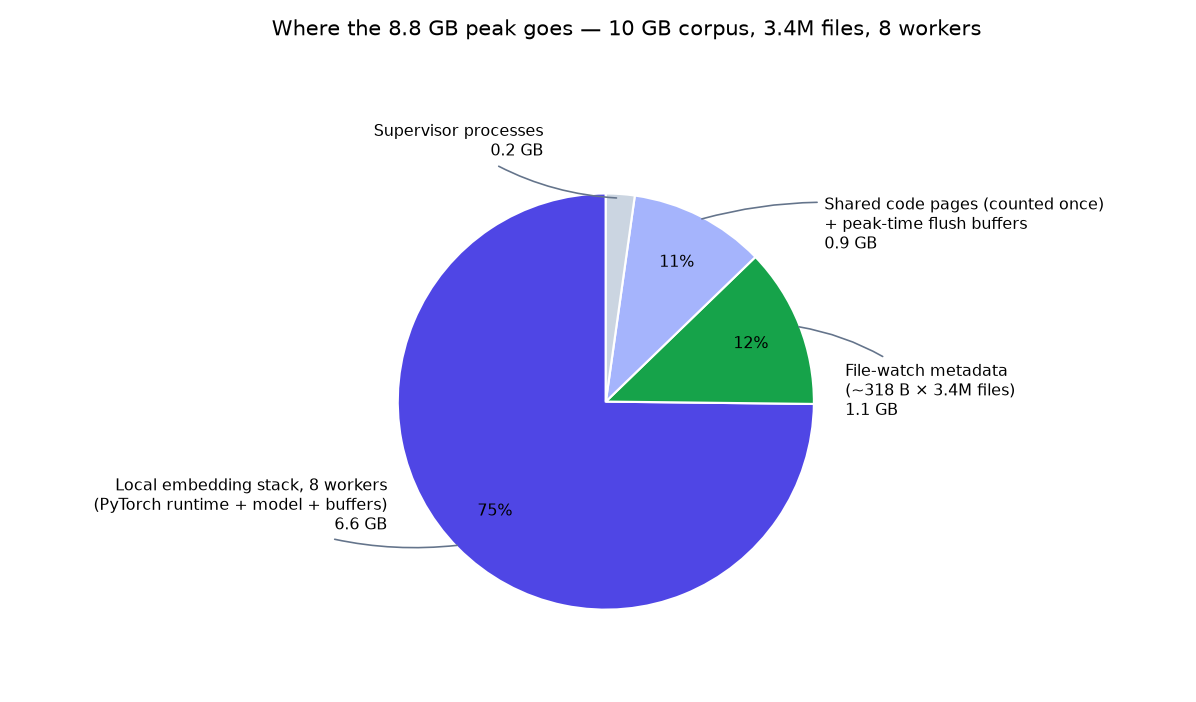
 +
 +
 - Deploy with GCP |
-
 - Deploy with AWS |
-
 - Deploy with Azure |
-
 - Deploy with Render
-
 -