diff --git a/README.md b/README.md index d761323..f13f439 100644 --- a/README.md +++ b/README.md @@ -3,36 +3,50 @@ alt="OpenCode Heads Up" width="510"> -OpenCode Heads Up is a heads-up display (HUD) with per-turn telemetry -for both local inference engines and remote models. It contains a -universal layer of baseline metrics along with any additional data from -the provider. - - -``` -▾ MTPLX · last turn - -speed 34.4 tok/s -ttft 17.19s -prefill 460 tok/s -tokens 1,233 -time 207.37s -MTP 3.42x -accepted 91/79/64% -sub-agent 191 tok - 23.91s - -▸ Session · 14 turns 48.2 tok/s -``` - -Two boxes, each opened and closed by clicking its heading: the last turn, -and the session so far. `details ›` under them opens the full picture: -where each turn's time went, every step and tool call, and the session's -spread and coverage (see [Details](#details)). - -Requires [**OpenCode 2**](https://opencode.ai/v2/docs). For the v1 line -(OpenCode 1.18.x), see -[opencode-engine-hud](https://github.com/charlesnutter/opencode-engine-hud). +OpenCode Heads Up is a heads-up display (HUD) with telemetry +for both local inference engines and remote models. Get your data straight from the source, with OpenCode's own data layer filling in the gaps. + + + + + + + + + + + + + + + + + + +
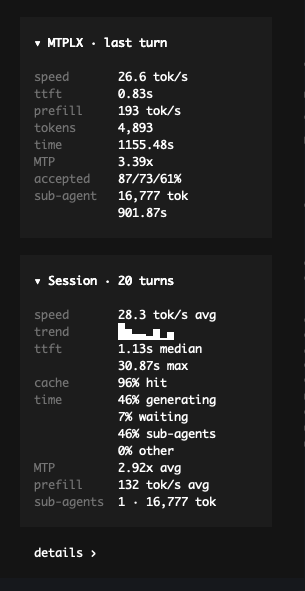
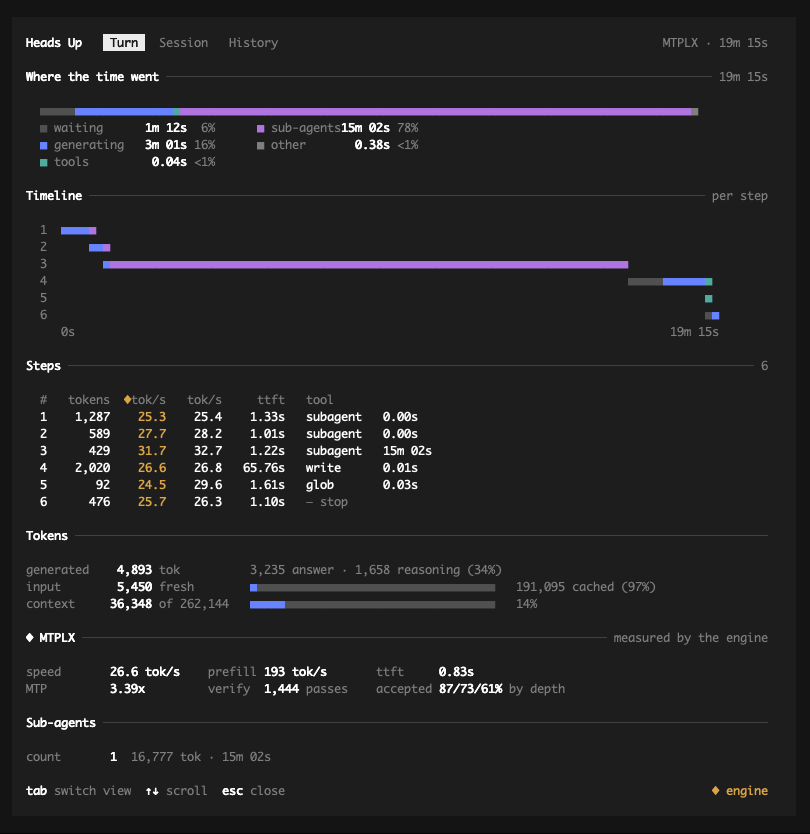
+ Heads Up in the OpenCode sidebar: the last turn and the session so far + + Heads Up details dialog, Turn tab +
Sidebar
The last turn and the session so far, each collapsible, with details › for the full picture.
Turn
Where the time went, a timeline per step, every tool call, tokens and the engine's own figures.
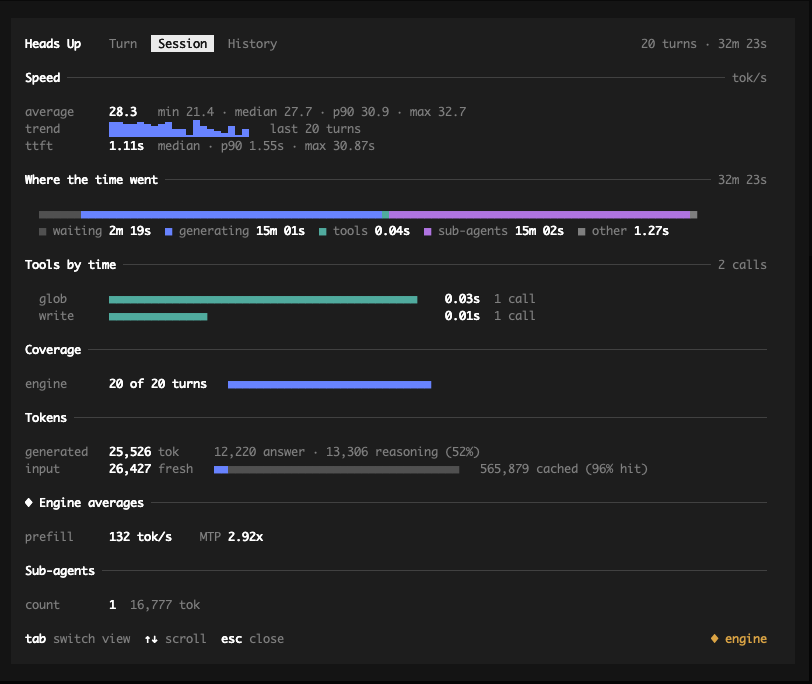
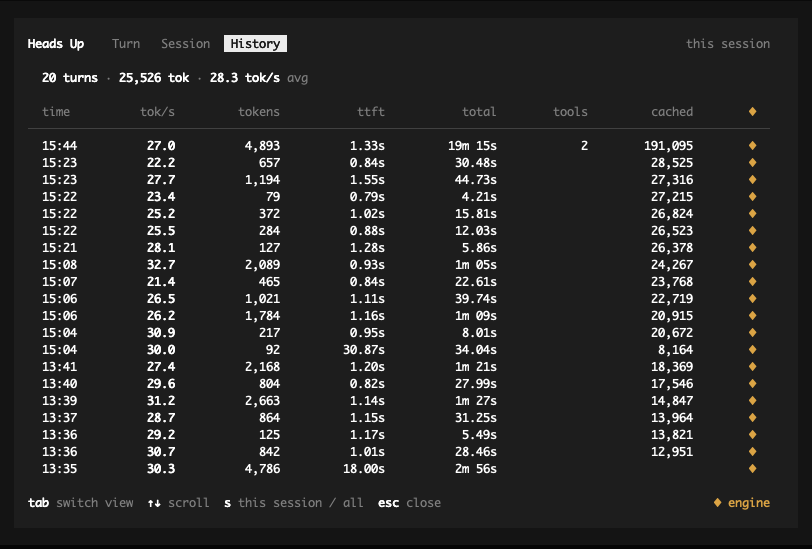
+ Heads Up details dialog, Session tab + + Heads Up details dialog, History tab +
Session
Speed and its spread, where the time went, tools, coverage and engine averages.
History
Every turn in fixed columns, for this session or all of them.
+ +## Features + + - **Metrics straight from local engines**: speed, prefill, cache and speculative-decoding + figures read from the engine itself. [See the full list](#supported-engines). + - **Works with any model**: remote and hosted models get the same core + figures from OpenCode's own data. + - **Sidebar and details view** + - **Turn and session figures** + - **Where the time went**: each turn split into waiting, generating, tools, + sub-agents and compaction, step by step. + - **Practical numbers**: tok/s is generation speed only, time is real elapsed + time, bad data is dispensed with. + - **Sub-agent aware**: sub-agents are counted and shown + separately. ## Contents @@ -48,15 +62,15 @@ Requires [**OpenCode 2**](https://opencode.ai/v2/docs). For the v1 line ## Install +Headsup requires [**OpenCode 2**](https://opencode.ai/v2/docs). For the v1 line +(OpenCode 1.18.x), see +[opencode-engine-hud](https://github.com/charlesnutter/opencode-engine-hud). + ```bash opencode plugin add @banburist/opencode-headsup ``` -Restart OpenCode. The panel appears in the sidebar footer after the first -turn. `opencode plugin list` shows what is installed; `plugin update` and -`plugin remove` handle the rest. - -Equivalent, if you keep your config in version control: +Or place it within the OpenCode cli config file. ```jsonc // ~/.config/opencode/cli.json @@ -453,62 +467,24 @@ Same shape for any OpenAI-compatible server: ### tok/s is generation speed; the total is what you waited -`tok/s` is tokens over the time spent streaming after the first token — -raw generation speed. OpenCode's own tok/s, in the footer under each turn, -divides by each step's time from the request to the end of streaming: it -leaves out time spent running tools, but includes prefill and the wait for -the first token. On a turn with a long wait before the first token the two -differ widely (measured: 38.1 tok/s over a 0.97s decode window against 3.7 -over the same turn's 10.03s; on MTPLX with a 17.6s prefill, 35.2 against -OpenCode's 13.1). Both are correct; the TTFT -beside the rate is what reconciles them. A turn that cannot be timed -from its stream shows no rate rather than a whole-turn figure. - -A large prefill shows in TTFT, in the prefill rate where the engine -reports one, and in the total — never in `tok/s`. The total runs from -the request to the end of the turn, and names any retries OpenCode made: -`60.00s (6 retries)`. - -A turn that calls tools is several requests, one per step. Its tokens, -cost and cache reuse are summed over every step; its `tok/s` covers only -the steps' own streaming, never the time spent running tools. +`tok/s` counts only the time spent generating, after the first token, so +it can be far higher than OpenCode's own figure, which includes the wait +for the first token. That wait shows as TTFT, and the total is the real +time from request to answer, retries included. ### Every figure is one turn, never a running total -Four things in this API are cumulative where a per-turn figure is -expected — `session.usage.updated`, `session.cost()`, raw engine -counters, and `time.streamed` (which is stamped at the *end* of the -stream, not the start, and is therefore not a TTFT). The per-turn -figures here are differenced or measured accordingly. - -A counter difference is only one turn's when the requests that reached the -engine between the two readings are this turn's own — one per step — and -its token count equals OpenCode's for the turn. OpenCode's own background -work (a new session's title, compaction), a turn you interrupted that kept -generating, or another tab or client sharing the server all break that, and -no engine here labels its counters by request or session to separate them -again. So a turn that shared its window shows the universal line with -`engine data skipped: overlapping requests` rather than figures that -describe several requests at once. This applies to every engine that -differences counters: the Prometheus engines, `llamacpp`, `llamafile`, -`splash` and `omlx`, checked against the turn's tokens and, where the -engine counts requests, against its steps. Verified live on vllm-mlx; the -others are built from their live captures. - -`mtplx`, `koboldcpp` and `mlxserve` report only the engine's latest -request, so they are read at the end of every step and the steps' receipts -combined: tokens summed, the rate over every step's decode time, TTFT and -prefill from the first step, the step that read the context. Each receipt -must match OpenCode's count for its step, or the turn shows the universal -line with the notice. Verified live on MTPLX; KoboldCpp and mlx-serve are -built from their live captures but not yet run step by step against a live -server. +Engines that only publish running totals are read before and after each +turn, and the difference is used only when it matches OpenCode's count for +that turn. When other work shares the engine at the same time (another tab, +say), the engine's figures are left out and the reason is shown. ### Absent is not zero -A free model shows no cost rather than `$0.00`, a cold prompt shows no -cache line rather than `0 cached`, and a missing speculative-draft -counter shows nothing rather than `0% accepted`. +A figure that isn't available is left out, not shown as zero: no `$0.00` +for a free model, no `0 cached` for a cold prompt. + +More detail: [docs/measurement-notes.md](docs/measurement-notes.md). ## Roadmap diff --git a/assets/screenshot-history.png b/assets/screenshot-history.png new file mode 100644 index 0000000..c777624 Binary files /dev/null and b/assets/screenshot-history.png differ diff --git a/assets/screenshot-session.png b/assets/screenshot-session.png new file mode 100644 index 0000000..dd0ed9c Binary files /dev/null and b/assets/screenshot-session.png differ diff --git a/assets/screenshot-sidebar.png b/assets/screenshot-sidebar.png new file mode 100644 index 0000000..4b74dc6 Binary files /dev/null and b/assets/screenshot-sidebar.png differ diff --git a/assets/screenshot-turn.png b/assets/screenshot-turn.png new file mode 100644 index 0000000..8f3ae03 Binary files /dev/null and b/assets/screenshot-turn.png differ diff --git a/dialog.ts b/dialog.ts index a408b62..52e09e6 100644 --- a/dialog.ts +++ b/dialog.ts @@ -442,49 +442,6 @@ export function engineItems(rows: ReadonlyArray): Arr return items.sort((a, b) => rank(a.label) - rank(b.label)) } -/** - * Label/value rows packed several to a line, as the mockup's engine section: - * `speed 41.2 tok/s prefill 475 tok/s ttft 17.37s`. A row with an - * empty label continues the one above; acceptance by depth folds into - * `93/87/82% by depth`. - */ -export function packRows(rows: ReadonlyArray, w: number): Line[] { - const all: Array<{ label: string; values: string[] }> = [] - for (const [label, value] of rows) { - if (label || all.length === 0) all.push({ label, values: [value] }) - else (all[all.length - 1] as { values: string[] }).values.push(value) - } - // The mockup's order: rates first, then speculative decoding. The token - // count is left out: the Tokens section already has it. - const ORDER = ["speed", "prefill", "ttft", "MTP", "accepted", "draft"] - const rank = (l: string): number => (ORDER.includes(l) ? ORDER.indexOf(l) : ORDER.length) - const groups = all.filter((g) => g.label !== "tokens").sort((a, b) => rank(a.label) - rank(b.label)) - const segs = groups.map(({ label, values }): { label: string; value: Line } => { - const depths = values.map((v) => /^(\d+)% at depth \d+$/.exec(v)?.[1]) - if (depths.length > 1 && depths.every((x) => x !== undefined)) { - return { label, value: [[`${depths.join("/")}%`, "bold"], [" by depth", "dim"]] } - } - const [first, ...rest] = values - return { label, value: [[first ?? "", "bold"], ...(rest.length > 0 ? ([[` ${rest.join(" ")}`, "dim"]] as Line) : [])] } - }) - const out: Line[] = [] - let cur: Line = [] - let prev = "" - for (const g of segs) { - const first: Line = [[g.label.padEnd(LABEL), "dim"], ...g.value] - const next: Line = [[" ", ""], [`${g.label} `, "dim"], ...g.value] - const newGroup = prev !== "" && rank(prev) <= 2 && rank(g.label) > 2 - prev = g.label - if (cur.length === 0) cur = first - else if (newGroup || width(cur) + width(next) > w) { - out.push(cur) - cur = first - } else cur = [...cur, ...next] - } - if (cur.length > 0) out.push(cur) - return out -} - // ---- Session ------------------------------------------------------------------------ /** The Session tab, laid out as the mockup. */ @@ -608,7 +565,7 @@ export function historyTabLines( const out: Line[] = [ [ [" ", ""], - [`${n0(rows.length)} turns`, "bold"], + [`${n0(rows.length)} ${rows.length === 1 ? "turn" : "turns"}`, "bold"], [" · ", "dim"], [`${n0(tokens)} tok`, "bold"], ...(genS > 0 ? ([[" · ", "dim"], [`${n1(genTok / genS)} tok/s`, "bold"], [" avg", "dim"]] as Line) : []), diff --git a/docs/measurement-notes.md b/docs/measurement-notes.md new file mode 100644 index 0000000..211c704 --- /dev/null +++ b/docs/measurement-notes.md @@ -0,0 +1,78 @@ +# Measurement notes + +The README's "Important Notes" section in full, as it stood before it was +shortened (2026-09-25). Kept here as source material for fuller docs later. + +Two things have changed since it was written and should be updated before +this is published anywhere: + +- **Compaction.** A compaction inside a turn on a counter engine is now read + before and after and taken out of the turn's window, so the turn keeps its + engine figures; `compaction ran this turn` is shown only when that fails. +- **Same-engine sub-agents.** A sub-agent on the same counter engine as its + parent is expected in the parent's window (its tokens and steps are added + to the check) and labelled `incl. sub-agents`, and each turn now takes its + own starting reading, so the sub-agent's report no longer moves it. + +--- + +## Important Notes (as of 0.4.0) + +### tok/s is generation speed; the total is what you waited + +`tok/s` is tokens over the time spent streaming after the first token — +raw generation speed. OpenCode's own tok/s, in the footer under each turn, +divides by each step's time from the request to the end of streaming: it +leaves out time spent running tools, but includes prefill and the wait for +the first token. On a turn with a long wait before the first token the two +differ widely (measured: 38.1 tok/s over a 0.97s decode window against 3.7 +over the same turn's 10.03s; on MTPLX with a 17.6s prefill, 35.2 against +OpenCode's 13.1). Both are correct; the TTFT +beside the rate is what reconciles them. A turn that cannot be timed +from its stream shows no rate rather than a whole-turn figure. + +A large prefill shows in TTFT, in the prefill rate where the engine +reports one, and in the total — never in `tok/s`. The total runs from +the request to the end of the turn, and names any retries OpenCode made: +`60.00s (6 retries)`. + +A turn that calls tools is several requests, one per step. Its tokens, +cost and cache reuse are summed over every step; its `tok/s` covers only +the steps' own streaming, never the time spent running tools. + +### Every figure is one turn, never a running total + +Four things in this API are cumulative where a per-turn figure is +expected — `session.usage.updated`, `session.cost()`, raw engine +counters, and `time.streamed` (which is stamped at the *end* of the +stream, not the start, and is therefore not a TTFT). The per-turn +figures here are differenced or measured accordingly. + +A counter difference is only one turn's when the requests that reached the +engine between the two readings are this turn's own — one per step — and +its token count equals OpenCode's for the turn. OpenCode's own background +work (a new session's title, compaction), a turn you interrupted that kept +generating, or another tab or client sharing the server all break that, and +no engine here labels its counters by request or session to separate them +again. So a turn that shared its window shows the universal line with +`engine data skipped: overlapping requests` rather than figures that +describe several requests at once. This applies to every engine that +differences counters: the Prometheus engines, `llamacpp`, `llamafile`, +`splash` and `omlx`, checked against the turn's tokens and, where the +engine counts requests, against its steps. Verified live on vllm-mlx; the +others are built from their live captures. + +`mtplx`, `koboldcpp` and `mlxserve` report only the engine's latest +request, so they are read at the end of every step and the steps' receipts +combined: tokens summed, the rate over every step's decode time, TTFT and +prefill from the first step, the step that read the context. Each receipt +must match OpenCode's count for its step, or the turn shows the universal +line with the notice. Verified live on MTPLX; KoboldCpp and mlx-serve are +built from their live captures but not yet run step by step against a live +server. + +### Absent is not zero + +A free model shows no cost rather than `$0.00`, a cold prompt shows no +cache line rather than `0 cached`, and a missing speculative-draft +counter shows nothing rather than `0% accepted`. diff --git a/package.json b/package.json index 4a5fce7..c7e335c 100644 --- a/package.json +++ b/package.json @@ -25,7 +25,7 @@ }, "scripts": { "typecheck": "tsc --noEmit", - "test": "npm run typecheck && bun test/format.test.mjs && bun test/http.test.mjs && bun test/prometheus-text.test.mjs && bun test/universal.test.mjs && bun test/mtplx.test.mjs && bun test/omlx.test.mjs && bun test/llamacpp.test.mjs && bun test/prometheus.test.mjs && bun test/koboldcpp.test.mjs && bun test/splash.test.mjs && bun test/mlxserve.test.mjs && bun test/history.test.mjs && bun test/panels.test.mjs && bun test/session.test.mjs && bun test/rows.test.mjs && bun test/detail.test.mjs && bun test/counters.test.mjs && bun test/references.test.mjs && bun test/e2e/turns.e2e.mjs && bun test/e2e/counters.e2e.mjs" + "test": "npm run typecheck && bun test/format.test.mjs && bun test/http.test.mjs && bun test/prometheus-text.test.mjs && bun test/universal.test.mjs && bun test/mtplx.test.mjs && bun test/omlx.test.mjs && bun test/llamacpp.test.mjs && bun test/prometheus.test.mjs && bun test/koboldcpp.test.mjs && bun test/splash.test.mjs && bun test/mlxserve.test.mjs && bun test/history.test.mjs && bun test/panels.test.mjs && bun test/session.test.mjs && bun test/rows.test.mjs && bun test/detail.test.mjs && bun test/counters.test.mjs && bun test/dialog.test.mjs && bun test/references.test.mjs && bun test/e2e/turns.e2e.mjs && bun test/e2e/counters.e2e.mjs && bun test/e2e/dialog.e2e.mjs" }, "files": [ "tui.tsx", diff --git a/test/dialog.test.mjs b/test/dialog.test.mjs new file mode 100644 index 0000000..b2b8e8a --- /dev/null +++ b/test/dialog.test.mjs @@ -0,0 +1,83 @@ +// Validates dialog.ts where an error can be reliably triggered in isolation: +// arithmetic with a known wrong answer, and layout that can overflow or +// misalign. The tabs as a whole are covered end to end (test/e2e/dialog.e2e.mjs). +// Run with: bun test/dialog.test.mjs +import { strict as assert } from "node:assert" +import { bar, share, alignedRows, columns, turnLines, width } from "../dialog.ts" + +let passed = 0 +function test(name, fn) { + try { + fn() + passed++ + console.log(" ok ", name) + } catch (e) { + console.log(" FAIL", name, "\n ", e.message) + process.exitCode = 1 + } +} +const cells = (l) => l.reduce((n, [t]) => n + t.length, 0) + +test("a bar fills exactly its cells, however its parts round", () => { + for (const n of [7, 20, 61]) { + assert.equal(cells(bar([[1, "gen", "■"], [1, "wait", "■"], [1, "tool", "■"]], n)), n) + assert.equal(cells(bar([[73.2, "wait", "■"], [25.1, "gen", "■"], [1.6, "tool", "■"], [0.1, "dim", "■"]], n)), n) + } +}) + +test("a small but real part keeps a cell of its bar", () => { + const b = bar([[99.9, "gen", "■"], [0.1, "tool", "■"]], 20) + assert.ok(b.some(([t, st]) => st === "tool" && t.length === 1), JSON.stringify(b)) +}) + +test("shares never round a real part to 0% or the rest to 100%", () => { + assert.equal(share(18369, 18398), "99.8%") + assert.equal(share(0.06, 81), "<1%") + assert.equal(share(0, 10), "0%") + assert.equal(share(5, 10), "50%") +}) + +test("aligned rows: values end, and bars start and end, at the same columns", () => { + const rows = alignedRows( + [ + { label: "input", value: "13,797", qual: "fresh", bar: [[1, "gen", "■"], [1, "wait", "■"]], note: "8,241 cached" }, + { label: "context", value: "8,726", qual: "of 262,144", bar: [[1, "gen", "■"], [9, "wait", "■"]], note: "3%" }, + ], + 24, + 80 + ) + const text = rows.map((l) => l.map(([t]) => t).join("")) + const barAt = text.map((t) => t.indexOf("■")) + const barEnd = text.map((t) => t.lastIndexOf("■")) + assert.equal(barAt[0], barAt[1], text.join("\n")) + assert.equal(barEnd[0], barEnd[1], text.join("\n")) + assert.equal(text[0].indexOf("13,797") + 6, text[1].indexOf("8,726") + 5, "values right-aligned") +}) + +test("aligned rows give up bar length before they overflow", () => { + const rows = alignedRows([{ label: "input", value: "13,797", qual: "fresh", bar: [[1, "gen", "■"]], note: "91,498 cached (92% hit)" }], 40, 60) + assert.ok(width(rows[0]) <= 60, String(width(rows[0]))) +}) + +test("a column grid drops to fewer columns rather than overflow", () => { + const items = ["speed", "prefill", "ttft", "MTP", "verify", "accepted"].map((l) => ({ label: l, value: [["x".repeat(18), "bold"]] })) + const three = columns(items, 120, 3) + assert.equal(three.length, 2) + const narrow = columns(items, 60, 3) + assert.ok(narrow.length > 2, "fewer columns, more rows") + for (const l of narrow) assert.ok(width(l) <= 60, String(width(l))) +}) + +// Regression: `■ sub-agents15m 02s` -- the longest legend name ran into its time. +test("a long legend name keeps a space before its time", () => { + const T0 = 1_000_000 + const d = { + engine: "MTPLX", totalS: 1155, steps: [], tokens: { output: 0, reasoning: 0, input: 0, cacheRead: 0, cacheWrite: 0 }, engineRows: [], + time: { waiting: 72, generating: 181, tools: 0.04, subagents: 902, compaction: 0, other: 0.38 }, + } + const text = turnLines(d, 80).map((l) => l.map(([t]) => t).join("")).join("\n") + assert.ok(/sub-agents\s+15m 02s/.test(text), text) + void T0 +}) + +console.log(`\n${passed} passed`) diff --git a/test/e2e/dialog.e2e.mjs b/test/e2e/dialog.e2e.mjs new file mode 100644 index 0000000..d5dc5c3 --- /dev/null +++ b/test/e2e/dialog.e2e.mjs @@ -0,0 +1,174 @@ +// End-to-end: the details dialog's three tabs, built from what real turns +// leave behind. Turns run through the entry file (see harness.mjs); each tab +// is then laid out exactly as the entry file lays it out -- dialog.ts's lines +// with the chosen spacing -- and read as the user would read it. +// Run with: bun test/e2e/dialog.e2e.mjs +import { strict as assert } from "node:assert" +import { startPlugin, engineServer, settle, test, done } from "./harness.mjs" +import { turnLines, sessionLines, historyTabLines, spaced, width } from "../../dialog.ts" +import { sessionFigures } from "../../session.ts" + +const MTPLX = { provider: "mtplx", model: "qwen3.8-27b" } +const receipt = (tokens, tokS) => ({ + latest: { completion_tokens: tokens, decode_tok_s: tokS, prefill_tok_s: 450, ttft_s: 2, verify_calls: Math.round(tokens / 3), mean_accept_probability_by_depth: [0.93, 0.87, 0.82] }, +}) +const text = (lines) => lines.map((l) => l.map(([t]) => t).join("")) +const tab = { + turn: (h, sid, w) => spaced(turnLines(h.detail(sid), w), "roomy"), + session: (h, sid, w) => spaced(sessionLines(sessionFigures(h.history(), sid), w), "roomy"), + history: (h, sid, w, scope = "session") => historyTabLines(h.history(), sid, scope, w), +} +const WIDTHS = [72, 80, 106, 130] + +/** A turn with a tool call, then a sub-agent, then an answer: three steps. */ +async function toolTurn(h, eng, sid) { + h.user(sid) + h.executionStarted(sid) + await h.step(sid, { + ...MTPLX, ttftMs: 2_000, streamMs: 4_000, finish: "tool-calls", + tokens: { input: 900, output: 100, reasoning: 20, cache: { read: 0, write: 0 } }, + tools: [{ name: "bash", ms: 3_000 }], + beforeStreamed: () => { eng.routes["/metrics"] = receipt(120, 30) }, + }) + await h.step(sid, { + ...MTPLX, ttftMs: 500, streamMs: 1_000, finish: "tool-calls", + tokens: { input: 50, output: 30, reasoning: 0, cache: { read: 900, write: 0 } }, + tools: [{ name: "subagent", ms: 20_000 }], + beforeStreamed: () => { eng.routes["/metrics"] = receipt(30, 30) }, + }) + await h.step(sid, { + ...MTPLX, ttftMs: 500, streamMs: 2_000, finish: "stop", + tokens: { input: 40, output: 60, reasoning: 0, cache: { read: 950, write: 0 } }, + beforeStreamed: () => { eng.routes["/metrics"] = receipt(60, 30) }, + }) + h.executionSucceeded(sid) + await settle() +} + +await test("Turn tab: the time split adds up, and every step, tool and engine figure is there", async () => { + const eng = engineServer() + const h = await startPlugin({ mtplxMetricsUrl: `${eng.url}/metrics` }) + try { + const sid = h.session("ses_t") + await toolTurn(h, eng, sid) + const lines = text(tab.turn(h, sid, 80)) + const all = lines.join("\n") + // 2 + 4 + 3 (bash) + 0.5 + 1 + 20 (sub-agent) + 0.5 + 2 = 33s + assert.ok(lines[0].startsWith("Where the time went") && lines[0].endsWith("33.00s"), lines[0]) + for (const part of ["waiting", "generating", "tools", "sub-agents"]) assert.ok(all.includes(`■ ${part}`), part) + assert.equal(lines.filter((l) => /^ {2}\d {2}/.test(l) && l.includes("■")).length, 3, "a timeline row per step") + assert.ok(/bash\s+3\.00s/.test(all), all) + assert.ok(/subagent\s+20\.00s/.test(all), all) + assert.ok(all.includes("— stop")) + // Tokens lead with what was generated, as the steps count it: 120 + 30 + 60. + assert.ok(/^generated\s+210 tok/m.test(all), all) + // The engine's figures, in its grid, and not OpenCode's total. + assert.ok(/speed\s+30\.0 tok\/s/.test(all) && all.includes("prefill") && all.includes("93/87/82%"), all) + assert.ok(!/◆ MTPLX[\s\S]*33\.00s/.test(all), "the engine section has no OpenCode total") + } finally { + h.restore() + eng.stop() + } +}) + +await test("every tab fits its width: no line wraps onto a blank-looking row", async () => { + const eng = engineServer() + const h = await startPlugin({ mtplxMetricsUrl: `${eng.url}/metrics` }) + try { + const sid = h.session("ses_w") + await toolTurn(h, eng, sid) + await toolTurn(h, eng, sid) + for (const w of WIDTHS) { + for (const [name, lines] of [ + ["turn", tab.turn(h, sid, w)], + ["session", tab.session(h, sid, w)], + ["history", tab.history(h, sid, w)], + ["history all", tab.history(h, sid, w, "all")], + ]) { + for (const l of lines) assert.ok(width(l) <= w, `${name} at ${w}: ${width(l)} > ${w}: ${l.map(([t]) => t).join("")}`) + } + } + } finally { + h.restore() + eng.stop() + } +}) + +await test("Session tab: tools by time, coverage and tokens over the session's turns", async () => { + const eng = engineServer() + const h = await startPlugin({ mtplxMetricsUrl: `${eng.url}/metrics` }) + try { + const sid = h.session("ses_s") + await toolTurn(h, eng, sid) + await toolTurn(h, eng, sid) + const all = text(tab.session(h, sid, 80)).join("\n") + assert.ok(/Tools by time[─ ]+2 calls/.test(all), all) + assert.ok(/ {2}bash\s+■+\s+6\.00s\s+2 calls/.test(all), all) + assert.ok(!/ {2}subagent /.test(all), "a sub-agent's time is its own part, not a tool's") + assert.ok(/engine\s+2 of 2 turns/.test(all), all) + assert.ok(/generated\s+420 tok/.test(all), all) + } finally { + h.restore() + eng.stop() + } +}) + +await test("Session tab: a turn with no tool calls says so, rather than hiding the section", async () => { + const h = await startPlugin({}) + try { + const sid = h.session("ses_n") + h.user(sid) + h.executionStarted(sid) + await h.step(sid, { provider: "lmstudio", model: "m", ttftMs: 500, streamMs: 1_000, finish: "stop", + tokens: { input: 10, output: 30, reasoning: 0, cache: { read: 0, write: 0 } } }) + h.executionSucceeded(sid) + await settle() + const all = text(tab.session(h, sid, 80)).join("\n") + assert.ok(all.includes("no tool calls in these turns"), all) + } finally { + h.restore() + } +}) + +await test("History tab: a row per turn in this session; all sessions adds the model", async () => { + const eng = engineServer() + const h = await startPlugin({ mtplxMetricsUrl: `${eng.url}/metrics` }) + try { + const a = h.session("ses_a") + await toolTurn(h, eng, a) + const b = h.session("ses_b") + await toolTurn(h, eng, b) + const mine = text(tab.history(h, b, 80)) + assert.ok(/\b1 turn\b/.test(mine[0]) && !mine[0].includes("1 turns"), mine[0]) + assert.equal(mine.filter((l) => /^ {2}\d\d:\d\d/.test(l)).length, 1) + assert.ok(!mine.join("\n").includes("model")) + const every = text(tab.history(h, b, 80, "all")) + assert.equal(every.filter((l) => /^ {2}\d\d:\d\d/.test(l)).length, 2) + assert.ok(every.some((l) => l.includes("model")) && every.some((l) => l.includes("qwen3.8-27b")), every.join("\n")) + assert.ok(every.filter((l) => /^ {2}\d\d:\d\d/.test(l)).every((l) => l.trimEnd().endsWith("◆")), "engine figures used on both") + } finally { + h.restore() + eng.stop() + } +}) + +await test("spacing: a blank row under each heading, and no blank row doubled", async () => { + const eng = engineServer() + const h = await startPlugin({ mtplxMetricsUrl: `${eng.url}/metrics` }) + try { + const sid = h.session("ses_sp") + await toolTurn(h, eng, sid) + for (const lines of [tab.turn(h, sid, 80), tab.session(h, sid, 80)]) { + const t = text(lines) + t.forEach((l, i) => { + if (/ ─{3,}/.test(l) && t[i + 1] !== undefined) assert.equal(t[i + 1].trim(), "", `no blank row under: ${l}`) + if (l.trim() === "" && i > 0) assert.notEqual(t[i - 1].trim(), "", `two blank rows before: ${t[i + 1]}`) + }) + } + } finally { + h.restore() + eng.stop() + } +}) + +done()